# BrainGrid — Full Content
---
> Full markdown of the product documentation, all published blog posts and the legal documents. See https://www.braingrid.ai/llms.txt for the curated index.
---
# Billing & Credits
Source: https://www.braingrid.ai/docs/billing
Description: Understand BrainGrid's credit-based billing, model pricing, and BYOK options.
BrainGrid uses a credit-based system that gives you control over usage. Choose your model, top up as needed, or bring your own API key.
## Plans & Pricing [#plans--pricing]
BrainGrid requires a paid plan—there's no free trial. Choose monthly or yearly billing (yearly saves about two months). All plans are priced per seat.
| Plan | Monthly | Yearly | Monthly credits | Projects | Users |
| ----------- | --------- | --------------------- | --------------- | --------- | --------- |
| Builder | $29/seat | $24/seat ($290/yr) | 5,000 | Up to 3 | 1 |
| Builder Pro | $99/seat | $83/seat ($990/yr) | 20,000 | Up to 25 | Unlimited |
| Team | $199/seat | $166/seat ($1,990/yr) | 50,000 | Unlimited | Unlimited |
Yearly prices show the effective monthly rate; the full amount is billed once per year (shown in parentheses). Credits reset on your billing date each month.
## Credit Top-Ups [#credit-top-ups]
Purchase additional credits anytime. Larger packs offer better value.
| Pack | Price | Per Credit | Savings |
| ------- | ----- | ---------- | ------- |
| 1,000 | $10 | $0.0100 | — |
| 5,000 | $45 | $0.0090 | 10% off |
| 11,750 | $100 | $0.0085 | 15% off |
| 50,000 | $400 | $0.0080 | 20% off |
| 100,000 | $750 | $0.0075 | 25% off |
Purchased credits are shared across your organization and valid for 12 months.
## Model Selection [#model-selection]
Choose from a range of models and set a default for your organization.
| Model | Best For |
| ----------------- | ------------------------------------------------------------------------------------------- |
| Gemini 3.5 Flash | Fast, affordable tasks (Google) |
| Gemini 3.1 Pro | Deep reasoning (Google) |
| Claude Haiku 4.5 | Fast, affordable tasks (Anthropic) |
| Claude Sonnet 4.6 | Fast, capable everyday tasks like requirement breakdowns and quick edits (Anthropic) |
| Claude Opus 4.7 | Most capable, with adaptive thinking for complex analysis and detailed planning (Anthropic) |
## Credit Rates [#credit-rates]
How credits are consumed per token.
| Model | Type | Credits/Token |
| ---------------- | ------ | ------------- |
| Gemini 3.5 Flash | Input | 0.0000355 |
| Gemini 3.5 Flash | Output | 0.000177 |
| Gemini 3.1 Pro | Input | 0.000071 |
| Gemini 3.1 Pro | Output | 0.000354 |
| Haiku 4.5 | Input | 0.000142 |
| Haiku 4.5 | Output | 0.000708 |
| Sonnet 4.6 | Input | 0.000425 |
| Sonnet 4.6 | Output | 0.002125 |
| Opus 4.7 | Input | 0.000708 |
| Opus 4.7 | Output | 0.003542 |
## Bring Your Own Key (BYOK) [#bring-your-own-key-byok]
Connect your own AI provider API key—Anthropic or Google—to pay the provider directly. BrainGrid charges a reduced platform fee in credits: 15% of the standard rate for Anthropic models (Haiku, Sonnet, Opus), and no platform fee for Gemini models.
**BYOK rates per token (credits):**
| Model | Type | Credits/Token |
| ---------------- | ------ | ------------- |
| Gemini 3.5 Flash | Input | 0 |
| Gemini 3.5 Flash | Output | 0 |
| Gemini 3.1 Pro | Input | 0 |
| Gemini 3.1 Pro | Output | 0 |
| Haiku 4.5 | Input | 0.0000213 |
| Haiku 4.5 | Output | 0.0001062 |
| Sonnet 4.6 | Input | 0.00006375 |
| Sonnet 4.6 | Output | 0.00031875 |
| Opus 4.7 | Input | 0.0001062 |
| Opus 4.7 | Output | 0.0005313 |
## FAQ [#faq]
You can access your epics and requirements, but you won't be able to use the agent.
Monthly plan credits reset each billing cycle. Purchased top-ups are valid for 12 months.
In **Settings** → **Organization**, you can set the default model for your organization.
Go to **Settings** → **AI Provider API Keys** → Add your Anthropic or Google API key.
You can choose to fallback to BrainGrid credits when your key gets rate limited.
---
# Set up Claude Code to build locally
Source: https://www.braingrid.ai/docs/claude-code
Description: Build a BrainGrid requirement locally with Claude Code
## What is Claude Code? [#what-is-claude-code]
Claude Code is an AI coding assistant made by Anthropic. It runs in your terminal and can read your codebase, write code, run commands, and work through tasks — all from a text-based interface.
BrainGrid connects to Claude Code to give it structured instructions. Instead of describing what to build from scratch, you point Claude Code at a BrainGrid requirement and it implements the tasks automatically.
## Prerequisites [#prerequisites]
Before you begin, make sure you have the following set up:
* A [BrainGrid account](/docs/quickstart) — create an account at braingrid.ai
* The [GitHub CLI](/docs/guides/github-cli) — installed and authenticated
* The [BrainGrid CLI](/docs/cli/overview) — installed and authenticated
* [Claude Code](https://docs.anthropic.com/en/docs/claude-code/overview) — installed from Anthropic
## Check out and initialize your project [#check-out-and-initialize-your-project]
Before Claude Code can build anything, you need to connect your code to BrainGrid. This tells BrainGrid which project you're working on and lets Claude Code find your requirements and tasks.
Your GitHub repository needs to be linked to a BrainGrid project. This is how BrainGrid knows which codebase your requirements belong to.
If you haven't done this yet, follow the [Create a Project](/docs/guides/create-project) guide. You'll also need the [GitHub App installed](/docs/github-installation) so BrainGrid can access your repository.
Cloning downloads a copy of your code to your computer. Open your terminal — on Mac, press **Command + Space**, type **Terminal**, and press **Enter**. On Windows, press the **Windows key**, type **PowerShell**, and click **Windows PowerShell**. Then run:
```bash
gh repo clone owner/repo
```
Replace `owner/repo` with your actual repository — for example, `my-company/my-app`.
Move into the folder you just downloaded:
```bash
cd repo
```
Replace `repo` with the name of your repository folder.
This tells BrainGrid which project this folder belongs to:
```bash
braingrid init
```
You'll be prompted to select your project. Once complete, a `.braingrid/project.json` file is created in your folder.
This command will fail if your repository isn't connected to a BrainGrid project yet. Make sure you completed the first step.
## Install the integration [#install-the-integration]
This adds BrainGrid commands to Claude Code so they can work together. Run this from your project folder:
```bash
braingrid setup claude-code
```
## Verify the integration [#verify-the-integration]
Make sure everything was set up correctly:
From your project folder, start Claude Code by running:
```bash
claude
```
Type `/` in the Claude Code prompt. You should see a list of commands pop up, including `/build`.
If you don't see `/build` in the list, close Claude Code, run `braingrid setup claude-code` again, and reopen it.
## What gets installed [#what-gets-installed]
The setup command installs four components into your project:
### Slash commands [#slash-commands]
Located in `.claude/commands/`, these give you quick access to BrainGrid features:
| Command | Description | Example |
| ------------------- | ------------------------------------------ | ------------------------------------ |
| `/specify` | Create a requirement from a rough idea | `/specify Add user auth with OAuth2` |
| `/save-requirement` | Save a Claude Code plan as a requirement | `/save-requirement` |
| `/build` | Build a requirement — implements all tasks | `/build REQ-123` |
### BrainGrid CLI skill [#braingrid-cli-skill]
Located in `.claude/skills/braingrid-cli/`, this gives Claude Code context about your project and the BrainGrid workflow so it knows how to use the commands effectively.
### Status line [#status-line]
Located in `.claude/statusline.sh`, this displays your current progress at the top of Claude Code:
**Example:** `BrainGrid: PROJ-3 > REQ-128 [2/5]`
* **Project**: Your current BrainGrid project
* **Requirement**: The requirement you're working on (detected from your branch name)
* **Progress**: How many tasks are completed (2 of 5 in this example)
### CLAUDE.md content [#claudemd-content]
Adds BrainGrid workflow documentation to your project's `CLAUDE.md` file, giving Claude Code background context about your commands and workflow.
## Build a requirement [#build-a-requirement]
Once everything is set up, tell Claude Code which requirement to build:
```bash Claude Code
/build REQ-123
```
Replace `REQ-123` with your actual requirement ID. Claude Code creates a feature branch, reads the requirement's tasks, and implements them one by one. The status line at the top updates as each task is completed.
You can also add specific instructions:
```bash Claude Code
/build REQ-123 Use TypeScript for all new code. Include unit tests.
```
## Learn more [#learn-more]
Explore all available CLI commands
Learn how to create requirements in BrainGrid
Manage projects in the browser
---
# Working with Cursor
Source: https://www.braingrid.ai/docs/cursor
Description: How to use BrainGrid and Cursor together
The Cursor integration provides three powerful components:
* **Slash Commands** - Quick commands for creating specs and breaking down work
* **Always-On Rules** - Automatic BrainGrid context without manual activation
* **AGENTS.md Integration** - Persistent workflow guidance throughout your Cursor session
## Installation [#installation]
Install the CLI globally:
```bash
npm install -g @braingrid/cli
```
Log in to your BrainGrid account:
```bash
braingrid login
```
Link your project to BrainGrid:
```bash
braingrid init
```
Set up slash commands, rules, and AGENTS.md:
```bash
braingrid setup cursor
```
## What Gets Installed [#what-gets-installed]
The setup command installs four key components:
### Slash Commands [#slash-commands]
Located in `.cursor/commands/`, these commands provide quick access to BrainGrid features:
| Command | Description | Example |
| ------------------- | ------------------------------------------------------------------------- | ------------------------------------ |
| `/specify` | Create AI-refined requirement from vague idea | `/specify Add user auth with OAuth2` |
| `/save-requirement` | Save a Cursor plan as a requirement | `/save-requirement` |
| `/breakdown` | Break requirement into perfectly-prompted tasks | `/breakdown REQ-123` |
| `/build` | Get complete implementation plan with all task prompts in markdown format | `/build REQ-123` |
In Cursor's Agent input type `/` to see all available commands. BrainGrid commands appear alongside Cursor's built-in commands.
### Always-On Rules [#always-on-rules]
Located in `.cursor/rules/braingrid.mdc`, this file teaches Cursor about BrainGrid automatically:
* **No explaining needed** - Cursor already knows what BrainGrid is
* **Context-aware responses** - Cursor understands PROJ-X, REQ-Y, TASK-Z references
* **Workflow guidance** - Cursor suggests next steps in the BrainGrid workflow
* **Better task execution** - Cursor follows BrainGrid task prompts more accurately
The rules are always active (`alwaysApply: true`) - no manual activation required.
### AGENTS.md Integration [#agentsmd-integration]
Located at your repository root, this file provides BrainGrid guidance:
* **Automatically loaded** - No manual activation needed
* **Persistent context** - Available throughout your Cursor session
* **Consistent guidance** - Same BrainGrid workflow across all projects
## Typical Workflow [#typical-workflow]
Here's how to use BrainGrid with Cursor:
In Cursor Agent, start with a vague idea and let AI refine it:
```bash Cursor
/specify Add dark mode toggle in settings with theme persistence
```
This creates a structured requirement with clear scope and acceptance criteria.
Convert the requirement into AI-ready tasks:
```bash Cursor
/breakdown REQ-1
```
This generates 5-10 focused tasks with clear prompts optimized for Cursor.
Create a git branch to enable auto-detection:
```bash Cursor
git checkout -b feature/REQ-1-dark-mode
```
BrainGrid automatically detects `REQ-1` from your branch name.
In Cursor Agent, get the complete implementation plan to start building:
```bash Cursor
/build REQ-1
```
This provides all task details in markdown format, perfect for Cursor.
## MCP Server Installation [#mcp-server-installation]
Prefer native tool integration? Install BrainGrid as an MCP server:
See the [MCP vs CLI](#mcp-vs-cli) section below to choose the right approach, and visit the [MCP Server documentation](/docs/mcp-server/installation) for detailed installation instructions.
### MCP vs CLI [#mcp-vs-cli]
#### Prefer the CLI when: [#prefer-the-cli-when]
* Don't want to bloat your context with more MCP servers.
* Speed matters, the CLI calls end up being faster than the MCP calls.
* You need to script custom workflows.
#### Prefer the MCP when: [#prefer-the-mcp-when]
* When you are in an environment that does not support the CLI.
* You are more comfortable with the MCPs than CLIs
**Choose one or the other, not both** - MCP and CLI are alternative approaches to integrating BrainGrid with Cursor. Select the approach that best fits your workflow.
## Tips for Effective Use [#tips-for-effective-use]
### Writing Good Prompts for `/specify` [#writing-good-prompts-for-specify]
Include these elements for best results:
* **Problem** - What are you trying to solve?
* **Context** - Why is this needed? What's the background?
* **Constraints** - Any technical or business limitations?
* **Users** - Who will use this feature?
* **Success Criteria** - How will you know it's done?
**Example:**
```bash Cursor
/specify Add user authentication for our web app. We need OAuth2 support
for Google and GitHub. Must work with our existing Express backend and
React frontend. Users should stay logged in for 30 days. Success means
users can sign up and log in without creating passwords.
```
### Using Additional Instructions with `/build` [#using-additional-instructions-with-build]
Provide specific guidance for task implementation:
```bash Cursor
/build REQ-123 Use TypeScript for all new code.
Follow the existing repository pattern in src/repositories/.
Include unit tests for all business logic.
```
### Git Branch Workflow [#git-branch-workflow]
Name your branches with the requirement ID for automatic detection:
```bash
# Good - auto-detects REQ-42
git checkout -b feature/REQ-42-stripe-integration
# Also works
git checkout -b fix/REQ-42-payment-bug
git checkout -b REQ-42-any-description
# Won't auto-detect
git checkout -b add-stripe-payments
```
## Learn More [#learn-more]
Complete reference for all CLI commands
Alternative tool-based integration
View source code and contribute
Manage projects in the browser
---
# Connect your project to GitHub
Source: https://www.braingrid.ai/docs/github-installation
Description: Complete guide to permissions and installation of the BrainGrid GitHub App
Installing the BrainGrid GitHub App requires specific permissions on your GitHub repository. This guide explains who can install the app and how to get the necessary permissions.
## Permission Requirements [#permission-requirements]
You must have **Admin** or **Owner** permissions to install the BrainGrid GitHub App on a repository.
### Who Can Install GitHub Apps? [#who-can-install-github-apps]
Role
Can Install?
Limitations
**Organization Owner**
✅ Yes
Can install on any repository in the organization
**Repository Admin**
✅ Yes*
Only on repos where they have admin rights, and only if the app doesn't request org-level permissions
**Personal Repo Owner**
✅ Yes
Full control over their personal repositories
**Maintainer/Write/Triage/Read**
❌ No
Can request installation, but owner must approve
**Important**: Organization owners can restrict repository admins from installing GitHub Apps in their organization settings.
## Installation Steps [#installation-steps]
Before starting, verify you have the necessary permissions:
1. Go to your repository on GitHub
2. Click **Settings** (if you don't see it, you don't have admin access)
3. Look for **Collaborators & teams** in the sidebar
If you can't access Settings, you'll need to request admin access first.
Go to the [Integrations](https://app.braingrid.ai/agent/integrations) section in the BrainGrid console.
Or click **Connect GitHub** from your BrainGrid dashboard.
Choose where to install:
* **Personal account**: Select your username
* **Organization**: Select the organization (you must be an owner or admin)
If you're not an owner/admin, you'll see "Request" instead of "Install"
Select which repositories BrainGrid can access:
Grants access to all current and future repos
Choose specific repositories from a list
We recommend selecting only the repositories you plan to use with BrainGrid
Carefully review the permissions BrainGrid is requesting:
* **Read** access to code and metadata
* **Write** access to issues and pull requests
* **Read** access to actions and workflows
These permissions allow BrainGrid to analyze your code and validate PRs.
Click the installation button:
* **Install** - If you have full permissions
* **Install & Request** - If you have partial permissions
* **Request** - If you need owner approval
If you see "Request", the organization owner will receive a notification to approve your request
## Getting Admin Access [#getting-admin-access]
If you don't have the necessary permissions, here's how to get them:
### For Organization Repositories [#for-organization-repositories]
If you're an admin and need to grant access to someone:
1. Go to the repository on GitHub
2. Click **Settings** → **Collaborators & teams**
1. Click **Add people** or **Add teams**
2. Search for the user by their GitHub username
3. Select them from the dropdown
1. In the role dropdown, select **Admin**
2. Click **Add \[username] to \[repository]**
The user now has admin access and can install GitHub Apps.
### For Personal Repositories [#for-personal-repositories]
Personal repositories only have two roles: **Owner** (you) and **Collaborators** (write access only).
Collaborators cannot have admin rights on personal repositories.
If you need multiple admins, consider:
1. **Transfer to an Organization**: Move your repository to an organization where you can assign admin roles
2. **Create an Organization**: Set up a new organization for your projects
## Troubleshooting [#troubleshooting]
You don't have admin access to the repository. Contact the repository admin or owner.
Check if:
* You selected at least one repository
* Your organization has restrictions on GitHub App installations
* You have a pending request waiting for approval
The organization owner may have concerns about:
* The permissions requested
* Organization policies
* Security requirements
Discuss with them and share BrainGrid's security documentation.
* For personal repos: Look for **Manage access** instead
* For org repos: You might not have admin permissions
* Some organizations hide this based on policies
## Quick Reference [#quick-reference]
### Installation URL [#installation-url]
```
https://github.com/apps/braingrid/installations/new
```
### Required Permissions [#required-permissions]
* **Minimum**: Repository Admin (with restrictions)
* **Recommended**: Organization Owner (full control)
### Can't Install? [#cant-install]
1. Check your repository role
2. Request admin access if needed
3. Or ask an admin to install for you
## Next Steps [#next-steps]
Once you've successfully installed the BrainGrid GitHub App:
Return to the quickstart guide to analyze your repository
Understand how BrainGrid works with your code
## Additional Resources [#additional-resources]
* [GitHub's official guide on managing repository access](https://docs.github.com/en/repositories/managing-your-repositorys-settings-and-features/managing-repository-settings/managing-teams-and-people-with-access-to-your-repository)
* [Understanding GitHub App permissions](https://docs.github.com/en/apps/creating-github-apps/setting-up-a-github-app/choosing-permissions-for-a-github-app)
* [Organization roles in GitHub](https://docs.github.com/en/organizations/managing-peoples-access-to-your-organization-with-roles/roles-in-an-organization)
---
# Welcome to BrainGrid!
Source: https://www.braingrid.ai/docs
Description: Plan, specify, and build your AI coding projects.
Built for AI coders beyond the initial prototype, BrainGrid helps you:
* Build features without breaking things
* Tackle more complex functionality with structured plans
* Build a well-structured and more maintainable application
* Ship faster with less bug fixing and rework
## The Workflow [#the-workflow]
AI coding tools are powerful, but they struggle with vague instructions. They go off-track, miss requirements, and need constant hand-holding.
BrainGrid is like an AI Tech Lead that brings clarity and structure with **a proven workflow to ship reliable software.**
The workflow is simple, yet powerful:
Start with a rough idea, a high level concept, or a problem to solve.
Click `Refine` to refine the rough idea with AI into a detailed specification.
BrainGrid asks clarifying questions to define the scope and uncover edge cases.
Upon completion, the basic prompt is refined into a full technical requirement with feature requests. This can be edited manually, or work with the AI to update the requirement.
In this example, the simple prompt has been expanded to include:
* Overview
* Actors
* Data Model Changes
* 6 Functional Requirements
* API Contract
* New Files
* Environmental Variables
* 10 Acceptance Criteria
## Overview [#overview]
A scheduled weekly email report delivered every Monday at 08:00 UTC to all users with `is_admin = true` in the `profiles` table. The report summarises each non-admin user's checklist completion progress across all countries and flags any user whose most-recent activity (`updated_at` on `user_progress`) is more than 7 days old.
The feature introduces:
1. A new Next.js API route (`POST /api/admin/weekly-report`) that builds and sends the report — callable by a Vercel Cron Job.
2. A Resend-powered HTML email template.
3. A new Supabase migration adding a `last_active_at` column to `profiles` (updated on every progress toggle).
***
## Actors [#actors]
| Actor | Description |
| ----------------- | --------------------------------------------------------------------------------- |
| **Company Admin** | Any `profiles` row where `is_admin = true`. Receives the weekly email. |
| **Employee** | Any `profiles` row where `is_admin = false`. Appears as a data row in the report. |
| **Vercel Cron** | Infrastructure trigger that calls the report API every Monday at 08:00 UTC. |
***
## Data Model Changes [#data-model-changes]
### Migration: `005_last_active_at.sql` [#migration-005_last_active_atsql]
```sql
ALTER TABLE public.profiles
ADD COLUMN IF NOT EXISTS last_active_at TIMESTAMPTZ;
```
* `last_active_at` is set to `NOW()` whenever a row in `user_progress` is inserted or updated for that user (via a new trigger `set_last_active_at` on `user_progress`).
* Existing rows default to `NULL` (treated as "never active" for inactivity logic).
### Trigger: `set_last_active_at` [#trigger-set_last_active_at]
Fires `AFTER INSERT OR UPDATE ON public.user_progress FOR EACH ROW`. Updates `profiles.last_active_at = NOW()` for the affected `user_id`.
***
## Functional Requirements [#functional-requirements]
### FR-1 — Report Trigger [#fr-1--report-trigger]
* A Vercel Cron Job defined in `vercel.json` calls `POST /api/admin/weekly-report` every Monday at 08:00 UTC.
* The route is protected by a `CRON_SECRET` environment variable. Requests without the header `Authorization: Bearer ` receive `401 Unauthorized`.
* The route can also be called manually by a super-admin for testing (same auth header).
### FR-2 — Employee Data Query [#fr-2--employee-data-query]
The API route uses the Supabase **service-role** client (bypasses RLS) to:
1. Fetch all employees: `SELECT id, email, full_name, last_active_at FROM profiles WHERE is_admin = false ORDER BY full_name ASC`.
2. For each employee, fetch aggregate progress across all countries:
```sql
SELECT
COUNT(*) FILTER (WHERE completed = true) AS completed_count,
COUNT(*) AS total_items
FROM user_progress
WHERE user_id =
```
3. Compute `completion_percentage = ROUND(completed_count / total_items * 100)`. If `total_items = 0`, percentage is `0`.
4. Determine inactivity flag: `is_inactive = last_active_at IS NULL OR last_active_at < NOW() - INTERVAL '7 days'`.
### FR-3 — Admin Recipients [#fr-3--admin-recipients]
* Fetch all admins: `SELECT email, full_name FROM profiles WHERE is_admin = true`.
* Send one email per admin (individual `to:` addresses, not BCC).
* If no admins exist, log a warning and return `200` with `{ sent: 0 }`.
### FR-4 — Email Content [#fr-4--email-content]
The HTML email contains the following sections in order:
#### 4a. Header [#4a-header]
* App name: **International Concierge**
* Report title: "Weekly Employee Progress Report"
* Date range: "Week of \[Monday date] – \[Sunday date]" (ISO format: `DD MMM YYYY`)
#### 4b. Summary Row [#4b-summary-row]
A single-line summary above the table:
> "\[N] employees · \[X] inactive (no activity in 7+ days)"
#### 4c. Employee Progress Table [#4c-employee-progress-table]
Columns: **Name**, **Email**, **Items Completed**, **Total Items**, **Completion %**, **Last Active**, **Status**
* Rows are sorted: inactive employees first (alphabetically), then active employees (alphabetically).
* **Last Active** cell: formatted as `DD MMM YYYY` if `last_active_at` is set; otherwise displays `—`.
* **Status** cell:
* Inactive (never active or >7 days): red badge label `⚠ Inactive`
* Active (activity within 7 days): green badge label `✓ Active`
#### 4d. Footer [#4d-footer]
* Static text: "This report is sent automatically every Monday. Log in to International Concierge to view detailed progress."
* Link to the admin dashboard (configured via `NEXT_PUBLIC_APP_URL` env var).
### FR-5 — Email Sending [#fr-5--email-sending]
* Use **Resend** (`resend` npm package) with API key stored in `RESEND_API_KEY` env var.
* `from:` address: `reports@` (stored in `REPORT_FROM_EMAIL` env var).
* `subject:` `"International Concierge — Weekly Report ([DD MMM YYYY])"`
* Email is HTML with a plain-text fallback.
* If Resend returns an error for one admin, log the error and continue sending to remaining admins. Return a partial-success response.
### FR-6 — Edge Cases [#fr-6--edge-cases]
| Scenario | Behaviour |
| ------------------------------------------ | --------------------------------------------------------------------------------------- |
| No employees (`is_admin = false` rows = 0) | Send email with empty table and summary "0 employees · 0 inactive" |
| No admins (`is_admin = true` rows = 0) | Skip sending; API returns `{ sent: 0, reason: "no_admins" }` with HTTP 200 |
| Employee has no `user_progress` rows | `completed_count = 0`, `total_items = 0`, `completion_percentage = 0`, flagged inactive |
| `last_active_at` is NULL | Treated as inactive (never used the site) |
| Resend API failure for one admin | Log error, continue to next admin, return `{ sent: N, errors: [...] }` |
| Cron called with wrong/missing secret | Return `401 Unauthorized`, do not send any emails |
***
## API Contract [#api-contract]
### `POST /api/admin/weekly-report` [#post-apiadminweekly-report]
**Request Headers:**
```
Authorization: Bearer
```
**Response — Success:**
```json
{
"sent": 2,
"employees": 14,
"inactive": 3
}
```
**Response — No admins:**
```json
{ "sent": 0, "reason": "no_admins" }
```
**Response — Partial failure:**
```json
{
"sent": 1,
"errors": [{ "admin": "admin@example.com", "error": "Resend API error" }]
}
```
**Response — Unauthorized:**
```
HTTP 401
{ "error": "Unauthorized" }
```
***
## New Files [#new-files]
| File | Purpose |
| -------------------------------------------- | ------------------------------------------------------ |
| `supabase/migrations/005_last_active_at.sql` | Adds `last_active_at` column + trigger |
| `src/app/api/admin/weekly-report/route.ts` | Cron-triggered report API route |
| `src/lib/email/weeklyReport.ts` | HTML email template builder (returns `{ html, text }`) |
| `vercel.json` | Cron schedule definition |
### `vercel.json` snippet [#verceljson-snippet]
```json
{
"crons": [
{
"path": "/api/admin/weekly-report",
"schedule": "0 8 * * 1"
}
]
}
```
***
## Environment Variables [#environment-variables]
| Variable | Description |
| --------------------- | --------------------------------------------------------- |
| `CRON_SECRET` | Shared secret for authenticating cron requests |
| `RESEND_API_KEY` | Resend API key for sending emails |
| `REPORT_FROM_EMAIL` | Sender address, e.g. `reports@internationalconcierge.com` |
| `NEXT_PUBLIC_APP_URL` | Base URL for dashboard link in email footer |
***
## Acceptance Criteria [#acceptance-criteria]
### AC-1: Cron Authentication [#ac-1-cron-authentication]
* **Given** a POST request to `/api/admin/weekly-report` without the `Authorization` header
* **When** the request is processed
* **Then** the API returns HTTP `401` and no emails are sent
* **Given** a POST request with `Authorization: Bearer wrong-secret`
* **When** the request is processed
* **Then** the API returns HTTP `401` and no emails are sent
* **Given** a POST request with the correct `Authorization: Bearer `
* **When** the request is processed
* **Then** the API proceeds to build and send the report
### AC-2: Employee Progress Aggregation [#ac-2-employee-progress-aggregation]
* **Given** employee Alice has completed 8 of 10 checklist items across all countries
* **When** the report is generated
* **Then** Alice's row shows `completed_count = 8`, `total_items = 10`, `completion_percentage = 80%`
* **Given** employee Bob has no `user_progress` rows
* **When** the report is generated
* **Then** Bob's row shows `completed_count = 0`, `total_items = 0`, `completion_percentage = 0%`
### AC-3: Inactivity Flagging [#ac-3-inactivity-flagging]
* **Given** employee Carol's `last_active_at` is 8 days ago
* **When** the report is generated
* **Then** Carol's row shows the `⚠ Inactive` status badge
* **Given** employee Dave's `last_active_at` is NULL (never logged in)
* **When** the report is generated
* **Then** Dave's row shows the `⚠ Inactive` status badge
* **Given** employee Eve's `last_active_at` is 3 days ago
* **When** the report is generated
* **Then** Eve's row shows the `✓ Active` status badge
### AC-4: last\_active\_at Updates [#ac-4-last_active_at-updates]
* **Given** employee Frank toggles a checklist item (insert or update on `user_progress`)
* **When** the database trigger fires
* **Then** `profiles.last_active_at` for Frank is updated to the current timestamp
### AC-5: Email Delivery [#ac-5-email-delivery]
* **Given** there are 2 admins and 5 employees
* **When** the report API is called with a valid secret
* **Then** 2 separate emails are sent (one per admin), each containing a table with 5 employee rows
* **And** the API returns `{ "sent": 2, "employees": 5, "inactive": }`
### AC-6: Email Content [#ac-6-email-content]
* **Given** the report email is generated
* **When** the email is rendered
* **Then** the subject line matches `"International Concierge — Weekly Report ([DD MMM YYYY])"`
* **And** the header shows the correct week date range (Monday–Sunday)
* **And** inactive employees appear before active employees in the table
* **And** the footer contains a working link to `NEXT_PUBLIC_APP_URL/admin`
### AC-7: No Admins Edge Case [#ac-7-no-admins-edge-case]
* **Given** no profiles have `is_admin = true`
* **When** the report API is called
* **Then** no emails are sent and the API returns `{ "sent": 0, "reason": "no_admins" }` with HTTP `200`
### AC-8: No Employees Edge Case [#ac-8-no-employees-edge-case]
* **Given** all profiles have `is_admin = true` (zero employees)
* **When** the report API is called
* **Then** emails are sent to all admins with an empty table and summary "0 employees · 0 inactive"
### AC-9: Resend Partial Failure [#ac-9-resend-partial-failure]
* **Given** there are 2 admins and Resend fails for the second admin's email
* **When** the report API is called
* **Then** the first admin's email is sent successfully
* **And** the error for the second admin is logged
* **And** the API returns `{ "sent": 1, "errors": [{ "admin": "...", "error": "..." }] }`
### AC-10: Cron Schedule [#ac-10-cron-schedule]
* **Given** `vercel.json` is deployed with the cron configuration
* **When** Monday 08:00 UTC arrives
* **Then** Vercel automatically calls `POST /api/admin/weekly-report` with the correct `Authorization` header (configured via Vercel environment variables)
Automatically build the requirement with your AI coding tool.
You can feed tasks via the [MCP](/docs/mcp-server/overview), [CLI](/docs/cli/overview), or just copy paste them into your AI coding tool.
```bash Claude Code or Cursor
/build REQ-8
```
BrainGrid and your AI coding tool will build the code required to complete the requirement. Under the hood:
* New GitHub branch
* Tasks are created
``Install the `resend` npm package. Create a service-role Supabase client at `src/lib/supabase/service-role.ts` that uses SUPABASE_SERVICE_ROLE_KEY to bypass RLS. Document required env vars: RESEND_API_KEY, CRON_SECRET, REPORT_FROM_EMAIL, SUPABASE_SERVICE_ROLE_KEY.``
Create `src/lib/email/weeklyReport.ts` with a pure function `buildWeeklyReportHtml(employees, period)` that returns an HTML string. Must include: header with app name and report period, summary row (total employees, completions, inactive count), employee table sorted alphabetically (Name, Country, Items Completed/Total, Completion %, Last Active, Status badge), footer. Handle empty states: no employees message, no country shows "—", inactive employees get ⚠️ badge. Include inline styles only, no external CSS.
Create `src/app/api/cron/weekly-report/route.ts` with POST handler that:
1 Validates Authorization Bearer CRON\_SECRET (401 if invalid)
2 Queries all non-admin employees with completion stats using service-role Supabase client
3 Queries all admins (is\_admin=true)
4 Builds HTML email using buildWeeklyReportHtml
5 Sends email to each admin via Resend
6 Returns 200 with sent, employees count. Handle edge cases: no admins (log report\_skipped), no employees (send empty-state email), Supabase failure (500), Resend partial failure (log error, continue). Implement structured logging: cron\_started, report\_sent, report\_skipped, cron\_error.
Create `vercel.json` with cron configuration: path "/api/cron/weekly-report", schedule "0 8 \* \* 1" (every Monday at 08:00 UTC).
* Completes the coding for the tasks.
* Updates BrainGrid with the tasks shown as completed.
* Commits the code to the Github repository.
Each stage adds structure, so by the time your AI starts coding, it knows exactly what to build and how to verify it's correct.
## Getting Started [#getting-started]
Step by step guide to get started in minutes
Start working on new or existing projects.
---
# Quickstart
Source: https://www.braingrid.ai/docs/quickstart
Description: Turn your first idea into a working product
This quickstart will cover:
* [Creating an Account](#create-your-account)
* [Starting to Build: Creating a Plan](#start-building)
* [Specifying Requirements](#specify-requirements)
* [Installing the BrainGrid CLI, and configuring your agent](#install-the-braingrid-cli)
* [Building it with your favorite AI coding tool](#build-it-with-your-favorite-ai-coding-tool)
## Let's get started! [#lets-get-started]
Go to [https://app.braingrid.ai](https://braingrid.link/docs/sign-up) and create an account.
Give your organization a name and pick a username.
Now it is time to start building. Enter a prompt that describes what you are looking to build. Note that you can connect your prompt to a GitHub repository.
If you have not yet connected your GitHub account to BrainGrid, there are [detailed instructions](github-installation).
Once you enter your prompt that describes your idea, the agent will start thinking and analyzing the codebase (if it exists). It can come back with some clarifying questions to help it understand the requirement better, or ask you if you are comfortable with the plan proposed. Iterate with the agent until you are happy with the plan.
Once you accept the plan, BrainGrid will use the plan to create an EPIC user story. Several requirements are stubbed out that will be used to implement the plan.
In the right frame of BrainGrid, the proposed requirements are listed. Click "Specify" to begin building the specifications around a requirement. BrainGrid will begin building the requirement. It may ask clarifying questions to refine and enhance the requirements.
Once completed, A full requirements document is created that outlines what will be built. You can ask the agent to make changes, clarify things, add or remove details (or you can edit the document manually.)
We are now ready to build!
Before we can build locally, we need to install BrainGrid's Command Line Interface (CLI).
In the local directory of your repository:
```bash
npm install -g @braingrid/cli #install BrainGrid with NPM
braingrid login #login to BrainGrid (a browser tab will open)
braingrid init #initialize the BrainGrid project in your local repository.
```
If you have Claude Code or Cursor installed, you will be prompted to install the BrainGrid integration into those tools. (Claude code shown as an example):
Need more help? Check our detailed [CLI installation guide](/docs/cli/overview).
We are now ready to begin building. If you click the "Start Building" button, you will see detailed instructions for your AI Agent:
Now you're ready to implement your tasks using your AI coding assistant!
In your Agent, follow the instructions from BrainGrid:
You Agent will connect with BrainGrid, read the EPIC and requirement, and begin building!
Congratulations! You've completed the quickstart.
Now you can start building your product with BrainGrid!
## Video Guides [#video-guides]
Check out our complete [Video Guides](/docs/guides/create-project) section for detailed walkthroughs of each step in the BrainGrid workflow.
---
# Security
Source: https://www.braingrid.ai/docs/security
Description: Security and compliance at BrainGrid
At BrainGrid, we understand that our platform is integral to your software development lifecycle. We've built comprehensive security measures to protect your code, requirements, and intellectual property while providing powerful AI-driven development capabilities.
BrainGrid was founded by ex-Twilio engineers experienced in building, operating, and securing large-scale cloud platforms.
## Account Security [#account-security]
* **Passwordless Authentication**: BrainGrid exclusively uses secure, passwordless authentication methods
* **Cloud Provider Sign-In**: Support for Google, GitHub, and Microsoft authentication
* **Magic Links**: Email-based authentication with time-limited secure links
* **Enterprise SSO**: BrainGrid supports Single Sign-On through WorkOS, compatible with providers like Okta, Azure AD, and Google Workspace.
* **Maximum Session Length**: Sessions last up to 30 days with continued activity
* **Inactivity Timeout**: Automatic logout after 7 days of inactivity for security
* **Access Token Duration**: Short-lived 5-minute access tokens minimize exposure risk
* **Secure Token Handling**: All tokens are cryptographically secure and regularly rotated
* **2FA Support**: Time-based One-Time Password (TOTP) support for all accounts
* **SSO MFA**: Inherits MFA policies from your SSO provider
* **Backup Codes**: Generate one-time backup codes for account recovery
* **Enforcement Options**: Organizations can require MFA for all team members
* **Secure Recovery**: Email-based account recovery with time-limited tokens
* **Identity Verification**: Additional verification steps for sensitive account changes
* **Admin Recovery**: Organization admins can assist with team member account recovery
* **Audit Trail**: All recovery attempts are logged.
## Infrastructure Security [#infrastructure-security]
* **Encryption in Transit**: All data transmitted between your browser and BrainGrid servers is encrypted using TLS 1.3
* **Encryption at Rest**: All stored data, including requirements, code analysis results, and agent conversations, is encrypted.
* **Secure Key Management**: Encryption keys are rotated regularly and stored separately from encrypted data
* **Multi-Factor Authentication**: All BrainGrid employees are required to use MFA for accessing production systems
* **Role-Based Access Control**: Strict RBAC policies ensure employees only access systems necessary for their role
* **Audit Logging**: All access to production systems is logged and regularly reviewed
* **Cloud Security**: Our infrastructure runs on Vercel's secure cloud platform with additional security layers
* **Network Isolation**: Production systems are isolated from development and staging environments
* **Regular Security Updates**: All systems receive security patches within 24 hours of release
* **Continuous Monitoring**: 24/7 monitoring for security incidents and anomalies
* **Incident Response**: Engineering team counts on documented incident response procedures
* **Regular Security Audits**: Annual third-party security assessments and penetration testing
## Data Privacy & Intellectual Property [#data-privacy--intellectual-property]
BrainGrid processes different types of data based on your usage:
* **Requirements & Tasks**: Stored securely to enable AI-powered planning and breakdown
* **Code Analysis**: Repository code is analyzed temporarily and deleted immediately after analysis completes - we never store your source code long-term
* **Agent Conversations**: The agent's conversation history is retained for 30 days to improve context and performance
* **Integration Data**: GitHub, Slack, and Linear data is processed according to strict access controls
* **Active Data**: Requirements, tasks, and prompts are retained while your account is active
* **Agent Conversations**: AI chat conversations are automatically deleted after 30 days.
* **Deleted Data**: When you delete data, it's permanently removed from our systems within 30 days
* **Backup Retention**: Encrypted backups are retained for 90 days for disaster recovery
* **Analysis Results**: Code analysis results are cached for 7 days to improve performance
* **Opt-in Only**: Your data is never used for AI model training without explicit consent
* **Anonymization**: If you opt-in, data is fully anonymized before any model improvement use
* **No Code Training**: Your proprietary code is never used for training, regardless of settings
* **Your Output, Your IP**: All requirements, tasks, and documentation generated belong to you
* **No Claims**: BrainGrid makes no intellectual property claims on your generated content
* **Model Usage**: We use Anthropic's Claude and Opus models as well as Google's Gemini models depending on the task.
* **Model Privacy**: We do not store any of your data in our models.
## Integration Security [#integration-security]
* **Minimal Permissions**: We request only necessary GitHub permissions for functionality
* **Token Security**: GitHub tokens are encrypted and never exposed in logs or errors
* **Webhook Validation**: All GitHub webhooks are validated using secure signatures
* **Repository Isolation**: Each repository's data is isolated from others
* **OAuth 2.0**: Secure authentication using Slack's OAuth 2.0 flow
* **Scoped Access**: We only access channels and messages you explicitly connect
* **Message Privacy**: Slack messages are processed temporarily and not stored permanently
* **Encrypted Storage**: Any stored Slack data is encrypted at rest
* **API Key Security**: Linear API keys are encrypted using per-organization keys
* **Sync Controls**: You control which Linear teams and projects sync with BrainGrid
* **Data Minimization**: We only sync necessary fields for requirements and task management
## User Best Practices [#user-best-practices]
* **Always Review AI Output**: While our AI agents are sophisticated, always review generated requirements and tasks
* **Verify Technical Decisions**: Ensure AI-suggested implementations align with your architecture
* **Test Generated Code**: Thoroughly test any code snippets or implementations suggested by AI
* **Use SSO When Available**: Enable Single Sign-On through WorkOS for centralized access control
* **Regular Access Reviews**: Periodically review team member access and permissions
* **Remove Inactive Users**: Promptly remove access for team members who leave
* **Never Share Secrets**: Don't include API keys, passwords, or secrets in requirements or prompts
* **Use Environment Variables**: Reference credentials through environment variables, not directly
* **Rotate Integration Keys**: Regularly rotate API keys for integrated services
* **Avoid Entering Sensitive Data**: Avoid entering sensitive data into the requirements or tasks.
* **Limit AI Access**: For highly sensitive projects, consider limiting AI agent access.
* **Use Branch Protection**: Enable branch protection rules in GitHub for AI-generated PRs
* **Require Reviews**: Always require human review for AI-generated code changes
* **Limit Repository Access**: Only connect repositories that need AI assistance
* **Sandbox Testing**: Test AI-generated code in isolated environments first
## Shared Responsibility Model [#shared-responsibility-model]
Security at BrainGrid follows a shared responsibility model. While we secure the infrastructure and platform, you maintain control over your data and how you use our services.
As a BrainGrid customer, you are responsible for:
**Data & Access Management**
* Determining what data to upload and process through BrainGrid
* Managing user access and permissions within your organization
* Reviewing and approving AI-generated requirements and code
* Maintaining the security of your API keys and integration tokens
**Content Security**
* Ensuring no sensitive data is included in prompts or requirements
* Protecting your source code and intellectual property
* Validating AI outputs before implementation
* Managing environment variables and secrets
**Integration Management**
* Configuring secure connections to GitHub, Slack, and Linear
* Setting appropriate permissions for connected repositories
* Managing which channels and teams have access to BrainGrid
* Regularly reviewing and revoking unused integrations
**Compliance & Best Practices**
* Assessing whether BrainGrid meets your security requirements
* Implementing proper code review processes
* Training team members on secure AI usage
* Monitoring your organization's activity logs
We work together with you on:
**Authentication & Access Control**
* BrainGrid provides SSO and MFA capabilities; you configure and enforce them
* We secure the authentication infrastructure; you manage user policies
**Data Privacy**
* BrainGrid encrypts data; you control what data is processed
**Audit & Monitoring**
* BrainGrid logs platform events.
**Incident Response**
* BrainGrid responds to platform incidents.
* We notify you of breaches.
BrainGrid is responsible for:
**Infrastructure Security**
* Securing our cloud infrastructure and servers
* Maintaining network security and firewall rules
* Applying security patches and updates promptly
* Protecting against DDoS and other attacks
**Platform Security**
* Encrypting data in transit and at rest
* Securing our APIs and web applications
* Maintaining secure development practices
* Regular security testing and audits
**AI Model Security**
* Protecting AI models from manipulation
* Ensuring model outputs are safe and appropriate
* Preventing prompt injection attacks
* Maintaining model performance and reliability
**Operational Security**
* 24/7 monitoring of platform health
* Incident detection and response
* Disaster recovery and backup procedures
* Maintaining compliance certifications
## Where Does My Data Live? [#where-does-my-data-live]
Understanding where your data resides is crucial for compliance and security. BrainGrid uses a modern, distributed infrastructure designed for performance, reliability, and security.
**PostgreSQL Database (Supabase)**
* **Provider**: Supabase - SOC 2 Type II certified
* **Location**: United States
* **What's Stored**: Requirements, tasks, prompts, organization data, user profiles, and integration configurations
* **Encryption**: All data encrypted at rest using AES-256 encryption
* **Backups**: Automated daily backups retained for 90 days
* **Access**: Restricted to authorized BrainGrid services only
* **Compliance**: Hosted on SOC 2 compliant infrastructure
**Redis Cache (Upstash)**
* **Provider**: Upstash - SOC 2 Type II certified
* **Purpose**: Performance optimization and real-time features
* **What's Stored**: Conversation history, rate limiting data, temporary session information
* **Data Lifetime**: Automatically expires based on usage patterns (typically 24-72 hours)
* **Security**: All cached data is encrypted in transit
* **Location**: United States
* **Compliance**: Hosted on SOC 2 compliant infrastructure
**Vercel Blob Storage**
* **Purpose**: Storing large content that doesn't fit efficiently in databases
* **What's Stored**: Prompt markdown files, requirement documentation, generated reports
* **Location**: Distributed across Vercel's global edge network
* **Access Control**: Secure, signed URLs with time-based expiration
* **Location**: United States
**Vercel Platform**
* **Hosting**: Application deployed on Vercel's secure cloud infrastructure
* **Geographic Distribution**: Global edge network for optimal performance
* **Compliance**: SOC 2 Type II certified infrastructure
* **DDoS Protection**: Built-in protection against distributed attacks
**Google Cloud Platform**
* **Services Used**: Cloud Tasks for asynchronous processing
* **Security**: Enterprise-grade security infrastructure
* **Compliance**: SOC 2, ISO 27001, and FedRAMP certified
* **Data Processing**: Temporary processing with immediate deletion of source data
### Data Residency by Region [#data-residency-by-region]
While BrainGrid's infrastructure is globally distributed for performance, we understand the importance of data residency for compliance:
* **United States**: Primary data centers located in US regions
* **European Union**: Data processing compliant with GDPR requirements
* **Data Transfers**: All international data transfers use appropriate safeguards including Standard Contractual Clauses
### Third-Party Sub-processors [#third-party-sub-processors]
BrainGrid uses carefully selected sub-processors to deliver our services:
| Service | Purpose | Data Processed |
| --------- | -------------------- | ------------------------------------------------------------- |
| Anthropic | AI model provider | Requirements, prompts, conversations (not stored by provider) |
| OpenAI | AI model provider | Requirements, prompts, conversations (not stored by provider) |
| WorkOS | Authentication & SSO | User authentication data, organization info |
| Resend | Email delivery | Transactional email content |
| MaxMind | Geolocation | IP addresses for extension tracking |
All sub-processors are bound by data protection agreements and are prohibited from using your data for their own purposes.
## GDPR Compliance [#gdpr-compliance]
The EU General Data Protection Regulation (GDPR) governs the use of personal data in the European Union and United Kingdom. At BrainGrid, we are committed to GDPR compliance and protecting the privacy rights of all our users.
Our GDPR commitments include:
* Implementing appropriate technical and organizational security measures to protect personal data
* Promptly notifying customers of any data breaches that may affect their personal data
* Imposing similar data protection obligations on all our sub-processors and service providers
* Responding to data subject rights requests including access, correction, deletion, and portability
* Using EU Standard Contractual Clauses and UK Addendum for international data transfers
For more information about how we handle your data, please refer to our [Privacy Policy](https://www.braingrid.ai/legal/privacy-policy) and [Data Processing Addendum](https://www.braingrid.ai/legal/dpa).
## Continuous Improvement [#continuous-improvement]
Security at BrainGrid is an ongoing commitment. We continuously:
* Update our security practices based on emerging threats
* Enhance our AI models to better understand security implications
* Expand our compliance certifications
* Improve transparency through regular security updates
Your trust is paramount to us, and we're committed to maintaining the highest security standards as we help accelerate your development workflow.
## Security Contact [#security-contact]
If you discover a security vulnerability or have security concerns:
**Email**: security \[at] our domain name.
**Response Time**: Within 24 hours for critical issues
We take all security reports seriously and will work with you to understand and address any concerns.
---
# What is BrainGrid? AI Planning Platform for Coding Agents
Source: https://www.braingrid.ai/docs/what-is-braingrid
Description: BrainGrid is the AI planning platform that turns Claude Code, Cursor, and other coding agents into reliable teammates. Plan features, break down tasks, and ship faster.
Built for developers by ex-Twilio engineers.
The bottleneck in software development is no longer just the speed of writing code. The bottleneck has shifted to the speed of creating a reliable plan.
BrainGrid is the AI-powered planning platform built to solve this new bottleneck. It's designed to provide the structure and guidance—the "babysitting plan"—that turns powerful but unreliable coding agents into predictable and effective teammates.
Here's how:
* **We Give the Agent a Map:** BrainGrid starts by deeply analyzing your entire codebase—its architecture, data models, and dependencies. It provides the persistent context that agents desperately need but currently lack.
* **We Help You Define the Destination:** Our requirements agent acts like a seasoned tech lead, asking you and your team clarifying questions to transform a high-level idea into a detailed, code-aware specification. No more ambiguity.
* **We Chart the Course, Step-by-Step:** BrainGrid breaks the final requirement down into a series of atomic, verifiable, AI-ready tasks. Each task is a hyper-specific prompt, rich with context and constraints, designed to keep the agent on track and dramatically increase the likelihood of a successful, one-shot execution.
The goal is to get you back to focusing on the hard problems, trusting that the execution of well-defined work is being handled reliably. It's time to trade the babysitting tax for real velocity.
Ready to try it? [Get started](https://www.braingrid.ai) and let's build the toolchain for reliable agentic development.
---
# 2025 Changelog
Source: https://www.braingrid.ai/docs/changelog/2025
Description: Product updates and improvements
## New Features [#new-features]
** The Agent is now branch-aware** - The agent's search, read, and list files tools now respect the selected GitHub branch. No more accidentally reading from main when you're working on a feature branch.
***
** Smart codebase context** - The agent starts with just the codebase summary (\~80% smaller initial context) and fetches Directory Structure, Data Model, Architecture, and Key Workflows on demand. Prevents context overflow on large codebases.
***
** CLI: Create branches** - `braingrid requirement create-branch` creates git branches via GitHub API. Auto-generates branch names in the format `{username}/REQ-123-slugified-name`. No need to manually format branch names.
```bash
braingrid requirement create-branch
```
***
** CLI: Specify tasks** - `braingrid task specify "Add error handling"` creates a single task using AI. Works on requirements that already have tasks. Context-aware: understands existing task dependencies.
```bash
braingrid task specify "Add error handling"
```
***
** CLI: Review PRs** - `braingrid requirement review` streams AI-powered acceptance reviews. Auto-detects PR from current branch. Falls back to interactive prompt if no PR found.
```bash
braingrid requirement review
```
***
## Improvements [#improvements]
* **Circular context indicator** - New circular indicator replaces horizontal progress bar. Hover shows token breakdown by category.
* **CLI: Task auto-detection** - `task show` and `task update` work without task ID. Uses first in-progress or planned task.
* **CLI: Claude Code status line shows current task** - Status line now shows: `PROJ-X > REQ-Y > TASK-Z [completed/total]` with git branch.
* **CLI: Update notifications** - Warns when newer version available with interactive update prompt.
* **CLI: Shell tab completion** - Run `braingrid completion --setup` for bash/zsh autocomplete.
* **CLI: Requirement auto-detection for tasks** - Task commands detect requirement from branch name (e.g., `feature/REQ-123-something`).
* **CLI: Format options** - `--format json|xml|markdown|table` for `requirement show` and `task show`.
***
## Fixes [#fixes]
* **Filter documents by branch** - Analysis documents now filter correctly by branch.
* **Repository renamed handling** - When you rename a repo on GitHub, BrainGrid updates automatically.
* **Editor overflow** - Fixed content overflow in requirement editor.
* **Cleaner requirement UI** - Removed metadata clutter and moved title to header.
***
## New Features [#new-features-1]
** Message actions & feedback** - Take control of your conversations with the agent:
* **Copy** any message to clipboard with one click
* **Edit** any of your messages (not just the most recent)
* **Delete** user messages to continue the conversation from that point
* **Rate responses** with thumbs up/down for better feedback
Agent message actions appear on the last message in each group, keeping the interface clean while giving you control when you need it.
Useful when:
* You want to go back to a previous point in the conversation. You can delete the message and start over from there.
* You want to tweak a message you sent earlier.
You can edit the message and start over from there.
***
** Connect repository to existing projects** - Link a GitHub repository to projects you've already created. Previously, you had to delete and recreate a project to add repo integration. Now:
* Go to project settings to connect a repository
* Automatic code analysis starts when you connect
* Repository becomes read-only once linked (prevents accidental changes)
***
## Improvements [#improvements-1]
* **Type while agent streams** - The input box stays enabled while the agent is thinking or streaming a response. Compose your next message while waiting instead of watching the agent work.
* **MCP tool improvements** - Added task deletion tool and git branch creation tool to the MCP server. The server now requires `project_id` explicitly for better clarity in server mode deployments.
* **Smarter task dependency validation** - Circular dependencies are now detected before saving, and cancelled tasks no longer incorrectly block other tasks from being updated.
***
## Fixes [#fixes-1]
* **Race condition in requirement updates** - Fixed 500 errors when a requirement was deleted while being updated. Now returns a proper 404 with a helpful message.
* **Consistent error responses** - Fixed cases where missing requirements returned 500 instead of 404, making it easier to understand what went wrong.
* **CLI skill installation** - Fixed issue where Claude Code skills were installed to a nested directory instead of the correct flat structure.
* **CLI organization ID** - Fixed issue where `.braingrid/project.json` stored "default" instead of the actual organization UUID, which could cause authentication issues.
***
## New Features [#new-features-2]
**GitHub branch-aware code reading** - The agent can now read code from any branch, not just main:
* Read files from specific branches, tags, or commits
* Compare implementations across releases
* Reference code from feature branches
* Example: "Show me auth.ts from the feature/auth-improvements branch"
***
## Improvements [#improvements-2]
* **Better Accept/Reject UI for accepting edits** - Improved bottom bar in the agent UI, making it easier to accept or reject edits.
* **Branch selector in workflows** - Added branch selector to the new requirement workflows to easily provide the right branch as context.
***
## Fixes [#fixes-2]
* **Task update errors** - Fixed 500 errors when updating tasks in unfunded organizations - now returns proper 402 payment required status.
* **GitHub avatar display** - Fixed GitHub avatar in integrations page.
***
## New Features [#new-features-3]
**AI Implementation plan review** - The "Review implementation plan" action now appears when tasks exist. This review takes a second look at the tasks and makes sure:
* Tasks fully cover the requirement
* Tasks are complete and ready to be implemented
* Implementation is architecturally sound.
***
## Improvements [#improvements-3]
* **Streaming AI responses** - The thinking tool now streams responses in real-time. Watch the agent's reasoning unfold as it happens instead of waiting for the complete response.
***
## Fixes [#fixes-3]
* **Invite links in Apple Mail** - Fixed critical bug where Apple Mail was breaking invite links.
* **MCP dependency validation** - When task dependencies block completion, you now get helpful error messages instead of cryptic 500 errors. Shows exactly which tasks need completion first with proper HTTP 409 Conflict status and clear resolution steps.
* **Repository dropdown display** - Fixed visual issues with repository selection, making repository names clearer and selection smoother.
***
## New Features [#new-features-4]
** AI Feature & Bug Fix Recommendations** - You now get AI-powered recommendations on what to build next. BrainGrid will recommend features, bug fixes, ideas, and deep dives to learn about your codebase, including:
* "Did you know" insights about your codebase
* Features mapped to customer value
* Bug fixes affecting the user experience
* Ideas to brainstorm and explore
***
** Complete build workflow guide** - New Build tab provides an 8-step development flow from setup through deployment:
* Step-by-step instructions for opening AI agents (Claude Code, Cursor, etc.)
* Git commands with copy buttons for branching, committing, and pushing
* BrainGrid MCP integration guidance with official documentation links
* Dynamic content using your actual requirement IDs, titles, and branch names
* Acceptance criteria validation and deployment checklists
* Works for both technical and non-technical team members
***
## Improvements [#improvements-4]
* **Smarter idea agent** - Idea agent now suggests the simplest implementation first, to prevent over-engineering. Emphasizes code reuse and progressive complexity - build the MVP, then add features when needed.
***
## Fixes [#fixes-4]
* **Better analysis status visibility** - Fixed color contrast issues in analysis status indicators for better readability in both light and dark modes. Status colors now use semantic design tokens that adapt to your theme.
***
## New Features [#new-features-5]
** Ideas workflow** - Not every requirement is ready to build immediately. The new Ideas status and dedicated Ideas tab give you a space to capture possibilities before committing to development:
* Collect feature concepts and user requests as Ideas
* Validate the technical feasibility of the idea
* Refine and discuss them before they hit your backlog
* Move to Backlog when ready to build
* Keep your active backlog focused on ready-to-build work
→ Click on a [Project](https://braingrid.link/app), then go to the "Ideas" tab to create your first idea.
***
** Requirement mentions** - Reference specific requirements using `@` syntax to bring another requirement into context:
* Type `@` followed by requirement ID or name in agent chat
* Useful when breaking down large features into smaller requirements
* Useful when a new requirement depends on another one that is not yet built
→ Click on a [Project](https://braingrid.link/app), create a new requirement, and use the `@` syntax to mention another requirement.
***
** Project deletion** - Clean up old projects or remove test data safely:
* Organization owners can delete projects from settings
* GitHub-style "Danger Zone" shows exactly what will be deleted
* Preview includes requirements, tasks, and other project data
* Must type project name to confirm deletion
* Prevents accidental deletions while giving you control
***
## Improvements [#improvements-5]
** Automatic code analysis** - Creating a new project with a repository? Code analysis now starts automatically in the background. Within a few minutes, you'll have architecture summaries, directory structures, and other analysis documents available without manually triggering the analysis. This saves a step and ensures your project documentation is ready when you need it.
***
## New Features [#new-features-6]
** Projects** - Requirements now automatically organize into projects based on your repositories:
* Each repository gets its own project with sequential IDs (PROJ-1, PROJ-2, etc.)
* Easy to identify work by codebase at a glance
* Requirements without a repo link go to your organization's default project
* Project pages show only relevant requirements for that repository
* No more manual filtering or searching through unrelated work
→ Create your first [Project](https://braingrid.link/app).
***
** Bulk operations** - Select multiple requirements and update them together instead of one-by-one:
* Change status of 10 items from "Planned" to "In Progress" at once
* Assign a batch of requirements to the same person
* Move a group to a different project
* Update tags or other properties across multiple items
* Smart confirmation dialogs show exactly what's changing before you commit
***
## New Features [#new-features-7]
** GitHub code search** - Large codebases often have similar patterns implemented multiple times. The agent can now search across your GitHub repositories to find existing implementations, helping you maintain consistency and avoid reinventing solutions. Need to see how authentication is handled elsewhere? Search for "auth token" to find all the relevant code. Includes language filtering so you can narrow results to Python when working on Python features. The search respects GitHub's rate limits with smart retry logic.
***
** Branch-specific file reading** - Sometimes you need to see how code worked in a previous release, or compare implementations across branches. The agent's GitHub file tools now accept a `ref` parameter, letting you read files from any branch, tag, or commit - not just the default branch. Want to see how authentication worked in release v1.2? Just specify the tag. This works with both authenticated repositories and public repos you have access to.
***
## Improvements [#improvements-6]
** 400k context window** - The context window is now 400k tokens, up from 200k. Think of the context window like the agent's working memory - it's how much information it can consider at once. Doubling this means the agent can handle much larger codebases and longer conversations without losing track of earlier context. You'll especially notice this when working with monorepos or having extended back-and-forth discussions about complex requirements. The agent maintains full awareness of your entire conversation history and codebase structure.
***
## Improvements [#improvements-7]
** Precise requirement editing** - The agent can now make surgical edits to your requirements with the new `update_requirement` tool. Instead of rewriting entire documents, it makes targeted line-by-line changes and shows exactly what changed: "Successfully made 3 changes" or "No changes made."
***
** Cleaner question flow** - When the agent generates clarifying questions, it now stops right there instead of continuing. Makes the conversation feel more natural when gathering requirements.
***
## New Features [#new-features-8]
** AI-powered PR acceptance reviews** - An easy way to know if the agent is done. The new [MCP tool](https://docs.braingrid.ai/mcp-server/usage#acceptance-review-on-a-pull-request) validates pull requests against a requirement's acceptance criteria to know if it is done done.
***
## New Features [#new-features-9]
** Smart file summarization** - BrainGrid now intelligently summarizes the files it reads. It is great to learn what a specific file does and what are the key parts and integration points. Just click the "Show more" any time the agent reads a file.
***
** Massive performance boost for code analysis** - We spent a week making analysis 10x faster.
***
## Improvements [#improvements-8]
** Repository dropdown that makes sense** - Full repo names visible (`owner/repo`) for easier repository identification.
***
## New Features [#new-features-10]
** Multiple GitHub organizations** - Connect up to 5 GitHub orgs to one BrainGrid account.
***
** Redesigned feedback page** - New streamlined feedback form for easier submission.
***
** Dedicated Agent integrations page** - All your integrations now live in their own space. Less clutter, more focus.
***
## Improvements [#improvements-9]
** Tool error recovery** - Tools that fail now gracefully recover and retry automatically.
***
## New Features [#new-features-11]
** Requirement validation tool** - New MCP tool validates requirements against their acceptance criteria. Catch issues before they become problems.
***
## Improvements [#improvements-10]
** Instant tool feedback** - Agent tool cards now appear immediately instead of after processing.
***
** Web page caching** - Repeated webpage reads are now cached for 10x faster performance.
***
## New Features [#new-features-12]
** Web search** - BrainGrid can now search the internet for current information. Documentation moved? API changed? No problem - we'll find the latest.
***
** Read any webpage** - Give BrainGrid a URL and it extracts the content, understands it, and uses it in your requirements.
***
## Improvements [#improvements-11]
** Workflow-aware requirements** - BrainGrid now understands whether you are creating requirements from scratch, refining an existing requirements doc, or breaking an existing requirement into tasks.
***
## New Features [#new-features-13]
** Image support** - You can now share screenshots, designs, and diagrams with the BrainGrid agent for more visual collaboration.
***
** Refine existing PRDs** - Upload your existing PRDs in markdown format to enhance them and get them AI-ready before you start building.
***
** Smart context compaction** - Long conversations with large repos now use intelligent context management, so the agent maintains performance without running out of context window.
***
## Improvements [#improvements-12]
** Faster code analysis** - Code analysis now runs 2-5x faster, making a huge difference for large repositories. Your feedback helped us optimize this!
***
** Reasoning agent** - BrainGrid now shows its "thinking" process, making it more transparent and capable of handling complex planning and specification challenges.
---
# 2026 Changelog
Source: https://www.braingrid.ai/docs/changelog/2026
Description: Product updates and improvements
## The docs moved to braingrid.ai/docs [#the-docs-moved-to-braingridaidocs]
Same guides, same changelog, now on the main site with full-text search, a dark mode, and mobile navigation that works. Old `docs.braingrid.ai` links redirect to their new home. The one exception is the API reference, which is temporarily unavailable while we rebuild it — those URLs redirect to the CLI overview for now.
Every page also has a plain-markdown twin at `.md` — try [/docs/quickstart.md](/docs/quickstart.md) — so Claude Code, Cursor, and any other agent can read the docs directly.
** New Build experience** — Coding agents can now build entire requirements, so we replaced the Tasks tab with a new Build workflow. Choose your agent (Claude Code, Cursor, MCP, or copy-paste), paste one command, and go. Agents create tasks in BrainGrid as they work — serving as a record of what happened so you can resume builds without losing progress. Build and Plan tabs are now bookmarkable via `?tab=build` and `?tab=plan`.
[Try the Build tab →](https://app.braingrid.ai?utm_source=changelog\&utm_medium=content\&utm_campaign=build_tab)
***
## New Features [#new-features]
** Base Branch Setting** - Configure which branch new requirement branches are based on. Set it once in Project Settings → Advanced, and every new branch starts from the right place. The setting shows your repository's default branch automatically when no custom branch has been saved.
***
## Improvements [#improvements]
* **Cleaner credit display** - Organization and total credit balances now show a single number (e.g., "99,018") instead of a redundant fraction ("99,018 / 99,018").
***
## Fixes [#fixes]
* **Completed requirement badge** - Requirements already marked as completed no longer show a misleading "In Review" pill in the build tab.
* **Agent input overflow** - Long repository names in the agent pane are now truncated with ellipsis instead of breaking the layout when resizing.
* **Branch creation conflicts** - Creating a branch that already exists now returns a clear 409 conflict instead of a 500 server error.
## Designs [#designs]
Create visual designs from a prompt, tied to your requirements. See what you are building before you build it.
[Try Designs →](https://app.braingrid.ai/designs?utm_source=changelog\&utm_medium=content\&utm_campaign=designs) · [Read the blog post →](https://www.braingrid.ai/blog/introducing-designs)
***
** Desktop and Mobile Views** - Switch between desktop and mobile boards to see your designs at every screen size before writing code.
***
** Chat-Based Iteration** - Talk to the design agent to iterate on your designs. Try different directions, refine layouts, and get it right through conversation.
***
** Annotations** - Select parts of the design you want to change. Draw annotations and highlight elements — the agent sees exactly what you mean.
***
** Element Selection** - Pick individual components from your design and send them to the agent for precise, targeted changes.
## AI Product Planner Agent [#ai-product-planner-agent]
Structure your ideas before you build. Turn scattered thinking into organized epics and requirements that AI coding tools can execute reliably.
[Try AI Product Planner →](https://app.braingrid.ai/projects/new?utm_source=changelog\&utm_medium=content\&utm_campaign=ai_product_planner)
***
** AI-Guided Specification** - A planning agent asks clarifying questions to refine vague ideas into buildable requirements. Covers scope, edge cases, constraints, and acceptance criteria.
***
** Readiness Scoring** - Each requirement receives an AI-evaluated score from 1 to 5. Know what is ready to build and what still needs work before handing off to your coding agent.
***
** Dependency Management** - See what is blocked and what is blocking it. AI Product Planner sets dependencies automatically so you build in the right order.
***
** Coding Agent Handoff** - Send structured tasks to Claude Code, Cursor, or your favorite coding agent via MCP, CLI, or copy-paste. Each task includes all the context needed to build it correctly.
## New Features [#new-features-1]
** File Attachments in Planning** - Upload files directly in the Product Planning Agent chat. Share mockups, specs, or reference documents so the agent has full context when refining your requirements.
** Feature Requests** - Submit product ideas, vote on others' requests, and track what the community wants. Feature request titles are auto-generated from your description, and you get a confirmation email when you submit.
** Change Repository in Settings** - Switch which GitHub repository is linked to your project directly from Project Settings — no need to recreate the project.
** Sonnet 4.6** - The default AI model has been upgraded from Claude Sonnet 4.5 to Sonnet 4.6 across the entire platform — planning, specification, and all agent conversations.
** Cost Tier Badges** - Model selection cards now show relative cost indicators (`$` through `$$$$$`) next to each model name, so you can see the trade-off between capability and cost at a glance.
** Epics API (v1)** - Full CRUD for epics under the `/v1/projects` scope. Requirement and epic API responses now include a `url` field linking directly to the resource in the app.
** CLI: Parallel Build Mode** - The `/build` command can now spawn agent teams for concurrent task implementation. Multiple tasks build simultaneously instead of one at a time.
** CLI: Frontend Design & UX Skills** - Two new skills ship with `braingrid setup claude-code`: a frontend design skill with design system references (color, typography, spacing, accessibility) and a UX skill covering patterns for forms, navigation, search, feedback, and more.
## Improvements [#improvements-1]
* **Smarter context recovery** - When you hit the context limit, the "start a new chat" banner now preserves your requirement and artifact context instead of starting a blank conversation.
* **Value-first requirement ordering** - The planning agent now bundles infrastructure (auth, payments, notifications) into single requirements and prioritizes user-facing features in execution order.
* **Improved onboarding** - Requirement descriptions are more concise, wireframes appear before user stories, and the editor auto-accepts content instead of showing an empty diff view.
* **Instant credit allocation** - Credits are allocated immediately when you upgrade your plan, instead of waiting for the next billing cycle.
* **Codebase summaries include file paths** - Generated codebase summaries now serve as a navigable index with key file paths per section, not just descriptions.
* **CLI: SSH URL support** - `.braingrid/project.json` now accepts SSH git remote URLs (`git@github.com:...`), not just HTTPS.
***
## Fixes [#fixes-1]
* **Git branch creation for OAuth-only users** - Creating branches no longer fails with a 500 error for users who connected via personal OAuth instead of the GitHub App.
* **Requirement creation deadlock** - Concurrent requirement creation across different projects no longer causes database deadlocks.
* **Billing page for trial users** - The upgrade button now shows correctly on the billing page for users on the trial plan.
* **BYOK rate limit handling** - Mid-stream rate limits from bring-your-own-key API providers are now caught and surfaced with a clear error message.
* **Archived account credit balance** - Archived user accounts no longer inflate organization credit totals, preventing phantom balances.
## New Features [#new-features-2]
** Personal GitHub OAuth** - Connect your personal GitHub account without installing the GitHub App. BrainGrid tries your personal connection first, then your org's GitHub App, then public access—so you always get the best available access. Perfect for personal repos or orgs where you can't install apps.
Find it in Settings → Integrations → Connect GitHub Account.
***
** Epic hierarchy** - Organize requirements into epics with parent-child relationships:
* Group related requirements under an epic
* Add dependencies between requirements (Requirement A blocks Requirement B)
* View execution order—BrainGrid automatically determines the right order based on dependencies
* Status gates prevent starting blocked requirements until dependencies complete
* Max 20 dependencies per requirement, with warnings if requirements would block each other in a loop
***
** Requirements filter bar** - Find requirements faster with new filter dropdowns:
* Filter by status (Planned, In Progress, Review, etc.)
* Filter by assignee
* Filter by tags
* Search by title or description
* Filters persist in URL—bookmark filtered views or share with teammates
***
** Clarifying questions redesign** - The survey experience got a major upgrade:
* Click any option label to add inline clarifications
* Agent messages now display formatted text properly (headings, tables, code, and quotes)
* Auto-scrolls to bottom when the agent starts thinking
* Cleaner checkbox and multiple-choice styling
***
** Paste images anywhere** - Cmd+V (Mac) or Ctrl+V (Windows/Linux) now works in both the agent chat and requirement forms. Paste screenshots directly from your clipboard—no more saving files first.
***
** CLI: Tag management** - Manage requirement tags from the command line:
```bash
braingrid requirement tag add REQ-123 --name "urgent" --color "#FF0000"
braingrid requirement tag list REQ-123
braingrid requirement tag remove REQ-123 --name "urgent"
```
***
** CLI: API token authentication** - Use `BRAINGRID_API_TOKEN` environment variable for CI/CD pipelines and sandbox environments. No interactive OAuth needed.
***
## Improvements [#improvements-2]
* **Refined dark mode** - New dark palette with deeper blacks, cleaner whites, and subtler borders. The agent chat, sidebar, and cards all feel more cohesive.
* **Unified Plan view** - Ideas tab is gone. Ideas now live in the main Plan tab alongside your other requirements.
* **More reliable AI responses** - Agent tools are now more robust, so you'll see fewer errors and retries.
* **Onboarding simplified** - After completing onboarding, you go straight to the project agent instead of creating a requirement first.
* **Settings navigation** - Dropdown now shows Billing, Team, API Keys, Organization, and Integrations directly instead of a generic "Settings" link.
* **Smarter context detection** - The agent knows whether you have an epic or requirement selected and uses the right tools automatically.
* **Inline requirement creation** - Create requirements directly in the Plan view with keyboard navigation (Tab, Enter, Escape).
* **Smarter breakdown button** - The "Breakdown into tasks" button only shows when the agent has task creation capabilities.
***
## Fixes [#fixes-2]
* **Branch selection in documents** - Code analysis documents now correctly show content from your selected branch, not just the latest analyzed revision.
* **File attachments in epics** - File uploads now work in epic workflow chats, not just requirement chats.
* **Image upload limit** - Images over 5MB are rejected before upload with a clear error message (Anthropic API limit).
* **Organization name validation** - Fixed false "name unavailable" error when saving an organization name that was already yours.
* **User initials in chat** - Your messages now show your actual initials instead of "U".
* **Tool call recovery** - When something goes wrong with agent tools, you now see a helpful error message instead of a generic failure.
---
# Command Reference
Source: https://www.braingrid.ai/docs/cli/commands
Description: Complete reference for all BrainGrid CLI commands
## Authentication Commands [#authentication-commands]
### login [#login]
Authenticate with your BrainGrid account using OAuth2.
```bash
braingrid login
```
Opens your browser for authentication. Once complete, your credentials are stored locally.
### whoami [#whoami]
Display information about the currently authenticated user.
```bash
braingrid whoami
```
Shows your username, email, and account details.
### logout [#logout]
Sign out from your BrainGrid account.
```bash
braingrid logout
```
Removes stored authentication credentials from your local machine.
## Initialization Commands [#initialization-commands]
### init [#init]
Initialize a BrainGrid project in the current directory.
```bash
# Interactive wizard
braingrid init
# Specify project directly
braingrid init --project PROJ-123
# Skip confirmation prompts
braingrid init --force
```
Creates a `.braingrid/project.json` file linking your local directory to a BrainGrid project.
**Options:**
* `--project ` - Specify the project ID to link
* `--force` - Skip confirmation prompts
## Project Commands [#project-commands]
### project list [#project-list]
List all accessible projects.
```bash
# Default table format
braingrid project list
# JSON format with pagination
braingrid project list --format json --page 1 --limit 20
```
**Options:**
* `--format ` - Output format: `table`, `json`, `xml`, `markdown`
* `--page ` - Page number for pagination (default: 1)
* `--limit ` - Results per page (default: 20)
### project show [#project-show]
Display details for a specific project.
```bash
# Show initialized project
braingrid project show
# Show specific project by ID
braingrid project show PROJ-123
# Show project by repository
braingrid project show --repository "owner/repo"
```
**Options:**
* `--repository ` - GitHub repository in format "owner/name"
### project create [#project-create]
Create a new project.
```bash
braingrid project create --name "My Project" \
--description "Project description" \
--repository "owner/repo-name"
```
**Options:**
* `--name ` - Project name (required)
* `--description ` - Project description (optional)
* `--repository ` - GitHub repository (optional)
### project update [#project-update]
Update an existing project.
```bash
# Update project name
braingrid project update PROJ-123 --name "New Name"
# Update description
braingrid project update PROJ-123 --description "Updated description"
```
**Options:**
* `--name ` - New project name
* `--description ` - New project description
### project delete [#project-delete]
Delete a project.
```bash
# With confirmation prompt
braingrid project delete PROJ-123
# Skip confirmation
braingrid project delete PROJ-123 --force
```
**Options:**
* `--force` - Skip confirmation prompt
Deleting a project also deletes all associated requirements and tasks. This action cannot be undone.
## Requirement Commands [#requirement-commands]
### specify [#specify]
Create an AI-refined requirement from a natural language prompt.
```bash
# Create requirement in current project
braingrid specify --prompt "Add user authentication with OAuth2"
# Create in specific project
braingrid specify -p PROJ-123 --prompt "Implement dark mode toggle"
# JSON output for scripting
braingrid specify --prompt "Add email notifications" --format json
```
**Options:**
* `-p, --project ` - Target project (defaults to initialized project)
* `--prompt ` - Natural language description (required)
* `--format ` - Output format: `table`, `json`, `xml`, `markdown`
The `specify` command uses AI to refine your prompt into a structured requirement with clear scope, acceptance criteria, and technical considerations.
### requirement list [#requirement-list]
List all requirements in a project.
```bash
# List all requirements
braingrid requirement list
# Filter by status
braingrid requirement list --status IN_PROGRESS
# JSON format
braingrid requirement list --format json
```
**Options:**
* `--status ` - Filter by status: `IDEA`, `PLANNED`, `IN_PROGRESS`, `REVIEW`, `COMPLETED`, `CANCELLED`
* `--format ` - Output format: `table`, `json`, `xml`, `markdown`
### requirement show [#requirement-show]
Display details for a specific requirement.
```bash
# Auto-detect from git branch (e.g., feature/REQ-123-auth)
braingrid requirement show
# Show specific requirement
braingrid requirement show REQ-123
# JSON format for scripting
braingrid requirement show REQ-123 --format json
```
**Options:**
* `--format ` - Output format: `table`, `json`, `xml`, `markdown`
### requirement create [#requirement-create]
Manually create a requirement without AI refinement.
```bash
braingrid requirement create --name "Implement feature X" \
--content "Detailed description here"
```
**Options:**
* `--name ` - Requirement name (required)
* `--content ` - Detailed description (optional)
### requirement update [#requirement-update]
Update an existing requirement.
```bash
# Update status
braingrid requirement update REQ-123 --status IN_PROGRESS
# Update name
braingrid requirement update REQ-123 --name "Updated Name"
# Update content
braingrid requirement update REQ-123 --content "New description"
```
**Options:**
* `--status ` - New status
* `--name ` - New name
* `--content ` - New content
### requirement delete [#requirement-delete]
Delete a requirement and all associated tasks.
```bash
# With confirmation prompt
braingrid requirement delete REQ-123
# Skip confirmation
braingrid requirement delete REQ-123 --force
```
**Options:**
* `--force` - Skip confirmation prompt
### requirement build [#requirement-build]
Generate a complete implementation plan with all task details.
```bash
# Markdown format (default, perfect for AI agents)
braingrid requirement build REQ-123
# JSON format for tooling
braingrid requirement build REQ-123 --format json
# Auto-detect requirement from branch
braingrid requirement build --format markdown
```
**Options:**
* `--format ` - Output format: `markdown`, `json`, `xml`
### requirement create-branch [#requirement-create-branch]
Create a git branch for a requirement via the GitHub API.
```bash
# Auto-detect requirement from current context
braingrid requirement create-branch
# Create branch for specific requirement
braingrid requirement create-branch REQ-123
```
Automatically generates branch names in the format `{username}/REQ-123-slugified-name` and creates the branch on GitHub.
This command requires a GitHub repository to be linked to your project. The branch is created remotely via the GitHub API.
### requirement review [#requirement-review]
Stream an AI-powered acceptance review for a pull request.
```bash
# Auto-detect PR from current branch
braingrid requirement review
# Review specific requirement
braingrid requirement review REQ-123
```
Analyzes your pull request against the requirement's acceptance criteria and provides detailed feedback. If no PR is found for the current branch, you'll be prompted to select one interactively.
## Task Commands [#task-commands]
### task list [#task-list]
List all tasks for a requirement.
```bash
# Auto-detect requirement from git branch
braingrid task list
# List tasks for specific requirement
braingrid task list -r REQ-123
# Markdown format for AI context
braingrid task list -r REQ-123 --format markdown
# JSON for scripting
braingrid task list -r REQ-123 --format json
```
**Options:**
* `-r, --requirement ` - Requirement ID (auto-detected from branch if not specified)
* `--format ` - Output format: `table`, `json`, `xml`, `markdown`
### task show [#task-show]
Display details for a specific task.
```bash
# Auto-detect first in-progress or planned task
braingrid task show
# Show specific task
braingrid task show TASK-456
# JSON format for scripting
braingrid task show TASK-456 --format json
```
**Options:**
* `--format ` - Output format: `table`, `json`, `xml`, `markdown`
When called without a task ID, shows the first in-progress task. If none are in progress, shows the first planned task.
### task create [#task-create]
Manually create a task.
```bash
braingrid task create -r REQ-123 \
--title "Implement OAuth2 login flow" \
--content "Create login endpoint and integrate with provider"
```
**Options:**
* `-r, --requirement ` - Parent requirement ID (required)
* `--title ` - Task title (required)
* `--content ` - Task description (optional)
### task update [#task-update]
Update a task's status, title, or content.
```bash
# Auto-detect current task and update status
braingrid task update --status COMPLETED
# Update specific task status
braingrid task update TASK-456 --status COMPLETED
# Update title
braingrid task update TASK-456 --title "New title"
# Update content
braingrid task update TASK-456 --content "Updated description"
```
**Options:**
* `--status ` - New status: `PLANNED`, `IN_PROGRESS`, `COMPLETED`, `CANCELLED`
* `--title ` - New title
* `--content ` - New content
When called without a task ID, updates the first in-progress task. If none are in progress, updates the first planned task.
### task delete [#task-delete]
Delete a task.
```bash
# With confirmation prompt
braingrid task delete TASK-456
# Skip confirmation
braingrid task delete TASK-456 --force
```
**Options:**
* `--force` - Skip confirmation prompt
### task specify [#task-specify]
Create a single AI-refined task from a description.
```bash
# Create task with AI refinement
braingrid task specify "Add input validation for email field"
# Specify for a specific requirement
braingrid task specify -r REQ-123 "Implement rate limiting on API endpoints"
```
**Options:**
* `-r, --requirement ` - Parent requirement ID (auto-detected from branch if not specified)
The `task specify` command creates individual tasks with AI refinement. It's context-aware and understands existing task dependencies when adding to a requirement that already has tasks.
## Utility Commands [#utility-commands]
### status [#status]
Display CLI configuration and status.
```bash
braingrid status
```
Shows authentication status, current project, CLI version, and configuration details.
### update [#update]
Update the CLI to the latest version.
```bash
# Check for updates and install
braingrid update
# Check for updates without installing
braingrid update --check
```
**Options:**
* `--check` - Only check for updates, don't install
### completion [#completion]
Set up shell autocompletion for the CLI.
```bash
# Interactive setup (recommended)
braingrid completion --setup
```
This adds autocompletion to your shell configuration. After setup, restart your terminal or source your config file.
**Manual setup:**
```bash Bash
# Add to ~/.bashrc
eval "$(braingrid completion bash)"
```
```bash Zsh
# Add to ~/.zshrc
eval "$(braingrid completion zsh)"
```
### --version [#--version]
Display the CLI version.
```bash
braingrid --version
```
### --help [#--help]
Display help information.
```bash
# General help
braingrid --help
# Command-specific help
braingrid project --help
braingrid requirement build --help
```
## Status Flows [#status-flows]
### Requirement Status Flow [#requirement-status-flow]
Requirements progress through the following states:
```
IDEA → PLANNED → IN_PROGRESS → REVIEW → COMPLETED
↓
CANCELLED
```
* **IDEA** - Initial concept or feature request
* **PLANNED** - Refined and ready for implementation
* **IN\_PROGRESS** - Active development
* **REVIEW** - Under review or testing
* **COMPLETED** - Successfully implemented
* **CANCELLED** - No longer needed
### Task Status Flow [#task-status-flow]
Tasks have a simpler workflow:
```
PLANNED → IN_PROGRESS → COMPLETED
↓
CANCELLED
```
* **PLANNED** - Ready to be worked on
* **IN\_PROGRESS** - Currently being implemented
* **COMPLETED** - Successfully finished
* **CANCELLED** - No longer needed
## Flexible ID Formats [#flexible-id-formats]
All commands accept multiple ID formats for convenience:
* **Canonical**: `REQ-456`, `TASK-123`, `PROJ-789`
* **Lowercase**: `req-456`, `task-123`, `proj-789`
* **Numeric**: `456`, `123`, `789`
* **UUID**: Full UUID strings
Examples:
```bash
# All of these are equivalent
braingrid requirement show REQ-123
braingrid requirement show req-123
braingrid requirement show 123
braingrid requirement show 550e8400-e29b-41d4-a716-446655440000
```
## Output Formats [#output-formats]
Most commands support multiple output formats:
### Table (Default) [#table-default]
Human-readable ASCII tables for terminal viewing.
```bash
braingrid project list
```
### JSON [#json]
Machine-readable format for scripting and automation.
```bash
braingrid project list --format json
```
### XML [#xml]
Structured data for enterprise integrations.
```bash
braingrid project list --format xml
```
### Markdown [#markdown]
Rich formatted output optimized for AI agents and documentation.
```bash
braingrid task list -r REQ-123 --format markdown
```
Use markdown format when providing task context to AI coding agents. It includes all necessary details in a format that's easy for AI to parse and understand.
## Common Patterns [#common-patterns]
### Complete Feature Development Workflow [#complete-feature-development-workflow]
```bash
# 1. Create and refine requirement
braingrid specify --prompt "Add payment integration with Stripe"
# → Creates REQ-42
# 2. Create feature branch via GitHub API
braingrid requirement create-branch REQ-42
# → Creates nico/REQ-42-stripe-integration
# 4. Check out the branch locally
git fetch && git checkout nico/REQ-42-stripe-integration
# 5. Get full context for AI agent
braingrid requirement build --format markdown
# 6. Work through tasks (auto-detects current task)
braingrid task update --status IN_PROGRESS
# ... implement task ...
braingrid task update --status COMPLETED
# 7. Create PR and get AI review
braingrid requirement review
```
### Quick Status Check [#quick-status-check]
```bash
# Check your current context
braingrid status
# View current requirement (from branch)
braingrid requirement show
# List remaining tasks
braingrid task list -r REQ-42
```
### CI/CD Integration [#cicd-integration]
```bash
# Get requirement data in CI pipeline
REQ_DATA=$(braingrid requirement show REQ-42 --format json)
# List completed tasks for release notes
braingrid task list -r REQ-42 --format markdown > RELEASE_NOTES.md
```
---
# CLI
Source: https://www.braingrid.ai/docs/cli/overview
Description: The power of BrainGrid in your terminal
Manage projects, requirements, and tasks from your terminal.
Common use cases:
* **Fetch a requirement's tasks** - Get the tasks for a requirement for your coding agent to implement.
* **Save agent plans** - Save your coding agent's plans to share and implement later.
* **Refine vague ideas** - Transform rough concepts into clear, actionable requirements with AI assistance.
## Installation [#installation]
Install the BrainGrid CLI globally using npm:
```bash
npm install -g @braingrid/cli
```
## Authentication [#authentication]
Before using the CLI, authenticate with your BrainGrid account:
```bash
braingrid login
```
## Quick Start: One-Minute Flow [#quick-start-one-minute-flow]
Get started with BrainGrid in four simple steps:
Initialize your project with BrainGrid:
```bash
braingrid init
```
Create a requirement with AI refinement:
```bash
braingrid specify --prompt "Add user authentication with OAuth2"
```
Get complete implementation plan:
```bash
braingrid requirement build REQ-1
```
The CLI automatically detects your current project from `.braingrid/project.json` and can extract requirement IDs from your git branch names (e.g., `feature/REQ-123-auth`).
## AI Coding Integration [#ai-coding-integration]
BrainGrid CLI integrates seamlessly with AI coding tools:
Skills and slash commands for Claude Code.
Rules and slash commands for Cursor.
## Typical Workflow [#typical-workflow]
Here's how BrainGrid CLI fits into your development process:
1. **Capture Ideas** - Use `braingrid specify` to refine vague ideas into structured requirements
2. **Build Features** - Create a git branch and let your AI agent work through tasks
3. **Track Progress** - Update task status with `braingrid task update` as you complete work
## Auto-Detection Features [#auto-detection-features]
The CLI includes smart auto-detection to minimize typing:
* **Project Detection** - Automatically finds project from `.braingrid/project.json`
* **Branch-Based Requirements** - Extracts requirement IDs from branch names like `feature/REQ-123-description`
* **Flexible ID Formats** - Accepts `REQ-123`, `req-123`, `123`, or full UUIDs
## Output Formats [#output-formats]
Commands support multiple output formats for different use cases:
* **`table`** (default) - Human-readable tables for terminal viewing
* **`json`** - Machine-readable format for scripting and automation
* **`xml`** - Structured data for enterprise integrations
* **`markdown`** - Rich formatted output perfect for AI agents
Use the `--format` flag on any command:
```bash
braingrid requirement list --format json
braingrid requirement build REQ-123 --format markdown
```
## Next Steps [#next-steps]
Explore all available commands and their options
Set up BrainGrid as a Model Context Protocol server
---
# Create a Project
Source: https://www.braingrid.ai/docs/guides/create-project
Description: Learn how to create your first project in BrainGrid
This guide will walk you through creating your first project in BrainGrid.
A project is where you'll organize your requirements, tasks, and codebase analysis.
## Overview [#overview]
Creating a project in BrainGrid is the first step to organizing your development work. Each project:
* Links to a GitHub repository
* Contains requirements and their associated tasks
* Maintains codebase documentation and context
* Tracks implementation progress
## What's Next? [#whats-next]
Once you've created your project, you can:
* [Create your first requirement](/docs/guides/create-requirement)
* [Connect additional repositories](/docs/github-installation)
* [Set up the BrainGrid MCP](/docs/mcp-server/installation)
## Related Resources [#related-resources]
* [What is BrainGrid?](/docs/what-is-braingrid)
* [Quickstart Guide](/docs/quickstart)
* [GitHub Installation](/docs/github-installation)
---
# Create a Requirement
Source: https://www.braingrid.ai/docs/guides/create-requirement
Description: Learn how to create build-ready requirement documents with BrainGrid
This guide demonstrates how to create detailed requirement documents that serve as the foundation for your implementation tasks.
## Overview [#overview]
Requirements in BrainGrid are comprehensive documents that:
* Define what needs to be built with clear objectives
* Include technical specifications and constraints
* Establish acceptance criteria for validation
* Provide context from your codebase analysis
## What's Next? [#whats-next]
After creating your requirement:
* [Start implementation](/)
* Review and iterate based on team feedback
## Related Resources [#related-resources]
* [Quickstart Guide](/docs/quickstart)
* [MCP Usage](/docs/mcp-server/usage)
* [What is BrainGrid?](/docs/what-is-braingrid)
---
# Installing the GitHub CLI
Source: https://www.braingrid.ai/docs/guides/github-cli
Description: Step-by-step guide to install the GitHub CLI on Mac and Windows
The GitHub CLI (`gh`) lets you interact with GitHub from your terminal. BrainGrid uses it to connect with your repositories, create branches, and manage pull requests.
## What is GitHub? [#what-is-github]
GitHub is a platform where developers store and collaborate on code. Think of it as a shared folder for your project's code, where you can track every change, work with teammates, and review each other's work. BrainGrid connects to GitHub to analyze your code and help manage your development workflow.
## Create a GitHub Account [#create-a-github-account]
If you are going to build a BrainGrid requirement locally, you will first need the GitHub CLI installed to download the code and upload any changes you make. To use the GitHub CLI, you need a GitHub account.
Open [github.com](https://github.com) in your browser and click **Sign up**.
Provide your email address, create a password, and choose a username. Follow the verification steps to confirm your account.
Select the **Free** plan. It includes everything you need to use BrainGrid.
## Opening a Terminal [#opening-a-terminal]
A terminal is a text-based application where you type commands. You'll need one to install the GitHub CLI.
1. Press **Command + Space** to open Spotlight Search
2. Type **Terminal**
3. Press **Enter** to open it
A window with a text prompt will appear — this is your terminal.
1. Press the **Windows key** on your keyboard
2. Type **PowerShell**
3. Click **Windows PowerShell** from the results
A blue window with a text prompt will appear — this is your terminal.
Use **PowerShell**, not Command Prompt. PowerShell comes pre-installed on Windows 10 and later.
## Install the GitHub CLI [#install-the-github-cli]
The easiest way to install on Mac is with Homebrew, a popular package manager.
Paste this command into your terminal and press **Enter**:
```bash
/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"
```
Follow the on-screen instructions. You may need to enter your Mac password — the characters won't appear as you type, but they are being entered.
If you already have Homebrew, you can skip this step. To check, type `brew --version` and press Enter. If you see a version number, it's already installed.
Run this command:
```bash
brew install gh
```
Wait for the installation to finish.
If you prefer not to use Homebrew, you can download the `.pkg` installer directly from the [GitHub CLI releases page](https://github.com/cli/cli/releases/latest). Open the downloaded file and follow the installation wizard.
Windows 10 and later include a built-in package manager called `winget`. Paste this command into PowerShell and press **Enter**:
```powershell
winget install --id GitHub.cli
```
Follow any prompts that appear.
If `winget` is not available, download the `.msi` installer from the [GitHub CLI releases page](https://github.com/cli/cli/releases/latest). Open the downloaded file and follow the installation wizard.
## Verify the Installation [#verify-the-installation]
Close your terminal and open a new one (this ensures the new command is recognized). Then run:
```bash
gh --version
```
You should see output like `gh version 2.x.x`. If you see an error like "command not found", try closing and reopening your terminal again.
## Log In to GitHub [#log-in-to-github]
Before using the GitHub CLI, you need to connect it to your GitHub account:
Run this command:
```bash
gh auth login
```
The CLI will ask you a series of questions. Choose the following:
1. **Where do you use GitHub?** → Select `GitHub.com`
2. **Preferred protocol for Git operations?** → Select `HTTPS`
3. **Authenticate Git with your GitHub credentials?** → Select `Yes`
4. **How would you like to authenticate?** → Select `Login with a web browser`
The CLI will display a one-time code and open your browser. Paste the code into the browser page and authorize access.
Once complete, you'll see a confirmation message in your terminal.
## Verify Authentication [#verify-authentication]
Run this command to confirm you're logged in:
```bash
gh auth status
```
You should see your GitHub username and a confirmation that you're logged in.
## Troubleshooting [#troubleshooting]
Close your terminal completely and open a new one. The terminal needs to restart to recognize newly installed commands.
On Mac, if it still doesn't work after restarting the terminal, run the command that matches your Mac's chip. This is a temporary fix for the current session:
```bash
# Apple Silicon (M1/M2/M3/M4)
eval "$(/opt/homebrew/bin/brew shellenv)"
# Intel
eval "$(/usr/local/bin/brew shellenv)"
```
On Windows, try restarting your computer.
Your version of Windows may not include `winget`. Download the GitHub CLI installer directly from the [releases page](https://github.com/cli/cli/releases/latest) and run the `.msi` file.
This is your Mac user password (the one you use to log in to your computer). The characters won't appear as you type — this is normal. Type your password and press Enter.
If the browser doesn't open automatically, copy the URL shown in your terminal and paste it into your browser manually.
This typically means your Homebrew directory has incorrect ownership. **Do not use `sudo` with `brew` commands** — it can break your Homebrew installation.
Instead, fix the directory ownership by running this command, then try installing again:
```bash
sudo chown -R $(whoami) $(brew --prefix)
```
You'll be prompted for your Mac password.
## Next Steps [#next-steps]
Connect your repositories to BrainGrid
Set up your first BrainGrid project
---
# Installing BrainGrid MCP
Source: https://www.braingrid.ai/docs/mcp-server/installation
Description: Step-by-step guide to install BrainGrid MCP
Add BrainGrid to your Claude Code configuration:
```bash
claude mcp add --transport http braingrid https://mcp.braingrid.ai/mcp
```
Then restart your Claude Code session. You'll see that the BrainGrid MCP is available but needs authentication.
Enter `/mcp` to manage your MCP servers:
```bash
/mcp
```
Then you'll see "BrainGrid disconnected - enter to login"
Hit "Enter", this will open a browser window to login to BrainGrid. Once you log in, you can approve the BrainGrid MCP to connect to your account.
Once the authentication is complete, you'll see "Authentication successful. Connected to BrainGrid." and you can start using the BrainGrid MCP.
You can now use the BrainGrid MCP to create requirements and tasks.
To install the BrainGrid MCP server in Codex:
1. **Install mcp-remote globally**
```bash
npm install -g mcp-remote
```
2. **Open the Codex configuration file**
* Open `~/.codex/config.toml` in your preferred text editor
3. **Add the BrainGrid MCP configuration**
* Add the following configuration:
```toml
[mcp_servers.braingrid]
command = "npx"
args = ["-y", "mcp-remote@latest", "https://mcp.braingrid.ai/mcp"]
```
4. **Restart Codex**
* Restart Codex to load the new MCP server configuration
* Once restarted, you will need to authenticate with BrainGrid
5. **Authenticate**
* Follow the authentication prompts to connect your BrainGrid account
* Once authenticated, you can start using the BrainGrid MCP
To install the BrainGrid MCP server in Cursor, click the button below.
Once you click, you'll be taken to the Cursor MCP settings.
Click "Install" and you'll see the BrainGrid MCP server installed with a "Needs login" message.
Click on the "Needs login" message and you'll be taken to the BrainGrid login page. Once you log in, you can approve the BrainGrid MCP to connect to your account.
Once you're logged in, you can start using the BrainGrid MCP.
To install the BrainGrid MCP server in Windsurf:
1. **Install mcp-remote globally**
```bash
npm install -g mcp-remote
```
2. **Open Windsurf Settings**
* Click the Settings -> **Windsurf Settings**, or
3. **Scroll down to the MCP Servers section**
* Click **Open MCP Marketplace**
4. **In the Installed MCPs sub section**
* Click the gear icon on the right.
5. **Configure the Server**
* Enter the following configuration:
```json
{
"mcpServers": {
"braingrid": {
"command": "npx",
"args": ["-y", "mcp-remote@latest", "https://mcp.braingrid.ai/mcp"]
}
}
}
```
6. **Complete Setup**
* Close all tabs
* Reopen the Windsurf Settings
* Go to the MCP Marketplace, click open
* You will see the BrainGrid MCP server listed
7. **Troubleshooting**
* If you are having connection or auth issues, disable it and re-enable it.
To install the BrainGrid MCP server in Warp:
1. **Open MCP Settings**
* Click on the **Settings menu** in Warp
* Navigate to **Features** → **AI** → **Model Context Protocol (MCP)** → **MCP settings**
* Or visit the [MCP settings documentation](https://docs.warp.dev/knowledge-and-collaboration/mcp#adding-an-mcp-server) for more details
2. **Add the Server Configuration**
* In the MCP settings, add the following configuration:
```json
{
"braingrid": {
"command": "npx",
"args": [
"-y",
"mcp-remote@latest",
"https://mcp.braingrid.ai/mcp"
],
"env": {},
"working_directory": null
}
}
```
3. **Complete Setup**
* Save the configuration
* Restart Warp to load the new MCP server
* You will need to authenticate with BrainGrid on first use
For other tools, add BrainGrid MCP to your JSON configuration:
```json
{
"mcpServers": {
"braingrid": {
"url": "https://mcp.braingrid.ai/mcp",
"transport": "httpStream"
}
}
}
```
---
# BrainGrid MCP
Source: https://www.braingrid.ai/docs/mcp-server/overview
Description: Use BrainGrid directly from your AI coding assistant
BrainGrid's MCP server allows you to access and create requirements, build tasks, and track progress directly from your AI coding assistant.
We recommend using the [CLI](/docs/cli/overview) over the MCP server. The MCP server is best suited for web-based environments where you cannot run the CLI.
## Get Started [#get-started]
Ready to supercharge your AI coding workflow?
Step-by-step setup for Claude Code, Codex, Cursor, Windsurf, and more
Learn how to use all MCP tools effectively
## Common Workflows [#common-workflows]
With BrainGrid's MCP server, your AI assistant can:
Connect to your BrainGrid project automatically
Create from brief ideas or capture detailed requirements
Work with the requirements agent to refine and break down requirements
Generate implementation tasks using AI via MCP
Fetch and implement tasks for a requirement
View specific task information and content
Mark tasks as in progress or completed
Review a pull request against a requirement
Check server status and authentication
## Requirements [#requirements]
**Prerequisites**:
* Active BrainGrid account
* Claude Code, Codex, Cursor, Windsurf, or any other MCP compatible AI coding agent
---
# Using BrainGrid MCP
Source: https://www.braingrid.ai/docs/mcp-server/usage
Description: Learn how to use the BrainGrid MCP
Once you've installed BrainGrid MCP, you can use natural language to manage requirements and tasks directly from your AI assistant.
## Common Workflows [#common-workflows]
Connect to your BrainGrid project automatically
Create from brief ideas or capture detailed requirements
Work with the requirements agent to refine and break down requirements
Generate implementation tasks using AI via MCP
Fetch and implement tasks for a requirement
View specific task information and content
Mark tasks as in progress or completed
Review a pull request against a requirement
Check server status and authentication
## Available Tools [#available-tools]
BrainGrid MCP provides these tools that your AI assistant uses intelligently based on your intent:
**Important**: These are not rigid commands you call directly. Your AI assistant uses these tools flexibly to accomplish what you're trying to achieve.
### Project Discovery [#project-discovery]
Tools to discover and connect to your BrainGrid projects:
* **get\_project** - Discovers your BrainGrid project from your git repository and caches project context locally
* **get\_profile** - Retrieves your user profile and organization information
### Requirement Management [#requirement-management]
Your AI assistant can use these tools to help you work with requirements in whatever way makes sense for your situation:
* **create\_project\_requirement** - Creates requirements from brief ideas using AI refinement (for when you have a rough concept)
* **capture\_project\_requirement** - Captures pre-written requirements with full details (for when you already have detailed content)
* **breakdown\_project\_requirement** - Breaks down existing requirements into implementation tasks using AI
* **list\_project\_requirements** - Lists all requirements in your project with filtering options
* **get\_project\_requirement** - Retrieves detailed requirement information including content and acceptance criteria
* **update\_project\_requirement** - Updates requirement properties like status, name, or assignee
* **build\_project\_requirement** - Fetches requirements and tasks, adapting the presentation to your needs
* **acceptance\_review** - Reviews pull requests against requirements from multiple perspectives
### Task Management [#task-management]
Flexible task operations that adapt to your workflow:
* **list\_project\_tasks** - Lists all tasks for a requirement with filtering and pagination
* **create\_project\_task** - Creates new tasks within a requirement
* **get\_project\_task** - Retrieves detailed task information with implementation content
* **update\_project\_task** - Updates task status, content, and properties
### Information & Status [#information--status]
Context and authentication tools your assistant uses as needed:
* **info** - Provides server status, version information, and available tools
* **auth\_status** - Checks authentication status and displays user information
* **authenticate** - Initiates browser-based authentication (stdio mode only)
* **logout** - Clears stored credentials and logs out (stdio mode only)
**Key Insight**: Instead of memorizing tool parameters, focus on expressing your goals. Your AI assistant will use these tools in the right combination to accomplish what you want.
## Working with AI-Powered Tools [#working-with-ai-powered-tools]
**Key Concept**: MCP tools are not rigid commands like traditional CLI tools. They are flexible instruments that your AI assistant uses intelligently based on your natural language intent.
Unlike traditional software where `build_project_requirement` always does the same thing, BrainGrid's MCP tools adapt to your specific needs:
### Express Your Intent, Not Just Commands [#express-your-intent-not-just-commands]
**Instead of thinking**: "I need to call the build\_project\_requirement tool"
**Think**: "I want to understand this requirement and start working on it"
### Examples of Intent-Driven Usage [#examples-of-intent-driven-usage]
```bash Basic Usage
> Build REQ-123
⏺ I'll build requirement REQ-123 for you, fetching the tasks and getting you ready to implement.
```
```bash With Understanding Intent
> Build REQ-123, I want to understand all the tasks before we start building
⏺ I'll get REQ-123 and walk you through each task so you understand the full scope before we begin implementation.
```
```bash With Review Intent
> Build REQ-123 but first show me the acceptance criteria for each task
⏺ I'll get the requirement and break down the acceptance criteria for each task so you can see what success looks like.
```
### The Power of Natural Language [#the-power-of-natural-language]
Your AI assistant can:
* **Adapt tool usage** based on your specific goals
* **Combine multiple tools** in intelligent sequences
* **Ask clarifying questions** when your intent needs refinement
* **Provide context** and explanations tailored to your needs
**Pro Tip**: Don't just say what tool to use—tell your AI assistant what you're trying to accomplish. Let it figure out the best way to use the tools to meet your needs.
## Workflows [#workflows]
### Discover your project [#discover-your-project]
Before creating requirements or working with tasks, your AI assistant needs to know which BrainGrid project you're working with. The `get_project` tool discovers your project automatically.
```bash
> What project am I working on?
⏺ Let me check which BrainGrid project is linked to this repository...
⏺ braingrid - get_project (MCP)
⏺ ✅ Project discovered successfully!
- Name: My Awesome App
- ID: PROJ-123
- Repository: owner/my-awesome-app
```
**Automatic Discovery**: Your AI assistant automatically runs `get_project` when needed. It discovers your project by looking at your git repository and caches the project information locally in `.braingrid/project.json` for faster access.
The project discovery workflow:
1. Checks if `.braingrid/project.json` exists locally (cached project info)
2. If not found, reads your git repository information
3. Queries BrainGrid API to find the matching project
4. Caches project details locally for future use
Once discovered, all subsequent operations (creating requirements, listing tasks, etc.) automatically use this project context.
### Create a new requirement [#create-a-new-requirement]
There are two ways to create requirements in BrainGrid, depending on how much detail you already have:
#### Option 1: Create from brief ideas (AI refinement) [#option-1-create-from-brief-ideas-ai-refinement]
Use **create\_project\_requirement** when you have a rough concept or brief description. The AI will refine it into a structured requirement with detailed content, acceptance criteria, and complexity ratings.
```bash
> Create a requirement for user authentication with OAuth
⏺ I'll create a new requirement using AI to refine your idea into
a detailed requirement with acceptance criteria.
⏺ braingrid - create_project_requirement (MCP)
```
**Best for:** Quick ideas, rough concepts, feature requests that need structure
#### Option 2: Capture pre-written requirements [#option-2-capture-pre-written-requirements]
Use **capture\_project\_requirement** when you already have a detailed requirement with full content and acceptance criteria written out.
```bash
> Capture this requirement: [detailed requirement text with acceptance criteria]
⏺ I'll capture your pre-written requirement in BrainGrid.
⏺ braingrid - capture_project_requirement (MCP)
```
**Best for:** Requirements you've already detailed in a plan, pre-written specifications, documented feature requests
You can optionally specify repositories to associate with either type of requirement:
```bash
> Create a requirement for user auth and link owner/repo-one, owner/repo-two
⏺ I'll create a new requirement and associate the specified repositories.
⏺ braingrid - create_project_requirement (MCP) (repositories: "owner/repo-one, owner/repo-two")
```
**Claude Code tip:** Use plan mode to create a plan, then hit "ESC" and say `Create a new requirement from the plan you made`
Note: If `repositories` is not provided, the server will attempt to auto-detect the current GitHub repository from your local git configuration.
**Project Context Required**: The `create_project_requirement` tool needs to know which project to create the requirement in. If you haven't run `get_project` yet, your AI assistant will automatically discover your project first.
**What's next?** After creating a requirement via MCP, you'll typically want to:
1. **Refine it** using the requirements agent in the [BrainGrid web app](https://app.braingrid.ai)
2. **Build it** using MCP in your AI coding tool
This two-stage approach lets you do detailed requirement work in the web interface, then seamlessly build via MCP.
### Refine and break down a requirement [#refine-and-break-down-a-requirement]
Once you've created a requirement, you'll often need to refine it and break it down into actionable tasks. This is where BrainGrid's requirements agent becomes invaluable.
**What is the requirements agent?**
The requirements agent is an AI assistant built into the BrainGrid web app at [https://app.braingrid.ai](https://app.braingrid.ai). It helps you write detailed requirement documents and break them down into implementation tasks.
The requirements agent can help you:
* Write and refine detailed requirement documents
* Ask clarifying questions to better understand your needs
* Break down complex features into specific implementation tasks
* Add acceptance criteria and technical specifications
* Ensure requirements are ready for your AI coding tools
**How it works:**
1. **Access the requirements agent**: Go to [https://app.braingrid.ai/requirements](https://app.braingrid.ai/requirements) and click "Create requirement" or open an existing requirement
2. **Work with the agent**: The requirements agent will help you write and refine your requirement document by:
* Asking clarifying questions about your needs
* Writing detailed requirement specifications
* Adding technical details and acceptance criteria
* Breaking the requirement down into specific implementation tasks
3. **Use MCP to build**: Once your requirement is refined and has tasks, use the MCP to fetch it and start building
**Example workflow:**
```
Web App: Create/refine "user authentication" requirement
↓ Requirements agent asks: What auth methods? 2FA needed? User management scope?
↓ Agent writes detailed requirement with acceptance criteria
↓ Agent breaks it down into 5 specific implementation tasks
↓ Switch to Cursor, Claude Code, or your MCP-enabled IDE
↓
MCP: "Build REQ-123" → Your AI coding tool fetches the refined requirement and tasks
```
**Pro tip**: Work with the requirements agent until your requirement has clear, actionable tasks. Well-defined requirements lead to smoother implementation and better results.
**Need detailed guidance?** See our [Quickstart guide](/docs/quickstart) for step-by-step instructions with screenshots showing how to [write your first requirement](/docs/quickstart#write-your-first-requirement-document) and [break it down into tasks](/docs/quickstart#break-down-your-requirement-into-tasks).
#### Alternative: Break down requirements via MCP [#alternative-break-down-requirements-via-mcp]
If you prefer to stay in your AI coding environment, you can use the **breakdown\_project\_requirement** tool to generate tasks using AI without switching to the web app.
```bash
> Break down REQ-123 into implementation tasks
⏺ I'll use AI to analyze REQ-123 and generate actionable implementation tasks.
⏺ braingrid - breakdown_project_requirement (MCP)
⏺ ✅ Generated 5 tasks for REQ-123:
1. Set up database schema for user authentication
2. Implement OAuth2 provider integration
3. Create authentication middleware
4. Build user session management
5. Add frontend login/logout flows
```
**When to use MCP breakdown:**
* You want to stay in your coding environment
* The requirement content is already well-defined
* You need quick task generation without detailed refinement
**When to use the web app requirements agent:**
* You need interactive refinement and clarification
* The requirement needs significant detail work
* You want to collaborate with your team on requirement structure
Both approaches produce the same result - a requirement with actionable tasks ready to build.
### Build a requirement [#build-a-requirement]
Once you have a requirement with tasks broken down (see [Refine and break down a requirement](#refine-and-break-down-a-requirement) above), you can work with it in many different ways by expressing your intent in natural language.
**Remember**: You're not limited to just "Build REQ-123". Express what you want to accomplish and let your AI assistant use the tools intelligently to meet your needs.
```bash Quick Start
> Build REQ-123
⏺ I'll get REQ-123 ready for you to start implementing.
Let me fetch the requirement and its tasks.
⏺ The requirement has 5 tasks. Here's task 1 to get you started...
```
```bash Understand First
> Build REQ-123, I want to understand all the tasks before we start building
⏺ I'll fetch REQ-123 and walk you through each task so you understand
the full scope before implementation.
⏺ **Task Overview for REQ-123:**
- Task 1: Database schema updates (estimated 2 hours)
- Task 2: API endpoint implementation (estimated 4 hours)
- Task 3: Frontend integration (estimated 3 hours)
Would you like me to explain any of these in detail before we begin?
```
```bash Review Acceptance Criteria
> Build REQ-123 but first show me the acceptance criteria for each task
⏺ I'll get the requirement and break down what success looks like for each task.
⏺ **Acceptance Criteria Summary:**
**Task 1**: Database schema must support user roles, pass all migrations
**Task 2**: API must handle authentication, return proper error codes
**Task 3**: Frontend must be responsive, include proper validation
Ready to dive into the details of any specific task?
```
**Pro Tip**: Combine multiple intents in one request: "Build REQ-123, commit after the task has been marked complete and all tests pass."
### Get a task [#get-a-task]
Getting a task is flexible - you can express different intents about how you want to work with tasks. Your AI assistant uses `get_project_task` to retrieve task details.
```bash Basic Task Retrieval
> get task 1 of REQ-123
⏺ I'll fetch task 1 from REQ-123 with all the details you need to start implementing.
```
```bash Get Task with Context
> get task 1 of REQ-123, I want to understand how it relates to the other tasks
⏺ I'll get task 1 and explain how it fits into the overall requirement and its dependencies with other tasks.
```
```bash Get Next Logical Task
> get the next task I should work on with REQ-123
⏺ Let me look at REQ-123's tasks and your progress to suggest which task makes the most sense to tackle next.
```
```bash Get Task with Time Estimate
> get task 2 of REQ-123 and help me estimate how long it will take
⏺ I'll fetch task 2 and break down the work involved to give you a realistic time estimate based on the complexity.
```
### Update a task [#update-a-task]
Task status updates can be simple or include additional context and planning. Your AI assistant uses `update_project_task` to update task properties.
```bash Simple Status Update
> update task 1 of REQ-123 to COMPLETED
⏺ I'll mark task 1 as completed for you.
```
```bash Update with Progress Note
> update task 2 of REQ-123 to IN_PROGRESS, I'm working on the API endpoints
⏺ I'll mark task 2 as in progress and can help you with API endpoint implementation as you work through it.
```
```bash Smart Progress Update
> I just finished the user authentication part of REQ-123, help me update progress and plan next steps
⏺ Let me look at your requirement to understand which task this completes and suggest what to work on next based on your progress.
```
**Smart Updates**: Your AI assistant can help determine which tasks to update based on what you've accomplished, suggest next steps, and even identify blockers before they slow you down.
### Acceptance review on a pull request [#acceptance-review-on-a-pull-request]
PR reviews can be tailored to different perspectives and focus areas.
```bash Standard Acceptance Review
> acceptance review https://github.com/owner/repo/pull/123 against REQ-123
⏺ I'll validate the pull request against REQ-123's acceptance criteria and requirements.
```
```bash Review for Stakeholder
> acceptance review https://github.com/owner/repo/pull/123 against REQ-123, I need to present findings to the product team
⏺ I'll review the PR with a focus on user-facing changes and business requirements that the product team cares about.
```
```bash Technical Review Focus
> acceptance review https://github.com/owner/repo/pull/123 against REQ-123, focus on architecture and performance
⏺ I'll examine the PR's technical implementation, architecture decisions, and performance implications against the requirement.
```
```bash Pre-merge Checklist
> before I merge this PR, verify it meets all requirements in REQ-123
⏺ I'll run a comprehensive pre-merge check ensuring the PR fully satisfies REQ-123 and is ready for production.
```
**Multi-perspective Reviews**: Your AI assistant can review PRs from different angles - technical, business, user experience, or compliance - based on your specific needs and audience.
## Maximizing AI-Powered Development [#maximizing-ai-powered-development]
**Mindset Shift**: You're not operating a traditional tool - you're collaborating with an intelligent assistant that uses MCP tools to understand and accomplish your development goals.
### Best Practices for Intent-Driven Development [#best-practices-for-intent-driven-development]
#### Express Context and Goals [#express-context-and-goals]
```bash
# Instead of: "get task 1"
# Try: "get the next task I should work on, I'm strongest with backend APIs"
# Instead of: "build REQ-123"
# Try: "build REQ-123, help me understand the architecture decisions needed"
```
#### Combine Multiple Intents [#combine-multiple-intents]
```bash
# "Build REQ-456, break down the complexity of each task, and suggest an order
# based on my team's frontend-heavy skillset"
# "Review REQ-789 focusing on security, and help me prepare talking points
# for the architecture review meeting"
```
#### Ask for Guidance [#ask-for-guidance]
```bash
# "I'm new to this codebase - help me understand REQ-234 and suggest how
# to approach it safely"
# "REQ-345 seems complex - can you break it down and identify any risks
# I should discuss with my team first?"
```
### Key Mental Models [#key-mental-models]
1. **AI as Collaborator**: Your assistant understands context, makes intelligent decisions, and adapts to your specific situation
2. **Tools as Instruments**: MCP tools are flexible instruments your AI uses - not rigid commands you must learn
3. **Intent Over Commands**: Focus on what you want to accomplish, not how to invoke specific tools
4. **Context Awareness**: Your AI remembers your conversation context and adapts its tool usage accordingly
**Remember**: The more context you provide about your goals, constraints, and preferences, the better your AI assistant can help you achieve successful outcomes with BrainGrid.
---
# How Much Time Should You Spend Planning Before Coding With AI?
Source: https://www.braingrid.ai/blog/how-much-time-planning-before-coding-ai
Published: 2026-08-17T00:00:00Z
AI made writing code almost free, which should have finally ended the old argument about how much to plan before you start. Why design carefully when regenerating the whole thing takes thirty seconds? Instead the opposite happened. The cheaper the code got, the more the planning started to matter.
That is not a paradox once you watch where the time actually goes. This week in r/nocode, someone who had burned through Lovable, Replit, and Cursor credits and still had nothing working asked which AI app builder to buy next. An experienced builder replied with a ratio, not a tool: [you should spend about 1 hour designing the specs and 20-30 minutes actually building](https://www.reddit.com/r/nocode/comments/1vm2afr/best_ai_app_builder_for_noncoders_in_2026/). Then the line that turns it from advice into a diagnosis: if you find yourself cursing the AI that it is not what I asked for, it is largely because you didn't set the requirements properly.
Two to one, planning to building. From someone whose building step is an agent that writes the code for him. That is the number worth explaining.
## The hypothesis: unplanned time doesn't vanish, it moves
Here is the claim this post is built to test. **The hour you skip up front does not disappear. It reappears downstream as debugging, reprompting, and rework, and it costs more there than it would have cost as planning.**
The old wisdom was that planning trades slow-now for fast-later, a tax you pay to avoid mistakes. With an AI agent that math gets sharper, because the agent removes almost all of the "building" time but none of the "deciding what to build" time. When the code was the expensive part, a vague plan cost you a few extra hours of typing. Now the code is nearly free and the vague plan costs you something worse: an agent that confidently builds the wrong thing, fast, and reports done.
You have felt this if you have ever watched an agent produce a beautiful, complete, working feature that solves a problem you did not have. It did exactly what you said. You just had not decided what you meant. The gap between those two is where the skipped hour went.
## Cursing the AI is a requirements bill coming due
The r/nocode builder's reframe is the whole argument in one sentence. When the output is wrong, the instinct is to blame the tool and go shopping for a better one. Sometimes the tool is genuinely weak. Far more often, the requirements were never set, and no tool can build what you did not specify.
This shows up as a specific, repeatable feeling. Builders in r/ExperiencedDevs described [feeling illiterate about the codebase](https://www.reddit.com/r/ExperiencedDevs/comments/1vmayzf/how_are_people_blowing_through_token_usage/) as agents generate faster than anyone can read, and one named the root cause bluntly: people run agentic loops to solve problems they do not even understand themselves. That is not a model problem. An agent handed a fuzzy goal will fill the gaps with its best guess, and its best guess is a coin flip that looks like a decision. You do not discover the mismatch until you are three features deep and the auth logic it invented in feature two fights the state management it invented in feature four. This is the same drift that makes [your agent keep breaking things that already worked](/blog/why-ai-keeps-breaking-things-that-worked): nothing carried your intent forward, so each feature quietly renegotiated it.
The planning hour is where you catch that before it's written. Not because planning is virtuous, but because it's the only place the mismatch is cheap to fix. A wrong sentence in a spec costs one edit. The same wrong assumption discovered in a shipped feature costs a debugging session, a reprompt, and the quiet erosion of your trust in the whole app.
## The ratio is not the point. The exit condition is.
Two-to-one is a useful anchor, but do not turn it into a rule. The honest version is that planning time should scale with how much of your intent the agent would otherwise have to guess. A one-file script needs almost none. A multi-screen app with auth, data, and money needs a lot, because every unstated rule is a decision the agent makes for you.
What you are actually buying with that hour is a definition of done the agent can be measured against. This is the difference between a loop that converges and a loop that just burns tokens. A builder in r/AI_Agents put the failure mode precisely while defending the idea of agent loops against the skeptics: a bare loop with no verifiable exit is [guaranteed token burn with fingers-crossed results](https://www.reddit.com/r/AI_Agents/comments/1vlanp8/wait_am_i_just_an_idiot_or_is_all_the_talk_about/). Planning is how you write the exit condition. Without it, "build until it looks done" is the only stopping rule the agent has, and looks-done is exactly the thing that fails in production.
Consider the same feature, planned two ways.
Vague: "Build me a client portal with login and file upload."
Structured: authenticated users land on a dashboard listing their own files in a table with name, size, and upload date; clicking a row downloads the file; uploads accept PDF and images under 10MB and reject everything else with a visible error; unauthenticated users redirect to /login; a user can never see another user's files. Every clause in the second version is a line the finished build can be checked against. That is the skill underneath the planning hour, and it has a name: [writing acceptance criteria an agent can actually verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify). The agent still moves at agent speed. It just can no longer quietly ship the version where any logged-in user can download everyone's files, which is the kind of gap a demo hides and production reveals.
## Where BrainGrid fits
That planning hour has a shape, and doing it well is a skill most builders are learning on the fly. This is the gap [BrainGrid](https://braingrid.ai) was built to close, so the hour is spent on decisions instead of on staring at a blank requirements doc.
You describe the idea in plain English, and the Planning Agent turns it into a structured requirement with acceptance criteria, data models, and designs. It asks the clarifying questions you did not think to answer and pushes back when the intent is vague, which is precisely the "set the requirements properly" step the r/nocode builder was pointing at. Then the Builder Agent runs the build against that spec, either in a managed cloud sandbox with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. And the part almost nobody does by hand happens automatically: verification checks the finished build against every acceptance criterion, so the feature is not done until the evidence says it matches what you asked for.
That is the two-to-one ratio turned into a workflow, and it is the whole idea behind [spec-driven development](/spec-driven-development): the planning is where you decide what you mean, and the verification is where the agent proves it built that and not its best guess. Charity Majors made the underlying point in [The Pragmatic Engineer](https://newsletter.pragmaticengineer.com/p/stop-being-skeptical-about-ai-for): when you did not write the code, you have to move your trust to the other end of the process, to validation. The plan is what validation checks against. Skip the plan and there is nothing to verify against except vibes.
## What changes for you
If you are shipping with an AI coding agent right now, here is the concrete implication. Your instinct is to measure progress by how fast the agent produces code, so a slow planning step feels like the agent is idling. Invert it. Measure progress by how few times you have to say "no, not like that." The builders who spend an hour framing the feature say it once or zero times. The builders who skip straight to building say it five times across three reprompts, and each round quietly rewrites something that already worked.
The trade-off is real and worth stating. On a genuine throwaway, a scratch script, a one-day prototype nobody will maintain, the planning hour is pure overhead, and you should skip it and vibe. The ratio only pays off when the thing has to keep working after you stop looking at it. That is also exactly the moment most builders wish they had planned, and by then the skipped hour has already been spent, at a worse exchange rate, on figuring out why the app broke.
So how much time should you spend planning before coding with AI? Enough that the agent is executing a decision instead of making one. The code was never the expensive part. Deciding what it should do always was, and pretending otherwise just moves the bill to the end and adds interest.
## FAQ
### How much time should you spend planning versus coding?
There is no universal ratio, but builders working with AI agents converge on planning taking as long as or longer than the build, often around two-to-one for anything non-trivial. The reason is that an AI agent collapses the coding time to near zero while leaving the "decide what to build" time untouched, so planning becomes the larger share by default. Scale it to ambiguity: a small script needs minutes, while a multi-feature app with auth, data, and permissions needs real planning because every unstated rule becomes a decision the agent makes for you. The goal is not a fixed percentage. It is that the agent should be executing decisions you made, not guessing at ones you skipped.
### Is it better to plan before coding or just start coding?
For a small, well-understood task you have done before, starting directly is fine because you are effectively planning as you type. For anything with multiple moving parts, planning first wins, and it wins harder when an AI agent is doing the building. Unplanned work does not save time, it relocates it: the decisions you skip come back as debugging, reprompting, and rework, which are more expensive than the same decisions made up front. The practical test is whether you can state what "done" looks like before you start. If you cannot, you are not ready to build yet, you are ready to plan.
### Why does my AI agent keep building the wrong thing?
Almost always because the requirements were underspecified, not because the model is weak. An agent handed a vague goal fills the gaps with its best guess and reports success, so "wrong" usually means "technically what I said, not what I meant." The fix is to write the acceptance criteria before building: the specific behaviors, edge cases, and constraints the result must satisfy. When those exist, the agent has something concrete to build toward and you have something concrete to check the result against. When they do not, you are relying on the agent to read your mind, and it cannot.
### What is the 80/20 rule in coding?
The 80/20 rule (the Pareto principle) observes that roughly 80% of outcomes come from 20% of causes, and in software it shows up several ways: a small fraction of the code causes most of the bugs, a small set of features drives most of the value, and the last 20% of a project often takes 80% of the effort. For AI-assisted building, the useful version is that a small amount of upfront planning prevents a large amount of downstream rework. The 20% you spend deciding exactly what to build is what keeps the other 80% from turning into a debugging spiral.
### Does planning still matter when AI writes the code so fast?
More than before, not less. When writing code was slow, a vague plan cost you extra typing. Now that an agent writes code in seconds, a vague plan costs you a confident, fast build of the wrong thing, which is worse because it looks finished. Speed makes the mismatch cheaper to produce and more expensive to catch, so the planning that prevents the mismatch is the best-paying time you spend. The bottleneck moved from writing code to deciding what the code should do, and that is exactly the part AI does not do for you. It's the same reason [a vague prompt costs more than it looks like it should](/blog/the-real-cost-of-a-vague-prompt): the cost is just deferred.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform: it turns your idea into a spec with acceptance criteria, builds against it with your agent, and verifies the result before you call it done. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The Best Spec-Driven Development Tools in 2026 (Tested & Compared)
Source: https://www.braingrid.ai/blog/spec-driven-development-tools
Published: 2026-08-12T00:00:00Z
Adding a spec-driven development tool does not make your development spec-driven. Most of them just generate a folder of markdown, hand it to the same agent that was already guessing, and call the ceremony a method.
That gap is exactly what a builder in r/AI_Agents was circling this week when the whole "loop engineering" idea got picked apart. His verdict on the wave of new agent-workflow tooling was blunt: [Cron jobs with a shiny new UI are still cron jobs](https://www.reddit.com/r/AI_Agents/comments/1vlanp8/wait_am_i_just_an_idiot_or_is_all_the_talk_about/). He is right about most of them, and the same critique lands on half the "spec-driven" category. A markdown template with a shiny new UI is still a markdown template.
So which of these tools actually change the outcome, and which just add paperwork? We use spec-driven development to ship our own product every day, so this is the field guide we wish existed: what each tool really does, who it fits, and the one axis that separates the ones that work from the ones that generate homework.
## The hypothesis: the spec is the easy half
Here is the claim this guide is built to test. **The value of a spec-driven development tool is not in writing the spec. It is in what happens after.**
Writing a spec has never been the hard part. In an r/LLMDevs thread this week on where the real bottleneck sits, one builder described his workflow, having the AI write explicit input/output/behavior contracts for every function before implementing anything, and added the line that says everything: [90% of vibe coders still don't do it](https://www.reddit.com/r/LLMDevs/comments/1vh749h/comments/). Someone asked what prompt would backfill that discipline into an existing codebase. The reply was two words: it's called spec-driven development.
That is the tell. People reinvent this practice from scratch, hit the wall, and only then learn it already has a name and a category of tools. The category is real. But most of the tools stop at the easy half. They help you produce a beautiful spec, then hand the spec to the same coding agent that will report "done" the moment it stops running, whether or not the build matches a single line you wrote.
The tools worth your time are the ones that close the loop: spec, build, and then verify the build against the spec before anyone calls it done. Keep that axis in mind as we go through them.
## GitHub Spec Kit
[Spec Kit](https://github.com/github/spec-kit) is the reference implementation of the category, an open-source CLI toolkit from GitHub that walks your coding agent through a structured pipeline: Constitution, Specify, Clarify, Plan, Tasks, Implement. It writes markdown templates that plug into Claude Code, Copilot, Gemini CLI, and most other agents, so it is agent-agnostic by design.
Its strength is also its ceiling. Spec Kit is a scaffolding for the workflow, not a product that runs it for you. You get discipline and a shared vocabulary, which is genuinely valuable, but you are still driving the whole thing from a terminal, and the verification step is whatever your agent decides to do on its own. It fits engineers who want structure without a new IDE. If you have a repo and you are comfortable in the CLI, start here. We wrote a full [Spec Kit walkthrough for an existing project](/blog/github-spec-kit-tutorial-existing-project) if you want the hands-on version.
## OpenSpec
[OpenSpec](https://github.com/Fission-AI/OpenSpec) is the lightweight answer to Spec Kit's ceremony. It breaks a high-level prompt into granular, ordered task lists and keeps a set of markdown files in sync as the agent works, so it stays out of your way. If Spec Kit felt like too much process for a solo project, OpenSpec is the trimmed-down version that still gives the agent a plan to follow instead of a vibe.
The trade-off is that lighter also means less opinionated about what "done" means. You get a cleaner task breakdown and less overhead, and you give up the fuller lifecycle framing. It fits solo builders and small teams who want just enough structure to stop the agent from wandering. We put it head to head with Spec Kit in [OpenSpec vs Spec Kit vs BrainGrid](/blog/openspec-vs-spec-kit-vs-braingrid) if you want the direct comparison.
## Kiro (and the spec-driven IDE camp)
[Kiro](https://kiro.dev), Amazon's spec-driven IDE, represents the other end of the spectrum: a full VS Code-style environment built around specs. You describe requirements in natural language, Kiro generates user stories, design docs, and steering files, and you check off implementation against them inside the editor. It is the most "product" of the open toolkits, with interactive UI to track features from requirement to code.
The cost is lock-in and weight. You are adopting an IDE, not a workflow you can bolt onto the tools you already use. For a developer who wants a native, self-contained spec-driven environment, that is a fair trade. For a non-technical founder, an IDE is still an IDE, with all the friction that implies. We compared its philosophy to ours in [Kiro vs BrainGrid](/blog/kiro-vs-braingrid-spec-driven-development).
## BMAD and the framework crowd
[BMAD-METHOD](https://github.com/bmad-code-org/BMAD-METHOD) and the growing shelf of SDD frameworks (Spec Kitty, Agent OS, Tessl, and more) are for people who want to assemble their own pipeline from parts. They give you agent personas, planning phases, and templates you wire together yourself. Powerful in the right hands, and a rabbit hole in the wrong ones.
This is where a warning belongs. The moment picking a framework becomes its own project, the tool has failed at its job. If you have spent a weekend comparing steering-doc syntaxes instead of shipping a feature, [you are shopping for tools instead of building](/blog/stop-shopping-for-spec-driven-development-tools). The framework crowd fits engineers who genuinely enjoy building their own harness. Most builders do not, and should not have to.
## The contract-and-API-spec category
There is a second, older meaning of "spec-driven" that shows up in the same searches: API-first tools like [SwaggerHub](https://swagger.io/tools/swaggerhub/), [Specmatic](https://specmatic.in/), and [TypeSpec](https://typespec.io). These treat an OpenAPI or contract file as the source of truth and enforce it in CI before code ships. They are excellent, and they solve a different problem: the contract between services, not the requirement behind a feature. If your pain is "my agent keeps breaking the API between the frontend and backend," this is your aisle. If your pain is "my agent built the wrong thing confidently," it is not.
## Where BrainGrid fits
Everything above is strong at producing a spec. The question our own hypothesis forces is what happens next, and that is where we built [BrainGrid](https://braingrid.ai) to be different.
You describe an idea in plain English, and the Planning Agent turns it into a structured requirement with acceptance criteria, data models, and designs, asking clarifying questions and pushing back when the intent is vague. That is the part most tools stop at. Then the Builder Agent takes over: it runs the build against that spec, either in a managed cloud sandbox with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. And then the part almost nobody automates happens. Verification checks the build against every acceptance criterion, and the feature is not done until the evidence says it matches what you asked for.
That closes the loop the r/codex thread was worried about this week, where builders debated whether smarter agents still need review and landed on a hard truth: [they do not own mistakes](https://www.reddit.com/r/codex/comments/1vkscm1/apparently_now_that_codexcc_are_getting_better_we/), so someone still has to prove the work is right. A spec you can verify against is how you prove it without reading every line of code yourself. The spec is not paperwork. It is the standard the build gets checked against.
## Old way vs new way
The difference between using a spec-driven tool and actually doing spec-driven development comes down to one habit.
Old way: "Build me a CRM with React." The agent generates something, reports success, and you find out at feature four that the auth logic conflicts with the state management it wrote in feature two.
New way: a requirement that says a contact-management view displays contacts in a sortable table with name, company, and last-contacted date; clicking a row opens a detail panel; only authenticated users can access it; unauthenticated users redirect to /login. Every one of those lines is a criterion the build can be checked against. The agent still moves fast. It just cannot quietly ship the wrong thing.
The tool that generates the second version for you is doing useful work. The tool that also verifies the build against it is doing the whole job.
## What changes for you
If you are building a SaaS product with an AI coding agent right now, here is the concrete implication. Adopting any tool on this list will make your third and fourth features less likely to break, because the agent finally has a plan and a shared definition of the feature. That alone is worth it.
But do not stop at the spec. The failure mode this whole category exists to fix is not "the agent had no plan." It is "the agent said done and it wasn't." Pick your tool on the verification axis. If two tools produce equally good specs, the one that checks the build against the spec is the one that saves you the afternoon you would have spent discovering the gap in production.
And the honest trade-off: spec-driven development is slower on feature one. You are front-loading the thinking. The payback comes at feature five, when your codebase is still coherent and your agent is still building the thing you asked for instead of the thing it guessed. If you are shipping a one-day throwaway, skip all of it and vibe. If you are building something real, the spec is the cheapest insurance you will buy.
## FAQ
### What is spec-driven development?
Spec-driven development is a workflow where you write a structured specification, requirements, constraints, and acceptance criteria, before an AI agent writes code, and the spec becomes the source of truth the build is measured against. It replaces "prompt, hope, and patch" with "specify, build, and verify." The point is not the document. It is that a clear spec gives the agent something concrete to build toward and something concrete to be checked against. We cover the full method in [Spec-Driven Development: Ship Reliable Software Faster with AI](/blog/spec-driven-development).
### What are the best spec-driven development tools?
For agent-agnostic structure from the CLI, GitHub Spec Kit is the reference tool. For a lighter task-focused workflow, OpenSpec. For a full spec-driven IDE, Kiro. For assembling your own pipeline, frameworks like BMAD. For API contracts specifically, SwaggerHub or TypeSpec. And for a workflow that plans, builds, and then verifies the build against acceptance criteria in one loop, BrainGrid. The right pick depends on whether you want scaffolding you drive yourself or a system that closes the loop for you.
### What is the difference between spec-driven development tools?
They differ mainly on two axes: how much they do for you, and whether they verify the result. Spec Kit and OpenSpec are scaffolding you drive from a terminal. Kiro is a full IDE. Framework kits like BMAD are parts you assemble. Most of them stop after generating the spec and planning the work. The meaningful divide is verification: does the tool check the finished build against the spec, or does it trust the agent's own "done"?
### What is the difference between BDD and spec-driven development?
Behavior-driven development (BDD) focuses on describing expected behavior as executable scenarios ("given, when, then") that become automated tests. Spec-driven development is broader: the spec covers requirements, constraints, data models, and acceptance criteria, and drives both the build and its verification, not only the test suite. BDD scenarios can live inside a spec-driven workflow as one form of acceptance criteria. SDD is the wider frame; BDD is one technique for expressing part of it.
### Do I need a spec-driven tool, or can I just write a good prompt?
A single good prompt works for a single small feature. It stops working once a project has many moving parts, because nothing carries your intent from one session to the next and nothing checks the result. A spec-driven tool exists to make that intent durable and verifiable. If you keep re-explaining your app to the agent every session, or keep discovering broken features you thought were done, you have outgrown prompting and the category is for you.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into a spec your coding agent can build against, then verifies the build matches it before you call it done. Try it at [braingrid.ai](https://braingrid.ai).*
---
# How to Verify AI-Generated Code (Before It Breaks Production)
Source: https://www.braingrid.ai/blog/how-to-verify-ai-generated-code
Published: 2026-08-11T12:00:00Z
The agent said it was done. It ran the app, showed you a green result, and wrote a tidy summary of what it built. None of that tells you whether the code does what you asked. Those are two different questions, and the gap between them is where production breaks.
Here is the hypothesis this guide rests on: verifying AI-generated code is not reading it line by line, it is checking it against a target you defined before the build. The more of your building an agent does, the less "I read it and it looked fine" scales, and the more you need a repeatable way to prove the change matches intent. The good news is that this is a learnable process, not a talent. The bad news is that almost nobody is taught it, so most builders default to eyeballing a demo and hoping.
## "It runs" is not "it works"
An AI coding agent optimizes for the shortest path to something that looks complete. Ask for a login flow and it will build the happy path, run it once, watch a user log in, and call that done. It is not lying. It genuinely did produce a thing that works, for the one case it tried. What it did not do is check the wrong password, the expired session, the empty email field, or the second user whose data must not leak into the first user's account. Those are the cases that surface in production, at the worst possible time, in front of a real person.
This is the distinction [Stanislav Sorokin named cleanly](https://x.com/stas_sorokin_/status/2083480323476656211), writing about agent runs on X:
> Completion is a runtime event. Success is a verified state.
That is the whole problem in nine words. The agent stopping is a fact about the loop. Whether it succeeded is a separate fact that has to be established on purpose, and the agent will not establish it for you unless you told it what success means. Verification is how you turn "it stopped" into "it works," and it is the step the demo quietly skips.
## The five checks that actually catch things
When developers on [r/ExperiencedDevs compared notes](https://www.reddit.com/r/ExperiencedDevs/comments/1rzq738/what_tools_and_techniques_are_you_using_to_verify/) on verifying AI code, the useful answers were not "read every line." They were specific, repeatable checks. Here is the shortlist that catches the most, in the order that catches it fastest.
Start with intent, not code. Before you look at a single function, restate what the change was supposed to do and confirm the code is even solving that problem. Agents drift: you asked for a filter and got a sort, or the feature works but silently changed an unrelated screen. Catching a wrong-problem build here saves you from carefully reviewing code that was never going to be right.
Run the tests, and then read them. A passing suite feels like proof until you notice the agent wrote tests that assert the happy path and nothing else. The test that matters is the one for the case you are worried about, and if it is missing, the green checkmark is meaningless. Read what the tests actually assert before you trust that they passed.
Exercise the edge cases by hand. Wrong password. Empty input. The second concurrent user. The thing that was working yesterday. Agents are strong on the path they were shown and weak on the paths they were not, so five minutes of deliberately trying to break it finds more than an hour of reading finds.
Check it in a real environment, not the demo. [Addy Osmani put the rule plainly](https://www.linkedin.com/posts/addyosmani_ai-programming-softwareengineering-activity-7338086913477627905-hO2w):
> Always test AI-generated code in a sandbox before merging.
A demo runs on the machine that just built it, with the data that happens to be loaded. A sandbox that looks like production surfaces the hardcoded path, the missing environment variable, and the assumption that only holds on the developer's laptop. This is exactly where the "it works on my machine" class of bug lives.
Diff for collateral damage. AI agents edit more than you asked. Look at the full change, not just the new feature, and ask what else moved. A refactor that "cleaned up" a shared function may have broken three callers you did not think to test.
Notice what these have in common: not one of them is "understand every line the agent wrote." You verify against behavior and intent, not against a code-reading marathon you do not have time for. That is the shift. You are not auditing the agent's homework, you are proving the result.
## Verification needs a target, and the target is the receipt
Here is the reframe. Every one of those checks assumes you already know what "correct" looks like. The edge cases you test, the behavior you confirm, the intent you check against, all of it depends on a [definition of done](/blog/definition-of-done-for-ai-builders) that existed before the build started. If that definition lives only in your head, verification becomes a vibe, and a vibe does not scale past the third feature.
A builder in [r/ClaudeCode described the fix](https://www.reddit.com/r/ClaudeCode/comments/1vdmg1n/) without naming a product:
> You need a receipt for each agent. That receipt, verified, becomes the record.
That is the missing piece. A receipt is a checkable claim: "this feature is done because these specific conditions were confirmed." Written before the build, it is the [acceptance criteria the agent builds toward](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify). Verified after, it is the evidence that the build matches intent. Without receipts, you are left staring at a diff trying to reconstruct what the change was supposed to prove. With them, verification is mechanical: check the change against each criterion, and a criterion either passed or it did not.
Compare the two ways of asking an agent to be done.
Vague: "Add login and make sure it works."
With a receipt: "Add email and password login. A valid pair signs the user in and redirects to /dashboard. A wrong password shows an inline error and does not redirect. An empty field is rejected before submit. A logged-in user hitting /login is redirected to /dashboard. Only the authenticated user's own records are returned."
The first gives the agent nothing to verify against, so it invents its own bar and clears it. The second is five checkable statements. The agent builds toward them, and you (or a verifier) confirm each one with evidence instead of opinion.
## Where BrainGrid fits
This is the layer [BrainGrid](https://braingrid.ai) works in. You describe a feature in plain language and the Planning Agent turns it into structured requirements with acceptance criteria written to be checkable, the "when this, the system shall that" statements that double as the receipt. Then the Builder Agent builds against those criteria, in a BrainGrid-managed cloud sandbox with a live preview, or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. A feature is not marked done until verification checks the build against every criterion and the evidence says it matches intent.
That closes [the loop](/loop) the five checks are reaching for. Plan the receipt, build against it, verify with evidence, repeat. The intent is captured as a durable record instead of a sentence in a chat window that scrolls away, so the thing you verify against outlives the session that created it. Everyone else sells speed of generation. The point of a receipt is certainty of outcome.
```mermaid
flowchart LR
A["Agent says 'done'"] --> B{"Verify against what?"}
B -->|"No receipt"| C["Eyeball the demo, hope"]
C --> D["Bug surfaces in production"]
B -->|"Receipt exists"| E["Check each acceptance criterion"]
E --> F["Evidence per criterion"]
F --> G["Done means verified"]
```
## The trade-off worth naming
Verification is not free. Writing acceptance criteria before the build and checking them after is real work, and for a throwaway script or a weekend experiment it is overkill. If you are prototyping to learn whether an idea is worth pursuing, skip the receipts and move fast. The cost is justified the moment the code is going to be used by someone other than you, or is going to be built on top of next week. That is the line: verify what has to be trusted, not what you are about to throw away. Applying the full process to a one-off is how you make AI building feel slower than it should.
## What this changes for you
If you are building a SaaS product with Claude Code or Cursor right now, this means your verification bottleneck is not the reading, it is the missing target. The reason [reviewing AI code feels endless](/blog/why-reviewing-ai-code-costs-more-than-writing-it) is that you are reconstructing intent at review time instead of defining it at plan time. Move that definition earlier. Write down what done means as checkable statements before the agent starts, and the after-the-fact review collapses from "read everything and hope I catch it" into "confirm these specific things passed." You pay the clarity cost once, up front, instead of paying the review tax on every feature forever.
## Action steps
For your next AI-built feature, run this sequence:
1. Before the build, write 3 to 6 checkable statements of what "done" means, including the edge cases you are worried about.
2. Have the agent build against those statements, not a one-line prompt.
3. Run the tests, then read what they assert, and add the missing edge-case test.
4. Exercise the failure paths by hand: wrong input, empty input, second user, the thing that worked yesterday.
5. Test in a production-like environment, never just the demo that built it.
6. Diff the full change and confirm nothing outside the feature moved.
7. Check the result against each statement from step one. Anything not confirmed is not done.
## FAQ
### How do you validate AI-generated code?
Validate it against a definition of "done" you wrote before the build, not by reading every line after. Confirm the code solves the intended problem, run and read the tests, exercise the edge and failure cases by hand, test it in a production-like sandbox rather than the demo environment, and diff the full change for edits outside the feature. Each check confirms behavior against intent instead of auditing the agent's code line by line.
### Is there a way to identify what an AI agent actually changed?
Yes, and you should always look. Review the complete diff, not just the new feature the agent describes. AI coding agents frequently edit shared functions, refactor unrelated code, or adjust configuration as a side effect. Reading the full set of changes is how you catch collateral damage in code the agent did not mention in its summary.
### Why does AI-generated code pass tests but still break in production?
Because the agent often writes tests that assert only the happy path it already built, so the suite passes without covering the cases that fail. A green checkmark proves the tests that exist passed, not that the right tests exist. Read what the tests actually assert, and add coverage for the edge cases and failure paths you care about before trusting the result.
### Do I need to read AI-generated code to verify it?
Not line by line. Effective verification checks behavior against a defined target: does it do what you asked, does it handle the cases you specified, does it work in a real environment. You will read specific code when a check fails and you need to find out why, but the goal is proving the result against acceptance criteria, not understanding every function the agent wrote.
### What is the fastest way to verify AI code before merging?
Test it in a sandbox that resembles production, then check the change against the acceptance criteria you defined before the build. If those criteria exist, verification is mechanical: each one either passed with evidence or it did not. If they do not exist, you are reconstructing intent at review time, which is exactly why reviewing AI code so often takes longer than writing it.
The shift is simple to state and hard to skip: define what done means before the agent builds, and verification stops being a guess. It works because it gets more necessary as models get better, not less. More autonomy means more decisions nobody wrote down, and evidence is how you trust what you did not read.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that turns your idea into checkable requirements, builds against them, and verifies every one with evidence. Try it at [braingrid.ai](https://braingrid.ai).*
---
# EARS Notation, Explained: The Requirements Syntax Behind Every AI Spec
Source: https://www.braingrid.ai/blog/ears-notation
Published: 2026-08-10T12:00:00Z
A requirements syntax invented in 2009 for jet engine software is quietly becoming the house style for AI coding tools. It was designed for a room full of engineers arguing over a spec. Its best audience turned out to be a machine that never argues.
EARS notation, short for the Easy Approach to Requirements Syntax, came out of Rolls-Royce when [Alistair Mavin](https://alistairmavin.com/ears/) and colleagues got tired of aerospace requirements that read like legal fog. The [2009 IEEE paper](https://ieeexplore.ieee.org/document/5328509/) has been cited over 500 times. For fifteen years it lived in systems engineering, the discipline that writes requirements for things that kill people when they fail. Then the AI tools arrived, and EARS started showing up where nobody in 2009 would have predicted: in the specs that coding agents read before they build.
## What EARS notation actually is
EARS is a constraint on how you write a requirement, not a new document format or a tool you install. The idea is that most bad requirements are bad in the same few ways, so you give authors a small set of sentence templates that make the common mistakes impossible. Every EARS requirement follows the same clause order:
> While ``, when ``, the `` shall ``.
That is the whole grammar. The clauses always appear in that order, most are optional, and the word "shall" carries the actual behavior. From that one skeleton, five patterns cover almost everything you need to say.
A **ubiquitous** requirement is always true, no condition attached: "The system shall encrypt all stored passwords." An **event-driven** requirement fires on a trigger: "When a user submits the signup form, the system shall send a verification email." A **state-driven** requirement holds while something is true: "While a payment is processing, the system shall disable the submit button." An **unwanted-behavior** requirement handles the sad path, the one everyone forgets: "If the payment provider returns an error, then the system shall display the failure reason and preserve the cart." And an **optional-feature** requirement scopes to a configuration: "Where two-factor authentication is enabled, the system shall require a code on login."
Read those back. Notice what the template forced you to do. You named the exact trigger, the exact state, the exact system, and the exact response. There is no room for "the app should probably handle errors gracefully," because the grammar has no slot for "probably" or "gracefully." That constraint is the entire point.
## The reframe: it was built for humans, it pays off with agents
Here is the hypothesis this post rests on. EARS was designed to make requirements unambiguous for a human reader, and it did that job for fifteen years. But its value goes up, not down, the moment the reader is an AI agent, because an agent takes the sentence literally in a way a human colleague never quite does.
When a human reads "the system should handle invalid input," they fill the gap with judgment. They have seen a hundred forms, they know what validation usually means, and they quietly do the reasonable thing. That gap-filling is a feature when the reader is a senior engineer and a liability when the reader is an agent, because the agent also fills the gap, just not necessarily with your version of reasonable. It picks a plausible interpretation, writes code against it, and the demo runs. The mismatch surfaces three weeks later when a real user pastes an emoji into a field you never specified.
The [GitHub Spec Kit team is actively debating EARS integration](https://github.com/github/spec-kit/issues/1356) for exactly this reason. The issue puts it plainly: EARS gives authors sentence templates that help them write specifications AI agents can parse more reliably. Amazon's Kiro already generates its acceptance criteria in EARS by default, [one of two very different takes on spec-driven development](/blog/kiro-vs-braingrid-spec-driven-development). The tools converging here are not doing it out of nostalgia for a 2009 aerospace standard. They are doing it because a constrained sentence is a better instruction to a literal machine than a fluent paragraph is.
This is the same lesson the AI building community keeps rediscovering in its own words. Steinberger's line that your job is to [design the loops that prompt your agents](/blog/loop-engineering) is really a statement about inputs: the loop is only as good as the target you hand it. EARS is one disciplined way to write that target so the agent and the verifier read it the same way.
## Vague requirement versus EARS requirement
The difference is easiest to see side by side. Take a single feature, password reset, written the way it usually reaches an agent versus written in EARS.
> Vague: "Users should be able to reset their password securely."
> EARS: "When a user requests a password reset, the system shall send a reset link to the account email within one minute. The reset link shall expire 30 minutes after issue. When a user opens a valid reset link, the system shall allow a new password to be set. If a user opens an expired or already-used link, then the system shall display 'This link is no longer valid' and offer to send a new one. When a password reset completes, the system shall invalidate all existing sessions for that account."
The first version is a wish. It has one word, "securely," doing an enormous amount of undefined work. The second version is a set of facts you can check. Each "shall" is either true of the running app or it is not, with no room to argue. An agent can build against it, and just as important, a verifier can measure the result against it without asking anyone what "securely" was supposed to mean.
That is the connection most explainers miss. A well-formed EARS requirement is already an acceptance criterion. The syntax that makes intent unambiguous is the same syntax that makes "done" checkable. Write the requirement in EARS and you have not just specified the feature, you have specified the test.
```mermaid
flowchart LR
A["Vague intent: 'handle errors gracefully'"] --> B["Agent fills the gap with a guess"]
B --> C["Demo runs, looks done"]
C --> D["Bug surfaces in production"]
E["EARS requirement: 'If X, then the system shall do Y'"] --> F["Agent builds against a literal target"]
F --> G["Verifier checks each 'shall'"]
G --> H["Done means verified"]
```
## Where BrainGrid fits
This is the layer [BrainGrid](https://braingrid.ai) works in. You describe a feature in plain language, "let users reset their password," and the Planning Agent turns it into structured requirements with acceptance criteria written to be checkable, the EARS-shaped "when this, the system shall that" statements rather than a paragraph of hope. Then the Builder Agent, working in a cloud sandbox or in your own GitHub repo through Claude Code, Cursor, or Codex, builds against those criteria, and a feature is not done until each one is verified with evidence.
The point is not that you must memorize five patterns and hand-write "shall" sentences all day. Most builders never learn the acronym, and they should not have to. The point is that the discipline EARS encodes, name the trigger, name the system, name the exact response, cover the unwanted path, is exactly the discipline that separates a spec an agent can build reliably from a prompt it has to guess at. BrainGrid captures that intent as a durable record so the plan outlives the chat window, instead of decaying the moment the context fills up.
## The trade-off worth naming
EARS is not free, and pretending it is would be dishonest. Constrained syntax is slower to write than a fluent sentence, and it can feel stiff, almost robotic, when you first switch to it. "When a user submits the form, the system shall validate the email field" is less pleasant to read than "the form should check the email." Mavin's own work concedes EARS is a starting discipline, not a universal law: some requirements, particularly complex interacting behaviors, do not fold neatly into one template, and forcing them can make things worse rather than clearer. It is a floor for quality, not a ceiling.
It also does not verify anything on its own. A perfectly formed EARS requirement that nobody checks is still just a nicely worded wish. The syntax makes "done" definable. Something still has to do the defining-versus-reality comparison, which is the verification step, not the writing step. EARS gets you a target the machine can read. It does not pull the trigger.
## What this means if you build with agents
If you hand your coding agent one-line prompts and get back plausible code that breaks on the second user, the fix is not a smarter model. It is a less ambiguous instruction. You do not need to adopt EARS formally to get the benefit. You need to write requirements the way EARS forces you to: state the trigger, state the exact behavior, and always write the "if this goes wrong, then the system shall" case, because that is the one your agent will otherwise invent for you.
A requirements syntax built for jet engines turns out to be the right shape for the age of coding agents, for a reason that has nothing to do with aerospace. The literal reader rewards the precise writer. EARS just happens to be the cleanest way anyone has found to write precisely.
## FAQ
### What is EARS notation?
EARS notation, the Easy Approach to Requirements Syntax, is a structured way to write natural-language requirements using a small set of keywords and a fixed clause order. Developed by Alistair Mavin and colleagues at Rolls-Royce in 2009, it constrains every requirement to the shape "While ``, when ``, the `` shall ``," which removes the ambiguity that makes ordinary requirements hard to build and impossible to test cleanly.
### What are the five EARS patterns?
The five patterns are ubiquitous (always true: "the system shall encrypt all stored passwords"), event-driven (triggered: "when a user submits the form, the system shall send an email"), state-driven (conditional on a state: "while a payment is processing, the system shall disable the button"), unwanted behavior (error handling: "if the provider returns an error, then the system shall display the failure"), and optional feature (scoped to a configuration: "where 2FA is enabled, the system shall require a code"). Almost every requirement you need to write fits one of these five shapes.
### Why is EARS used in spec-driven development and AI coding?
Because an AI agent reads a requirement literally, and a constrained sentence is a more reliable instruction than a fluent paragraph. Tools like Amazon's Kiro generate acceptance criteria in EARS, and the GitHub Spec Kit team is debating adding it, precisely because EARS templates produce specs that agents parse consistently. A well-formed EARS requirement is also already an acceptance criterion, so the same syntax that makes intent unambiguous makes "done" checkable, which is the core of [spec-driven development](/spec-driven-development).
### What is the difference between EARS notation and acceptance criteria?
They overlap heavily. EARS is a syntax for writing any requirement clearly; an acceptance criterion is a condition that defines when a feature is done. The connection is that a requirement written in EARS is usually already a good acceptance criterion, because "when X, the system shall Y" is both a statement of intent and a checkable test. For the full craft of writing criteria an agent can verify, see [how to write acceptance criteria an AI agent can actually verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
### Do I have to use EARS to write good requirements for AI agents?
No. EARS is one disciplined way to hit the target, not the only one. What matters is that your requirement names the exact trigger, the exact system, the exact response, and the unwanted-path behavior, which is precisely the discipline EARS enforces. You can get the same benefit by writing that way without ever learning the acronym, which is essentially what BrainGrid's Planning Agent does for you when it turns a plain-language idea into structured, verifiable criteria.
*[BrainGrid](https://braingrid.ai) is the plan-first platform that turns your idea into requirements and acceptance criteria your agent can build and verify against. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is a CLAUDE.md File? The One Anthropic's Own Docs Tell You to Keep Short
Source: https://www.braingrid.ai/blog/what-is-a-claude-md-file
Published: 2026-08-09T12:00:00Z
Everyone tells you to write a CLAUDE.md file, and almost nobody tells you what it is actually for. So you create one, paste in everything you can think of, and watch your agent behave beautifully for a week. Then it starts ignoring the file you spent an afternoon on, and a thread titled ["What is the point of CLAUDE.md?"](https://www.reddit.com/r/ClaudeAI/comments/1nokaln/what_is_the_point_of_claudemd/) with 180 comments suddenly makes total sense.
Here is the claim worth sitting with. A CLAUDE.md file is not your project's memory. It is a set of standing instructions the model reads at the start of a session, and the more you treat it like a durable record of what your product is supposed to be, the faster it turns into a liability.
## What a CLAUDE.md file actually is
A CLAUDE.md file is a plain Markdown file that [Claude Code](https://code.claude.com/docs/en/memory) reads automatically at the start of every session. It goes in your project's root, you write it by hand, and it holds the things the agent would otherwise have to guess: your tech stack, your build and test commands, your coding conventions, the folders it should not touch. Anthropic's own docs describe it as persistent instructions for a project. The keyword there is instructions, not knowledge.
That distinction is the whole post. The file is prepended to the conversation, so it costs context tokens on every single turn. It is not a database the agent queries when it needs something. It is a preamble it carries the entire time, whether the current task needs those rules or not. Which is exactly why the advice that actually works, once you get past "just write one," is to keep it short.
The counterintuitive part is that cutting the file down often makes the agent better, not worse. One builder [reported cutting roughly 80% of his Claude Code context](https://x.com/kingwilliam_/status/2083596741719261535) and getting sharper results, echoing guidance from Anthropic's own team that less instruction beats more. That reframes the file from a place to hoard context into a budget you spend carefully. A 400-line CLAUDE.md is not a well-documented project. It is a 400-line tax on every request, and past a certain point the model starts skimming it, which is the exact behavior the Reddit thread was complaining about.
## What goes inside a CLAUDE.md file
The useful contents are narrow and stable. Think of the small set of facts that are true today and will still be true next month: the frameworks you use, the command to run tests, the command to build, the linter you enforce, the one architectural rule you never want violated ("all API calls go through the client in `lib/api`, never fetch directly"). These earn their place because they change slowly and apply to nearly every task.
Here is the difference between a file that helps and one that rots, side by side.
Rots: "We migrated the auth flow last Tuesday and the new endpoint is `/v2/login`, but the old one still works for now, and Sarah is refactoring the session handling this sprint so check with her before touching it."
Helps: "Auth lives in `src/auth`. Run `pnpm test:auth` after any change there."
The first one is a status update. It will be false in a week, and when it is, the agent will confidently act on it anyway. The second is a durable fact about where things live and how to verify them. One is a note to a coworker. The other is a rule for a machine.
## Should you commit your CLAUDE.md file?
Yes, for the project-level file. The whole value is that everyone on the team, and every remote agent, loads the exact same rules. Commit the `CLAUDE.md` in your repo root the way you commit your linter config, because it is the same kind of artifact: a shared standard, not a personal preference. Check it into Git and your agent behaves consistently no matter who runs it or where.
Your personal, machine-wide file (the one in `~/.claude/`) is different. It holds your individual workflow quirks, it lives in your home directory outside any repo, and it should stay there. The rule of thumb: project rules are team property and get committed; personal preferences are yours and do not.
## The reframe: instructions are not a record
Now the part that most "how to write a great CLAUDE.md" posts miss. Builders keep reaching for CLAUDE.md, or Claude's auto-memory, to solve a problem it was never designed for: remembering what the product is supposed to do. What did we decide about how billing works? Why is this feature built the way it is? What counts as done for the checkout flow? That is not instruction. That is your product's record, and stuffing it into a file the model skims on every turn is how it goes wrong.
The evidence for this is everywhere once you look. In a recent [r/ClaudeCode thread on whether anyone actually uses Claude's memory feature](https://www.reddit.com/r/ClaudeCode/comments/1vfcmmw/), four separate builders landed on the same verdict without coordinating. One put it bluntly:
> I made the mistake of trying to use it for project knowledge and now it is bleeding into other projects smh. Don't be like me.
Others in the same thread said it "quickly gets outdated," that it stayed "entirely opaque" for a month before they noticed a wrong note, and that memory "should be reserved for user preferences and nothing more. Not for actual knowledge." Four people, one conclusion: the model's memory is a preference store, not a project record. It bleeds, it goes stale, and you cannot see what is in it.
This is the capability point that does not go away as models improve. Better models make it more tempting to offload durable knowledge into the model's context, not less, because the agent feels smart enough to trust. But a smarter agent working from a stale note is not more reliable. It is more confidently wrong, and harder to debug, because the mistake traces back to something it "remembered" that stopped being true weeks ago. Models are stateless. Your product isn't. (If you want the deeper version of why auto-memory rots, we wrote it up in [the state file pattern](/blog/claude-code-memory-state-file-pattern).)
## Where the product record actually belongs
So if instructions live in CLAUDE.md and durable knowledge does not belong in memory, where does the record of what your product is supposed to do actually live? Outside the model, in something you own and update deliberately.
This is the gap [BrainGrid](https://braingrid.ai) fills. You describe a feature, and the Planning Agent turns it into a requirement with explicit acceptance criteria, the specific, checkable statements of what done means for that feature. When the Builder Agent builds it, whether in a BrainGrid Cloud sandbox or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP, verification checks the result against every one of those criteria before the feature counts as done. And all of it, the specs, the decisions, the criteria, the verifications, accumulates per product as a record you can read.
The difference from a CLAUDE.md file is the point. CLAUDE.md tells the agent how you work: your commands, your conventions, your house rules. The product record holds what you decided and why, and it does not depend on the model remembering anything. One is a preamble the model reads. The other is the source of truth the model is checked against. You still want a lean CLAUDE.md. You just stop asking it to be something it was never built to be. This is the heart of [context engineering](/context-engineering): deciding what the model should carry in its head, and what belongs in a record outside it.
## The one trade-off worth naming
Keeping durable knowledge out of the model's context has a real cost: it is more work up front. Writing an acceptance criterion is slower than typing a sentence into a chat and hoping the agent remembers it. The lazy path genuinely feels faster on day one. It just stops feeling faster the first time you spend an afternoon debugging behavior that traces back to a note nobody knew was there. The effortless option rots. The deliberate one compounds. That is the trade, and it is worth making on any project you intend to keep.
If you're building a real product with Claude Code or Cursor right now, this means your CLAUDE.md should get shorter over time, not longer, and the knowledge you were tempted to cram into it needs a home the model doesn't own.
## FAQ
### Is a CLAUDE.md file necessary?
Not strictly, but it is worth it for any project you return to. Without one, the agent re-guesses your stack, your commands, and your conventions every session, and guesses wrong often enough to waste real time. A short, accurate CLAUDE.md removes that friction. Skip it only for a throwaway experiment you will never open again.
### What do you put in a CLAUDE.md file?
The stable facts an agent needs on nearly every task: your tech stack, the commands to run and test and build the project, your core coding conventions, and the hard rules you never want broken. Keep it lean. Leave out anything that changes week to week, like current sprint status or in-progress decisions, because that is exactly what goes stale and misleads the agent later.
### Should I commit my CLAUDE.md file to Git?
Commit the project-level `CLAUDE.md` in your repo root, because its value is that every teammate and every agent loads the same rules. Do not worry about the personal file in your home directory (`~/.claude/CLAUDE.md`); it lives outside the repo and holds your individual preferences, so it stays local by design.
### Why does Claude ignore my CLAUDE.md file?
Usually because the file is too long. Everything in CLAUDE.md is prepended to every request, so a bloated file both costs tokens on every turn and gets skimmed rather than followed. Cut it to the rules that matter most, phrase them as clear directives, and the model follows them far more reliably. If a rule is critical, keeping it near the top and stated plainly helps.
### Is a CLAUDE.md file the same as agent memory?
No. CLAUDE.md is instructions you write and control, read at the start of each session. Auto-memory is notes the agent writes for itself in the background, in a Claude-specific location. The file you own stays accurate because you edit it; the notes the agent writes tend to go stale and bleed across projects, which is why most builders reserve memory for preferences and keep real project knowledge in files, or in a [product record](https://braingrid.ai) that lives outside the model entirely.
*[BrainGrid](https://braingrid.ai) is the plan-first platform that gives your product a record the model can be checked against, not just instructions it reads. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is AI-Native Development? (And Why "Disposable Software" Is Only Half True)
Source: https://www.braingrid.ai/blog/ai-native-development
Published: 2026-08-08T12:00:00Z
Search "AI-native development" today and every definition on the first page was written by a platform vendor. IBM, DevOps.com, a half-dozen consultancies, all describing a paradigm where "intelligent agents act as primary implementers" and "platforms enforce guardrails." It reads like the future arriving on schedule, clean and inevitable.
Then you open the Reddit threads where builders actually live in this paradigm, and the tone flips. Under a post titled "Is demand for new software decreasing?", the top comment is three words repeated twice: [software is now disposable](https://www.reddit.com/r/cscareers/comments/1uc8naj). The reply underneath: "I hate this so much."
Same paradigm. Two completely different emotions. The vendors sell AI-native as liberation. The people doing it feel something closer to grief. Both are describing something real, and the gap between them is the most useful thing to understand about where software is going.
Here is the hypothesis this post is going to test: AI-native development is real and worth adopting, "disposable software" is true for a narrower slice of what you build than the grief implies, and the thing that separates the disposable from the durable is not the agent. It's whether a plan and a set of acceptance criteria outlive the chat that produced the code.
## AI-native development, defined honestly
Strip away the vendor gloss and AI-native development means one thing: you build assuming the agent writes most of the code, and you organize your work around that assumption instead of fighting it.
That is a real shift, not a marketing one. In the old model, AI was a consultant on your shoulder. You wrote the code and asked ChatGPT when you got stuck. AI-native inverts the default. The agent writes the first draft of almost everything, and your job moves up a level, to deciding what gets built, describing it precisely enough that the agent can execute, and verifying that what came back actually does the job.
Patrick Debois, who has done more than anyone to name this shift, [frames it as four patterns](https://www.infoq.com/presentations/patterns-ai-native-development/):
> Transitioning from producer to manager, focusing on intent over implementation through spec-driven development, moving from delivery to discovery, and managing agentic knowledge.
Read that list twice and notice what is not on it. None of the four patterns is "write better code." All four are about the work that surrounds the code: intent, management, discovery, memory. The framing reorders the whole job. The thing you used to be paid for, producing code, is now pattern zero, the part the agent handles, and every named pattern lives above it.
That is the honest core of AI-native development. The coding got cheap. Everything around the coding became the actual job. If you have felt your role quietly change from typing to describing and checking, you already work this way, whether or not you have a word for it.
## The old way and the AI-native way, side by side
The difference is easiest to see in a single feature.
Old way: you get a ticket that says "add password reset." You know your codebase, so you open the auth module, write the endpoint, wire up the email, handle the token expiry, and test it as you go. The knowledge of what "done" means lives in your head the entire time, because you are the one holding all the pieces.
AI-native way: you tell an agent "add password reset" and it produces a working-looking flow in four minutes. Now the knowledge that used to live in your head has to live somewhere the agent can see, or it doesn't get applied at all. Did it expire the token after one use? Rate-limit the request endpoint? Invalidate old sessions on reset? The agent will happily skip every one of those unless someone wrote them down, because "add password reset" is not a specification. It's a wish.
That is the whole game. In the old model, the spec could stay implicit because the person writing the code was the person who knew the requirements. In the AI-native model, the writer and the knower are different entities, and anything you don't make explicit is anything the agent is free to get wrong. This is the practical difference between [vibe coding and agentic coding](/blog/vibe-coding-vs-agentic-coding): one accepts whatever the agent produces, the other writes down what "produced correctly" means first.
## Where "disposable software" is actually true
Now the disposability claim, taken seriously.
The builders saying "software is now disposable" are not wrong. There is a large and growing category of software that genuinely is throwaway now, and pretending otherwise would be dishonest. The internal script that reformats a CSV once a quarter. The landing page for a launch that runs for two weeks. The prototype you build to answer a single question in a meeting, screenshot, and never open again. The one-off tool that scrapes a report so you don't have to.
For all of that, disposability is not a loss. It's the point. Building these used to cost an afternoon of a developer's time, which meant they mostly didn't get built. Now they cost ten minutes, so they get built, used, and discarded, and the world is slightly better for it. If the software has a lifespan measured in days and a blast radius of exactly one person, spec-driven rigor is overhead you should skip. Vibe your way through it and move on.
The grief in those threads is real, but a lot of it is misattributed. What feels like "all software is disposable now" is usually "the disposable category got much bigger and much more visible." That is a different and less alarming claim.
## Where it's a bug, not a feature
The line gets crossed the moment other people depend on the thing.
A demo that only you will ever run can be disposable. The customer-facing app it turns into cannot. The script that formats your own CSV can be disposable. The billing job that formats every customer's invoice cannot. The prototype that proves an idea can be disposable. The product you charge money for, that holds someone's data, that you will still be editing in six months, cannot be. Not because rigor is virtuous, but because "disposable" and "load-bearing" are opposites, and you don't get to be both.
Here is the trap AI-native development sets, and it's worth stating plainly because almost nobody warns you about it. The disposable version and the durable version look identical when they're born. The agent produces the same clean, confident, working-looking output either way. That is [the illusion of completeness](/blog/illusion-of-completeness-ai-demo): looking done and being done are different properties, and the agent only guarantees the first one. The demo that will run once and the app that will run for years come out of the same prompt looking equally finished. You cannot tell them apart by looking, which means the moment your throwaway quietly becomes load-bearing, and it will, because the useful ones always do, you inherit a codebase that was never specified, never verified, and never meant to survive.
Disposable software is fine until the day it stops being disposable. And that day never announces itself.
## What makes software non-disposable
So what actually converts a disposable build into a durable one? Not more code. The code is the cheap part now, and adding more of it just gives you more to distrust.
What makes software non-disposable is the layer above the code: a plan that says what this thing is supposed to do, and a set of [acceptance criteria an agent can actually verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify) that says how you'll know it does it. Those two artifacts are what let you change the software next month without fear, because they tell the next agent, and the next you, what must stay true. Code without them is a black box you're afraid to touch. Code with them is a system you can keep evolving. That is the entire difference between something you throw away and something you build on.
This is exactly the gap [BrainGrid](https://braingrid.ai) is built to close, and it's the whole point of practicing [agentic engineering](/agentic-engineering) instead of just prompting faster. You describe what you want, and the Planning Agent turns it into a real requirement with acceptance criteria, the questions you didn't think to ask, and a spec that survives the conversation. Then the Builder Agent writes the code, in our cloud or in your own repo with Claude Code, Cursor, or Codex. And nothing counts as done until it's been verified against those criteria, with evidence that it does what you intended. The agent forgets everything the moment the session ends. The plan and the criteria don't. That persistence is what makes the output something you can depend on instead of something you'll be scared to open later.
It runs as a loop, Plan then Build then Verify then Repeat, and the point of the loop is that the durable version costs you almost nothing extra up front. You get the plan for free by describing the idea, and you get to keep it. The tax of AI-native development was never the coding. It was inheriting code nobody wrote down the intent for. The loop pays that tax at the start, once, instead of every time you come back scared to change something.
## What this means if you're building right now
If you're shipping with agents today, the practical move is not "spec everything" or "spec nothing." It's knowing which side of the line a given build sits on, before you start.
Ask one question: will anyone other than me depend on this, now or later? If the honest answer is no and will stay no, vibe it and enjoy the speed. That is AI-native development working exactly as advertised, and the disposability is a gift. If the answer is yes, or if there's a real chance a throwaway becomes something people rely on, then the ten minutes you spend writing down what "done" means is the cheapest insurance you will ever buy. You are not adding process. You are refusing to inherit a load-bearing black box.
The verdict on the hypothesis: AI-native development is real, disposable software is real, and the grief is mostly about not knowing where the line is. The line is dependence. Below it, throwaway is a feature. Above it, the plan and the criteria are what turn the agent's confident output into something you can actually trust. The agent gave you the code for free. The intent is the part you have to keep.
## FAQ
### What is AI-native development?
AI-native development is an approach to building software where you assume AI agents write most of the code and you organize your work around that assumption. Instead of AI acting as an occasional assistant while you write the code yourself, the agent produces the first draft of almost everything, and your job shifts up a level: deciding what to build, specifying it precisely, and verifying that the result does what you intended. The four recurring patterns are moving from producer to manager, focusing on intent over implementation through spec-driven development, shifting from delivery to discovery, and managing knowledge so context survives across sessions.
### What are the 4 patterns of AI-native development?
The four patterns, as named by Patrick Debois, are: (1) transitioning from producer to manager, where you operate and review agent output instead of writing every line; (2) focusing on intent over implementation through spec-driven development, where living specifications matter more than granular code; (3) moving from delivery to discovery, where the work shifts from shipping known features to exploring what should exist; and (4) managing agentic knowledge, where feedback from code, tickets, and incidents continuously updates the context your agents work from. All four are about the work surrounding the code, not the code itself.
### What is the difference between AI-native and AI-first?
AI-first usually means AI is a priority or a default tool in how you work, bolted onto an existing process. AI-native means the process itself was designed from the ground up assuming AI does the core work, the way "cloud-native" meant designing for the cloud rather than lifting an old app into it. In practice, an AI-first team adds an agent to its existing workflow; an AI-native team rebuilds the workflow around the agent, which is why intent, specification, and verification become the load-bearing skills rather than typing speed.
### Is AI-native development the same as vibe coding?
No, though they overlap. Vibe coding means prompting an agent and accepting what comes back without a written spec or verification, which is a legitimate mode for throwaway work. AI-native development is the broader practice of building around agents, and for anything that needs to last it adds the discipline vibe coding skips: a plan, acceptance criteria, and verification against them. Vibe coding is one style of AI-native work that is fine when the software is disposable and dangerous the moment it becomes something people depend on.
### Does AI-native development mean software is disposable now?
Only for a specific slice of it. Software that one person uses briefly, a one-off script, a short-lived landing page, a throwaway prototype, genuinely is disposable now, and that category has grown a lot. But the moment other people depend on the software, or a throwaway quietly becomes load-bearing, disposability turns from a feature into a liability. The dividing line is dependence, and what keeps depended-on software from being disposable is a plan and acceptance criteria that outlive the code.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform: it plans before it builds, then verifies every change against acceptance criteria, so the software you depend on never has to be disposable. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is an Agent Loop? The Reason-Act-Observe Cycle, Explained
Source: https://www.braingrid.ai/blog/what-is-an-agent-loop
Published: 2026-08-07T12:00:00Z
A chatbot answers you once and stops. An agent keeps going until the job is done. The difference between the two is not a bigger model or a cleverer prompt. It is a loop.
That loop is the most important idea in AI building right now, and it is also the most misunderstood. The search volume for "agent loop" is up more than 1,000% in a year, and half the explanations you will find describe the mechanism perfectly while missing the part that actually determines whether your agent ships something good or burns through your budget producing confident garbage. The mechanism is simple. What you feed it is the whole game.
## What an agent loop actually is
An agent loop is a cycle: the model reasons about a task, takes an action using a tool, observes the result, and then repeats, feeding what it just learned back into the next turn. It keeps going until it decides the work is done or it hits a limit you set.
Strip away the diagrams and it is four moves. Reason: the model looks at the task and its history and decides what to do next. Act: it calls a tool, running a terminal command, editing a file, hitting an API. Observe: it reads what came back, including the errors. Repeat: it writes that result into its own context and starts the next turn with more information than it had before.
That fourth step is the one that matters. Anyone can call a model and get a paragraph. Writing the result back into the context, so the next turn is informed by the last, is what turns a stateless text generator into something that can pursue a goal across many steps. Simon Willison put the whole thing about as bluntly as it can be put:
> An LLM agent runs tools in a loop to achieve a goal.
>
> [Simon Willison](https://simonwillison.net/2025/Sep/18/agents/)
LangChain's team, writing about how they build agents, describe the core the same way:
> At its core, an agent is just a model calling tools in a loop until a task is complete.
>
> [LangChain, "The Art of Loop Engineering"](https://www.langchain.com/blog/the-art-of-loop-engineering)
If you have used Claude Code, Cursor's agent mode, or Codex, you have watched this happen. You ask for a feature. The agent reads a file, tries an edit, runs the tests, sees three of them fail, reads the error, fixes the edit, runs the tests again. Each of those is one turn through the loop. You did not prompt it five times. You prompted it once, and the loop did the other four turns on its own. Chain a few of these loops together across a whole task and you get an [agentic workflow](/blog/what-is-an-agentic-workflow); the loop is the atom that everything larger is built from.
## Why the loop, not the model, is the unlock
Here is the reframe most explainers skip. The loop is not a feature of the model. It is a feature of the harness wrapped around the model. The same model that gives you one flat answer in a chat window becomes an agent the moment you put it in a loop that can act and observe.
This is why the last two years felt like such a step change even when the underlying models improved only incrementally. a16z's Yoko Li described the shift precisely this week:
> An AI model can almost always produce another answer. It can revise the paragraph again. It can try another implementation. Instead of a human prompting a model, inspecting the result, describing what went wrong, and prompting it again, we can ask the system to perform the whole cycle itself.
>
> [Yoko Li, a16z](https://x.com/a16z/status/2085448947359965220)
That is the promise. The human used to be the loop, prompting and inspecting and re-prompting by hand. Now the system runs the cycle itself, and you step up a level to design the loop instead of running it. It is a genuine gain in leverage, one full step up the ladder.
It is also a genuine transfer of risk, and this is the part the excited version leaves out.
## The loop's blind spot: it does not know what "done" means
A loop can act. A loop can observe. A loop can repeat. The one thing a loop cannot do is tell you whether the thing it produced is actually right. It only knows whether it finished.
That gap is not academic. It is the single most common failure builders describe, and this week I watched three people, in three different corners of the internet, name the same thing from three different directions. An agent-ops practitioner put it as a distinction:
> When the loop stops, teams are tempted to mark success. But an agent can stop after a tool error or an unconfirmed write. Completion is a runtime event. Success is a verified state.
>
> [Stanislav Sorokin](https://x.com/stas_sorokin_/status/2083480323476656211)
Completion is a runtime event. Success is a verified state. Nine words, and they carry the entire problem. The loop terminates when the model returns a final answer with no pending tool calls. That is completion. Whether the feature it built does what you wanted, handles the edge cases, guards the auth route, and does not silently break the thing next to it, that is success, and the loop has no idea. It stopped. That is all it knows.
A builder in r/ClaudeCode arrived at the fix on their own, without a vendor telling them to:
> You need a receipt for each a,b,c agent. That receipt, verified, becomes the record. That's how you not only perform loop engineering, but auditable loop engineering.
>
> [r/ClaudeCode commenter](https://www.reddit.com/r/ClaudeCode/comments/1vdmg1n/)
They reinvented acceptance criteria and evidence from scratch because they needed them and nothing shipped them. That is the tell. When people independently build the same missing piece, the piece is not optional. It is load-bearing, and the loop leaves it out.
Without something to check against, a loop that runs longer does not get you closer to done. It gets you a more expensive way to be wrong. A commenter in r/VibeCodeDevs said it in one line:
> Without those guardrails, loop engineering stops being leverage and just becomes an expensive way to keep the meter running.
>
> [r/VibeCodeDevs commenter](https://www.reddit.com/r/VibeCodeDevs/comments/1vcf5r1/)
## What changes for you
If you are building with an agent right now, this means your job moved. It did not disappear. When you were prompting one step at a time, you were the verifier: you read each response, caught the wrong turn, and corrected it before the next step. The loop takes that seat. Nobody is reading each turn anymore, which means the standard the agent is checked against has to exist before the run, not in your head during it.
Concretely, the difference looks like this.
> Loop with no target: "Build a contact management view." The agent builds a table, calls it done, and stops. It works in the demo. It has no auth guard, the filter breaks on an empty state, and you find out in production.
>
> Loop with a target: "Build a contact management view. Sortable table with name, company, last-contacted date. Row click opens a detail panel. Only authenticated users can access it; unauthenticated users redirect to /login. Empty state shows a 'no contacts yet' message." Now the loop has something to check itself against, and "done" means every one of those is true.
The second version is not a better prompt. It is a definition of done the loop can verify against. That is the input the loop cannot generate for itself, and it is exactly where the whole approach lives or dies.
## Where BrainGrid fits
This is the gap BrainGrid is built to close. The loop is a powerful engine with no steering wheel, and the steering wheel is a plan with acceptance criteria. In BrainGrid, you describe what you want to build and the Planning Agent turns it into a requirement with [acceptance criteria](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify), the observable, testable conditions that define done, before any code runs. Then the Builder Agent runs the [loop](/loop), either in a BrainGrid Cloud sandbox with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex. When the loop stops, the work is checked against those criteria, and a feature is not done until the evidence says it does what you intended.
That is the receipt the r/ClaudeCode builder wanted, generated for you instead of hand-rolled. The loop still does the acting and observing. BrainGrid supplies the one thing the loop cannot: a definition of done that outlives any single run and a record of whether the run met it.
The honest trade-off: writing acceptance criteria up front is work, and for a throwaway script it is work you can skip. Nobody needs a verified definition of done for a one-off data cleanup. The moment the thing you are building is something other people will use, though, the criteria stop being overhead and become the only thing standing between "the loop finished" and "the feature works."
## The loop is the engine. The spec is the destination.
An agent loop is reason, act, observe, repeat, running until a stop condition is met. That is what turns a model into an agent, and it is genuinely the most important primitive in AI building today. But a loop optimizes for termination, not correctness. It will happily stop on a broken result and report success, because stopping is the only signal it has.
The models will keep getting better at running the loop. They will not get better at knowing what you meant. That part is still yours, and the way you hand it to the agent is a plan it can check itself against. Give the loop a destination and it becomes leverage. Give it none and it becomes a very fast way to arrive somewhere you did not want to go.
## FAQ
### What is an agent loop?
An agent loop is the continuous cycle an AI agent runs to complete a task: it reasons about what to do next, takes an action using a tool, observes the result, and repeats, feeding each result back into its context until it reaches a stop condition. This loop is what separates an agent, which can pursue a multi-step goal, from a chatbot, which answers once and stops.
### What are the steps in an agent loop?
Most agent loops have four stages. Reason: the model evaluates the task and decides the next step. Act: it executes a tool, such as running a command, editing a file, or calling an API. Observe: it reads the output or error and feeds it back into its context. Repeat: it starts the next turn with that new information. The fourth step, writing the result back so the next turn is better informed, is what makes it an agent rather than a series of one-off answers.
### How does an agent loop stop?
A loop ends when the model returns a final answer with no pending tool calls, meaning it believes the work is complete. Harnesses also add safety limits: caps on the number of iterations, a wall-clock time budget, a token budget, and error detection that breaks out when the agent keeps retrying the same failing action. Reaching a stop condition tells you the loop finished; it does not tell you the result is correct.
### What is the difference between an agent loop and loop engineering?
An agent loop is the underlying cycle, reason, act, observe, repeat. [Loop engineering](/blog/loop-engineering) is the practice of designing the system that runs those loops for you, on a schedule, so you are no longer prompting the agent by hand. Put simply, the agent loop is the engine, and loop engineering is the discipline of building and steering a fleet of those engines.
### Why does my AI agent say it's done when the code is broken?
Because the loop's stop condition is completion, not correctness. The agent stops when it has no more actions queued, which can happen even after a tool error or an unverified change. The loop has no built-in notion of whether the result matches what you wanted. The fix is to give it an external standard to check against, acceptance criteria that define done in observable, testable terms, so "finished" and "correct" stop being the same claim.
*[BrainGrid](https://braingrid.ai) is the system that takes an idea to a live product you can trust, giving your agent's loop the one thing it can't supply itself: a plan with acceptance criteria to verify against. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is a System Prompt? Where Your Durable Instructions Actually Belong
Source: https://www.braingrid.ai/blog/what-is-a-system-prompt
Published: 2026-08-06T12:00:00Z
A system prompt is the most powerful instruction you can give an AI model, and it is the wrong place to put almost everything people cram into it.
That sounds backwards. The system prompt sits above every other message, it steers tone, format, and behavior across the whole conversation, and it is the first thing most builders reach for when their agent misbehaves. So the instinct is to keep adding to it. When the agent forgets a rule, you add the rule to the system prompt. When it uses the wrong style, you add the style. A month in, your system prompt is a 400-line rulebook, and the agent still drifts.
The problem is not that the system prompt is weak. It is that you have been using it as a filing cabinet for things that were never supposed to live in a prompt at all.
## What a System Prompt Actually Is
A system prompt is a set of standing instructions given to a language model before it ever sees a user's message. It defines how the model should behave across the entire session: its role, its tone, its constraints, the format it should answer in. NIST's glossary puts it precisely: system prompts are ["application-specific instructions provided in-context to a GenAI system by the model developer or application designer."](https://csrc.nist.gov/glossary/term/system_prompt) They are the ambient behavior layer.
Think of it as the difference between a job description and a task. The system prompt is the job description. It says "you are a senior code reviewer, you respond in plain language, you never approve code you cannot explain." The user prompt is the task: "review this pull request." The job description is set once and applies to everything. The task changes every time.
Every major model exposes this layer. In the OpenAI, Anthropic, and Google APIs, you pass a `system` role (or a system instruction) separate from the `user` turns. In consumer tools, it is the "custom instructions" or "personality" field. In coding agents, it shows up as the file the agent reads on startup, `CLAUDE.md` for Claude Code, [`AGENTS.md`](/blog/agents-md-explained) for the broader ecosystem, the ambient context that shapes every response before you type a word.
## System Prompt vs User Prompt: The Distinction That Matters
The cleanest way to understand a system prompt is by what it is not. A user prompt is a single request in a single turn. A system prompt is the standing context that request lands in.
> System prompt: "You are a technical writer for a developer audience. Write in short paragraphs. Never use marketing language. Always include a concrete code example when explaining an API."
>
> User prompt: "Explain how our webhook signing works."
Swap the user prompt for a hundred different questions and the system prompt still holds. That persistence is the whole point, and it is also the trap. Because the system prompt persists, it feels like the natural home for anything you want the agent to remember. Your API conventions. Your database schema. The acceptance criteria for the feature you are shipping this week.
That is where builders go wrong. Persistence across a conversation is not the same as being the durable record of your product. A system prompt lives inside one model's context window, for one session, and it is invisible to everyone but you. Push project knowledge into it and you have created a record that only exists as long as the chat does.
## The System Prompt Is Not Your Product's Memory
Here is the reframe. Builders keep discovering, the expensive way, that the model's context is a bad place to store what the product actually needs to know.
The clearest recent evidence came from a Claude Code thread where someone asked whether anyone actually uses the [built-in memory feature](/blog/claude-code-memory-state-file-pattern) as a project record. The answers were unanimous, and none of them were kind. One developer had tried exactly that and [regretted it](https://www.reddit.com/r/ClaudeCode/comments/1vfcmmw/):
> I made the mistake of trying to use it for project knowledge and now it is bleeding into other projects smh. Don't be like me.
Others in the same thread reported the same failure from different angles. The memory was ["entirely opaque"](https://www.reddit.com/r/ClaudeCode/comments/1vfcmmw/) and a wrong entry went undiscovered for a month. Another disabled it outright because ["it quickly gets outdated."](https://www.reddit.com/r/ClaudeCode/comments/1vfcmmw/) The consensus that emerged was a rule worth writing down: memory is for user preferences, not for knowledge. Behavior, not facts.
That rule applies to your system prompt too, because a system prompt and an agent's memory are the same kind of thing. Both are ambient context. Both shape behavior. Both go stale silently, because nothing checks them against reality. The moment you use either one to hold your product's requirements, you have made a record that bleeds, drifts, and lies without telling you.
The counterargument is fair, and you should sit with it: any written record goes stale, including the one you keep outside the model. That is true. But there is a difference between a record you can see, version, and verify against, and one buried in a context window you never read. A builder in another thread named the discipline that makes a written record survive: ["the wiki must reflect the current state 100%."](https://www.reddit.com/r/ClaudeCode/comments/1vgd4g2/) You cannot enforce that on a system prompt you last touched three weeks ago and cannot inspect. You can enforce it on a plan you own.
## What Belongs in a System Prompt, and What Doesn't
The useful line to draw is between *how* your agent works and *what* it is building.
The system prompt is for the "how." Your conventions, your tone, your formatting rules, the commands the agent should run, the mistakes it made last week that you turned into a standing instruction. These are true across every feature. They are ambient by nature, and the system prompt is exactly where they should live.
The "what" is different. The requirements for the feature you are shipping, the acceptance criteria that define done, the specific behavior the code must exhibit, none of that is ambient. It is specific, it changes per feature, and it needs to be verifiable. Put it in the system prompt and it competes for attention with everything else in the window, degrades as the session grows, and leaves you no artifact to check the finished work against.
Compare the two failure modes:
> The agent behaves inconsistently across a session: it forgets your code style, ignores your naming convention, switches tone. That is a system prompt problem. Fix the "how" in the ambient layer.
>
> The agent builds the wrong thing, or builds something that looks right and breaks in production. That is not a prompt problem at all. That is a missing spec. No system prompt is going to define "done" for a feature it has never heard of.
This is the gap BrainGrid is built to close. The **Planning Agent** takes the feature you describe and turns it into a requirement with real acceptance criteria, the "what" written down as statements you can verify, not buried in a prompt. That requirement is the durable record. When the **Builder Agent** writes the code, in BrainGrid Cloud or in your own GitHub repo with Claude Code, Cursor, or Codex over MCP, the acceptance criteria are what the work gets checked against. A feature is not done because the agent stopped. It is done because every criterion is verified with evidence.
The system prompt still matters. It carries how your agent works. But the thing that defines whether the build is correct lives in the plan, where you can see it, version it, and hold the finished code up against it. Models are stateless. Your product is not.
## The Practical Version
If you are debugging an agent that keeps misbehaving, the fastest triage is to ask which layer the problem lives in.
If the agent's *behavior* is off, tone, format, ignoring a convention, that is your system prompt. Tighten it, and keep it short. A shorter system prompt attends better than a long one, the same reason a bloated context window makes an agent [dumber, not smarter](/blog/context-rot). Deciding what earns a place in that ambient layer, and what belongs somewhere the model can be checked against, is the whole discipline of [context engineering](/context-engineering). Boris Cherny, who built Claude Code, found that [cutting context beat adding it](https://x.com/kingwilliam_/status/2083596741719261535) for the tool itself.
If the agent builds the *wrong thing*, stop editing the prompt. No amount of ambient instruction defines a feature the agent was never given. Write the requirement, with acceptance criteria, somewhere you own and can verify against. Then let the agent build against that.
The system prompt sets the stage. It does not write the play.
## FAQ
### What does a system prompt mean?
A system prompt is a set of standing instructions given to an AI model before any user message, defining how it behaves across the whole session: its role, tone, constraints, and output format. It is the ambient behavior layer that applies to every response, as opposed to a single request. Most model APIs expose it as a separate `system` role.
### What is the difference between a system prompt and a user prompt?
A user prompt is a single request in a single turn ("review this pull request"). A system prompt is the persistent context that request lands in ("you are a senior code reviewer who responds in plain language"). The user prompt changes every turn; the system prompt is set once and shapes all of them. The system prompt is the job description, the user prompt is the task.
### Do I need a system prompt?
For a one-off question, no. For anything you use repeatedly, yes: a good system prompt reduces the instructions you have to repeat in every message, lowers token usage, and makes responses more predictable. But keep it to behavior and conventions, the "how." Do not use it to store your product's requirements or a feature's acceptance criteria, which belong in a plan you can verify against, not in ambient context.
### What is the system prompt in ChatGPT?
In ChatGPT, the system-level instructions come from OpenAI's own hidden system prompt plus your "custom instructions," the fields where you tell it how to respond across all chats. In the API, you set it explicitly with the `system` (or `developer`) role. Either way it plays the same part: standing behavior applied before your actual message.
### Can a system prompt go stale?
Yes, and this is its main risk as a knowledge store. A system prompt is invisible ambient context that nothing checks against reality, so outdated instructions sit there silently steering the model wrong. That is why it should hold durable behavior, not fast-changing project facts. Requirements that change per feature belong in a record you can inspect and version, not in a prompt you last edited weeks ago.
Your agent's behavior belongs in the system prompt. What it is building belongs in a plan you can verify against.
*[BrainGrid](https://braingrid.ai) is the system that takes an idea to a live product you can trust, turning what you want built into requirements with acceptance criteria your coding agent can be verified against. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The Illusion of Completeness: Why Your AI Demo Feels Done and Isn't
Source: https://www.braingrid.ai/blog/illusion-of-completeness-ai-demo
Published: 2026-08-05T12:00:00Z
Your AI-built app looks done. The screens render, the buttons click, the demo you showed a friend got a "wait, you built that?" And yet you have not shipped it, and if you are honest about why, it is not a to-do item you can name. It is a feeling. Something about it is not finished, and you cannot point to the part that is missing.
That feeling is correct, and it has a name. The demo is complete the way a movie set is a house: convincing from the one angle you were meant to look at, and hollow from every other. The reason you cannot name the missing part is that the missing part is, by definition, the thing nobody built and nobody wrote down. This is the illusion of completeness, and understanding it is the difference between a builder who ships and one who stalls on app number one forever.
## Looks-done and is-done are two different states
Start with the honest version of what an AI coding tool actually does when it hands you a working demo. It builds the path you described. You asked for a login screen, a dashboard, and a way to add a record, so it built a login screen, a dashboard, and a way to add a record. Run it exactly the way you demoed it, with the one account you created and the three rows of data you typed in, and it works flawlessly. That is not a trick. It genuinely does the thing you asked for.
The illusion is not that the demo is fake. The illusion is that "does the thing I asked for, the way I asked for it" feels identical to "is a product," and it is not. A product is what happens when a second person logs in and can see the first person's data. It is what happens when someone leaves a required field blank, or pastes a 900-character name, or clicks submit twice because the first click seemed slow. It is what happens at 2am when the one API you depend on returns an error instead of an answer. None of those paths were in your demo, so none of them were built, and the app has no idea they exist.
Here is the reframe the whole piece rests on. A demo proves your app *can* exist. It does not prove your app *works*. Those sound like the same claim. They are as far apart as a blueprint and a building you can live in.
## Why AI makes the illusion worse, not better
You might think this is just the normal gap between an MVP and a finished product, the one every builder has always faced. It is that, amplified, and the amplifier is the exact thing that makes AI building feel effortless. Speed.
When building was slow, the gap announced itself. You wrote the login screen by hand, so you knew, viscerally, that you had not yet written the password reset, the "email already taken" case, or the check that stops one user reading another's data. The unfinished parts were unfinished in your own memory. The slowness was annoying, but it was also an honest accounting of what existed.
AI removes the slowness and, with it, the accounting. The agent produces the happy path so fast and so polished that your brain files the whole feature under "done" before you have registered everything the feature would need to actually be done. The output looks like the output of a finished project, because the agent is very good at making the part it built look professional. Polish on the visible path reads as completeness across all paths. It is not.
This is why the felt experience of vibe-coded apps keeps landing on the same wall. Builders describe getting to something that looks shippable and then freezing, unable to trust it. One [r/vibecoding builder](https://www.reddit.com/r/vibecoding/comments/1t0rgxz/) put the fear plainly: they had a working app and could not deploy it, because they did not know how much they could trust the code the agent generated. That is not timidity. That is a builder correctly sensing the gap between looks-done and is-done, without the vocabulary to name it or the tools to close it. An agency that [hardens AI prototypes into production systems](https://ost.agency/services/ai-prototype-to-production/) describes the same gap from the other side, noting that prototypes routinely skip error handling, cost controls, and the unglamorous plumbing, exactly the parts a demo never has to show.
## What actually lives in the gap
The gap is not mysterious once you name what is in it. It is a short, specific list, and it is the same list almost every time.
The first thing missing is anyone who is not you. Your demo has one user: you, with your data, your permissions, your well-behaved inputs. A product has strangers. The moment a second real person signs up, the questions your demo never asked become urgent. Can they see data that is not theirs? What happens when they do the thing you would never think to do? A builder on [r/EntrepreneurRideAlong](https://www.reddit.com/r/EntrepreneurRideAlong/comments/1v3833h/my_first_real_user_found_the_permissions_hole_i/) learned this the hard way when a real user saw another account's data, a permissions hole that existed across eleven different endpoints, none of which the builder's own testing ever tripped, because testing with your own account passes every check by design.
The second thing missing is every path except the one you walked. The demo is the golden path. The product is the golden path plus the empty form, the duplicate submit, the expired session, the network that drops mid-request, the file that is too big, the input that is not what you expected. Each of these is a small decision about what should happen, and in the demo, none of them were decided, because none of them came up.
The third thing missing is the honest failure. A demo never fails in front of you, because you drive it down the one road that works. A product fails in front of users, and the difference between a good product and a scary one is whether it fails loudly and safely or silently and destructively. An agent told to make something "work" will often paper over a broken state with a fallback that hides it, so the app looks healthy while quietly doing the wrong thing. That looks like completeness. It is the opposite: it is the app lying to you about being done.
None of these are code the agent wrote badly. They are behaviors nobody specified, so the agent, having no way to read your mind, did not build them. The gap is not a quality problem. It is a completeness-of-intent problem.
## Closing the gap is a specification problem, not a coding problem
If the missing parts are the parts nobody wrote down, the fix is not "prompt better" or "review harder after the fact." The fix is to write down what done means *before* the build, so the invisible paths become visible requirements the agent can actually build and you can actually check.
Consider the difference in practice.
> The demo instruction: "Build me a page where users can save their notes."
>
> The is-done specification: "Build a notes page. A signed-in user can create, edit, and delete only their own notes, never anyone else's, enforced at the database. Empty notes are rejected with a clear message. If saving fails, the note stays in the editor and the user is told, never silently lost. An unauthenticated visitor is redirected to login."
The first produces a beautiful demo. The second produces something you can trust, because every sentence after the first is one of the invisible paths made explicit. The second version is not longer because it is bureaucratic. It is longer because it is honest about what "a notes page" actually has to do to be a product instead of a screenshot.
This is exactly where [BrainGrid](https://braingrid.ai) sits, and it sits before the first line of code. You describe the feature in plain language, and the Planning Agent asks the questions your demo never asked, the second-user question, the empty-field question, the what-happens-when-it-fails question, and turns your idea into a requirement with explicit acceptance criteria: the testable conditions that define done. Then the [Builder Agent](/ai-coding-agents) builds against that spec, in a managed cloud sandbox with a live preview or in your own repo through Claude Code, Cursor, or Codex over MCP. And here is the part the demo tools skip entirely: verification checks the result against every criterion before it counts as done, so "each user sees only their own notes" is not a hope, it is a checked fact with evidence behind it. That is the [Verify step of the loop](/loop), Plan, Build, Verify, Repeat, and it is the step that turns looks-done into is-done.
The honest trade-off is that this is slower than typing one sentence and watching a demo appear. Writing down what done means takes real thought, and it will feel like friction the first few times, especially when the demo already looks finished and the specification feels like paperwork for something you can already see working. That friction is the point. It is the accounting that speed took away, deliberately put back. You are paying a few minutes of clarity up front to avoid the version where a real user finds the permissions hole for you.
## What this means if you are stuck on your first ship
If you have an AI-built app that looks done but you have not shipped it, and you cannot say exactly why, this is the why. You are not being paranoid, and you do not need to learn to code to get past it. You need to convert the vague dread into a specific list: who else uses this, what can they see, what happens when they do the wrong thing, and how does it fail. Every item on that list is one of the invisible paths, and every one of them is answerable in plain language before you ask the agent to build it.
The builders who ship are not the ones who trust the demo. They are the ones who stopped mistaking a demo for a product, wrote down what the product actually has to do, and built against that instead. The demo was never the finish line. It was the moment the real work became visible, if you knew where to look. For the rest of the missing 20 percent that lives past the demo, [the second 80 percent](/blog/the-second-80-percent) is where that work goes, and [Lovable's limitations](/blog/lovable-limitations) are the same wall seen from inside a single prototype tool.
## FAQ
### Why does my AI app work in the demo but break in production?
Because the demo and production exercise completely different paths. In a demo, you drive the app down the one route you designed, with your own account, your own clean data, and inputs you know it can handle. Production sends real strangers down every other route: a second user whose data must stay separate, an empty or malformed input, a duplicate click, an expired session, a dependency that fails. Your AI tool built the path you demoed and nothing else, because nothing else was described. The app breaks in production not because the code is bad, but because the paths that break were never specified, so they were never built. The fix is to write down what the app must do on those paths before the build, as acceptance criteria the agent builds against and the build is checked on.
### What is the difference between a prototype and a production-ready product?
A prototype proves the idea can exist: it runs, it looks right, and it does the main thing you designed it to do. A production-ready product proves the idea works for people who are not you, under conditions you did not choreograph. The production version handles multiple users with separate data, rejects bad input gracefully, fails loudly and safely instead of silently, guards who can access what, and holds up when a dependency misbehaves. The prototype is one honest angle; the product is every angle. The distance between them is not more code, it is the specific set of behaviors, security rules, and failure cases that a demo never has to show, made explicit and verified.
### Why do AI coding tools make apps that look finished but aren't?
Because they are optimized to produce the visible, happy path fast and make it look polished, and polish on the part you can see reads as completeness across the parts you cannot. When building was slow, the unfinished parts stayed unfinished in your own memory, so you knew what was missing. AI removes that slowness and the built-in accounting that came with it: the agent hands you a professional-looking result before you have registered everything a finished feature would need. It is not deceiving you on purpose. It built exactly what you described, and "what you described" left out every path you did not think to mention.
### How do I know if my AI-built app is actually ready to ship?
Stop testing it as yourself and start testing it against a written definition of done. Create a second account and confirm it cannot see the first account's data. Submit empty and malformed inputs and confirm the app rejects them with clear messages instead of crashing or saving garbage. Force a failure (disconnect the network mid-save) and confirm nothing is silently lost. Check that unauthenticated visitors cannot reach protected pages. If you have not written down what "correct" looks like for each of those, you cannot know if it is ready, because clicking around your own app the way you always do will pass every time by design. Readiness is measured against criteria you set before the build, not against how good the demo felt.
### Is a working demo the same as a minimum viable product?
No. A working demo shows that the core idea functions along the path you designed. A minimum viable product is the smallest version real users can actually rely on, which means it also has to handle the users, inputs, and failures your demo never encountered: separate data per user, graceful handling of bad input, safe failure, basic access control. A demo can become an MVP, but only after you close the gap between the path you showed and the paths real people will take. The demo is where the visible work ends and the real work becomes visible.
*[BrainGrid](https://braingrid.ai) is the AI product planner that turns your idea into a requirement with acceptance criteria, then verifies every build against them, so looks-done becomes is-done before you ship. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Architecture Decision Records for AI Coding Agents: Where the Why Lives
Source: https://www.braingrid.ai/blog/architecture-decision-records-for-ai-coding-agents
Published: 2026-08-04T00:00:00Z
Your git history remembers every line your agent wrote. It remembers nothing about why.
Fork a branch a week later and the code is all there, exactly as you left it. What is gone is the argument. The option you rejected, the reason you went one way instead of the other, the constraint that made an obvious choice wrong: none of that is on disk. A builder on [r/ClaudeCode](https://www.reddit.com/r/ClaudeCode/comments/1v6yc26/) described the exact moment this bites, resuming a session and staring at their own conclusion with no idea how they got there:
> the reasoning is the part nothing stores. that only exists at the moment you branch.
That line names a gap that predates AI by decades, and has a decades-old fix. It is called an architecture decision record. What changed is that the fix stopped being optional. When a stateless agent is doing most of the typing, the reasoning behind your decisions is the one thing it cannot reconstruct, and the one thing it will silently overwrite if you never wrote it down.
## What an Architecture Decision Record Actually Is
An architecture decision record, or ADR, is a short document that captures one meaningful decision: the context that forced it, the options you weighed, the choice you made, and the consequences you accepted. Michael Nygard proposed the format in 2011, and [Martin Fowler](https://martinfowler.com/bliki/ArchitectureDecisionRecord.html) describes it as a document that captures and explains a single decision relevant to a product. The convention that matters most: an ADR is immutable. You never edit an accepted record. When a decision changes, you write a new ADR that supersedes the old one, so the trail of why-we-changed-our-mind stays intact.
A minimal ADR is five fields. Title, so you can find it. Status, one of proposed, accepted, or superseded. Context, the forces and constraints in play. Decision, the option you chose. Consequences, the trade-offs you took on, including the options you left behind.
Here is the part the enterprise-architecture write-ups underplay, and the part that matters for anyone building with an agent. The value of an ADR was never the decision. Git already records the decision, in the shape of the code that exists. The value is the *rejected* alternative and the reason. Microsoft's own guidance says the record should document alternatives that you ruled out, not just the winner. That is the expensive knowledge. That is what nobody can recover by reading the diff.
## Why This Went From Nice-to-Have to Load-Bearing
For twenty years, ADRs were a discipline a senior engineer imposed on a team so that the next engineer would not re-litigate a settled question. Useful, easy to skip. The person who made the decision was usually still around to explain it.
Coding agents broke that assumption in two ways.
First, the volume of decisions exploded. An agent running a loop makes dozens of small architectural calls in a single session: which state library, how to shape an API response, whether to cache here or there. Most never surface as a conversation you would remember. They just show up in the code. Second, the agent that made those calls remembers none of them tomorrow. Models are stateless. Every session starts from zero, and everything that scrolled out of the context window is gone. The decision survives as code; the reasoning evaporates.
Now stack a second agent, or the same agent a week later, on top of that code. It reads the result, has no idea a decision was ever made, and cheerfully changes it. This is the mechanism behind the complaint every builder eventually voices: the agent keeps breaking things that already worked. It is not being careless. It is working from a blank slate against a codebase full of invisible, unexplained choices. We wrote about the drift version of this in [why your AI agent keeps breaking things that worked](/blog/why-ai-keeps-breaking-things-that-worked). The decision record is the upstream cause: without it, every choice is a suggestion the next agent is free to overrule.
This is why the fix gets more valuable as the models get better, not less. A more capable agent reads more, writes more, and decides more on its own. More autonomy means more decisions nobody wrote down. The faster your agent moves, the faster it accumulates undocumented reasoning it will later contradict.
## The Diff Shows What. The ADR Shows Why.
Watch the difference on a single choice. Say your agent picks optimistic UI updates for a comments feature.
Without a record, six days later another agent sees latency complaints in an issue, notices the optimistic update, and "fixes" it by making the mutation await the server. It looks like a reasonable change. It quietly reintroduces the exact lag you designed around.
With a record, the same agent reads the ADR first:
> **Title:** Optimistic updates for comment posting
> **Status:** Accepted
> **Context:** Comment round-trip averages 600ms on mobile. Users perceived the feed as broken.
> **Decision:** Render the comment immediately, reconcile on server response, roll back visibly on failure.
> **Consequences:** Rare flash of a comment that fails to post. Accepted over the alternative of a 600ms freeze on every post. Rejected: server-await (too slow), spinner-on-button (still feels broken).
Now the second agent knows the latency was the point, sees that server-await was already considered and rejected, and leaves it alone. Same code. Completely different outcome, because the reasoning traveled with it.
That is the whole job of an ADR. The diff is a perfect record of *what* changed and a useless record of *why*. The ADR carries the why forward to whoever, or whatever, touches the code next.
## Where This Fits, and Where It Falls Short
An ADR is one member of a small family of durable-context files, and it is worth being precise about the division of labor, because builders on the same r/ClaudeCode thread were hand-rolling all of them: a codemap for structure, a decisions file for choices, a frictions file for known sharp edges. This is [context engineering](/context-engineering) in its most practical form, deciding what information survives outside the model's window so a stateless agent can pick the work back up.
A CLAUDE.md or [AGENTS.md](/blog/agents-md-explained) file carries your conventions and commands, the ambient how-we-build context loaded every session. That is a different job from an ADR. Conventions are standing rules; an ADR is a point-in-time record of one choice and its rationale. The state-file version of this, the durable memory an agent reads every morning, we covered in [the state file pattern](/blog/claude-code-memory-state-file-pattern). You want all of it in the repo, in version control, next to the code, so the agent reads it the same way it reads everything else.
Here is the honest limitation, and it is the one that matters. An ADR is a record of a decision already made. It documents the past beautifully and says nothing about whether the thing you are building next is correct. You can keep an immaculate decision log and still point your agent at a feature that was never clearly defined, and it will build the wrong thing with a full paper trail. The record tells the next agent why you chose optimistic updates. It does not tell it what "the comment feature is done" means.
That forward-looking definition is a different artifact, and it is where most agent failures actually originate. An ADR captures why you decided; a requirement with [acceptance criteria an agent can verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify) captures what the agent must build and how you will know it succeeded. One looks back, one looks forward. You need both, and the second is the one a fresh agent checks its work against.
This is the gap [BrainGrid](https://braingrid.ai) is built to close. You describe what you want to build, and the Planning Agent turns it into a requirement with explicit acceptance criteria, the checkable definition of done that an ADR was never meant to supply. The Builder Agent then builds against that requirement, in a managed sandbox with a live preview or in your own GitHub repo through your coding agent over MCP, and a feature is not finished until every criterion is verified with evidence. The requirement and its criteria become the same kind of durable, in-repo record an ADR is, except aimed at the work in front of you instead of the work behind you. The decision record explains the past. The acceptance criteria pin down the present. Together they give a stateless agent something to read that is truer than its own guess.
## What To Do This Week
If you are building with an agent right now, start narrow. Do not try to document everything; you will burn out and the log will rot, which is worse than no log. Write an ADR only when a decision was genuinely contested, when the obvious choice was wrong for a non-obvious reason, or when you can already imagine a future agent undoing it. Five fields, one screen, committed to the repo.
Then point your agent at the folder. Tell it, in your CLAUDE.md, to read `docs/decisions/` before making architectural changes and to write a new record when it makes a consequential one. The agent that keeps a decision log is the one that stops relitigating your settled questions every Monday.
The code was never the expensive part. The reasoning behind it is, and it is the one thing your tools throw away by default. Write down the why, and the next agent inherits your judgment instead of guessing at it.
## FAQ
### How do you write an architecture decision record?
Keep it to five fields on a single page. Title (a short name for the decision), Status (proposed, accepted, or superseded), Context (the forces and constraints that made a decision necessary), Decision (the option you chose), and Consequences (the trade-offs you accepted, including the alternatives you rejected and why). Write it in Markdown, store it in your repo under a folder like `docs/decisions/`, and treat accepted records as immutable: when a decision changes, add a new record that supersedes the old one rather than editing history.
### What is the architecture decision record format?
The most common format, from Michael Nygard's original proposal, is a short Markdown file with Title, Status, Context, Decision, and Consequences. Variants exist: some teams add Date, Drivers, or an explicit Options section listing pros and cons. The exact fields matter less than the two non-negotiables: capture the rejected alternatives and the reasoning, and keep each record to a single decision. A record that tries to document five decisions at once is a design doc, not an ADR.
### What is the difference between an ADR and an RFC?
An RFC (request for comments) comes before a decision: it proposes a change and invites feedback while the question is still open. An ADR comes after: it records the decision that was made, its rationale, and its consequences. The natural sequence on a significant change is RFC first to gather input, ADR second to memorialize the outcome. For solo builders and small teams working with agents, you often skip the RFC and go straight to a lightweight ADR, because the "comments" step is a conversation with yourself and your agent, not a committee.
### What is an architectural decision?
An architectural decision is a choice about the structure of a system that is expensive or disruptive to reverse later: which state management approach, how services communicate, where data is cached, how authentication is enforced. It is distinct from an ordinary implementation choice like a variable name. The test is reversibility and blast radius. If undoing the choice later would ripple across the codebase or reintroduce a problem you deliberately solved, it is architectural, and it is worth an ADR.
### What makes a good ADR?
A good ADR is short, focused on one decision, and honest about what it rejected. The single most common failure is recording only the winning option, which makes the document a restatement of the code rather than an explanation of it. Capture the alternatives you ruled out and the reason each lost, because that is the knowledge nobody can recover from the diff. Keep it immutable, keep it in the repo next to the code, and write one only when the decision was actually contested. A pile of trivial ADRs rots as fast as no ADRs at all.
*[BrainGrid](https://braingrid.ai) turns your idea into a requirement with acceptance criteria your coding agent builds against and is verified by, so the reasoning behind your product survives every session, not just the code. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The Slot Machine Trap: Why AI Coding Burns You Out (and Ships Nothing)
Source: https://www.braingrid.ai/blog/slot-machine-trap-ai-coding-burnout
Published: 2026-08-03T12:00:00Z
You can feel productive and ship nothing for a week straight, and AI coding is the first tool that makes that failure mode feel like progress. Every prompt returns something. Something always runs. The screen keeps changing. And at the end of the day you are exhausted, the app is not done, and you cannot point to the moment it went wrong, because there was no moment. There was a lever, and you kept pulling it.
That is the real vibe coding problem, and it is not the one Google's AI Overview will tell you about. Search "vibe coding problems" and you get security holes, spaghetti code, and hardcoded API keys. Those are real. They are also not why people quit. People quit because of the loop.
## The slot machine effect is not a metaphor
A developer on Hacker News named the mechanism better than any of us have, in a thread bluntly titled "Agentic coding is burning me out":
> "feels some kind of slot machine effect. 'Maybe now I get what I want. Argh, not quite. Okay, feels nearly there.'"
Read that again, because it is the whole post. A slot machine works on a variable reward schedule: you do not win every pull, but you win often enough, and unpredictably enough, that you cannot stop. That is the most addictive reinforcement pattern psychologists have ever measured, and it is exactly what a coding agent gives you. Prompt, almost-right, prompt again. Almost. Nearly. The output is good enough to make you believe the next pull lands it, and just wrong enough that it never quite does.
Nobody designed it to be a slot machine. It became one because of what is missing. When there is no fixed target the output gets measured against, "done" is whatever the last generation happened to produce, and "not done" is whatever you notice is off this time. So you keep pulling. Not because you are undisciplined, but because the loop has no exit condition. It cannot converge on a spec that was never written.
## Why the loop never closes on its own
Here is the reframe, and it is the reason the security-and-spaghetti framing misses the point. Vibe coding does not burn you out because the code is bad. It burns you out because the loop has no definition of finished.
Think about what "correct" means to the agent on any given pull. It means: plausible continuation of this conversation. That is all a model can optimize for when you hand it a vague prompt. It has no idea that "the export button should be disabled while a job is running" is load-bearing and "make the header a bit bigger" is not, because you never said so. So it fixes the header, breaks the export, and the next pull fixes the export and breaks something else. The "Whack-a-Mole" trap, as one analysis of vibe coding failure patterns put it. The app runs the entire time. It just never arrives.
The token counter runs too. Every "not quite" is a full generation you paid for, reviewed, and threw away. We wrote a whole post on [the real cost of a vague prompt](/blog/the-real-cost-of-a-vague-prompt), and the short version is that the cheap part of AI coding happens once and the expensive part happens on a loop. The slot machine is just that cost curve, felt as an emotion instead of a bill.
```mermaid
flowchart TD
A[Vague prompt] --> B[Agent generates plausible output]
B --> C{Right this time?}
C -->|Almost| D[Notice something new is off]
D --> A
C -->|Feels close| E[One more pull]
E --> A
F[Spec with acceptance criteria] --> G[Agent builds against the target]
G --> H{Every criterion met?}
H -->|No| I[Fix the specific gap]
I --> H
H -->|Yes| J[Verified. Done. You stop.]
```
The top loop has no exit. The bottom one does, and the only difference between them is a written target the work can be checked against.
## The burnout is a review problem too
Even when a pull looks like a win, the win is expensive in a way that does not show up until later. A second Hacker News thread, "Agentic Coding Is a Trap," put its finger on it: reviewing agent output carefully costs more than writing the code yourself would have, and the bugs the agent introduces are disguised as working code. You are not saving the effort. You are moving it from writing to reviewing, and review is the harder job, because now you are auditing plausible-looking code you did not write for defects you did not cause.
So the day has two exhaustions stacked on each other. The slot machine drains your attention with the pulling. The review burden drains your judgment with the checking. And because there is no spec, the checking has no anchor either. You are not verifying against a standard. You are squinting at output and asking "does this look right," which is the same question that started the loop.
If you are building a real SaaS product this way, here is the concrete version of what that means for you: your third or fourth feature is where it stops being fun. The first feature vibes into existence in an afternoon. By the fourth, every fix ripples, every review takes longer than the generation, and you are pulling the lever at 11pm trying to get back to the version that worked yesterday. That is not a discipline failure. That is the predictable output of a loop with no target.
## What actually stops the pulling
The fix is not "vibe less" or "learn to code first." The fix is to give the loop an exit condition, which means writing down what "done" is before you start generating against it. A spec with acceptance criteria is not bureaucracy. It is the thing that lets you stop.
Compare the two workflows directly.
Slot machine: "make the export feature better," pull, review, "still not right," pull, review, repeat until you give up or get lucky.
Structured: "the export button is disabled while a job runs; clicking it while enabled produces a CSV with the visible columns; an empty result set shows a message instead of an empty file; only the row owner can export." Now the agent builds against something, and more importantly, you check against something. When all four are true, you are done. Not "feels done." Done. The lever has an off position.
This is the gap [BrainGrid](https://braingrid.ai) is built to close. You describe the idea, and the Planning Agent turns it into a requirement with explicit acceptance criteria, so the target exists before the first line of code does. Then the Builder Agent builds against that target, in a Managed sandbox with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. The loop is Plan, Build, Verify, Repeat, and the Verify step is the one the slot machine skips: a feature is not finished until every criterion is checked with evidence. You are not pulling a lever hoping the next output is the one. You are running a loop that knows when to stop.
That is also where the honest trade-off lives, so here it is. Writing acceptance criteria up front is slower than typing "build me a CRM" and hitting enter. The first ten minutes feel worse. For a throwaway script or a weekend sketch, that overhead is not worth it, and you should absolutely just [vibe it](/vibe-coding-tools). The moment it becomes worth it is the moment the thing has to keep working, because that is the exact moment the slot machine turns on. Planning is the price of an exit condition, and you only need an exit when you actually intend to arrive.
## FAQ
### What is the slot machine effect in AI coding?
It is the pattern where an AI coding agent returns output that is almost right often enough, and unpredictably enough, that you keep re-prompting without ever converging. Because there is no fixed definition of "done," each pull fixes one thing and breaks another, and the near-misses keep you pulling the lever the same way a slot machine's variable rewards do. The term comes from developers describing the feeling directly on Hacker News.
### Why is agentic coding burning me out?
Two costs stack up. The loop itself drains attention because it has no exit condition, so you keep prompting toward a target that was never written down. On top of that, carefully reviewing agent-generated code costs more effort than writing it yourself would, and the bugs are disguised as working code. Speed on generation plus a heavier review burden, with no spec to anchor either, is a recipe for exhaustion.
### Is vibe coding actually the problem, or is it the code?
The code quality issues (security holes, spaghetti architecture, silent logic bugs) are real, but they are symptoms. The root cause is that vibe coding produces no written record of what the software is supposed to do, so neither you nor the agent can tell whether a given change is correct. Without a target, the loop cannot converge. We go deeper on this in [Is Vibe Coding Good? An Honest Answer](/blog/is-vibe-coding-good).
### How do I stop the endless re-prompting loop?
Give the loop an exit condition before you start: write acceptance criteria that state exactly what "done" looks like, in checkable terms. Then build against those criteria and verify each one instead of asking "does this look right." When every criterion is met with evidence, you stop. The re-prompting continues indefinitely only when there is nothing concrete to check the output against.
### Does writing a spec slow me down?
Up front, yes. Writing acceptance criteria takes longer than sending a vague prompt, and for throwaway scripts or quick sketches that overhead is not worth it. It pays off the moment the software has to keep working, because that is when the slot machine loop and the review burden appear. The time you spend defining "done" is far less than the afternoons the loop would otherwise consume.
If you are tired of pulling the lever, the fix is not a better prompt. It is a target the work can be finished against.
*[BrainGrid](https://braingrid.ai) is the system that takes an idea to a live product you can trust, running the loop Plan, Build, Verify, Repeat so your coding agent has a target instead of a slot machine. Try it at [braingrid.ai](https://braingrid.ai).*
---
# UAT for Solo Builders: Why Your Own Test Accounts Pass Every Check
Source: https://www.braingrid.ai/blog/uat-for-solo-builders
Published: 2026-07-30T12:00:00Z
You clicked through every screen of your app before launch and everything worked. That is exactly why your first real user found the bug in an afternoon.
The gap is not effort. You tested hard. The problem is that you tested as yourself, on your own accounts, with the data you created, following the paths you already knew were safe. A solo builder doing user acceptance testing has a structural blind spot the enterprise QA playbook was never written to cover: the person accepting the software is the same person who built it. And your own accounts pass every check, because you built them to.
This is the felt version of a number that is getting harder to ignore. Anthropic told The Pragmatic Engineer that on a recent internal rewrite, [implementation was about 15% of the work and 85% went to "getting it to compile, fixing tests, verifying that it worked."](https://newsletter.pragmaticengineer.com/p/inside-anthropic) The building is the cheap part now. Making sure it actually works is the job. The hypothesis of this post is simple: **UAT for a solo builder cannot be a testing phase you perform at the end, because you are structurally unable to be the independent tester it requires. It has to become a written standard you define before the build, so the verification has something to check against that your own habits would never reveal.**
## What UAT actually assumes
User acceptance testing has a clean definition that every enterprise QA vendor repeats: it is the final phase where real users, not the developers, confirm the software does what they need before it ships. Read that again and notice the load-bearing word. *Not the developers.* UAT was invented for a world with a division of labor. Someone specifies the feature, someone else builds it, and a third group, users or a dedicated UAT team, tries to break it against a written set of expectations they did not write the code to satisfy.
The whole method rests on independence. The tester's value is precisely that they don't share the builder's assumptions. They click the button you never click. They log in as a customer who isn't you. They type a name with an apostrophe in it because that's their actual name. They find the bug because they don't know where the bodies are buried.
Now collapse all three roles into one person building alone at a laptop. You are the specifier, the builder, and the "user." You know every happy path because you designed them. You test the flows you built, with the account you set up, using the seed data you entered. Every implicit assumption you made while building, you carry straight into testing, because it is the same brain. The independence that made UAT work is gone, and no amount of careful clicking brings it back. As one builder put it after their first real user hit a permissions bug, [testing with your own accounts will never catch it, because your own accounts pass every check.](https://www.reddit.com/r/EntrepreneurRideAlong/comments/1v3833h/my_first_real_user_found_the_permissions_hole_i/)
## The bug you cannot see
The story behind that line is worth sitting with, because it is the most common shape of a solo-builder launch bug. The builder had auth working. Login worked, logout worked, the dashboard loaded their data. They [mentally filed auth under "done"](https://www.reddit.com/r/EntrepreneurRideAlong/comments/1v3833h/my_first_real_user_found_the_permissions_hole_i/) and moved on. Then a real user signed up, logged in, and saw another account's data. The same permissions hole was sitting in eleven different endpoints.
Here is why one person testing alone could never have caught it. To see that bug, you need two accounts, and you need to be logged into one while trying to reach the other's data. But you only ever had one account: yours. When you're the only user, every query you run returns your own rows, so the app looks perfectly scoped. The bug is invisible not because it's subtle but because reproducing it requires a second person's perspective you structurally don't have. It is the same blind spot behind [missing row-level security](https://braingrid.ai/blog/what-is-row-level-security-for-vibe-coders): the demo works because there was only ever one user's data to see.
Coding agents make this sharper, not softer. When you build fast with Claude Code or Cursor, the agent optimizes for the same thing you're eyeballing: a screen that shows data. It will happily ship a working-looking feature that trusts every request, because "only the owner can see this row" was never part of what you asked for. The faster the build, the more untested surface area you're accepting on the strength of a demo that only ever ran as you.
## Why more clicking won't fix it
The instinct, when you know your testing is thin, is to test more. Click through the app again. Try a few weird inputs. Make a checklist. This helps at the margins and it does not close the gap, because the gap is not quantity of testing. It is the direction of it. More clicking as yourself just re-confirms the paths you already trust.
Watch the difference between testing by exploration and testing against a standard.
> Exploration: "I'll sign up, add a project, edit it, delete it, and make sure nothing errors out."
> Standard: "Create account A and account B. Logged in as B, request A's project by its ID directly. The response must be denied, not A's project. Repeat for every endpoint that takes a resource ID."
The first is what you naturally do, and it will never surface the permissions hole, because it never involves a second account trying to reach the first one's data. The second is a written expectation that forces the exact path your habits avoid. You don't have to be a security expert to run it. "Log in as B, try to open A's thing, confirm you can't" is a test anyone can execute and anyone can read. "Is the authorization correct?" is not. The first is verifiable from the outside. The second is a code review you can't perform on code you didn't write.
That distinction is the whole move. The thing that replaces the independent tester you don't have is not more of your own attention. It is a definition of what "acceptable" means, written down before the build, in checkable terms, so that verifying the software is a matter of running the checks rather than trusting your own tour of the happy path.
## Where this fits in the loop
This is exactly the gap BrainGrid is built to close, and it lives at the front of [the loop](https://braingrid.ai/loop), not the end. Before any code gets written, you describe what you're building, and BrainGrid's Planning Agent turns that into a requirement with [acceptance criteria](https://braingrid.ai/blog/how-to-write-acceptance-criteria-ai-agent-can-verify): the specific, testable statements of what "done" and "acceptable" mean for this feature. "Each user can access only their own resources, verified by attempting cross-account access on every ID-bearing endpoint" becomes a criterion the work is measured against, not an afterthought you hope to remember.
Then the Builder Agent builds against those criteria, in the BrainGrid Cloud sandbox or in your own GitHub repo through your coding agent over MCP, and a feature isn't done until every criterion is verified with evidence. That is your UAT, relocated. Instead of you playing an independent tester you can't actually be, the standard an independent tester would have brought is captured up front, and the verification checks the build against it. You move from being the bottleneck who has to catch everything by eye to the person who set the bar the work has to clear.
The honest trade-off: this front-loads work you're used to deferring. Writing "only the owner sees this row, and here's how we prove it" before you've built the feature feels slower than just building the feature and clicking around after. It is slower, in the same way that Anthropic's 85% is slower than the 15%. That is not a tax on top of the real work. In an AI build, it *is* the real work, and skipping it doesn't remove the cost, it just moves the discovery to your first real user's afternoon.
## What changes for you
If you're building a SaaS product solo with an AI coding agent right now, this means your launch-blocking bugs are almost never in the feature you were staring at. They're in the second account you never created, the input you'd never type, the permission you filed under "done." No amount of testing as yourself reaches them, because the version of you that built the app and the version testing it share every blind spot.
So stop trying to be your own QA department by clicking harder. You will lose, structurally, every time. Write down what acceptable means before you build, in terms a stranger could check, especially the boring cross-account and wrong-input cases you'd never explore on your own. Then verify the build against that list instead of against your memory of the happy path. The independent tester UAT assumes isn't coming to save your solo launch. The written standard they would have used can.
## FAQ
### What is meant by UAT testing?
User acceptance testing (UAT) is the final phase of software testing where actual users, rather than the developers, confirm that the software does what they need in real conditions before it goes live. Its defining feature is independence: the person accepting the software is not the person who built it, so they don't carry the builder's assumptions into the test. For a solo builder, that independence is missing, which is why UAT has to shift from an end-phase you perform to a written standard you define before building and verify against.
### What is UAT vs QA testing?
QA (quality assurance) testing checks that the software was built correctly against its technical spec: the code runs, functions return what they should, nothing crashes. UAT checks something different: that the correct thing was built, judged by whether it meets a real user's needs and expectations. QA asks "did we build it right"; UAT asks "did we build the right thing, and does it hold up for an actual user." A solo builder tends to do informal QA by clicking around and skips UAT entirely, because they have no independent user to run it, which is exactly where launch bugs slip through.
### Who is responsible for UAT testing?
In a traditional team, UAT is run by the end users or a dedicated UAT group, deliberately kept separate from the developers so the testing is independent. When you're building solo, you are structurally all of those roles at once, which is the core problem: you cannot be the independent tester and the builder in the same head. The practical substitute is to make the acceptance standard itself do the work an independent tester would have done, by writing testable acceptance criteria before the build and checking the software against them.
### Which comes first, QA or UAT?
QA comes first, then UAT. QA verifies the software works as specified at a technical level, and once it passes, UAT confirms it meets real user needs before release. For a solo builder shipping with AI tools, the more useful reordering is earlier still: define what "acceptable" means, in checkable terms, before any code is written, so that both "does it work" and "is it the right thing" have a written standard to be verified against instead of relying on your own tour of the app at the end.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that turns your idea into a requirement with acceptance criteria, so verification checks the build against a real standard instead of your own happy path. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Requirements Management for AI Builders (Without the Enterprise Baggage)
Source: https://www.braingrid.ai/blog/requirements-management-for-ai-builders
Published: 2026-07-29T12:00:00Z
Search "requirements management" and you land in 1998. The results are enterprise suites built for aerospace programs and medical-device compliance, all traceability matrices and DOORS licenses and words like "elicitation." None of it looks remotely like what you do when you open Cursor and start describing an app. So most AI builders take one glance, decide requirements management is a thing that happens to other people, and go back to prompting.
That instinct is half right. The tools are wrong for you. The practice is not.
Here is the part that flips it. The more capable your coding agent gets, the more you need requirements management, not less. A slow human developer who half-understood your idea would build slowly and ask you questions along the way. A fast agent that half-understands your idea builds the wrong thing at full speed, then writes tests that prove the wrong thing works. The gap between what you meant and what you wrote down used to close itself through conversation. With agents, nothing closes it but the requirement.
## What requirements management actually is (minus the enterprise version)
Strip away the enterprise packaging and requirements management is three plain activities. You capture what the software has to do. You keep those statements current as your understanding changes. And you check the built thing against them. Capture, maintain, verify. That is the whole discipline. Everything Jama and IBM DOORS add on top of that, the sign-off workflows, the compliance audit trails, the multi-hundred-seat traceability, exists because a regulated program with 400 engineers needs a paper record that survives a lawsuit.
You're not building a pacemaker. You don't need the paper record. You need the three activities, because they're what stands between your intent and your agent's guess. This is the practical core of [spec-driven development](/spec-driven-development): the spec, not the chat, is what the build answers to.
The reframe worth sitting with: for an AI builder, a requirement is not documentation. It is the input to the build. In a human team, requirements are a communication artifact, a way for a product manager to tell an engineer what to make. When your engineer is an agent, the requirement is the literal thing it reads and executes against. Vague in, vague out, at machine speed. That single change, from "requirement as memo" to "requirement as build input," is why the practice matters more now than it did when it had a boring enterprise name.
## The failure mode you already recognize
You've felt this even if you never called it a requirements problem. You describe a feature, the agent builds something that looks finished, you click through the demo, it works. Two features later something you never touched is broken, and when you go back to figure out what the app was even supposed to do, there's no answer written down anywhere. The only record of your intent was the chat, and the chat is gone.
One builder on Hacker News described exactly this after leaving an agent to run overnight against what he thought was a solid plan:
> "Somewhere in the loop it had to make a decision and it made a wrong one. The code 'worked' but it had the wrong system design and wrote the most brittle tests around its assumption, validating its own decision."
That is not a coding failure. The agent coded fine. It is a requirements failure: the plan did not pin down the decision the agent hit at 3am, so the agent decided for itself and then graded its own homework. A managed requirement is what would have made that decision a checkable fact instead of a coin flip. This is the same trap we unpacked in [why your AI agent keeps breaking things that worked](/blog/why-ai-keeps-breaking-things-that-worked): without a durable statement of intent, every session starts from zero and the agent is free to reinvent decisions you already made.
## Requirements management vs. "just writing a good prompt"
The common objection: I already write detailed prompts, isn't that the same thing? It is not, and the difference is the whole point.
A prompt is a single message. It lives for one turn and then it is gone. A managed requirement outlives the conversation. It is the thing you return to when the agent drifts, the thing a second agent reads when the first one hits its context limit, the thing your verification step checks the build against. Prompts are how you talk to the agent right now. Requirements are how the product remembers what it is supposed to be.
Put them side by side:
> Prompt: "Add a way for users to reset their password. Make it secure."
>
> Requirement: "Authenticated and unauthenticated users can request a password reset by email. The reset link expires after 30 minutes and is single-use. On success, all existing sessions for that user are invalidated. Rate-limit reset requests to 5 per hour per email. Show the same confirmation message whether or not the email exists in the system."
The prompt gets you a password reset. Which behaviors you get is up to the agent's mood that day. The requirement gets you *those* behaviors, and, more importantly, it gives you five specific things to check when the agent says it is done. "Make it secure" is not checkable. "The reset link expires after 30 minutes" is. That checkability is the entire reason requirements management exists, and it is exactly what a good prompt, however detailed, cannot give you, because a prompt is not something you keep and verify against later.
## Where this fits the loop
Requirements management is not a phase you do once at the start. It is the part of the build loop that everything else depends on. Plan, build, verify, repeat: the plan is where requirements are captured and maintained, and the verify step is where they get checked. Skip the first and the last has nothing to check against.
```mermaid
flowchart LR
A[Idea] --> B[Capture as requirement with acceptance criteria]
B --> C[Agent builds against the requirement]
C --> D[Verify build vs. each criterion]
D -->|criteria met| E[Ship]
D -->|criteria missed| B
E --> F[New idea / change] --> B
```
Notice the requirement is the hub, not a one-time input. When you change your mind two weeks in, you change the requirement, and the verify step now checks against the new target. That is the "maintain" activity doing its job. The alternative, changing your mind in a fresh chat and hoping the agent remembers the last six decisions, is how apps drift into a state nobody can describe.
This is the gap [BrainGrid](https://braingrid.ai) is built to close. You describe the idea, and the Planning Agent turns it into a requirement with real acceptance criteria, asking the clarifying questions that surface the decisions you did not know you were leaving to chance, and scoring whether the requirement is actually ready to build before any code exists. The Builder Agent then builds against that requirement, in BrainGrid's cloud or in your own repo through Claude Code, Cursor, or Codex. And verification checks the finished work against every criterion, so "done" is evidence, not a vibe. The requirement is not a document you file and forget. It is the spine the whole loop runs on, and it accumulates in the product record so the next feature starts from what the app already is instead of from a blank prompt. That is the same discipline behind [the three artifacts that actually matter](/blog/three-artifacts-requirements-acceptance-tests-code): requirements, acceptance tests, and code, in that order.
## The honest trade-off
Writing requirements is slower at the start than firing off a prompt and watching something appear. That is real, and pretending otherwise would be dishonest. The first ten minutes of naming what "done" means for a feature feels like overhead when the agent could already be generating.
The trade shows up later. The cost of skipping requirements is not paid on feature one. It is paid on feature four, when the agent has quietly made a dozen decisions you never saw, and untangling them costs an afternoon and a pile of tokens. You are choosing between ten minutes of clarity now or an afternoon of archaeology later. For a throwaway weekend toy, skip it, genuinely. For anything you intend to keep, maintain, and put in front of a user, the ten minutes wins every time it comes up, which is every feature.
## The takeaway
Requirements management sounds like the most enterprise phrase in software, and for decades it was. AI builders inherited the problem it solves without inheriting the practice, which is why so many vibe-coded apps hit a wall nobody can diagnose. The fix is not a compliance suite. It is treating the requirement as what it now is: the build input your agent reads, the target your verification checks, and the memory your product keeps when the chat is gone. The faster your agent gets, the more that written-down intent is the only thing holding the line between what you meant and what you shipped.
## FAQ
### What is requirements management?
Requirements management is the practice of capturing what a piece of software must do, keeping those statements current as your understanding changes, and checking the built software against them. Traditionally it meant heavyweight enterprise tools for regulated industries. For AI builders, it is simpler and more direct: the requirement is the plan your coding agent builds against and your verification step checks.
### Do AI builders and vibe coders actually need requirements management?
Yes, and arguably more than traditional teams do. A fast coding agent that misunderstands your intent builds the wrong thing at full speed and can even write tests that validate its own wrong assumptions. A managed requirement is what pins down the decisions the agent would otherwise make on its own. You do not need enterprise tooling, but you do need to capture, maintain, and verify intent.
### Is a detailed prompt the same as a requirement?
No. A prompt lives for one conversation turn and then it is gone. A requirement outlives the conversation: it is what you return to when the agent drifts, what a second agent reads when the first hits its context limit, and what your verification checks the finished build against. Prompts are how you talk to the agent now. Requirements are how the product remembers what it is supposed to be.
### What is the difference between requirements management and requirements management software?
Requirements management is the practice (capture, maintain, verify). Requirements management software is the category of enterprise tools built to do it at scale for regulated programs, with traceability matrices, sign-off workflows, and audit trails. Most AI builders do not need that machinery. They need the practice, embedded in the build loop, close to where the agent actually reads the spec.
### How do you write a requirement an AI agent can build against?
Write it as checkable behavior, not intent. Instead of "make the login secure," specify the observable facts: session expiry, rate limits, what happens on success and failure, what the user sees in each case. Each statement should be something you can later confirm as true or false against the built app. If a line cannot be checked, it is a wish, not a requirement. See [how to write acceptance criteria an AI agent can actually verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify) for the full method.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that turns your idea into a requirement your agent can build against, then proves the build matches it. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Vibe Coding vs Agentic Coding: Which One Actually Ships?
Source: https://www.braingrid.ai/blog/vibe-coding-vs-agentic-coding
Published: 2026-07-28T12:00:00Z
Vibe coding and agentic coding both start the same way: you type what you want, and an AI writes the code. Watch two builders for five minutes and you cannot tell them apart. The difference shows up weeks later, when one of them ships something they trust and the other is staring at an app they are afraid to touch.
That gap is the whole story, and almost every explainer gets it wrong. The popular framing is that vibe coding is casual and agentic coding is autonomous, or that vibe coding is for prototypes and agentic coding is for production. Those are symptoms. The real difference is not how much the AI does on its own or which tool you point it at. It is a single question: who owns the definition of done. Answer that, and you know which one you are actually doing, and which one will still be standing when your app matters.
## The definitions everyone agrees on (and why they miss the point)
Start with the words, because the term got blurry fast. Andrej Karpathy coined "vibe coding" in early 2025 to describe a specific mode: you talk to the model, you accept what it gives you based on whether it looks like it works, and you mostly do not read the code. Simon Willison, who has written more carefully about this than anyone, draws the line sharply:
> "Vibe coding" is a very different beast from responsible use of AI to write code, which I've since started to call agentic engineering.
>
> [Simon Willison, "Vibe coding and agentic engineering are getting closer than I'd like"](https://simonwillison.net/2026/May/6/vibe-coding-and-agentic-engineering/)
The standard contrast follows from there. Vibe coding: loose prompts, no review, no tests, you trust the output because the demo runs. Agentic coding: you set rules, you review the pull requests, you keep architectural judgment in your own hands while the agent does the typing. Google's arXiv survey puts it in one line, calling agentic coding "outcome-oriented, resilient, and self-directed" against vibe coding's "focus on expressiveness and flow."
All of that is true. It is also a description of the weather, not the cause. Telling a beginner "review the pull requests and set strict rules" is like telling someone the difference between a hobby cook and a chef is that the chef follows recipes. Sort of. The deeper difference is that the chef knows what the finished dish is supposed to taste like before the pan is hot, and can tell you exactly why yours is wrong.
## The real dividing line: who owns "done"
Here is the reframe. In vibe coding, the AI owns the definition of done. You asked for a login page, the agent produced something that renders a login page, the demo works, so it is done. Done means "the output stopped and it looks right." You never wrote down what right was, which means you cannot check it, which means the agent's judgment is the only judgment in the loop.
In agentic coding, you own the definition of done. Before the agent writes a line, there is a standard the result gets measured against: this input produces this output, this edge case is handled this way, an unauthenticated user hitting this route lands there. The agent is autonomous inside those boundaries and accountable to them at the end. Done means "the evidence says it does what I specified," not "it looks like it works."
That is the actual fork in the road. Not autonomy. Not tooling. Ownership of the standard.
Look at what the arguing communities are really circling. In an r/vibecoding thread titled "Agentic Engineering vs Vibe Coding, not the same thing," the top-voted framing lands on exactly this: vibe coding ignores the code and has no idea what the output does, while agentic coding is having the model deliver something you engineered. "Engineered" is the tell. You cannot engineer toward a target you never named.
This is also why the "vibe is for prototypes, agentic is for production" rule of thumb keeps failing people. Plenty of production disasters were built agentically, with fancy tooling and autonomous overnight runs, that still shipped garbage. Why? Because nobody wrote the standard down, so the powerful autonomous agent optimized for the only signal it had: make the tests pass, make it look done. One builder in a Hacker News thread on why software factories fail described letting a capable model run unsupervised overnight and waking up to code that "worked" but had the wrong system design, wrapped in tests the agent wrote to validate its own bad decision. That is not a vibe coding story. That is an agentic setup with no owned definition of done. The autonomy made it worse, not better.
Which gives us the hypothesis worth testing: the more autonomous your coding agent gets, the more it matters who owns the definition of done, because a fast agent with no standard to hit just reaches the wrong destination faster.
## Same prompt, two outcomes
Watch it happen on one feature. You want users to be able to reset their password.
The vibe version:
> "Add password reset to my app."
The agent does something reasonable-looking. It adds a "forgot password" link, a form, maybe an email. The demo works: you type an email, you see a success message. Done, apparently. Except nobody said the reset token should expire, or that it should be single-use, or that submitting an email that is not in the system should behave identically to one that is (so attackers cannot fish for valid accounts). The agent did not skip those because it is dumb. It skipped them because they were not in the definition of done, and the definition of done was "make it look like it works."
The agentic version starts from the standard:
> "Add password reset. A logged-out user enters their email and always sees the same confirmation message whether or not the account exists. If it exists, send a reset link containing a token that expires in 30 minutes and works only once. The reset page rejects an expired or already-used token with a clear error and no password change. On success, invalidate all of the user's existing sessions."
Same feature. Same agent. The second one is not more code you wrote; it is a description of done you wrote, in plain language, that the agent now has to satisfy and that you can check it against. The token either expires or it does not. The used link either fails on reuse or it does not. There is no "looks right" to hide behind.
That second block is the entire difference between the two disciplines, compressed into one prompt. Vibe coding hands the agent a wish. Agentic coding hands it a contract.
## This is a spec, and you have been avoiding writing it
The uncomfortable part: that second prompt is a specification. Not a formal document with headers and sign-offs, just a clear statement of what the feature must do and how you will know it did. [Structured prompting is just a spec you have not written yet](/blog/structured-prompting-is-just-a-spec); "context engineering," writing good acceptance criteria, these are all names for the same act of writing the standard down before the agent runs.
So the honest way to describe the two is not casual versus serious. It is: [agentic coding](/agentic-engineering) is vibe coding plus a written definition of done. Everything else people list, the review, the tests, the architectural ownership, flows out of that one addition. You can review pull requests meaningfully because you have something to review them against. You can trust an autonomous run because you can verify the result, not just admire it.
This is exactly the gap BrainGrid is built to close, and it is why the fork matters so much for what you build. You describe the feature you want and BrainGrid's Planning Agent turns it into a real requirement with acceptance criteria, asking the clarifying questions you did not think to answer (does the reset token expire? what happens on reuse?) before any code exists. Then the Builder Agent builds against that spec, in a cloud sandbox with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. And nothing counts as done until it is verified against every criterion, with evidence. That is agentic coding with the missing piece supplied: the definition of done becomes an artifact the agent is accountable to, instead of a judgment call you outsourced to the model.
Notice what that does to the "who owns done" question. It moves ownership back to you, without making you write the code. You hold the standard. The agent does the work. The verification proves the two match.
## The honest trade-off
None of this makes vibe coding wrong. It is the on-ramp, and a good one. Karpathy's own framing is that vibe coding raises the floor: people who could never have built software now can. If you are just getting started, [our guide to agentic coding without a CS degree](/blog/agentic-coding) walks through the first real task and where the cliff usually is. For a throwaway prototype, a personal tool nobody else depends on, a Saturday experiment to see if an idea has legs, writing a formal definition of done is overhead you do not need. Type the wish, take the output, move on. The stakes are low and the cost of being wrong is an afternoon.
The trap is not noticing when the stakes change. The moment real users, real data, or real money touch your app, "it looks like it works" stops being an acceptable definition of done, and the discipline has to switch even though the tools and the typing feel identical. (If you are weighing which [vibe coding tools](/vibe-coding-tools) to start with, that choice matters far less than whether you ever write the standard down.) That switch is invisible if you are watching the surface. It is obvious the instant you ask: if this breaks in a way the demo did not show, who finds out, and how? If the answer is "my users, in production," you needed the spec three features ago.
Karpathy drew the two ends of the same spectrum in one line worth keeping:
> Vibe coding raises the floor. Agentic engineering is about extrapolating the ceiling.
The floor and the ceiling are not enemies. Most builders should start on the floor and climb. The mistake is thinking the tool you use decides which one you are doing. It does not. The definition of done does.
## FAQ
### What is the difference between vibe coding and AI coding?
AI coding is the broad umbrella: any use of AI to help write software, from autocomplete finishing your line to an agent building a whole feature. Vibe coding is one specific style within it, where you prompt the model, accept what it produces because it looks like it works, and mostly do not read or verify the code. All vibe coding is AI coding; most AI coding is not vibe coding.
### Is vibe coding better than agentic coding?
Neither is universally better; they fit different stakes. Vibe coding is faster and lighter for prototypes, personal tools, and experiments where being wrong costs you an afternoon. Agentic coding adds a written definition of done and verification, which is overhead you want the moment real users, real data, or real money depend on the result. The skill is switching modes when the stakes change, not picking a side.
### What is agentic coding?
Agentic coding is a development approach where an autonomous AI agent plans, writes, tests, and modifies code across your project with limited step-by-step intervention, working toward a standard you define. The distinguishing feature is not the autonomy itself but that you own the definition of done: the agent builds against acceptance criteria you set and its work is verified against them, rather than being accepted because the demo runs.
### Do you need to know how to code to do agentic coding?
No. The core skill of agentic coding is writing a clear definition of done, stating what the feature must do and how you will know it worked, in plain language. That is a judgment skill more than a syntax skill, and domain experts often have it in surplus. The agent handles the implementation; you hold the standard and check the result against it.
### Is vibe coding vs agentic coding just a spectrum?
Mostly, yes. The two sit at ends of one line that runs from "accept whatever looks right" to "verify against a written standard," and real projects slide along it as the stakes rise. The cleanest way to place yourself on the spectrum is to ask who owns the definition of done: if the agent decides when it is finished, you are near the vibe end; if you wrote down what done means and the result is checked against it, you are near the agentic end.
The next time someone asks whether you are vibe coding or agentic coding, do not answer with your tool. Answer with your definition of done, or admit you do not have one.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform: it turns your idea into a spec with acceptance criteria, builds against it with your choice of agent, and verifies every change with evidence, so "done" is something you own, not something the AI guesses. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is a Merge Conflict? The Non-Engineer's Fix When Your AI Agent Gets Stuck
Source: https://www.braingrid.ai/blog/what-is-a-merge-conflict
Published: 2026-07-27T12:00:00Z
A merge conflict is the one error message that makes a non-engineer feel most like a fraud. Everything else your AI agent hits, it seems to just handle. Then two changes collide, the screen fills with arrows and equals signs and the words `<<<<<<< HEAD`, and the agent that has been so confident all afternoon suddenly stops and hands the mess to you. You did not write the code. You cannot read the code. And now you are supposed to resolve a conflict in it.
Here is the reframe this whole piece rests on: a merge conflict is not a bug, and it is not a sign you did something wrong. It is version control working exactly as designed, refusing to guess between two changes when guessing could destroy one of them. Understanding that one sentence turns the scariest moment in AI building into a routine, five-minute decision you are fully qualified to make.
## What a merge conflict actually is
Start with the plain version, because the jargon hides how simple the idea is. Your project lives in a system called version control, usually Git, that tracks every change as a separate entry in a history. When your agent works on a feature, it does not edit your live product directly. It makes a copy of the project, called a branch, does its work there, and later folds that work back into the main version. That folding-back is a "merge," and most of the time Git does it silently and you never notice.
A conflict happens when two branches change the same lines of the same file, and Git cannot tell which version you meant to keep. GitHub's own docs put it exactly this way: merge conflicts occur when you merge branches that have competing commits, and Git cannot automatically decide which to use. So instead of picking one and quietly deleting the other, it stops. It marks the spot with those symbols, and it asks a human to choose. The markers look like this:
> Everything between `<<<<<<< HEAD` and `=======` is the change already in your main version.
>
> Everything between `=======` and `>>>>>>>` is the incoming change from the other branch.
>
> Your job is to decide what the final version should be, then delete all three marker lines.
That is the entire concept. Two edits to the same spot, a tool that refuses to guess, and a decision only a person can make. The scary part, the raw symbols, is Git being careful with your work, not Git breaking.
## Why your AI agent causes more of them
If merge conflicts feel more frequent now that an agent is doing the building, that is not your imagination. It is a direct, measurable consequence of how agents work, and the research has started to catch up to it. A July 2026 paper introduced [AgenticFlict](https://arxiv.org/html/2604.03551v2), a large-scale dataset built specifically from merge conflicts in AI coding agent pull requests on GitHub. The fact that a dataset that size exists at all tells you something: agents generate conflicts at a scale worth studying.
The reason is structural. Agents work fast, touch many files at once, and increasingly run in parallel, several of them building different features at the same time. When two agents (or one agent across two sessions) both edit your authentication file, your route list, or your config, they are editing the same hotspots independently, and those overlapping edits are exactly what produces a conflict. Some tools are throwing automation at the symptom: Replit Agent shipped parallel task forking that auto-resolves conflicts roughly ninety percent of the time. Useful, and also a tell. If your tooling advertises that it handles most conflicts for you, conflicts are common enough to advertise about.
Here is the before and after that makes the shift concrete.
> The old world: a team of engineers, each aware of what the others were touching, coordinating in standup so two people rarely rewrote the same function on the same day. Conflicts were occasional.
>
> Your world: an agent, or several, editing your codebase at machine speed with no standup and no memory of what the last session changed. Conflicts are routine, because nothing is coordinating the parallel work.
The agent is not being careless. It simply has no shared picture of who is changing what, so it collides with itself.
## How to resolve a merge conflict without reading code
The trick, exactly like [reviewing a pull request when you can't read code](/blog/what-is-a-pull-request-non-engineer-guide), is to stop trying to be the engineer and start being the decider. You do not need to understand the code on either side of the markers. You need to answer one question: which of these two changes do I actually want, or do I want both?
The most reliable move is to not touch the markers yourself at all. Hand the conflict back to the agent with context. This is the same [oversight role](/ai-for-product-managers) at the heart of building products without writing the code: you supply the judgment, the agent does the mechanical work. Tell it, in plain language, what each change was trying to do and which outcome you want: "The main version has the login form I approved yesterday. The new branch is adding password reset. I want both to work. Resolve this conflict so the login form stays and the reset feature is added, and explain what you did." The agent is far better at editing the raw text than you are, and your job is to supply the intent it is missing, not to hand-edit symbols you have never seen before.
When you do need to look yourself, the decision reduces to three plain-English options. Keep the current version, if the incoming change is one you did not want. Keep the incoming version, if it replaces something you meant to replace. Or keep both, when the two changes are additions that should coexist. Whatever you choose, the mechanical finish is the same: the conflict is resolved only once all three marker lines are gone and the file reads as one clean version. If you can still see a `<<<<<<<` anywhere, it is not done.
The one rule that saves you: never guess in the dark. If you cannot tell what a change does, do not accept it because the conflict is annoying and you want it gone. That is how a "fix" silently deletes the login flow you shipped last week. An unresolved conflict is safe; it just sits there. A carelessly resolved one ships broken. Ask the agent to explain both sides in plain language before you decide, every time.
## The deeper fix: conflicts are a planning problem
Resolving conflicts well is a useful skill. Not creating so many of them is the better one, and that is where the honest limitation of everything above shows up. You can get good at the five-minute fix and still lose whole afternoons to it, because the fix treats the symptom. The cause is upstream: two changes collided because nobody drew a boundary between the work, so the agents wandered into the same files.
This is the same complexity wall that shows up everywhere in AI building. A prototype is easy because there is only one change happening. A real product is where auth, payments, and state management all live in overlapping files, and where parallel agent work turns "edit the same hotspot" from a rare event into a daily one. The way through is not a better conflict resolver. It is deciding, before the agents start, what each piece of work is allowed to touch.
This is exactly where [BrainGrid](https://braingrid.ai) sits, and it sits before the first line of code. You describe the feature in plain language, and the Planning Agent turns it into a scoped requirement with explicit acceptance criteria, the testable conditions that define done. That scoping is the part that quietly prevents conflicts: when the work is broken into requirements with clear boundaries instead of one vague "build the whole thing," the [Builder Agent](/ai-coding-agents) knows what belongs to this task and what does not, so parallel work stops overlapping in the same files. When it builds, in a managed sandbox or in your own repo through [Claude Code, Cursor, or Codex](/ai-coding-agents) over MCP, verification checks the result against every criterion before it merges. The conflict you never have to resolve is the one that was never created, because the plan drew the line the agent respected. That is the Plan step of the loop, Plan, Build, Verify, Repeat, and the discipline behind it is the same one in [git version control for AI builders](/blog/git-version-control-for-ai-builders).
Strip away the AI and the point is old. Two people editing the same paragraph of the same document have always had to talk before they could combine their edits. A merge conflict is that conversation, made explicit by a tool that would rather stop and ask than guess and lose your work. The agent writes faster than you can read. The decision about which change survives is still, and increasingly, the job that is yours.
## FAQ
### What exactly is a merge conflict in simple terms?
A merge conflict is what happens when two different versions of your project change the same lines of the same file, and the version control tool (usually Git) cannot tell which change you want to keep. Rather than pick one and silently throw away the other, it stops and asks you to choose. It marks the exact spot with symbols (`<<<<<<<`, `=======`, `>>>>>>>`) showing both versions side by side. Nothing is broken and nothing is lost; the tool is just refusing to guess with your work. You decide which version wins, or combine both, delete the markers, and the merge finishes.
### What is an example of a merge conflict?
Imagine your app already has a homepage headline that says "Welcome." Yesterday you had your agent change it to "Welcome back." Today, in a separate branch, a different agent session changed the same headline to "Get started." When those two branches merge, Git sees two competing versions of the exact same line and cannot know which you meant, so it flags a conflict and shows you both "Welcome back" and "Get started" between the marker symbols. You pick the one you want, delete the markers, and save. That single overlapping line is the whole conflict.
### How do I get rid of a merge conflict?
You resolve it by choosing a final version for each conflicted spot, then removing the three marker lines so the file reads cleanly. The safest path for a non-engineer is to hand it back to your AI agent with plain-language context: tell it what each side was trying to do and which outcome you want, and let it edit the raw text. If you do it yourself, decide whether to keep the current change, the incoming change, or both, delete every `<<<<<<<`, `=======`, and `>>>>>>>` line, and save. The conflict is gone only when no marker symbols remain anywhere in the file.
### How do I check if there are merge conflicts?
Your tools will tell you, loudly. When a merge hits a conflict, Git stops the process and prints which files are affected, and running `git status` lists every file marked as conflicted. In a visual tool like GitHub, VS Code, or your AI builder's interface, conflicts show up as highlighted files with the marker symbols visible inside them, usually flagged in a color you cannot miss. If your agent paused mid-task and told you it hit a conflict, that is the check: it will not continue merging until each flagged file is resolved and the markers are gone.
### Why does my AI agent keep creating merge conflicts?
Because agents edit fast, touch many files at once, and often run in parallel across different sessions or tasks, with no shared awareness of what the others are changing. When two of those changes land on the same lines of the same file, usually a hotspot like your auth logic, route list, or config, you get a conflict. It is a coordination gap, not a coding mistake. The durable fix is upstream: scope each piece of work with clear boundaries before the agents start, so parallel changes stop overlapping in the same files in the first place.
*[BrainGrid](https://braingrid.ai) is the AI product planner that turns your idea into scoped requirements with acceptance criteria, so your agents build against clear boundaries instead of colliding in the same files. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Why We Made Our Agent Ask Questions Before It Builds
Source: https://www.braingrid.ai/blog/why-we-made-our-agent-ask-questions
Published: 2026-07-24T12:00:00Z
The obvious way to build an AI product builder is to make it obedient. You describe what you want, it builds exactly that, fast, no friction. That is the demo everyone wants to give. It is also the reason so many AI-built apps arrive looking finished and behaving like a stranger wrote them. We built the opposite on purpose. Before our Planning Agent writes a requirement, it stops and asks you the questions you didn't think to answer.
That decision gets pushback in almost every demo. Why add a step? Why slow down the one part of AI that finally feels effortless? The honest answer is that the step is not friction. It is the difference between an agent that builds what you said and an agent that builds what you meant, and those two things diverge the moment your idea leaves the sentence you described it in.
## The hypothesis: the agent worth trusting is the one that won't build blind
Here is the claim, stated so you can argue with it. The value of an AI coding agent is not how fast it goes from prompt to preview. It is how few of your unstated decisions it has to guess. A capable agent handed a vague prompt does not fail loudly. It succeeds at building something, quietly inventing every detail you left out, and hands you a working app whose behavior you now have to reverse-engineer to trust. The interrogation up front is not a tax on speed. It is what makes the speed worth having.
You can watch this happen with any coding agent today. Tell one to "ask clarifying questions" before it builds and it turns out most of them can, well. A commenter on Hacker News put it bluntly:
> "I think the asking clarifying questions thing is solved already. Tell a coding agent to 'ask clarifying questions' and watch what it does!"
The reframe hiding in that line is the whole point. The capability was never the hard part. The models are already good enough to ask sharp questions. What almost nobody does is make asking the default instead of a trick you have to remember to invoke. Left to its defaults, an agent optimizes for producing output, because that is what looks like progress. Asking first has to be designed in, not prompted in, or it does not happen when it matters most.
## What the questions actually catch
A builder describing an idea leaves out the things that feel too obvious to say. That is not carelessness. It is how human communication works. When you tell a contractor you want a kitchen island, you do not specify that it should be attached to the floor. You assume it. The agent does not share your assumptions, and unlike the contractor, it will never look at you funny for leaving them out. It will just pick.
Consider what "build me a contact form" leaves undecided. Who can submit it, anyone or only logged-in users? What happens after submit, a thank-you page, an email, a database row, all three? What counts as a valid email, and what does the form do with an invalid one? Where do the submissions go, and who is allowed to read them? None of those are in the prompt. Every one of them is a decision the agent will make silently if you let it, and each wrong guess is a bug you find in production instead of a question you answered in ten seconds.
This is why we made asking the first move. When you describe a feature to BrainGrid, the [Planning Agent](https://braingrid.ai/ai-prd-generator) does not race to code. It interrogates the idea the way a good senior engineer would in a hallway conversation: what did you not decide, what did you assume, what breaks if I guess wrong. Then it writes those answers down as a requirement with acceptance criteria, a plan you can read and correct before a single line is built. The questions are cheap. The re-derivation you avoid is not. We wrote up the specific decisions worth catching in [the eight questions to answer before your agent writes a line of code](/blog/8-questions-before-your-agent-writes-code); this post is about why the agent should be the one asking them.
## The believable version, side by side
The difference is easiest to see in the gap between what you say and what a build actually needs.
> What you typed: "Add user login."
>
> What the agent has to decide silently: Email and password, or social sign-in, or both? Password reset flow, yes or no? What happens to a user who is half-registered? Do sessions expire? Is there a "remember me"? What does a wrong password say, and after how many tries does it lock? Where does an unauthenticated user land when they hit a protected page?
Hand that four-word prompt to an obedient agent and you get login. It will work in the demo. It will also have made nine decisions you never saw, and you will discover them one at a time, usually when a real user hits the edge you didn't know existed. Hand the same idea to an agent that asks first and you spend three minutes answering, then get a plan that names every one of those decisions before it becomes code. Same feature. One version you can trust because you can see what it decided. The other you can only hope about.
## The honest trade-off
Asking questions is not free, and pretending otherwise would be its own kind of dishonesty. Sometimes you genuinely do just want the throwaway version now, the rough prototype to see if the idea has legs, and a barrage of questions is exactly the wrong response to "just show me something." The interrogation earns its keep when the app matters, when someone other than you will use it, when you will still be changing it in three months. For a weekend experiment you will delete on Sunday, the questions are overhead. We know that, and the answer is not to remove them but to keep them proportional: ask what changes the build, skip what doesn't.
There is a second limit worth naming. Asking good questions does not rescue a builder who cannot answer them. The agent can surface the decision "what happens to a half-registered user," but it cannot make that call for you well, because it does not know your product or your users. This is the part that stays human. Clarity is still your job. What the questions do is make sure you spend it on the decisions that matter, up front, instead of paying it back with interest later.
## What this changes if you're building right now
If you are shipping features with Claude Code, Cursor, or any capable agent, the practical move is small and it pays immediately. Stop handing your agent a confident one-paragraph prompt and letting it run. Before it builds, make it enumerate what it is about to assume. In a raw coding tool you do this by ending your prompt with "ask me clarifying questions before you write any code," and then actually reading the list instead of skimming it. In BrainGrid the step is the product: the Planning Agent asks, you answer, the answers become acceptance criteria, and the Builder Agent builds against a target you can verify instead of a hope you have to inspect.
The measurable effect shows up in regeneration. The vague-prompt loop is: describe, build, discover a wrong guess, re-describe, rebuild, repeat, four or five times per feature before it settles. Answering the questions once collapses that. You are trading a five-minute conversation for the three or four rebuilds you would otherwise pay in tokens, credits, and afternoons. We put real numbers on that waste in [the real cost of a vague prompt](/blog/the-real-cost-of-a-vague-prompt). Every decision you make explicit before the build is one the agent cannot get wrong during it. This is the front end of [spec-driven development](/blog/spec-driven-development): the questions produce the spec, and the spec is what the build is checked against.
Strip out the trending hook and the argument still stands: an agent that builds from your assumptions will build your assumptions, including the ones you were wrong about. The questions are how you find the wrong ones while they are still cheap to change. Speed was never the scarce thing. Knowing what "done" means before the agent decides for you always was.
## FAQ
### Why would an AI agent ask clarifying questions instead of just building?
Because the prompt you write is almost never a complete specification. A short description leaves out the decisions that feel too obvious to state, and the agent does not share your assumptions, so it fills those gaps by guessing. Asking first surfaces the guesses as questions you can answer in seconds, instead of bugs you find in production. The capability is easy for modern models; making it the default, rather than something you have to remember to request, is the design choice that matters.
### How do I get my coding agent to ask questions before writing code?
End your prompt with an explicit instruction like "ask me clarifying questions before you write any code," then read the list carefully and answer it before you let the agent proceed. Most capable agents handle this well when told to. The failure mode is not the agent's ability, it is skipping the step because generating output feels like faster progress. Tools built around planning, like BrainGrid, make the questions a required part of the flow so you do not have to remember to invoke them.
### Doesn't asking questions slow down building with AI?
It adds a few minutes up front and removes the rebuild cycles that vague prompts cause. The typical vague-prompt loop runs four or five regenerations per feature as you discover wrong guesses one at a time. Answering the questions once collapses that into a single well-aimed build. For a throwaway prototype the questions are overhead; for anything you will ship or maintain, they are faster overall.
### What kinds of decisions do clarifying questions catch?
The ones you left implicit: who is allowed to do the thing, what happens on success and on error, what counts as valid input, where data goes and who can read it, and what the edge cases do. A prompt like "add user login" hides a dozen of these. The agent will decide every one silently if you do not answer them first, and each wrong default is a defect you inherit rather than a choice you made.
### Is BrainGrid's Planning Agent the same as prompting an agent to ask questions?
The behavior is related but the design is different. Prompting a coding agent to ask questions works, but it is opt-in and the answers live in a chat that scrolls away. BrainGrid's Planning Agent asks by default, then writes the answers down as a requirement with acceptance criteria, a durable plan the Builder Agent builds against and verifies. The questions become a record you can review and reuse, not a conversation you have to remember.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that asks the questions you didn't think of, turns your answers into a requirement with acceptance criteria, then builds against a target you can verify. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Agent Orchestration for Builders: When One Agent Isn't Enough
Source: https://www.braingrid.ai/blog/agent-orchestration-for-builders
Published: 2026-07-23T12:00:00Z
Running three agents at once feels like a force multiplier right up until you read what they produced. Then you discover that agent one built the API, agent two built the UI against an API it invented, and agent three wrote tests that pass against both.
Nobody failed. Each agent did competent work. They just did it toward three slightly different versions of the same feature, and nothing in the system was responsible for noticing.
That is the part the orchestration guides skip. Search "agent orchestration" and you get a control layer: task delegation, state management, handoffs, error recovery. Every one of those is real, and none of them answers the question a builder actually has, which is why the output of five coordinated agents is often harder to trust than the output of one.
## What agent orchestration actually is
Agent orchestration is the coordination layer that runs multiple AI agents toward a shared goal: deciding which agent runs, in what order, what context each one gets, and what happens to the results. [OpenAI's own definition](https://openai.github.io/openai-agents-python/multi_agent/) is refreshingly plain: orchestration is the flow of agents in your app, which agents run, in what order, and how they decide what happens next.
The distinction that matters is scope. An [agentic workflow](/blog/what-is-an-agentic-workflow) is one agent running its own loop: plan, act, observe, adjust. [Loop engineering](/blog/loop-engineering) is the practice of designing that loop well. Orchestration is what you add on top when a single loop stops being enough, because the work splits into parts that want different context, different tools, or genuine parallelism.
The honest version of when you need it is narrower than the vendor pages suggest. [Lyzr puts it bluntly](https://www.lyzr.ai/blog/agent-orchestration/): a single AI agent answering questions does not need orchestration. You reach for it when one agent's context window cannot hold the whole job, when subtasks are genuinely independent and waiting on each other wastes hours, or when you want a reviewer whose objective is different from the builder's.
## The four patterns, and what each one costs
Strip the frameworks away and coordination comes in four shapes.
**Sequential** is a chain. Agent A finishes, hands its output to agent B, and so on. It is the easiest to reason about and the easiest to debug, because there is exactly one path through the work. The cost is wall-clock time, and the fact that an error in step one gets faithfully elaborated by steps two through five.
**Parallel** fans work out and collects it back. Three agents each take an independent slice, and you merge. This is where the speedup actually lives. It is also where the API-that-does-not-exist problem lives, because parallel agents cannot see each other's decisions. Anything two agents both depend on has to be settled before they start, or they will each settle it differently.
**Hierarchical** puts a manager agent on top: it decomposes the goal, delegates to specialists, and reassembles. The appeal is obvious. The cost is that the manager becomes a single point of misunderstanding. If it decomposes the goal wrong, every worker below it does excellent work on the wrong task, and the failure is now buried under three layers of confident summary.
**Evaluator loops** pair a builder with a checker: one agent attempts, another assesses, and the cycle repeats until the work clears a bar. This is the pattern that pays off most for anyone shipping a product, and it has a hard dependency the other three do not. An evaluator needs a bar. Give it "review this code" and you get taste. Give it a list of criteria the change is supposed to meet and you get a verdict.
```mermaid
flowchart LR
G[Goal + acceptance criteria] --> P[Plan / decompose]
P --> A1[Agent: API]
P --> A2[Agent: UI]
P --> A3[Agent: tests]
A1 --> E{Evaluator: criteria met?}
A2 --> E
A3 --> E
E -->|No| P
E -->|Yes| D[Done, with evidence]
```
Notice what sits at both ends of that diagram. The same written standard that starts the work is what closes it. Take it out and the arrows still connect, but nothing in the system can tell you whether the thing is finished.
## The multiplier runs in both directions
Here is the reframe, and it is the whole post. Orchestration is a multiplier, and a multiplier has no opinion about what it multiplies.
Give five agents a clear, checkable target and you get five agents converging on it. Give five agents a vague one and you do not get five interpretations averaged into something sensible. You get five interpretations, each internally consistent, each subtly incompatible, and an integration bill that arrives later and costs more than the time you saved. A single agent with a vague spec produces one wrong thing you can see. Five produce a system whose parts disagree, and disagreement is much harder to spot than an obvious error.
This is why the "just add more agents" instinct so often disappoints. The r/AI_Agents thread that ran this week asked it directly: [is anyone actually orchestrating multi-agent workflows well, or are we all duct-taping?](https://www.reddit.com/r/AI_Agents/comments/1v0xs0p/is_anyone_actually_orchestrating_multiagent/) The question keeps coming back because the tooling answer keeps missing. People are not short a framework. LangGraph, CrewAI, and the OpenAI Agents SDK all work, and neither is the scaffolding around them the gap, which is what [harness engineering](/blog/harness-engineering) is for. What is missing is upstream of all of it.
The cost side is real too, and worth saying plainly. Parallel agents burn tokens in parallel. Splitting a job across specialists that each re-read the same context multiplies spend, and rework from three agents that disagreed is paid twice: once to generate, once to reconcile. Orchestration is not free speed. It is speed you buy with coordination overhead, and the overhead is only worth it when the target is sharp enough that the parts fit together on the first try.
There is also a real failure mode in the other direction. Not everything should be orchestrated. If your feature is one coherent change to one part of the codebase, splitting it across agents adds handoffs, context loss, and merge conflicts to buy you nothing. One agent with a good spec beats five agents with a vague one, most days.
## What this changes if you are building right now
If you are running Claude Code in three terminals, or spinning up parallel background agents on the same repo, the constraint you are hitting is almost never the orchestrator. It is that each agent is making judgment calls you never made explicitly, and the calls only conflict where the work meets.
The practical move is to settle the shared decisions before the fan-out, not after. Anything more than one agent will touch, the data shape, the endpoint contract, the auth rule, what the error states are, belongs in writing before any of them start. Anything only one agent touches can stay loose. That single distinction does more for multi-agent output quality than any framework choice, and it costs a few minutes.
This is the layer [BrainGrid](https://braingrid.ai) sits at, above whichever orchestrator you use. You describe the feature in plain language and the Planning Agent asks the clarifying questions a senior engineer would ask, surfaces the edge cases you did not name, and turns the intent into a requirement with explicit acceptance criteria.
That requirement does double duty in an orchestrated setup. It is the shared context every parallel agent works from, so they stop inventing incompatible answers to the same question. It is also the rubric the evaluator checks against, so "done" is a verdict rather than a vibe. You can hand it to [Claude Code, Cursor, or Codex](/ai-coding-agents) over MCP in your own repo, or let the Builder Agent run it in a managed sandbox and open a pull request.
That is the loop we keep coming back to in [agentic engineering](/agentic-engineering): Plan, Build, Verify, Repeat. Orchestration makes Build wider. It does nothing for Plan or Verify, which is exactly why widening Build alone tends to produce more work rather than more product.
Strip out the framework names and the trending term and the argument still stands. Coordinating agents is a solved problem with several good answers. Deciding what they are coordinating toward, precisely enough that three of them working in parallel produce parts that fit, is still yours. The orchestrator schedules the work. It cannot tell you what the work was supposed to be.
## FAQ
### What is agent orchestration?
Agent orchestration is the coordination layer that runs multiple AI agents toward a shared goal. It decides which agent runs, in what order, what context each one receives, how work is handed between them, and what happens when one fails. A single agent running its own plan-act-observe loop does not need orchestration. You add it when the job splits into parts that want different context, different tools, or true parallelism, and something has to keep those parts pointed at the same outcome.
### What is orchestration in simple terms?
Orchestration is scheduling and routing for work done by more than one worker. In the AI context, it means one system decides which agent handles which piece, passes the right information to each, keeps track of what has been done, retries what failed, and combines the results. The everyday analogy is a project manager: not doing the work, but deciding who does what, in what order, and whether the result is acceptable.
### How do you do AI agent orchestration?
Start by deciding whether you need it, since one agent with clear instructions beats several with vague ones. If the work genuinely splits, pick the pattern that fits: sequential for dependent steps, parallel for independent ones, hierarchical when a manager agent should decompose the goal, and an evaluator loop when output needs to clear a quality bar. Then settle every decision two or more agents depend on before they start, including data shapes, interface contracts, and what counts as done, and give the evaluator explicit criteria to check against rather than asking it to review in general.
### What is the difference between an agentic workflow and agent orchestration?
An agentic workflow is a single agent pursuing a goal by reasoning about the next step, using tools, observing results, and adjusting. Agent orchestration is the layer above that, coordinating several such agents toward one outcome. The workflow is what happens inside one agent. Orchestration is what happens between agents: routing, handoffs, shared context, and result aggregation. Most builders need a well-specified workflow long before they need orchestration.
### What is the best agent orchestrator?
There is no single best one, and the choice matters less than most comparisons imply. LangGraph suits explicit state machines and complex branching, CrewAI suits role-based teams of agents, and the OpenAI Agents SDK suits handoff-style flows with less setup. For coding work specifically, many builders orchestrate by running several coding agents in parallel with a shared spec rather than adopting a framework at all. The variable that actually predicts output quality is whether the agents share a precise definition of what they are building, not which orchestrator schedules them.
### Does agent orchestration reduce AI hallucinations?
Partly, and only in one direction. Adding an evaluator agent whose objective differs from the builder's does catch real errors, which is why builder-critic pairs work. But orchestration also multiplies the surface for a different failure: parallel agents that cannot see each other's decisions each fill the same gap differently, producing components that are individually plausible and mutually incompatible. Coordination reduces errors when the target is explicit and increases divergence when it is not.
*[BrainGrid](https://braingrid.ai) turns your plain-language idea into acceptance criteria every agent in your setup builds against and gets verified by, so coordination produces one product instead of three. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Why Reviewing AI Code Costs More Than Writing It
Source: https://www.braingrid.ai/blog/why-reviewing-ai-code-costs-more-than-writing-it
Published: 2026-07-22T12:00:00Z
The agent finished in four minutes. You spent fifty-five reviewing it. And at the end of those fifty-five minutes, you still weren't sure.
That ratio is the thing nobody puts in the pitch deck. Every AI coding tool sells you the four minutes. None of them sell you the fifty-five. Yesterday someone posted to r/ArtificialIntelligence with a title that reads like a confession: [I spend more time worrying about AI code than writing it](https://www.reddit.com/r/ArtificialInteligence/comments/1v296oh/i_spend_more_time_worrying_about_ai_code_than/). Search "how do you even review ai code" and the top result is not a vendor page. It is [a 120-comment thread in r/cscareerquestions](https://www.reddit.com/r/cscareerquestions/comments/1s1y2ud/how_do_you_even_review_ai_code/) where the top-voted answer describes the cognitive load as heavier than doing the work by hand.
Here is the hypothesis this post is going to test: the review time is not overhead you can optimize away with a better tool. It is a fixed cost of not having written down what you wanted, and the only real lever you have is *when* you pay it.
## The review tax is not a skill problem
The standard advice for reviewing AI code is to review harder. Pull the branch. Run it locally. Step through it in a debugger. Read every line. Check for hallucinated dependencies, swallowed exceptions, and missing null checks. All of that advice is correct, and all of it is a treadmill.
Consider the arithmetic. If your agent generates a feature in four minutes and careful review takes an hour, then two agents running in parallel do not double your throughput. They double your queue. The generation side of the ledger got roughly two orders of magnitude cheaper in three years. The reading side got nothing. Human comprehension of unfamiliar code did not speed up in 2024, or 2025, or this year, and it is not going to.
John Crickett named the shape of it [in a post two weeks ago](https://www.linkedin.com/posts/johncrickett_how-to-review-ai-generated-code-when-there-activity-7480149918318477312-X9nn):
> AI doesn't just help us write code faster. It creates more code than most teams can review with the same old process.
That reframe matters more than it looks. The problem is not that any single review is hard. The problem is that the volume broke the process, and the process was never designed to be the throughput-limiting step. This is [the verification gap](/blog/verification-gap) showing up in your calendar instead of your architecture diagram. Review used to be a sanity check on work you already understood, because you wrote it. Now it is the first time you are meeting the code at all. Those are two completely different cognitive tasks that we kept calling by the same name.
And the tax gets worse as the models get better, not easier. A weak model writes obvious garbage, and obvious garbage is cheap to catch. A strong model writes plausible code with a subtle problem buried three functions deep, and plausible is precisely what a skimming reviewer approves. The bugs that survive an AI code review are the ones disguised in a way no human would have written by accident, which is precisely why a human skims past them. Better generation moves defects from obvious to subtle. Subtle is where reading fails.
## The question you are actually trying to answer
Watch what happens in your head during an AI code review. You read a function. You decide it is well written. Then you pause, because "well written" was never the question you needed answered.
The question is: does this do what I meant?
Reading the code cannot answer that one. The code is a perfectly self-consistent artifact. It compiles. It is idiomatic. Its variables are named sensibly. None of that tells you whether it handles the case where the user's trial has expired but their card is still on file, because that case existed only in your head, and your head is not a document anybody can check the code against.
This is why the review feels so much more exhausting than writing. When you write code, you are holding the intent and producing the artifact at the same time, so verification is continuous and nearly free. When you review generated code, you have to reconstruct the intent from scratch, then hold it in working memory while you trace an implementation that someone else's statistical model chose. You are doing two jobs. Only one of them was ever the hard part.
A PM in r/cscareerquestions put the frame in language that travels:
> They're helpful accelerators but asking them to build something complex from scratch is like asking a very confident intern who memorized stackoverflow.
Nobody reviews an intern's work by reading every line and squinting. You tell the intern what done looks like before they start. Then you check the result against that. The review is fast because the standard existed first. That shift, from correcting every artifact to setting the standard and checking against it, is the whole difference between [being in the loop and being on it](/blog/human-in-the-loop-vs-on-the-loop).
## Move the hour, do not try to delete it
So the reframe is this. You can't delete the review. Anyone who promises you can is selling you the four minutes again. What you can do is move it.
Right now most builders pay the hour *after* generation, in the least efficient possible currency: reading unfamiliar code, trying to infer intent, deciding by feel. Move that same hour before generation and it buys something durable. Thirty minutes deciding what "done" means for this feature produces a written definition that survives the session, gets handed to the agent as the target, and turns the post-build review from an open-ended reading exercise into a checklist with answers.
Same hour. Completely different return.
Put the two side by side.
**Review after:** the agent opens a PR with 400 changed lines. You read them, form an opinion, notice the auth check looks fine, miss that it runs after the data fetch instead of before, approve, and find out in production. Time: 55 minutes. Output: an opinion.
**Review against:** before the build, you wrote down that unauthenticated requests must be rejected before any database read, that an expired trial with a valid card gets a specific error rather than silent success, and that the existing export endpoint keeps working. After the build, you check three specific things with three specific answers. Time: 15 minutes. Output: evidence.
The second one is faster, but speed is not the point. The point is that the second one produces something you can act on when you are not sure. "I read it and it seemed fine" gives you nothing to do at 11pm when a customer reports a bug. "Criterion two was never verified" gives you the next move.
```mermaid
flowchart LR
A[Idea] --> B{Where does the hour go?}
B -->|After| C[Agent builds]
C --> D[Read 400 lines]
D --> E[Form an opinion]
E --> F[Ship and hope]
B -->|Before| G[Define done]
G --> H[Agent builds]
H --> I[Check against criteria]
I --> J[Ship with evidence]
```
## Where this fits in the loop
This is the problem BrainGrid was built around, and it is why [the loop](/loop) is **Plan → Build → Verify → Repeat** rather than just build.
You describe the feature to the Planning Agent, in normal language, and it does the part most builders skip: it asks the clarifying questions and turns the idea into a requirement with acceptance criteria attached. Not a vague ticket. Specific, checkable statements about what has to be true when the feature is done. The Builder Agent then builds against that requirement, either in a BrainGrid Cloud sandbox with a live preview, or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. When it finishes, verification checks the result against every criterion you set, and the feature is not done until the evidence says it matches what you asked for.
The part that changes your afternoon is what your review becomes. You are no longer reading 400 lines to form a general impression of quality. You are looking at a list of things you said had to be true, with evidence next to each one, and spending your attention only on the ones that failed or look thin. That is the same review, at a fraction of the cost, and it is legible to someone who cannot read the code at all.
Everyone else sells speed of generation. This is the other half of the trade.
## The honest limitation
Two of them, actually.
Writing acceptance criteria is real work, and it is work you have to do before you get the dopamine hit of seeing something appear on screen. Some people will hate that. If you're exploring, prototyping, or genuinely don't know what you want yet, front-loading the definition is the wrong move. Go generate, poke at it, throw it away. The review tax only bites when the code is going to survive.
And criteria are not a guarantee. You can write five criteria, verify all five, and still miss the sixth thing you never thought of. Nothing catches unknown unknowns. What criteria do is shrink the surface you are reviewing by feel from "everything the agent touched" down to "the things I did not think to specify," which is a much smaller and much more honest problem to have.
## What changes for you tomorrow
If you're building with Claude Code, Cursor, or Codex right now and your workflow is prompt, wait, read the diff, feel uneasy, ship anyway, here is the concrete change: before your next feature, write down three sentences describing what has to be true when it works. Not how to build it. What must be true.
Then let the agent build, and review only against those three sentences.
You will notice two things immediately. The review will be faster, because you are checking instead of reading. And you will notice that writing the three sentences was harder than you expected, which is not a sign you are bad at this. It is the actual work, finally visible. It was always there. You were just paying for it at the end, in the most expensive currency available, one afternoon at a time.
The code got cheap. Knowing what you wanted never did.
## FAQ
### Why does reviewing AI generated code take longer than writing it?
Because you are doing two jobs instead of one. When you write code, you hold the intent and produce the artifact simultaneously, so verification is nearly free. When you review generated code, you have to reconstruct the intent from scratch and then trace an unfamiliar implementation against it. The volume makes it worse: a process designed as a sanity check on work you already understood is now the first time you are meeting the code.
### How do you review AI generated code effectively?
Check it against a written standard rather than reading it for general quality. Decide before the build what has to be true when the feature works, in specific, checkable statements, then verify each one after. Running the code and testing the edge cases matters more than reading the diff, because a well-written function can still solve the wrong problem.
### Can you trust AI generated code?
You can trust it the way you trust any work you did not do yourself: on evidence, not on impression. Reading the code tells you whether it is well written. It does not tell you whether it does what you meant. Trust comes from checking the output against criteria you defined up front, which is a fact you can point at rather than a feeling you formed while skimming.
### Do AI code review tools solve this?
They help with a real but narrower problem. Automated reviewers catch style issues, common vulnerability patterns, and mechanical mistakes, which is genuinely useful and worth having in the pipeline. What they cannot do is tell you whether the feature matches your intent, because your intent was never written anywhere they can read it. That gap is upstream of any reviewing tool.
### Should you read every line of AI generated code?
For anything you are going to keep, someone or something needs to check it, but reading every line by hand does not scale past one agent working at a time. The more sustainable version is to define what done means before the build and check against that, using reading as a targeted tool for the criteria that failed or look uncertain rather than as a blanket pass over the whole diff.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that turns your idea into a requirement with acceptance criteria, so your review is a check instead of a reading assignment. Start at [braingrid.ai](https://braingrid.ai).*
---
# What Is an Agent Flywheel? Why Most Spin Fast and Compound Nothing
Source: https://www.braingrid.ai/blog/agent-flywheel
Published: 2026-07-21T00:00:00Z
A flywheel is supposed to get easier every turn. That is the whole promise of the word: you push once, momentum builds, and each rotation costs less than the last. So here is the uncomfortable question nobody asks about the "agent flywheel" everybody is suddenly building. If your agent is faster this week than last week, is your product actually compounding, or are you just spinning a heavier wheel harder?
Those are not the same thing. A flywheel that spins fast but stores nothing is just a fan.
## What an agent flywheel actually is
An agent flywheel is a loop where the output of each run becomes the input that makes the next run better. You point a coding agent at a task, it produces work, something checks that work, and what it learns feeds back in so the next task starts from a better place. Turn after turn, the wheel picks up speed on its own.
The term is having a moment because the pieces finally ship inside the tools. Augment Code describes its version as a [four-stage loop](https://www.augmentcode.com/guides/agent-learning-flywheel): execute, coach, distill, improve, "to compound AI agent gains across sessions instead of" starting cold every time. Google's developer team shipped a [quality-flywheel skill](https://developers.googleblog.com/driving-the-agent-quality-flywheel-from-your-coding-agent/) that automates testing and grading so prompt tweaks stop silently breaking your agents. Even on Hacker News, builders trade notes on their own [agent flywheel workflow](https://news.ycombinator.com/item?id=48232169), with one describing it honestly: it "feels a bit like using power tools to shape wood but the final product needs a lot of sanding and polishing."
Read those three descriptions again and notice what they have in common. Execute, then grade. Build, then check. Produce, then verify. The flywheel is not the agent going fast. The flywheel is the loop that turns each run into something the next run can stand on.
## The part that makes it compound
Here is the hypothesis this whole post rests on. An agent flywheel compounds only if each pass leaves behind a durable artifact the next pass reads. Take that artifact away and you do not have a slower flywheel. You have no flywheel at all, just a fast loop that forgets.
This is worth sitting with, because it contradicts the way the flywheel usually gets sold. The pitch is about autonomy: the agent runs, you walk away, it keeps going. But autonomy is the flywheel's speed, not its momentum. Speed without stored energy is exactly the fan problem. The agent can rip through ten tasks an hour and, if nothing accumulates between them, you are no further along than when you started, you are just further along faster.
What actually accumulates? Not the code. The code is the output, and output is not the same as compounding memory. What compounds is the record of intent and judgment around the code: what "done" meant for this feature, which decisions were already made and why, what got verified and what evidence proved it. Peter Steinberger, who built the open-source agent gateway OpenClaw and now works at OpenAI, put the shift bluntly:
> Here's your monthly reminder that you shouldn't be prompting coding agents anymore. You should be designing loops that prompt your agents.
>
> [Peter Steinberger on X](https://x.com/steipete/status/2063697162748260627)
The quote reframes the work. If you are designing the loop instead of driving it, then the thing you are actually designing is what the loop remembers between turns. That is the flywheel's mass. This is the same shift behind [loop engineering](https://braingrid.ai/blog/loop-engineering): the leverage is not the agent, it is the system around it. Get the memory right and every rotation gets cheaper. Get it wrong and you are hand-pushing a fan that looks like a flywheel.
## Fast loop versus real flywheel
The difference shows up in one concrete place: what happens on the second, third, and tenth pass.
A fast loop starts every task from roughly the same spot. The agent scans the repo, re-derives what the code does, guesses at the conventions, and produces something plausible. It is quick, but there is no gradient. One builder on r/Anthropic described the tax precisely: the models "come back the next day to ask a simple question" and have to "scan your whole repo and think about what it does every time," so you "effectively get charged hundreds of times again for code that it wrote and knew better than you." That is a loop with no memory. Every turn pays full price.
A real flywheel starts each task from the artifact the last one produced. The plan for this feature already exists, with acceptance criteria written down. The decision to use a particular auth pattern is recorded, so the agent does not relitigate it. The last verification left evidence, so the next task knows what is already trusted. The agent does not re-derive; it reads. Each turn is cheaper than the last, which is the only thing that earns the word flywheel.
Put them side by side and the gap is obvious:
> Fast loop: prompt, generate, ship, forget. Next task: scan the whole repo again, guess the conventions again, hope it lines up.
>
> Real flywheel: plan with criteria, build, verify with evidence, record. Next task: read the plan, read what is verified, build on top.
The first one accelerates your typing. The second one accelerates your product.
## Where BrainGrid fits
This is exactly the gap [BrainGrid](https://braingrid.ai/loop) is built to close, because the flywheel's stored energy is the thing it produces on purpose. You describe what you want, and the Planning Agent turns it into a requirement with real acceptance criteria, the questions you did not think to ask, the data model, the definition of done. That requirement is the artifact the loop reads on the next turn. The Builder Agent builds against it, in the BrainGrid Cloud sandbox with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. Then every change is verified against those criteria, and a feature is not done until the evidence says it does what you intended.
Run that on the kanban, feature after feature, and the momentum is the point. Every criterion you write, every decision the plan captures, every verification that leaves evidence accrues to your product's record. The loop does not start cold on task eleven because tasks one through ten wrote down what they meant. That is a flywheel with mass. The agent forgets between runs. The record does not.
To be honest about the trade-off: building this way is slower on turn one. Writing a plan with acceptance criteria before the agent starts feels like friction when a raw prompt would already be generating code. It is friction. It is also the exact energy you are storing in the wheel. You pay it once, up front, and get it back on every rotation after. Skip it and turn one is faster, but there is no turn-ten payoff, because nothing compounded.
## What this means if you are building right now
If you are running a coding agent day to day, here is the concrete implication. Look at your third feature, not your first. On the first feature, a fast loop and a real flywheel look identical, both produce a working result quickly. The difference only appears once the work stacks. By feature three or four, the fast loop is re-deriving context it already had, generating conflicting patterns, and quietly slowing down, while the flywheel is speeding up because each feature stood on the recorded one before it.
So the question to ask about your setup is not "how autonomous is my agent." It is "what does my agent read at the start of a task that it did not have to figure out from scratch." If the answer is nothing, you have a fast loop. If the answer is a plan, a set of criteria, and evidence of what is already verified, you have a flywheel. Strip away every trend and every tweet about autonomy, and that single question is the whole game.
A flywheel is not defined by how hard you push it. It is defined by whether it keeps turning after you stop.
## FAQ
### What is an agent flywheel?
An agent flywheel is a loop where each run of an AI coding agent produces something that makes the next run better, so momentum builds turn after turn. In practice that means the agent executes a task, its output is checked, and what it learns or records feeds back in, so the loop compounds instead of starting cold every time. The key ingredient is a durable artifact between runs, a plan, acceptance criteria, or verified evidence, that the next pass reads rather than re-deriving.
### How is an agent flywheel different from just running an agent in a loop?
A plain loop repeats the same action, but nothing accumulates between iterations, so every pass starts from roughly the same place and pays full cost. A flywheel is a loop where each pass leaves behind something the next pass builds on, so it gets cheaper and faster over time. The difference is memory: a loop with no stored record is fast but flat, while a flywheel stores intent and judgment so the curve bends upward.
### Why does my AI coding agent get slower or more expensive over time?
Usually because it has no durable memory between tasks, so it re-scans your repository and re-derives what the code does every session. Builders report being "charged hundreds of times again" for context the agent already had, because nothing from the last run carried forward. The fix is to keep the source of truth outside the agent's context window, a plan and acceptance criteria the agent reads at the start of a task, so it does not pay to rediscover the same thing repeatedly. Keeping that record in a durable place the agent reloads, rather than in the chat it forgets, is the whole idea behind the [state file pattern](https://braingrid.ai/blog/claude-code-memory-state-file-pattern).
### What makes an agent flywheel actually compound instead of just spin fast?
A durable artifact that persists between runs. Speed alone is just autonomy, the agent going fast, and a fast loop that forgets accumulates nothing. What compounds is the record around the code: what "done" meant, which decisions were made and why, and what was verified with evidence. When each task reads that record instead of guessing, every rotation is cheaper than the last, which is what earns the word flywheel.
### Do I need acceptance criteria for an agent flywheel to work?
Yes, because the flywheel needs something to verify against, and criteria are what turn "the agent produced output" into "the output does what I intended." Without a written definition of done, the loop can run fast but cannot tell whether each pass moved the product forward or sideways. Acceptance criteria are the stored energy of the wheel: you write them once, and every future run reads and checks against them instead of relitigating what the feature was supposed to do.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that turns your idea into a requirement with acceptance criteria, builds it with your agent, and verifies every change, so your agent flywheel compounds instead of spinning in place. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The Three Artifacts That Actually Matter: Requirements, Acceptance Tests, Code
Source: https://www.braingrid.ai/blog/three-artifacts-requirements-acceptance-tests-code
Published: 2026-07-20T12:00:00Z
Every week the AI building community rediscovers a truth that has been sitting in software engineering textbooks since before most of these tools existed. This week it showed up in a Reddit comment. A builder who had wired up a full-stack loop with agents, and did not yet know "loop engineering" was even a term, worked out the whole thing from first principles and posted it as advice.
> "You have to define 'done' for your application, plan all the work it takes to get there, and then do it. There are three major artifacts you need: Your requirements, Your acceptance tests, Your code. All other artifacts are ancillary."
He is right, and the reason he is right is more interesting than the list. The person who wrote that was not reciting a methodology. He arrived at it because his loop kept producing things that looked finished and were not, and he reverse-engineered the fix. What he found is the same three artifacts a disciplined team would name, in the same order. The surprise is not that they matter. It is which one almost everyone skips.
## Why only three artifacts carry signal
Open any real project and you will find dozens of artifacts. Chat logs, prompts, markdown files, tickets, design notes, a scratchpad of half-ideas, the PR description the agent auto-generated. It feels like they all count. Most of them do not. They are records of how you got somewhere, not statements of what has to be true. Strip them away and three things are left standing.
Requirements say what the software must do. Acceptance tests say how you will know it did. Code is the thing that makes the tests pass. That ordering is not decorative. Requirements come first because you cannot test against a target you never named. Acceptance tests come second because "done" has to be a checkable fact before any code exists, not a feeling you develop after the demo. Code comes last because it is downstream of both. This is the same sequence the community keeps landing on in its own words: [the r/vibecoding thread](https://www.reddit.com/r/vibecoding/comments/1uxhatn/built_a_fullstack_loop_harness_didnt_know_loop/) puts it as "requirements to acceptance tests to code," and then delivers the line that should be taped to every agent's monitor.
> "If you want deterministic results, you need deterministic verification."
That is the whole argument in eight words. Everything else in the pile is a detail.
## The one artifact everyone skips
Here is the hypothesis this post rests on: most AI builds have two of the three artifacts and pretend the middle one is optional. There is a requirement, usually a sentence typed into a chat box. There is code, generated in seconds. And between them, where the acceptance test should be, there is nothing but the builder's own eyeballs and a demo that runs.
That missing middle is why the loop feels like a slot machine. Without an acceptance test, "done" is decided by looking at the screen, and a screen is a terrible verifier. It shows you the happy path, in good lighting, with the one input you happened to type. It does not show you the empty state, the second user, the expired token, the row that belongs to someone else. So the agent ships, you glance, it looks right, and the gap between looks-right and is-right gets discovered by a real user three weeks later. The acceptance test is the artifact that would have caught it, and it is precisely the one that got skipped because it is the only one that requires you to think before the code appears.
Consider the difference in plain terms. A requirement without an acceptance test is a wish. "Users can reset their password" is a direction, not a definition of done. Turn it into an acceptance test and it becomes checkable: a user who requests a reset gets an email within a minute, the link works exactly once, an expired link shows a specific message and not a stack trace, and a reset invalidates every existing session. Now there is a fact to verify instead of a vibe to trust. Same feature, same requirement, completely different odds of shipping the right thing.
## The middle artifact is what makes the loop hold
This maps directly onto the loop that AI building keeps converging on: [plan, build, verify, repeat](/blog/loop-engineering). The three artifacts are not a separate framework bolted on the side. They are what each stage of the loop actually produces. Plan produces the requirements. The definition of done produces the acceptance tests. Build produces the code. And verify is the step where the code is measured against the acceptance tests, not against a human's patience.
A loop with all three artifacts converges, because every pass has a target and a way to check whether it hit. A loop missing the acceptance test never converges. It just runs, produces something plausible, and waits for you to approve it on faith. The reason a loop that works on a toy breaks on a real app is not that the model got worse. It is that a toy has few enough states that your eyeballs are an adequate verifier, and a real app does not. As autonomy goes up, the number of decisions nobody explicitly wrote down goes up with it, and eyeball verification falls further behind. The acceptance test is how you scale verification past the point where looking still works.
This is where [BrainGrid](https://braingrid.ai) sits in the workflow. It is the plan-first platform that produces the first two artifacts before any code exists. You describe the feature, and the Planning Agent turns it into a requirement with acceptance criteria written to be checkable, the exact middle artifact most builds skip. Then the Builder Agent, working in a managed sandbox or in your own GitHub repo through your coding agent, builds against those criteria, and a feature is not done until each one is verified with evidence. The point is not the tooling. The point is that the acceptance test exists on purpose, upstream of the code, so the loop has something real to verify against instead of your attention span.
## The trade-off nobody advertises
Writing acceptance tests before the code is genuinely harder than not writing them. It front-loads the thinking. You have to decide what "reset works" means while you are still staring at an empty editor, which is exactly the moment your brain would rather skip ahead to the part where something runs. That friction is real, and pretending it away would be dishonest. The middle artifact costs you time up front, every time.
You pay for it either way. Skip the acceptance test and the cost moves downstream, into regeneration loops, into review sessions where you read code trying to guess what it was supposed to do, into the production bug that arrives with no test to reproduce it. Reviewing AI-generated code is its own tax, and a large part of it is [the oversight premium](/blog/the-oversight-premium): the cost of checking work against a standard that was never written down. The acceptance test is that standard, captured before the code, so review becomes a check instead of an archaeology dig. The bill comes due at planning time or at debugging time. It is smaller at planning time.
## What this means if you build with agents
If your current loop is "type a request, look at the result, ship if it seems fine," you are running on two artifacts and calling the demo your third. That works right up until the app has more states than you can hold in your head, which for anything real is around the fourth or fifth feature. The fix is not a better prompt or a smarter model. It is to write the acceptance test as a deliberate step, before the build, so the agent has a target it can check itself against and you have a fact you can trust instead of a screen you have to believe.
Three artifacts carry the signal. Requirements name the target, acceptance tests define the hit, code is downstream of both. Skip the middle one and the loop cannot converge, because there is nothing for it to converge toward.
## FAQ
### What is an acceptance test?
An acceptance test is a checkable condition that says whether a feature does what it was supposed to do. It describes behavior from the outside, a given starting state, an action, and the exact expected result, so that passing or failing is a fact rather than an opinion. In an AI build, the acceptance test is the standard the agent's output is measured against, which is what turns "the demo ran" into "the feature is verified."
### What is an example of an acceptance test?
Take "users can reset their password." A good acceptance test breaks that into specific, verifiable conditions: requesting a reset sends an email within one minute, the reset link works exactly once, an expired link shows a defined message instead of an error page, and completing a reset invalidates all existing sessions. Each of those either happens or it does not, with no room to argue, which is what makes them testable rather than aspirational.
### How do you write good acceptance tests?
Start from the requirement and ask what a skeptic would need to see to agree it is done. Name exact values instead of adjectives: the specific error message, the exact time limit, the precise state after the action. Cover the paths the happy demo skips, empty states, second users, expired tokens, and permission boundaries. The test to apply to every criterion is whether two people, or two agents, could disagree about whether it passed. If they could, it is not specific enough yet. For the full craft, see [how to write acceptance criteria an AI agent can actually verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
### What is the difference between acceptance criteria and acceptance tests?
Acceptance criteria state the conditions a feature must meet; acceptance tests are the concrete checks that confirm those conditions were met. In practice the line is thin, criteria are the definition, tests are the definition made runnable or verifiable. The important part for AI builders is that both live upstream of the code. They are the middle artifact that says what "done" means before the agent writes a line, not a QA step you improvise afterward. This is the core idea behind [spec-driven development](/spec-driven-development): the specification, requirements plus acceptance criteria, comes first, and the code is built to satisfy it.
### What is the difference between requirements and acceptance criteria?
Requirements describe what the software should do at the level of intent, "users can reset their password." Acceptance criteria pin that intent down into specific, testable conditions, "an expired reset link shows this message and does not error." Requirements come first and set direction; acceptance criteria come second and set the bar for done. Code is downstream of both, which is why getting the first two right is what decides whether the third is correct.
*[BrainGrid](https://braingrid.ai) is the plan-first platform that turns your idea into requirements and acceptance criteria your agent can build and verify against. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The Real Cost of a Vague Prompt (In Tokens, Credits, and Afternoons)
Source: https://www.braingrid.ai/blog/the-real-cost-of-a-vague-prompt
Published: 2026-07-19T12:00:00Z
Everyone is arguing about the price of a token. The real bill is somewhere else entirely, and it is bigger. A vague prompt is cheap to send and expensive to own, because the cheap part happens once and the expensive part happens over and over: the agent re-reads your repo to figure out what you meant, generates something plausible, you review it, it is wrong in a way you did not specify, and you prompt again. The token counter ticks up the whole time. So does the afternoon.
That is the part the pricing debate keeps missing. When a Reddit thread titled "Spent 4,000 USD on AI coding. Everything worked in dev. Nothing worked in production" pulls 450+ comments, the story is not really about token rates. It is about paying repeatedly for the same undefined intent. This post is about where that money actually goes, why a vague prompt is the most expensive input you can hand an agent, and the two-minute fix that changes the math.
## The hypothesis: you are not paying for tokens, you are paying for re-derivation
Here is the claim, stated so you can argue with it. The dominant cost of AI coding is not the price per million tokens. It is the number of times the agent has to re-derive what you want because you never wrote it down. A clear input is expensive to write once. A vague input is cheap to write and then charges you on every loop after it: to re-scan, to re-guess, to re-review, to re-generate. The token price is a rounding error next to the loop count.
The people closest to the money have started saying this out loud. On Hacker News, in a thread about AI coding cost, the top comment lands it cleanly:
> Human time spent redirecting AI coding agents towards better strategies and reviewing work remains dramatically more expensive than the token cost for AI.
That reframes the entire "is AI too expensive" panic. The token bill is visible, so it gets the attention. The redirect-and-review bill is invisible, so it gets ignored, and it is the one that actually hurts. Coding got cheap. Deciding what to build, and checking that it got built, did not.
## Where the money actually goes
Walk through what a vague prompt costs, dollar by dollar and hour by hour, and the shape of the bill becomes obvious.
The first cost is re-derivation. When you come back the next morning and ask a follow-up, the agent does not remember your app. It re-scans the repo, re-reads the files, and rebuilds its mental model from scratch before it answers. A builder in r/Anthropic described exactly this:
> When you come back the next day to ask a simple question it has to scan your whole repo and think about what it does every time, so you effectively get charged hundreds of times again for code that it wrote and knew better than you.
You are paying, in tokens, for the agent to re-learn code it already wrote, because the context lived in a conversation that is now gone. That cost recurs every session. It is the single most avoidable line item in the whole bill. It is the same dynamic behind [context rot](https://braingrid.ai/blog/context-rot): the longer the thread, the worse and pricier the answers get, until you start over and pay to rebuild the model again.
The second cost is the review tax. A vague prompt produces plausible output, and plausible is the most dangerous kind of wrong, because it passes a glance and fails in production. Someone has to read it closely, and reading closely is not free. Business Insider found developers spent 20% more time reviewing AI outputs than they saved writing them. The demo worked. The review is where the afternoon went.
The third cost is rework, which is the review tax with compound interest. You did not specify what "done" meant, so the agent picked. It picked wrong, and you re-prompt. Multiply that by every feature and the loop never converges, because there is nothing for it to converge on. As one Medium engineer put it, AI is accelerating software production but not eliminating software complexity, so poorly defined systems simply produce faster versions of the same mess.
## The reframe: a vague prompt is not underspecified, it is unbounded
Here is the moment where the assumption flips. Most builders think a vague prompt is a small prompt that could be a little more detailed. It is not. A vague prompt is an unbounded prompt. There is no edge to it, so there is no point at which the agent, or you, can say the work is finished. Every gap you left is a decision the agent makes for you, silently, and every silent decision is a place the loop can wander.
The two paths cost wildly different amounts, and the difference is the number of trips around the loop.
```mermaid
flowchart TD
A[Vague prompt] --> B[Agent guesses intent]
B --> C[Plausible output]
C --> D[Review finds it wrong]
D --> E[Re-prompt]
E --> B
F[Bounded prompt with done defined] --> G[Agent builds to spec]
G --> H[Verify against criteria]
H --> I[Done]
```
This is why loops that work on a toy fall apart on a real app. The failure is not the model getting worse. It is the decisions compounding. A builder in r/AI_Agents named it precisely: at small scale a loop works, at large scale it breaks, because the "amount of decisions greatly increase, and compound exponentially." Each unspecified detail multiplies against every other one. A vague prompt does not cost you a little more than a clear one. It costs you the exponential.
Look at the two side by side and the price difference is visible in the text itself.
> Vague: "Add user settings."
> Bounded: "Add a settings page at /settings, visible only to authenticated users. It has two fields: display name (text, required, 2 to 40 characters) and email notifications (on/off toggle, default on). Saving shows a success toast and persists immediately. Unauthenticated users hitting /settings redirect to /login. Done means: an authenticated user can change both fields, reload the page, and see the saved values."
The first one is a prompt. The second one is a boundary. The first will be re-run four times as you discover what you actually meant. The second gets built once and verified once, because there is a definition of done attached to it that both you and the agent can check against. The extra ninety seconds of writing is the cheapest ninety seconds in the whole project. This is the entire premise of [spec-driven development](https://braingrid.ai/spec-driven-development): the spec is not overhead, it is the thing that stops the loop from wandering, and there is [a right way to vibe code that keeps the speed and loses the debt](https://braingrid.ai/blog/how-to-vibe-code-the-right-way).
## Where BrainGrid fits: write the boundary once, stop paying for the guess
This is the exact gap BrainGrid was built to close, and it is a workflow step, not a slogan. The problem is not that you are bad at prompting. It is that a chat window is the wrong place to store the boundary, because it evaporates and the agent has to re-derive it every session.
In BrainGrid, you describe the idea in plain English, the way you already do. The Planning Agent turns it into a requirement with explicit acceptance criteria: the settings page, the auth guard, the field constraints, the definition of done, written down and kept. That requirement is the boundary the vague prompt never had. The Builder Agent then builds against it, in a BrainGrid Managed sandbox with a live preview, or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. And a feature is not done until every criterion is verified with evidence, so the loop has something concrete to converge on instead of your best guess about what you might have meant.
The point is not that BrainGrid saves you tokens as a feature claim. The point is structural: when the boundary lives in a durable requirement instead of a disposable conversation, the agent stops charging you to rediscover your own app, and the reviewer stops paying the tax on plausible-but-unspecified output. You wrote the intent down once. Nobody has to re-derive it.
## What this means if you are building right now
Be concrete about who this hits. If you are shipping a SaaS product with Claude Code, Cursor, or a vibe-coding tool this week, your cost problem is almost certainly not your plan tier. It is that your third and fourth features are being generated against intent that only ever existed in a chat you have since closed. That is why the same feature keeps coming back slightly wrong, why the token bill climbs faster than your feature count, and why every session starts with the agent re-reading everything.
The fix is not a cheaper model or a bigger context window. It is moving the boundary out of the conversation and into a written definition of done before the agent starts. Do that and the loop count drops, which is the number that was actually costing you, not the token rate. A durable record of what "done" means is the context the agent stops charging you to rediscover.
The honest trade-off: writing the boundary is real work, and it is slower than typing "add user settings" and hitting enter. On a throwaway prototype you will never touch again, skip it, the vague prompt is genuinely cheaper there. The moment the thing is real, the moment you are going to keep building on it, that up-front minute is the highest-return time you will spend all week. The vague prompt was never the cheap option. It just moved the invoice to a line you were not watching.
## FAQ
### Why does AI coding get so expensive?
The visible cost is tokens, but the dominant cost is re-derivation and rework. Every session, the agent re-scans your repo to rebuild context it does not retain, and every vague prompt produces plausible output that has to be reviewed and often re-prompted. You end up paying repeatedly for the same undefined intent. As the top Hacker News comment on AI coding cost puts it, human time redirecting and reviewing agents is dramatically more expensive than the token price.
### What is the real cost of AI generated code?
It is the total of three things the token counter does not show: re-derivation (the agent re-learning code it already wrote each session), the review tax (Business Insider found developers spent 20% more time reviewing AI output than they saved), and rework (re-prompting because "done" was never defined). The generation is cheap. Understanding, reviewing, and fixing the output is where the real bill lands.
### How do I reduce my AI coding costs?
Cut the loop count, not just the token rate. The biggest lever is defining "done" before the agent starts, so it builds against a boundary instead of guessing and getting re-prompted. Keep that boundary in a durable requirement with acceptance criteria rather than a chat window, so the agent is not re-deriving your app every session. A bounded prompt gets built and verified once; a vague one gets re-run until you accidentally specify it.
### Is a vague prompt really more expensive than a detailed one?
Yes, because a vague prompt is unbounded, not just short. Every gap you leave is a decision the agent makes silently, and those decisions compound. A builder in r/AI_Agents observed that loops work at small scale but break at large scale because the amount of decisions increases and compounds exponentially. A detailed prompt costs ninety extra seconds to write and gets built once. A vague one is cheap to send and charges you on every loop after it.
### Will AI coding tokens just get cheaper over time?
Token prices may fall, but that is not where your money is going. The re-derivation, review, and rework costs scale with how undefined your intent is, not with the token rate, so cheaper tokens do not fix an unbounded prompt. They just make each wasted loop slightly less expensive while you run more of them. Lowering the loop count with a clear definition of done saves more than any price drop.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns a plain-English idea into a requirement with acceptance criteria your coding agent can build and verify against, so you stop paying to re-explain your own app. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Claude Code vs Cursor vs Codex vs Gemini: The 2026 Agent Comparison
Source: https://www.braingrid.ai/blog/claude-code-vs-cursor-vs-codex-vs-gemini
Published: 2026-07-17T12:00:00Z
I have run all four of these agents against the same codebase, and I am going to give you the comparison you came for. Claude Code, Cursor, Codex, and Gemini each have a real shape, and picking the wrong one for your workflow will cost you weeks.
But here is what nobody selling you a comparison chart will say. After the fourth or fifth time you switch, you notice the bugs follow you.
Same vague feature request, same confidently wrong result, different logo in the corner. That pattern is the actual finding, and it is worth more than any benchmark table.
## The four agents, honestly
**Claude Code** is a terminal agent from Anthropic. You run it in your CLI, it reads your repo, it makes multi-file changes and commits them. It is exceptional at holding a large codebase in its head and executing long refactors without losing the thread. If you live in a terminal, it feels like the tool was built by someone who watched you work.
**Cursor** is an AI-native IDE, a fork of VS Code. You get inline chat, fast autocomplete, and visual diffs across files. It is the lowest-friction option because it looks exactly like the editor you already use, and its agent has closed most of the gap with the terminal-first tools. (We compared these two [head to head last quarter](/blog/claude-code-vs-cursor), and the gap has narrowed since.)
**Codex** is OpenAI's asynchronous, cloud-sandboxed agent. You hand it a task, it spins up its own environment, works without you watching, and comes back with a pull request. The interaction model is genuinely different: you are not pairing with it, you are dispatching it.
**Gemini** brings Google's models with a very large context window and a CLI of its own. It is strong on sprawling, unfamiliar codebases where you need the agent to read a lot before it writes anything.
Those differences are real. Choose on workflow, not on a leaderboard: terminal-native goes Claude Code, editor-native goes Cursor, fire-and-forget goes Codex, huge unfamiliar repo goes Gemini.
Now let me spend the rest of this post on why that choice is not the one determining your outcome.
## The convergence nobody prices in
Look at what these tools have actually done over the past eighteen months. Cursor shipped a stronger agent. Claude Code shipped a web and cloud experience. Codex shipped local execution. Gemini shipped a CLI. Every one of them added the thing its rival was known for.
Steve Sewell at Builder.io [put it plainly](https://www.builder.io/blog/codex-vs-claude-code) after testing them head to head:
> "All of these products are converging. Cursor's latest agent is pretty similar to Claude Code's latest agents, which is pretty similar to Codex's agent."
That quote reframes the entire comparison genre. If the products are converging, then a post ranking them is measuring the gap that is closing fastest, and it expires the moment someone ships. Every one of these vendors will keep shipping.
So the interesting question is not which agent is ahead this quarter. It is what stays constant while they converge.
## The variable that does not converge
Here is my hypothesis, and it is testable: **the quality of your output is bounded by the quality of your instruction, and no agent improvement lifts that ceiling.**
Test it yourself. Hand any of the four this:
> Vague: "Add user profiles to the app."
You will get four different implementations. One puts the avatar upload in the wrong service. One invents a schema that collides with your auth table. One adds a settings page you never asked for. One does something reasonable and forgets that only the profile's owner should be able to edit it. All four will report success. All four will look done.
Now hand any of the four this:
> Specific: "Add a user profile page at /profile. Display the authenticated user's name, email, avatar, and join date. The user can edit name and avatar only; email is read-only and changed through the existing account flow. Avatar accepts PNG or JPG under 2MB and stores to object storage, not the database. Only the profile's owner can edit; other authenticated users viewing /profile/:id get a read-only view; unauthenticated users redirect to /login."
Now the four results converge. Not because the agents got better, but because the ambiguity that made them diverge is gone. Every difference you were measuring in that first test was the agent guessing, and each one guessed differently.
That is the reframe. The comparison charts are measuring how each model guesses. They are benchmarking the part of your workflow you should be eliminating.
## Why this gets worse as the agents get better
The intuitive read is that better agents need less instruction. The opposite is true, and this is the part that surprises people.
A weak agent that writes twenty lines and stops is easy to correct. You read the twenty lines. But Codex works unattended in a sandbox and returns a pull request touching fourteen files. Claude Code executes a refactor across your repo while you are in a meeting. The agent's autonomy is exactly the thing that removes your chance to course-correct mid-flight.
More autonomy means more decisions nobody wrote down. This is the [oversight premium](/blog/the-oversight-premium): the less you watch, the more the standard you set up front has to carry.
When you did not write down that email should be read-only, someone decided. It was not you. And you found out in review, or worse, in production. The faster and more capable the agent, the more decisions it makes per unit of your attention, and the more expensive each unwritten one becomes.
A PM in r/cscareerquestions [described the current generation this way](https://www.reddit.com/r/cscareerquestions/comments/1uwxs3p/):
> "They're helpful accelerators but asking them to build something complex from scratch is like asking a very confident intern who memorized stackoverflow."
The useful part of that line is not the dig. It is the word *confident*. Confidence is not correctness, and every agent on this list reports success identically whether it understood you or invented an answer. You cannot tell the two apart from the agent's output. You can only tell them apart against something you wrote down first.
## What this means if you are building right now
If you are three features into a SaaS product with any of these four, the switch you are considering will not fix what is bothering you. You will get a better autocomplete and the same drift. Your fourth feature will still contradict your second, because nothing in your setup ever recorded what your second feature was supposed to do.
This is where BrainGrid sits, and it is deliberately not a fifth agent on this list. It is the layer above [all four](/ai-coding-agents). You describe the feature to the Planning Agent, it asks the questions you did not think of (who can edit this, what happens when the file is too large, what does the unauthenticated case do), and turns your idea into a requirement with real acceptance criteria. Then the Builder Agent builds it, either in BrainGrid Cloud with a live preview, or in your own GitHub repo driving Claude Code, Cursor, or Codex over MCP. The agent you love keeps doing the part it is good at.
The part that changes is the ending. Every criterion gets checked against the build, and the feature is not done until the evidence says it does what you intended. Code review tells you the code is well-written. Verification tells you it does what you meant.
Your tools change. The workflow doesn't.
## The trade-off
Writing the specific version of that profile requirement takes longer than typing "add user profiles." That is a real cost and I am not going to pretend otherwise. For a throwaway prototype, a script you will run once, or an experiment you fully intend to delete, it is not worth it. Type the vague prompt. Let it rip. Speed is the whole point and there is nothing downstream to protect.
The calculus flips the moment the thing has users. Then the ten minutes of clarity is not overhead, it is the best-value ten minutes in the project, because the alternative is finding the missing authorization check after someone else does.
Vibe tools are fast until your app matters.
## The verdict
The hypothesis holds. Pick your agent on workflow fit, terminal or editor or async or big-context, and pick it in an afternoon, because that decision is smaller than the internet wants you to believe. Then spend your real effort on the input, which is the only variable in this system that does not improve on its own.
The agents will keep converging. What you hand them is the part that stays yours.
## FAQ
### Which is better, Claude Code or Cursor?
Neither, structurally. Claude Code is a terminal agent that excels at large multi-file refactors and deep codebase reasoning; Cursor is an AI-native IDE with the lowest friction if you already work in VS Code. Their agents have largely converged in capability. Pick on where you want to work, terminal or editor, and expect the gap to keep narrowing.
### Is Codex better than Claude Code?
They solve different interaction problems. Codex runs asynchronously in a cloud sandbox and returns a pull request without you watching, which suits well-defined tasks you can dispatch and forget. Claude Code runs locally in your terminal and is better when you want to stay in the loop on a complex change. Async autonomy raises the value of writing your requirements down first, because you are not there to correct it mid-run.
### Can I use more than one AI coding agent?
Yes, and many builders do: an IDE agent for daily edits, an async agent for batched tasks. The friction is that each agent starts from zero on what your product is supposed to do. Keeping requirements and acceptance criteria outside any single tool is what makes switching between them cheap.
### Do better AI coding agents need less detailed instructions?
No. More capable agents work more autonomously, which means they make more decisions per unit of your attention, and every decision you did not specify is one they make for you without asking. Capability raises the cost of ambiguity rather than lowering it.
### What is the best AI coding agent in 2026?
There is no single best one, and any post that names one is measuring a gap that closes within a quarter. Claude Code for terminal-native deep work, Cursor for editor-native flow, Codex for fire-and-forget async tasks, Gemini for large unfamiliar codebases. The larger determinant of your result is the clarity of the requirement you hand whichever one you pick.
Pick your agent this afternoon, then go write down what "done" actually means for your next feature.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that turns your idea into a real spec with acceptance criteria, then builds it with the agent you already use and proves it works. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Skills, Hooks, and Subagents: Assembling Your First Agent Loop in Claude Code
Source: https://www.braingrid.ai/blog/skills-hooks-subagents-first-agent-loop
Published: 2026-07-16T12:00:00Z
The most powerful features in Claude Code are the three most people never turn on. Hooks, skills, and subagents have been sitting in the docs for months, and the builders who wired them together are running agent loops that ship real work while the rest of us are still typing prompts one at a time.
That gap is the story of loop engineering, the term that took over the AI building conversation this summer after Boris Cherny, who leads Claude Code at Anthropic, [told an audience he does not prompt Claude anymore](https://thenewstack.io/loop-engineering/): "I have loops running that prompt Claude and figuring out what to do." The idea landed because it is true. The way to get more out of a coding agent is not a better prompt. It is a better loop. And the raw material for that loop, if you are working in Claude Code, is exactly these three primitives. The hypothesis for this post is simple: **hooks, skills, and subagents are the parts you assemble into a reliable agent loop, and learning what each one does is the fastest way to stop babysitting your agent. But all three control *how* the loop runs, and none of them define *what done means*, which is the one input the loop cannot generate for itself.**
## Hooks: the rules that fire whether or not the agent remembers
Start with hooks, because they are the most underused and the easiest to misunderstand.
A [hook](https://code.claude.com/docs/en/hooks) is a shell command, HTTP endpoint, or prompt that Claude Code runs automatically at a specific point in its lifecycle: before it edits a file, after it finishes a task, right before it runs a shell command. You configure it once, and it fires every time that moment arrives, no matter what the agent is "thinking." That last part is the whole point. If you put "run the formatter after every edit" in your instructions, the agent will do it most of the time and forget it some of the time, because instructions are suggestions a model weighs against everything else in its context. A hook is not a suggestion. It is a guarantee.
The community figured this out fast. One of the most-shared explainers on the topic called hooks ["the permission system for AI agents"](https://cobusgreyling.medium.com/claude-code-hooks-f5a4a8b0e53c), and that framing is exactly right. The reason you reach for a hook instead of a line in your `CLAUDE.md` is determinism. You want the linter to run every single time, the secret-scanner to block a commit every single time, the test suite to fire before the agent declares victory every single time. Model behavior is probabilistic. A hook is not.
Here is the concrete difference. Tell the agent in prose to "always run `pnpm test` before finishing," and on a long, messy task it will sometimes skip it, announce the feature is done, and hand you a broken build. Wire a `Stop` hook that runs the tests and blocks completion on failure, and it cannot skip it, because the skip is no longer the model's decision. Same agent, same model. The only variable is whether the check was a request or a rule.
## Skills: the expertise the agent loads only when it needs it
Skills solve the opposite problem. Hooks are always-on guarantees. Skills are on-demand knowledge.
A [skill](https://code.claude.com/docs/en/skills) is a folder with a Markdown file that teaches the agent how to do one specific thing: how your team writes migrations, how to generate a PDF invoice, how to review a component against your design system. It sits dormant until the agent hits a situation the skill describes, and only then does it load into context. This is the fix for the failure mode we wrote about in [context rot](https://braingrid.ai/blog/context-rot): the more you stuff into the agent's context up front, the worse it performs on the task in front of it. Skills let you keep deep, specialized expertise available without paying for it on every turn. The knowledge is there when the job needs it and out of the way when it does not.
The trade-off is real, and worth naming. A skill only fires if the agent recognizes that the moment has arrived, so a skill with a vague description will sit unused while the agent improvises badly. The skill is only as good as its trigger. Write the description as if you are telling a new hire exactly when to reach for this playbook, or it will gather dust.
## Subagents: the fresh context that keeps the main thread clean
The third primitive is the one that makes the loop scale.
A [subagent](https://code.claude.com/docs/en/sub-agents) is a separate instance of the agent with its own context window, spun up to handle a delegated piece of work. The main session hands it a task, the subagent does all its exploring, file-reading, and dead-end reasoning inside its own window, and only the result comes back. The messy middle never touches your main thread. This matters because a single long agent session degrades as its context fills with the debris of everything it has already tried. Subagents are how you run a big job without letting the exploration for step three poison the agent's judgment on step seven.
In practice this is what lets a loop take on real scope. A "reviewer" subagent checks the work a "builder" subagent produced, each in a clean window, the way you would split the maker from the checker on a real team. The main loop orchestrates; the subagents do the isolated work and report back. That separation is why builders describe subagents as the feature that took their Claude Code setup from a clever assistant to something that actually holds together across a multi-step task.
## Assembling the loop
Put the three together and the loop stops being a metaphor and becomes a machine you can point at a goal.
```mermaid
flowchart LR
A[Task from your work queue] --> B[Skill loads the right playbook]
B --> C[Subagent builds in clean context]
C --> D[Hook fires: tests + lint]
D -->|fails| C
D -->|passes| E[Reviewer subagent checks the result]
E --> F[Result returns to main loop]
F --> A
```
Skills supply the how-to at the moment it is needed. Subagents do the isolated work without clogging the main thread. Hooks fire the non-negotiable checks that the model is not allowed to skip. Wrap that in a loop that pulls the next task and repeats, and you have the thing Cherny described: a system that prompts the agent so you do not have to. This is loop engineering at the level a working builder can actually reach today, not a research demo.
And this is genuinely a step up. Scheduled, self-checking agent runs are real, they ship in Claude Code right now, and assembling these primitives will get you further than any amount of prompt-tuning. If you build with Claude Code, the practical implication is direct: your next hour is better spent wiring one hook and one subagent than polishing another prompt, because the prompt is a one-time gain and the loop compounds.
## The reframe: the loop runs the work, but it cannot decide what "done" means
Here is the part the loop tweets leave out, and it is the part that matters most.
Every one of these three primitives controls *how* the loop runs. A hook decides *when* a check fires. A skill decides *how* a task is performed. A subagent decides *where* the work happens. None of them decides *what* you are building or *how you will know it is right*. Your `Stop` hook can run the test suite on every pass, but something has to have written the tests, and something has to have decided that passing them actually means the feature does what you intended. That "something" is not a hook, a skill, or a subagent. It is a plan with acceptance criteria, and the loop cannot generate it for itself.
A vibe coder in a recent Reddit thread rebuilt this idea from scratch without any of the vocabulary, and said it better than most docs: ["You have to define 'done' for your application, plan all the work it takes to get there... requirements, acceptance tests, code. If you want deterministic results, you need deterministic verification."](https://www.reddit.com/r/vibecoding/comments/1uxhatn/built_a_fullstack_loop_harness_didnt_know_loop/) That is the whole game. A loop only holds together at scale when there is a fixed standard it is checking each pass against. Without one, the reviewer subagent has nothing to review against, the `Stop` hook is checking that the code runs rather than that it is correct, and every pass of the loop can quietly drift a little further from what you actually wanted. The loop runs beautifully and ships the wrong thing.
This is exactly the gap [BrainGrid](https://braingrid.ai/loop) is built to close. BrainGrid is the plan-first app-building platform, and it runs the same loop, Plan then Build then Verify then Repeat, but it owns the two pieces the Claude Code primitives cannot generate: the plan and the standard. You describe the feature, and the Planning Agent turns it into a requirement with explicit acceptance criteria, the definition of done your loop's checks measure against. The Builder Agent then builds it, either in the BrainGrid Cloud sandbox or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP, so your hooks and subagents keep doing what they are good at while the loop finally has a target. Verification checks the build against every criterion, and the feature is not done until the evidence says it matches intent. The primitives make the loop run. The plan is what makes the loop worth running.
## FAQ
### What are Claude Code hooks?
Claude Code hooks are shell commands, HTTP endpoints, or prompts that run automatically at specific points in the agent's lifecycle, such as before it edits a file, before it runs a shell command, or when a task finishes. Because they fire deterministically rather than depending on the model to remember an instruction, they are used to enforce guarantees like running a formatter after every edit, blocking a risky command, or running the test suite before the agent can declare a task complete. They are the closest thing Claude Code has to a permission and automation system, and they are configured once in your settings rather than requested on each prompt.
### What is the difference between hooks, skills, and subagents in Claude Code?
The three solve different problems. Hooks are always-on rules that fire automatically at set moments and cannot be skipped by the model, so they are for guarantees like tests and linting. Skills are on-demand knowledge, folders of instructions the agent loads only when it recognizes the relevant situation, so they are for specialized expertise you do not want in context all the time. Subagents are separate agent instances with their own context windows that handle a delegated task and return only the result, so they are for isolating messy work and keeping the main session clean. Hooks control when checks run, skills control how a task is done, and subagents control where the work happens.
### Do I need to use hooks, skills, and subagents to build with Claude Code?
No, you can build productively with Claude Code using plain prompts, and many people do. These three features matter when you want to move from prompting one step at a time to running a more autonomous loop that ships multi-step work with less babysitting. Hooks give you deterministic checks, skills give you reusable expertise, and subagents let a bigger job run without degrading the main context. If your agent keeps skipping steps you told it to take, forgetting your conventions, or losing the thread on long tasks, those are the signals that assembling these primitives will pay off.
### What is loop engineering?
Loop engineering is the practice of designing a system that prompts and orchestrates an AI coding agent automatically, instead of prompting it by hand one step at a time. The term spread after Boris Cherny, who leads Claude Code at Anthropic, said he no longer prompts Claude directly but writes loops that prompt Claude for him. In Claude Code, the building blocks of such a loop are hooks, skills, and subagents. The catch is that a loop only produces reliable results when it has a fixed standard to check each pass against, which means requirements and acceptance criteria the loop verifies the work against, not just automation that keeps it running.
### Can a Claude Code loop verify that a feature is actually correct?
Only partly, and this is the key limitation. Hooks can run your tests and subagents can review the work, but that only verifies what the tests and the reviewer were told to check for. Something still has to define what "done" means for the feature, write the acceptance criteria, and decide that passing the checks actually equals doing what you intended. That definition is a plan, and the loop's primitives cannot generate it for themselves. This is why builders pair an agent loop with an explicit requirement and acceptance criteria: the loop runs the work, but the plan is what tells it, and you, that the result is right.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that turns your idea into a requirement with acceptance criteria, so your Claude Code loop finally has a definition of done to build and verify against. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Webhook vs API: What Your Agent Wired Up When It Added a Webhook
Source: https://www.braingrid.ai/blog/webhook-vs-api
Published: 2026-07-15T12:00:00Z
Your agent said it "added a webhook for payments," the checkout worked, and you moved on to the next feature. Here is the part nobody told you: you just opened a door on the public internet that an outside service knocks on, and the agent almost certainly did not add the one check that makes sure the knock is real.
That is a different kind of gap than a bug. A bug is code that does the wrong thing. This is code that does exactly what it was asked, where the important part was never asked for. A webhook is not the same as the API you already have, and the difference is not academic trivia. One of them is a door you open when you want something. The other is a door someone else opens whenever they want, and if you do not check who is knocking, anyone can knock.
If you have been shipping with Cursor, Claude Code, Lovable, or Replit and "webhook" has always just slid past you as one more word the agent used, this one is for you. The hypothesis: **an API is a door you knock on to pull data when you want it, a webhook is a door another service knocks on to push you news, and the check that a webhook is genuine is an acceptance criterion you specify, not a default the agent picks.**
## The plain difference: pull versus push
Start with the version the vendor pages bury under diagrams.
An **API** is the set of doors your app knocks on to get things done. When your app wants a user's data, it calls the API and asks for it. When it wants to charge a card, it calls the payment API and tells it to. The pattern is always the same: your app initiates, on your schedule, because it wants something right now. Zapier's [explainer](https://zapier.com/blog/webhook-vs-api/) puts the mechanics plainly: APIs are "request" driven, while webhooks are "event-driven" data transfers. You pull with an API. You knock, and the other side answers.
A **webhook** flips the direction. Instead of your app asking, an outside service tells you the moment something happens. Stripe finishes charging a card, so it sends a message to a URL you gave it: "this payment succeeded." You did not ask at that moment. You set up a door ahead of time and handed the address to Stripe, and now Stripe knocks on it whenever there is news. RudderStack's [comparison](https://www.rudderstack.com/blog/webhook-vs-api/) names the split cleanly: APIs use a pull approach where your application actively requests information, while webhooks employ a push mechanism where data is sent automatically when an event fires.
Here is the mental picture that survives contact with a real app. An API is you calling the pizza place to ask if your order is ready. A webhook is the pizza place texting you the second it comes out of the oven. In the first, you decide when to ask, and you can ask a hundred times. In the second, they decide when to tell you, and you just have to be ready to receive the text. Both move the same information. The difference is who starts the conversation, and that difference is the whole thing.
The confusion is so common that the top organic result for this exact search, six years running, is a [Reddit thread](https://www.reddit.com/r/webdev/comments/d6o9j4/whats_the_difference_between_a_webhook_and_api/) of developers trying to pin it down, and a fresh one landed [last week](https://www.reddit.com/r/webdev/comments/1upisf5/how_is_a_webhook_different_from_a_push_api/) asking how a webhook differs from a push API. If professional developers keep re-asking this, the answer is not obvious, and you were never behind for not knowing it.
## Why AI builders trip over this one specifically
Search "webhook vs api" and you get mParticle, Akamai, Twilio, Zapier, SuperTokens, Strapi. Every page is technically correct and written for someone who decided, on purpose, to wire up a webhook and needed to understand it to do so. None of them is written for your situation: you did not decide to add a webhook, you cannot fully read the handler the agent wrote, and you only know it exists because the agent mentioned it in a sentence you scrolled past on the way to seeing the payment go through.
That is the actual shift, and it is bigger than one integration. In the old world, the person who set up a webhook understood it, because setting it up required understanding it. You could not register a Stripe webhook and write the handler without learning what a webhook was and what could go wrong. The knowledge and the code arrived together. AI cut that link. Now the webhook can exist, and route real payment events into your database, in the hands of someone who has never heard the term. The integration gets built. The understanding of what it should guard against does not come bundled in.
This is the capability-test version of the problem, the one that gets worse as the models get better, not better. Andrej Karpathy [named the failure mode](https://x.com/karpathy/status/1886192184808149383) when he coined vibe coding: you "fully give in to the vibes" and "forget that the code even exists." Forgetting the code exists is harmless for a weekend toy. But a payment webhook is not code you can afford to forget. It is a public URL that an outside service calls to tell your app that money moved, and a handler that believes every knock is a handler that will believe a forged one. The more your agent can wire up on its own, the more public doors exist that you never decided the rules for. Autonomy does not remove the decision about who is allowed to knock. It just makes that decision silently, on your behalf, in the direction of whatever demos fastest.
Consider the same feature asked two ways.
> Vague: "Add a webhook so we mark the order as paid when Stripe confirms the payment."
> Specified: "Add a webhook endpoint at `/api/webhooks/stripe` that listens for the `payment_intent.succeeded` event. Before trusting any incoming request, verify the Stripe signature against our webhook signing secret and reject with a 400 if it fails. Only then mark the matching order as paid. Ignore duplicate events for an order that is already paid."
Same webhook. The first version hands every one of those decisions, is this call genuine, what event does it handle, what if it arrives twice, to the agent's default, which is the configuration that gets the happy-path demo working with the least friction: accept the request, trust it, mark the order paid. The second version turns each rule into something you can actually check without reading the handler. Send a request with a bad signature and confirm you get a 400. Send the same valid event twice and confirm the order is not charged forward twice. That is a test anyone can run. "Is the webhook set up correctly?" is not a question you can answer by looking. "Does a forged webhook call get rejected?" is a question you can answer in ten seconds.
## The one check the agent skipped: is this knock real?
Here is the thing that separates a webhook from the rest of your API, and it is the thing worth carrying out of this whole post. When your app calls an API, your app is the one initiating, so your app controls the conversation. When a webhook fires, an outside party initiates, which means the request arrives at a public URL that anyone on the internet can also find and call. Nothing about the address stops a stranger from sending your webhook endpoint a message that says "payment succeeded" for an order that was never paid.
That is why real webhook providers sign their requests. Stripe, GitHub, and every serious sender attach a signature computed from a secret only you and they share, and the deal is simple: your handler recomputes that signature and, if it does not match, throws the request away. A [Stack Overflow answer](https://stackoverflow.com/questions/45197360/whats-the-difference-between-http-request-and-webhook-request-in-azure-func) in the "is a webhook just an HTTP request" thread gets the mechanics right, a webhook is just a specific kind of HTTP request, but that framing hides the danger. Because it is just an HTTP request, anyone can send one. The signature check is the entire difference between "a message from Stripe" and "a message claiming to be from Stripe."
An agent building for a passing demo has no reason to add that check. The demo works without it. Stripe sends a real event, the handler trusts it, the order is marked paid, the video looks great. The signature verification only matters the day someone who is not Stripe sends the same shape of request to your public URL and your app, trusting every knock, marks their order paid for free. Nothing in the demo would ever surface that. It is a hole that is invisible until it is exploited, which is exactly the kind of hole that never makes it into a spec nobody wrote.
There is a real trade-off here, and pretending otherwise would be dishonest. Not every webhook guards money, and locking down a low-stakes internal notification the way you would lock a payment handler is wasted effort and a source of false alarms when the signing secret rotates and legitimate calls start bouncing. And webhooks bring their own operational headaches the pull-based API does not: if your endpoint is down when the event fires, you may miss it entirely, so anything critical needs the sender's retries turned on or a periodic reconciliation against the API as a backstop. The skill is not "verify and armor every webhook to the maximum." It is knowing which incoming doors carry consequences, money, access, destructive actions, and specifying the checks for those precisely, while leaving the trivial ones simple. Telling those apart is judgment. Judgment is the part the agent does not do for you.
## The reframe: the check is a criterion, not a default
This is the same move we made writing about [what an API endpoint is](https://braingrid.ai/blog/what-is-an-api-endpoint) and [what an API gateway is](https://braingrid.ai/blog/what-is-an-api-gateway): the holes that keep showing up in AI-built apps are not coding mistakes, they are unspecified rules. An unverified webhook is exactly that. Its job was never just "receive the event and update the database." Its full job is "receive the event, confirm it genuinely came from the real sender, ignore it if it is a duplicate, and only then update the database." That second half is the part that never gets written down, so the agent ships the first half and the door stands unlatched.
Reframing it this way changes what you are on the hook for. You are not responsible for writing the signature-verification code; the agent can do that, and do it well, once it is told to. You are responsible for stating what the door must check before it trusts a knock, and then confirming that it does.
A webhook has a small, answerable set of questions attached to it, and every one is a plain-language decision. Does this handler verify the request genuinely came from the sender before acting on it? What happens to a request that fails that check, a clean rejection, or a silent pass-through that updates your data anyway? What happens if the same event arrives twice, does the order get processed twice? And is the receipt logged, so that when a payment does not reconcile you can see what actually arrived? Answer those, and you have written the acceptance criteria for one of the most exposed surfaces in your app: a public door an outsider gets to open.
## Where this fits in the loop
This is the gap [BrainGrid](https://braingrid.ai/vibe-coding-tools) is built to close. You describe the feature in plain language, "mark the order paid when the payment succeeds," and the Planning Agent turns it into a requirement with explicit acceptance criteria, including the ones you would otherwise leave in your head: verify the sender's signature, reject anything that fails it, handle duplicate events, log every receipt. "A webhook request with an invalid signature is rejected with a 400 and changes nothing" becomes part of the standard the Builder Agent builds against, whether that build runs in BrainGrid Cloud with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP.
That is the loop: Plan the door's checks alongside the feature, Build against them, Verify each one with evidence, Repeat. A webhook that accepts a forged call does not quietly pass, because "only genuine, signature-verified requests are acted on" is written down as a criterion, and a feature is not done until every criterion is checked with evidence. Code review can tell you the handler is tidy. Verification tells you a forged request actually bounces. Those are different questions, and for a public door that touches real money, only the second one keeps you safe.
## What this means if you are building right now
If your agent added or touched a webhook this week, do one thing before you ship. Find out what the webhook does, and ask whether it touches money, access, or anything you cannot undo. If it does, write the rule down as a criterion, "only requests with a valid signature from the real sender are trusted, everything else is rejected," and then verify it the only way that counts. Send the endpoint a request with a bad signature and confirm it refuses. Send a real event twice and confirm the work happens once. If a forged knock gets in, or a duplicate double-processes, you found the unlatched door before someone else did.
The uncomfortable truth underneath this is the same one that runs through every honest conversation about building with AI. The agent is not wiring up your webhook badly. It is wiring it up silently, toward whatever demos fastest, every time you leave the checks out of the spec. An unverified webhook is not a mysterious flaw buried in code you cannot read. It is a public door whose lock you never asked for. Ask for the lock, make it a criterion, and check it. For the doors behind this one, we wrote about [what an API endpoint is](https://braingrid.ai/blog/what-is-an-api-endpoint) and [how to write acceptance criteria an AI agent can actually verify](https://braingrid.ai/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
## FAQ
### What is the difference between a webhook and an API?
An API is a door your app knocks on to pull data or trigger an action when you want it: your app initiates the request, on your schedule. A webhook flips the direction: it is a door you set up so an outside service can push you news the moment an event happens, like a payment succeeding or a file finishing upload. With an API, you ask and wait for an answer. With a webhook, you register a URL ahead of time and the other service calls it whenever there is something to report. A useful shorthand: APIs pull, webhooks push. Technically a webhook is delivered as an API call, so it is fair to call it a specific, event-driven kind of API rather than a separate technology.
### Is a webhook just an HTTP request?
Yes, mechanically a webhook is an HTTP request, usually a POST, sent to a URL you provided. That is exactly why it needs care. Because it is an ordinary HTTP request, anyone who knows or guesses your webhook URL can send one that looks just like the real thing. The safeguard is that legitimate senders like Stripe and GitHub sign their requests with a secret only you and they share, and your handler is supposed to verify that signature before trusting the request. So "it's just an HTTP request" is true, and it is the reason the signature check is not optional for any webhook that touches money or access.
### Is a webhook better than an API?
Neither is better; they solve opposite problems. Use an API when your app needs to fetch data or perform an action on demand, when you are the one who decides the timing. Use a webhook when you need to react the instant something happens on another service and you do not want to poll it over and over asking "did it happen yet?" In practice most real apps use both: a webhook tells you an event occurred, and then your code often calls that service's API to fetch the full up-to-date details. The webhook is the notification; the API is how you ask follow-up questions.
### What are webhooks used for?
Webhooks are used anywhere your app needs to know about an event on another service the moment it happens, without constantly checking. The classic example is payments: Stripe sends a webhook when a charge succeeds or fails so you can fulfill the order. Others include a CI service telling you a build finished, a form tool notifying you of a new submission, a chat platform pushing you new messages, or a file service reporting an upload completed. The common thread is real-time reaction to someone else's event. Instead of your app asking "anything new?" every few seconds, the other service tells you, which is faster and far less wasteful.
### What are the disadvantages of webhooks?
Webhooks have three main downsides. First, security: because the endpoint is a public URL an outsider can call, you must verify each request is genuinely from the real sender, or a forged call can trick your app. Second, delivery reliability: if your endpoint is down or slow when the event fires, you can miss it, so critical webhooks need the sender's retry feature enabled or a periodic reconciliation against the API as a backstop. Third, duplicates and ordering: the same event can arrive more than once or out of order, so your handler needs to be safe to run twice without doing the work twice. None of these are reasons to avoid webhooks; they are the reasons a webhook that touches anything important needs a real specification, not just a handler that trusts every knock.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into a requirement with acceptance criteria, including the checks a public door has to pass before your app trusts it, so your agent ships a latched door instead of an open one. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is an API Gateway? The Front Door Your AI Agent Built for a Backend You Didn't Design
Source: https://www.braingrid.ai/blog/what-is-an-api-gateway
Published: 2026-07-14T12:00:00Z
Your agent said it "set up an API gateway," the app kept working, and you nodded along like you knew what that meant. You didn't, and that's fine. The problem is that a gateway is the single front door in front of everything your app does, and right now the rules for that door were written by an agent optimizing for a passing demo, not by you.
That is a different kind of gap than a bug. A bug is code that does the wrong thing. This is code that does exactly what it was told, where nobody told it the important part. A gateway decides who gets to knock on your backend at all, how many times a second, and whether anyone is watching. Those are decisions. When you leave them out of the spec, the agent doesn't skip them. It picks the defaults that make the feature light up fastest, and moves on.
If you have been shipping with Cursor, Claude Code, Lovable, or Replit and the phrase "API gateway" has always just slid past you, this one is for you. The hypothesis: **an API gateway is the one front door in front of your whole backend, and what that door enforces, who gets through, how often, and what gets logged, is a set of acceptance criteria you decide, not a default you inherit.**
## What an API gateway actually is
Start with the plain version, before the cloud vendors bury it in diagrams.
Your app is not one thing. Behind the screen your users see, there are usually several separate services: one that handles logins, one that handles payments, one that stores data, one that sends email. An **API gateway** is a single entry point that sits in front of all of them. Every request from the outside world hits the gateway first, and the gateway decides where it goes and whether it's allowed to go there at all. IBM's [definition](https://www.ibm.com/think/topics/api-gateway) is clean: it is "a software layer that presents a single entry point for clients to access multiple backend services."
The reason this pattern exists is worth holding onto, because it explains why the gateway matters so much. Without a front door, every one of your services has to independently handle the boring, dangerous work: checking who's calling, rejecting abuse, keeping logs, enforcing limits. Five services, five copies of that logic, five chances to get one of them wrong. The gateway pulls all of that into one place. F5's [glossary](https://www.f5.com/glossary/api-gateway) calls it "a data-plane entry point for API calls," which is a precise way of saying: this is the chokepoint every request passes through. That is its power and its danger. One door, one place to get the rules right, one place to get them catastrophically wrong.
The best plain-language picture came, predictably, from a builder who was as confused as you are. The top result when you search this question is a [Reddit thread](https://www.reddit.com/r/aws/comments/1gpixqo/what_does_api_gateway_actually_do/) titled, verbatim:
> I've read the docs, a few reddit threads and videos and still don't know what it sets out to accomplish.
That is the honest starting point, and it's the one every vendor page skips. So here is the mental model that survives contact with a real app. Think of your backend as an office building with several departments. The gateway is the lobby with one security desk. Everyone entering the building goes through that desk. The desk checks badges, turns away people who show up a hundred times a minute, and writes down who came and went. The departments upstairs, payments, user data, admin tools, trust that the lobby already did the checking. Which means if the lobby waves everyone through, every department upstairs is exposed, and none of them know it.
## Why AI builders trip over this one specifically
Search "what is an API gateway" and you get IBM, F5, AWS, GeeksforGeeks, Red Hat, Postman. Every page is technically correct and written for a cloud engineer who is choosing to stand up a gateway on purpose. None of them is written for your situation: you did not decide to add a gateway, you cannot fully read the config the agent wrote, and you only know it's there because the agent mentioned it in a sentence you scrolled past.
That is the actual shift, and it is bigger than one piece of infrastructure. In the old world, the person who configured a gateway understood it, because configuring it required understanding it. You could not set up routing and auth and rate limits without knowing what each of those words meant. The knowledge and the config arrived together. AI cut that link. Now the gateway can exist, and route traffic correctly, in the hands of someone who has never heard the term. The infrastructure gets built. The understanding of what it should enforce does not come bundled in.
This is the capability-test version of the problem, the one that gets worse as the models get better, not better. Andrej Karpathy [named the general failure mode](https://x.com/karpathy/status/1886192184808149383) when he coined vibe coding: you "fully give in to the vibes" and "forget that the code even exists." Forgetting the code exists is harmless for a weekend toy. But your gateway is not code you read, it is the single control point for who reaches your entire backend, and a control point nobody is watching is not a convenience, it is an open lobby. The more your agent can stand up on its own, the more infrastructure exists that you never decided the rules for. Autonomy doesn't remove the decisions. It just makes more of them silently on your behalf.
Consider the same feature asked two ways.
> Vague: "Set up an API gateway for the app so the frontend can reach the backend."
> Specified: "Route all `/api/*` traffic through a single gateway. Public routes (`GET /api/posts`) are open. Everything under `/api/admin/*` and `/api/users/*` requires a valid logged-in session; reject unauthenticated requests with a 401. Rate-limit any single client to 100 requests per minute and return a 429 when exceeded. Log the method, path, and response status of every request."
Same front door. The first version hands every one of those decisions, who's allowed, how often, what's logged, to the agent's default, which is the configuration that gets the demo working with the least friction: open routes, no limits, minimal logging. The second version turns each rule into something you can actually check without reading a line of gateway config. Hit an admin route with no login and confirm you get a 401. Fire 200 requests in a minute and confirm the door starts returning 429. That is a test anyone can run. "Is the gateway configured correctly?" is not a question you can answer by looking. "Does an unauthenticated admin request get rejected?" is a question you can answer in ten seconds.
## The reframe: a gateway's rules are criteria, not a config it picks for you
This is the same move we made writing about [what an endpoint is](https://braingrid.ai/blog/what-is-an-api-endpoint) and [row-level security](https://braingrid.ai/blog/what-is-row-level-security-for-vibe-coders): the holes that keep showing up in AI-built apps are not coding mistakes, they are unspecified rules. A gateway that lets anyone reach an admin service is exactly that. Its job was never just "pass traffic to the backend." Its full job is "pass the right traffic to the right service, at a sane rate, and turn away everything else." That second half is the part that never gets written down, so the agent ships the first half and the lobby stands unmanned.
Reframing it this way changes what you're on the hook for. You are not responsible for writing gateway config; the agent can do that. You are responsible for stating what the door must enforce, and then confirming it does.
A gateway has a small, answerable set of questions attached to it, and every one is a plain-language decision. Which routes are public and which require a logged-in user? How many requests per minute is any one client allowed before the door starts saying no? What happens to a request that fails the check, a clean rejection with the right status code, or a silent pass-through? And is every request logged, so that when something goes wrong you can see who did what? Answer those, and you have written the acceptance criteria for the most exposed part of your entire app, the one door standing in front of all the others.
There is a real trade-off here, and pretending otherwise would be dishonest. A gateway you over-lock is a product that frustrates its own users: legitimate traffic hitting a rate limit that's too tight, a public page that demands a login it never needed. And for a small app early on, a full gateway can be more machinery than the moment calls for; sometimes the honest answer is a simpler setup until the app grows into needing one. The skill is not "lock every door as hard as possible." It is knowing which routes lead to money, private data, or destructive actions, and specifying the rules for those precisely, while leaving the front page open. Telling those apart is judgment. Judgment is the part the agent does not do for you.
## Where this fits in the loop
This is the gap [BrainGrid](https://braingrid.ai/vibe-coding-tools) is built to close. You describe the feature in plain language, and the Planning Agent turns it into a requirement with explicit acceptance criteria, including the ones you would otherwise leave in your head: which routes this feature exposes, which of them require authentication, what the rate limits should be, and what a rejected request should return. "Admin routes require a logged-in session and return a 401 otherwise" becomes part of the standard the Builder Agent builds against, whether that build runs in BrainGrid Cloud with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP.
That is the loop: Plan the door's rules alongside the feature, Build against them, Verify each one with evidence, Repeat. A gateway that waves through an unauthenticated admin request does not quietly pass, because "unauthenticated requests to admin routes are rejected" is written down as a criterion, and a feature is not done until every criterion is checked with evidence. Code review can tell you the gateway config is tidy. Verification tells you the door actually turns away the request it should. Those are different questions, and for the single entry point in front of your whole backend, only the second one keeps your users safe.
## What this means if you are building right now
If your agent stood up or touched a gateway this week, do one thing before you ship. List the routes your app exposes, and for each one answer two questions: does it require a logged-in user, and does it touch anything you can't undo. For the routes that handle real data or real money, write the rule down as a criterion, "only a logged-in user reaches this, everyone else gets a 401," and then verify it the only way that counts. Call the route with no session and confirm the door rejects you. Hammer it past your intended limit and confirm it starts refusing. If nothing pushes back, you found the unmanned lobby before an attacker did.
The uncomfortable truth underneath this is the same one that runs through every honest conversation about building with AI. The agent is not configuring your infrastructure badly. It is configuring it silently, toward whatever demos fastest, every time you leave the rules out of the spec. An open gateway is not a mysterious flaw buried in config you can't read. It is a front door whose rules you never wrote. Write the rules, make them criteria, and check them. For the pieces behind this door, we wrote about [what an API endpoint is](https://braingrid.ai/blog/what-is-an-api-endpoint) and [how to write acceptance criteria an AI agent can actually verify](https://braingrid.ai/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
## FAQ
### What is an API gateway in simple terms?
An API gateway is a single front door that sits in front of all the services that make up your app. Instead of the outside world talking directly to your login service, your payment service, and your data service separately, every request goes through the gateway first. The gateway decides where each request should go and whether it's even allowed, and it handles shared jobs like checking who's calling, limiting how often someone can call, and keeping a log. For a builder, the key point is that the gateway is the one place that controls access to everything behind it, so the rules it enforces matter more than the rules on any single service.
### What is an example of an API gateway?
Amazon API Gateway is the most common one you'll see named, because it's the managed service AWS offers for exactly this job. Other widely used gateways include Kong, and the routing layers built into platforms like Cloudflare and Vercel. If your AI agent deployed your app to a cloud platform, there is a good chance one of these is quietly sitting in front of your backend already, routing `/api/*` requests to the right place. The specific product matters less than what it's configured to enforce: which routes are open, which need a login, and what gets turned away.
### What is the difference between an API and an API gateway?
An API is the set of ways programs are allowed to talk to your app, made up of individual endpoints (doors). An API gateway is the single entry point that sits in front of those endpoints and controls access to all of them at once. Think of the endpoints as the doors to individual rooms and the gateway as the building's one staffed lobby that everyone passes through first. You secure an endpoint door by door; the gateway lets you enforce shared rules, like authentication and rate limits, in one central place instead of repeating them everywhere.
### Is an API gateway a server?
Functionally, yes, an API gateway runs as a piece of software that receives network requests and responds to them, which is what a server does. But it usually doesn't do the actual work of your app. It receives the request, applies rules (auth, rate limiting, logging), and forwards it to whichever backend service should handle it, then passes the response back. So it's better to think of it as a routing-and-control layer in front of your real servers than as the server that runs your business logic.
### What does an API gateway do that a regular backend doesn't?
A regular backend service handles one job, like storing orders or sending email. An API gateway handles the cross-cutting jobs that every service would otherwise have to duplicate: authenticating callers, enforcing rate limits, routing requests to the right service, and logging traffic in one place. The value is centralization. Instead of each service independently getting authentication right (and each one being a chance to get it wrong), the gateway does it once for everything behind it. That's also why an unmanaged gateway is dangerous: one open front door exposes every service upstream at the same time.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into a requirement with acceptance criteria, including which routes your agent exposes and what the front door in front of them must enforce, so your app ships with a staffed lobby instead of an open one. Try it at [braingrid.ai](https://braingrid.ai).*
---
# AGENTS.md, Explained: The README Your Coding Agent Actually Reads
Source: https://www.braingrid.ai/blog/agents-md-explained
Published: 2026-07-13T12:00:00Z
Your AI coding agent has never read your README. It reads a different file, and if you have not written that file, it is working off guesses about your project every single time you prompt it.
That file is `AGENTS.md`, and in the last year it has quietly become the closest thing the industry has to a standard. Over 60,000 open-source projects now ship one, and every major agent, Cursor, Claude Code, GitHub Copilot, Codex, Windsurf, Aider, has agreed to look for it. If you have been building with an agent and wondering why it keeps using the wrong test command, importing the wrong way, or "fixing" things you told it never to touch, the answer is usually that nobody wrote down the rules where the agent would see them. The hypothesis for this post is simple: **AGENTS.md is where your project's *how* lives, the durable instructions an agent needs to work in your repo, and it is essential precisely because it stops the agent from reinventing your conventions on every run. But it has a hard ceiling, and knowing where that ceiling is matters as much as knowing what the file does.**
## What AGENTS.md actually is
Start with the plain version, because the docs bury it under "agent-native repos" and "deterministic parsing."
A `README.md` is written for a human. It has a quick-start, a description of what the project does, maybe a contributing guide. It assumes a person is reading it, skimming, filling in gaps with judgment. An `AGENTS.md` is written for a machine. It sits at the root of your project, and when a coding agent starts working in your repo, it reads that file first to learn the things it cannot infer: how to build the project, how to run the tests, what conventions to follow, and what it must not do.
The [official spec](https://agents.md/) puts it in one line:
> Think of it as a README for agents.
That is the whole idea. It is standard Markdown, no special syntax, no framework. You write down the stuff a new engineer would need on their first day, except the "new engineer" is an agent that starts fresh every session and has no memory of the last one. Exact build and test commands. The linter rules you actually enforce. Which directories hold what. The "never do this" and "always ask first" boundaries that keep it from making a confident, destructive mistake.
Here is the analogy that makes it stick. AGENTS.md is the onboarding doc you would hand a contractor who is genuinely skilled but has never seen your codebase and will forget everything the moment they walk out the door. You would not explain what a database is. You would tell them "we use pnpm, not npm," "run `pnpm test` before you commit," "the auth logic lives in `src/auth` and you do not touch it without asking." That is exactly what belongs in AGENTS.md. Skilled worker, zero context about *your* specific project. The file supplies the context.
## Why it caught on so fast
The reason AGENTS.md spread is not that it is clever. It is that the alternative was chaos.
Before the standard, every tool wanted its own instruction file. Cursor read `.cursorrules`. Claude Code read `CLAUDE.md`. Copilot read `.github/copilot-instructions.md`. If you used more than one agent, or switched between them, you were maintaining three or four files that all said roughly the same thing and drifted apart the moment you updated one and forgot the others. AGENTS.md collapsed that into one file that every agent agreed to read. Write your instructions once, and they travel across tools.
And the payoff is measurable, not vibes. GitHub studied the pattern across [more than 2,500 repositories](https://github.blog/ai-and-ml/github-copilot/how-to-write-a-great-agents-md-lessons-from-over-2500-repositories/) and found the same thing the whole community keeps rediscovering: an agent's success is tied directly to the quality of the instructions it is given. A vague or missing AGENTS.md means the agent guesses at your build command, your import style, your file layout, and gets a meaningful fraction of those guesses wrong. A good one means it gets them right on the first try, which is the difference between a clean pull request and three rounds of "no, we use the other pattern."
Consider the concrete before and after. Without an AGENTS.md, you ask the agent to add a feature and it runs `npm install`, writes tests in a style you abandoned six months ago, and puts a new component in the wrong folder. You spend twenty minutes correcting things that have nothing to do with the actual feature. With a good AGENTS.md, the agent reads "use pnpm, tests go in `__tests__` next to the file, components live in `src/components` and use the existing `Button` primitive," and the first draft already matches your conventions. Same agent. Same model. The only variable is whether the rules were written down where it looks.
## What belongs in it, and what does not
This is where most of the pain lives, and where the file gets misused.
AGENTS.md is for the durable, project-wide *how*. The things that are true across every feature you will ever build in this repo. Build and test commands. Coding conventions and the linter rules you enforce. The tech stack and versions. Directory structure and where things live. Hard boundaries: files not to touch, patterns to never use, "ask before you run a migration." The rule of thumb: if it would be true no matter what feature you are working on today, it belongs in AGENTS.md.
What does not belong in it is the *what* of any specific piece of work. The requirements for the feature you are building right now. What "done" means for this particular task. The acceptance criteria for the checkout flow you are adding this afternoon. Those are not ambient facts about your project; they are the definition of one job, and they change with every job. Stuffing them into AGENTS.md is how the file rots.
And it does rot, which is the failure mode worth naming honestly. The whole design of AGENTS.md is that it loads into the agent's context at the start of a session, once, always on. That is its strength and its trap. Because it is always loaded, every line you add is a line the agent carries through every single task, whether or not it is relevant. The sharpest version of the critique came from a builder on LinkedIn who called [AGENTS.md "the new 'just add more comments'"](https://www.linkedin.com/posts/shreyshahh_agentsmd-is-the-new-just-add-more-comments-activity-7458952727105093632-DaEm), a lazy solution everyone adopted because no one questioned it, one flat file that grows until it is noise. There is even [research suggesting that verbose, poorly structured AGENTS.md files can *reduce* an agent's success rate](https://www.reddit.com/r/ClaudeAI/comments/1r7mvja/new_research_agentsmd_files_reduce_coding_agent/), because you are spending the context window on instructions the agent does not need for the task at hand and diluting the ones it does.
So the trade-off is real: the file is only useful while it stays lean. Lead with the commands. Keep the boundaries tight. Resist the urge to paste your entire style guide into it. And whenever you catch the agent making the same mistake twice, that is the signal to add one line to AGENTS.md, a mistake turned into a rule, which is the highest-value thing the file can hold.
## The reframe: AGENTS.md carries how you build, a spec defines what done means
Here is the distinction that untangles most of the confusion, and it is the same line that runs through everything we write about building with agents.
There are two completely different kinds of knowledge an agent needs, and people keep trying to cram both into one file. The first is *how you build here*, your conventions, commands, and constraints. That is ambient. It is true all the time, it belongs in context always, and AGENTS.md is exactly the right home for it. The second is *what this specific thing should do and how you will know it is done*. That is not ambient. It is the definition of a single unit of work, and it belongs with that work, not in a file every task drags along.
When you blur those two, both jobs get done badly. Your AGENTS.md swells with feature-specific detail that becomes stale the moment the feature ships, and your actual requirements live nowhere durable, so the agent builds against a vague prompt and you find out it built the wrong thing at review time. Keep them separate and both get sharp. AGENTS.md stays a lean, stable description of your project's rules. The requirement for each feature carries its own acceptance criteria, the specific, checkable statements of what this build has to do.
This is exactly the gap [BrainGrid](https://braingrid.ai/context-engineering) is built to close. AGENTS.md tells the agent *how* to work in your repo, and it should. But it was never designed to tell the agent *what* to build or to verify that the build is correct, and it cannot, because it is a static file with no notion of "done." In BrainGrid, you describe the feature and the Planning Agent turns it into a requirement with explicit acceptance criteria, the *what* and the definition of done, which the Builder Agent then builds against, whether that build runs in the BrainGrid Cloud sandbox or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. AGENTS.md sets the ground rules. The requirement sets the target. The two are complements, not competitors, and trying to make one file do both jobs is why so many AGENTS.md files end up bloated and so many builds end up subtly wrong.
## What this means if you are building right now
If you are shipping features with an agent and you do not have an AGENTS.md, write one today, and keep it short. Put your exact build and test commands at the top. Name your stack and versions. State the two or three conventions you actually care about and the two or three boundaries the agent must never cross. That alone will kill a whole category of "why did it do it that way" friction, because the agent will finally be working from your rules instead of its priors.
But do not ask that file to do the job it cannot. The moment you find yourself pasting the requirements for a specific feature into AGENTS.md, stop. That is a sign the *what* of your work has nowhere durable to live, and the fix is not a longer instruction file. It is a real requirement with acceptance criteria for that feature, kept with the feature and checked against the build. AGENTS.md is how your agent learns your project. It is not how your agent learns what you actually want it to ship this afternoon. Get the ambient rules into AGENTS.md, keep the per-feature definition of done somewhere the build gets verified against it, and you have covered both kinds of knowledge instead of half of each.
If you want to go deeper on the ambient side, we wrote about [context engineering](https://braingrid.ai/blog/four-pillars-of-context-engineering) and [why agents get less reliable the longer they run](https://braingrid.ai/blog/context-rot). For the target side, here is [how to write acceptance criteria an AI agent can actually verify](https://braingrid.ai/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
## FAQ
### What is an AGENTS.md file?
AGENTS.md is a standard Markdown file placed at the root of a project that gives AI coding agents the project-specific context they cannot infer on their own: how to build and test the project, what coding conventions to follow, where files live, and what the agent must not do. It works like a README written for machines instead of humans. Over 60,000 open-source projects use it, and major agents including Cursor, Claude Code, GitHub Copilot, Codex, and Windsurf all read it, so you can write your instructions once and have them apply across every tool.
### Do I need an AGENTS.md file?
If you build with an AI coding agent regularly, yes, it is one of the highest-value things you can add. Without it, the agent guesses at your build command, your import style, your file layout, and your conventions on every session, and it gets a meaningful fraction of those guesses wrong. A short, well-structured AGENTS.md means the agent's first draft already matches how your project works, which removes a whole category of correction cycles. For a one-off script or a repo you never touch with an agent, it is not necessary.
### Does AGENTS.md actually help?
It helps when it is lean and specific, and it can hurt when it is bloated. GitHub's study of over 2,500 repositories found that agent success is directly tied to the quality of the instructions, so a focused file with exact commands and clear boundaries measurably improves results. But because AGENTS.md is always loaded into the agent's context, a long, poorly structured file spends the context window on irrelevant instructions and can actually reduce success rates. The fix is to keep it short, lead with commands, and only add rules that apply across every task.
### Is AGENTS.md always loaded?
Yes, that is the core of how it works and also its main limitation. Instruction files like AGENTS.md are loaded once at the start of a session and stay in the agent's context for that session, so every rule in the file is carried through every task whether or not it is relevant. This is why the file is ideal for ambient, project-wide facts (your build command, your conventions) and a poor fit for feature-specific requirements, which change with every task and are better kept with the individual piece of work.
### What is the difference between AGENTS.md and a spec or acceptance criteria?
AGENTS.md carries the *how*: the durable, project-wide rules for working in your repo, true no matter what feature you build. A spec with acceptance criteria carries the *what*: the specific definition of one feature and how you will know it is done, which changes with every task. AGENTS.md is a static file with no concept of "done," so it can tell the agent how to work but cannot verify that a build is correct. The two are complements. You keep the ambient rules in AGENTS.md and the per-feature definition of done in a requirement the build is checked against.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into a requirement with acceptance criteria, the definition of done your agent builds against, so AGENTS.md can stay lean and your builds still land correct. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is an API Contract? The Agreement That Keeps Your AI Agent From Breaking Its Own Codebase
Source: https://www.braingrid.ai/blog/what-is-an-api-contract
Published: 2026-07-12T12:00:00Z
Your AI agent can build a working feature in ten minutes. It can also, three features later, quietly break that feature while adding a fourth, and never notice it did.
That second sentence is the one nobody warns you about when you start building with an agent. The demos all show the first ten minutes. The pain shows up around feature five, when your app has grown past the size the agent can hold in its head, and a change over here silently breaks something over there. It is not that the agent got worse. It is that nothing wrote down how the pieces are supposed to fit together, so the agent is guessing at the seams every single time.
A builder who has shipped millions of lines of autonomous AI code named the exact fix, in a [thread about why "just vibe-code it" stops working](https://www.reddit.com/r/AINativeAgencies/comments/1uqnzab/) once the codebase grows. His verdict was blunt:
> As long as the API contracts are solid it's probably the only workable approach. It absolutely cannot follow all the loosely coupled implications of a change and constantly forgets parts or implements incorrectly.
That is the whole post in one quote. If you have been building with Cursor, Claude Code, Lovable, or Replit and you have watched your agent "fix one thing but destroy ten others," the missing piece is probably an API contract. The hypothesis is simple: **an API contract is a written agreement about how two parts of your app talk to each other, and it is the boundary your agent needs precisely because it cannot infer the boundaries nobody wrote down.**
## What an API contract actually is
Start with the plain version, the one the docs bury under OpenAPI and Swagger jargon.
Your app is not one thing. It is a bunch of parts that talk to each other: a frontend that shows the screens, a backend that stores the data, sometimes a payment service, an email service, an auth service. Every time two of those parts talk, one sends a request and the other sends a response. An **API contract** is the written agreement about what that request and response look like. What does the frontend send when it asks for a user's orders? What exactly does the backend send back, and in what shape? A contract answers those questions in a form both sides, and both agents building those sides, can be checked against.
The GeeksforGeeks [definition](https://www.geeksforgeeks.org/system-design/api-contracts-system-design/) gets the mechanics right:
> API Contracts are agreements that define how two systems communicate through an API. They specify request formats, response structures, methods, and error handling.
The word that matters in that sentence is *agreement*. A contract is not code. It is the thing the code on both sides has to agree with. If the backend promises "asking for an order returns an object with an `id`, a `total`, and a `status`," then the frontend can be built to expect exactly that, and the backend can be tested to confirm it delivers exactly that. Neither side has to read the other's code. They both read the contract.
Here is the analogy that makes it stick. A contract is like the agreed shape of a plug and a socket. The lamp does not need to know how the power station works. It needs to know the plug has two flat prongs a certain distance apart, because that is what the socket promises to accept. The contract is the shape of the plug. As long as both sides honor it, you can rewire the entire power station behind the socket and the lamp keeps working. Break the shape of the plug, and it does not matter how good the wiring is. Nothing connects.
## Why AI builders trip over this specifically
Search "api contract" and you get Bump.sh, GeeksforGeeks, Adobe, a survival guide from a frontend engineer, and a six-year-old Medium post. Every one of them explains contracts correctly. Every one of them is written for a professional developer on a team, someone who already knows why two services need a shared agreement and is looking for the best tool to write one. None of them is written for the person whose situation is genuinely new: someone whose agent is building both sides of the conversation at once, fast, in a codebase that is outgrowing what any single prompt can see.
That is the actual problem, and it is worth being precise about. In the old world, an API contract solved a *coordination* problem between people. The backend team and the frontend team needed to agree so they would not build two halves that did not connect. The contract was a treaty between humans.
AI changed what the contract is for. Your agent is not a team that forgets to communicate. Your agent is one worker with a memory that fills up. The reason it "constantly forgets parts," as the builder above put it, is that the whole codebase no longer fits in its context window, so when it changes the backend it cannot see everywhere the frontend depended on the old shape. It is not being careless. It genuinely cannot hold the loosely coupled implications of a change in view all at once. The contract stops being a treaty between people and becomes the durable memory of the seams, the record of how the pieces connect that lives *outside* the window that keeps overflowing.
This is the same failure mode we wrote about in [context rot](https://braingrid.ai/blog/context-rot): the agent gets less reliable the longer it runs and the more it has to remember. A contract is one of the few things that fights it, because it moves the most breakable knowledge, how the parts fit, out of the agent's leaky memory and into a written artifact the agent can re-read every time.
Consider the difference between two ways of adding the same feature.
> Vague: "Add a way for the frontend to load a user's orders."
> With a contract: "The frontend loads orders by calling `GET /api/orders`. The response is a JSON array of order objects. Each order object has exactly these fields: `id` (string), `total` (number, in cents), `status` (one of `pending`, `paid`, `shipped`), and `createdAt` (ISO date string). If the user has no orders, return an empty array, never null."
Same feature. The first version leaves the shape of the data entirely to whatever the agent invented that afternoon. The second version pins the shape down. Now, three features later, when the agent needs to change how orders are stored, the contract is still there saying "the response must still have `total` in cents." If the agent ships a change that returns dollars instead, that is not a mysterious bug that surfaces when a customer sees a $47 order billed as $4,700. It is a contract violation you can catch with a single test, before it ever ships.
## The reframe: a contract is captured intent for the seams between your features
This is the same move that runs through everything we write about building with agents: the thing that keeps AI from quietly breaking your app is not smarter code, it is intent someone wrote down. A contract is that idea applied to the joints of your application.
Think about what actually breaks when your codebase grows past the point the agent can see all at once. It is almost never the middle of a feature. It is the *edges*, the places where one feature's output is another feature's input. The agent changes the shape of what the orders endpoint returns, and the dashboard that consumed the old shape breaks. The agent renames a field in the user object, and the settings page that read the old name goes blank. These are not deep logic errors. They are broken handshakes. And a handshake only breaks when the two sides disagree about its shape, which can only happen when the shape was never written down as something both sides had to honor.
Reframing it this way changes what you are responsible for. You are not responsible for writing the OpenAPI file or wiring up contract-testing tooling; the agent can do that. You are responsible for deciding, in plain language, what the important seams in your app are and what shape they should hold. The orders endpoint returns these fields in these types. The auth service always returns a user object with an `id` and a `role`. The payment webhook always includes the amount and the order it belongs to. Those are the plugs and sockets of your app, and stating their shape is a decision, not a default.
There is a real trade-off worth naming, because pretending otherwise would be dishonest. You do not need a formal contract for every function in your app, and trying to write one for everything would slow you to a crawl and bury the contracts that matter under noise. A contract earns its keep at a boundary that two independently changing parts have to agree on: the frontend and the backend, your app and a third-party service, one module and another that a different agent run might touch. The seams inside a single small feature that always changes together do not need a treaty. The skill is not "contract everything." It is knowing which seams are load-bearing, the ones where a silent disagreement becomes a customer-facing break, and pinning those down. Telling them apart is judgment, and judgment is exactly the part the agent does not do for you.
## Where this fits in the loop
This is the gap [BrainGrid](https://braingrid.ai/spec-driven-development) is built to close. When you describe a feature that touches a boundary, the Planning Agent turns it into a requirement with explicit acceptance criteria, including the ones you would otherwise leave in the agent's short-term memory: what shape this endpoint returns, what the other side is allowed to depend on, what happens at the edges. "The orders endpoint returns `total` in cents and never null" becomes part of the standard the Builder Agent builds against, whether that build runs in the BrainGrid Cloud sandbox or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP.
That is the loop: Plan the shape of the seam along with the feature, Build against it, Verify the shape actually holds, Repeat. A change that quietly breaks the contract does not slip through, because "the response still matches this shape" is written down as a criterion, and a feature is not done until every criterion is verified with evidence. Code review tells you the new code reads well. Verification against the contract tells you the new code did not break the handshake three features away that you forgot existed. As your agent does more work unattended, that second check is the one that keeps a growing codebase from turning into "fix one thing, break ten."
## What this means if you are building right now
If your app has more than three or four features and your agent has started breaking things it built earlier, this is almost certainly your problem, and the fix is not a better prompt. Find the boundaries where one part of your app depends on the shape of another part's output: frontend to backend is the big one, but also anywhere you talk to a payment or auth or email service. For each of those, write down the shape of the agreement in plain language, the fields, the types, what happens when there is nothing to return, and make that shape an acceptance criterion the agent's work gets checked against. Then, next time the agent changes one side, you find out immediately if it broke the handshake, instead of discovering it when a user does.
The uncomfortable truth underneath this is the same one that runs through every honest conversation about building with AI. The agent is not too dumb to keep your codebase coherent. It is working blind at the seams, because the seams were never written down, and no amount of context window will fix a boundary that exists only in the agent's fading memory of what it built last week. Write the contracts for the boundaries that matter, make them criteria, and check them. For the door your agent built into your app, we wrote about [what an API endpoint is](https://braingrid.ai/blog/what-is-an-api-endpoint), and for turning any rule like this into something an agent can verify, [how to write acceptance criteria an AI agent can actually verify](https://braingrid.ai/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
## FAQ
### What is an API contract, in simple terms?
An API contract is a written agreement about how two parts of an app talk to each other over an API: what one side sends in a request, and what the other side promises to send back in the response. It specifies the exact shape of the data, the fields, their types, and how errors are handled, so both sides can be built and tested against the same agreement without reading each other's code. A good analogy is the shape of a plug and socket: as long as both honor the agreed shape, either side can change internally and the connection still works.
### What does an API contract look like?
In practice, an API contract describes, for each endpoint, what request it accepts and what response it returns. For an orders endpoint it might say: the request is `GET /api/orders`; the response is a JSON array where each item has an `id` (string), a `total` (number in cents), a `status` (one of a fixed set of values), and a `createdAt` (ISO date). Contracts are often written in a machine-readable format like OpenAPI (also called Swagger) so tools can check both sides automatically, but the underlying idea is just a precise description of the request and response shape that both sides agree to honor.
### Is Swagger an API contract?
Swagger, now standardized as OpenAPI, is a format for writing an API contract, not the contract itself. The contract is the agreement about how the API behaves; Swagger/OpenAPI is one popular, machine-readable way to write that agreement down so tools can generate documentation, client code, and tests from it. You can have an API contract without Swagger (written in plain language or another spec format), and you can use Swagger to describe an API without treating it as a strict contract. The value comes from both sides actually being checked against whatever form the contract takes.
### Why do API contracts matter for AI coding agents?
Because an AI agent cannot hold a large codebase in its context window all at once, so when it changes one part it often cannot see every other part that depended on the old behavior. That is why agents "forget parts" and break working features as the codebase grows. An API contract moves the knowledge of how the parts connect out of the agent's fading memory and into a written artifact it can re-read and be verified against. It turns a silent, delayed break at the seams of your app into a contract violation you can catch with a single test before it ships.
### What is the difference between an API contract and an API endpoint?
An API endpoint is a single door into your app, one URL paired with an action, like `GET /api/orders`. An API contract is the agreement about how that door behaves: what a request to it must contain and what shape of response it promises to return. The endpoint is the location; the contract is the promise about what happens there. You can have an endpoint with no written contract (the agent just made up the shape), which is exactly the situation that leads to broken handshakes later. Writing the contract turns the endpoint's behavior from an assumption into something both sides can rely on and verify.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into a requirement with acceptance criteria, including the shape of the seams your agent builds against, so a growing codebase stops meaning "fix one thing, break ten." Try it at [braingrid.ai](https://braingrid.ai).*
---
# The 8 Questions to Answer Before Your AI Agent Writes a Line of Code
Source: https://www.braingrid.ai/blog/8-questions-before-your-agent-writes-code
Published: 2026-07-11T12:00:00Z
The best way to get bad software out of a good AI agent is to give it a good prompt. Not a lazy one. A confident, detailed, one-paragraph prompt that sounds like you know exactly what you want, handed to a capable agent that will build precisely what you said and quietly invent everything you didn't. The agent isn't the problem. The eight things you never decided are.
This is the gap underneath almost every "I thought AI would build my app for me, here's what actually happened" thread. The builder had an idea, described it in a sentence, watched a working preview appear in ten minutes, and then spent the next three weeks discovering all the decisions the agent made on their behalf. So here is the checklist that goes in front of the build: the eight questions you answer before your agent writes a line of code, and why skipping any one of them is how you end up scared to ship.
## The hypothesis: your agent is only as good as the questions you answered first
Here is the claim, stated so you can push back on it. The quality of AI-built software is set before the build starts, not during it. The agent's job is to execute a definition of done. If that definition lives only in your head, the agent fills the gaps with guesses, and it guesses differently every time you regenerate. The reason two people using the same tool get wildly different results is not skill with the tool. It is how much they decided before they pressed go.
A builder in r/ClaudeAI put the working version of this better than any tutorial:
> "For me the line is whether the human is still making the product/architecture calls. Vibe coding is 'make something and hope'. Agentic engineering is more like: write a spec, constrain the files, run tests, review the diff, then let the agent do the boring execution."
The eight questions below are how you make the product and architecture calls before the agent does. Answer them and you get to hand off the boring execution with confidence. Skip them and the agent makes those calls for you, silently, in code you now have to reverse-engineer.
## The eight questions
You do not need a document. You need answers, in plain English, that you could say out loud in two minutes. Most of these are decisions only you can make, because they are about what the product is, not how the code works.
**1. Who is the user, and what one thing are they here to do?** Not the feature list. The single job. "A signed-in freelancer logs their hours against a client." If you can't name the one job, the agent will build for a user it imagined, and that user is always more generic than yours.
**2. What is the smallest version that is actually useful?** The agent will happily scope up. It will add settings pages, role systems, and a dashboard you didn't ask for, because more looks like better. Decide the first useful slice yourself. Everything past it is a later loop, not this one.
**3. What has to be true for this to count as done?** This is the one everyone skips and the one that matters most. Write the conditions in behavior, not vibes. "The streak count survives a page refresh." "A signed-out user hitting /dashboard lands on /login." These are your acceptance criteria, and they are the only thing that lets you check the result instead of squinting at it.
**4. Who is allowed to do what?** Auth is not a feature you add later. It is a decision that shapes every screen. Who can see this data, who can edit it, who is locked out. The agent will build a working app with no real access control and it will look fine in the demo, because in the demo you are the only user.
**5. What is the data, and what are its rules?** Name the core things your app stores and how they relate. A habit has a name, a frequency, and a list of completion dates. A completion belongs to exactly one habit. Get this wrong and every feature built on top inherits the mistake, which is why "it worked until my data got real" is such a common wall.
**6. What happens when it goes wrong?** The empty state before any data exists. The duplicate submission. The expired session. The network that drops mid-save. Demos only ever show the happy path, so if you don't name the unhappy ones, the agent won't build them, and your users will find them for you.
**7. What are you explicitly not building?** A boundary is a gift to the agent. "No payments yet. No mobile app. No admin panel." Naming the non-goals keeps the agent from wandering into scope that quietly triples the surface area you have to trust.
**8. How will you know it works, without reading the code?** This is the question that makes the other seven real. If your answer is "I'll click around," you have no gate. If your answer is "I'll walk down the done conditions from question three and confirm each one," you have a way to trust the result you didn't write. That is the whole difference between shipping and hoping.
## Vague prompt versus answered prompt
The gap is not effort. It is specificity. Watch the same idea, unanswered and answered.
> Unanswered: "Build me a client invoicing app with login and a dashboard."
>
> Answered: "A signed-in freelancer creates an invoice for a client with line items, a due date, and a total. They see a list of their own invoices, filterable by paid or unpaid, and can mark one paid. Only the invoice's owner can see or edit it. An unpaid invoice past its due date shows as overdue. Signed-out users go to /login. Not building: payments, PDF export, multi-user teams."
The second prompt is not slower to think of. It is the same app, with the eight decisions made out loud. And every phrase in it is a place the first prompt would have handed the agent a coin to flip: who owns an invoice, what "overdue" means, whether filtering exists, where signed-out users go. The agent building the vague version isn't worse. It just had to guess, and you will spend your afternoons discovering which way it guessed.
## Where this gets hard, honestly
There is a real cost here, and ignoring it makes this advice worse. Answering eight questions feels like friction at the exact moment you are most excited to just start building. And some ideas genuinely aren't worth it. A throwaway script, a landing page you'll delete next week, a weekend experiment, planning that is wasted ceremony. The line is durability: the moment real people or real data depend on the thing, the two minutes of questions saves you the three weeks of archaeology.
The other failure mode is the opposite one, and the audience calls it out constantly. One builder described the trap as being "stuck writing md files 80% of the time instead of actually getting stuff done." That is real. If your eight answers grow into a folder of design documents you maintain by hand, you have traded a fast mess for a slow one. The answers are a paragraph, not a project. They exist to define done, then get out of the way.
## What this changes for you
If you are building in Cursor, Lovable, Claude Code, or Replit right now, here is the concrete version. Your first feature will feel great either way. The eight questions won't change that. What they change is feature three and four, when the agent is editing a system it can no longer fully see. With the questions answered and written down, there is a record of what each earlier piece was supposed to do, so the agent, and you, can tell when a change breaks something load-bearing. With nothing written down, the agent breaks behavior it never knew was load-bearing, and you inherit a bug "disguised in a way no sane human could have come up with," to borrow a line from a builder on Hacker News describing exactly this.
This is the gap BrainGrid is built to close, and to close it without the md-files-all-day tax. You describe the feature in plain English, and BrainGrid's Planning Agent asks these questions for you, the ones about users, edge cases, access, and done, the ones you'd have skipped in the rush. It turns your answers into a requirement with explicit acceptance criteria, the kind you'd get from a good [AI PRD generator](/ai-prd-generator) that actually interrogates the idea instead of formatting it. From there you build in BrainGrid's managed sandbox with a live preview, or in your own GitHub repo with Claude Code, Cursor, or Codex over MCP. The Builder Agent works against those criteria, and a feature isn't done until every one is verified with evidence. The loop is Plan, Build, Verify, Repeat. The eight questions are just the Plan step, made explicit, before the agent can guess.
## The checklist, in one line
Before your agent writes anything, decide who it is for, the smallest useful version, what counts as done, who is allowed to do what, the data and its rules, what happens when things break, what you are not building, and how you will check the result. Two minutes of answers buys you a product you can trust instead of a demo you are afraid of. If you want the fuller method, read [how to vibe code the right way](/blog/how-to-vibe-code-the-right-way), and if you are still choosing tools, start with our guide to [vibe coding tools](/vibe-coding-tools).
## FAQ
### What should I plan before building an app with AI?
Plan the product decisions the AI can't make for you: who the user is and their one core job, the smallest useful version, what has to be true for the feature to count as done, who is allowed to do what, the core data and its rules, what happens in error and empty states, what you are explicitly not building, and how you will verify the result without reading the code. These are answers in plain English, not a formal document. The build goes well or badly depending on how many of them you settled before pressing go.
### What questions should I ask before building software with AI?
Start with the eight in this post. The most important one is what counts as "done," written as checkable conditions ("a signed-out user is redirected to /login," "the total updates when a line item changes") rather than a vibe. Those conditions become the standard you check the agent's output against. Without them you can only judge the result by gut, one prompt at a time, which is how vague requirements turn into weeks of rework.
### Do I need to write a spec before using an AI coding agent?
You need answers, not necessarily a spec document. For anything durable, write a short paragraph that defines the feature and its done conditions, then let the agent build against it. For throwaway work, skip it. The trap on one side is starting with no plan and letting the agent invent your product decisions. The trap on the other side is turning planning into a folder of documents you maintain by hand. A paragraph per feature is the balance.
### Why does AI build the wrong thing even when my prompt is detailed?
Usually because the prompt is detailed about what you want and silent about the edges: access control, error states, data rules, and what "done" means. A capable agent fills every silence with a guess, and it guesses differently each time you regenerate. The fix is not a longer prompt, it is answering the specific decisions the eight questions surface, so the agent is executing your intent instead of improvising around its absence.
### How do I know if my AI-built app is actually done?
Check it against the done conditions you defined before the build, one by one, rather than clicking around and calling it finished when nothing obviously breaks. "Done" for a feature is a list of behaviors that have to be true, and verification is confirming each one with evidence. If you never wrote the list, you have no way to know the app is done, only a feeling that it seems to work, which is exactly the feeling that collapses the first time a real user does something you didn't test.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that asks the questions you'd skip and turns your answers into criteria your agent builds against. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Context Rot: Why Your AI Agent Gets Dumber the Longer It Runs
Source: https://www.braingrid.ai/blog/context-rot
Published: 2026-07-10T12:00:00Z
A bigger context window is supposed to make your agent smarter. Most of the time, past a certain point, it does the opposite.
You have felt this even if you never had a name for it. The first hour with a coding agent is sharp. It reads your files, follows your conventions, ships the feature. Then the session runs long, the diff piles up, and somewhere around the fortieth message the same agent starts forgetting the function it wrote an hour ago, reintroducing a bug you already fixed, or confidently editing a file it clearly no longer remembers reading. Same model. Same prompt quality. Worse output.
That decay has a name now, and it is the most useful term in AI building this year.
## What Context Rot Actually Is
Context rot is the measurable degradation in an LLM's performance as its input context grows longer. The more you stuff into the window, the worse the model gets at using any of it.
The phrase was coined in June 2025 by a Hacker News commenter and then proven, hard, by a [Chroma research study](https://www.trychroma.com/research/context-rot) that tested eighteen models including GPT-4.1, Claude 4, and Gemini 2.5. The finding was uncomfortable and consistent: as context length increases, performance degrades across every model, not because the task got harder but because the input got longer. A model that aces a needle-in-a-haystack question at 1,000 tokens starts missing the same needle at 100,000, even though the answer is sitting right there.
Here is the part that breaks most people's mental model. A context window is not memory. It is attention, and attention is a budget. Every token you add competes with every other token for the model's finite ability to focus. Gergely Orosz, watching his own agents fail, [put the confusion plainly](https://x.com/GergelyOrosz/status/2072832511474811323):
> I'm starting to realize just how important it is to understand context sizes, context rot, context compression & similar behaviors to understand why these models often fall short. Eg why it is that you give it a large block of stuff and the model "forgets" about parts of it.
The model did not forget. It was never able to attend to all of it at once. A 200,000-token window does not mean the model reads 200,000 tokens well. It means it can hold them, and holding is not the same as using.
## Why It Hits Coding Agents Hardest
Context rot is worst exactly where AI coding agents live: long sessions, big files, and a window that fills with things the agent generated itself.
Salesforce describes the mechanism cleanly. In production agents, rot happens when newer content, [retrieved code chunks, tool outputs, and fresh conversation turns, displaces older history from the window](https://www.salesforce.com/artificial-intelligence/ai-context/context-rot/). Your carefully stated constraint from message three gets pushed toward the edge by the agent's own file reads, test logs, and thinking, until the thing you told it to never do is no longer in effective focus. This is why a coding agent reintroduces a bug you fixed twenty minutes ago. The fix is technically still in the transcript. It is just buried under the last forty tool calls, and buried is functionally gone.
There is a shape to it, too. Performance is not just worse at the end of a long context, it is worst in the *middle*. Researchers call it the lost-in-the-middle effect: models attend best to the beginning and end of their context and quietly skim the vast middle where most of your session actually lives. The r/ClaudeAI community landed on the sharpest framing of what this means in practice: [Claude Code is a context-engineering harness, and most "it got dumber" moments are context rot](https://www.reddit.com/r/ClaudeAI/comments/1u9wuaq/), not a worse model.
Compare the two sessions and the pattern is obvious.
> Fresh session: you ask for a change, the agent reads three relevant files, makes the edit, tests pass, done in one pass.
>
> Rotted session: two hours in, you ask for a similar change, the agent re-reads files it already has, misses the convention it followed an hour ago, edits the wrong module, and "fixes" a test by weakening it.
Nothing about the request got harder. The window got louder.
## Why Bigger Windows Don't Save You
The obvious fix, buy a bigger context window, is the one that does not work, and understanding why is the whole point.
If rot were a capacity problem, a million-token window would solve it. But rot is an attention problem, and attention does not scale linearly with capacity. Every model tested in the Chroma study degraded well before it ran out of room. The window was not full. The model was already distracted. Doubling the size of a room does not help someone who cannot focus on the person in front of them, it just adds more people to ignore.
The standard mitigations all help and all share one ceiling. You can prune the context, dropping stale turns to keep the window lean. You can use retrieval to inject only the relevant chunk instead of the whole codebase. You can start a fresh session when things get muddy. These are the Compress and Select moves from [the four pillars of context engineering](/blog/four-pillars-of-context-engineering), and you should use them. But every one of them works by managing what is *inside* the window. They are all defense against a window that is always, structurally, going to rot as it fills.
Which points at the actual fix, and it is not a window-management trick.
## The Fix Is Keeping the Truth Outside the Window
The durable answer to context rot is to stop trusting the window to remember what your product is supposed to be. Keep the source of truth outside the conversation, in a record the agent re-reads instead of a constraint it is slowly forgetting.
Think about what actually rots. It is not your code, your tests, or your git history, those live on disk and do not decay. What rots is the *intent*: the constraint you stated in chat, the convention you explained once, the "never touch the auth flow" you mentioned forty messages ago. That intent lived only in the context window, so when the window rotted, the intent rotted with it. The agent did not lose your codebase. It lost the plan for your codebase, because the plan was never anywhere but the chat. This is the same mechanism behind [why your agent keeps breaking things that already worked](/blog/why-ai-keeps-breaking-things-that-worked): the constraint that would have stopped it scrolled out of focus.
The primitive version of externalizing intent is a file the agent reloads every session, a CLAUDE.md or the [state file pattern](/blog/claude-code-memory-state-file-pattern) that carries durable facts across sessions. That helps, and it is worth doing. But a flat file is still a file you maintain by hand, and it drifts. The stronger version ties the record to the work itself.
This is exactly the gap BrainGrid is built to close. In BrainGrid, you describe what you want and the Planning Agent turns it into a requirement with explicit acceptance criteria, a durable record of what this feature means and when it is done. That record does not live in the agent's rotting window. It lives in the product, alongside every other spec and decision, and the Builder Agent, whether it runs in BrainGrid's cloud sandbox or in your own GitHub repo with Claude Code, Cursor, or Codex over MCP, builds against that record and gets checked against it. When the session gets long and the agent's own memory of the goal has decayed, the goal is still written down where it cannot rot. Every session starts from the same source of truth instead of from zero. The agent forgets. The record does not.
The reframe is the whole thing: context rot is not a reason to distrust AI agents, it is a reason to stop keeping your product's definition inside a conversation that was always going to degrade.
## What This Means If You Build With Agents Today
If you run long coding sessions with Claude Code, Cursor, or any agent, this changes how you should work starting now. Stop treating a long-running chat as your product's memory. The moment your intent matters, and it matters the instant the app is more than a throwaway, get it out of the transcript and into a record the agent reloads: a spec, acceptance criteria, a written definition of what "done" means for this feature.
The trade-off is real and worth stating. Writing intent down before you build costs you a few minutes up front, and if you are prototyping something disposable, that cost is not worth paying, just vibe it and throw it away. But the second the thing has to keep working across sessions, the few minutes you spend externalizing intent is the cheapest insurance you will buy, because the alternative is discovering at message sixty that the agent has been building against a goal it can no longer remember.
Context rot is not going away. Windows will get bigger, attention will still be finite, and the sessions where you actually build real things will always run long enough to rot. Keeping the source of truth out of the rotting window is the whole point of [context engineering](/context-engineering). The builders who stay ahead of rot are not the ones with the biggest window. They are the ones whose source of truth was never in the window to begin with.
## FAQ
### What is context rot?
Context rot is the measurable decline in an AI model's performance as its input context grows longer. Past a certain length, adding more tokens makes the model worse at using any of them, because a context window is a finite attention budget, not unlimited memory. It shows up as an agent forgetting earlier instructions, missing details it was given, or contradicting itself the longer a session runs.
### What causes context rot?
Two things. First, attention dilution: every token in the window competes for the model's finite focus, so a longer context means each individual instruction gets less attention. Second, displacement: in a running agent session, new content like file reads, tool outputs, and fresh messages pushes your earlier constraints toward the edges of the window, where they stop being attended to. There is also a lost-in-the-middle effect, where models focus on the start and end of their context and skim the middle.
### How do you prevent context rot?
The common techniques manage what is inside the window: prune stale turns to keep it lean, use retrieval to inject only the relevant code instead of the whole codebase, and start fresh sessions when things get muddy. These help but share a ceiling, because the window always rots as it fills. The durable fix is to keep your source of truth outside the conversation, as a spec or acceptance criteria the agent re-reads, so the definition of what you are building cannot decay along with the chat.
### Why does an AI coding agent forget files it already read?
Because reading a file loads it into the context window, and as the session grows, that file's contents get displaced by newer tool outputs and pushed into the low-attention middle of the window. The information is technically still in the context, but the model can no longer effectively attend to it, so it behaves as if it forgot, and often re-reads the same file rather than trusting the copy already in context.
*[BrainGrid](https://braingrid.ai) is the plan-first app builder that keeps your product's definition in a durable record the agent re-reads, not a chat window that rots. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Agentic Engineering vs Vibe Coding: The Line Is the Plan, Not the Vocabulary
Source: https://www.braingrid.ai/blog/agentic-engineering-vs-vibe-coding
Published: 2026-07-09T12:00:00Z
The internet has spent six months arguing about which label to put on people who build software with AI, and it has the whole fight backwards. The words are not the point. Two builders can open the same editor, run the same coding agent, and type nearly the same prompt, and one of them is doing careful engineering while the other is gambling. The tool did not decide which is which. Something that happened before either of them hit enter did.
That something is the entire difference between agentic engineering and vibe coding. Not the model, not the IDE, not whether you call yourself an engineer or a vibe coder on your bio. The line is whether a reviewable plan and a way to check the result existed before the agent started writing. Everything else is vocabulary.
## The definition builders keep reaching for
Watch how the audience actually talks about this and the pattern is unmistakable. In a recent r/ClaudeAI thread titled ["The difference between agentic engineering and vibe coding?"](https://www.reddit.com/r/ClaudeAI/comments/1uoxrjw/), the top answer lands on a definition nobody handed them:
> For me the line is whether the human is still making the product/architecture calls. Vibe coding is "make something and hope." Agentic engineering is more like: write a spec, constrain the files, run tests, review the diff, then let the agent do the boring execution.
Read that again, because it is not one person's opinion. It is a workflow, stated as a sequence: write a spec, set the boundaries, run the checks, look at what came back, then hand the tedious part to the machine. Another commenter in the same thread put the boundary even more bluntly: "vibe coding is when you dont read the code. if you're bothering to read the code it's not vibe coding anymore." A third described their real job now as "converting agent behavior into a combination of cheap code, and strict gates that agent output must satisfy."
Simon Willison, who has been careful with these terms since the beginning, [drew the same line](https://simonwillison.net/2026/May/6/vibe-coding-and-agentic-engineering/): vibe coding is "a very different beast from responsible use of AI to write code, which I've since started to call agentic engineering." And on Hacker News, a commenter compressed the whole thing into [one sentence](https://news.ycombinator.com/item?id=48037128): "Once you've done the work to deterministically define your system, you're not vibe coding anymore. You're officially an engineer who cares."
Notice what none of these definitions mention. Not the specific tool. Not the model version. Not a certification. Every one of them points at the same thing: was there a defined target before the agent ran, and did a human stay in charge of judging the output against it.
## Why the tool cannot be the dividing line
The tempting shortcut is to say vibe coding is what non-engineers do in Lovable and agentic engineering is what real engineers do in Claude Code. That framing shows up constantly, and it is wrong in both directions.
You can vibe code in Claude Code. Fire off "build me a dashboard," accept whatever comes back, never open the diff, ship it. That is vibe coding no matter how professional the tool is. And you can do genuine [agentic engineering](/agentic-engineering) through a copy-paste workflow into a browser-based builder, if you wrote down what you wanted, set the constraints, and checked the result against them before you called it done. The tool raises or lowers the ceiling on what is possible. It does not decide whether you engaged your judgment.
Here is the hypothesis this whole post rests on, and it is testable: **the more autonomous the agent becomes, the more the plan and the gate matter, not less.** A weak assistant that suggests one line at a time cannot get very far off track before you notice. An agent that reads forty files, writes a dozen, runs commands, and opens a pull request while you get coffee can travel an enormous distance in the wrong direction before anyone looks. Autonomy multiplies whatever you pointed it at. If you pointed it at a vague hope, it multiplies the vagueness.
That is why "vibe coding vs agentic engineering" is not a debate that resolves as models improve. It gets sharper. A better model executes your intent more faithfully and further, which means a fuzzy intent produces a larger, more convincing, more expensive mess. The skill that scales is not prompting. It is defining the target clearly enough that faithful execution is a good thing.
## Same prompt, two outcomes
Make it concrete. Two builders want the same feature.
Builder one types: "Add user authentication to my app." The agent picks a library, invents a session model, scatters auth checks across a few routes, and returns something that logs a test user in. It looks done. Whether it is done, whether unauthenticated users are actually blocked from every protected route, whether the token expires, whether the password reset path exists, is unknown, because nobody said what done meant. This is make-something-and-hope. The demo works. The demo is not the product.
Builder two writes it down first: authenticated users can access the dashboard; unauthenticated requests to any protected route redirect to /login; sessions expire after 24 hours; passwords are hashed, never stored in plaintext; a failed login shows an error without revealing whether the email exists. Then the agent builds against that list, and each item is something you can check. The agent did the same amount of typing. The difference is that one build can be verified and the other can only be hoped over.
That list is not bureaucracy. It is the thing that turns "the agent seems to have added login" into "these six behaviors are true and I confirmed them." It is also, not coincidentally, exactly what the r/ClaudeAI definition was describing: the spec you write and the gate the output has to satisfy. This is the core of [spec-driven development](/blog/spec-driven-development), and it is the same discipline whether you write the criteria by hand or generate them.
## Where BrainGrid fits
This is the workflow BrainGrid is built to run, so you do not have to assemble it out of loose habits every time. You describe the idea, "add authentication to my app," and the Planning Agent turns it into a requirement with acceptance criteria: the specific, checkable behaviors that define done. That is the "write a spec" step, produced as a reviewable artifact you actually read and correct, not a prompt you fire and forget.
Then the Builder Agent implements against those criteria, either in a managed sandbox with a live preview or directly in your own GitHub repo through MCP with Claude Code, Cursor, or Codex. The part that makes it engineering rather than hoping is the last step: a feature is not done until every acceptance criterion is verified with evidence. The plan existed before the agent ran, and the gate exists after. The vocabulary you use for yourself is beside the point. The plan and the gate are the point, and they are the product.
## The honest limit
Structure is not a cheat code that makes the complexity wall disappear. Even builders doing disciplined, spec-driven, test-covered agentic work hit a ceiling. One heavy autonomous builder in r/AINativeAgencies, describing millions of lines of agent-written code, was candid about it: "Things like having spec driven development and TDD, coverage gates, solid CI... get you a long way. There's still a complexity ceiling though... things get way worse after 50k lines of code in a single repo." The agent, he added, "constantly forgets parts or implements incorrectly."
A plan does not repeal that wall. What it does is push it out and, more importantly, make it visible when you hit it, because you have criteria the output is failing against instead of a vague sense that things feel off. Vibe coding hides the wall until you are already through it and standing in the rubble. Agentic engineering does not remove the wall. It gives you a way to see it coming.
## FAQ
### What is the difference between agentic engineering and vibe coding?
Vibe coding means prompting an AI to build something and accepting the output without reading the code or defining what "correct" means first. Agentic engineering means writing a spec, setting constraints, running checks, and reviewing the diff, so a human stays in charge of the product and architecture decisions while the agent handles execution. The dividing line is not the tool. It is whether a reviewable plan and a way to verify the result existed before the agent ran.
### Is agentic engineering just vibe coding with extra steps?
No. The "extra steps," a written spec and a verification gate, are what change the outcome from unpredictable to checkable. Without them, more agent autonomy just produces a bigger, more convincing mess faster. The steps are not overhead on top of vibe coding; they are the difference between building something you can trust and hoping something works.
### Can you do agentic engineering with any AI coding tool?
Yes. Agentic engineering is a practice, not a product. You can do it in Claude Code, Cursor, Codex, or through a copy-paste workflow into a browser-based builder, as long as you define the target before the agent runs and check the result against it after. Likewise, you can vibe code in the most professional tool available by skipping those steps. The tool sets the ceiling; your judgment sets whether it is engineering.
### Why does the plan matter more as AI models get better?
Because a more capable model executes your intent more faithfully and travels further on its own before you check. That is great when the intent is clear and dangerous when it is vague, since faithful execution of a fuzzy goal produces a larger and more expensive mistake. As autonomy grows, the value shifts from writing good prompts to defining the target precisely, which is the core of agentic engineering.
### Is vibe coding bad?
No, it is a great on-ramp. Vibe coding is how a lot of people discover they can build at all, and it is fine for throwaway prototypes and side projects where nobody depends on the result. We have made [the honest case for it](/blog/is-vibe-coding-good) before. It stops being fine the moment the app starts to matter, because "make something and hope" is not a foundation you can maintain, extend, or trust. That is the point where you move from hoping to a plan you can verify against, and where [agentic coding](/blog/agentic-coding) picks up.
The words will keep shifting. People will invent new labels for "I use AI heavily but I read the diff," and the labels will not matter. The question that will still matter in a year is the same one it is now: before your agent wrote a line, did you know what done looked like, and can you prove the result meets it.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into a reviewable plan with acceptance criteria, so the agent builds against a target you can verify instead of a hope. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The Best Code Review Skill Is the One You Never Have to Run
Source: https://www.braingrid.ai/blog/best-code-review-skill-review-against-a-standard
Published: 2026-07-08T12:00:00Z
The fastest-growing search in AI coding right now is people looking for a code review skill to install. The best one is the one you never have to run.
That sounds like a dodge, but it is the whole argument. A code review skill is a file you drop into Claude Code or Codex that tells the agent how to critique a diff: check correctness, flag security anti-patterns, look at test coverage, rate readability. They are genuinely useful, and the good ones are getting shared fast. But every one of them reviews the code against a general standard of what good code looks like. None of them can tell you the thing you actually need to know, which is whether the code does what you meant it to do. That question was never in the skill, because your intent was never in the skill.
## The review skill gold rush is real, and it is mostly good
Look at what ranks when you search "code review skills" today and you see the shift in real time. The top result is [obra's `receiving-code-review` skill](https://github.com/obra/superpowers/blob/main/skills/receiving-code-review/SKILL.md), whose core principle is blunt: verify before implementing, ask before assuming, technical correctness over emotional performance. Right below it, [Addy Osmani's agent-skills repo](https://github.com/addyosmani/agent-skills/blob/main/skills/code-review-and-quality/SKILL.md) publishes a five-axis review, correctness, readability, architecture, security, performance, as a reusable rubric any agent can run. [Anthropic's own Code Review docs](https://code.claude.com/docs/en/code-review) now analyze your pull requests and post findings as inline comments. There is even a two-layer review skill in the Anthropic skills discussions with project-aware checklists.
This is a good development. A shared, structured rubric beats an ad hoc glance every time, and handing your agent a consistent review procedure is strictly better than hoping it critiques carefully on its own. The [community answer that keeps surfacing in the r/ClaudeCode threads](https://www.reddit.com/r/ClaudeCode/comments/1sqxmb9/) gets the nuance right:
> The best code review skill is the one you build for your own repo. Generic ones catch style and obvious bugs but miss the stuff that actually matters.
That instinct is correct, and it points at exactly the gap. The reason a generic skill misses the stuff that matters is not that it was written badly. It is that the stuff that matters lives outside the code entirely.
## What a review skill can see, and what it can't
A code review skill reads a diff and evaluates it against patterns of good engineering. It can tell you this function is doing too much, this query is unindexed, this endpoint has no auth guard, this branch is untested. That is real value, and it is the kind of value that scales, because good-engineering patterns are general. They apply to any codebase.
Here is what the same skill cannot do. It cannot tell you that the checkout flow was supposed to apply the discount before tax, not after. It cannot tell you that "notify the user" was supposed to mean an email and an in-app toast, not just the toast. It cannot tell you that the report was supposed to exclude cancelled orders. Those are not code-quality facts. They are product facts, and they are not in the diff. The code can be clean, well-tested, correctly typed, secure, and completely wrong, and a review skill checking the code against a standard of good code will pass it, because by every standard it can see, it is fine.
This is the distinction that gets lost in the rush to install a rubric. There are two questions a review answers, and they are not the same question:
> Is this built well? A review skill can answer this by reading the code.
>
> Is this the right thing, built correctly? Only your intent can answer this, and your intent is not in the code.
The first question is about the how. The second is about the what. Review skills are getting very good at the first and cannot touch the second, and the second is the one that ships broken features while every automated check stays green.
## Where the durable standard actually lives
If the review skill can only check the code against generic quality, then the standard for "did this do the right thing" has to come from somewhere else. It comes from what you decided the feature should do, written down before the agent built it. That written-down decision has a name in every mature engineering process: [acceptance criteria](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify). They are the per-feature definition of what "correct" means for this specific change, and they are the only thing that lets any reviewer, human or agent, check the build against your actual intent instead of against a general notion of tidy code.
Consider the difference concretely.
> Generic review skill: "This function looks correct, is well-typed, and has test coverage. Approved."
>
> Review against a standard: "Criterion 3 says a cancelled order must not appear in the revenue total. The test only covers active orders. This is not done until there is a test asserting a cancelled order is excluded, and it passes."
The second review is not smarter about code. It is anchored to a target the first review never had. And notice what it produces: not a subjective opinion you have to adjudicate, but a checkable claim with a pass-or-fail answer. That is the review you do not have to run by eye, because the criterion either has evidence behind it or it does not.
## Why this matters more now, not less
The reflex is to think that as agents get better at reviewing code, this problem shrinks. It grows. The better the review skill gets at catching style issues and security holes, the more confident the green checkmark looks, and the easier it becomes to mistake "passed the review skill" for "does what I wanted." A rubric that catches nine kinds of code smell and cannot see intent is more dangerous than no rubric, because it manufactures a feeling of thoroughness around the one gap it structurally cannot close.
There is a real trade-off here worth naming. Writing acceptance criteria before the build is work, and it is work you do when there is nothing to look at yet, which is exactly when it feels least urgent. Installing a review skill takes thirty seconds and feels productive immediately. The review skill is the easy purchase; the standard is the thing that actually protects you, and it costs you upfront attention instead of a download. Most people buy the easy thing. That is precisely why the durable advantage sits with the builders who do the harder one.
If you are shipping features with Claude Code, Cursor, or Codex right now, the practical implication is direct. Keep the review skill, it is a fine second line of defense for catching the code-quality issues a spec would not mention. But stop treating it as the standard. The standard is the set of acceptance criteria you wrote before the agent started, and the review that matters is the one that checks the diff against those, not against a general idea of good code.
## The review you don't have to run
This is the exact seam [BrainGrid](https://braingrid.ai) is built to close, and it sits one step before any review skill runs. You describe the feature in plain language, and the Planning Agent turns it into a requirement with explicit, testable acceptance criteria, the questions you did not think to ask, the edge cases you did not name, pinned down as the definition of correct for this change. Those criteria are not a document you file away. They become the standard the build is checked against.
Then [the loop](/loop) closes on them. Whether the Builder Agent works in BrainGrid Cloud or you hand the plan to your own agent in your GitHub repo over MCP, the feature is not done until every criterion is verified with evidence, not "the code looks good," but "criterion 3 has a passing test that proves a cancelled order is excluded." That is the review nobody has to run by eye, because the standard was set before the build and the evidence is checked against it. As we argued in [the verification gap](/blog/verification-gap), code review tells you the code is well-written; verification tells you it does what you intended. A review skill is firmly on the first side of that line.
Strip away the skills and the agents and the argument is older than any of them. Reviewing code against a general standard of quality has always been necessary and never sufficient, because a reviewer who does not know what the feature was supposed to do can only tell you it was built tidily, not that it was built right. What changed is that the reviewer is now often an agent running a rubric, and the intent it is missing is now often nowhere written down at all. Write the standard first, and the best code review skill becomes the one you set up front and never have to run in a panic later.
## FAQ
### What is a code review skill?
A code review skill is a reusable instruction file you install into an AI coding agent like Claude Code or Codex that tells it how to critique a code change. It typically defines a rubric, common examples include correctness, readability, architecture, security, and performance, so the agent reviews a diff systematically and consistently instead of critiquing ad hoc. Popular ones are published in repos like Addy Osmani's agent-skills and obra's superpowers. They are useful for catching code-quality issues, but they evaluate the code against a general standard of good engineering, not against what your specific feature was supposed to do.
### What is the best code review skill?
The most useful installable skills give the agent a clear, consistent rubric, Addy Osmani's five-axis review (correctness, readability, architecture, security, performance) is a well-regarded example, and Anthropic's built-in Code Review posts findings directly on your pull requests. But the best review, the one that catches shipped-but-wrong features, is not a skill you run after the build. It is the acceptance criteria you write before it: the per-feature definition of what correct means for this change. A generic skill checks whether the code is good; your criteria check whether it does what you intended, which is the failure a rubric structurally cannot see.
### How do I improve my code review skills?
Two moves compound. First, learn to read a diff for the general engineering issues a good rubric covers: correctness, edge cases, security, test coverage, and unnecessary complexity. A shared skill or checklist accelerates this and keeps you consistent. Second, and more important as agents write more of the code, get in the habit of defining what "done" means before the work starts, as specific, testable acceptance criteria, and reviewing every change against those rather than against a vague sense of quality. The reviewers who add the most value now are the ones checking intent, not just style.
### Can AI do code review?
Yes, and it is increasingly good at the part that generalizes: spotting anti-patterns, missing tests, security holes, and readability problems by comparing a diff to patterns of good engineering. What AI code review cannot do on its own is judge whether the change matches your intent, because your intent is not in the code. It will happily approve a clean, well-tested implementation of the wrong behavior. To close that gap you have to give the review a standard to check against, acceptance criteria written before the build, so the agent verifies the diff against what the feature was supposed to do, not just against generic quality.
### Is code review still necessary with AI agents?
More than ever, but the useful form of it changes. Line-by-line style review is increasingly handled by review skills the agent runs itself. The review only humans and a well-specified standard can do, confirming the change does what you actually meant, becomes the high-value work. As agents produce more code faster, the bottleneck moves from writing to verifying, and the way to keep that verification fast instead of overwhelming is to define acceptance criteria up front so most of the review is checking evidence against a standard rather than reading everything by eye.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that turns your idea into a requirement with acceptance criteria, then verifies every change against them, so the review that matters is set before the build instead of run after it. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is an API Endpoint? The Door Your Agent Built Into Your App
Source: https://www.braingrid.ai/blog/what-is-an-api-endpoint
Published: 2026-07-07T12:00:00Z
Your coding agent said it "added an endpoint," you saw the feature work, and you moved on. That endpoint is now a door into your app that anyone on the internet can walk up to and knock on, and you have no idea what happens when they do.
That gap, between "the feature works" and "I know who is allowed through this door," is where a lot of AI-built apps quietly go wrong. Not because the agent wrote bad code. Because the most important thing about an endpoint, who can call it and what it hands back, is a decision, and nobody made that decision out loud. So the agent made it for you, in favor of whatever got the demo working fastest.
If you have been building with Cursor, Claude Code, Lovable, or Replit and you have never been quite sure what "an API endpoint" actually is, this post is for you. The hypothesis is simple: **an API endpoint is a public door into your app, and the behavior of that door, who is allowed through and what they get, is an acceptance criterion you specify, not a default you inherit.**
## What an API endpoint actually is
Start with the plain-language version, the one the docs bury under jargon.
An **API** is the set of ways other programs are allowed to talk to your app. An **endpoint** is one specific door in that set: a single URL, paired with an action, that does one job. When your frontend loads a user's orders, it is knocking on a door like `GET /api/orders`. When someone signs up, the app knocks on `POST /api/users`. Each of those is an endpoint. The developer community has a good analogy for the relationship. As one widely shared explainer [put it](https://apidog.com/blog/apis-vs-endpoints/):
> You can think of an API as a building, and endpoints are the doors to enter that building. Each endpoint corresponds to a specific function or data point in the API.
That building-and-doors picture is the whole mental model, and it is worth holding onto, because it makes the security question obvious in a way the word "endpoint" never does. A building can have a front door with a receptionist who checks your badge, and it can have a loading dock around the back that someone left propped open. Both are doors. Both let you into the building. Only one of them is watching who comes through.
Here is the part that surprises non-technical builders. When your agent "adds an endpoint," it is adding a door to the public building that is the internet. By default, that door is reachable by anyone who knows the URL, not just the polished button in your app that calls it. Your login screen guards the front of the app. It does nothing for the loading dock your agent added at `POST /api/admin/delete-user` unless someone specifically decided that door needs a badge check. IBM's [definition](https://www.ibm.com/think/topics/api-endpoint) is precise about what an endpoint is, a digital location where an API receives requests, usually a URL. What the definition leaves out is the thing that matters most to you: a location where an API receives requests is, by default, a location where it receives requests from anyone.
## Why AI builders trip over this specifically
Search "what is an API endpoint" and you get IBM, Postman, Cloudflare, Contentful, GeeksforGeeks, and a ten-year-old Reddit thread. Every one of them explains the mechanics correctly. None of them is written for the person whose situation is new: someone who did not write the endpoint, cannot fully read it, and only knows it exists because the agent mentioned it in passing.
That is the actual problem. In the old world, the person who created an endpoint understood it, because creating it required understanding it. You had to know what a route was, what an HTTP method was, and what "authenticated" meant, or the code would not run. The knowledge and the artifact came together. AI severed that link. Now the endpoint can exist, and work, in the hands of someone who has never heard the word "route." The door gets built. The understanding of who should be allowed through it does not come automatically bundled in.
Andrej Karpathy [described the general version of this](https://x.com/karpathy/status/1886192184808149383) when he coined vibe coding: you "fully give in to the vibes" and "forget that the code even exists." Forgetting the code exists is fine for a weekend toy. The trouble is that the code includes doors, and a door you forgot about is a door nobody is watching. The agent will happily generate an endpoint that returns every user's data, or accepts a request from anyone, or triggers a destructive action without checking who asked, because the fastest path to a working feature is a door with no lock, and you never said the door needed one.
Consider the difference between two ways of asking for the same feature.
> Vague: "Add an endpoint to update a user's profile."
> Specified: "Add a `PATCH /api/users/:id` endpoint that updates a user's profile. Only the logged-in user may update their own profile, never another user's. A request from user A trying to update user B's profile must be rejected with a 403, not silently allowed. Requests with no valid session must be rejected with a 401."
Same door. The first version leaves the lock, and the identity check, and the failure behavior entirely up to the agent's default, which is usually "make it work in the demo." The second version turns the door's security from an invisible assumption into a written rule you can test. And you can test it without reading a single line of the code behind the door: log in as user A, try to change user B's profile, and confirm you get rejected. That is a check anyone can run. "Is the authorization logic correct?" is not.
## The reframe: an endpoint's behavior is a criterion, not a default
This is the same move we made when we wrote about [row-level security](https://braingrid.ai/blog/what-is-row-level-security-for-vibe-coders): the hole that keeps showing up in AI-built apps is not a coding mistake, it is an unspecified rule. A missing auth check on an endpoint is exactly that. The endpoint's job is not just "return the profile." Its full job is "return the profile, but only to someone allowed to see it, and reject everyone else with a clear failure." The second half of that sentence is the part that never gets written down, so the agent ships the first half and the door hangs open.
Reframing it this way changes what you are responsible for. You are not responsible for writing the auth code; the agent can do that. You are responsible for stating the rule the door must obey, and then verifying the door obeys it. Every endpoint your app exposes has four questions attached to it, and every one of them is a decision you can make in plain language:
Who is allowed to call this door, anyone or only a logged-in user? Whose data can they touch, only their own or everyone's? What is this door allowed to do, read something harmless or delete something permanent? And when someone who should not be allowed knocks, what happens, a clean rejection or a silent success? Answer those four for each endpoint that handles real data, and you have written the acceptance criteria for the most dangerous part of your app, the part that faces the open internet.
There is a real trade-off worth naming, because pretending otherwise would be dishonest. Not every endpoint needs a fortress. A public endpoint that returns your marketing site's blog posts is supposed to be open to everyone; adding an auth check there would be wasted work and a worse product. The skill is not "lock every door." It is knowing which doors lead to a user's private data or a destructive action, and specifying those. The blog-post door can stay open. The delete-account door cannot. Telling them apart is judgment, and judgment is exactly the part AI does not do for you.
## Where this fits in the loop
This is the gap [BrainGrid](https://braingrid.ai/vibe-coding-tools) is built to close. You describe the feature in plain language, and the Planning Agent turns it into a requirement with explicit acceptance criteria, including the ones you would otherwise leave in your head: which endpoints this feature adds, who is allowed to call each one, whose data they can reach, and what happens when an unauthorized request arrives. "Only the profile's owner can update it; anyone else gets a 403" becomes part of the standard the Builder Agent builds against, whether that build runs in BrainGrid Cloud or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP.
That is the loop: Plan the door's rules along with the feature, Build against them, Verify each one with evidence, Repeat. An endpoint that leaves the door open does not quietly pass, because "unauthorized requests are rejected" is written down as a criterion, and a feature is not done until every criterion is verified with evidence. Code review tells you the code behind the door is well-written. Verification tells you the door actually rejects the people it should. Those are different questions, and for an endpoint facing the internet, only the second one keeps your users safe.
## What this means if you are building right now
If your agent added an endpoint this week, do one thing before you ship: name every door the feature opened, and for each one, answer whether it touches private data or does something you cannot undo. For those doors, write the rule down as a criterion, "only the owner can call this, everyone else gets rejected," and verify it the only way that counts. Log in as one user, try to reach another user's data or trigger the action as someone who should not be allowed, and confirm the door slams shut. If it does not, you found the open loading dock before an attacker did.
The uncomfortable truth underneath this is the same one that runs through every honest conversation about building with AI. The agent is not making your security decisions badly. It is making them silently, in favor of whatever demos fastest, every time you leave them out of the spec. An open endpoint is not a mysterious bug in code you cannot read. It is a door whose rules you never wrote. Write the rules, make them criteria, and check them. For the mechanics of reviewing what your agent ships, we wrote about [reviewing AI code as a non-engineer](https://braingrid.ai/blog/what-is-a-pull-request-non-engineer-guide), and about [how to write acceptance criteria an AI agent can actually verify](https://braingrid.ai/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
## FAQ
### What is an API endpoint, in simple terms?
An API endpoint is a single URL, paired with an action, where your app receives a specific kind of request. If your API is a building, each endpoint is one door into it, and each door does one job: `GET /api/orders` returns a user's orders, `POST /api/users` creates a new user. Your app's frontend calls these endpoints to load and save data. The important part for a builder is that an endpoint is a public door on the internet by default, reachable by anyone who knows the URL, not just by the buttons inside your app.
### What is an API endpoint example?
A common example is `GET /api/users/123`, an endpoint that returns the profile for the user with ID 123. The `GET` part is the action (read something), and `/api/users/123` is the address (the door). Other everyday examples: `POST /api/login` to sign in, `POST /api/orders` to place an order, `DELETE /api/posts/45` to remove a post. Each combination of an action and an address is a separate endpoint with its own job, and each one needs its own answer to the question "who is allowed to call this?"
### What is the difference between an API and an endpoint?
An API is the whole set of rules for how programs can talk to your app; an endpoint is one specific door within that set. Think of the API as a building and the endpoints as the individual doors, each leading to one function or piece of data. You do not "call an API" so much as call one of its endpoints. The distinction matters for security because you do not secure "the API" in one move; you decide, door by door, which endpoints are open to everyone and which require a logged-in, authorized user.
### What is the difference between an API key and an endpoint?
An endpoint is the door (the URL you send a request to); an API key is one kind of badge you might have to show at the door. The endpoint is the location, the API key is a credential that identifies who is calling. An API key typically identifies which application or project is making the request, which is different from authenticating an individual user (that is usually a login session or token). A door can require a key, a user login, both, or nothing, and choosing which applies to each endpoint is the security decision you should specify rather than inherit from a default.
### How do I find the API endpoints in my app?
If your app was built by an AI agent, the endpoints usually live in a folder like `app/api`, `pages/api`, `routes`, or `server`, and each file or route there is a door. You can also open your browser's developer tools, go to the Network tab, use the app, and watch the requests fire, each one is hitting an endpoint. But finding them is only step one. The step that protects your users is going door by door and asking who is allowed to call each one and whose data it touches, then writing that answer down as a criterion your build gets verified against.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into a requirement with acceptance criteria, including who is allowed through each endpoint your agent builds, so your app ships with locked doors instead of open ones. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is Row-Level Security? The Auth Hole in Your Vibe-Coded App That Isn't a Code Bug
Source: https://www.braingrid.ai/blog/what-is-row-level-security-for-vibe-coders
Published: 2026-07-06T12:00:00Z
Your app has a login screen, so you assumed it was secure. That login screen is the reason you never checked whether user B can read user A's data.
This is the most common way a vibe-coded app leaks. Not a dramatic exploit. Not a clever attacker. Just a database table that, by default, hands every row to anyone who asks, while a polished login screen out front convinces you the door is locked. The lock is on the front door. The filing cabinet inside is wide open, and every logged-in user has a key to all of it.
The fix has a name that sounds like something only a database administrator should care about: row-level security, or RLS. It is not. If you built anything on Supabase, Postgres, or a similar backend without knowing what an RLS policy is, this is the single most important security concept you are missing. And the reason it keeps getting missed is not that it is hard. It is that nobody told the agent to turn it on, because nobody wrote down that each user should only see their own rows. The hypothesis of this post is simple: **a missing RLS policy is not a bug the AI wrote wrong, it is an access rule you never specified, and the durable fix is writing that rule down as a criterion the build gets checked against.**
## What row-level security actually is
Picture your database table as a shared spreadsheet. You have an `orders` table, and every row has a `user_id` column saying who it belongs to. Without row-level security, that spreadsheet has one rule: if you can open it, you can read every row. All of them. Yours, mine, and every other customer's.
Row-level security changes that one rule. It is a policy you attach directly to the table that says, in effect, "a user can only see the rows where `user_id` matches their own." The database itself enforces it, on every single query, automatically. As one engineer [put it plainly on LinkedIn](https://www.linkedin.com/posts/christophernorthfield_quick-one-on-postgres-row-level-security-activity-7470366830826795008-xQCu):
> Normally if you can read a table, you can read every row in it. RLS changes that. You stick a rule on the table and Postgres does the filtering for you per query based on whoever's asking.
That last part is what makes it powerful and what makes its absence dangerous. The filtering happens at the database layer, below your application code, below your API, below the login screen. It does not matter how the request arrives. A user hitting your app, a script hitting your API directly, a third-party tool with a stolen token: the database applies the same policy to all of them. Turn RLS off, and you are trusting every layer above the database to remember to filter by user, every single time, forever. Turn it on, and the database refuses to hand over rows that are not yours, no matter who forgot what.
Here is the surprise most vibe coders hit. On Supabase, a brand-new table has RLS **enabled but with no policies**, which means it denies everything until you write a rule, but the moment you flip a table to public or attach a permissive policy to make your app "just work," you can accidentally open it to the entire internet. The failure is rarely that a hacker broke your encryption. It is that the table was configured to trust anyone, and the app looked fine in the demo because you were the only user, so you never saw anyone else's data leak into your view. There was only your data to see.
## Why this hole is the one that shows up every time
Search "vibe coding security" and every vendor page and AI Overview lists the same top offender: databases like Supabase deployed without row-level security policies. It is not a coincidence that it ranks first. When an engineering manager [reviewed 25 vibe-coded apps](https://www.facebook.com/groups/claudeaicommunity/posts/1303845358449295/), the same handful of holes appeared in all of them, and missing RLS was near the top of the list every time. On r/vibecoding, the recurring question is not academic. Someone asked the whole community, flatly, [how are you handling security in your vibe-coded projects today?](https://www.reddit.com/r/vibecoding/comments/1uiu1c5/how_are_you_handling_security_in_your_vibecoded/) and the honest answers reveal a lot of people who just found out their filing cabinet was open.
The reason it recurs is worth sitting with, because it explains why buying a scanner will not save you. The agent building your app is optimizing for the same thing you asked for: a working demo, fast. A table with no access restrictions is the fastest path to a screen that shows data. Restricting rows to their owner is extra work the agent will happily skip if you never mention it, because skipping it makes the demo appear sooner and nothing visibly breaks while you are the only user. As one builder said in a widely shared post, most AI-generated apps are not hacked because of AI, they are hacked because basic security is skipped. Skipped, not failed. The agent did not get RLS wrong. It was never told RLS was part of the job.
## The reframe: it's an access criterion, not a code bug
Here is where it clicks, and it is the same move we made in [our post on vibe coding security](https://braingrid.ai/blog/vibe-coding-security). Missing row-level security feels like a technical bug, something gone wrong in the code that a good enough programmer would have caught. It is not. It is a decision about who is allowed to see what, and that decision was never made out loud, so the agent made it for you, silently, in favor of the demo.
Watch what happens when you make the decision explicitly.
> Vague: "Build an orders page where users can see their orders."
> Specified: "Build an orders page. Each user can see only their own orders, never another user's. Enforce this at the database with a row-level security policy on the orders table matching `user_id` to the logged-in user, not just by filtering in the app. A direct query to the database by any other user must return zero rows."
Same feature. The second version turned an invisible assumption into a written access rule. It named the enforcement layer, the database, not the UI, so the agent cannot satisfy it by hiding rows in the frontend while leaving them readable through the API. And, crucially, it gave you something you can check without reading a line of the auth code. "Log in as user A, then try to fetch user B's orders directly. Do you get zero rows?" is a test anyone can run. "Is the authorization logic correct?" is not a test a non-engineer can run. The first question is the durable one. The second is the trap.
That distinction, between a criterion you can verify and a code review you can't perform, is the whole reason this matters more now than it did five years ago. When an agent writes the code and you cannot read it, the security you can actually rely on is the security you can specify and test from the outside. RLS is a perfect example: you may not be able to audit the policy's SQL, but you can absolutely confirm that user B gets zero rows. Put yourself in the path there. That is the gate.
## Where this fits in the loop
This is exactly the gap [BrainGrid](https://braingrid.ai/vibe-coding-tools) is built to close. You describe the feature in plain language, and the Planning Agent turns it into a requirement with explicit acceptance criteria, including the access rules you would otherwise leave in your head: who owns each row, who is allowed to read or change it, and where that rule is enforced. A criterion like "each user sees only their own orders, enforced at the database with row-level security" becomes part of the standard the Builder Agent builds against, whether that build happens in the Managed sandbox or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. It is not decoration. A feature that leaves the table wide open does not quietly pass, because "enforced at the database, other users get zero rows" is written down as a criterion, and a feature is not done until every criterion is verified with evidence.
That is the loop: Plan the access rules along with the feature, Build against them, Verify each one with evidence, Repeat. The RLS hole that scanners find, and that reviews of vibe-coded apps keep finding, lives in the gap between "the demo shows my data" and "no other user can reach it." Closing that gap with a criterion you defined up front is what turns a screen that happens to work into an app you can put real users and real data behind.
There is an honest limit here worth naming. Row-level security protects rows inside a database that supports it, Postgres and Supabase do, and it will not cover every security concern in your app. It does nothing for a leaked API key, an unprotected file upload, or a missing rate limit. It is one criterion, not the whole definition of done. But it is the one that shows up most often and does the most damage when it is missing, which is exactly why it deserves to be written down first.
## What this means if you are building right now
If you are building on Supabase or Postgres this week, the practical step is narrow and immediate. For every table that holds user data, answer one question before you ship the feature that touches it: who owns each row, and is anyone else able to read it? Then turn that answer into a criterion, "each user sees only their own rows, enforced at the database," and verify it the only way that counts: log in as one user, try to reach another user's data directly, and confirm you get nothing back. If you can reach it, RLS is missing or wrong, and you found out before your users did.
The uncomfortable truth underneath this is that the agent is not making your access-control decisions badly. It is making them silently, in favor of whatever demos fastest, every time you leave them out of the spec. A missing row-level security policy is not a mysterious bug in code you cannot read. It is a sentence you did not write. Write the sentence, make it a criterion, and check it. For the fuller version of this discipline, we wrote about [how a missing auth guard is a missing acceptance criterion](https://braingrid.ai/blog/vibe-coding-security), and about [how to write acceptance criteria an AI agent can actually verify](https://braingrid.ai/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
## FAQ
### What is meant by row-level security?
Row-level security (RLS) is a database feature that restricts which rows a user can see or change based on who they are. Instead of granting access to an entire table, the database attaches a policy to the table and filters rows on every query, so a user only ever sees the rows they are authorized to access. On Postgres and Supabase, a common policy is "a user can only read rows where the `user_id` column matches their own logged-in ID." The database enforces it automatically, below your app code, so it holds even if a request bypasses your application entirely.
### What is an example of row-level security?
A SaaS app with a shared `orders` table is the classic example. Every order row has a `user_id`. Without RLS, any logged-in user who can query the table can read every order, including other customers'. With an RLS policy that says "return only rows where `user_id` equals the current user," the database automatically filters each query so each customer sees only their own orders, even though all the data lives in one physical table. The same pattern secures multi-tenant apps where many companies share one database but must never see each other's data.
### Should I enable row-level security?
For any table holding user-specific or tenant-specific data, yes. Without RLS, you are trusting every layer of your app, including future code an AI agent writes, to remember to filter by user on every query, forever. One missed filter leaks everyone's data. RLS enforces the rule once, at the database, so it cannot be forgotten higher up. On Supabase, new tables have RLS enabled by default with no policies, which denies all access until you write one, so the real task is writing correct policies rather than turning the feature on. The main trade-off is a small query-performance cost and the effort of writing policies, which is minor next to the cost of a data leak.
### What is the difference between row-level security and column-level security?
Row-level security controls which rows a user can see, filtering the table horizontally so a user gets only the records that belong to them. Column-level security controls which columns a user can see, hiding specific fields, like masking a salary or a Social Security number, so a user can see a row but not every field in it. They solve different problems and are often used together: RLS ensures a customer only sees their own orders, while column-level security might hide an internal cost field on the orders they can see. For most vibe-coded apps, missing row-level security is the more common and more dangerous gap.
### How do I add row-level security to my Supabase app without being a database expert?
Treat it as a behavior to specify and verify, not SQL to master. In plain language, decide who owns each row and who may read it, then make that a written acceptance criterion: "each user sees only their own rows in this table, enforced at the database with row-level security." Hand that criterion to your coding agent as part of the feature, and it can generate the policy. You then verify it without reading the SQL: log in as one user, attempt to fetch another user's data directly, and confirm you get zero rows. You do not need to be a Postgres expert to define the rule and test the result, which is the part that actually protects your users.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into a requirement with acceptance criteria, including the access rules like row-level security, so your agent builds toward a standard instead of guessing. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Vibe Coding Security: The Holes Aren't in the Code, They're in the Spec
Source: https://www.braingrid.ai/blog/vibe-coding-security
Published: 2026-07-05T12:00:00Z
Every article about vibe coding security wants to sell you a scanner. Almost none of them mention that the scanner is looking for a decision you never made.
That is the part the security-vendor blogs skip. When a vibe-coded app ships without authentication on an admin route, or with a Supabase table wide open to the internet, or with an API key sitting in the client bundle, the tempting story is that the AI "wrote insecure code." It didn't, exactly. It wrote code for a requirement you never gave it. You asked for a dashboard. You did not say who is allowed to see it. So the agent picked, and it picked the version that demos fastest: everyone.
That distinction matters because it changes where the fix lives. A scanner catches the hole after it exists, in code you now have to read and understand to trust. Defining the behavior up front prevents the hole from being generated at all. The hypothesis of this post is simple: **most vibe coding security failures are missing acceptance criteria wearing a security costume, and the durable fix is upstream of any tool.**
## The community already diagnosed this
You do not have to take our word for it. Go read what builders are actually saying in the last few weeks. On r/vibecoding, someone asked the whole community, flatly, [how are you handling security in your vibe-coded projects today?](https://www.reddit.com/r/vibecoding/comments/1uiu1c5/how_are_you_handling_security_in_your_vibecoded/) The replies are not "which scanner." They are people realizing nobody told the agent the rules.
An engineering manager who [reviewed 25 vibe-coded apps](https://www.facebook.com/groups/claudeaicommunity/posts/1303845358449295/) put it bluntly: the same issues show up in all of them. Not twenty-five creative new vulnerabilities. The same handful, over and over. Missing auth. No row-level security. Secrets in the repo. Permissive defaults. When the same holes appear in every app built by different people with different tools, the problem is not the tool. It is that none of them said what secure meant before they hit build.
One builder on Instagram, of all places, said the quiet part out loud:
> Most AI-generated apps aren't hacked because of AI, they're hacked because basic security is skipped.
Skipped, not failed. You cannot skip a step you were required to take. The reason auth gets skipped is that "users must log in to see their own data" lived in your head as an obvious assumption instead of on the page as a criterion the build gets checked against.
## The scanner-shaped hole in the advice
Search "vibe coding security" and the first page is a wall of vendors: Checkmarx, Wiz, Oligo, Databricks, GuidePoint, Contrast. Their advice converges on one move: shift security left, scan the output, treat AI code as untrusted. The AI Overview at the top of that same search even lists the exact failure modes, missing authentication, no row-level security policies, hardcoded secrets, overly permissive access controls.
That advice is not wrong. It is incomplete in a specific, expensive way. "Treat AI code as untrusted and review all of it" is sound in principle and brutal in practice, because the person who vibe-coded the app is frequently the person least equipped to read it. If you could confidently audit the auth logic line by line, you probably would not have needed to vibe-code it in the first place. The scanner tells you a hole exists. It does not tell you what the right behavior was, and it cannot, because you never wrote it down.
There is a real trade-off here, and it is worth naming. Scanners genuinely catch a class of problems that upstream specs never will: a vulnerable transitive dependency, a subtly wrong crypto call, slopsquatted packages. Keep the scanner. This is not scanner-versus-spec. It is that the scanner is the second line, and right now most builders are running it as the only line, against code whose intended behavior was never defined. The first line is cheaper and you skipped it.
## Move security into the definition of done
The reframe is to stop treating security as a scan you bolt on at the end and start treating it as behavior you define at the beginning. The common holes map, almost one to one, onto acceptance criteria a non-engineer can write in plain language.
Consider the difference.
> Vague: "Build me a dashboard where users can see their orders."
> Specified: "Build an orders dashboard. Only authenticated users can access it. Each user sees only their own orders, never another user's, enforced at the database layer, not just hidden in the UI. Unauthenticated requests redirect to /login. No API keys or secrets appear in client-side code."
Same feature. The second version made four security decisions out loud: authentication is required, authorization is per-user, enforcement is server-side, secrets stay server-side. The agent now has no room to guess "everyone can see everything" because that is the fastest path to a working demo. And, just as importantly, you now have four concrete things to verify against, whether you can read the code or not. "Does an unauthenticated request redirect to /login?" is a question anyone can check by trying it. "Is the auth logic correct?" is not.
This is the whole game, and it echoes the best line we read all week, from a random Hacker News comment that has stuck with us:
> You can make good software with agents, if you exhibit good judgement and put yourself in the path as a gate on quality.
Put yourself in the path. Not by reading every line, most vibe coders can't, but by defining the behavior the code must satisfy and then checking the result against it. Security is not a property of the code you can eyeball. It is a set of behaviors you can specify and verify. Missing auth is a criterion you did not write. A table without row-level security is a criterion you did not write. A leaked key is a criterion you did not write.
## Where this fits in the loop
This is exactly the gap [BrainGrid](https://braingrid.ai/vibe-coding-tools) is built to close. You describe the feature in plain language, and the Planning Agent turns it into a requirement with explicit acceptance criteria, including the security ones you would otherwise leave implicit: who is authenticated, who is authorized to see what, where enforcement happens, what data must never be exposed. Those criteria are not decoration. They are the standard the Builder Agent builds against and the checklist a feature is verified against before it counts as done. A build with an unprotected admin route does not quietly pass, because "admin routes require an admin role" is written down as a criterion, and a feature is not done until every criterion is verified with evidence.
That is the loop: Plan the behavior including its security posture, Build against it, Verify each criterion with evidence, Repeat. The security holes the scanners find live in the gap between "looks done" and "is done." Closing that gap with criteria you defined up front is what turns a demo that happens to work into software you can actually trust with real users and real data.
## What this means if you are building right now
If you are vibe-coding a real app in Lovable, Cursor, Claude Code, or Bolt this week, the practical implication is narrow and immediate. Before your next feature, write down the answers to four questions the agent is otherwise deciding for you: Who has to be logged in? Who is allowed to see or change which data? Where is that enforced, in the UI or in the database? And what secrets must never leave the server? Those four answers are your security acceptance criteria. They take five minutes and they close the majority of the holes that show up in every review of vibe-coded apps.
The uncomfortable truth underneath all of this is that the AI is not making your security decisions badly. It is making them silently, on your behalf, every time you leave them out of the prompt. The fix was never a better scanner. It was saying what secure means before the agent builds, so there is a standard to build toward and something concrete to check against when it is done. If you want the fuller version of this discipline, we wrote about [how to vibe code the right way by planning first](https://braingrid.ai/blog/how-to-vibe-code-the-right-way), and about why [the oversight is the premium](https://braingrid.ai/blog/the-oversight-premium) once the agent does the typing.
## FAQ
### Is vibe coding safe?
Vibe coding is as safe as the requirements you give it. The tool is not the risk. The risk is unspecified behavior: when you do not say who must be authenticated, who is authorized, and what data must stay private, the agent picks defaults that favor a fast demo over a secure app. Define those behaviors as acceptance criteria and the same tools produce far safer output. Safety comes from the spec, not the scanner.
### How dangerous is vibe coding?
The danger is concentrated in a small, repeatable set of holes, not spread randomly across everything the AI writes. Reviews of many vibe-coded apps keep finding the same four: missing authentication, no row-level security on the database, hardcoded secrets, and overly permissive defaults. Because the failures are predictable, they are preventable. Each one corresponds to a decision you can make explicitly up front instead of letting the agent make it silently.
### What are the most common vibe coding security risks?
The common ones are missing or weak authentication on protected routes, missing authorization so users can access other users' data, backend databases like Supabase deployed without row-level security policies, hardcoded API keys and secrets left in the codebase (often shipped to the client), and unaudited third-party packages pulled in by default. Every item on that list is a behavior you can specify before the build rather than a bug you hunt after it.
### Should I use a security scanner for vibe-coded apps?
Yes, as a second line of defense, not your only one. Scanners catch things upfront specs will not, like a vulnerable dependency or a subtly wrong crypto call. But a scanner reports a hole after it exists, in code you then have to understand to fix. Defining security behavior as acceptance criteria prevents most of the common holes from being generated in the first place. Use both: specify the behavior, then scan to catch what slipped through.
### How do I make a vibe-coded app secure without reading all the code?
Shift the work from reading code to defining and verifying behavior. Write down, in plain language, who must be authenticated, who is authorized to see or change which data, where that enforcement lives (server-side, not just hidden in the UI), and what secrets must never reach the client. Then verify each one by testing it: try an unauthenticated request, try to access another user's data, check the client bundle for keys. You do not need to read the auth code to confirm the auth behavior is correct.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into a requirement with acceptance criteria, including the security ones, so your agent builds toward a standard instead of guessing. Try it at [braingrid.ai](https://braingrid.ai).*
---
# How to Vibe Code the Right Way: Plan First, Then Let It Rip
Source: https://www.braingrid.ai/blog/how-to-vibe-code-the-right-way
Published: 2026-07-04T12:00:00Z
Every guide to vibe coding tells you to skip the planning. "Don't get bogged down in technical decisions, let the AI pick." "Iterate on bugs, not features." "Start prompting." That advice is right for exactly one afternoon and wrong for every afternoon after it. The way to vibe code that actually holds up is the opposite of what the tutorials teach: you plan first, then you let it rip.
That sounds like a contradiction, because "vibe" is supposed to mean no plan. It isn't. The vibe is the part where the agent writes the code and you never touch a syntax error. The plan is a paragraph of plain English you write before that, and it is the single thing that separates a project you can keep building from one that turns into a pile you are scared to touch. This post is the method: how to vibe code the right way, step by step, without giving up the speed that made you fall in love with it.
## The hypothesis: the plan is the vibe, not the enemy of it
Here is the claim this whole post rests on, stated so you can argue with it. The failure mode of vibe coding is not bad code. It is undefined intent. The fix is not less vibe coding, it is a two-minute plan written before the agent starts, so the agent builds against something instead of guessing.
Watch what the audience actually does when nobody is scripting them. On r/GithubCopilot, a builder describing their real workflow wrote:
> "I plan directly in agent mode, discussing design options, asking clarifications, reviewing and requesting changes, all that as it creates and updates the design document (.md). Then only when I agree with the plan, will I ask to start the implementation."
That is not a beginner following a tutorial. That is someone who got burned and worked their way back to planning first, on their own. They are not the exception. They are the pattern underneath every "how I finally got vibe coding to work" thread. The people shipping real things with agents almost always plan before they build, and the people hitting a wall almost always don't.
## Step 1: Say what you are building, not just what you want
The first move is the one the tutorials skip. Before you prompt for code, write one short paragraph that answers three questions: what is this feature, who uses it, and how do you know it worked. Not a spec document. A paragraph. But a specific one.
The difference is the entire game, so look at it side by side.
> Vibe: "Build me a habit tracker with login."
>
> Planned: "Build a habit tracker. A signed-in user can create a habit with a name and a daily or weekly frequency, mark it done for today, and see a streak count. Only signed-in users reach the tracker; signed-out users go to /login. The done button has to save so the streak survives a refresh."
The second one is not slower to think of. It is the same idea, said out loud with the edges filled in. And every one of those edges is a place the vague version would have let the agent quietly invent an answer you didn't want. Streak survives a refresh, signed-out users redirect, frequency is daily or weekly. Those are not technical decisions you delegated to the AI. Those are product decisions only you can make, and if you don't make them, the agent will, and it will make them differently every time you regenerate.
## Step 2: Let the agent build against the plan, and actually let go
Now you vibe. This is where the tutorials are right. Hand the agent your paragraph, let it write the code, let it host and preview, and do not read every line. Karpathy's original framing, where you ["fully give in to the vibes" and "forget that the code even exists"](https://x.com/karpathy/status/1886192184808149383), is completely correct here, because the plan is doing the job that used to require reading the code. You are not trusting the agent blindly. You are trusting it against a written standard you can check the result on.
This is the part people get backwards. They think planning means micromanaging the agent. It is the reverse. The clearer your paragraph, the less you have to babysit the build, because the agent has something to be right or wrong about. Vague inputs are what force you to hover over every generation, because with a vague input the only judge of "correct" is your gut, in the moment, one prompt at a time.
## Step 3: Check the result against the plan, not against your vibe
When the preview comes back, you have a definition of done sitting right there in your paragraph. Go down it. Does a signed-out user actually hit /login, or did the agent build the page and forget the guard? Does the streak survive a refresh, or does it reset because "save" meant something looser than you assumed? This is the step that makes vibe coding safe, and it is the step the ["iterate on bugs"](https://developer.microsoft.com/blog/complete-beginners-guide-to-vibe-coding-an-app-in-5-minutes) advice quietly deletes.
Iterating on bugs sounds fine until you notice what it means: you only fix what you happened to see break. The behaviors you didn't think to click never get checked, so they rot in silence and surface three features later as the regression you can't explain. A commenter on Hacker News put the healthy version of this in one line:
> "You can make good software with agents, if you exhibit good judgement and put yourself in the path as a gate on quality."
Being the gate is the whole job. Not writing the code, not reviewing every line, but standing at the point where "the agent says it's done" meets "it actually does what I said," and only letting through the things that match. A plan is what makes that gate possible, because without a written definition of done you are not a gate, you are just a person hoping.
## Where this breaks, honestly
This method has a real cost, and pretending otherwise would make it a worse method. Writing the paragraph feels like friction at the exact moment you are most excited to just start. On the same threads where builders praise planning, others push back: ["like I was chatting and writing md files 80% of the time instead of actually getting stuff done."](https://www.reddit.com/r/GithubCopilot/comments/1uksz1y/) That complaint is legitimate. If you turn planning into ceremony, into a folder of design documents you maintain by hand, you have traded one mess for a slower one.
So the rule is proportion. The plan should be roughly one paragraph per feature, not a document. It exists to define done, not to impress anyone. The moment it grows into homework, you are doing it wrong in the other direction. Keep the speed, lose the mess, and the plan is one paragraph. If you find yourself writing specs for a throwaway script or a landing page you will delete next week, stop. Disposable work does not need a plan. This method is for the stuff that has to still work next month.
## What changes for you
If you are building something real in Cursor, Lovable, Claude Code, or Replit right now, here is the concrete implication. Your first two features will feel incredible either way, plan or no plan. The difference shows up at feature three or four, when the agent starts editing a system it can no longer fully see. With no written record of what each earlier feature was supposed to do, it breaks load-bearing behavior it didn't know was load-bearing, and you spend your afternoons chasing regressions instead of shipping. That is the three-month wall, and the paragraph you wrote in Step 1 is what keeps the agent from walking you into it. We wrote the full autopsy in [why your AI agent keeps breaking things that worked](/blog/why-ai-keeps-breaking-things-that-worked).
This is exactly the gap BrainGrid is built to close, and it is built to do it without the "writing md files 80% of the time" tax. You describe the feature in plain English, and BrainGrid's Planning Agent asks the clarifying questions you would have skipped, then turns your idea into a requirement with explicit acceptance criteria: the conditions that have to be true for the feature to count as done. From there you build in BrainGrid's managed sandbox with a live preview, or in your own GitHub repo with Claude Code, Cursor, or Codex over MCP. The Builder Agent works against the criteria, and a feature is not finished until every one is verified with evidence. The loop is Plan, Build, Verify, Repeat. Vibe coding is that loop with Plan and Verify deleted. Put them back and you keep the whole vibe.
## The right way, in one line
Vibe coding done right is not less vibe. It is a plan the agent can build against and a definition of done you can check the result on, wrapped around the same fast, code-you-never-read loop you already love. Plan the feature in a paragraph. Let the agent rip. Gate the result against what you wrote. That is the difference between a demo you abandon and a product you keep. If you are still assembling your toolkit, start with our guide to [vibe coding tools](/vibe-coding-tools), then decide [whether vibe coding is good for what you are building](/blog/is-vibe-coding-good).
## FAQ
### How do you actually vibe code, step by step?
Write one plain-English paragraph defining the feature: what it is, who uses it, and how you will know it worked. Hand that to an AI agent like Claude Code, Cursor, Lovable, or Replit and let it write and preview the code without you reading every line. Then check the result against your paragraph, point by point, and only accept the parts that match. Plan, build, check. The plan is what makes the "don't read the code" part safe instead of reckless.
### Is vibe coding good for beginners?
It is a great on-ramp if you use it to learn rather than to avoid learning. The trap for beginners is skipping the plan and treating a working preview as a finished product. Write the short paragraph first, ask the agent to explain what it built, and check the result against what you asked for. That turns vibe coding from a way to ship things you don't understand into a way to build things you do.
### Is ChatGPT or Claude better for vibe coding?
Both can vibe code, and the model matters less than the method. Claude, through Claude Code, and agentic IDEs like Cursor are built for the full build-preview-iterate loop, while plain ChatGPT is stronger for planning and generating snippets you paste elsewhere. Whichever you pick, the thing that determines whether the result holds up is not the model, it is whether you defined what "done" meant before it started building.
### Do you have to plan before vibe coding?
For anything you intend to keep, yes. For a throwaway script or a page you will delete next week, no, planning is wasted effort there. The line is durability. The moment real people or real data depend on the software, a one-paragraph plan that defines done is what keeps the project from collapsing at the three-month mark. Below that line, skip it and enjoy the speed.
### What is the biggest mistake people make when vibe coding?
Letting the agent decide things they never noticed were decisions. When your prompt is vague, the AI silently picks the behavior for auth, edge cases, and state, and it picks differently every time you regenerate. The fix is to make those decisions yourself in a short written plan, so the agent is building against your intent instead of guessing at it, and so you have something concrete to verify the result against.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that captures what "done" means before your agent builds, so you can vibe code fast without the three-month mess. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The Fallback Trap: When Defensive AI Code Hides a Broken App
Source: https://www.braingrid.ai/blog/the-fallback-trap
Published: 2026-07-03T12:00:00Z
Defensive programming is one of the oldest good habits in software. Check your inputs, handle the edge cases, never let a bad value crash the whole app. When an AI agent does it, that same habit quietly becomes one of the most dangerous things in your codebase.
The instinct is right. The default the agent reaches for is wrong. Told to be careful, a coding agent wraps everything in try/catch, adds a fallback for every failure, and returns a safe-looking value when something goes sideways. The app never crashes. It also never tells you it broke. It just keeps running, serving the wrong answer with a straight face, and you find out weeks later when a customer does.
That is the fallback trap. And it is worth naming precisely, because "AI writes bad code" is too vague to act on. This is a specific, checkable failure mode: defensive code that swallows a broken state instead of surfacing it.
## The habit that turns into a hazard
Armin Ronacher, the creator of Flask, wrote a widely discussed post called [The Coming Loop](https://lucumr.pocoo.org/2026/6/23/the-coming-loop/) about his unease with where agentic coding is heading. In the thread that followed on [r/ExperiencedDevs](https://www.reddit.com/r/ExperiencedDevs/comments/1ukttup/), one line landed hard for a lot of engineers:
> They add fallbacks instead of making bad states impossible.
Another put the consequence plainly:
> Tons of default/fallbacks that end up masking real problems when they happen.
Read those two sentences together, because between them is the whole trap. Making a bad state impossible means the program refuses to continue in a broken condition. Adding a fallback means the program continues anyway, on a guess. Those are opposite philosophies, and an agent optimizing for "don't crash" will pick the second one every single time.
Here is why this is structural and not a passing model weakness. A defensive fallback is, by design, invisible. Its entire job is to make a failure look like a non-failure. So the better your agent gets at writing plausible, tidy-looking code, the better it gets at burying the failure where you will never see it by reading. This is the same reason the [verification gap](/blog/verification-gap) widens as models improve: capability moves errors from obvious to subtle, and subtle is exactly where a silent fallback lives.
## What the trap looks like in real code
Consider the difference between the two philosophies on the same tiny function: fetch a user's plan so the app can decide what features to show.
The fallback version:
```javascript
async function getUserPlan(userId) {
try {
const plan = await db.plans.findByUser(userId);
return plan ?? 'free';
} catch {
return 'free';
}
}
```
It looks responsible. It handles the missing row, it handles the thrown error, it never crashes. It is also the trap in its purest form. If the database is down, every user silently becomes a free user. Paying customers lose the features they paid for, no error is logged, no alert fires, and the app looks completely healthy on your dashboard. You will find this bug when the support tickets arrive, not when it happens.
The fail-loud version:
```javascript
async function getUserPlan(userId) {
const plan = await db.plans.findByUser(userId);
if (!plan) {
throw new Error(`No plan found for user ${userId}`);
}
return plan.tier;
}
```
This one can crash. That is the point. A crash is information. It tells you, immediately and loudly, that a user has no plan and something upstream is wrong. The fallback version traded that information away for the appearance of stability, and the appearance of stability is worth nothing when the app is stable and wrong.
Notice what the reader cannot do here. You cannot look at the first version and know it is a bug, because there is no bug in the code. The bug is in the gap between what the code does (returns 'free' on failure) and what you intended (only free users see the free tier). That gap does not live in the diff. It lives in a requirement nobody wrote down.
## The reframe: a silent fallback is a failed acceptance criterion
The instinct at this point is to tell the agent to stop doing this. Add a rule to your instructions file: no silent fallbacks, fail fast. That helps, and it is worth doing. But a blanket rule is a blunt instrument, because sometimes a fallback is exactly right (a cached value when a non-critical service is slow) and sometimes it is catastrophic (defaulting a paying user to the free tier). The agent cannot tell which is which from a general instruction. Only the intended behavior of that specific feature can.
So the durable fix is not a better rule. It is a written statement of what correct behavior actually is, before the code exists.
Think of it this way. A silent fallback is not a coding-style problem. It is a feature that fails its acceptance criteria without telling you. If the requirement said "when the plan lookup fails, surface an error and do not grant or revoke access," then the fallback version is not defensive code, it is a build that violates its spec. You just could not see the violation by reading, because the spec was never captured anywhere the code could be checked against it.
This is the shift. Stop trying to catch silent fallbacks by reviewing code harder. Start defining the correct behavior up front, so a failure to meet it is a fact the loop can check instead of an opinion you have to form by staring at a green dashboard.
That is where a plan-first workflow changes the outcome. In BrainGrid, before the Builder Agent writes anything, the Planning Agent turns "look up the user's plan" into a requirement with [explicit acceptance criteria](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify), including what must happen when the lookup fails. The build is then verified against those criteria with evidence, so a change that silently defaults on error does not pass as done. This is the [Verify step of the loop](/loop) doing its job: the agent is not left to guess whether continuing on a fallback is safe, the criterion already answered that, and the verification step checks the answer. It isn't done until the evidence says it does what you intended.
```mermaid
flowchart LR
A[Feature request] --> B[Plan: define correct failure behavior]
B --> C[Build: agent writes code]
C --> D{Verify against acceptance criteria}
D -->|Silent fallback| E[Fails: does not match intent]
D -->|Fails loud as specified| F[Done: evidence matches]
E --> B
```
## What this changes for you
If you are shipping features through Claude Code, Cursor, or Codex right now, this means the bugs that hurt you most will not be the ones that crash. They will be the ones that don't. Your agent is competent enough to keep the app running through almost any failure, which sounds like a feature and is actually the problem. The silent-fallback bug is invisible in a demo, invisible in a code review skim, and invisible on your monitoring until real usage hits the failure path you defaulted your way past.
The practical move is small and it is upstream. Before you hand a feature to an agent, decide what the failure paths should do, and write it down as part of the spec, not as an afterthought. "On error, fail and alert" versus "on error, use the cached value" is a product decision, and it is yours to make, not the agent's to guess. Once it is written, it becomes something the build can be checked against. Without it, "handle the error gracefully" collapses into "hide the error," and graceful is the last word you would use for an app that lies to you.
There is a trade-off worth naming honestly. Failing loud means more visible errors during development, and some of them will feel like noise. A system that refuses to continue in a bad state is louder than one that limps along on defaults. But that loudness is the whole value. You are moving the discovery of a failure from your customers to your test run, which is the only trade in software that is always worth making.
## FAQ
### Is defensive programming good?
Defensive programming is good in principle and dangerous in one specific practice: silent fallbacks. Validating inputs, guarding against null, and handling edge cases explicitly all make software more robust. The problem is the version of "defensive" that swallows a failure and continues on a default, because that hides a broken state rather than handling it. The useful distinction is between defending against bad input (good) and defending against your own program ever surfacing that something went wrong (bad). When an AI agent writes defensively, it tends toward the second, so the goal is not to turn defensiveness off but to specify when a failure should stop the program instead of being papered over.
### What is defensive programming?
Defensive programming is the practice of writing code that anticipates and handles things going wrong, so that unexpected inputs or failures do not corrupt data or crash the system. In its healthy form it means checking assumptions explicitly: validate arguments, guard against null, handle the edge cases you can foresee. The failure mode this post is about is a specific overcorrection, where "handle the failure" quietly becomes "hide the failure" by returning a safe-looking default. The line between the two is whether the code makes a bad state visible or invisible.
### What are two common defensive coding techniques?
Two of the most common are input validation and guard clauses. Input validation checks that data is well-formed and within expected bounds before the code acts on it, rejecting or flagging anything that is not. Guard clauses check for invalid conditions at the top of a function and exit early rather than nesting the real logic inside deep conditionals. Both are healthy because they make bad states explicit and stop them early. The technique to be careful with is the catch-all fallback, a try/catch or default value that lets execution continue no matter what failed, because that one hides the bad state instead of surfacing it.
### What is defensive design in programming?
Defensive design is the broader idea of structuring a system so that failures are contained, predictable, and hard to trigger accidentally, rather than left to chance. It includes defensive coding techniques like validation and guard clauses, but it also covers how components fail: whether a failure is loud and isolated or silent and spreading. Good defensive design makes bad states impossible or immediately visible. The anti-pattern, common in AI-generated code, is design that makes bad states survivable but invisible, which trades a crash you would notice for a wrong answer you would not.
*[BrainGrid](https://braingrid.ai) plans every feature into acceptance criteria, including what should happen when things fail, then verifies each build against them with evidence, so a silent fallback that hides a broken state never passes as done. Try it at [braingrid.ai](https://braingrid.ai).*
---
# OpenSpec vs Spec Kit vs BrainGrid: The Honest Decision Map
Source: https://www.braingrid.ai/blog/openspec-vs-spec-kit-vs-braingrid
Published: 2026-07-02T00:00:00Z
The comparison you came here for takes about five minutes to settle. OpenSpec is the light one. Spec Kit is the rigorous one. Then the choice is supposed to feel obvious, and instead most builders end up three tabs deep in Reddit threads at 11pm, still not building anything.
That is the tell. If picking a spec-driven development tool were really the hard part, you would have picked one by now. The reason the decision stalls is that the tools all agree on the thing that actually matters and differ only on the thing that doesn't, so no amount of comparing resolves the itch that made you start comparing.
Here is the hypothesis this post tests: the OpenSpec vs Spec Kit question is genuinely answerable in a few minutes, and the moment you can answer it that fast is the moment you realize you were never choosing a methodology. You were choosing a file format for a practice all three tools share. The durable decision is a different one, and it is the last section of this post.
Let me give you the honest map first, because you deserve a real answer, not a dodge.
## The Two-Minute Version
[OpenSpec](https://github.com/Fission-AI/openspec) is a lightweight, open-source framework that crossed 27,000 GitHub stars in under six months. Its whole model is a minimal loop: propose a change, apply it, archive it into one living spec document. No API keys, no MCP wiring, specs are just markdown in your repo. It shines on an existing codebase where you are making focused, day-to-day changes and want the ceremony to stay out of your way. Thoughtworks' Technology Radar [singled out exactly that](https://www.thoughtworks.com/en-us/radar/tools/openspec): a "fluid, minimal workflow."
[GitHub Spec Kit](https://github.com/github/spec-kit) is the opinionated one. It walks you through gated phases, specify, plan, tasks, implement, and it fragments specs so each feature gets its own directory, often with acceptance criteria written in EARS syntax. It fits greenfield projects and teams that want upfront design debate and a paper trail. As one [GitHub discussion](https://github.com/github/spec-kit/discussions/1536) put it plainly, Spec Kit is "the more general-purpose option" while OpenSpec leans brownfield.
So the honest map is short. Modifying an existing app, working solo, want to move fast? OpenSpec. Starting fresh, working with a team, want rigor and separation between the planner and the builder? Spec Kit. Juan Carmona [compressed the whole thing into one line](https://jgcarmona.com/en/moving-toward-spec-driven-development/): "OpenSpec feels like a continuity layer; Spec Kit, a governance layer."
That is the answer. You could stop reading and go install one. But notice how little that decision actually commits you to, and notice what it left untouched.
## What You Were Actually Comparing
Look at what varied across that map and what didn't.
What varied: where the specs live, how they are sequenced, whether they accumulate or merge, how much scaffolding sits between you and the code. File layout and ceremony. Real differences, and if you enjoy this kind of thing you can spend a good weekend on it.
What did not vary: every one of these tools makes you write down what you want, plan it before the agent codes, define what done means, and keep a record. That is the constant. OpenSpec, Spec Kit, SuperPowers, BMAD, all of them are competing on how to store and order the same four artifacts. Not on whether you should produce them.
This is the reframe, and it flips the whole exercise. The spec-driven tools are not arguing about whether to plan first. They agree on that completely. They are arguing about where to put the files.
Once you see it, the late-night comparison threads read differently. A builder on r/SpecDrivenDevelopment recently [laid out the differences carefully](https://www.reddit.com/r/SpecDrivenDevelopment/comments/1uepz6g/learning_sdd_and_have_some_questions/) and then admitted, "I think we are all still figuring these things out. Sometimes it's best to just dive in and give it a try." He had done the homework and still could not tell that he had already found the answer, because the tool comparison was the thing holding his attention. (We wrote a whole piece on that trap: [stop shopping for the right SDD tool](/blog/stop-shopping-for-spec-driven-development-tools).)
## Why the Tool Is the Least Durable Part of Your Choice
Here is the uncomfortable part for anyone mid-comparison.
The tool layer is churning faster than you can finish evaluating it. Latent.Space catalogued what they called ["meta-harness summer"](https://www.latent.space/p/ainews-its-meta-harness-summer): Conductor, Zed's ACP, Vercel's Eve, HarnessAgent, Databricks' Omnigent, a new orchestration layer landing what feels like every week. The SDD tools sit one layer below that and move just as fast. OpenSpec went from near-zero to tens of thousands of stars in months. Whatever you pick today could be unmaintained by spring, or eclipsed by something that did not exist when you opened the comparison tab.
So run the test. What survives the churn?
Not the tool. The spec.
The requirement that says what you are building and why. The acceptance criteria that define done. The record of decisions that explains, six months from now, why the code looks the way it does. Those are plain text. They outlive any CLI that produced them. Move them from OpenSpec to Spec Kit to a bare text file and they lose nothing, because they were never really about the tool.
Boris Cherny, who reports writing 100% of his Claude Code contributions with Claude Code, [describes his job now](https://x.com/sydneyrunkle/status/2066928783534289358) as writing loops and making sure they can verify themselves. The loop is what he owns. The model is rented. Push that up one level and it holds for tooling too: the spec is what you own, the SDD tool is rented. You just do not usually notice the lease terms until the tool you standardized on stops shipping.
Consider the difference concretely.
Tool-first thinking: "Should I use OpenSpec or Spec Kit? OpenSpec is lighter, but Spec Kit has better task templates, though the community around OpenSpec is bigger right now, and SuperPowers' accumulation model kind of fits how I work."
Practice-first thinking: "This feature is 'let users reset their password by email.' Done means: a logged-out user requests a reset, gets a one-time link valid for an hour, sets a new password, and the old one stops working. Now, which tool helps me build that against those criteria?"
The second builder ships this afternoon. The first one has three more comparison articles to read.
## The Decision That Actually Matters
So if the OpenSpec vs Spec Kit choice is a five-minute decision about file layout, what is the choice that deserves real thought? It is this: do you want to assemble and maintain the practice yourself, or do you want it delivered as a product?
That is the fork the tooling map hides.
```mermaid
flowchart TD
A[You've decided to plan before you build] --> B{Assemble it yourself or have it delivered?}
B -->|Assemble| C[Pick an SDD framework]
C --> D[OpenSpec: light, brownfield, solo]
C --> E[Spec Kit: gated, greenfield, teams]
D --> F[You install, wire, and keep the discipline every time]
E --> F
B -->|Delivered| G[BrainGrid: the practice as a product]
G --> H[Planning Agent writes the spec + criteria]
H --> I[Builder Agent builds and verifies it]
```
The SDD frameworks hand you a toolkit and leave you to run it. You install the CLI, learn its commands, wire it into your agent, and remember to follow every step on every feature. The practice is sound. But you are the one assembling it and keeping it running, and that maintenance is precisely the labor those Reddit threads are full of. That is a fine trade if you want maximum control and do not mind being the process's operator.
BrainGrid ships the same practice as a product instead of a framework. You describe a feature, and the Planning Agent turns it into a requirement with acceptance criteria, data models, and designs, challenging the vague parts and asking the questions you did not think to ask before any code is written. That is "one spec per feature, one plan per spec," done for you rather than configured by you. Then the Builder Agent builds it two ways: in BrainGrid Cloud, a sandbox with live preview that opens a pull request, or on your own machine in your GitHub repo with Claude Code, Cursor, or Codex over MCP. Whichever agent you point at it, the plan and the criteria are the same, and a feature is not done until the evidence shows it matches what you intended. Swap the agent, swap the model, keep the workflow.
That is the honest trade in the other direction. You give up some low-level control over file layout and CLI ceremony. You get the discipline as a product you do not have to babysit, and a spec that is portable across every agent you might use next.
Here is what changes for you specifically. If you are a solo builder shipping a SaaS product with Cursor or Claude Code, and you have been stuck comparing SDD tools instead of building, the practical move is to stop treating the tool as the decision. Pick OpenSpec in two minutes if you want to run the framework yourself. Or skip the assembly entirely and let the plan and criteria be produced and verified for you. Either way, the thing you carry forward, the spec, is identical. Only one of those paths asks you to also be the maintenance crew.
Strip every trending reference out of this post, the meta-harness churn, the star counts, the Reddit thread, and the argument still stands: the tool you pick is a temporary container, and the spec is the asset. The comparison was never the hard part. Deciding to own the practice, in whatever form survives the next tool cycle, is.
## FAQ
### What is the difference between OpenSpec and Spec Kit?
OpenSpec is a lightweight, open-source framework built around a minimal propose-apply-archive loop that consolidates everything into one living spec document. It suits brownfield work and solo builders who want speed. GitHub Spec Kit is more rigorous and gated, walking you through specify, plan, tasks, and implement phases, fragmenting specs per feature, and often generating acceptance criteria in EARS syntax. It suits greenfield projects and teams that want upfront design and a paper trail. The practical shorthand: OpenSpec is a continuity layer, Spec Kit is a governance layer.
### Should I use OpenSpec or Spec Kit?
Use OpenSpec if you are modifying an existing application incrementally, working solo, and prefer a single living document with minimal ceremony. Use Spec Kit if you are building a new project, working with a team, and want gated reviews, structured phases, and clear separation between planning and implementation. Both encode the same underlying practice, so the choice is mostly about file layout and how much structure you want between you and the code.
### Is spec-driven development worth it?
Yes, but not because of any particular tool. The value comes from the practice underneath every SDD tool: one focused spec per feature, a plan you can review before the agent writes code, and acceptance criteria that define done and accumulate over time. That practice is what keeps an AI agent from confidently building the wrong thing. The tool you use to store those artifacts matters far less than actually producing them.
### What are the alternatives to Spec Kit?
The most common alternatives are OpenSpec (lighter, brownfield-oriented), SuperPowers (timestamped specs that accumulate), BMAD-METHOD (role-based planning), and Kiro (an IDE with spec-driven workflows built in). BrainGrid takes a different shape entirely: rather than a framework you install and run, it delivers the same plan-then-verify practice as a product, with a Planning Agent that writes the spec and a Builder Agent that builds and verifies it. If you want a deeper single-tool comparison, we covered [Kiro versus BrainGrid](/blog/kiro-vs-braingrid-spec-driven-development).
### Do I have to pick just one spec-driven tool?
No, and that is part of the point. Because the durable artifacts, the requirement, the acceptance criteria, and the decision record, are plain text, they are portable. You can move them between OpenSpec, Spec Kit, or any other tool with little loss. That portability is exactly why the tool choice is lower-stakes than it feels: you are choosing a temporary container, not locking in a methodology.
*[BrainGrid](https://braingrid.ai) is the system that takes an idea to a live product you can trust, shipping spec-driven development as a product instead of a framework you assemble and maintain. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Human in the Loop vs On the Loop: Where You Belong When Agents Build
Source: https://www.braingrid.ai/blog/human-in-the-loop-vs-on-the-loop
Published: 2026-07-01T00:00:00Z
The phrase "human in the loop" is supposed to make you feel safe. In practice, it is often the thing slowing you down the most.
Being in the loop means you approve every step before the agent moves on. That is exactly what you want when a decision is expensive and rare. It is exactly what you do not want when an agent can open twelve pull requests before lunch and you are the one gate all twelve wait behind. At some point, sitting inside the loop stops being oversight and starts being a bottleneck wearing oversight's clothes.
So the real question is not whether a human belongs in the loop. It is *which* loop, and *where* in it.
## The two postures, in plain language
Two terms get used interchangeably and mean very different things. Getting them straight is the whole point.
**Human in the loop (HITL):** the human sits inside the execution path. The agent drafts or proposes, then stops and waits. Nothing finalizes until you review and approve. Control is high, and so is the cost of your attention, because every single action routes through you.
**Human on the loop (HOTL):** the human sits alongside the execution path. The agent runs autonomously inside limits you set in advance. You monitor, and you step in to correct or stop it when something crosses a line. Control is supervisory. You are watching the standard hold rather than pressing the button each time.
The cleanest articulation of this comes from Martin Fowler, who lays out three postures for humans working with coding agents: outside the loop, in the loop, and on the loop.
> Humans on the loop [...] design the specifications, tests, and feedback mechanisms that guide AI agents rather than reviewing every generated artifact directly.
Read that carefully, because it reframes the whole debate. On-the-loop is not "caring less." It is moving your effort from inspecting each output to defining what a good output *is*, up front, in a form the agent and the system can check. You trade a thousand small approvals for one durable standard.
## The mistake is treating it as a personality, not a decision
Most builders pick a posture once and never revisit it. The cautious ones stay in the loop forever and drown in review. The optimistic ones jump on the loop too early and wake up to a merged PR that quietly broke checkout.
Neither is a character trait. It is a per-task call, and the variable is stakes.
High-stakes, low-volume, hard-to-reverse work belongs in the loop. A schema migration on your production database. The auth logic that decides who can see whose data. A payment flow. You want to be the gate here, because the cost of a wrong action dwarfs the cost of your time.
High-volume, lower-stakes, easy-to-reverse work belongs on the loop. Renaming variables across forty files. Drafting the tenth CRUD endpoint that looks exactly like the previous nine. Writing tests for code whose shape you already approved. Sitting inside each of those approvals is not diligence. It is waste.
Here is the shift that matters: as agents get more capable, more of your work slides from the first bucket toward the second. That is not a reason to disengage. Anthropic's [2026 Agentic Coding Trends Report](https://resources.anthropic.com/2026-agentic-coding-trends-report) found developers now integrate AI into 60% of their work while maintaining active oversight on 80 to 100% of the tasks they delegate. The agents do more. The humans do not do less. They do something different. They move from in to on. That move is the whole reason [oversight, not generation speed, is the skill that now compounds](/blog/the-oversight-premium).
## What actually lets you move from in to on
You cannot supervise a loop you have no standard for. This is the part every generic "HITL vs HOTL" explainer skips, because it is written for compliance officers, not builders shipping features.
To be *in* the loop, you need attention. You read the diff, you feel whether it is right, you approve or reject. That works, and it does not scale.
To be *on* the loop, you need something the loop can be checked against without you. A written definition of what "done" means for this feature. The edge cases it has to handle. The behavior that would count as a failure. In other words, acceptance criteria that exist before the agent starts and outlive the conversation it happens in.
Consider two builders shipping the same feature with the same agent.
Builder A stays in the loop by instinct. They prompt, the agent builds, they eyeball the result, they approve. It works in the demo. Three weeks later a user hits an unauthenticated route the demo never exercised, because "only logged-in users can see this" lived in Builder A's head and nowhere the agent could read.
Builder B writes the criteria first: authenticated users see the dashboard, unauthenticated requests redirect to login, an expired session is treated as unauthenticated. Then Builder B lets the agent run on the loop, and checks the output against those three lines. The redirect was missing. They caught it in thirty seconds, because they were comparing against a standard, not a memory.
Same agent. Same speed. The difference is that Builder B had something to be on the loop *of*.
This is the gap [BrainGrid](https://braingrid.ai) is built to close. When you describe a feature, the Planning Agent turns it into a requirement with real acceptance criteria before any code exists, so the standard is written down instead of carried in your head. The Builder Agent then builds against that requirement, in BrainGrid Cloud or in your own repo with Claude Code, Cursor, or Codex over MCP. Verification checks each criterion with evidence, so a feature is not done until the proof says it does what you intended. That is the on-the-loop posture made concrete: you set the standard once, and the loop is checked against it every run instead of you inspecting every line by hand.
## Karpathy already named the destination
When Andrej Karpathy [introduced "agentic engineering"](https://x.com/karpathy/status/2019137879310836075) in early 2026, he described the new default this way:
> You are not writing the code directly 99% of the time, you are orchestrating agents who do and acting as oversight.
Orchestrating and oversight. Not typing. That is the on-the-loop role stated as a career, not a config setting. And notice what makes it possible: you can only orchestrate work whose target you have defined, and you can only oversee output you have a standard to judge. The word "oversight" quietly assumes there is something to oversee *against*. This is also why [designing the loop itself becomes the real work](/blog/loop-engineering): once you are on the loop, you are no longer the one prompting the agent, you are the one who decided what the agent is checked against.
## The honest trade-off
Moving on the loop is not free, and pretending it is would be the same hype that got people into trouble.
Writing acceptance criteria up front costs time you do not spend when you just prompt and hope. For a throwaway prototype, that cost is not worth it. Vibe code the weekend project. Stay outside the loop entirely on the demo you will delete Monday.
The cost also does not disappear, it moves. On-the-loop supervision means you have to notice when the standard itself is wrong. If the criteria you wrote are incomplete, the agent will satisfy them perfectly and still ship the wrong thing. Being on the loop shifts your job from catching bad code to catching bad definitions of done. That is a better job, and a real one. It is not no job.
And there is a failure mode worth naming: on the loop can decay into outside the loop if you stop watching. The monitor who never intervenes is not supervising, they are absent. The posture only holds if you actually check the evidence.
## What this means for you
If you are building a SaaS product with AI agents right now, your edge is not how fast you can approve things. Approving is the bottleneck you are trying to escape. Your edge is how clearly you can define what good looks like before the agent runs, so that you can step back to the loop's edge and still trust what comes out.
Stay in the loop where a mistake is expensive and hard to undo. Move on the loop everywhere else, but only after you have written the standard the loop gets checked against. The builders who scale with their agents are not the ones who trust more or review more. They are the ones who wrote down what "done" means, so the loop can hold the line when they are not staring at it.
## FAQ
### What is the difference between human in the loop and human on the loop?
Human in the loop means the person sits inside the execution path and approves each action before the agent proceeds, so nothing finalizes without a human decision. Human on the loop means the person sits alongside an agent that runs autonomously within preset limits, monitoring the process and intervening only when something goes wrong. In the loop is direct control per action; on the loop is supervisory control over the whole run.
### When should you use human in the loop vs on the loop?
Use human in the loop for high-stakes, low-volume, hard-to-reverse decisions where the cost of a wrong action is high, such as production database migrations, authentication logic, or payment flows. Use human on the loop for high-volume, lower-stakes, easily reversible work where approving every step would create a bottleneck, such as repetitive endpoints, renames, or test generation. The choice is per task, not a fixed personality, and it depends on the stakes and reversibility of the work.
### What are examples of human on the loop?
Common examples include fraud detection systems that flag transactions for later review, content moderation that auto-removes clear violations while a human monitors edge cases, and coding agents that open pull requests autonomously while a builder reviews the output against a written standard rather than watching each line get typed. In each case the system acts on its own within limits and the human supervises and can override.
### Is human in the loop the same as human oversight?
Not exactly. Human oversight is the broader goal of keeping a person accountable for what AI does. Human in the loop is one way to achieve it, by requiring approval on every action. Human on the loop is another way, by supervising an autonomous system against a defined standard. Oversight can be exercised from inside the loop or from on the loop, and as agents get more capable, more oversight happens on the loop rather than in it.
### How do you move from human in the loop to human on the loop safely?
The safe path is to define your standard before you step back. Write acceptance criteria that state what "done" means, which edge cases must be handled, and what counts as a failure, so the agent's output can be checked against something explicit instead of your memory. Once the standard exists, you can let the agent run autonomously and verify the result against those criteria, intervening when the evidence shows a criterion is unmet. Without a written standard, moving on the loop is really moving outside it.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that turns your idea into a plan with acceptance criteria, builds against it, and proves every change with evidence, so you can move from in the loop to on the loop without losing trust. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Software Development Methodologies in the AI Era: Where Spec-Driven Fits
Source: https://www.braingrid.ai/blog/software-development-methodologies-ai-era
Published: 2026-06-30T12:00:00Z
Every list of software development methodologies you can find right now was written for a world that no longer exists. Search the term and you get the same eight entries in a slightly different order: Waterfall, Agile, Scrum, Kanban, Lean, Feature-Driven Development, DevOps, Spiral. Solid history. None of it accounts for the single biggest change to how software gets built in twenty years.
The methodologies were all designed to answer one question: how do humans coordinate the work of writing code? That question is quietly becoming the wrong one. When an agent writes most of the code, coordinating humans matters less than telling the agent what to build and proving it did. The methodology question moved, and the listicles didn't follow it.
Here is the hypothesis worth testing: every methodology in the canon is an answer to "how do we manage the people writing the code," and the AI era introduces a methodology that answers a different question entirely, namely "what does the agent build against, and how do you know it's done." Spec-driven development is not the ninth item on the list. It is a different kind of item.
## A Short, Honest History of the Methodologies
Take the canon seriously before you argue with it, because each entry solved a real problem of its time.
**Waterfall** came first because hardware was expensive and changes were catastrophic. You gathered every requirement up front, designed the whole system, built it, tested it, then shipped, each phase finishing before the next began. It gets mocked now, but it was rational when a mistake meant re-cutting tape. Its weakness is obvious in hindsight: it assumes you know everything before you start, and you never do.
**Agile** was the rebellion against that assumption. The 2001 manifesto valued working software over comprehensive documentation and responding to change over following a plan. **Scrum** and **Kanban** are the two most common ways teams actually run Agile: Scrum boxes work into fixed sprints with defined roles, Kanban runs a continuous flow with limits on how much is in progress at once. **Lean** borrowed from Toyota's factory floor, eliminating waste and deferring decisions until the last responsible moment.
**Feature-Driven Development** (still a low-difficulty search term, which tells you it never died) organizes everything around a list of small, client-valued features you build one at a time. **DevOps** collapsed the wall between building software and running it, so the team that writes the code also owns the deploy. **Spiral** wrapped the whole thing in repeated risk assessment for projects too large to fail.
Strip away the vocabulary and a pattern shows up. Every one of these is a coordination protocol. Who does what, in what order, with what handoffs, reviewed by whom. They differ on how sequential the phases are and how much ceremony surrounds them, but they share an unspoken premise: the scarce, expensive, error-prone resource is the humans writing the code, so the methodology exists to organize those humans.
That premise held for fifty years. It is the part that broke.
## What Actually Changed
The scarce resource moved. Writing code is no longer the bottleneck, and the people noticing it are not marketers.
Across r/cscareers and r/dataengineering the same line keeps surfacing, said with a mix of awe and grief: ["software is now disposable."](https://www.reddit.com/r/cscareers/comments/1uc8naj) One engineer in the same thread put the new shape of the work precisely:
> "The big picture creative, architectural decisions is what AI excels at. You can regenerate 10 plans in a matter of seconds and pick the best parts of them. AI's weakness is getting details right, making lots of little mistakes."
Read that carefully, because it inverts the entire premise of the canon. The expensive part used to be producing the code. Now you can regenerate ten attempts in the time it takes to read this paragraph. The expensive part is deciding which one is right and confirming it actually works. The bottleneck moved from typing to judgment.
This is why a coordination protocol, on its own, no longer answers the whole question. Scrum can tell you whose sprint a feature belongs to. It cannot tell an agent what "done" means for that feature, and it cannot check the agent's output against your intent. The old methodologies assumed a human on the other end who already knew what good looked like and would catch the mistakes by hand. Hand the same vague ticket to an agent and it will produce something that compiles, demos, and is subtly wrong in a way no sane human would have written. The ceremony around the work is intact. The thing being coordinated changed underneath it.
## The Methodology the Canon Is Missing
Here is the reframe. Spec-driven development is not a better way to coordinate people. It is a way to make intent legible to a machine that will build against it and be checked against it.
A [spec-driven approach](https://www.braingrid.ai/blog/spec-driven-development) answers the two questions the older methodologies never had to: what exactly should the agent build, and how will you know it succeeded. The first is a requirement with enough precision that an agent cannot wander, including the edge cases, the data shape, and the constraints. The second is a set of acceptance criteria, written before the build, that define done as something you can verify rather than something you eyeball.
The difference is concrete. Watch what happens to the same feature under the old frame and the new one.
> **Agile ticket:** "As a user, I want to reset my password so that I can regain access to my account." (Estimated: 3 points. Assigned to a sprint.)
>
> **Spec with acceptance criteria:** "Authenticated and unauthenticated users can request a reset from /login. The system sends a single-use token valid for 30 minutes. Reused or expired tokens show 'This link has expired, request a new one.' On success, all existing sessions are invalidated and the user is redirected to /login with a confirmation banner. Rate limit: 3 requests per email per hour."
The Agile ticket is a coordination artifact. It tells a human which sprint the work lives in and roughly how big it is, then trusts that human to fill in everything that matters. The spec is a build-and-verify artifact. It tells an agent precisely what to construct and gives you a checklist to confirm it did. One organizes people. The other defines done.
Notice what spec-driven development does not replace. You still need Agile's iteration, DevOps's ownership of the deploy, Kanban's limit on work in progress. Spec-driven development is not a rival coordination protocol. It is the missing layer underneath whichever one you already use, the part that survives when the agent, not the engineer, is holding the keyboard. It is also the foundation of what people are starting to call [agentic engineering](https://www.braingrid.ai/agentic-engineering): the practice of running agents against a written standard instead of supervising them line by line.
This is the gap [BrainGrid](https://www.braingrid.ai) was built to close. You describe the feature you want, and the Planning Agent turns it into a requirement with explicit acceptance criteria, asking the questions you didn't think to answer before any code is written. The Builder Agent then builds against that spec, in BrainGrid Cloud or in your own GitHub repo with Claude Code, Cursor, or Codex over MCP. Nothing is marked done until every criterion is verified with evidence. The loop is [Plan, Build, Verify, Repeat](https://www.braingrid.ai/spec-driven-development), and it runs the same way for every feature. You can't verify if you don't have a plan.
## Why the Spec Outlives the Method
The deeper reason spec-driven development belongs on the list is that it changes which artifact is durable.
In the Waterfall era, the durable artifact was the code, and a thick requirements document that mostly went stale on a shelf. In the Agile era, the durable artifact was still the code, plus a backlog of tickets that meant little once closed. In the AI era, the code is the cheap, regenerable, partly-disposable part. The plan and the acceptance criteria are the thing that lasts. They are what let you regenerate the code next month against a better model and still know it does what you intended. They are the record that explains, six months from now, why the system behaves the way it does, when nobody, human or agent, can reconstruct it from the source alone.
That is the test of a real methodology in this era: does it produce an artifact that survives the code? Waterfall's spec was too rigid and too early. Agile threw out the comprehensive document for good reasons that no longer fully apply. Spec-driven development keeps the precision Waterfall wanted and the iteration Agile won, and attaches it to the one thing the older methods treated as disposable: a written, verifiable definition of what you are building and what done means.
Be honest about the trade-off, though. Spec-driven development front-loads work that vibe coding skips entirely. If you are throwing together a weekend prototype or a single-use internal script, writing acceptance criteria first is overkill, and you should just build. The discipline earns its keep the moment the software starts to matter, the moment other people depend on it, the moment "it demos fine" stops being good enough. Vibe tools are fast until your app matters. That is the line where the methodology question becomes real again.
## FAQ
### What are the five software development methodologies?
The five most commonly cited are Waterfall, Agile, Spiral, Rapid Application Development, and Incremental (sometimes listed as iterative). They differ mainly in how sequential versus iterative the phases are: Waterfall finishes each phase before the next, while Agile and incremental approaches build and refine in repeated cycles. Spec-driven development is a newer addition that sits underneath whichever of these you use, defining what the code should do and how to verify it.
### What is a methodology in software development?
A software development methodology is a structured approach for planning, managing, and executing the work of building software. It defines the phases, the order they happen in, who is responsible for what, and how the team handles change. Most classic methodologies were designed to coordinate the humans writing the code. Spec-driven development extends that idea to the AI era by defining what an agent should build and how you confirm it succeeded.
### What are the 7 models of the SDLC?
The software development lifecycle (SDLC) is commonly described with seven models: Waterfall, V-model, Agile, Lean, Iterative, Spiral, and Big Bang. Some lists add Rapid Application Development as well. These are templates for sequencing the lifecycle phases, planning, design, development, testing, deployment, and maintenance, with each model trading off predictability against flexibility.
### What are the four types of Agile methodology?
The four most common Agile frameworks are Scrum, Kanban, Extreme Programming (XP), and Lean. Scrum organizes work into fixed-length sprints, Kanban runs a continuous flow with work-in-progress limits, XP emphasizes engineering practices like pair programming and test-first development, and Lean focuses on eliminating waste. All four share the goal of delivering value iteratively rather than in one large release.
### Where does spec-driven development fit among these methodologies?
Spec-driven development is not a replacement for Agile, Scrum, or DevOps. It is a layer underneath them. The older methodologies coordinate the people doing the work; spec-driven development defines what the agent builds against and how you verify it is done. You keep your existing coordination method and add a precise spec with acceptance criteria for each feature, which is what survives when an agent, not a human, writes most of the code.
*[BrainGrid](https://www.braingrid.ai) is the plan-first app-building platform that plans before it builds, then proves every change against its acceptance criteria. Try it at [braingrid.ai](https://www.braingrid.ai).*
---
# OpenSpec vs Spec Kit vs SuperPowers: Stop Shopping for the Right SDD Tool
Source: https://www.braingrid.ai/blog/stop-shopping-for-spec-driven-development-tools
Published: 2026-06-29T00:00:00Z
A builder on r/SpecDrivenDevelopment recently laid out, carefully and honestly, the difference between SuperPowers, OpenSpec, and Spec Kit. He had clearly done the homework. He could tell you that SuperPowers keeps timestamped specs that accumulate, that OpenSpec merges everything into a single spec artifact, that Spec Kit scaffolds the whole flow. And then he ended with the most honest line in the entire thread:
> "I think we are all still figuring these things out. Sometimes it's best to just dive in and give it a try."
That sentence is the real story of spec-driven development right now. Not which tool wins. The fact that thoughtful, motivated builders are spending their evenings comparing CLIs instead of shipping features, because the tooling layer is moving faster than anyone can keep up with. The shopping has become the work.
Here is the hypothesis worth testing: the tool you pick for spec-driven development matters far less than you think, and the time you spend choosing is mostly wasted, because the practice underneath every one of these tools is identical and that practice is the only durable part.
## The Tools Genuinely Differ (and It Mostly Doesn't Matter)
Let's be fair to the tools first, because they are real and they are good.
[OpenSpec](https://github.com/Fission-AI/openspec) is a lightweight, open-source framework that crossed 27,000 GitHub stars in under six months. Its whole pitch is a minimal three-step loop: propose, apply, archive. Specs live as markdown in your repo, no API keys, no MCP required. Thoughtworks' Technology Radar [praised exactly that](https://www.thoughtworks.com/en-us/radar/tools/openspec) minimalism: "fluid, minimal workflow."
[GitHub Spec Kit](https://github.com/github/spec-kit) is the scaffolding-heavy option. It gives you a structured set of commands and templates that walk you from a specification through a plan to tasks, often generating acceptance criteria in EARS syntax. It is opinionated about the phases.
SuperPowers takes yet another stance: specs are timestamped and accumulate over time, so you get a running history of intent rather than one merged document.
Those are real differences. If you are the kind of person who enjoys this, you can spend a happy weekend comparing them. But notice what you are actually comparing. You are comparing how each tool stores and sequences the same four things: a description of what you want, a plan for building it, criteria for knowing it's done, and a record of decisions. The storage format is the variable. The four things are the constant.
This is the reframe. The spec-driven tools are not competing on whether you should write a spec. They all agree on that completely. They are competing on file layout.
## What Actually Survives
Here is where it gets uncomfortable for anyone deep in tool comparison.
Look at how fast this layer is churning. Latent.Space recently catalogued what they called ["meta-harness summer"](https://www.latent.space/p/ainews-its-meta-harness-summer): Conductor, Zed's ACP, Vercel's Eve, HarnessAgent, Databricks' Omnigent, a new orchestration layer landing seemingly every week. The SDD tools sit one layer down and they are churning just as fast. The tool you carefully chose this month may be unmaintained by spring, or eclipsed by something that didn't exist when you started reading the comparison threads.
So what survives the churn?
Not the tool. The spec.
A requirement that says what you're building and why. The acceptance criteria that define done. The record of decisions that explains, six months from now, why the code is the way it is. Those artifacts are plain text. They outlive any CLI that produced them. You could move them from OpenSpec to Spec Kit to a text file to a different tool entirely, and they would lose nothing, because they were never really about the tool.
Boris Cherny, who reports writing 100% of his Claude Code contributions with Claude Code, [describes his job now as writing loops](https://x.com/sydneyrunkle/status/2066928783534289358) and making sure they can verify themselves. The loop is what he owns. The model is rented. The same logic applies one level up: the spec is what you own, the tool is rented.
Once you see it that way, the comparison shopping looks different. You weren't choosing a methodology. You were choosing a temporary container for the thing that actually matters.
## The Practice Underneath All Three
Strip away OpenSpec, Spec Kit, and SuperPowers entirely, and here is the practice every one of them is trying to encode. It comes down to three habits.
One spec per feature. Not a 40-page document for the whole product, and not a one-line prompt. A focused description of a single buildable thing, scoped tightly enough that an agent can build it and you can check it.
A plan you can review before the agent writes code. The point of planning first is not bureaucracy. It is that catching a wrong assumption in a paragraph costs minutes, and catching it in a generated codebase costs an afternoon. The plan is where you find the questions you didn't think to ask.
Criteria that accumulate. Each feature's acceptance criteria become part of a growing record of what your product is supposed to do. That record is what lets you change things later without breaking what already worked, and it is what tells you, definitively, whether a feature is done or just looks done.
That's it. That is the whole of [spec-driven development](/spec-driven-development), and it is tool-agnostic by definition. The r/SpecDrivenDevelopment poster had actually already figured this out, almost word for word. He described the shared model as "one spec per feature, one plan per spec." He just couldn't tell that he'd found the answer, because the tool comparison was still demanding his attention.
Consider the difference concretely.
Tool-first thinking: "Should I use OpenSpec or Spec Kit? OpenSpec is lighter but Spec Kit has better task templates, though SuperPowers' accumulation model fits how I work, but the community around OpenSpec is bigger right now."
Practice-first thinking: "This feature is 'let users reset their password by email.' Here's what done looks like: a logged-out user requests a reset, gets a one-time link valid for an hour, sets a new password, and the old one stops working. Now which tool helps me build that against those criteria?"
The second builder is going to ship. The first one is going to keep reading comparison threads.
## Where BrainGrid Sits
This is the gap BrainGrid is built to close, and it's worth being precise about how.
The SDD tools hand you a framework and leave you to run it. You install the CLI, learn its commands, wire it into your agent, and remember to follow the steps every time. The practice is sound, but you are assembling and maintaining it yourself, which is exactly the labor the r/SpecDrivenDevelopment thread is full of. (If you want a deeper look at one tool's tradeoffs, we compared [Kiro and BrainGrid's takes on spec-driven development](/blog/kiro-vs-braingrid-spec-driven-development) and where each fits.)
BrainGrid ships the practice as a product instead of a framework. You describe a feature, and the Planning Agent turns it into a requirement with acceptance criteria, data models, and designs, challenging the vague parts and asking the questions you didn't think of before any code is written. That is "one spec per feature, one plan per spec," done for you rather than configured by you. Then the Builder Agent builds it, two ways: in BrainGrid Cloud, a sandbox with live preview that opens a pull request, or on your own computer in your GitHub repo with Claude Code, Cursor, or Codex over MCP. Whichever agent you point at it, the plan and the criteria are the same. Every feature flows across a board from planning to building to published, and the specs, decisions, and verifications accumulate into a record of the product. Swap the agent, swap the model, keep the workflow.
The structural point is the same one the tools are trying to deliver, just without the assembly: the spec is the durable asset, and a feature isn't done until the evidence says it matches what you intended. You don't pick a file format and hope you maintain the discipline. The discipline is the product.
## The Honest Trade-Off
There is a real cost here, and it cuts against BrainGrid as much as it favors it.
If you love your tools, an open-source framework like OpenSpec gives you total control over every file and every step. You own the whole stack. Some builders genuinely want that, and for them the comparison shopping is not waste, it's craft. A managed product trades that control for the thing being done for you. That is a real choice, and it's not the right one for everyone.
But for most builders, and certainly for the ones writing "we are all still figuring these things out," the control isn't the point. Shipping is the point. (If you're specifically weighing the open-source frameworks, our [BrainGrid vs Spec Kit comparison](/braingrid-vs-spec-kit) walks the tradeoff in detail.) And the truth the tool-comparison threads obscure is that you can start practicing spec-driven development today, in any tool, the moment you write one tight spec with real acceptance criteria for the next feature you build. You do not need to finish the research first.
## FAQ
### What is OpenSpec?
OpenSpec is a lightweight, open-source spec-driven development framework for AI coding agents. It stores specifications as markdown in your repo and runs a minimal three-step loop, propose, apply, archive, with no API keys or MCP required. It is one of several tools (alongside GitHub Spec Kit and SuperPowers) that help you write a spec before your coding agent writes code. The framework differs from the others mainly in how it stores and sequences specs, not in the underlying practice.
### What is the difference between OpenSpec and Spec Kit?
OpenSpec is minimal and merges work into a single evolving spec artifact through a propose-apply-archive loop. GitHub Spec Kit is more scaffolding-heavy, giving you structured commands and templates that walk you from a specification through a plan to tasks, often in EARS syntax. The practical difference is file layout and how opinionated each is about the phases. Both encode the same core practice: one spec per feature, a reviewable plan, and acceptance criteria that define done.
### Which spec-driven development tool is best?
There is no single best tool, and the choice matters less than most comparison threads suggest. OpenSpec, Spec Kit, and SuperPowers all encode the same practice and differ mainly in how they store and sequence specs. The better question is whether you are actually practicing spec-driven development: writing one focused spec per feature, reviewing a plan before the agent codes, and keeping acceptance criteria that accumulate. Any of the tools can support that. So can a managed product like BrainGrid, which ships the practice rather than a framework you assemble.
### Do I need a tool to do spec-driven development?
No. Spec-driven development is a practice, not a tool. You can start today by writing one tight spec for your next feature, including specific acceptance criteria for what "done" means, then building against it and checking the result. The tools (OpenSpec, Spec Kit, SuperPowers) automate and structure that habit, and a product like BrainGrid runs the whole loop for you, but the practice itself works in a plain markdown file. The durable asset is the spec, not the software that produced it.
### Why does spec-driven development matter for AI coding agents?
Because a vague prompt is a confident mistake machine. When an agent writes most of the code, the bottleneck stops being typing speed and becomes clarity: how precisely you describe what you want and how done is defined. A spec gives the agent a target and gives you a way to verify the result against acceptance criteria instead of reading every line. As agents get more autonomous, this matters more, not less, because more autonomy means more decisions nobody wrote down unless the spec captured them.
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that ships the spec-driven practice as a product: it plans each feature into acceptance criteria, builds with your choice of agent, and verifies every change with evidence, so you stop shopping for tools and start shipping. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Definition of Done for AI Builders: The Quality Bar Every Agent Build Must Clear
Source: https://www.braingrid.ai/blog/definition-of-done-for-ai-builders
Published: 2026-06-28T12:00:00Z
Your agent will tell you it is done. It will say so confidently, with a green checkmark, a passing demo, and a tidy summary of what it built. And it will be wrong often enough that "the agent said done" has quietly become the most expensive phrase in AI building. The problem is not that the agent lies. The problem is that nobody told it what done means, so it picked its own definition, and its definition is "the happy path runs."
For most of software history, that gap was covered by a team. A developer finished a feature, but "finished" was understood to include tests, a review, and a deploy, because the team shared an unwritten standard. Now the developer is an agent that has no unwritten standards and no shared anything. It has whatever you wrote down, and it fills the rest with the shortest path to something that looks complete. So here is the hypothesis this post rests on: the more of your building an agent does, the less you can rely on a shared sense of "done," and the more you need that standard written down as one explicit, every-feature bar. That bar has a name. It is your definition of done.
## What a definition of done actually is
The term comes from agile, and the agile definition is worth keeping because it is clean. A definition of done is a shared set of conditions a piece of work must satisfy before anyone calls it complete. Scrum.org puts it as a formal description of the state of the work when it meets the quality required for the product. The key word is "shared." It is not per-feature. It is the standing bar that applies to every feature, the checklist that is true whether you are shipping a login screen or a billing page.
That makes it different from the thing it gets confused with. Acceptance criteria answer "is this the right thing," feature by feature. The definition of done answers "is it built to standard," every time. A login feature's acceptance criteria might say a wrong password shows an error. Your definition of done says, for that feature and all the others, that the tests pass, the change was verified against its criteria, and it works in a real environment, not just a demo. One is specific to the feature. The other is the bar underneath all of them. You need both, and we go deep on the per-feature half in [how to write acceptance criteria an AI agent can verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify). This post is about the standing bar.
Strip away the agile vocabulary and the idea is older than software. A definition of done is just the answer to a question every builder has always had to answer: when do I get to stop. The answer used to live in people's heads. It cannot anymore.
## Why AI builders need one more than anyone
Here is the part that surprises people. Definition of done is treated as a process nicety, a thing mature teams have and small teams skip. For AI building, it is the opposite. The smaller and faster your operation, the more you need it, because the agent is moving faster than your ability to catch what it skipped.
Consider the line from the [apimatic team's writeup](https://www.apimatic.io/blog/agentic-engineering-claude-code) on moving from vibe coding to agentic engineering with Claude Code:
> "It should work correctly" is not a criterion.
That is the whole problem in five words. To you, "it should work correctly" is obviously the bar. To an agent, it is noise, because nothing in it is checkable. The agent cannot run "correctly." It can run a test, hit an endpoint, render a page. When your standard is a feeling and the agent only understands facts, the agent ships the version that matches the facts it can see and silently drops everything else. A definition of done is how you translate your felt standard into facts the agent, and you, can actually check.
The stakes scale with autonomy, which is exactly why this gets worse as the models get better. Addy Osmani, talking about the loop-driven way agents now work, made the point cleanly when [The Register pushed back](https://www.theregister.com/ai-and-ml/2026/06/24/loop-engineering-latest-ai-buzzword-still-needs-humans-in-the-loop/) on the whole idea:
> The loop changes the work, it does not delete you from it. The agent runs more of the loop unattended every month. The work that does not disappear is deciding what the loop is allowed to call finished. A definition of done is that decision, written once, applied to every run.
## What goes in it (and what does not)
A good definition of done for AI building is short, concrete, and the same for every feature. It is not the feature spec. It is the floor. Here is the difference between a standard an agent can clear and a wish it cannot.
> The wish: "The feature should be done, tested, and ready for users."
>
> The standard: "Every acceptance criterion is verified with evidence. Automated tests for the new behavior pass. The change runs in a real preview environment, not just locally. Inputs that should fail (empty, wrong, malformed) are handled, not just the happy path. Nothing that worked before is broken."
The first one feels complete and checks nothing. The second one is five facts, each of which is either true or false for any feature you build. An agent can be pointed at the second list. You can read down it at the merge button. Neither of you has to interpret a mood.
Notice what is not on it. There is no business logic, no "the report should show monthly revenue," no feature detail at all. That belongs in the acceptance criteria for that one feature. The definition of done is deliberately generic, because its job is to be the one bar that holds no matter what you are building. The moment it starts describing a specific feature, it has stopped being a definition of done and become a spec.
Here is how the two layers sit together across a build.
```mermaid
flowchart LR
A[Idea] --> B[Acceptance criteria is it the RIGHT thing?]
B --> C[Agent builds]
C --> D[Definition of done is it built to STANDARD?]
D -->|all clear| E[Merge / ship]
D -->|gap found| C
```
Acceptance criteria gate the front of the build: are we building the right thing. The definition of done gates the back: is what got built allowed to be called finished. An agent that passes the first and fails the second has built the right feature badly, which is the single most common way AI work looks done and isn't.
## The trap, and the honest limit
The failure mode to name out loud is the demo. An agent produces something that runs in front of you, and a running demo is the most persuasive evidence there is and the least reliable. The demo is the happy path the agent was always going to nail. Your definition of done exists to ask the questions the demo never does: what happens with bad input, what broke upstream, is there a single shred of evidence beyond "it looked fine when we clicked it." Approving because the demo worked is approving the eighty percent and inheriting the missing twenty.
And the honest limit, because pretending otherwise would be its own kind of hype. A definition of done is a floor, not a ceiling. It catches the predictable, repeatable gaps, the missing tests, the unhandled error, the broken neighbor. It will not catch a subtle security flaw or a design decision that is technically "done" and strategically wrong. For a personal project, a strong definition of done plus behavioral review is genuinely enough to ship with confidence. For anything touching real user data or money, you still want a deeper technical pass on top. The bar raises your floor a lot. It does not replace judgment about which floor you need.
## How to make the bar enforce itself
A definition of done that lives in your head, or in a doc nobody opens, is the same as not having one. The whole value is that it gets checked, every feature, without you remembering to. That is the gap between knowing the standard and having it hold.
This is where [BrainGrid](https://braingrid.ai) fits, and it sits on both sides of the build. When you describe a feature, the Planning Agent turns it into a requirement with explicit acceptance criteria, so the per-feature "right thing" is written down before any code exists. When the Builder Agent builds it, in [BrainGrid Cloud](/spec-driven-development) with a live preview or in your own repo with [Claude Code, Cursor, or Codex](/ai-coding-agents), verification checks the result against every one of those criteria and reports the evidence, so "verified against its criteria" stops being a hope you have to police and becomes a step that runs on every feature. That is the standing bar made automatic: the same check, every build, with proof attached. It is the Verify step of the loop, Plan, Build, Verify, Repeat, and it is what turns "the agent said done" into "here is the evidence it is done."
So here is the verdict on the hypothesis. The faster your agent moves, the less a shared sense of done can be assumed and the more it has to be written, because the one thing an autonomous builder cannot supply is its own standard for stopping. Write the bar once. Make every feature clear it. The code got cheap and fast. The decision about what counts as finished is still yours, and it is more load-bearing than it has ever been.
## FAQ
### What is the definition of done in code?
In code, the definition of done is the standing set of conditions a change must meet before it can be merged or shipped, applied to every feature rather than written fresh each time. Typical conditions are: automated tests for the new behavior pass, the change was verified against its acceptance criteria, it runs in a real environment and not just locally, error and edge cases are handled, and nothing that previously worked is broken. It is deliberately generic. The feature-specific requirements live in the acceptance criteria; the definition of done is the quality floor that holds regardless of which feature you built.
### What is the difference between definition of done and acceptance criteria?
Acceptance criteria are specific to one feature and answer "did we build the right thing": a wrong password shows an error, the report totals monthly revenue, and so on. The definition of done is generic and answers "is it built to standard": tests pass, criteria were verified, it deploys, edge cases are handled. Acceptance criteria change with every feature. The definition of done stays the same across all of them. You need both, because a feature can satisfy its acceptance criteria (right thing) and still fail the definition of done (built badly, no tests, breaks something else).
### What is DoR and DoD in agile?
DoR is the Definition of Ready and DoD is the Definition of Done. The Definition of Ready is the bar a piece of work must clear before anyone starts building it, usually meaning it is clear, scoped, and has acceptance criteria. The Definition of Done is the bar it must clear before anyone calls it complete. For AI builders the pair maps neatly onto the loop: readiness is whether the plan is good enough to hand to the agent, and done is whether what the agent produced is good enough to ship. Both exist to stop guessing, one at the start, one at the end.
### What does "done" mean in software?
In software, "done" means a change meets every condition the team agreed defines completeness, not just that it appears to work. That usually includes the feature behaving as specified, automated tests passing, the change reviewed or verified, and it deploying to a real environment without breaking existing behavior. The reason teams write this down as a definition of done is that "done" otherwise means something slightly different to everyone, and an AI agent has no shared sense of it at all. Without an explicit standard, "done" collapses into "the demo ran," which is the weakest possible bar.
### Do small teams or solo builders really need a definition of done?
Yes, and arguably more than large teams do. A big team has reviewers, QA, and shared habits that catch skipped steps even when nothing is written down. A solo builder shipping through an agent has none of that backstop, and the agent moves faster than any one person can manually inspect. A short, explicit definition of done is the fastest way to get a quality floor without a team: five or six conditions, the same for every feature, that the agent is held to and you can read at the merge button. It takes minutes to write and prevents the most common and most expensive AI failure, shipping something that looked done and wasn't.
*[BrainGrid](https://braingrid.ai) plans every feature into acceptance criteria and verifies each change against them with evidence, so "done" stops being the agent's opinion and becomes a bar you can prove. Try it at [braingrid.ai](https://braingrid.ai).*
---
# GitHub Spec Kit Tutorial: Spec-Driven Development in an Existing Project
Source: https://www.braingrid.ai/blog/github-spec-kit-tutorial-existing-project
Published: 2026-06-27T00:00:00Z
Most GitHub Spec Kit tutorials start from an empty folder. That is the easy case, and it is not the one you have. You have a codebase. It has conventions nobody wrote down, a half-finished refactor, and a feature you shipped last month that the next feature has to respect. The empty-folder demo never shows you what happens when Spec Kit meets all of that.
That gap is the whole reason this tutorial exists. Spec Kit is a genuinely good toolkit, and the idea underneath it is correct: write a structured spec before you let an agent write code. GitHub open-sourced it in September 2025 and it crossed 100,000 stars faster than almost any developer tool in recent memory. But the README's quickstart assumes a greenfield project, and the real builders trying to adopt it are not greenfield. One developer on r/SpecDrivenDevelopment recently laid out, earnestly, the difference between SuperPowers, OpenSpec, and Spec Kit and ended with a line that has become the unofficial motto of this whole space:
> "I think we are all still figuring these things out. Sometimes it's best to just dive in and give it a try."
So let's dive in, on a project that already exists. Here is the hypothesis we are going to test: Spec Kit makes spec-driven development concrete and approachable, and the moment you run it on a real codebase, you find the exact line where a per-run toolkit ends and a durable system has to begin.
## What GitHub Spec Kit Actually Is
Spec Kit is a command-line tool, written in Python, that installs a spec-driven workflow into your project. You run it through an agent you already use. It works with Claude Code, Cursor, GitHub Copilot, Codex, Gemini CLI, and roughly 30 other agents, because it does not replace your agent. It gives your agent a sequence of slash commands and a set of templates that turn "build me a thing" into a reviewable plan.
The whole method is six commands, run in order:
```bash
/speckit.constitution # the project's non-negotiable rules
/speckit.specify # what you're building, in plain English
/speckit.clarify # the agent asks questions to kill ambiguity
/speckit.plan # the stack and architecture
/speckit.tasks # a dependency-ordered task list
/speckit.implement # the agent finally writes code
```
That ordering is the entire point. As Den Delimarsky, who maintains the project, frames it, Spec Kit is about making the intent explicit before the implementation exists. Akshay Pachaar put the cultural read on it more bluntly when the repo took off:
> "The core idea: write a structured spec before you prompt your AI coding agent."
Notice what is missing from a normal AI coding session: the questions. In a vibe-coding loop you prompt, eyeball the output, and prompt again. Spec Kit inserts `/speckit.clarify` specifically to make the agent ask you what it does not know before it guesses. That single step is the difference between an agent that builds what you meant and one that builds what it assumed.
## Installing Spec Kit in a Repo That Already Has Code
Here is where the existing-project case diverges from every quickstart. Install the CLI the same way:
```bash
uv tool install specify-cli --from git+https://github.com/github/spec-kit.git
```
Then, from inside your existing repository, initialize Spec Kit in place rather than scaffolding a new directory:
```bash
specify init --here --integration claude
```
The `--here` flag is the one the greenfield tutorials skip. It tells Spec Kit to lay its `.specify/` directory, templates, and agent command files alongside your code instead of in a fresh folder. Swap `--integration claude` for `cursor`, `copilot`, `gemini`, or whichever agent you run. Your code is untouched. What you have added is a workflow, not a rewrite.
This is also the first moment the existing-project case gets interesting, because Spec Kit now knows nothing about the code it is sitting next to. The constitution is where you fix that.
## Writing a Constitution for Code That Already Exists
The constitution is Spec Kit's most underrated command and the one that matters most in a brownfield project. In a new project, the constitution is aspirational: here is how we intend to build. In an existing project, the constitution is archaeological: here is how this codebase already works, and the agent must respect it.
Run `/speckit.constitution` and describe the rules your code already lives by. A weak constitution reads like a wish list. A strong one reads like a description of reality.
Vague: "Write clean, well-tested code with good architecture."
Concrete: "API routes live in `src/app/api` and return typed responses via the `ApiResponse` helper. Database access goes through the repository classes in `src/db/repositories`, never raw queries in route handlers. All new tables use `snake_case` columns and include `created_at` and `updated_at`. Tests use Vitest and live next to the file they cover. Auth is checked with `requireSession()` at the top of every protected route."
The second one is what stops your agent from inventing a parallel pattern next to the one you already have. The number one failure mode of AI on an existing codebase is not bad code. It is plausible code that ignores your conventions: a second auth helper, a fourth way to fetch data, a state pattern that fights the three already there. The constitution is the document that prevents it, and `spec kit constitution example` is one of the most-searched queries about the tool for exactly this reason. People feel the gap.
## The Specify-to-Implement Loop on a Real Feature
Now the working part. Say your existing app has user accounts and you want to add team invitations. You do not describe the whole app. You describe the one feature, and you let Spec Kit's structure carry it from sentence to code.
```bash
/speckit.specify Add team invitations. An account owner can invite a teammate by email.
The invite expires after 7 days. The teammate accepts via a link and joins with a "member"
role. Owners can see pending invites and revoke them.
```
Then `/speckit.clarify`, where the agent surfaces the questions a vague prompt would have buried: what happens if the email already has an account, can a member invite other members, what is the role hierarchy. You answer those once, in writing, and they become part of the spec instead of a surprise in the diff.
`/speckit.plan` is where you tell it the stack, and on an existing project this is where the constitution earns its keep: the plan should reuse your repository classes, your auth helper, your table conventions, not invent new ones. `/speckit.tasks` breaks it into a dependency-ordered list. `/speckit.implement` builds it, task by task.
Here is the before-and-after that makes the case. Without Spec Kit, "add team invitations" to an existing app is a single prompt and a roll of the dice, and the agent's first guess about your role model is probably wrong. With Spec Kit, the same feature arrives as a spec you reviewed, a plan that respects your conventions, and a task list you can check off. The work is the same size. The number of times you regenerate it from scratch is not.
```mermaid
flowchart LR
A[Idea: team invitations] --> B[/speckit.specify/]
B --> C[/speckit.clarify/]
C --> D[/speckit.plan/]
D --> E[/speckit.tasks/]
E --> F[/speckit.implement/]
F --> G{Does it meet the spec?}
G -->|verify| H[Merge]
G -->|gap| B
```
## Where Spec Kit Stops
Now the honest part, because a tutorial that only sells the tool is not a tutorial. Run Spec Kit on a real project for a week and you find its edges.
The first edge is that it is per-run. Spec Kit is brilliant inside a single feature. It is quiet about the relationship between features. Your team-invitations spec does not know your billing spec exists, and next month when you build seat-based billing, nothing connects the two. The specs are files in a folder. They do not accumulate into a model of your product unless you build that yourself. Builders feel this immediately: one r/GithubCopilot thread is titled, plainly, "Spec-driven development with Spec-Kit is eating my tokens alive," because re-establishing context every run is expensive when the context does not persist.
The second edge is verification. Spec Kit gets you a spec, a plan, and tasks. What it does not give you is proof that the implementation actually did what the spec said. `/speckit.implement` ends when the code is written, not when the acceptance criteria are demonstrated. That last step, the one where someone confirms the invite really does expire after 7 days and a revoked invite really is dead, is left to you. On a one-person demo that is fine. On anything you ship, that gap is where the trouble lives.
The third edge is reach. Spec Kit lives in the terminal, behind a CLI, run through a coding agent. That is perfect for the engineer on your team. It is a closed door for the non-technical co-founder who actually knows what "done" means for the invitations feature, and who will never run `uv tool install` to weigh in.
None of these are bugs. They are the natural boundary of a per-run toolkit. Spec Kit is a method made concrete, and a method has to stop somewhere.
## What Has to Begin Where Spec Kit Ends
The boundary Spec Kit hits is the same one every spec-driven workflow hits eventually: a spec is only as valuable as the system that keeps it, connects it, and checks it. This is exactly the seam [BrainGrid](https://braingrid.ai) is built for, and it picks up where the per-run toolkit leaves off.
BrainGrid runs the same shape of loop, Plan to Build to Verify to Repeat, but the spec is not a file you regenerate each run. You describe the feature, and the Planning Agent turns it into a requirement with acceptance criteria, in the web app, where your non-technical co-founder can read and edit it too. That requirement persists. When you build the next feature, the previous ones are still there as context, so your billing work knows your invitations work happened. Then the Builder Agent builds it, either in a BrainGrid-managed sandbox with a live preview, or self-managed in your own GitHub repo through MCP, driving Claude Code, Cursor, or Codex against the plan. And the part Spec Kit hands back to you, verification, is the part BrainGrid treats as the definition of done: a feature is not finished until every acceptance criterion is checked with evidence.
So the honest framing is not Spec Kit versus BrainGrid. It is Spec Kit teaching you the discipline, and BrainGrid being the place that discipline lives once one feature becomes fifty. If you want the full structural comparison, we wrote it up at [BrainGrid vs Spec Kit](https://braingrid.ai/braingrid-vs-spec-kit).
## What This Means If You're Adopting Spec Kit Right Now
If you are a solo builder or a small team adding Spec Kit to an existing codebase this week, here is the concrete read. Start with the constitution, and spend real time on it, because on a brownfield project the constitution is the single thing standing between you and an agent that quietly forks your conventions. Use `/speckit.clarify` every time and answer the questions in writing, because that is where the spec actually gets its value. And go in knowing the two things Spec Kit will hand back to you: the connective tissue between features, and the proof that each feature met its criteria. Those are the two jobs you own.
The deeper point survives even if you never touch Spec Kit. Spec-driven development is not really about a CLI. It is about deciding, in writing, what "done" means before an agent guesses. As Boris Cherny, who reports writing nearly all of his Claude Code contributions with Claude Code, [put it](https://x.com/sydneyrunkle/status/2066928783534289358), his job now is to write loops that can verify themselves. Spec Kit is one good way to start writing those loops. The question that decides everything after that is whether your specs are a pile of files or a system that remembers.
## FAQ
### How do I use GitHub Spec Kit in an existing project?
Install the CLI with `uv tool install specify-cli --from git+https://github.com/github/spec-kit.git`, then run `specify init --here --integration claude` from inside your repository. The `--here` flag installs Spec Kit alongside your existing code instead of scaffolding a new folder. Then run `/speckit.constitution` first and describe the conventions your codebase already follows, so the agent respects your existing patterns instead of inventing new ones.
### What are the GitHub Spec Kit commands?
There are six, run in order: `/speckit.constitution` sets the project's non-negotiable rules, `/speckit.specify` describes what you're building in plain English, `/speckit.clarify` makes the agent ask questions to remove ambiguity, `/speckit.plan` defines the stack and architecture, `/speckit.tasks` generates a dependency-ordered task list, and `/speckit.implement` writes the code last.
### What is a Spec Kit constitution?
The constitution is the file that holds your project's durable rules, the standards every spec and plan must respect. In a new project it describes how you intend to build. In an existing project it should describe how the codebase already works: where files live, which helpers to reuse, naming conventions, how auth and data access are handled. A concrete constitution is what stops an agent from forking your existing patterns.
### Does GitHub Spec Kit work with Claude Code and Cursor?
Yes. Spec Kit is agent-agnostic and works with Claude Code, Cursor, GitHub Copilot, Codex, Gemini CLI, and roughly 30 other agents. You choose the agent at init time with the `--integration` flag, and Spec Kit installs the matching slash commands. It augments your agent rather than replacing it.
### Is GitHub Spec Kit free?
Yes. Spec Kit is an open-source toolkit released by GitHub, free to install and use. Your only costs are the usual ones: the model usage your coding agent consumes when it runs the spec, plan, and implement steps.
### What is the difference between Spec Kit and BrainGrid?
Spec Kit is a per-run, CLI-based toolkit that produces a spec, plan, and tasks for one feature at a time inside your terminal. BrainGrid is a system where specs persist and connect across features, accessible in a web app so non-technical teammates can write and review them, with verification against acceptance criteria built into the definition of done. Spec Kit teaches the discipline; BrainGrid is where that discipline lives as a project grows.
*[BrainGrid](https://braingrid.ai) is the system that takes an idea to a live product you can trust, with specs that persist and verification built into done. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Is Vibe Coding Good? An Honest Answer (Great Start, Bad Finish)
Source: https://www.braingrid.ai/blog/is-vibe-coding-good
Published: 2026-06-26T12:00:00Z
Vibe coding is good at the exact thing that makes it look dangerous, and dangerous at the exact thing that makes it look good. It will take you from an empty folder to a working screen faster than anything in the history of software. That speed is real. It is also the reason people get hurt, because the same flow that gets you to a demo in an afternoon quietly carries you past the point where you understand what you built.
So is vibe coding good? The honest answer is yes, and then no, and the order matters. It is a great start and a bad finish. If you only ever ask the question once, you will get the wrong answer, because the answer changes depending on which afternoon you are standing in: the one where you are sketching an idea, or the one three months later where the thing you depend on breaks and neither you nor the AI can say why. This post is the line between those two afternoons, drawn as clearly as I can draw it.
## What vibe coding is actually good at
Start with the part that is genuinely great, because pretending otherwise is the fastest way to lose a reader who has felt how good it can be. You describe what you want in plain English, the agent writes the code, and you iterate together until something runs. Andrej Karpathy [coined the term](https://x.com/karpathy/status/1886192184808149383) for the version where you "fully give in to the vibes" and "forget that the code even exists." For a certain kind of work, that is not reckless. It is correct.
If you are sketching an idea, building a landing page, wiring up a throwaway internal script, or learning how a framework fits together, vibe coding is the best tool that has ever existed for the job. It flattens the learning curve to nearly nothing. It lets a non-engineer hold a real artifact in their hands in an hour instead of a quarter. Google's own AI Overview on this exact question lands in the same place: vibe coding is "incredibly good for rapid prototyping and side projects." Nobody serious disputes the start. The disputes all begin at the finish. (If you are still picking a tool, we [tested and ranked the best vibe coding tools for 2026](/blog/best-vibe-coding-tools-2026).)
## Where it stops being good
Here is the reframe, and it is the whole post. Vibe coding does not fail because the code is bad. It fails because the intent was never written down.
Watch what happens at the three-month mark. The Red Hat Developer team, in a piece bluntly titled [The uncomfortable truth about vibe coding](https://developers.redhat.com/articles/2026/02/17/uncomfortable-truth-about-vibe-coding), describes the wall: because you built the app without explicit specifications, the architecture becomes muddled, and neither you nor the AI can map out exactly how the system interacts anymore. The code runs. What it does, and why it does it that way, is gone. A novice building in public put the same fear in plainer words on r/vibecoding: ["if at some point this context deviates from the truth of your product, the AI will start getting confused, you are creating debt."](https://www.reddit.com/r/vibecoding/comments/1ucd7u1) They were right, and they were describing the exact mechanism.
The reason this happens is structural, not a skill issue. When you vibe code, the only record of what the app is supposed to do lives in two places: the running code, and the conversation you had with the agent. The conversation evaporates. The code remains, but code tells you what the software does, never what it was supposed to do or which behaviors are load-bearing. So when you come back to change one thing, you and the agent are both reverse-engineering your own product from its output. That is the lost-intent problem, and no model upgrade fixes it, because the missing thing was never in the model. It was supposed to be in a document you never wrote.
## "Software is now disposable" is true, until it isn't
You can feel this debate hardening into a belief right now. Across r/cscareers and r/dataengineering the same line keeps recurring, said with a mix of awe and grief: ["Software is now disposable."](https://www.reddit.com/r/cscareers/comments/1uc8naj) And for a huge amount of what gets vibe coded, that is simply true. A demo is disposable. A prototype is disposable. The script you wrote to clean one CSV is gloriously disposable, and treating it like a maintainable system would be the actual mistake.
The trap is letting the disposable case set the standard for everything. The moment software starts mattering, the moment real people depend on it, their data lives in it, your business runs on it, disposability flips from a feature to the bug. That is the line. Vibe coding is good precisely up to the point where the thing you are building stops being disposable. One afternoon past that line, the same workflow that felt like a superpower becomes a liability you cannot see into.
> "It should work correctly is not a criterion."
That line, from APIMatic's [Vibe Coding to Agentic Engineering](https://www.apimatic.io/blog/agentic-engineering-claude-code) piece, reframes the entire good-or-bad question. The difference between vibe coding that ships and vibe coding that collapses was never the tool, the model, or the prompt. It is whether anyone ever wrote down what "correct" means for this specific thing, in terms a human or an agent could actually check. Vibe coding skips that step by design. That is what makes it fast, and that is what makes it fail.
## What changes if you are building something real
If you are using Cursor, Lovable, Claude Code, or Replit to ship a product people will pay for, here is the concrete implication. Your first two features will feel incredible. Your third or fourth feature is where it breaks, not because the AI got worse, but because it is now editing a system it cannot fully see, with no record of which behaviors it must not break. You will spend afternoons chasing regressions in features you finished last week. The speed you fell in love with starts working against you. We wrote a whole post on [why your AI agent keeps breaking things that worked](/blog/why-ai-keeps-breaking-things-that-worked); the short version is that nothing ever told it what "still working" means.
The fix is not to stop vibe coding. The fix is to give the work the one thing the vibe never produced: a written definition of what done means, before the agent builds. Compare the two inputs directly.
> Vibe: "Build me a dashboard with user login."
>
> Captured: "Build a user dashboard. Only authenticated users can access it; unauthenticated users redirect to /login. Show the user's name, plan tier, and last login date, read from the existing user object without changing its shape. The login flow built earlier must keep working unchanged."
The second one is not slower to think of. It is the same idea, written down so it survives the conversation and so anyone, human or agent, can verify the result against it. That written record is the difference between a start and a finish.
This is the gap BrainGrid is built to close. You describe the feature you want, and BrainGrid's Planning Agent asks the questions you would have skipped, then turns your idea into a requirement with explicit acceptance criteria: the conditions that have to be true for the feature to count as done. From there you can build in BrainGrid's managed sandbox with a live preview, or in your own GitHub repo with Claude Code, Cursor, or Codex over MCP. Either way, the Builder Agent works against the spec, and a feature is not finished until every criterion is verified with evidence. The loop is Plan, Build, Verify, Repeat. Vibe coding is that loop with the Plan and Verify steps deleted. Put them back, and you keep the speed of the start without the three-month wall.
## So, is vibe coding good?
Yes, for getting started, and no other answer survives contact with the evidence. It is the best on-ramp software has ever had and the worst place to leave a product you depend on. The skill is not choosing between vibe coding and "real" engineering. The skill is knowing which afternoon you are in, and writing down what done means before the thing you are building stops being disposable. Keep the vibe for the start. Capture the intent for the finish. If you want the tools that make the start as good as possible, start with our guide to [vibe coding tools](/vibe-coding-tools).
## FAQ
### Is vibe coding actually any good?
For the right job, yes. Vibe coding is excellent for prototypes, landing pages, throwaway scripts, learning, and getting a real artifact in your hands fast. It stops being good when the project has to be maintained, because it skips the step of writing down what the software is supposed to do, and that missing record is what makes long-lived vibe-coded projects collapse.
### What is the downside of vibe coding?
The core downside is lost intent. Because you build without explicit specifications, the architecture gets muddled and, around the three-month mark, neither you nor the AI can reconstruct how the system fits together or why it was built that way. Secondary downsides follow from it: regressions in features that used to work, security gaps nobody specified against, and a codebase you cannot safely change.
### Why do vibe coders fail?
They usually fail at the finish, not the start. The same speed that makes the first demo feel effortless carries them past the point of understanding their own product. With no written definition of "correct," every change becomes reverse-engineering, the agent breaks load-bearing behavior it could not see, and the project hits a wall it cannot climb without rebuilding. The failure is missing intent, not a missing skill.
### Is vibe coding good or bad for beginners?
It is a great learning tool if you use it as one. Ask the agent to explain the code it writes, break things on purpose to see what happens, and treat each project as a chance to understand the system rather than just ship it. It turns bad for beginners only when they lean on it to avoid ever understanding the result, which is exactly when a working demo gets mistaken for a finished product.
### Has anyone made money with vibe coding?
Yes, mostly at small scale and mostly for simple products. The pattern people report is consistent: the technical part was the easy part, and the real work was everything around it, like distribution, support, and keeping the thing running as it grew. That last part, keeping it running, is where the lost-intent problem shows up, and where a written spec starts paying for itself.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that captures what "done" means before your agent builds, so vibe coding keeps its great start and gains a finish you can trust. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Every Software Factory Needs a Planning Floor
Source: https://www.braingrid.ai/blog/every-software-factory-needs-a-planning-floor
Published: 2026-06-25T12:00:00Z
Build a factory that runs itself and you would expect the output to get more reliable, not less. With software factories, the opposite keeps happening. The faster and more autonomous the line gets, the more spectacular the misses become, because a fast line pointed at a vague target just produces the wrong thing at scale.
The reason is unglamorous. Every software factory automates the floor that turns a requirement into shipped code. That throughput is the part most teams optimize, and it is worth getting right, but a faster line is [not the same as a more trustworthy one](/blog/product-factory-vs-software-factory). Almost none of them automate the floor that turns a fuzzy idea into a precise requirement. That second floor barely exists in most setups, and it is the one that decides whether all the autonomy downstream helps you or quietly works against you.
Call it the planning floor. It is the part of the factory nobody is building, and it is the part that matters most.
## The factory got automated from the wrong end
Look at how the term is being used right now and you can watch the gap form in real time. Factory.ai just shipped [Factory 2.0](https://factory.ai/news/software-factory), pitching autonomous Droids that triage a signal, plan it, code it, review it, test it, ship it, and monitor it. Chamath, describing [8090's software factory](https://x.com/chamath/status/2067987920653582463), was unusually honest about where the hard part lives:
> We first help write requirements, expand and frame dependencies and then execute with a more global knowledge of the problem.
Read that order again. Requirements first, dependencies framed, then execute. The execution is the easy half to automate, and it is the half everyone demos. The requirements-and-framing half is the planning floor, and it is the half that actually determines whether the global knowledge of the problem is correct or confidently wrong.
Simon Willison's [survey of the model](https://simonwillison.net/2026/Feb/7/software-factory/) lays out a ladder of automation that most teams climb: assisted, where AI is glorified autocomplete; supervised, where an agent drives and humans manage exceptions; and autonomous, where specs and scenarios drive agents that converge without human review. Notice that the top of the ladder is defined by specs and scenarios. The whole autonomous dream rests on the quality of the input. Climb the ladder without building the floor that produces good input, and you have automated the journey from a bad spec to a shipped mistake.
## The hypothesis: input quality is the new bottleneck
Here is the claim the rest of this rests on. The more autonomous your software factory becomes, the more its output quality is bounded by the quality of what enters the line, and the less anyone is watching that entry point. Speed at the execution stage does not relax this constraint. It tightens it, because a faster line spends your vague requirement faster and in more places before anyone notices the target was wrong.
This is not the familiar complaint that AI writes bad code. The models are extraordinary and getting better every month. That is exactly why the bottleneck moved. When generation was scarce, the quality of your prompt was forgivable, because a human reviewed every line on the way out and caught the drift. When generation is effectively free and the review step is what you are automating away, the only place left to inject correctness is before the agent runs. The plan stops being paperwork. It becomes the load-bearing input.
There is a second-order version of this that makes the planning floor even more valuable. The execution layer is churning weekly. The Latent.Space newsletter recently called it ["meta-harness summer"](https://www.latent.space/p/ainews-its-meta-harness-summer), cataloging a wave of new orchestration layers arriving almost faster than you can name them: Conductor, Zed's ACP, Vercel's Eve, HarnessAgent, Databricks' Omnigent. If your factory's value is tied to whichever harness you wired in this month, you are rebuilding it next month. The thing that survives the churn is not the tool. It is the captured intent and the criteria the tool is checked against. The harness is rented. The plan is owned.
## What lives on the planning floor
A planning floor is not a Notion doc full of good intentions. It has machinery, and the machinery does three things the execution layer cannot do for itself.
It interrogates the idea before anyone builds. A real planning floor asks the questions you did not think to answer: what happens to an unauthenticated user, what does a canceled payment do to the plan, which edge cases are in scope. The point is to surface the unknowns while they cost a conversation, not a rewrite. You give a high-level description and the system asks the questions that turn it into something buildable.
It writes [acceptance criteria the line can be checked against](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify). This is the difference between "build a CRM" and a target an agent can hit and you can verify. Consider the same feature framed both ways:
> Vague: "Add user authentication."
> Precise: "A logged-out user hitting a paid route redirects to login. A canceled payment leaves the existing plan unchanged until the period ends. Session expiry forces re-auth on the next protected action. Each of these is a criterion the feature is not done without."
The first is an invitation for the agent to guess. The second is a contract. On an autonomous line, the difference between those two framings is the difference between a feature and an incident.
And it accumulates. Every requirement, decision, and verified criterion becomes part of the product's record, so the next feature starts from what the last one established instead of from a blank prompt. The execution layer is stateless by nature; a fresh agent session remembers nothing. The planning floor is where the memory lives.
This is the floor BrainGrid is built to be. The [Planning Agent](/loop) turns an idea into a requirement with explicit acceptance criteria, challenging vague intent and asking the clarifying questions before any code is written. The Builder Agent then executes against that spec, in a managed cloud sandbox with a live preview or directly in your GitHub repo through Claude Code, Cursor, or Codex over MCP, so the harness underneath stays swappable. Then the step the execution-first factories skip: a feature is not done until every criterion is met with evidence. Plan, build, verify, repeat. The plan is what the verifier checks against, which is the whole reason verification is possible at all. You cannot verify if you do not have a plan.
## What this changes for you on Monday
If you are wiring coding agents into anything that resembles a factory right now, the practical implication is specific. Your instinct is to spend your effort on the execution layer, picking the best harness, tuning the agent loop, wringing more speed out of the line. That effort has sharply diminishing returns, because the harness you tune this month is obsolete next month and the speed you gain is speed at producing whatever you pointed it at.
The real return is upstream. The hour you spend making a requirement precise, framing its dependencies, and writing down what "done" means is the hour that determines whether the next fifty automated steps converge on the right thing. On a manual team that hour was optional, because a human in the loop corrected the drift continuously. On an autonomous line there is no continuous human correction, so the correction has to be front-loaded into the plan. Build the planning floor first, and the factory above it gets trustworthy. Skip it, and you have built a very fast way to be wrong.
## The honest trade-off
A planning floor costs you the first hour of every feature, and that hour feels like friction when the agent is sitting right there, ready to generate. On a throwaway prototype, it is friction, and you should skip it. If the thing will never have a user, a payment, or your name on it, point the line at a loose target and let it rip. The software factory's pure-speed mode is genuinely the right call there.
The moment the thing is real, the math inverts. Anything someone depends on cannot afford a planning floor that does not exist, because the time you save skipping it gets repaid with interest the first time the autonomous line ships a confident, plausible, wrong implementation across twenty files you never read. Match the rigor to the stakes. For a demo, no floor. For a product, the floor is the load-bearing part.
The skeptics have a point worth taking seriously. The Register recently called loop engineering ["the latest AI buzzword"](https://www.theregister.com/ai-and-ml/2026/06/24/loop-engineering-latest-ai-buzzword-still-needs-humans-in-the-loop/) and quoted Addy Osmani with the line that actually settles the question:
> The loop changes the work, it does not delete you from it.
That is exactly right, and it is the whole argument for the planning floor. Automation did not remove the human. It moved the human's job to the front of the line, to the part where intent gets made precise. The factory can run the line. It cannot decide what should come off it. That decision is yours, and the planning floor is where you make it.
Automate the line all you want. Just build the floor that tells it what to make.
## FAQ
### What is a software factory?
A software factory is a structured, repeatable approach to producing software: standardized pipelines, reusable components, and automation that turns requirements into shipped code with less manual effort each cycle. The metaphor frames development as an assembly line where the process itself is engineered, not just the individual product. The idea predates AI by decades, but it has surged again as teams wire coding agents into the line so that agents, not humans, do most of the writing, reviewing, and testing.
### Why does input quality matter more in an autonomous software factory?
Because the human review step that used to catch mistakes is the thing autonomy removes. On a manual team, a person reviews each change on the way out and corrects drift continuously, so a vague requirement still gets fixed downstream. On an autonomous line there is no continuous human correction, so the only place to inject correctness is before the agent runs. That makes the precision of the plan the binding constraint on output quality. A faster line just spends a vague requirement faster.
### What is the difference between planning and execution in a software factory?
Execution is the part most factories automate: turning a written requirement into shipped, tested code. Planning is the part that turns a fuzzy idea into a precise requirement with framed dependencies and explicit acceptance criteria. Execution can be automated relatively easily and is what most demos show. Planning determines whether the execution is pointed at the right target, and it is the floor most factories never build.
### What are the phases of building software with AI agents?
A reliable loop has four: plan, where intent becomes a requirement with acceptance criteria; build, where an agent implements against that spec; verify, where the result is checked against each criterion with evidence; and repeat, where what was learned and verified accrues to the product's record so the next feature starts ahead. The plan phase is the one teams under-invest in and the one that bounds the quality of everything after it.
### Does building a planning floor slow you down?
At the start of each feature, yes. Writing acceptance criteria and framing dependencies before the agent runs costs an hour that feels like overhead when generation is instant. On a throwaway prototype, it is overhead and you should skip it. On anything real, that hour is what keeps the autonomous line from converging confidently on the wrong implementation, and it gets repaid the first time you would otherwise be debugging twenty files you never read.
If you are building something real and want the line pointed at a target your agent can hit and you can verify, [start with a plan instead of a prompt](/loop).
*[BrainGrid](https://braingrid.ai) is the plan-first app-building platform that makes intent precise before the agents run, then proves every feature against the criteria you set. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The Four Pillars of Context Engineering: Write, Select, Compress, Isolate
Source: https://www.braingrid.ai/blog/four-pillars-of-context-engineering
Published: 2026-06-24T00:00:00Z
Everyone agrees context engineering replaced prompt engineering. Almost nobody agrees on what it actually is.
Search the term and you will find a framework with four pillars, another with five, and one ambitious post claiming six. KeyValue lists data flow, tool integration, memory architecture, and format optimization. Weaviate counts six. Anthropic's own guidance frames it as curating the optimal set of tokens during inference. The phrase is everywhere and the definition is a moving target.
That is a problem if you are trying to actually get better at it. You cannot practice a discipline whose vocabulary changes per blog post.
So this post does one thing: it takes the framing that has the most staying power, the one [LangChain](https://www.langchain.com/blog/context-engineering-for-agents) popularized and that practitioners keep coming back to, and explains the four pillars in terms a builder can use on their next session. Write, Select, Compress, Isolate. Then it names the pillar that every one of these frameworks quietly leaves out, the one that decides whether all the context work was worth anything.
## What Context Engineering Actually Is
Start with the definition that holds up. Context engineering is the art of filling the model's context window with just the right information at each step, and nothing else.
That last part is what people miss. Context engineering is not "give the agent more." A model has a finite attention budget, and every token you add competes for it. Anthropic's guidance puts a name to the failure mode: as context grows, models suffer distraction, clashing, and poisoning. Stuff the window with everything you have and the agent gets worse, not better. The skill is curation, not accumulation.
Here is the contradiction at the heart of it. The more capable agents become, the more they read on their own: more files, more tool outputs, more history. Left unmanaged, a more powerful agent fills its own context with more noise faster. Capability raises the ceiling and the risk at the same time. Which is exactly why context engineering became a discipline the moment agents started running loops instead of answering single prompts.
The four pillars are four ways to manage that finite window. Think of them as the verbs of the job.
## Pillar One: Write
Writing context means putting information somewhere outside the context window so it survives.
A model is stateless. Every session starts from nothing, and within a session, anything that scrolls out of the window is gone. Writing context is how you fight that. It is the scratchpad the agent uses to take notes mid-task, the memory file that carries facts across sessions, the plan it writes down before it starts so it does not lose the thread halfway through.
If you use Claude Code or Cursor, you already do a primitive version of this with a CLAUDE.md or AGENTS.md file. That is written context: durable facts about your project that you control, loaded every session so the agent does not start from zero. We covered the durable-context version of this in depth in [the state file pattern](/blog/claude-code-memory-state-file-pattern), and it is the difference between an agent that knows your conventions and one you re-teach every morning.
The trap with Write is rot. Written context that drifts from the truth of your code stops helping and starts actively misleading. One builder on r/vibecoding put the cost plainly:
> if at some point this context deviates from the truth of your product, the AI will start getting confused. So basically you are creating debt, you will need to keep maintaining your comments AND your code.
Written context is an asset only as long as it stays true. The moment it lies, it is a liability the agent trusts.
## Pillar Two: Select
Selecting context means pulling in the right information at the right moment, instead of loading everything up front.
This is the retrieval pillar. When an agent reads a file, queries a vector store, calls a tool, or searches your codebase, it is selecting context. The whole game is relevance. An agent that reads the three files it needs makes a good decision. An agent that reads thirty files, twenty-seven of which are irrelevant, has poisoned its own window with noise and will make a worse one.
The same applies to tools. Each tool definition you expose costs tokens and adds a choice the agent has to reason about. Give an agent forty tools when the task needs three, and you have not empowered it, you have distracted it. Select is the discipline of bringing in only what this step requires.
Here is the side-by-side that makes it concrete:
> Loading everything: "Here is the entire codebase, all our docs, the full git history, every API endpoint. Build the contact form."
>
> Selecting: "Build the contact form. Relevant files: the existing form component, the validation utils, the contacts API route. Convention: all forms use react-hook-form."
The second agent succeeds more often, costs less, and is easier to review. Not because it knows less, but because nothing it knows is noise.
## Pillar Three: Compress
Compressing context means reducing what is already in the window to the tokens that still matter.
Long agent loops rot from the inside. Old tool outputs, abandoned approaches, and dead-end reasoning pile up turn after turn. Compression is how you keep the signal high: summarizing a long conversation into its conclusions, trimming a giant tool output to the relevant lines, replacing twenty turns of debugging with one line that says what finally worked.
This pillar has a cost most people do not see until the bill arrives. Every turn of a loop re-pays for the whole context window. One builder did the math in a thread on running agent loops:
> every loop turn re-pays for your always-on context, a loop that runs 50 turns pays that tax 50 times, the gap between $10 and $40 for the same work.
Compression is not just about staying under the token limit. It is about not paying for the same bloated context fifty times in a single task. Compress well and a long-running agent stays both sharp and affordable. Compress badly, and you are funding the model's confusion.
The trade-off is real: compress too aggressively and you lose the nuance the agent needed. The balance is genuinely hard, which is why it is a pillar and not a checkbox.
## Pillar Four: Isolate
Isolating context means splitting work across separate context windows so they do not contaminate each other.
This is the multi-agent pillar. Instead of one agent holding everything in one window, you give each sub-task its own clean context: a research agent with its own window, a builder agent with another, an orchestrator that hands off between them. Each one stays focused because it is not carrying the others' baggage.
Isolation is what makes parallel agent work possible at all. But it introduces the hardest problem in this whole discipline, and it is the bridge to the pillar nobody names. When you isolate work across separate windows, each agent only knows what you handed it. If what you handed it was vague, the agent fills the gap with a guess, and now you have several agents guessing differently about the same fuzzy target. Isolation multiplies your output and multiplies the ways a vague instruction goes wrong.
## The Pillar Everyone Skips
Write, Select, Compress, Isolate. Four verbs for managing the context window. Master all four and you can keep an agent's attention clean, cheap, and focused.
And the agent will still confidently build the wrong thing.
Here is the gap. Every one of these pillars is about *how* context flows: where it is stored, what gets pulled in, what gets trimmed, how it is partitioned. None of them is about *what the context is supposed to produce*. You can engineer a perfectly clean window pointed at a target that was never clearly defined, and the model will hit that fuzzy target with beautiful efficiency. Clean context, wrong outcome.
The missing pillar is **the definition of done**. Not how information moves through the window, but the specific, checkable description of what the agent is supposed to build and how you will know it succeeded. A circulating line in the agent-building community captures why this matters more as agents get more autonomous: a loop with nothing in it that can say "no" is just the agent agreeing with itself on repeat. Clean context with no acceptance criteria is a faster way to ship a confident mistake.
This is the part that does not live in a CLAUDE.md file or a retrieval system. A state file describes how your project works. Compression keeps the window lean. Isolation keeps agents focused. But none of them says: this feature is done when an unauthenticated user is redirected to /login, when the form rejects an invalid email with a visible error, when the contact is saved and appears in the list. That is a different kind of context, and it is the one that decides whether the other four pillars produced something you can trust.
This is the gap [BrainGrid](https://braingrid.ai) is built to close. You describe what you want to build, and the Planning Agent turns it into a requirement with explicit acceptance criteria, the checkable definition of done that the four pillars never supply on their own. The Builder Agent then builds against that requirement, in a managed sandbox with a live preview or in your own GitHub repo through your coding agent over MCP. And a feature is not finished until every criterion is verified with evidence. The four pillars keep the agent's attention clean. The acceptance criteria make sure that clean attention is pointed at the right thing, and prove it landed there.
## What This Means for You
If you are building with a coding agent right now, here is the concrete implication. The next time your agent confidently produces something subtly wrong, your instinct will be to blame the context: I should have given it more files, a better CLAUDE.md, a cleaner prompt. Sometimes that is right, and the four pillars are how you fix it.
But often the context was fine and the target was vague. The agent did exactly what you asked. You just never wrote down, in checkable terms, what "done" meant. No amount of Write, Select, Compress, or Isolate fixes an undefined outcome. Only a definition of done does.
So treat the four pillars as table stakes, the hygiene that keeps your agent sharp. Then add the fifth thing they leave out: before the agent writes a line, decide how you will know it succeeded. That is the context engineering that actually changes your hit rate.
## FAQ
### What are the 4 pillars of context engineering?
The four most widely cited pillars are Write, Select, Compress, and Isolate, a framing popularized by LangChain. Write means storing context outside the window so it survives (scratchpads, memory files, plans). Select means pulling in the right information at the right moment (file reads, retrieval, tool calls). Compress means reducing what is already in the window to the tokens that still matter (summarizing, trimming). Isolate means splitting work across separate context windows so sub-tasks do not contaminate each other (multi-agent setups). Note that there is no single official standard: other frameworks list different pillars, but these four are the most durable for builders working with coding agents.
### What is an example of context engineering?
A practical example: instead of telling a coding agent "here is the entire codebase, build the contact form," you select only the relevant files (the form component, validation utils, the contacts API route), state the convention it should follow, and write down what done means (an invalid email shows a visible error, the saved contact appears in the list). You are not giving the agent more, you are giving it exactly the right context and a checkable target. That curation, plus a clear definition of done, is context engineering in practice.
### Is context engineering still relevant?
More relevant, not less, as agents get more autonomous. The more an agent does on its own, the more context it pulls in without you watching, and the more a cluttered or poisoned window degrades its decisions. Context engineering is what keeps a long-running agent sharp instead of letting it drown in its own accumulated noise. The one caveat: managing context flow is necessary but not sufficient. A perfectly engineered window still needs a clear definition of done, or the agent just hits the wrong target efficiently.
### What is the difference between context engineering and prompt engineering?
Prompt engineering is about crafting the single instruction you type. Context engineering is about managing everything the model sees: instructions, retrieved files, tool outputs, memory, and conversation history, across an entire agent loop rather than one exchange. Prompt engineering optimizes one message. Context engineering optimizes the whole information environment the agent operates in, which is why it became the dominant framing once agents started running multi-step loops. We unpack this shift further in [why context engineering is what you're actually doing](/blog/context-engineering).
### Why isn't there one agreed definition of the pillars of context engineering?
Because the field is young and several frameworks emerged in parallel. LangChain's Write, Select, Compress, Isolate is the most cited, but you will also see four-pillar versions built around data flow, tool integration, memory, and format, and six-pillar versions that split things further. They mostly describe the same underlying job, managing a finite context window, with different groupings. The practical move is to pick one framing, get fluent in it, and not get lost arguing taxonomy. What matters more than the exact count is the pillar most of them skip: the definition of done.
*[BrainGrid](https://braingrid.ai) turns your idea into a requirement with acceptance criteria your coding agent builds against and is verified by, so a clean context window is always pointed at a target you can trust. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The AI Coding Workflow That Ships One Feature: Idea to Merged PR
Source: https://www.braingrid.ai/blog/ai-coding-workflow-idea-to-merged-pr
Published: 2026-06-23T12:00:00Z
Last week someone on r/codex asked a question that has no business being asked anymore: ["How do you use Codex like a professional AI builder?"](https://www.reddit.com/r/codex/comments/1ubq5m6) The tools are a year past magic. The models are good enough that "build me a login page" produces a login page. And yet the most upvoted answer was not a clever prompt or a secret setting. It was a workflow, hand-assembled by someone who had clearly been burned: write a spec first, break it into a phased plan, give each phase a definition of done, plan before you code, then review the diffs like a lead engineer.
Read that again. The top answer to "how do the pros use this AI tool" was not about the AI tool at all. It was a process for working around it. The fastest path to shipping something real with an agent turns out to be the part of software development that has nothing to do with the agent. That is the contradiction this whole piece rests on, and it is the most useful thing you can learn this year: the AI coding workflow that actually ships is mostly the workflow you build around the AI.
## The workflow everyone keeps reinventing
Spend an hour reading how working builders describe their setup and you notice they have all converged on the same shape without coordinating. Addy Osmani's [LLM coding workflow going into 2026](https://addyosmani.com/blog/ai-coding-workflow/) describes a virtuous cycle where the AI writes code, automated tools catch issues, and the AI fixes them. The most-shared [System Design newsletter version](https://newsletter.systemdesign.one/p/ai-coding-workflow) lists five steps and the second one is literally "Plan Before You Code." The [dev.to post that keeps circulating](https://dev.to/matthewhou/separate-planning-from-execution-the-ai-coding-workflow-that-actually-works-1n00) is titled, with no irony, "Separate Planning From Execution." Different people, different tools, same skeleton.
Here is that skeleton, the one a thousand builders are rebuilding by hand in a thousand slightly different ways:
```mermaid
flowchart LR
A[Idea] --> B[Spec: what done means]
B --> C[Plan: slice into phases]
C --> D[Build: agent writes the code]
D --> E[Verify: check against the spec]
E -->|passes| F[Merged PR]
E -->|fails| D
```
The shape is not the interesting part. The interesting part is which step does the work. Most people assume the agent, the "Build" box, is where the magic lives, because that is the box that got a thousand times better. They are wrong, and you can prove it to yourself. Take a strong agent and give it a vague idea. You get a confident, plausible, wrong result. Now take a mediocre agent and give it a precise spec with a clear definition of done. You get something you can actually ship. The power is not in the model. It is in the box labeled "what done means," and that box is the one no tool writes for you.
## One feature, start to finish
Abstractions are easy to nod along to and useless when you sit down to build. So walk one real feature through the loop: a password reset flow, the kind of thing every app needs and nobody wants to write.
The amateur version is one sentence. "Add password reset." You paste it into your agent, watch it generate four hundred lines across six files, see a form appear in the preview, and merge it because it looked done. Three days later a user emails that the reset link works twice, or never expires, or silently fails for anyone with a plus sign in their email. The demo worked. The feature did not. You shipped the gap.
Now the version the r/codex commenter was describing. Before any code, you write down what done actually means, in conditions a person can check:
> The user requests a reset by email. A one-time link is sent that expires in 30 minutes and works exactly once. An invalid or expired link shows a clear error, not a crash. After a successful reset, all existing sessions are logged out. An unknown email address returns the same neutral confirmation as a known one, so the form cannot be used to discover who has an account.
That is five testable conditions, and notice what just happened. You did not write code. You did not need to. But you now have something the one-sentence version never had: a definition of done that exists outside your head, that the agent can build against, and that you can check the result against later even though you cannot read a line of the code that produced it. The spec is the deliverable. The code is downstream of it.
From there the rest of the loop has somewhere to stand. You slice the work into phases, send the agent off to build, and when the pull request comes back you do not stare at the diff feeling unqualified. You walk your five conditions. Request a reset, click the link twice, watch the second click fail. Wait thirty-one minutes, confirm the link is dead. Enter an email that does not exist, confirm the message gives nothing away. You are reviewing behavior against a checklist you wrote, which is exactly the kind of review a non-engineer is qualified to do. We went deep on that skill in [reviewing a pull request when you cannot read code](/blog/what-is-a-pull-request-non-engineer-guide); the point here is that the checklist is what makes the review possible at all.
## Why the spec is the workflow
There is a backlash worth taking seriously. A sharp comment on a recent [Hacker News thread](https://news.ycombinator.com/item?id=48627815) called the whole agentic-workflow paradigm "a narrative trend pushed by AI companies to get people to 10x their token consumption." That critic is half right, and the half they are right about is the half that matters. A loop with no definition of done is exactly what they describe: an expensive way to keep rolling the dice. You prompt, the agent generates, you squint, you do not like it, you prompt again, and every turn burns credits while you converge on nothing, because there is nothing for the loop to converge toward.
The thing that turns that slot machine into a workflow is the one ingredient the skeptics never mention. Not a better model. Not more autonomy. A spec the output can be measured against. With it, every loop iteration has a target and a stopping condition: done is when the evidence matches the spec. Without it, "done" is whenever you get tired of pulling the lever. The definition of done is not a nice-to-have step in the workflow. It is the workflow. Everything else is plumbing.
This is also why the workflow does not get easier as the models get better, which is the part that surprises people. A more capable agent makes more decisions per turn, and every decision you did not write down is one it makes for you, silently, in a direction you will discover later. The more the agent can do on its own, the more the written spec is the only thing standing between its speed and your weekend. The hard part moves toward planning, not away from it.
## Where this stops being a hand-rolled process
You can run this entire loop yourself with sticky notes and discipline, and many good builders do. But look at what you are actually maintaining by hand: a definition of done for every feature, a way to slice it into buildable phases, a record of which conditions were checked and which were not, and a memory of what this product is supposed to do that survives from one session to the next. That is real work, and it is the same work whether you are one person or a team of fifty. The reason it keeps getting reinvented in Reddit comments is that nobody ships it as a product.
That is the gap [BrainGrid](https://braingrid.ai) sits in. You describe the feature in plain language, and the Planning Agent turns it into a requirement with explicit acceptance criteria, asking the clarifying questions you did not think to answer, the kind that catch the expired-link and plus-sign-email cases before any code exists. The Builder Agent then builds against that spec, either in a managed cloud sandbox with a live preview or in your own GitHub repo with [Claude Code, Cursor, or Codex](/ai-coding-agents). When it is done, verification checks the result against every acceptance criterion, so the pull request arrives with evidence attached instead of a diff you have to decode. That is the full loop, Plan, Build, Verify, Repeat, and the part that does the work, the captured definition of done, is the part the product remembers so you do not have to rebuild it every project. We cover the planning half in depth in [building the BrainGrid way](/blog/building-the-braingrid-way), and the spec craft itself in [how to write acceptance criteria an AI agent can verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
The honest limit: a spec does not write itself, and a bad one ships a bad feature with full confidence. If you write down the wrong conditions, the agent will satisfy them perfectly and you will have built the wrong thing precisely. The workflow does not remove your judgment about what good looks like. It just makes sure that judgment gets recorded once, up front, where it can actually steer the build, instead of living as a fuzzy feeling you compare the result against at the merge button.
So the next time you catch yourself asking how the pros use the latest agent, remember what the pros actually answered. They did not share a prompt. They shared a workflow, and the center of it was the least glamorous step there is. Write down what done means before you build. The agent got fast. Deciding what it is allowed to call finished is still your job, and it is the only job that ships.
## FAQ
### What is an AI coding workflow?
An AI coding workflow is the repeatable process you wrap around an AI agent to turn an idea into shipped software, rather than just prompting an agent and hoping. In practice it has converged on a consistent shape: write a spec that defines what "done" means, slice the work into phases, let the agent build against the spec, then verify the result against your original conditions before merging. The agent handles the code generation; the workflow handles everything that makes the code generation aim at the right target. The most common mistake is treating the prompt as the workflow when the spec is the part that actually does the work.
### How do I set up an AI coding workflow?
Start with the step everyone skips: before any code, write down what done looks like as a short list of conditions a person can check, not as a one-line prompt. Then break the feature into phases small enough to review one at a time, send each to your agent, and when it returns, walk your conditions against the running result instead of reading the diff. Keep a record of what this product is supposed to do so each new session does not start from zero. You can do this manually with notes and discipline, or use a tool that captures the spec, runs the build against it, and verifies the result for you.
### Is planning really necessary if the AI model is good enough?
Yes, and counterintuitively it matters more as models improve, not less. A more capable agent makes more decisions per turn, and every decision you did not specify is one it makes on its own, in a direction you discover after the fact. A strong model with a vague request produces a confident, plausible, wrong result; a modest model with a precise definition of done produces something you can ship. The work that decides the outcome is in the spec, because that is the only thing the agent's speed has to aim at. Skipping planning is how a loop becomes an expensive way to keep rolling the dice.
### How do I review an AI pull request if I can't read code?
Review the behavior, not the syntax. Read the summary and confirm the scope matches what you asked for, then open the preview and walk through your acceptance criteria the way a real user would, including the failure cases like expired links, wrong inputs, and empty forms. Notice how many files changed and be more cautious of a sprawling change than a small one. Approve only when the running feature satisfies every condition you wrote up front. This works precisely because you defined done before the build, so the review is checking a list instead of guessing against a fuzzy memory.
### What's the difference between vibe coding and an AI coding workflow?
Vibe coding is prompt, generate, eyeball, repeat, with no written definition of done and nothing to verify against, which is great for prototypes and a fast way to ship hidden gaps when the app matters. An AI coding workflow adds the missing piece: a spec the output is measured against, so each iteration has a target and a clear stopping condition. The difference is not how good the model is or how fast you go. It is whether there is anything in the loop that can say "not yet," which is what turns generation into shipping.
*[BrainGrid](https://braingrid.ai) turns your idea into acceptance criteria, builds against them with your choice of agent, and verifies every change with evidence, so the workflow you keep rebuilding by hand is just the product. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Why Your AI Agent Keeps Breaking Things That Worked
Source: https://www.braingrid.ai/blog/why-ai-keeps-breaking-things-that-worked
Published: 2026-06-22T12:00:00Z
The bug you are chasing today is not in the feature you asked for. It is in the feature you shipped last week, the one that worked fine until your AI agent touched something nearby and quietly took it down. You did not ask it to change the login flow. You asked for a new settings page. Login is broken anyway. This is the thing nobody warns you about when they sell you on building software with an agent: the speed is real, and so is the way it keeps breaking things that were already done.
If you have felt this, you are not imagining a pattern, and you are not bad at this. A builder on r/vibecoding [asked the whole community last week](https://www.reddit.com/r/vibecoding/comments/1u7syo8/how_do_you_deal_with_ai_breaking_stuff_that_was/) how they deal with AI breaking stuff that was already working, and the thread filled up fast. So here is the claim this post rests on, and it is not the one you have been told: the agent is not breaking your code because it is dumb. It breaks your code because nothing ever told it what "still working" means. Fix that, and the regressions mostly stop. That is a different problem than the one most advice tries to solve, and it has a different fix.
## What is actually happening when the agent breaks working code
Start with the mechanism, because the jargon hides how ordinary it is. When you ask an agent for a new feature, it reads some of your code, decides how to add the thing you asked for, and edits files to make it happen. The trouble is that it does not hold your whole project in its head while it works. It holds a slice. It sees the files it opened this session and the conversation you have had so far, and that is roughly it. The login flow you built three days ago is not in the room unless something put it there.
So when the new settings page needs to read the current user, the agent writes the most reasonable code it can for the slice it can see. Reasonable for that slice can be wrong for the whole. It renames a shared function, changes the shape of the user object, or "cleans up" an auth check it did not understand, and the settings page works perfectly while login, which depended on the old shape, falls over. The agent did not decide to break login. It never knew login was load-bearing, because nothing it could see said so.
This gets worse the longer a session runs, and there is a name for it now. Researchers and practitioners have started calling it context rot: as the conversation grows, models stop synthesizing genuinely new solutions and start repeating and recombining patterns from earlier in the same session. One widely shared breakdown of the data put it bluntly, that [AI coding agents introduce roughly 1.7 times more bugs than human-written code](https://www.instagram.com/reel/DWbrGmvj-m2/), and that the rate climbs as sessions get long and context fills past the point where the model can keep it all straight. The longer you let an agent run unsupervised across your codebase, the more confidently it overwrites things it has forgotten are there.
## The reframe: the model is stateless, your product is not
Here is the part that flips how you should think about this. Your codebase has state. It is a system where the pieces depend on each other, and a change in one place has consequences in another. The model does not have state. Every session it starts close to fresh, knowing only what it can see right now. You have been treating a stateless tool as if it remembers your product, and it does not, and it never will, no matter how good the model gets.
That last clause matters, because it is tempting to wait this out. Surely the next model is smart enough not to do this. But a smarter model with a bigger context window still does not know that login depends on the user object unless something records that fact outside the conversation. A more capable agent that forgets is just a faster way to break things you cannot see. The gap is not intelligence. The gap is memory and intent, and those live in your project, not in the weights.
This is why the usual advice underwhelms. "Write better prompts" helps the feature you are asking for right now. It does nothing for the feature you finished last Tuesday, because you are not prompting about that one. "Use a smarter model" raises the ceiling on what the agent can build and does nothing about what it forgets. The author of one of the top results for this exact problem landed on the same root cause from a different angle: [when AI coding goes wrong](https://levelup.gitconnected.com/why-your-ai-code-keeps-breaking-its-not-the-ai-3b4044627bb2), it is almost always because we started building before we knew what we were building. Hidden assumptions are the bug. The assumption "login needs the user object in this exact shape" was true, load-bearing, and written down nowhere.
## The before and after that makes it concrete
The difference between an agent that breaks things and one that does not is almost entirely about what it is checked against. Watch the two versions of the same request.
> The way it breaks: "Add a settings page where users can change their email." The agent opens a few files, sees the user object, decides the cleanest way to support an editable email is to restructure that object, ships a working settings page, and breaks login in the process because login read the old structure. You find out two days later from a user who cannot log in.
>
> The way it holds: "Add a settings page where users can change their email. Existing behavior that must still pass: users can log in with email and password, the session persists across refresh, and the current user loads on every authenticated page." Now the agent has a list of things it is not allowed to break, in writing, where it can see them. When its change threatens login, that is no longer an invisible side effect. It is a stated condition it has to satisfy.
Same model. Same feature. The only thing that changed is that the second version told the agent what "still working" means, so the agent could check its own work against it instead of finding out from your users.
That list has a name. They are acceptance criteria: the specific, testable conditions that have to be true for a feature to count as done, including the old features that must keep working. Most regressions are not the agent failing a test. They are the agent never being given the test in the first place.
## Where BrainGrid fits, and where it does not
The honest problem with the fix above is that nobody wants to hand-write a regression checklist before every small change. You came to AI building to go faster, not to maintain a growing document of everything that must not break. This is the gap [BrainGrid](https://braingrid.ai) is built to close, and it sits before the agent writes a line.
You describe the feature in plain language, the same sentence you would have typed into your agent. The Planning Agent turns it into a requirement with explicit acceptance criteria, and because it is reasoning about your product and not just this one request, those criteria include the conditions the new work must not violate. When the Builder Agent then builds it, in a managed sandbox with a live preview or in your own repo with [Claude Code, Cursor, or Codex](/ai-coding-agents) over MCP, the work is verified against every one of those criteria before it reaches you. The change that would have quietly broken login fails verification instead of failing in production, because "users can still log in" was a written condition with evidence attached, not an assumption the agent forgot it ever made. That is the Verify step of the loop, Plan, Build, Verify, Repeat, and it is the step that turns "the demo looked fine" into "every condition was checked." We go deeper on writing those conditions in [how to write acceptance criteria an AI agent can verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
Now the trade-off, because pretending there isn't one would be the same overselling this post is arguing against. Writing down what must keep working is not free. It is a few minutes of thinking up front, before the dopamine hit of watching the agent build. On a one-off script you will throw away tomorrow, that thinking is overhead you do not need, and you should skip it. The payoff shows up exactly where the pain does: on the third, fourth, and fifth feature of a real product, where the pieces have started to depend on each other and a forgotten assumption in one corner takes down a finished feature in another. That is where the slot machine of "build it again and hope it doesn't break something else" stops being fun, and a written record of intent starts paying for itself every single change.
## What this means for what you are building right now
If you are building a real product with an AI agent, here is the concrete version. Your regressions are not random, and they are not a sign you picked the wrong tool. They cluster around the features that other features depend on, the auth, the data model, the shared utilities, exactly the load-bearing parts the agent is most likely to "improve" without knowing what leans on them. The fix is not to prompt harder or wait for a smarter model. It is to make the invisible dependencies visible by writing down what each feature must keep doing, and to put that record where the agent is checked against it, not where it lives only in your head.
The agent forgets your product every session. That is not a bug you can prompt away, it is what a stateless model is. The durable thing, the part that actually keeps your product working as it grows, is the record of what it is supposed to do. Build that record, and the agent stops breaking things that worked, because for the first time it knows which things those are. If you keep one habit from this post, make it this one: before you ask for the next feature, write the one sentence that says what must still be true after it ships.
## FAQ
### Why does my AI keep breaking my code?
Because the model is stateless and your codebase is not. The agent only sees a slice of your project each session, the files it opened and the conversation so far, so it edits confidently without knowing what elsewhere depends on the code it is changing. When it renames a shared function or restructures a data object for the feature you asked about, it can break an older feature it cannot currently see. The fix is to record what each feature must keep doing and check the agent's work against that record, so the dependencies are no longer invisible.
### Is AI actually bad for coding?
No, but it is bad at remembering. AI coding agents are genuinely fast and capable at building the thing in front of them, and the bug rate climbs mainly when they work unsupervised across a large codebase and lose track of what already exists. Used with a written definition of what must keep working, and a verification step that checks against it, an agent is a real accelerant. Used as a black box you prompt and hope, it breaks finished features and you debug more than you ship. The difference is process, not the tool.
### How do I stop my AI agent from breaking features that already worked?
Give it, in writing, the list of behaviors that must still pass after the change, then have its work checked against that list before you accept it. These are acceptance criteria: testable conditions like "users can still log in" or "the cart total still updates when an item is removed." Most regressions happen because the agent was never told those conditions existed. When the conditions are written down and verified, a change that would break them fails the check instead of failing in production.
### What is context rot in AI coding?
Context rot is what happens when a model's working context grows too large during a long session: instead of synthesizing new solutions, it starts repeating and recombining patterns from earlier in the conversation, and its accuracy about your actual codebase degrades. In practice it means the longer an agent runs without a reset, the more likely it is to overwrite or contradict things it built earlier in the same session. Shorter, well-scoped tasks with a clear definition of done are far less prone to it than one sprawling open-ended session.
### Does using a smarter AI model fix the regressions?
Not by itself. A more capable model with a larger context window builds better features, but it still does not know that one part of your product depends on another unless that fact is recorded somewhere it can see. A smarter agent that forgets is just a faster way to break things you cannot see. The durable fix lives in your project, as captured intent and acceptance criteria, not in the model, which is why this problem gets more important, not less, as models improve.
*[BrainGrid](https://braingrid.ai) turns each feature into a [spec with acceptance criteria](/spec-driven-development) your coding agent builds against and is verified by, so the next change stops breaking the last one. Try it at [braingrid.ai](https://braingrid.ai).*
---
# The Verification Gap: Code Got Cheap, Trust Didn't
Source: https://www.braingrid.ai/blog/verification-gap
Published: 2026-06-21T12:00:00Z
Generating code is now the easy part of building software. Trusting it is the expensive part.
That inversion happened faster than most teams adjusted to. For most of the history of this craft, the slow, costly, skill-gated step was writing the code. Everything downstream, review, testing, shipping, was scaffolding around the hard part. Then Claude Code, Cursor, and Codex made the hard part nearly free. A feature that took a week to write now takes an afternoon to generate. And the moment generation got cheap, the bottleneck slid one step to the right and landed somewhere nobody had built infrastructure for: knowing whether the thing you just generated actually works.
Andrej Karpathy gave the gap its name. Riding [a post from Balaji Srinivasan](https://x.com/karpathy/status/1930305209747812559), he framed it cleanly:
> Sometimes you can verify by eye, which is why AI is great for frontend, images, and video. But for anything subtle, you need to read the code or test it.
That is the whole problem in two sentences. Generation scaled. Verification did not. And the distance between the two is the verification gap.
## The gap is measurable, and it is getting worse
This is not a vibe. In January 2026, Sonar published a study that put numbers on it: developers do not trust the code their tools produce, and the surge in AI output has created a new bottleneck at the verification stage rather than at generation. The stat that traveled furthest was blunt: 96% of developers do not fully trust AI-generated code. One engineer summarized the lived version of that number on LinkedIn:
> I use Cursor and Claude Code heavily, but I don't commit a single line without reviewing it first.
The discourse around that number has not cooled. This week alone, [Entrepreneur](https://www.facebook.com/Entrepreneur/posts/ai-is-generating-code-faster-than-humans-can-ever-hope-to-verify-if-your-qa-stra/1384748010190074/) put it plainly: AI is generating code faster than humans can ever hope to verify, and if your QA strategy has not evolved to match, your systems are living on borrowed time.
Read that again. The most productive AI coding setups in the world still bottleneck on a human reading every line before it ships. The generation got 10x faster. The reading did not get any faster at all. That is not a productivity gain evenly distributed. It is a productivity gain on one side of a wall and a pile-up on the other.
Here is the part that makes this a structural problem and not a temporary one. The better generation gets, the wider the gap grows. A weak model writes obvious garbage you catch in a glance. A strong model writes plausible code with a subtle bug buried in a way no sane human would have written, which means it is exactly the kind of bug a human reviewer skims right past. One developer described finding "a bug disguised in a way no sane human could have come up with." Capability does not close the verification gap. It widens it, because it moves the errors from obvious to subtle, and subtle is where review fails.
## Why "just review it harder" is not the answer
The instinctive fix is to review more carefully. Slow down, read every diff, be the responsible adult in the loop. It does not scale, and the reason it does not scale is arithmetic.
If an agent can open five pull requests in the time it used to take you to write one, and each PR still needs a human to read it end to end, you have not removed the bottleneck. You have moved it onto yourself and made it five times heavier. The agent is now waiting on you. The faster it generates, the longer your queue. Katja Obring put the dynamic precisely: the slow part of shipping used to be writing the code, and most testing setups still assume that is true. The bottleneck moved. It did not disappear. It slid.
Manual review also misses the failure mode that matters most. Reading code tells you whether the code is well written. It does not tell you whether the code does what you actually meant. This is the same reason [a single validation layer is not enough for AI tool calls](/blog/two-layer-ai-tool-validation): the output can be perfectly formed and still semantically wrong. Those are different questions, and the gap between them is where shipped bugs live. You can review a clean, well-structured function for an hour and never notice it solves the wrong problem, because the spec for the right problem was never written down. It only lived in your head, and your head is not something a reviewer can diff against.
## The reframe: verification is a property of the loop, not the reviewer
Here is the shift. Stop thinking of verification as something a person does to finished code. Start thinking of it as something the build loop does to itself, continuously, against a standard you set up front.
Sydney Runkle of LangChain laid out the cleanest version of this in [her writing on loop engineering](https://x.com/sydneyrunkle/status/2066928783534289358). Her framework has a dedicated verification loop, what she calls Loop 2, where a grader checks the agent's output against a rubric and, if it fails, sends the result back with feedback to try again. The agent does not get to declare itself done. A grader decides, against a rubric, and the rubric is the thing you control.
Sit with what that rubric is. It is a written, checkable description of what "working" means for this specific change. Which is to say: it is an acceptance criterion. The thing that closes the verification gap is not a smarter reviewer. It is a criterion the output gets measured against, written before the code exists, so that "done" is a fact the loop can check instead of an opinion you have to form by reading. Matt Van Horn, writing on the same theme, put the principle in one line: the loop is not the magic, the feedback inside it is.
That is the reframe. The verification gap is not a reviewing problem. It is a planning problem wearing a reviewing problem's clothes. You cannot verify what you never defined.
## Two ways to close "is it done?"
The contrast is sharpest when you put the two approaches side by side.
The old way, generate then inspect:
> Ship five PRs from the agent. A human reads each one top to bottom, holding the intended behavior in their head, hoping to spot the diff between what was meant and what was written. Trust comes from one person's attention, and it does not scale past that person.
The new way, define then verify:
> Before the agent writes anything, the change has acceptance criteria: authenticated users can filter contacts by company; unauthenticated users redirect to /login; the filter persists across page reload. The agent builds against those. Each criterion is checked with evidence. "Done" is the criteria passing, not a human's gut feeling after a read.
The first one gets slower the more the agent produces. The second one gets faster, because the standard is reusable and the checking is mechanical. That is the only version of this that survives contact with an agent that ships faster than you can read.
## Where BrainGrid fits
This is the gap BrainGrid is built to close, and it is why we describe the work as [a loop instead of a pipeline](https://braingrid.ai/loop): Plan, Build, Verify, Repeat. The Planning Agent turns your idea into a requirement with acceptance criteria before any code is written, so the standard exists up front instead of living in your head. The Builder Agent builds against that requirement, in our cloud sandbox with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. Then Verify does the part the verification gap is actually about: every acceptance criterion is checked, with evidence, and the feature is not done until the evidence says it does what you intended.
The point is not that BrainGrid reviews code for you. Code review tells you the code is well written. Verification tells you it does what you meant, and it can only do that because the meaning was captured as criteria before the build. The plan is what makes verification possible. Everyone else sells speed of generation. The gap is on the other side.
There is an honest limit here worth naming. Acceptance criteria are only as good as your ability to write them, and some intent is genuinely hard to pin down before you see the thing running. Visual taste, feel, the exact phrasing of a confirmation message, those resist criteria and you will still eyeball them. The verification gap does not vanish; it shrinks to the part that genuinely needs a human, and stops swallowing the 80% that did not.
## What this means if you are building right now
If you are shipping features with Claude Code or Cursor today, here is the concrete implication. Your bottleneck is no longer how fast you can produce code. It is how fast you can trust it. And every hour you spend reading agent output line by line is an hour the gap is winning, because the agent will out-generate your reading speed every single day.
The move is to push the verification earlier. Not "review the PR harder at the end," but "define what done means before the agent starts," so that by the time there is code, most of the trust question has already been answered by criteria the build was checked against. You will still review. You will review a lot less, and what you review will be the genuinely ambiguous part instead of all of it. That shift, from reading everything to checking the standard, is what we have called [the oversight premium](/blog/the-oversight-premium): the scarce skill is no longer writing code, it is knowing what good looks like and confirming you got it.
Code got cheap. Trust did not. The teams that win the next year are not the ones generating the most code. They are the ones who closed the distance between generating it and trusting it, and they closed it by writing down what "working" means before the writing starts.
## FAQ
### What is the verification gap in AI coding?
The verification gap is the growing distance between how fast AI can generate code and how fast a human can confirm that code actually works. Andrej Karpathy popularized the term: generation has scaled dramatically with tools like Claude Code and Cursor, but verification, the work of confirming the output is correct, has not. The result is a bottleneck that has moved from writing code to trusting it.
### Why is the verification gap getting wider as models improve?
Because better models produce more plausible code, and plausible-but-wrong code is harder to catch than obviously-wrong code. A weak model writes errors you spot at a glance. A strong model writes a subtle bug buried in clean, well-structured code that a human reviewer skims right past. Capability moves errors from obvious to subtle, and subtle is exactly where manual review fails, so the gap grows rather than shrinks.
### Can't I just review AI-generated code more carefully?
Careful review does not scale and misses the most important failure mode. If an agent opens five pull requests in the time you used to write one, reading each one end to end makes you the bottleneck and multiplies your work. Worse, reading code tells you whether it is well written, not whether it does what you meant. The intended behavior has to be written down as criteria for verification to mean anything.
### How do acceptance criteria close the verification gap?
Acceptance criteria are a written, checkable definition of what "working" means for a specific change, captured before the code is generated. They turn "done" from an opinion a human forms by reading into a fact the build loop can check against. Sydney Runkle's loop-engineering framework describes this as a verification loop where a grader checks output against a rubric; that rubric is an acceptance criterion. You cannot verify what you never defined.
### Does verification replace code review entirely?
No. Verification and code review answer different questions. Code review tells you the code is well written and idiomatic. Verification tells you the code does what you intended, measured against acceptance criteria with evidence. Some intent, like visual taste or the exact feel of an interaction, still needs a human eye. The goal is not to eliminate review but to shrink it to the genuinely ambiguous part instead of every line.
*[BrainGrid](https://braingrid.ai) is the system that takes your idea to a live product you can trust, running the loop Plan, Build, Verify, Repeat so a feature is not done until the evidence says it works. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Kiro vs BrainGrid: Two Takes on Spec-Driven Development
Source: https://www.braingrid.ai/blog/kiro-vs-braingrid-spec-driven-development
Published: 2026-06-20T00:00:00Z
Kiro and BrainGrid agree on the one thing most AI coding tools get wrong: you should write the spec before you write the code. They disagree on almost everything after that.
That disagreement is the whole point. Spec-driven development is having a moment because the industry finally noticed that a vague prompt is a confident mistake machine. But "write a spec first" is a method, not a product. The interesting question is where the spec lives, who owns it, and what it is allowed to control. Kiro answers one way. BrainGrid answers another. If you are choosing between them, the answer depends less on which is "better" and more on what you are actually trying to do.
This is not a teardown. Kiro is a genuinely good piece of software, and AWS shipping a spec-first IDE did more to popularize this idea than any blog post could. The honest take is that they solve adjacent problems, and the difference is structural, not cosmetic.
## What Kiro's Spec-Driven Development Actually Is
Kiro is an agentic IDE, a fork of VS Code with spec-driven development built into the editor. You start in plain English, and Kiro walks you through three phases before it writes production code: a requirements document (user stories plus acceptance criteria, often in EARS syntax), a design document with architecture and sequence diagrams, and a `tasks.md` file of sequenced, trackable work it can then execute. AWS describes it as moving "away from unstructured vibe coding by forcing users to establish structured specifications before generating any code."
The strength is obvious the first time you use it. As one developer put it after a month with the tool:
> "Kiro did not invent good engineering practices. It made them unavoidable."
That is the real value of Kiro. The spec stops being optional. The requirements, design, and tasks files sit in your repo as `.md` artifacts, and the human stays in the loop at every phase: you review the requirements, refine the design, then let the IDE run the tasks. Martin Fowler's team, comparing Kiro to Spec Kit and other tools, called it one of the more complete takes on the [spec-first workflow](https://martinfowler.com/articles/exploring-gen-ai/sdd-3-tools.html).
So if Kiro nails the spec, what is left to compare?
## The Reframe: The Spec Outlives the Editor
Here is the assumption worth flipping. We tend to think of the spec as something the tool produces. A by-product. You open the IDE, it generates a requirements doc, and the doc is scaffolding for the code that matters.
Invert it. The spec is the asset. The code is the disposable part.
That sounds backwards until you watch what happens over six months. Models get swapped. You start on one agent and move to another because a new one got better at your stack. The codebase gets rewritten twice. What survives every one of those changes is the record of what you decided and why: the requirement, the acceptance criteria, the evidence that a feature did what you intended. Boris Cherny, who reports writing 100% of his Claude Code contributions with Claude Code, has [said his job now is to write loops](https://x.com/sydneyrunkle/status/2066928783534289358) and make sure they can verify themselves. The loop is the thing he owns. The model is rented.
Once you see the spec as the durable asset, one question decides everything: is your spec free to move?
In Kiro, the spec lives inside the editor. That is a deliberate, defensible choice. It is also a constraint. The requirements, the design, the task execution, and the verification all happen in one place, tied to one IDE. If your team standardizes on Kiro, that is a feature. If half your team uses Claude Code in the terminal, someone is on Cursor, and your non-technical co-founder works in a browser, the spec is now trapped in a tool only some of you opened.
## Where BrainGrid Sits
BrainGrid takes the spec out of the editor and puts it one layer up, above your coding tools.
You describe an idea, and the Planning Agent turns it into a requirement with acceptance criteria, data models, and designs, challenging the vague parts before any code is written. Then the Builder Agent builds it, and this is where the structural difference shows. You can build in BrainGrid Cloud, a sandbox with live preview that opens a pull request, or you can build on your own computer in your GitHub repo with Claude Code, Cursor, or Codex over MCP. Same plan, same acceptance criteria, whichever agent you point at it. Swap the agent, swap the model, keep the workflow.
That is the contrast in one line. Kiro is the IDE where spec-driven development happens. BrainGrid is the planning and verification layer that feeds spec-driven development to whatever agent you already use.
Consider the difference concretely.
Kiro's way: open the Kiro IDE, generate a spec, design, and tasks inside it, let the IDE execute the tasks, review the result in the same editor.
BrainGrid's way: describe the feature in the web app, get a readiness-scored requirement with acceptance criteria, then build it in the Cloud sandbox or hand the plan to Claude Code in your existing repo, and verify the result against those criteria no matter where it was built.
Neither is wrong. They optimize for different shapes of team. Kiro optimizes for a developer who wants the whole loop in one editor. BrainGrid optimizes for a builder, or a mixed team, who wants the plan to be portable and the verification to be the same standard regardless of which agent did the work.
## The Part Both Get Right, and the Part That Is Harder
The reason this comparison matters is that both tools take verification seriously, and verification is the load-bearing wall of any spec-driven workflow. A spec that nobody checks against is just a longer prompt. Sydney Runkle of LangChain describes the second layer of a real agent loop as a grader that "checks the agent's output against a rubric and, if it fails, sends the result back with feedback." Acceptance criteria are that rubric. Kiro generates them. BrainGrid generates them too, and treats a feature as unfinished until the evidence says it does what you intended.
The honest trade-off is this. Putting the spec inside the IDE, as Kiro does, makes the loop tight and immediate: requirements, design, code, and check all in one window, with no handoff. Putting the spec above the tools, as BrainGrid does, adds a layer between you and the code, and in exchange the plan and the verification standard stay the same no matter how many agents, models, or teammates touch the work. Tight-and-local versus portable-and-consistent. That is the real decision, and it depends entirely on whether your team builds in one tool or many.
If you are a solo developer who lives in one editor and likes everything in one place, Kiro's integrated approach may simply feel better. If you are a founder coordinating a non-technical co-founder, a contractor on Cursor, and yourself on Claude Code, a spec trapped in one IDE is a spec half your team cannot see.
## What This Means If You Are Choosing Right Now
If you are evaluating spec-driven tools this quarter, stop asking which one writes better specs. Both write good specs. Ask two questions instead.
First, does your team build in one tool or several? If one, an integrated IDE like Kiro removes friction. If several, a portable planning layer keeps everyone working against the same definition of done.
Second, who needs to read the spec? If it is only the developers in the editor, in-editor is fine. If a non-technical founder, a PM, or a client needs to see what "done" means before and after it ships, the spec has to live somewhere they can reach.
The spec you write today will outlast the model that builds against it and probably the editor you wrote it in. The tools change. The workflow shouldn't. Spec-driven development is the right instinct either way; the only question is whether you let the spec move with you.
## FAQ
### What is Kiro's spec-driven development?
Kiro's spec-driven development is a workflow built into the Kiro IDE that takes a plain-English prompt through three phases before writing production code: a requirements document with user stories and acceptance criteria (often in EARS syntax), a design document with architecture, and a `tasks.md` file of sequenced work the IDE then executes. The goal is to replace unstructured prompting with a structured spec the AI follows.
### Is BrainGrid an alternative to Kiro?
They overlap on planning but solve different problems. Kiro is an AI IDE where the spec-driven workflow happens inside the editor. BrainGrid is a planning and verification layer that sits above your coding tools, so the same spec and acceptance criteria can drive Claude Code, Cursor, Codex, or BrainGrid's own Cloud sandbox. If you want everything in one editor, Kiro fits. If you want the plan to be portable across agents and visible to a mixed team, BrainGrid fits.
### What is the difference between Kiro and Spec Kit?
Both bring spec-driven development to AI coding, but Kiro is a full IDE with the workflow built in, while GitHub's Spec Kit is a set of files and commands you add to an existing project and run through your own agent. Kiro is the editor; Spec Kit is a methodology you bolt on. BrainGrid is closer to neither: it is a hosted planning and verification layer that feeds any agent. See our [BrainGrid vs Spec Kit](/braingrid-vs-spec-kit) comparison for that pairing.
### Does spec-driven development work with Claude Code or Cursor?
Yes. Spec-driven development is a method, not a single tool, so it works with any capable agent. Kiro builds the spec into its own editor, while BrainGrid lets you write the requirement and acceptance criteria once and hand them to Claude Code or Cursor in your own repo over MCP. The agent does the building; the spec defines what "done" means and gets checked against the result.
### Do I need acceptance criteria for spec-driven development?
Acceptance criteria are the part that makes spec-driven development more than a longer prompt. They are the rubric your agent's output gets checked against, the difference between "the code looks done" and "the evidence says it does what you intended." Both Kiro and BrainGrid generate them; the value is having them written before the agent starts and verified after it finishes. Our guide on [writing acceptance criteria an AI agent can verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify) covers the craft.
Spec-driven development is the right instinct. The only real choice is whether your spec is free to move with you. [BrainGrid](https://braingrid.ai) is the system that takes an idea to a live product you can trust, keeping your plan and your definition of done portable across every agent you use. Try it at [braingrid.ai](https://braingrid.ai).
---
# Claude Code Memory: The State File Pattern (and Where It Falls Short)
Source: https://www.braingrid.ai/blog/claude-code-memory-state-file-pattern
Published: 2026-06-19T12:00:00Z
Giving your coding agent a memory feels like the obvious fix for the most annoying thing about AI coding: every session starts from zero. So you turn on Claude Code's auto memory, or you stuff a CLAUDE.md full of context, and for a week it feels solved. Then the agent does something baffling, and you trace it back to a note it wrote to itself three weeks ago that is no longer true. The memory did not make the agent smarter. It made the agent confidently wrong, and harder to debug.
That is the claim worth sitting with. More memory is not the same as more reliability. A coding agent that remembers everything you ever told it, including the things that have since changed, is not a teammate with experience. It is a teammate working from a stale runbook nobody updated.
## How Claude Code memory actually works
Start with the mechanics, because the term "memory" hides three different things. Claude Code has a few layers, and conflating them is where most of the confusion comes from.
The first layer is the **CLAUDE.md file**, the one you write by hand. It lives in your repo, it holds your conventions, your build commands, and your house rules, and the agent reads it at the start of every session. This is the layer you control. The second layer is **auto memory**, where Claude saves notes for itself as it works, debugging discoveries, commands that worked, decisions it made, so it can accumulate knowledge across sessions without you typing anything. The official docs describe it plainly: auto memory lets Claude accumulate knowledge across sessions without you writing anything. The third layer is the live conversation, the context window, which evaporates the moment the session ends.
The distinction matters because the layer that feels most effortless, auto memory, is the one you control least. It writes itself, in a Claude-specific location, in the background, and it keeps doing so whether or not the things it recorded are still accurate.
## The reframe: stale memory is worse than no memory
Here is where the obvious fix turns on you. A real practitioner, posting the day before this was written, put the problem more sharply than any vendor would:
> I've seen so many times that stale memory caused the agent to make bad decisions. The information it puts into those memory files is inherently stale in a constantly-evolving project, and the agent would often trust the memory instead of looking up the latest information.
>
> [@kunchenguid on X](https://x.com/kunchenguid/status/2067728608584675465)
Read that twice, because it inverts the whole premise. The danger is not that the agent forgets. The danger is that it remembers, and trusts the memory over the code in front of it. In a project that changes daily, which is every project worth building, a note from two weeks ago is not context. It is a confidently stated falsehood the agent will act on without checking.
The same post raises a second cost that is easy to miss: auto memory stores into a Claude-only location that other agents do not share. If you build with Claude Code today and want to try Cursor or Codex tomorrow, that accumulated memory does not travel. You have quietly built lock-in into your own workflow, one auto-saved note at a time. The portable alternative people land on is an [AGENTS.md](/context-engineering)-style file, plain markdown in your repo that any agent can read.
So the instinct to "give the agent a memory" splits into two very different moves. One is letting a tool silently accumulate notes you never review. The other is deliberately writing down the durable facts about your project in a place you own and update. The first feels effortless and rots. The second takes work and compounds.
## The state file pattern
The pattern experienced builders converge on is not a database or a vector store. It is a file. A short, deliberately curated **state file** that holds the small set of things that are true about your project and unlikely to change session to session: the architecture, the conventions, the commands, the decisions you have already made and do not want re-litigated. The agent reads it at the start of every run. You, not a background process, decide what goes in it.
The contrast with auto memory is the whole point.
> Auto memory: the tool writes notes to itself as it works, in its own location, and trusts them later. You never see most of them, and stale entries quietly steer the agent wrong.
>
> State file: you write the durable facts, in your repo, in plain markdown. You can read it, diff it, and delete a line the moment it stops being true.
A state file is to a coding agent what a README is to a new hire. It does not try to capture everything that happened. It captures what matters and stays current because a human owns it. The 200-line cap people complain about in auto memory is not really the limitation; the limitation is that nobody is curating. A good state file is short on purpose. The discipline is in what you leave out.
This works, with one honest caveat. A state file is durable context, not a definition of done. It tells the agent how your project is built and what to assume. It does not tell the agent what this specific feature is supposed to do, or how you will know it worked. Memory, even good memory, is background. It is not a spec. And that gap is exactly where AI builds go sideways: not because the agent forgot your conventions, but because nobody ever wrote down what "done" meant for the thing it was building.
## Where memory ends and a spec begins
This is the line that matters, and it is the one the memory discourse keeps walking up to without crossing. Models are stateless. Your product is not. The job is to put the durable truth of your product somewhere outside the conversation, where it survives the session, survives the model upgrade, and survives the switch from one agent to another.
A state file is the lightweight version of that idea: durable context the agent reads every time. But context tells the agent how to work, not whether it succeeded. The heavier, more valuable version is a requirement with acceptance criteria, the durable record of what each feature is meant to do and the evidence that proves it did. That is the gap [BrainGrid](https://braingrid.ai) closes. Instead of hoping an auto-saved note still holds, you describe the feature in plain language and the Planning Agent turns it into a requirement: the conventions and context captured as the product's background, the task as a scoped requirement, the constraints as explicit acceptance criteria. That requirement is durable and yours. When you build, against [Claude Code, Cursor, or Codex](/ai-coding-agents) in your own repo or the Builder Agent in a managed sandbox, the agent works from that record, and verification checks the result against the same criteria you set. Every decision, criterion, and verification accumulates per product, so the next session does not start from zero and does not start from a stale guess either. It starts from a record you trust because you can read it.
The difference from auto memory is the difference between a note an agent wrote to itself and a spec a human wrote on purpose. One you hope is still true. The other you verified. This is the same move we make from the prompting side in [structured prompting is just a spec](/blog/structured-prompting-is-just-a-spec): the durable artifact is the written definition of what you want, not the conversation that produced a result once.
## What this means for you
If you build with Claude Code right now, the practical move is two-part. First, be deliberate about memory: keep a curated state file (or CLAUDE.md) with your durable conventions, and treat auto memory with suspicion, review what it stores, or turn it off, rather than trusting notes you never read. Second, and this is the part the memory tools cannot do for you, stop relying on memory to carry the thing it was never meant to carry. Your conventions belong in a state file. What "done" means for each feature belongs in a spec with acceptance criteria, checked with evidence. The first keeps the agent oriented. The second keeps it honest.
The builders who get reliable results from coding agents are not the ones with the most memory. They are the ones who decided, on purpose, what their agent should treat as true, and then verified the rest. Memory is the background. The spec is the contract. Confuse the two and you get an agent that remembers everything and is sure about nothing.
## FAQ
### How does Claude Code memory work?
Claude Code has three distinct layers. The CLAUDE.md file is one you write by hand in your repo; it holds your conventions, commands, and rules, and the agent reads it at the start of every session. Auto memory is separate: Claude writes notes to itself as it works, saving build commands, debugging discoveries, and decisions across sessions without you typing anything, stored in a Claude-specific location. The third layer is the live conversation context, which is lost when the session ends. The layer you fully control is CLAUDE.md; auto memory writes itself in the background.
### What is the difference between CLAUDE.md and auto memory?
CLAUDE.md is human-authored and curated: you decide what goes in it, you can read and edit it, and it lives in your repo in plain markdown. Auto memory is agent-authored: Claude Code accumulates its own notes as it works, in its own location, and references them in future sessions without you reviewing them. The practical trade-off is control versus effort. CLAUDE.md takes work to maintain but stays accurate because a human owns it. Auto memory is effortless but can go stale in a fast-changing project and steer the agent toward decisions based on outdated notes.
### Should I turn off Claude Code auto memory?
It depends on how fast your project changes. In a stable codebase, auto memory can save you from re-explaining setup. In a project that changes daily, stale auto-memory notes are a known failure mode: the agent may trust an outdated note over the current code. Many experienced users prefer to keep durable facts in a curated CLAUDE.md or AGENTS.md file they control, and either review auto memory periodically or disable it, rather than trusting notes they never see. The portable, agent-agnostic alternative (AGENTS.md) also avoids tying your accumulated context to one tool.
### What is the state file pattern for AI coding agents?
The state file pattern is keeping a short, human-curated file in your repo that holds the durable facts about your project: architecture, conventions, commands, and decisions already made. The agent reads it at the start of every session, so it does not start from zero, and because a human owns and updates it, it does not go stale the way auto-saved notes do. It is the lightweight way to give a coding agent persistent context. Its limit is that it describes how your project works, not what a specific feature is supposed to do; for that you need a requirement with acceptance criteria.
### Can Claude Code remember context across sessions?
Yes, in two ways with different reliability. A CLAUDE.md or AGENTS.md file gives it durable context you control on every session. Auto memory gives it self-written notes that persist but can drift out of date. Neither is a substitute for a record of what each feature is meant to do. To carry that across sessions reliably, you want the intent captured as a durable spec with acceptance criteria, outside the conversation, so the next session starts from a verified record rather than a stale note or an empty context window.
*[BrainGrid](https://braingrid.ai) turns your project's durable context and intent into a spec your coding agent builds against and is verified by, so no session starts from zero or from a stale note. Try it at [braingrid.ai](https://braingrid.ai).*
---
# AI Task Management for Builders Who Ship With Agents
Source: https://www.braingrid.ai/blog/ai-task-management-for-builders-who-ship-with-agents
Published: 2026-06-18T12:00:00Z
Search "AI task management" and you will get fifty tools that schedule your calendar and rewrite your to-do list. They are good at that. None of them solve the problem you actually have. Because if you ship software with a coding agent, your hardest task is not remembering what to do next. It is describing the work clearly enough that an agent can do it, and knowing for sure when it is actually done.
That gap is why the term means two completely different things right now. For most people, AI task management means an assistant that prioritizes your inbox and blocks out focus time. For builders, it means something else entirely: managing the queue of work you hand to an agent that writes real code. A recent [Hacker News thread on "open-source task management for AI agents"](https://news.ycombinator.com/item?id=47165602) put it plainly: the app's whole job is to poll a task queue, spawn the agent, handle retries, and track what got done. That is not a to-do list. That is a build system with a memory.
Here is the hypothesis worth testing: the better your coding agent gets, the less your task list looks like a list of reminders and the more it looks like a specification. Speed was never the bottleneck. Clarity was.
## A to-do list tells you what. A task for an agent has to tell it how.
When you write a task for yourself, you can be vague on purpose. "Fix the signup flow" is fine, because your brain fills in the rest. You know which bug, you know what good looks like, you know when to stop. The note is a pointer to context you already carry.
Hand that same line to a coding agent and watch what happens. It will fix *a* signup flow. Maybe it adds validation you did not ask for. Maybe it rewrites your auth logic to match a pattern from its training data. Maybe it "fixes" the symptom and leaves the cause. One vibe coder on Reddit described the agent that [decided to add a "productivity score" system they never mentioned](https://www.reddit.com/r/vibecoding/comments/1u391i3/what_i_learned_building_a_personal_finance_app/), and then spent two sessions stripping it back to what they actually needed. The task was clear in their head. It was not clear in the queue.
This is the reframe most task tools miss. The hard part of AI task management for builders is not capture or scheduling. It is the gap between what you meant and what you wrote down. An agent has no shared context to fall back on. Whatever the task does not say, the agent gets to decide. And the more autonomy you give it, the more decisions nobody actually wrote down.
> "AI agent task management involves using autonomous, self-directing AI to generate, prioritize, schedule, and delegate tasks." That is Google's AI Overview definition of the category, and it is exactly the wrong emphasis for builders. The agent generating and delegating tasks is the easy part. The hard part is making each task specific enough that "delegate" does not mean "guess."
Notice how that flips the usual pitch. Vendors sell you autonomy: the agent decides what to work on next. But for software, autonomy without a clear target is how you get a confident agent shipping the wrong thing fast. The task is where you remove the guessing.
## What a real task for an agent contains
Compare the two. This is a task as a reminder:
> Add filtering to the contacts page.
This is a task an agent can build against and you can check:
> Add a filter control to the contacts table. Users can filter by company name and by last-contacted date. Filtering updates the table without a full page reload. An empty filter shows all contacts. Only authenticated users can access the filtered view; unauthenticated users redirect to /login. Done means: filtering by company returns only matching rows, the date filter accepts a range, and the existing sort still works after a filter is applied.
The second one is longer, and that length is the entire point. Every sentence you add is a decision the agent no longer makes blindly, and a thing you can later check actually happened. The first task can "succeed" while doing almost anything. The second one can only succeed one way. That last clause, the "done means" part, is what turns a task into something verifiable instead of something you have to read the diff to trust.
This is the difference between a task list and a specification, and it is why builders keep outgrowing generic AI task managers. Motion and Reclaim optimize *when* you do work. They have nothing to say about whether the work an agent produced matches what you asked for. For a builder, that second question is the only one that matters, because you are the one who has to approve the result.
## Task management is where verification gets cheap or expensive
There is a hidden cost in every vague task, and you pay it later. When the agent finishes, you have to figure out whether it did the right thing. If the task only said "add filtering," that check is expensive: you open the diff, read the code, click through the app, and hope you notice what is missing. If the task said "done means filtering by company returns only matching rows," the check is cheap: you try exactly that, and either it works or it does not.
```mermaid
flowchart LR
A[Vague task: add filtering] --> B[Agent builds something]
B --> C[You read the diff and guess if it's right]
C --> D{Looks done?}
D -->|maybe| E[Ship and hope]
F[Task with criteria: done means X, Y, Z] --> G[Agent builds against criteria]
G --> H[Check each criterion directly]
H --> I{Evidence says done?}
I -->|yes| J[Merge with confidence]
```
The work of verification does not disappear when you write better tasks. It moves. Either you do it after the build by reading code you might not fully understand, or you do it before the build by writing down what done means. Front-loading is cheaper because you are deciding the target while the context is fresh, not reconstructing it from a diff three features later. One builder on Hacker News captured the alternative perfectly when he said the [investment in reviewing AI code is often deeper than writing it from scratch](https://news.ycombinator.com/item?id=48002442). A task that defines done is how you keep that review from swallowing your day.
This is the part that compounds. A reminder is gone the moment you check it off. A task with acceptance criteria becomes a record: this is what we built, this is what done meant, this is the evidence it was met. Run twenty features that way and you have a product that remembers its own decisions. Models are stateless. Your product does not have to be.
## Where BrainGrid fits
This is the exact problem [BrainGrid](https://braingrid.ai/agentic-engineering) is built around. You describe what you want in plain language, and the Planning Agent turns it into a requirement with acceptance criteria, then breaks larger ideas into AI-ready tasks. Each task carries its own definition of done, so the work you hand off is already specific enough to build against and check. Writing that definition is a craft in itself, and it is worth learning [how to write acceptance criteria an AI agent can actually verify](https://braingrid.ai/blog/how-to-write-acceptance-criteria-ai-agent-can-verify). The Builder Agent does the work, either in a cloud sandbox with a live preview or in your own GitHub repo through Claude Code, Cursor, or Codex over MCP. Then verification checks the build against every criterion, and the feature is not done until the evidence says it matches what you intended.
It is the same closed loop for every feature: plan it, build it, verify it, repeat. That loop is the backbone of [any real agentic workflow](https://braingrid.ai/blog/what-is-an-agentic-workflow), and the task queue is not a separate tool bolted on the side. It is the spec the verifier checks. That is what generic AI task managers cannot give a builder, because they were never designed to know what your software is supposed to do.
The honest trade-off: writing tasks this way is more work up front than typing "fix signup." If you are throwing together a weekend prototype you will never maintain, that overhead is not worth it, and a quick prompt is the right call. The structure pays off the moment the app matters, the moment a second person depends on it, the moment "I think it works" is not good enough. That is the line where a reminder has to become a specification.
## What this means for how you work
If you ship features through a coding agent, stop treating your task list as a memory aid and start treating it as the interface to the agent. Every task is an instruction the agent will follow literally and a claim you will later have to verify. The clearer the task, the cheaper the verification, and the less time you spend reading diffs to find out what the agent quietly decided on your behalf.
The builders pulling ahead right now are not the ones with the fastest agent. They are the ones whose tasks are specific enough that fast is actually useful. Give an unclear target to a fast agent and you just reach the wrong place sooner. The task is where you point it.
## FAQ
### What is AI task management for builders?
For most people, AI task management means an assistant that prioritizes your to-do list and schedules your calendar. For builders shipping with coding agents, it means managing the queue of work you hand to an agent that writes real code: describing each task clearly enough to build against, and defining what "done" means so the result can be verified. It is closer to a specification than a reminder list.
### How is this different from tools like Motion, Reclaim, or Taskade?
Those tools optimize *when* you do work. They schedule tasks, protect focus time, and automate your calendar. They have nothing to say about whether the code an AI agent produced matches what you asked for. For a builder, that second question is the one that matters, because you are the one who has to approve the result. A builder's task tool needs to define done, not just schedule the doing.
### What makes a good task for an AI coding agent?
A good task is specific enough that the agent cannot succeed by doing the wrong thing. It names what to build, the constraints (auth, edge cases, what should not change), and an explicit definition of done: the conditions you will check to confirm it works. "Add filtering" is a reminder. "Add company and date filters; done means filtering by company returns only matching rows and the existing sort still works" is a task an agent can build against and you can verify.
### Do I need a separate AI task manager, or can I just prompt the agent?
For a throwaway prototype, a quick prompt is fine. The structure matters once the app matters: when a second person depends on it, when you maintain it over time, or when "I think it works" is not good enough. At that point you want each task to carry its own acceptance criteria so verification is cheap, and you want those criteria to accumulate into a record of what your product is and what done meant for every feature.
### How does task management connect to verifying AI-built code?
Tightly. The work of verification does not disappear, it moves. A vague task pushes the check to after the build, where you read a diff and guess if it is right. A task with acceptance criteria moves the check before the build: you decide what done means while the context is fresh, then confirm each condition directly. That is why, for builders, the task queue and the verification step are really the same system seen from two ends.
*[BrainGrid](https://braingrid.ai) turns your ideas into AI-ready tasks with built-in acceptance criteria, so the work you hand your coding agent is specific enough to build and verify. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Structured Prompting Is Just a Spec You Haven't Written Yet
Source: https://www.braingrid.ai/blog/structured-prompting-is-just-a-spec
Published: 2026-06-17T12:00:00Z
Everyone treats structured prompting as a formatting trick. Add a role line, wrap your context in XML tags, specify the output format, and the model behaves. The advice is correct and the results are real. It is also hiding what is actually going on, which is why people keep relearning the same lesson every time they switch tools. Here is the claim worth sitting with: structured prompting is not a prompting technique at all. It is specification, smuggled into a chat box one message at a time.
Look at what a structured prompt is made of and the disguise falls apart. The standard anatomy, the one every guide converges on, is role, context, task, constraints, and output format. Rename those columns. Role and context are the background and assumptions. Task is the requirement. Constraints are the acceptance criteria. Output format is the interface contract. That is not a clever way to talk to a model. That is the skeleton of a specification, the same one engineers have written for fifty years, retyped from memory into a prompt window because nobody told you that is what you were doing.
## What structured prompting actually is
Start with the honest definition, because the term is used loosely. A structured prompt organizes your instruction into clear, labeled components instead of a freeform paragraph. The OpenAI developer community frames the value as enforcing a consistent interaction pattern rather than treating each prompt as a one-off. Compare the two and the gap is obvious.
> Unstructured: "Write me something about our new pricing page, make it good and on brand."
>
> Structured: "Role: senior product marketer. Context: we sell to non-technical builders; brand voice is direct, no hype. Task: write the hero section for a pricing page with three tiers. Constraints: under 60 words, no exclamation marks, lead with the outcome not the price. Output: a headline, a subhead, and three one-line tier descriptions."
The second one works better, and everyone knows it works better. The interesting question is why. It is not because the model prefers labels. It is because the act of writing those labels forced you to decide things you had left vague: who the reader is, what good means, where the boundaries are. The structure did not improve the prompt. It improved your thinking, by refusing to let you stay fuzzy. Lance Cummings, writing on whether structured prompting still matters in the age of smarter models, lands exactly here: structured prompting helps the user think about the problem and structure their thoughts and needs. The output quality is a side effect. The real product is a decision, made explicit.
## The reframe: you are writing a spec, badly
Once you see that the components of a structured prompt are the components of a specification, a second thing becomes obvious, and it is uncomfortable. If structured prompting is specification, then doing it inside a chat window is the worst possible place to do it. A chat prompt is disposable. You write it, you get a result, and the thinking that went into it evaporates when the session ends. Next feature, next session, you type the role and the context and the constraints again, slightly differently, and the model behaves slightly differently, and you wonder why your results are inconsistent.
Martin Fowler, describing what he calls Structured-Prompt-Driven Development, names the cost of leaving it informal:
> Ambiguous requirements become code quickly, and misunderstandings scale with them.
>
> [Martin Fowler, "Structured-Prompt-Driven Development"](https://martinfowler.com/articles/structured-prompt-driven/)
That is the whole problem in one sentence. The faster the model turns your words into output, the more expensive your vagueness becomes, because there is no slow human step left to catch it. Fowler's response is to treat prompts as first-class, version-controlled artifacts rather than ad-hoc chat logs. Which is the engineering community arriving, from the prompting side, at the thing the requirements community has always known: the valuable artifact is the written, durable definition of what you want, not the conversation that happened to produce a result once.
So the trajectory of anyone who gets serious about structured prompting is always the same. You start by adding a role line. Then you build a reusable template so you stop retyping it. Then you keep the templates in a file. Then you version that file. Each step is a step away from prompting and toward specification, and most people walk the whole path without noticing they have changed activities. The structured prompt was the larval form. The spec is what it was always becoming.
## What this means for you
If you build with AI coding agents, this changes where you spend your effort. The instinct is to get better at prompting, to collect the secret phrases and the tag syntaxes. That is optimizing the larval form. The better move is to skip ahead: write the spec once, as a durable artifact, and let every build run against it instead of reconstructing it in a prompt each time. Your third feature should not require you to re-explain who your user is and what your conventions are. That context should already exist, written down, and the agent should read it.
This is the gap [BrainGrid](https://braingrid.ai) closes, and it is the natural endpoint of the path structured prompting puts you on. Instead of composing the perfect structured prompt in a chat window, you describe the feature in plain language and the Planning Agent turns it into a requirement: the role and context captured as the product's background, the task as a scoped requirement, the constraints as explicit acceptance criteria, the output as a verifiable result. That requirement is durable. It does not evaporate at the end of a session, and it does not get retyped from memory next time. When you build, against [Claude Code, Cursor, or Codex](/ai-coding-agents) in your own repo or the Builder Agent in a managed sandbox, the agent works from that spec, and verification checks the result against the same criteria you set. The structured thinking you were doing in the prompt becomes a permanent asset instead of a disposable message. That is the loop, Plan, Build, Verify, Repeat, and it is the same idea we develop in [spec-driven development](/spec-driven-development) and [context engineering](/context-engineering).
There is a fair objection, and it is worth stating plainly. Models keep getting better at inferring what you meant from less. So is structured prompting on borrowed time, made obsolete by models smart enough to read a vague request and fill the gaps correctly? Partly yes, and that is fine, because it was never the structure that mattered. A smarter model can guess your intent better, but it cannot guess an intent you never formed. The constraint that survives every model upgrade is human clarity: knowing what you actually want and being able to state it. Structured prompting is training wheels for that skill. The spec is what you graduate to. Better models raise the floor on prompting and leave the value of a clear specification exactly where it was, which is to say, with you.
Strip away the tags and the templates and the trend, and the lesson is older than the tools: the people who get reliable results from AI are not better at phrasing requests. They are better at knowing what they want. Structured prompting is the moment you start writing that down. The only mistake is stopping at the chat box.
## FAQ
### What is an example of a structured prompt?
A structured prompt labels its parts instead of running them together in a paragraph. For example: "Role: senior product marketer. Context: we sell to non-technical builders, brand voice is direct with no hype. Task: write a three-tier pricing hero. Constraints: under 60 words, lead with the outcome, no exclamation marks. Output: a headline, a subhead, and three one-line tier descriptions." Each label, role, context, task, constraints, and output format, removes a decision the model would otherwise have to guess. The structure forces you to make those decisions explicit, which is exactly why the output improves.
### What is the difference between structured and unstructured prompts?
An unstructured prompt is freeform natural language, like "write something good about our pricing page." It is quick and fine for exploration. A structured prompt organizes the request into labeled components (role, context, task, constraints, output format) so the model focuses on the right things and you control the result. The deeper difference is on your side: an unstructured prompt lets you stay vague, while a structured one forces you to decide who the audience is, what done looks like, and where the limits are. That clarity, not the labels themselves, is what produces a better and more consistent answer.
### What are the 4 C's of prompting?
The 4 C's are a common framework for writing effective prompts: Creativity (start with a clear, strong idea of what you want), Context (explain the why and the background the model needs), Constraints (set boundaries like length, tone, and scope), and Clarity (be precise about the output structure and format). They are a lightweight version of the same components every structured prompt uses, and they map almost directly onto a specification: context and constraints in particular are just background and acceptance criteria by another name.
### Is structured prompting still necessary as models get better?
Less necessary for phrasing, just as necessary for thinking. Newer models are better at inferring intent from a vague request, so the exact tags and templates matter less than they used to. What does not change is that a model cannot build an intent you never formed. Structured prompting's lasting value was never the formatting, it was forcing you to clarify what you actually want. As models improve, the smart move is to capture that clarity once in a durable specification the agent can reuse, rather than reconstructing it in a perfectly formatted prompt every session.
### What is structured prompt-driven development?
Structured-Prompt-Driven Development (SPDD), a term from Martin Fowler, is an engineering method that treats prompts as first-class, version-controlled delivery artifacts rather than throwaway chat messages. The motivation is that ambiguous requirements turn into code fast with AI, so misunderstandings scale unless the instruction is explicit and durable. In practice it points in the same direction as spec-driven development: the valuable thing to keep and version is the clear written definition of what you want, which the agent then builds against and is checked against.
*[BrainGrid](https://braingrid.ai) turns the structured thinking you do in a prompt into a durable spec your agent builds against and is verified by, so you write it once instead of every session. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is a Pull Request? A Non-Engineer's Guide to Reviewing AI Code
Source: https://www.braingrid.ai/blog/what-is-a-pull-request-non-engineer-guide
Published: 2026-06-16T12:00:00Z
For thirty years, the person reviewing a pull request was always another engineer. The whole ritual assumed it: someone who could read the code approved the code. That assumption just broke. There is now a fast-growing group of people who own a product, ship features through an AI agent, and get asked to approve pull requests they cannot read a single line of. Nobody wrote the guide for them, because until about a year ago they did not exist.
If that is you, the standard advice is worse than useless. Every article on reviewing pull requests tells you to check variable names, scan for code smells, and verify the logic. You cannot do any of that, and being told to is what makes you feel like a fraud hovering over the merge button. So here is the contrarian claim this whole piece rests on: you do not need to read the code to review a pull request well. You need to review the thing the code was supposed to do. Those are different skills, and the second one is yours.
## What a pull request actually is
Start with the literal thing, because the jargon hides how simple it is. A pull request, usually shortened to PR, is a proposal to merge a set of code changes into your project's main version. GitHub's own docs put it exactly that way: pull requests are proposals to merge code changes into a project. The word "request" is the important part. Nothing happens to your live product until someone approves it. The PR is the agent raising its hand and saying, here is what I changed, do you want it.
The mechanics are worth picturing once. Your real product lives on a main version, the trunk everyone builds on. When your agent works on a feature, it does not touch the trunk directly. It makes a copy, called a branch, does its work there, and then opens a pull request to fold that branch back in. That isolation is a safety feature, not red tape. It means the agent can write anything it wants in the branch and your working product stays untouched until you say go. (If you have seen the term "merge request" on GitLab, it is the same thing under a different name.) The PR shows you the "diff," the exact lines added and removed, and gives you one decision: merge it, or send it back.
That decision is the entire job. Everything else is detail.
## How to review a pull request when you can't read code
The trick is to stop reviewing the code and start reviewing the behavior. An engineer reviews a PR by asking "is this code correct." You review it by asking "does this do what I asked, and what did it touch that I did not ask about." You can answer both questions without reading a line of syntax.
First, read the description, not the diff. A good pull request opens with a plain-language summary of what changed and why. If your agent opened it, that summary is your first signal. Does it describe the feature you actually asked for? If you requested a password reset flow and the summary talks about three things you never mentioned, that is a finding, and you found it without reading code. The scope of a PR should match the scope of your request. When it does not, the agent decided something on its own, and a quiet expansion of scope is the single most common way AI-built features go sideways.
Second, run it. This is the part non-engineers skip because it feels like the developer's job, and it is the most powerful thing you can do. The whole point of the [oversight role](/blog/the-oversight-premium) is that you judge the result, not the method. Open the preview, click through the feature as your user would, and try to break it the way a real person would: submit the empty form, enter the wrong password five times, use the back button mid-flow. If the feature does what you meant and survives a clumsy user, it has passed the only test that matters to your customers. If it does not, you have a concrete, specific piece of feedback to send back, in plain language, no code required.
Third, check the size. You do not need to read a diff to see how big it is, and size is a signal. A request you described in one sentence should not come back touching forty files. When it does, it usually means the agent fixed something you did not ask it to fix, or restructured code that was already working. Big, sprawling changes are where the hidden breakage lives. A reasonable instinct, even without technical knowledge, is to be more suspicious of a giant PR than a small one, and to ask the agent to explain why it is so large before you approve it.
Here is the before and after that makes the difference concrete.
> The old way: open the diff, see four hundred lines of code you cannot parse, feel unqualified, approve it because the demo looked fine, discover in production that login now breaks for anyone with a plus sign in their email.
>
> The reviewer's way: read the summary (does the scope match?), open the preview and click through the real flow including the failure cases, glance at how many files changed and ask why if it seems large, then merge only when the behavior matches what you intended.
Neither path required you to read code. One of them catches the problem.
## The trap, and the honest limit
The failure mode to name out loud: the demo looked fine. AI agents are extraordinary at producing something that works on the happy path and quietly skips the edges. The feature you watched in the demo is the eighty percent that was always going to work. The merge button is where the missing twenty percent, the malformed input, the second concurrent user, the security check nobody specified, becomes your problem or stays the agent's. Approving because the demo looked good is how the gap gets shipped.
And the honest limit, because pretending otherwise would be the same hype this post is arguing against: behavioral review is not a security audit. You clicking through a feature will not catch a subtle data leak, an injection vulnerability, or a credential left in the code. For a personal project or an internal tool, behavioral review plus good preconditions is genuinely enough to ship with confidence. For anything handling real user data or money, you still want a technical reviewer or an automated security pass in the loop. Knowing which tier you are in is part of the judgment. The reviewer's mindset gets you a long way; it does not make the deep technical review disappear.
## Make the review easier before the PR exists
The best way to review a pull request is to have written down, before the agent started, exactly what "done" looks like. Most of the dread at the merge button comes from comparing the result against a fuzzy memory of what you wanted. If instead you compare it against an explicit list of conditions you wrote up front, reviewing stops being a vibe check and becomes a checklist.
This is where [BrainGrid](https://braingrid.ai) fits, and it sits before the agent ever opens the PR. You describe the feature in plain language, and the Planning Agent turns it into a requirement with explicit acceptance criteria, the testable conditions that define done. When the Builder Agent then builds it, in a managed sandbox with a live preview or in your own repo with [Claude Code, Cursor, or Codex](/ai-coding-agents), verification checks the result against every one of those criteria, so the pull request arrives with evidence attached: here is what you asked for, and here is the proof each condition was met. You are not staring at a diff guessing. You are confirming a checklist you wrote, which is exactly the kind of review a non-engineer is qualified to do. That is the Verify step of the loop, Plan, Build, Verify, Repeat, and we go deeper on the criteria themselves in [how to write acceptance criteria an AI agent can verify](/blog/how-to-write-acceptance-criteria-ai-agent-can-verify).
Strip away the AI and the tooling and the point is old: approval has always meant taking responsibility for something you did not personally make. A manager approves work they could not have done themselves by judging the outcome against a clear standard, not by redoing the work. That is all a pull request review is now, and it is the same oversight skill at the heart of [building products as a non-engineer](/ai-for-product-managers). The code got written by something faster than you. The judgment about whether it is right is still, and increasingly, the job that is yours.
## FAQ
### How do you explain a pull request in simple terms?
A pull request is a proposal to add a set of changes to your project, with a built-in chance to review them before they go live. Picture it as the agent or developer saying "here is what I changed, do you approve?" Your real product stays untouched until you say yes. The pull request shows the exact changes and the reason for them, and gives you one decision: merge it into the main version, or send it back for more work. The "request" part matters: nothing is applied automatically.
### What is the difference between a pull request and a merge?
A pull request is the proposal and the review step; a merge is the action that actually combines the changes into your main version. You open or receive a pull request, review it, and then merging is what happens when you approve. In short, the pull request is the conversation and the decision, and the merge is the final button press that makes the change real. On GitLab the proposal is called a "merge request," which is the same concept as a GitHub pull request.
### What is the difference between git pull and a pull request?
They sound alike but are unrelated in practice. "Git pull" is a command a developer runs to download the latest changes from a shared project onto their own machine. A "pull request" is a proposal to add your changes into the shared project, with a review before it is accepted. One brings changes to you; the other proposes your changes to everyone. As a non-engineer reviewing AI-built features, the one you will deal with is the pull request, not the command.
### How do you review a pull request without reading the code?
Review the behavior instead of the syntax. Read the plain-language summary and check that the scope matches what you actually asked for. Open the preview and click through the feature the way a real user would, including the failure cases like empty forms and wrong inputs. Notice how many files changed, and be more cautious about very large changes than small ones. Approve only when the feature does what you intended and survives clumsy use. This catches the most common AI failure, an agent quietly doing more or less than you asked, without requiring you to read a single line.
### Is it safe to merge a pull request if I'm not technical?
For personal projects and internal tools, yes, provided you reviewed the behavior carefully and the feature was built against clear acceptance criteria. Behavioral review plus an explicit definition of done is enough to ship most things with confidence. The exception is anything handling sensitive user data, payments, or security: behavioral review will not catch a subtle vulnerability, so keep a technical reviewer or an automated security check in the loop for those. The safest setup is to define what "done" means before building, so the pull request arrives with evidence that each condition was met.
*[BrainGrid](https://braingrid.ai) turns your idea into acceptance criteria and verifies every change against them, so the pull request arrives with proof instead of a diff you have to decode. Try it at [braingrid.ai](https://braingrid.ai).*
---
# How to Write Acceptance Criteria an AI Agent Can Actually Verify
Source: https://www.braingrid.ai/blog/how-to-write-acceptance-criteria-ai-agent-can-verify
Published: 2026-06-15T18:00:00Z
Acceptance criteria were invented for humans to read. A product manager wrote them, a developer interpreted them, and a QA tester checked the result against them, with three brains in the loop to catch the gaps. That worked because the slack between a vaguely worded criterion and a correctly built feature got absorbed by people who could ask a follow-up question. Hand the same criteria to an AI coding agent and the slack does not get absorbed. It gets built.
That is the shift almost nobody writing about acceptance criteria has caught up to. Every guide still teaches them as an agile artifact for aligning a team. The format advice is sound, Given-When-Then, testable, no implementation detail, and you should follow it. But the stakes changed. When the thing reading your criteria is an agent that will write the code, run the tests, and declare the feature done without a single follow-up question, your acceptance criteria stop being a communication tool and become the specification the agent builds against and the only standard it checks itself by. Write them loosely and the agent will confidently ship you the wrong thing, on time.
## What acceptance criteria are, and what changed
Start with the definition the whole industry agrees on. Acceptance criteria are a set of specific, testable conditions that define when a feature is done and working as intended. They describe the what, not the how, and each one passes or fails with no middle state. Scrum Alliance puts the bar plainly: criteria must be clear to everyone involved, verifiable, and unable to be 50 percent complete. That has been the standard for two decades.
Here is what changed. In the human workflow, acceptance criteria were one input among many. The developer also had hallway conversations, Slack threads, a shared sense of the product, and the judgment to notice when a criterion did not quite make sense. An AI agent has none of that. It has the prompt, the codebase, and the criteria you gave it. Whatever you left implicit, it fills in by guessing, and it guesses in the direction of the shortest path to something that looks done.
So the criteria carry more weight than they ever did. They are no longer the summary of an agreement reached by people. They are the agreement. This is why the loop matters: you cannot verify a feature against criteria you never wrote, and an agent cannot self-correct toward a target it was never given. As we have argued in [planning in the age of capable coding agents](/blog/planning-in-the-age-of-capable-coding-agents), the more the agent does on its own, the more the upfront definition decides the outcome.
## The format an agent can verify
The most agent-friendly format is the one the industry already recommends for development: Given-When-Then. It maps directly onto how an agent reasons, a starting state, an action, an expected result, which is also exactly the shape of a test.
> Given an unauthenticated user on the login page, When they submit a valid email and password, Then they are redirected to /dashboard.
Each clause is a checkable fact. The agent can set up the precondition, perform the action, and assert the outcome. There is no interpretation left to do. Compare that with the kind of criterion that reads fine to a human and strands an agent:
> Vague: "Login should work properly and handle errors gracefully."
>
> Verifiable: "Given a user submits an email with no @ symbol, When they click sign in, Then the form shows the inline message 'Enter a valid email address' and does not call the login endpoint. Given five failed attempts within ten minutes, When a sixth is made, Then the account is locked and the response is 'Too many attempts, try again in 5 minutes.'"
The first one is not wrong. It is just unverifiable. "Properly" and "gracefully" are not conditions an agent can test, so it will ship a happy-path login, mark the story done, and you will discover what "gracefully" meant to it when a user with a typo'd email gets a blank screen in production. The second version states the exact error text, the exact threshold, and the exact behavior. There is nothing left to guess, which means there is nothing left to get wrong.
The principles behind the good version are the ones every solid guide repeats, and they happen to be precisely what an agent needs. Be specific and measurable: name the exact message, the exact limit, the exact state. Make every criterion pass-or-fail. Cover the edge cases, not just the happy path, because the happy path is the part the agent was always going to get right. The difference now is that these are not style preferences for a tidy backlog. They are the line between a feature an agent can verify and one it can only pretend to.
## The trap: criteria that sound testable but aren't
There is a failure mode that catches experienced people, because the criterion looks rigorous. "The page must load quickly." "The API should handle a reasonable load." "Search results should be relevant." These have the grammar of acceptance criteria and none of the substance. Quickly, reasonable, and relevant are not values an agent can check against, so it treats them as satisfied by default. The criterion was decorative.
The fix is to ask one question of every criterion before you hand it over: could two people, or two agents, disagree about whether this passed? If yes, it is not done. "The page must load quickly" fails the test. "The dashboard's largest contentful paint must be under 2.5 seconds on a throttled 4G connection" passes it, because there is a number and a condition and no room to argue. This is also the honest limitation worth stating: writing criteria this tight is real work, and it is work that happens before you get to see anything run. That front-loading is the trade. You pay in specification time now, or you pay in production surprises and regeneration loops later, and the second bill is always larger.
The other limit to be clear about: acceptance criteria check whether the feature does what you said, not whether what you said was right. If you specify the wrong behavior precisely, the agent will build the wrong behavior precisely and verify it as done. The criteria are only as good as the intent behind them, which is why the writing of them is the part that still needs you.
## Where this fits in the loop
This is the exact problem [BrainGrid](https://braingrid.ai) was built around, and it sits one step before the agent ever runs. You describe a feature in plain language, and the Planning Agent does the part most people skip: it asks the clarifying questions a senior engineer would, surfaces the edge cases you did not name, and turns your intent into a requirement with explicit, testable acceptance criteria. You are not staring at a blank Given-When-Then template hoping you remembered the failure modes. You are reviewing and correcting a draft that already pushed on the ambiguity.
Those criteria then do double duty. They are the specification your coding agent builds against, whether you hand them to [Claude Code, Cursor, or Codex](/ai-coding-agents) in your own repo or let the Builder Agent run in a managed sandbox. And they are the checklist verification runs at the end: every criterion is checked against the build, and the feature is not done until the evidence says it does what you meant. That is the whole point of writing them to be verifiable in the first place. As Scrum Alliance says, a criterion cannot be 50 percent complete, and now something other than a hopeful glance is enforcing that. This is the Verify step of the loop we cover across [spec-driven development](/spec-driven-development): Plan precisely, Build against the plan, Verify with evidence, repeat.
Strip away the agent and the tooling and the argument is older than any of it: a feature you cannot test against a clear standard was never really defined, you just felt like it was. Acceptance criteria have always been how teams turn a fuzzy intent into a checkable one. What changed is who is reading them and how literally. Write them for a machine that takes you at your exact word, and a strange thing happens. They get better for the humans too.
## FAQ
### What format is used for acceptance criteria?
The two most common formats are Given-When-Then and a simple checklist. Given-When-Then (the BDD format) states a precondition, an action, and an expected outcome, for example "Given an unauthenticated user, When they submit valid credentials, Then they are redirected to the dashboard." It is the most structured option and maps directly onto how a test is written, which makes it ideal for development and for AI agents. A plain checklist of testable statements works well for simpler features and non-developers. Either is fine as long as every line is specific and passes or fails with no middle state.
### What are good acceptance criteria?
Good acceptance criteria are clear, testable, and unambiguous. Each one is specific and measurable (it names exact values, messages, and states rather than words like "quickly" or "properly"), it can only pass or fail, it focuses on the user's experience rather than the implementation, and it covers edge cases instead of just the happy path. The practical test: if two people could disagree about whether a criterion was met, it is not specific enough yet. That same test is what makes criteria usable by an AI coding agent, which has no judgment to fall back on when wording is loose.
### What are the three C's of acceptance criteria?
The three C's, Card, Conversation, and Confirmation, come from the user story model. The Card is the short written story, the Conversation is the discussion that fleshes out the details, and the Confirmation is the acceptance criteria that confirm when the story is done. In an AI-assisted workflow the Conversation increasingly happens up front with a planning agent that asks clarifying questions, and the Confirmation becomes the criteria the build is verified against, but the underlying idea is unchanged: a story is not complete until there is an agreed, checkable definition of done.
### What are examples of acceptance criteria?
A clear example for a login feature: "Given a registered user enters a valid email and password, When they click sign in, Then they are redirected to /dashboard." For the failure path: "Given a user enters an email without an @ symbol, When they click sign in, Then an inline error reads 'Enter a valid email address' and no login request is sent." For a limit: "Given five failed attempts in ten minutes, When a sixth is made, Then the account locks for five minutes." Notice each one names exact behavior and exact text, so there is nothing left to interpret, which is what makes them verifiable by a person or an agent.
### What is the difference between acceptance criteria and a definition of done?
Acceptance criteria are specific to one feature or user story: they define what that particular thing must do to be accepted. A definition of done is a general checklist that applies to every story (for example, code reviewed, tests passing, documentation updated, deployed to staging). You need both. Acceptance criteria tell you whether the right thing was built; the definition of done tells you whether it was built to your team's standard of complete. For an AI agent, the acceptance criteria are what it verifies the behavior against, while the definition of done captures the surrounding quality bar.
*[BrainGrid](https://braingrid.ai) turns your plain-language idea into testable acceptance criteria your coding agent builds against and is verified by, so "done" means proven, not promised. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is an Agentic Workflow? (With Real Examples)
Source: https://www.braingrid.ai/blog/what-is-an-agentic-workflow
Published: 2026-06-15T12:00:00Z
Search "agentic workflow" and you will be told it is about frameworks. LangGraph for stateful graphs, CrewAI for multi-agent role-play, AutoGen for conversations between bots. Pick your orchestration layer, wire up the nodes, and you have an agentic workflow. That answer is technically correct and practically useless if you are a builder trying to ship a product.
Because the framework is not the workflow. The workflow is the loop the agent runs inside it: read the goal, decide the next step, act, check the result, and go again until the job is done or it gets stuck. You can run that loop in LangGraph or in a single Claude Code session with no framework at all. The interesting question was never which graph library to use. It is what happens when an agent gets to decide what to do next, and how you stay in control of the outcome when it does.
## What an agentic workflow actually is
Strip away the vendor framing and the definition is simple. An agentic workflow is a process where an AI agent pursues a goal by reasoning about what to do, taking actions with real tools, observing what came back, and adjusting, instead of following a fixed script you wrote in advance. IBM lands on the same place: agentic workflows are AI-driven processes where autonomous agents make decisions, take actions, and coordinate tasks with minimal human intervention.
The word doing the work in that sentence is "decisions." A traditional automation runs the steps you defined: if this, then that, in the order you set. An agentic workflow is handed a goal and figures out the steps itself. That is the whole difference, and it is a big one. Automation is a player piano. An agent is a session musician who knows the song and improvises the parts.
Under the hood, most agentic workflows are built from the same four moves, which the practitioner write-ups converge on. The agent **plans**, breaking a goal into steps. It **uses tools**, calling a web search, a database, a shell command, or another agent. It **reflects**, checking its own output for errors and updating what it does next. And in bigger systems, multiple agents **coordinate**, a researcher handing findings to an executor. Plan, act, reflect, repeat. If that rhythm sounds familiar, it should. It is how a competent person works through an unfamiliar task.
## Real examples, from trivial to load-bearing
The clearest way to understand an agentic workflow is to watch one scale up in stakes.
The trivial version: you ask an agent to rename every file in a folder to a consistent format. It lists the files, reasons about the pattern, runs the rename commands, and verifies the names changed. One tool, one loop, done. Nobody loses sleep if it gets a filename wrong.
The middle version: a research agent. You ask, "find the three most-cited papers on retrieval-augmented generation from the last year and summarize the disagreement between them." The agent searches, reads, decides which results are credible, searches again to fill gaps, and synthesizes. No fixed script could anticipate which papers exist or what they argue. The agent has to decide as it goes. This is the example Microsoft's own guide to building agentic workflows leads with, because it shows reasoning, tool use, and iteration in one task.
The load-bearing version, and the one that matters most to anyone reading this: building software. You describe a feature, and a coding agent like Claude Code or Cursor plans the change, writes across multiple files, runs the tests, reads the failures, fixes them, and keeps going until the feature works. GitHub now ships this pattern directly, letting you write repository automation in plain markdown and run it as an agentic workflow inside Actions. This is not autocomplete finishing your line. It is an agent running the errand end to end.
Here is where the three examples diverge, and it is the crux of the whole topic. When the file-rename agent is wrong, you see it instantly. When the software-building agent is wrong, you might not see it for weeks, because "the demo worked" and "the product is correct" are different claims, and an agentic workflow optimizes for the first one by default.
## The part the framework tutorials leave out
Every guide to agentic workflows spends its energy on the orchestration: how to structure memory, chain tools, route between agents. Almost none of them spend a word on the thing that determines whether the output is any good. The standard.
An agent's loop has a quiet dependency. To "reflect" and decide whether its work is done, it needs to know what done means. In the file-rename task, done is obvious and self-evident. In a software feature, done is a dozen things nobody wrote down: the happy path works, but also the empty state, the auth check, the error when the input is malformed, the behavior when two users hit it at once. If those are not stated, the agent does not reflect on them. It reflects on the goal it was given, declares victory, and moves on. The loop ran perfectly. It just ran toward an incomplete target.
This is why more autonomy makes the problem worse, not better. Andrej Karpathy, who coined "vibe coding" and then [called it obsolete for serious work](https://www.youtube.com/watch?v=96jN2OCOfLs), drew the line at Sequoia's AI Ascent:
> Vibe coding is about raising the floor for everyone in terms of what they can do in software. Agentic engineering is about preserving the quality bar of professional software.
>
> Andrej Karpathy, Sequoia AI Ascent 2026
The agentic workflow raises the floor for free. Preserving the quality bar is the part that does not come in the box, and it is not a framework feature. It is a written definition of what the workflow is supposed to produce, against which the result can be checked. A loop with no standard is not autonomous. It is unsupervised.
The contrast is concrete. Consider the same feature handed to an agent two ways.
> Vague: "Add user comments to the blog."
>
> Specified: "Add comments to each blog post. A logged-in user can post a comment up to 2,000 characters. Comments display newest-first with author name and timestamp. Empty or whitespace-only comments are rejected with an inline error. Unauthenticated users see comments but get a sign-in prompt when they try to post. The post author can delete any comment on their post."
Both are buildable. The first lets the agent decide what done means, which means you find out in production. The second tells the agent exactly what to reflect against, and gives you a list to check the result by. Same agent, same model, same framework. The difference in outcome is entirely upstream of the loop.
## What this changes for you
If you are building a product with a coding agent right now, the takeaway is not "use a better framework." It is that your leverage moved. The scarce skill in an agentic workflow is no longer running the loop, the agent does that. It is defining the target the loop runs toward and proving the result hit it. Get the target right and the autonomy compounds in your favor. Get it vague and the same autonomy produces more confident, harder-to-audit wrong answers, faster.
This is the gap [BrainGrid](https://braingrid.ai) was built to close, and it sits one layer above the workflow. You describe the feature in plain language, the way you described those comments above, and the Planning Agent asks the clarifying questions a senior engineer would, surfaces the edge cases you did not name, and turns your intent into a requirement with explicit acceptance criteria. That requirement becomes two things at once: the spec your agent's loop runs against, and the checklist your result gets verified by. You can hand it to [Claude Code, Cursor, or Codex](/ai-coding-agents) in your own setup, or let the Builder Agent run it in a managed sandbox and open a pull request. Either way, verification closes the loop: every criterion is checked against the build, and the feature is not done until the evidence says it does what you meant.
That is the same closed loop we cover in [agentic engineering](/agentic-engineering) and [spec-driven development](/spec-driven-development): Plan, Build, Verify, Repeat. The agentic workflow is the Build. The standard is the Plan and the Verify. Most tutorials hand you the middle verb and skip the bookends, which is exactly why so many builders end up with a workflow that runs beautifully and produces something they cannot trust.
Strip away the framework names and the trending term, and the argument holds on its own. An agentic workflow is an agent deciding its own steps toward a goal. The more steps it decides, the more it matters that someone, you, decided what the goal actually was and how you will know it was met. The loop is not the hard part anymore. Knowing what you want and proving you got it is.
## FAQ
### What is an agentic workflow?
An agentic workflow is a process where an AI agent pursues a goal by reasoning about what to do next, taking actions with real tools, observing the results, and adjusting, rather than following a fixed script written in advance. The agent breaks a goal into steps, calls tools like web search or a code editor, checks its own output, and iterates until the task is complete or it needs help. The defining trait is that the agent makes decisions, instead of just executing steps you predefined.
### What is the difference between an agentic workflow and an AI agent?
An AI agent is the actor: a model given tools and a goal. An agentic workflow is the loop that actor runs inside, planning, acting, reflecting, and repeating toward an outcome. In practice the terms overlap, but the distinction that matters is between rigid automation and agentic behavior. Automation follows the exact steps you defined. An agentic workflow is handed a goal and decides the steps itself, which is why it can handle tasks you could not fully script ahead of time.
### What are some examples of agentic workflows?
Common examples range from trivial to high-stakes. A simple one is an agent that renames files in a folder to a consistent format, listing them, applying the pattern, and verifying the result. A middle example is a research agent that searches, reads, evaluates credibility, and synthesizes a summary across sources. The most consequential for builders is software development: a coding agent that plans a feature, writes across multiple files, runs tests, reads the failures, and fixes them until the feature works. GitHub now supports this directly through repository automation written in plain markdown.
### What are the four design patterns of agentic workflows?
Most agentic workflows are built from four recurring patterns: planning (the agent decomposes a goal into steps), tool use (it calls capabilities like search, databases, or shell commands), reflection (it checks its own output for errors and updates its next move), and multi-agent orchestration (specialized agents hand work to each other, such as a researcher passing findings to an executor). Plan, act, reflect, and coordinate, repeated until the goal is met.
### Do agentic workflows replace the need for clear requirements?
No, and this is the most common misunderstanding. An agentic workflow can reflect on its work only against the goal it was given. If the standard for "done" is vague, the agent declares victory at the demo and skips the edge cases, security, and error handling nobody specified. More autonomy makes this worse, not better, because the loop runs confidently toward an incomplete target. Clear, checkable requirements are what let an agentic workflow produce something you can actually trust, which is why tools like BrainGrid turn a plain-language idea into acceptance criteria the agent builds against and the result is verified by.
*[BrainGrid](https://braingrid.ai) is the system that turns your plain-language idea into a spec your agentic workflow can build against and be verified by, so the loop runs toward the right target. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Product Factory vs Software Factory: Which One Are You Building?
Source: https://www.braingrid.ai/blog/product-factory-vs-software-factory
Published: 2026-06-14T12:00:00Z
The phrase "software factory" is having a moment. Every team with a CI pipeline and a few coding agents now describes itself as one, and the videos and essays calling it the agentic factory model are multiplying. The pitch is intoxicating: turn your engineering org into an assembly line, and software rolls off the end faster every quarter.
Here is the problem. A factory that ships code faster is not the same as a factory that ships products you can trust. Most teams are building the first and calling it the second.
That distinction is not pedantic. It decides whether all that new speed actually helps you or quietly works against you.
## A software factory optimizes the line. A product factory optimizes the outcome.
The classic definition of a software factory is a structured, repeatable process for producing software: standardized pipelines, reusable components, automation that turns requirements into shipped code with less friction each time. It is a genuinely good idea, and it predates AI by decades. The metaphor even has a sharper version. As one widely shared framing puts it:
> In a software factory, the software you ship is one product. The factory is another.
That is the key insight and also the trap. When the factory itself becomes the product you are proud of, you start measuring the wrong thing. You optimize throughput: pull requests per week, features per sprint, how fast a prompt becomes a diff. The line gets faster. Whether what comes off the line is correct, intended, and safe to ship becomes someone else's problem, usually a human's, usually too late.
A product factory inverts the priority. It still cares about speed, but speed is in service of a different output: not "we shipped code" but "we shipped the thing we meant to, and we can prove it." The unit of work is not a merged PR. It is a verified outcome.
## Speed was never the moat
For most of software history, the bottleneck was writing the code, so getting faster at writing felt like getting better at building. AI broke that assumption in about eighteen months. When a coding agent can produce a working feature in an afternoon, throughput stops being scarce, and the thing you were optimizing stops being the thing that matters.
A developer on Hacker News, in a thread about whether agentic coding erodes a company's moat, put the discomfort exactly:
> if I can do that in an afternoon, what does "shipping faster" actually protect?
It is a serious question, and the software-factory framing has no answer to it. If everyone can stamp out code at the same speed, a faster line is not a differentiator. It is table stakes. The same thread noted how trivial it now is to reverse-engineer a product with an LLM and clean-room a clone. Speed of generation is the one thing that no longer protects you, because your competitor has the same agents you do.
So what does protect you? The thing that did not get cheap. Knowing what to build, building exactly that, and being able to prove it does what you intended. Certainty of outcome, not speed of generation. A software factory sells the second. A product factory sells the first.
## The honest version of "it works"
Walk into the gap between those two and you find the most repeated fear in AI building right now. A vibe coder on r/vibecoding described shipping a real app and then hitting a wall:
> I'm scared to deploy it for everyone to use as I don't know how much I can trust the code that Claude has generated for me.
That is not a speed problem. That builder already has the code. What they are missing is evidence. The software factory delivered the artifact and left the hardest question, "is it actually done and correct," entirely unanswered. The illusion of completeness is the software factory's signature failure: the demo looks finished, the line ran clean, and nobody can say whether the product does what was intended.
This is where the two factory models stop being a word game and start changing what you do on Monday. Consider the same feature shipped two ways:
> Software factory: "The auth feature is merged. CI is green. Ship it."
> Product factory: "The auth feature meets all nine acceptance criteria. A logged-out user hitting a paid route redirects to login, verified. A canceled payment leaves the plan unchanged, verified. Session expiry forces re-auth, verified. Here is the evidence for each. Ship it."
Green CI tells you the code is well-formed. It does not tell you the code does what you meant. Those are different claims, and only one of them lets you deploy without that pit in your stomach.
## What makes a product factory repeatable
A product factory is the model BrainGrid is built around, and the mechanism is a loop you run for every feature: **Plan → Build → Verify → Repeat**. The [Planning Agent](/blog/what-is-a-product-management-agent) turns an idea into a requirement with explicit acceptance criteria before any code is written, so "done" is defined up front instead of argued about after. The Builder Agent implements it, in a managed sandbox with a live preview or directly in your GitHub repo through Claude Code, Cursor, or Codex over MCP. Then the part the software factory skips: a feature is not done until every acceptance criterion is met with evidence. Not approved. Not merged. Verified.
That last step is what converts a fast line into a trustworthy one. It is also what makes the whole thing repeatable, because the spec you wrote to plan the feature is the same spec the verifier checks it against. You cannot verify if you do not have a plan, and the plan is what survives from one loop to the next. The cycle gets easier every time you run it, not because the agents get faster, but because the standard for "done" stops living in someone's head.
## The trade-off
A product factory is slower at the start of each feature. Writing acceptance criteria before the agent runs feels like overhead when the agent could already be generating something. On a throwaway prototype you will never ship, it is overhead, and the software-factory speed is genuinely the right call. Match the model to the stakes.
The moment the thing is real, the calculus flips. Anything with a user, a payment, or your name on it cannot afford the illusion of completeness, and the time you save by skipping verification gets repaid with interest the first time you are scared to merge twenty files you do not understand. If you are building something people will actually use, the question is not how fast your factory runs. It is whether you can trust what comes off the end of it.
Speed got cheap. Certainty did not. Build the factory that produces the expensive one.
## FAQ
### What does software factory mean?
A software factory is a structured, repeatable approach to producing software: standardized pipelines, reusable components, and automation that turns requirements into shipped code with less manual effort each cycle. The metaphor frames development as an assembly line where the process itself is engineered, not just the individual product. The idea predates AI but has surged again as teams wire coding agents into that line.
### What is the difference between a software factory and a product factory?
A software factory optimizes throughput: how fast and consistently code moves from requirement to merge. A product factory optimizes outcome: whether what was built is the thing you intended and can be proven to work. The software factory's unit of work is a merged pull request; the product factory's is a verified outcome, where a feature is not done until every acceptance criterion is met with evidence. Speed serves the line in one and serves certainty in the other.
### What is the difference between a software factory and an AI factory?
A software factory focuses on speed, standardization, and quality through automation and reusable components, producing predictable applications. An AI factory is usually described as emphasizing adaptability and probabilistic systems that learn and evolve. Both are about how software gets produced. A product factory is a different axis entirely: it is about verifying that what gets produced matches intent, regardless of whether the work is done by deterministic pipelines or AI agents.
### Is a faster software factory a competitive advantage?
Less and less. When coding agents let anyone generate a working feature in an afternoon, raw speed of generation stops being scarce, so a faster line stops being a differentiator. What still protects you is knowing exactly what to build and being able to prove you built it: certainty of outcome rather than speed of output. That is the shift from a software factory to a product factory.
If you are building something real and want each feature to come off the line verified, not just merged, [start with a plan your agent can build and you can check](/loop).
*[BrainGrid](https://braingrid.ai) is the product factory that runs Plan, Build, Verify, Repeat, so every feature ships verified against the criteria you set, not just merged. Try it at [braingrid.ai](https://braingrid.ai).*
---
# You Exported Your Lovable Project. Now What?
Source: https://www.braingrid.ai/blog/you-exported-your-lovable-project-now-what
Published: 2026-06-14T00:00:00Z
Exporting your Lovable project feels like graduation. The code is finally yours, sitting in a GitHub repo, ready for any tool you want to point at it. Most people expect the next ten features to come faster than the first ten.
For a lot of builders, the opposite happens.
The export was supposed to remove a ceiling. Instead, the first week in your own repo feels slower and shakier than the months you spent in Lovable. You open the project in Cursor or Claude Code, ask for a small change, and something three screens away breaks. You ask for the fix, and now two other things break. That is not because you exported wrong. It is because exporting changed where your code lives, not how you build it.
That distinction is the whole game. We have already covered the mechanics: [how to export your Lovable project to GitHub](/blog/how-to-download-lovable-project) in under fifteen minutes, and [how to migrate that app to Next.js](/blog/migrate-lovable-to-nextjs) when you outgrow the Vite starting point. This post is about the part nobody walks you through. The code is in GitHub. Now what?
## The export moved your code, not your method
Here is the hypothesis worth testing: the export does not graduate you out of vibe coding. It just gives vibe coding a bigger blast radius.
Inside Lovable, the platform held a lot of guardrails for you. The preview rebuilt instantly. The scope of each change stayed small because the chat-driven loop kept you close to one screen at a time. When something broke, it broke visibly, in front of you, in seconds.
In your own repo, those guardrails are gone. An AI coding agent like Claude Code or Cursor can touch fifty files in one run. It will happily refactor your auth flow to fix a button color if you let it. The same prompting style that felt productive in Lovable, describe a vibe, see what comes back, now operates over a codebase large enough to hide its mistakes.
A Hacker News developer named the feeling precisely while describing agentic coding:
> feels some kind of slot machine effect. "Maybe now I get what I want. Argh, not quite. Okay, feels nearly there."
That [slot machine loop](https://news.ycombinator.com/item?id=47962775) is survivable when each pull costs ten seconds and touches one component. It is brutal when each pull costs a multi-file agent run and you cannot tell, by reading the diff, whether the thing you asked for actually happened. Exporting did not create that loop. It removed the conditions that kept it cheap.
## The real "now what" is a definition of done
So what do you actually do the day after you export? The instinct is to start adding features immediately. Resist it for one afternoon and do three things instead.
First, get the project running locally and deploying cleanly. Your export is a Vite-based React app with your components and client logic intact, but the managed pieces, authentication, payments, AI orchestration, do not come along as standalone code. Set those environment variables, confirm a deploy to Vercel or Netlify, and prove the app works end to end before you ask an agent to change anything. You cannot tell whether an agent broke something if you never confirmed it worked.
Second, write down what the app is supposed to do. Not a roadmap. A short, plain-language description of each core flow and what "working" means for it. "A logged-out user who visits a paid page gets redirected to /login. A logged-in user sees the page. Clicking Upgrade opens Stripe checkout and, on success, sets the user's plan to pro." That paragraph is worth more than any refactor.
Third, change one thing at a time and verify it against that description before you move on.
The reason this matters is the difference between two ways of asking for the same feature:
> Vague: "Add a way for users to upgrade to a paid plan."
> Specific: "Add an Upgrade button to the account page, visible only to logged-in users on the free plan. Clicking it opens Stripe checkout. On successful payment, set the user's plan to pro and show the pro dashboard. On cancel, return them to the account page with no change. Free-plan users still see the free dashboard."
The vague version is a slot pull. You get back something plausible, you eyeball it, you hope. The specific version is a contract. You can read the result and check it line by line against what you asked for. In a small Lovable preview you could get away with the vague version because the surface area was tiny. In a real repo, the specific version is the only one that scales past your third feature.
## Where BrainGrid fits the day after export
This is the gap that turns "I exported my project" into "I am shipping features again." You have a real codebase and a capable agent. What you are missing is the thing in the middle: a plan precise enough that the agent builds the right thing and you can prove it did.
That is the loop BrainGrid runs, **Plan → Build → Verify → Repeat**, on top of the tools you already have. You describe the feature you want, the way you described the upgrade flow above. BrainGrid's Planning Agent turns that into a requirement with explicit acceptance criteria, the data model it touches, and the edge cases you would have forgotten. Then the Builder Agent implements it, either in a managed sandbox with a live preview and a pull request, or directly in your GitHub repo through Claude Code, Cursor, or Codex over MCP. Because BrainGrid works over your existing repo and your existing agent, the export you just did is exactly what makes this possible. There is no second migration. Your tools change, the workflow does not.
The part that actually fixes the slot machine is the last step. A feature is not done because the agent says it is done. It is done when every acceptance criterion is met with evidence. As we put it: you cannot verify if you do not have a plan. After an export, when you can no longer eyeball the whole app in a preview pane, that verification step is the guardrail Lovable used to hold for you, now held by your own spec instead of the platform.
## The trade-off worth naming
Writing the spec first feels slower. On feature one, it is slower. You are typing out acceptance criteria instead of firing off a one-line prompt and watching something appear.
The payoff shows up on feature four. That is the feature where the vague-prompt approach starts generating conflicting state management, duplicate auth checks, and inconsistent API patterns, not because the agent is bad, but because nobody ever told it how the pieces fit together. The builders who slow down for an afternoon to define what "done" means are the ones still shipping in month two. The ones who treat the export as permission to prompt faster are the ones quietly rebuilding from scratch by then.
Export was the right move. It gave you ownership, hosting flexibility, and any AI tool you want. It is the natural step once you have pushed past what [vibe coding tools](/vibe-coding-tools) do well. Just remember what export did not give you: a method. That part is still yours to install, and the day after you export is the easiest time to do it, before feature four makes it expensive.
## FAQ
### What do I do after exporting my Lovable project to GitHub?
Get it running and deploying cleanly first, including the environment variables and managed services that did not export. Then write a short, plain-language description of each core flow and what "working" means for it. Only then start adding features, one at a time, checking each against that description. Exporting changes where your code lives, not how you should build, so the first job is installing a way to tell whether changes actually do what you intended.
### Can you transfer a Lovable project to someone else?
Yes. In Lovable, go to Project settings, then Transfer ownership, and select a workspace member who becomes the new owner. If you are handing a site to a client without sharing your chat history, you can remix the project first to create a clean copy, then transfer ownership of the remix. For moving the code itself out of Lovable rather than the project, use the GitHub export instead.
### How do I export a project out of Lovable?
Open your project in Lovable, click the GitHub icon in the top-right of the editor, authorize the Lovable GitHub app, and create the repository. Every save then syncs to GitHub automatically. A manual ZIP download also works but does not stay in sync. We walk through the full process, and the three pitfalls that derail most exports, in our [guide to exporting your Lovable project](/blog/how-to-download-lovable-project).
### Will my Lovable app keep working after I export it?
The front end will. You get a Vite-based React app with your UI, components, and client logic intact. What does not come across as standalone code are the managed services Lovable ran for you, such as authentication, Stripe payments, and AI orchestration. You will need to reconnect those with your own keys and configuration, which is why confirming a clean local run and deploy is the first thing to do after exporting.
### When should I migrate my exported Lovable app to Next.js?
Migrate when you need server-side rendering for SEO, API routes you control, or framework features the Vite starter does not give you cleanly, not just because Next.js is popular. If your app is a client-side React tool that deploys fine and ranks fine, the export is enough. When you do migrate, do it as a planned, verified change rather than a single giant agent run. We cover the full path in [how to migrate your Lovable app to Next.js](/blog/migrate-lovable-to-nextjs).
If you have exported your project and want the next ten features to actually ship, start by writing down what "done" means and building against it.
*[BrainGrid](https://braingrid.ai) is the product factory that turns your idea into a plan your coding agent can build and you can verify, so your exported project keeps moving instead of breaking. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Agentic Coding: How to Start When You Don't Have a CS Degree
Source: https://www.braingrid.ai/blog/agentic-coding
Published: 2026-06-13T12:00:00Z
The most useful skill in agentic coding is one you already have if you have ever managed a person. Not a framework, not a language, not a CS degree. The ability to say what you want clearly enough that someone else can build it, and to tell whether what came back is actually right. MIT's own course on this, part of its Missing Semester series, lands on the same mental model: you are not the coder anymore, you are the manager of an intern who does the nitty-gritty work but needs direction and occasionally does the wrong thing.
That reframe is good news and a warning at the same time. Good news, because it means the barrier to entry is judgment, not syntax, and judgment is something a domain expert often has in surplus. The warning is the part nobody puts in the tutorial: agentic coding will get you eighty percent of the way to a working product faster than you can believe, and then quietly strand you in the last twenty. Knowing where that cliff is, before you walk off it, is the difference between shipping and starting over.
## What agentic coding actually is
Start with a clean definition, because the term gets blurred with everything adjacent. Google Cloud puts it plainly: agentic coding is a software development approach where autonomous AI agents plan, write, test, and modify code with minimal human intervention. The key word is autonomous. A traditional AI assistant waits for you to type and suggests the next line. A coding agent takes a high-level instruction, breaks it into steps, reads and writes files across your project, runs commands, checks its own work, and keeps going until the task is done.
That is the difference between AI coding and agentic coding, which is the question most beginners actually have. Autocomplete finishes your sentence. An agent runs the errand. MIT's course defines the agent as a conversational AI model with access to tools: reading and writing files, searching the web, invoking shell commands. The model is the brain; the tools are the hands. Give it a goal and it operates your codebase the way a contractor operates on a job site, not the way a dictionary suggests a word.
The tools you would actually start with are mature now. Claude Code and Codex run in your terminal and drive multi-step work from the command line. Cursor and Windsurf put the same agent inside a code editor. You do not need to know which is best on day one. You need to know that all of them are doing the same thing: taking your intent and turning it into actions, then showing you the result.
## How to start without a CS degree
The first move is the smallest possible real task, not a whole app. MIT's example is a good shape: take a script you already have and tell the agent, turn this into a proper command-line program with argument parsing. One change, one file, something you can read the result of. You are not testing whether the agent is smart. You are learning the loop: describe, watch, correct, repeat.
The single skill that compounds from there is writing a good specification, and it is more art than science. The MIT course warns about both failure directions in one breath:
> You want the input to the agent to be descriptive enough so that the agent does what you want it to do, but not overly descriptive to the point where you're doing too much work yourself.
>
> [MIT, "Agentic Coding," The Missing Semester of Your CS Education](https://missing.csail.mit.edu/2026/agentic-coding/)
Too vague and the agent guesses, usually wrong. Too detailed and you are writing the code in English, which defeats the point. The sweet spot is stating the what and the how-you-will-know-it-worked, and leaving the how to the agent. Here is the difference in practice.
> Vague: "Build me a login page."
>
> Specific: "Build an email-and-password login page. Show an inline error if the email format is invalid. Lock the account for five minutes after five failed attempts. On success, redirect to /dashboard. Unauthenticated users who reach /dashboard redirect back to /login."
The second one is not code. It is a clear description of done, written in plain language, and it is exactly the skill a non-engineer can own. The agent handles the implementation. You hold the standard.
The last starting habit is keeping a rules file. Every agent looks for a project-level file, usually `AGENTS.md`, where you write down your conventions and, more usefully, every mistake the agent has made before so it stops repeating them. Treat it as the onboarding doc for your intern. It is the lowest-effort reliability you will ever buy.
And yes, you can start for free. Most agents have a free tier or a low-cost entry plan, and open-source options run on your own machine. Cost is not the barrier. The barrier is knowing what to ask for and recognizing when the answer is wrong.
## The trap: the 80 percent problem
Here is the cliff. Agents are stunningly good at the part of software that looks like a demo, and stubbornly weak at the part that makes it a product. The pattern is common enough that it has a name, the 80 percent problem:
> The agent wrote code that works. The agent did not write code that survives.
>
> [Augment Code, "The 80% Problem"](https://www.augmentcode.com/guides/the-80-percent-problem-ai-agents-technical-debt)
The first eighty percent is the happy path: the feature does the thing when you use it the expected way. The missing twenty is everything that makes it real. Error handling for the inputs you did not anticipate. Security applied across the whole system, not one form. Logging so you can tell why it broke. The edge cases. And that twenty percent does not just sit there waiting politely. Left unaddressed, it compounds into technical debt that is more expensive to retrofit than it would have been to build correctly the first time, because by then the duplication and inconsistency are spread across files you never read.
This is the moment most beginners hit and misread. The demo worked, so the project feels ninety percent done, and then every new change breaks two old things and nobody can say why. We told one version of that story in [I built a vibe-coding mess](/blog/i-built-a-vibe-coding-mess), and dug into why that final stretch is so stubborn in [The Second 80%](/blog/the-second-80-percent). It is not that you did agentic coding wrong. It is that generating code and producing a trustworthy product are different jobs, and the agent only volunteered for the first one. The honest trade-off of this entire approach: speed at the start, a debt at the finish, and the debt is invisible until you are standing in it.
## The skill that closes the gap
So if the bottleneck is not generating code, what is it? Andrej Karpathy, who coined the term vibe coding and then this year [declared it obsolete for serious work](https://www.youtube.com/watch?v=96jN2OCOfLs), drew the line that matters at Sequoia's AI Ascent:
> Vibe coding is about raising the floor for everyone in terms of what they can do in software. Agentic engineering is about preserving the quality bar of professional software.
>
> Andrej Karpathy, Sequoia AI Ascent 2026
Raising the floor is what gets you the eighty percent. Preserving the quality bar is what gets you the twenty, and Karpathy is explicit about how: you work with your agent to design a spec that is very detailed, basically the docs, and then get the agents to write against it. The skill is not coding. It is specifying precisely and verifying honestly. That is the thing the agent cannot do for you, because it is the definition of what right means, and the agent is the one being checked.
This is the gap BrainGrid was built to close, and it is built for exactly the person without a CS degree. BrainGrid is the system that takes an idea to a live product you can trust. You describe the feature in plain language, the way you described that login page above, and the Planning Agent asks the clarifying questions a senior engineer would, surfaces the edge cases you did not think of, and turns your intent into a requirement with explicit acceptance criteria. That requirement is the spec your agent works against and the standard your result is checked by.
From there you choose how to build. Hand the scoped tasks to [Claude Code, Cursor, or Codex](/ai-coding-agents) in your own setup, or let the Builder Agent build it in a managed sandbox with a live preview and open a pull request. Either way, verification closes the loop: every acceptance criterion is checked against the result, and the feature is not done until the evidence says it does what you meant. The twenty percent stops being the part you discover in production and becomes the part you specified up front. That is the whole loop, Plan, Build, Verify, Repeat, and it is the same discipline we cover in [agentic engineering](/agentic-engineering) and in [spec-driven development](/spec-driven-development).
Strip away the tool names and the trending terms and the argument holds on its own: agentic coding lowered the cost of producing software to almost nothing, which means the scarce thing is no longer typing. It is knowing what you want and proving you got it. If you are a domain expert who has been told you cannot build because you cannot code, that equation just moved in your favor. The work that is left is the work you were always good at.
## FAQ
### What is agentic coding?
Agentic coding is a software development approach where autonomous AI agents plan, write, test, and modify code with minimal human intervention. Instead of suggesting the next line like autocomplete, a coding agent takes a high-level instruction, breaks it into steps, reads and writes files across your project, runs commands, checks its own work, and iterates until the task is complete. You direct it and review the result; it does the implementation.
### What is the difference between AI coding and agentic coding?
Traditional AI coding assistants are reactive: they wait for you to type and offer suggestions or answer questions. Agentic coding tools are autonomous: they take a goal and execute it end to end, navigating files, running terminal commands, and self-correcting when a test fails. The simplest way to put it is that an assistant finishes your sentence, while an agent runs the errand.
### What is the 80 percent problem in agentic coding?
The 80 percent problem is the gap between the working code an agent reliably produces, roughly eighty percent of a solution, and the production-grade remaining twenty percent: error handling, security, observability, edge cases, and compliance. Agents are excellent at the happy-path demo and weak at the parts that make software survive real use. Left unaddressed, that twenty percent compounds into technical debt that costs more to retrofit than it would have to build correctly from the start. The fix is defining the full standard up front so the agent builds to it, not just to the demo.
### Can you do agentic coding for free?
Yes. Most coding agents offer a free tier or a low-cost entry plan, and there are open-source agents you can run on your own machine at no cost. Cost is rarely the real barrier to starting. The harder part is learning to write a clear specification and to recognize when the agent's output is wrong, both of which are free to practice on small tasks.
### Do you need to know how to code to do agentic coding?
You do not need a CS degree, but you do need judgment. The skill that matters most is writing a clear specification, stating what you want and how you will know it worked, and verifying the result honestly. MIT's own framing is that working with a coding agent is like managing an intern: you provide direction and catch mistakes, the agent does the detailed work. Domain experts who know exactly what good looks like in their field often have the most important skill already. Tools like BrainGrid's Planning Agent turn a plain-language idea into a structured requirement with acceptance criteria, so the specifying and checking happen without writing code yourself.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your plain-language idea into a spec your coding agent can build against and be checked against, so the last twenty percent stops being a surprise. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Harness Engineering, Explained: What Separates Top Agentic Engineers
Source: https://www.braingrid.ai/blog/harness-engineering
Published: 2026-06-12T12:00:00Z
OpenAI spent five months building an internal product where humans wrote zero lines of code, and the engineers on that team were busier than ever. Roughly a million lines shipped across more than 1,500 pull requests, every one of them authored, reviewed, and merged by agents. The work did not disappear. It moved into something the team calls the harness, and in the four months since, the idea has completed its arc from insider habit to formal discipline. There is now an open-source framework, [AutoHarness](https://github.com/aiming-lab/AutoHarness), whose entire premise is that an agent is just a model plus a harness, and the harness is the part you engineer.
Here is the claim worth testing: what separates the builders getting production-grade output from agents is not the model they picked or the prompts they write. It is whether they built the environment around the agent. And inside that claim hides a second one that matters even more, because the harness, for all its power, cannot generate its own most important input.
## What harness engineering actually is
The term has a precise origin story. Mitchell Hashimoto, the creator of Terraform and Vagrant, described the practice in [his AI adoption journey](https://mitchellh.com/writing/my-ai-adoption-journey) in early February 2026, as the step where his agent use stopped being frustrating and started compounding:
> Anytime you find an agent makes a mistake, you take the time to engineer a solution such that the agent never makes that mistake again.
>
> [Mitchell Hashimoto, "My AI Adoption Journey"](https://mitchellh.com/writing/my-ai-adoption-journey)
Six days later, OpenAI [gave the discipline its formal name](https://openai.com/index/harness-engineering/). Ryan Lopopolo's post described how their agent-first team operates: engineers do not write the code, they build the structure, documentation, and automated checks that keep agents on track. The post's core principle fits in four words: humans steer, agents execute. The metaphor is deliberate. A harness, in the original sense, is the equipment that channels a powerful animal's strength in a useful direction. Nothing about the harness makes the horse stronger. It makes the strength go somewhere.
So a working definition: harness engineering is the practice of designing the environment around an AI coding agent, the context it reads, the tools it can call, and the checks that catch its output, so the agent produces the right result instead of a plausible one. Your agent's raw capability is rented from a model provider, and it is the same capability everyone else rents. The harness is the part you own.
## What a harness is made of
Birgitta Böckeler, writing the most rigorous treatment of the subject [on martinfowler.com](https://martinfowler.com/articles/harness-engineering.html), defines the harness as everything in an agent except the model itself, and sorts its parts into two families. Guides act before the agent does: the AGENTS.md file that carries your conventions, the architecture notes, the bootstrap scripts that set up a working environment. Sensors act after: linters, type checkers, test suites, and review agents that inspect what came out and feed problems back in.
The whole practice reduces to one move, applied relentlessly. When the agent does something wrong, you do not correct it in chat. You encode the correction where every future run will hit it.
The difference is easy to see side by side. Chat correction: "No, use our date helper, not raw `Date()`," and the agent complies, and that knowledge evaporates the moment the session ends. Harness correction: a lint rule that flags raw `Date()` plus one line in AGENTS.md explaining the helper, and no agent in any future session ships that mistake again. The first is a conversation. The second is an asset. Top agentic engineers are the ones with eight months of accumulated corrections sitting in their repo, which is why their agents seem eerily reliable and yours seems forgetful. Same model. Different harness.
```mermaid
flowchart LR
S[Spec with acceptance criteria] --> A[Agent run]
G[Guides: AGENTS.md, conventions, scripts] --> A
A --> C{Sensors: tests, linters, review}
C -->|fail| F[Feedback to agent]
F --> A
C -->|pass| P[PR you can trust]
```
## The harness governs how. It cannot decide what.
Now for the part the harness explainers skip, and the reason the diagram above starts where it starts. Every component of a harness shares one property: it evaluates the agent's output against a standard somebody already wrote down. The linter knows your formatting rules. The type checker knows your interfaces. The test suite knows the behavior somebody specified. Feed the harness a vague goal and it will happily help the agent build the wrong thing correctly, with clean types, passing tests it wrote for itself, and conventions intact.
Böckeler lands on exactly this limit, and her conclusion is the reframe that should change how you spend your effort:
> A good harness should not necessarily aim to fully eliminate human input, but to direct it to where our input is most important.
>
> [Birgitta Böckeler, "Harness engineering for coding agent users"](https://martinfowler.com/articles/harness-engineering.html)
Where is your input most important? Not in the lint rules. The agent can draft those. Not in the test scaffolding. The agent writes that too, and the harness checks it. The one input the harness cannot generate, verify, or even detect the absence of is the definition of what you are building and how you will know it is right. A harness with no spec is scaffolding around an empty lot. This is also what distinguishes the harness from its sibling buzzword: the loop schedules and re-runs your agent, the harness shapes and checks each run, and the spec tells both of them what done means. We covered the loop layer in [What Is Loop Engineering?](/blog/loop-engineering); the punchline there was that the loop's verifier needs a standard. The harness is that verifier, and it needs the standard just as badly.
This is the gap BrainGrid fills. BrainGrid is the system that takes an idea to a live product you can trust, and it sits exactly at the harness's missing input. You describe the feature in plain language, and the Planning Agent interrogates it the way a senior engineer would, surfacing edge cases and turning intent into a requirement with explicit acceptance criteria. That requirement becomes the harness's reference point. Run the build either way: hand the scoped tasks to [Claude Code, Cursor, or Codex](/ai-coding-agents) over MCP inside your own harness, or let the Builder Agent build in a managed sandbox with a live preview and open the PR. Then verification closes the loop the way a linter never can, checking the result against each acceptance criterion and holding the feature short of done until the evidence says it does what you intended. Code review tells you the code is well-written. Verification tells you it does what you meant.
## The honest costs
Two trade-offs, because the discipline has them. First, a harness is a second codebase. Hashimoto's rule sounds light, but engineering a permanent fix for every mistake is real, ongoing work, and on a legacy codebase with years of unwritten conventions, the backfill is steep. Budget for it like infrastructure, because that is what it is.
Second, the harness has a ceiling, and you should know where it is. Böckeler's warning is that no current check, mechanical or model-based, reliably catches the agent that misunderstood the assignment. The failure mode that actually burns builders is not malformed code. It is well-formed code that solves the wrong problem. That failure is invisible to every sensor in the harness except one: a written statement of what the right problem was. The better your agents get, the more this holds, because more capable agents produce more output per unit of your attention, and every unit of output that nobody specified is a decision nobody made.
If you are building with Claude Code or Cursor today, here is what this means concretely: your edge is no longer in the prompt box. An hour spent writing one more clever prompt is worth less than an hour spent adding the lint rule, the AGENTS.md entry, and the acceptance criteria that make the next hundred prompts land. The builders pulling ahead right now are not prompting better. They are accumulating a harness, and they are feeding it specs.
**Start your harness this week:**
1. Create an AGENTS.md file and add one entry for every mistake your agent has made twice. ([Claude Code skills](/blog/claude-skills) are the structured version of the same move.)
2. Wire your existing checks into the agent's path: tests, linter, type checker, so failures feed back automatically.
3. Before the next feature, write the acceptance criteria first, in BrainGrid or anywhere, so the harness has something real to check against.
Strip away the OpenAI post, the GitHub stars, and the new vocabulary, and the argument stands on its own: an agent's output is only as trustworthy as the environment that checks it, and the environment is only as good as the intent you wrote down. The harness is how the agent stops repeating mistakes. The spec is how it stops making the expensive one.
## FAQ
### What is harness engineering?
Harness engineering is the practice of designing the environment around an AI coding agent so it produces reliable results: the context files it reads (like AGENTS.md), the tools and scripts it can call, and the automated checks (tests, linters, review agents) that catch its output and feed problems back. The core move is encoding every correction permanently in the environment instead of repeating it in chat.
### Who coined the term harness engineering?
Mitchell Hashimoto, creator of Terraform, described "engineering the harness" in his "My AI Adoption Journey" post on February 5, 2026. OpenAI formalized the term six days later in Ryan Lopopolo's February 11 post about building an internal product with zero human-written code. The underlying word is older: a harness has long meant the scaffolding around a model, and the equestrian metaphor, equipment that directs strength, is intentional.
### What is the difference between harness engineering and spec-driven development?
They cover opposite sides of the same problem. [Spec-driven development](/spec-driven-development) defines what to build before the agent starts: requirements, behavior, acceptance criteria. Harness engineering shapes how the agent works and checks what it produced: conventions, tools, tests, and feedback. A harness verifies output against a standard, and the spec is that standard, so each practice is incomplete without the other.
### What is the difference between a harness and a loop?
The harness is the environment around a single agent run: what the agent knows, what it can touch, and what checks its work. A loop is the orchestration above it: the scheduler that finds work, runs the agent again and again, and decides when to stop. The loop re-runs the agent; the harness makes each run trustworthy. Both depend on a spec to define what done means.
### Do you need to be an engineer to benefit from harness engineering?
The principle transfers even if you never write a lint rule. Any builder can keep a running file of corrections their agent must follow, and any builder can define acceptance criteria before the agent starts. Tools handle the rest: BrainGrid's Planning Agent turns a plain-language idea into a requirement with testable criteria, and its verification checks the build against each one, which is the harness's feedback layer without the infrastructure work.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that gives your harness the one input it cannot generate: a spec with acceptance criteria to check every build against. Try it at [braingrid.ai](https://braingrid.ai).*
---
# What Is Loop Engineering? Stop Prompting, Start Designing Loops
Source: https://www.braingrid.ai/blog/loop-engineering
Published: 2026-06-12T00:00:00Z
Every few months the AI building world agrees on a new thing you are supposed to be doing, and this month it is loop engineering. The pitch is clean: you do not prompt your coding agent one step at a time anymore. You design the loop that prompts it for you, point it at a goal, and walk away.
It is a real shift, and it is worth understanding. But the part the loop tweets leave out is the interesting part. The loop takes prompting off your plate and hands you back a harder job, one you cannot automate your way out of. Knowing what that job is tells you exactly where to put your effort.
## What loop engineering actually means
Loop engineering is the practice of designing a system that prompts and orchestrates an AI coding agent on a schedule, instead of you typing each prompt by hand. Addy Osmani, whose explainer became the reference for the term, defines it plainly:
> Loop engineering is replacing yourself as the person who prompts the agent. You design the system that does it instead.
>
> [Addy Osmani, "Loop Engineering"](https://addyosmani.com/blog/loop-engineering/)
A loop is roughly five pieces plus one. Automations that fire on a schedule and find work. Worktrees so two agents do not collide. Skills that write down project knowledge the agent would otherwise guess. Connectors that plug the agent into your real tools. Sub-agents, so the one that writes the code is not the one that grades it. And the sixth piece, the one that makes the whole thing hold together: a memory that lives outside any single run and remembers what is done and what is next.
The wave started with two sentences from people who would know. Peter Steinberger, who built the open-source agent gateway OpenClaw and now works at OpenAI, put it as a standing reminder:
> Here's your monthly reminder that you shouldn't be prompting coding agents anymore. You should be designing loops that prompt your agents.
>
> [Peter Steinberger on X](https://x.com/steipete/status/2063697162748260627)
Days earlier, Boris Cherny, who leads Claude Code at Anthropic, described on stage where his own job had gone:
> I don't prompt Claude anymore. I have loops running that prompt Claude and figuring out what to do. My job is to write loops.
>
> Boris Cherny, head of Claude Code at Anthropic
Steinberger's post hit 6.5 million views in a week. It landed because the pieces ship inside the products now: `/goal` in Claude Code defines a testable end state and keeps working until it is true, with a separate model grading whether it is done. The leverage point moved, and everyone felt it at once.
## The job the loop hands back
Here is the contradiction at the center of the hype. A loop running unattended is also a loop failing unattended. Take prompting off your plate and you have not removed the work, you have moved it somewhere worse: into runs you were never watching, with far too much output to read by hand. Akshay Pachaar said it sharply this week:
> Loop engineering takes you off prompting. It takes you off curating context. It takes you off babysitting a single run. It does not take you off debugging. It just moves the debugging somewhere worse, into runs you were never watching.
>
> [Akshay Pachaar on X](https://x.com/akshay_pachaar/status/2064265203488076020)
Stack the layers up, prompt to context to harness to loop, and one job survives all of them. Closing the loop on failure. You can only walk away from a loop if you trust the thing checking it, and a checker you do not trust drops you right back into reading every output by hand, which is the exact work the loop was supposed to take off you.
So the real question loop engineering raises is not "how do I build the loop." Both Claude Code and Codex ship the loop. The real question is "what does my checker check against." A loop with no definition of done is just a faster way to generate work you still have to inspect line by line.
## Why this moves the work upstream, not away
Watch what happens to the human as each layer of automation arrives. Prompt engineering asked you to write a good message. Context engineering asked you to curate what the model sees. Loop engineering asks you to design the system that does both on a schedule. At every step the manual labor shrinks and the judgment concentrates. The thing you cannot hand off is deciding what you actually want and stating it precisely enough that a machine can check the result.
That is a spec. Not a vague ticket, not a paragraph in Slack, but a requirement with testable acceptance criteria: the agent built this, here is how we know it is right. The sub-agent that "verifies against the spec," in Osmani's words, needs a spec to verify against. The loop's memory, the file that survives between runs, has to hold something worth remembering. Both of those are the same artifact, and writing it is the work that does not disappear.
Consider the before and after. Before: you babysit a single run, catch the drift in real time, correct it prompt by prompt. After: the loop runs ten times overnight and you wake up to ten pull requests, half of them subtly wrong in ways no human would have written, and no clear standard to grade them against. The loop made you faster at producing work and slower at trusting it. The fix is not a better loop. It is a definition of done the checker can actually use.
## Where BrainGrid fits in a loop
This is the gap BrainGrid was built for. BrainGrid is a product factory that runs the loop Plan, Build, Verify, Repeat, and it owns the two pieces a loop cannot generate for itself: the plan and the standard.
You describe a feature in plain language. The Planning Agent asks the clarifying questions a senior engineer would, surfaces the edge cases, and writes an engineering-grade requirement with acceptance criteria. That requirement is the spec your loop's verifier checks against. It is also the memory: it persists outside any single run, so when tomorrow's automation fires, the context is already there. The agent forgets between sessions. BrainGrid does not.
From there the loop runs either way. Load the scoped tasks into Claude Code, Cursor, or Codex over MCP and let your own harness drive them, or let BrainGrid's Builder Agent build the requirement in a managed sandbox and open a pull request, with AI code review checking the result against the acceptance criteria item by item. Verification stops being a thing you hope the loop got right and becomes a thing the loop can prove. That is what makes walking away safe. This is the same discipline we cover in [agentic engineering](/agentic-engineering), and the full five-stage version lives in [The BrainGrid Loop](/loop).
## So is it real, or just another buzzword
Both, the way most of these are. The mechanics are real and genuinely useful: scheduled, self-checking agent runs are a meaningful jump in capability, and if you have not tried `/goal` in Claude Code you should. The buzzword part is the implication that designing the loop is the whole job. It is not. It is the part that got automated. The part that did not, defining what done means and giving the checker something real to check, is where the work went. Put your effort there, and the loop pays off. Skip it, and the loop is just a faster way to dig the hole we wrote about in [I built a vibe-coding mess](/blog/i-built-a-vibe-coding-mess). The loop-as-a-running-joke version is our take on [the Ralph Wiggum plugin](/blog/ralph-wiggum-plugin).
## FAQ
### What is loop engineering?
Loop engineering is the practice of designing a system that prompts and orchestrates an AI coding agent automatically, on a schedule, instead of typing each prompt yourself. A loop typically combines scheduled automations, isolated worktrees, project skills, tool connectors, and sub-agents that check each other's work, plus a memory that persists between runs. The goal is to move from holding the agent's hand through every step to designing the system that runs it for you.
### Is loop engineering real or just another AI buzzword?
It is both. The underlying mechanics are real and shipping today in Claude Code and Codex, and scheduled self-checking agent runs are a genuine step up. The buzzword part is the suggestion that building the loop is the whole job. The loop automates the prompting, but it hands back the harder work: defining what "done" means so the loop's checker has a standard to verify against. Designing the loop is the easy half. Closing the loop on failure is the half that survives.
### What is the difference between loop engineering and prompt engineering?
Prompt engineering optimizes a single message you send by hand. Loop engineering designs the system that sends those messages for you, on a cadence, and checks the results. Prompt engineering is one turn; loop engineering is the machine that runs many turns unattended. The skill moves from wording a request to specifying a goal precisely enough that an automated checker can confirm it was met.
### Does Claude Code support loop engineering?
Yes. Claude Code ships the core pieces: `/loop` re-runs a prompt on a cadence, `/goal` keeps working until a condition you defined is true with a separate model grading whether it is done, and hooks plus scheduled tasks let you run autonomous work on an interval. Codex offers the same primitives through its Automations tab. The pieces are in the products now, which is why the term took off.
### What does loop engineering not solve?
Verification and your own understanding. A loop running unattended is also a loop making mistakes unattended, and the more code it ships that you did not write, the larger the gap between what exists and what you actually understand. The loop can take you off prompting, context curation, and babysitting a single run. It cannot take you off deciding what you want and confirming the result matches. That is why a clear spec with acceptance criteria, which is what BrainGrid produces, is the piece that makes a loop trustworthy enough to walk away from.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that gives your agent loops the one thing they cannot generate for themselves: a spec with acceptance criteria the verifier can check against. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Claude Pro vs Team vs Max: Which Plan Do You Actually Need in 2026?
Source: https://www.braingrid.ai/blog/claude-pro-vs-team-vs-max
Published: 2026-06-11T00:00:00Z
Anthropic names its Claude plans by who you are: Pro for individuals, Team for teams, Max for power users. Builders keep buying by the name and then discovering the name pointed them at the wrong plan.
Team size is the wrong axis.
The variable that actually determines which Claude plan you need is how much unattended agent work you run. A solo founder with Claude Code grinding through features every night needs more capacity than a ten-person team that uses chat for research. Price the workflow, not the headcount, and the confusing plan grid collapses into a few clear decisions.
## The plans, with current numbers
Here is the full lineup as of June 2026, straight from the [official pricing page](https://claude.com/pricing):
| Plan | Price | Usage | Claude Code? |
|---|---|---|---|
| Free | $0 | Basic limits | No |
| Pro | $20/mo ($17/mo billed annually) | 1x baseline | Yes |
| Max 5x | $100/mo | 5x Pro | Yes |
| Max 20x | $200/mo | 20x Pro | Yes |
| Team, standard seat | $25/seat/mo ($20 annually), 5-seat minimum | More than Pro per session | No |
| Team, premium seat | $125/seat/mo ($100 annually) | 5x a standard seat | Yes, plus Cowork |
| Enterprise | $20/seat plus usage at API rates | Pooled, custom | Yes |
Two numbers in that table do most of the damage. The 5-seat minimum means Team starts at $100 to $125 per month no matter how small your team is. And the standard seat, the one most people picture when they hear "Team plan," does not include Claude Code. The tool that most builders are actually buying capacity for lives in Pro, Max, and premium seats only.
That second detail is the most common and most expensive surprise in the whole lineup.
## The trap with the friendly name
Picture a three-person startup that builds with Claude Code all day. The Team plan sounds like it was made for them. They sign up for five standard seats at $125 per month, and within a week the developers discover their seats do not cover the one tool they use most, while the [usage limits](https://support.claude.com/en/articles/9266767-what-is-the-team-plan) feel barely different from the $20 Pro plan they left.
This failure mode is common enough that the math has become its own genre of post. Russell Reeder, who runs heavy Claude Code and Cowork workloads, put it bluntly:
> If you're a small team considering Claude Teams, slow down. The math might not work in your favor.
>
> [Russell P Reeder on LinkedIn](https://www.linkedin.com/posts/russellpreeder_if-youre-a-small-team-considering-claude-activity-7442567224357326848-Duvc)
His framing is the reframe this decision needs. Team is not the bigger Pro. Team is a different product: shared projects, central billing, SSO, and a contractual guarantee that your data never trains Anthropic's models. Those are collaboration and governance features. They have almost nothing to do with how much building capacity you get.
So the real decision tree has two independent questions, not one. First, how much agent capacity does each person need? Second, do you need the governance layer? Answer them separately and the plan picks itself.
```mermaid
flowchart TD
A[How do you use Claude?] --> B{Mostly chat and research?}
B -->|Yes, solo| C[Pro at $20]
B -->|Yes, team needing shared projects + privacy| D[Team standard seats]
A --> E{Heavy Claude Code or agent loops?}
E -->|Solo or small crew| F[Max 5x or 20x per builder]
E -->|Team that also needs admin + privacy| G[Premium seats for builders, standard for the rest]
E -->|Compliance, audit logs, 150+ seats| H[Enterprise]
```
A few concrete readings of that tree. A solo builder shipping nightly with Claude Code is better served by Max 5x at $100 than by five Team seats at the same price, because all of the capacity lands on one person and Claude Code is included. Two technical cofounders are usually best with two individual Max plans, not a Team minimum they cannot fill. A ten-person company where two people build and eight people research maps cleanly to two premium seats plus eight standard ones. And if your usage is spiky rather than constant, the [API's pay-per-token pricing](https://claude.com/pricing) can undercut every subscription, which is exactly how our deeper dive on [Claude Code pricing](/blog/claude-code-pricing) breaks down token costs against the flat plans. If you are still picking which agent to run on that plan, our field guide to [AI coding agents](/ai-coding-agents) compares Claude Code, Cursor, Windsurf, Codex, and Gemini side by side.
## The variable nobody prices: your rework rate
Here is the uncomfortable part. Most builders who hit usage limits do not have a capacity problem. They have a rework problem.
One developer described the pattern on [Hacker News](https://news.ycombinator.com/item?id=47962775) as a slot machine effect: maybe now I get what I want, argh, not quite, okay, feels nearly there. Every pull of that lever burns usage. A vague prompt produces an almost-right feature, the almost-right feature produces three correction prompts, and the corrections produce regressions that need their own corrections. Upgrade from Pro to Max and you have bought twenty times the capacity to run the same loop faster.
The cheaper upgrade is to stop paying for guesses. That is the whole argument for [spec-driven development](/blog/spec-driven-development), and it is exactly the gap BrainGrid exists to close: describe the feature once, and the Planning Agent asks the clarifying questions a senior engineer would, then writes a requirement with acceptance criteria your coding agent builds against. One well-specified task tends to land in one or two generations instead of five, because the agent is not inventing your edge cases mid-flight. The same plan then runs anywhere: load it into Claude Code on whichever Claude plan you chose, or let BrainGrid's Builder Agent build it in a managed sandbox and open a pull request your criteria can verify.
Run that math against the pricing table. If planning cuts your generations per feature roughly in half, a $20 Pro plan with specs often outships a $200 Max plan without them.
The honest trade-off: if you genuinely run long autonomous sessions every day, multiple agents in parallel, large codebases, overnight loops, no amount of planning replaces raw capacity. Heavy agentic builders should still buy Max 20x and will still be glad they did. Planning determines how much of that capacity becomes shipped product instead of discarded drafts.
## What this means for you
If you are deciding this week: solo and chat-first, take Pro at $20, and take the annual discount if you know you will stay. Solo and building daily with Claude Code, start at Max 5x and watch your limits for two weeks before paying for 20x. A team that mostly needs shared context, privacy guarantees, and admin controls wants standard Team seats. A team that builds wants premium seats for the builders only, or individual Max plans if the governance features do not matter yet. Compliance requirements, HIPAA, audit logs, or more than 150 people put you in Enterprise territory.
And whichever plan you choose, the lever that moves your bill most is upstream of the plan picker. Capacity multiplies what you can attempt. A spec decides how much of it ships.
## FAQ
### Is Claude Pro worth it in 2026?
For anyone using Claude more than casually, yes. At $20 per month ($17 billed annually) it includes Claude Code, higher limits than Free, and access to the best models. It is the right default for solo builders, and the plan to outgrow rather than skip.
### Which Claude subscription is better, Pro, Team, or Max?
Better for what is the real question. Pro is the best value for an individual. Max is for individuals who hit Pro's limits doing real agent work. Team is for groups that need shared projects, admin controls, and a no-training data guarantee. Pick by workload and governance needs, not by the plan names.
### What is the difference between Claude Team and Pro usage limits?
A Team standard seat offers more usage per session than Pro, with a weekly cap across models, per Anthropic's documentation. In practice the difference is modest. The big capacity jumps live in Max (5x and 20x Pro) and in Team premium seats (5x a standard seat).
### Does the Claude Team plan include Claude Code?
Standard seats do not. Claude Code comes with Pro, Max, and Team premium seats ($125 per seat monthly, $100 annually). This is the most common surprise for teams that signed up to build: budget premium seats for the people who code, standard seats for everyone else.
### Is Claude Team worth it compared to Max?
If you need collaboration and governance, yes: shared projects, central billing, SSO, and your data excluded from model training. If you just need more capacity for one or two builders, individual Max plans usually deliver more usage per dollar without the 5-seat minimum.
### Do plan limits change?
Yes, Anthropic adjusts limits and pricing as models evolve, and numbers in this post reflect June 2026. Check the [official pricing page](https://claude.com/pricing) before committing to annual billing.
*[BrainGrid](https://braingrid.ai) is the AI Product Planner that turns your idea into specs your Claude plan can build right the first time, whichever tier you pick. Try it at [braingrid.ai](https://braingrid.ai).*
---
# Setting Product Priorities With GOD: Goals, Objectives, and Deliverables
Source: https://www.braingrid.ai/blog/setting-product-priorities-with-god
Published: 2026-05-25T19:00:00Z
For most of software's history, planning mattered, but sloppy planning was survivable because building was slow.
Building was the bottleneck. A feature took weeks to ship, so a fuzzy spec got corrected in flight. You'd start building, discover what you actually meant halfway through, and the slow grind of implementation gave you time to course-correct. The plan was a rough sketch because the building was going to be the expensive part anyway.
That's over.
AI coding collapsed the cost of building. A developer with good tooling now opens five or six pull requests a day instead of one or two a week. AI already writes a large share of the code that gets committed, north of 40% by recent measures.[^1] Code that took weeks now takes hours. The thing we spent decades optimizing is no longer the thing holding us back.
So where did the bottleneck go? It didn't disappear. It moved to the two places building used to hide: **deciding what to build**, and **verifying that what got built is right**. Planning and verification. A 2026 analysis of 8.1 million pull requests across 4,800 organizations found developers feel about 20% faster with AI while actually running roughly 19% slower in delivery, because review time ballooned as generation sped up.[^2] Trust is the root of it: most professional developers say they don't fully trust AI-generated code without checking it themselves.[^3] The constraint relocated upstream and downstream at once, and squeezed the part in the middle that used to be the whole job.
This changes what product priorities are for. When building was slow, priorities were a way to ration scarce engineering time. Now building is cheap and the scarce resource is clear thinking about what's worth building and proof that it works. Priorities aren't a rationing tool anymore. They're the bottleneck itself.
Which means the quality of your goals and objectives now directly sets the speed of your team. A vague plan used to cost you a few wasted weeks. Now it costs you a flood of cheaply-built features that nobody can verify and nobody's sure they needed.
So let's get the planning layer right. Three concepts do the work, and they spell GOD: goals, objectives, and deliverables. A goal is where you're going. An objective is the proof you got there. A deliverable is the thing you build to move that proof. The letters run G to O to D, but it isn't a finish line. The D loops back to the O, because the only way to know a deliverable mattered is to check whether it moved the objective. It's a cycle you run, not a checklist you complete. Most teams confuse the three constantly, so start there.
## Goals and objectives are not the same thing
A **goal** is a qualitative statement of aspirational intent. Simple, big, inspiring, no numbers. It's the destination.
- Become the tool people reach for first in our category.
- Make new users succeed in their first week.
An **objective** is a measured change in customer behavior that proves you got there. It names three things: **who, doing what, by how much**. The "who" is a real customer, the "what" is something they now do differently because of your work, and the "by how much" is the number that makes it checkable. Not what you shipped, not how your system performed. What people do, and how much more of it. You nail it or you don't.
Some people call these OKRs or KPIs. Same idea, fancier acronym. The label doesn't matter. What matters is that all three parts are present. Drop the "who" and you're measuring a system, not a customer. Drop the "by how much" and you've written an aspiration, not a proof. If your objective doesn't have a person doing something in measurable quantity, it isn't measuring value yet.
- Grow the share of new users who finish a real task in week one from 32% to 55%.
- Lift the share of trials that convert to paid within 14 days from 6% to 15%.
A goal without objectives is a vibe. Objectives without a goal are a scorecard nobody can read. Together they say where you're going and how you'll know you arrived.
## The trap: outputs dressed up as objectives
Here's where almost everyone goes wrong. The goal is usually fine. The objectives are where it falls apart, because people reach for the number that's easiest to measure from the inside instead of the number that proves a customer got value.
There's a clean test, and it follows straight from the definition. A good objective measures what your customer *does differently* because of your work. A bad objective measures what your team *ships*, or what your system *does*, neither of which proves anyone got value. Outcomes, not outputs. If there's no human doing something in the metric, you've measured the wrong thing.
The fastest way to feel the difference is to put the weak version and the strong version side by side.
**Goal: Become the product people trust most in our category.**
- Bad objective: Hit 99.9% uptime for two quarters. *(A system metric. Uptime can be perfect while customers quietly churn. It measures your plumbing, not their trust.)*
- Good objective: Grow the share of teams running a mission-critical workflow on us from 30% to 55%. *(A behavior. Putting critical work on you is what trust actually looks like.)*
**Goal: Turn happy users into a growth engine.**
- Bad objective: Reach a net promoter score of 50. *(An attitude survey. It asks how people feel, not what they do, and feelings don't compound.)*
- Good objective: Lift the share of new signups arriving through an existing user's invite from 8% to 25%. *(A behavior. Referring is the action NPS was only ever a weak proxy for.)*
**Goal: Win the enterprise buyer without losing the solo builder.**
- Bad objective: Close 10 enterprise deals this year. *(An output, measured from your side. Closing a deal isn't the customer getting value, it's you booking revenue.)*
- Good objective: Grow accounts that expand from 1 seat to 5+ within 60 days from X to Y. *(A behavior. A team pulling in more seats on its own is the customer proving the value for you.)*
One caveat, because great product people smell naivety instantly: not every objective has to be a pure behavior change. A guardrail is fair game. "Hold solo-tier week-one activation flat while we chase enterprise" is a perfectly good objective, because it protects a behavior you've already earned. The rule isn't "behavior only." It's "stop mistaking your outputs for proof of someone else's value."
Notice the other pattern too. The goal never contains a number, and the objective is nothing but a number and a deadline. If your "goal" has a metric in it, it's an objective wearing the wrong label. If your "objective" can't be checked off as hit or missed, it's a goal in disguise.
That pairing is the entire foundation of a product priority. If a roadmap item doesn't trace to an objective, and that objective to a goal, you don't have a priority. You have a thing someone wanted to build.
## Deliverables: the thing you actually build
So far everything has been a planning artifact. Nobody ships a goal. Nobody ships an objective. They're the destination and the proof. At some point you have to build something, and that something is a deliverable.
A deliverable is an output. It's the concrete thing your team produces and ships: a feature, a flow, a redesign, an integration. It hangs directly off an objective, and the objective is the only reason it exists. "Ship one-click import" is a deliverable. "Rebuild the onboarding flow" is a deliverable. They are not outcomes, and that distinction is the whole game. The outcome is what the customer does differently. The deliverable is what you build hoping to cause it.
This is the layer most teams confuse with progress. Shipping a deliverable feels like winning. It isn't. It's a bet that this output will move that objective. Until the number moves, you've shipped work, not value. A deliverable that ships and doesn't move its objective isn't a success with a measurement problem. It's a miss.
So deliverables hang off objectives like this:
**Objective: Grow the share of new users who finish a real task in week one from 32% to 55%.**
- Deliverable: Replace the six-step signup with a single screen.
- Deliverable: Auto-generate a starter project from the user's first input.
**Objective: Lift the share of new signups arriving through an existing user's invite from 8% to 25%.**
- Deliverable: Add an in-product invite flow with a shareable link.
- Deliverable: Build a referral dashboard so users can see who joined.
Each deliverable points at exactly one objective. If you can't name the objective a deliverable serves, that's not a deliverable, it's a distraction with a ship date.
## Why this matters: deliverables are what AI made cheap
Here's the part that changes everything. Of the three concepts so far, the deliverable is the one AI collapsed in cost.
Goals, objectives, the judgment about what's worth building, none of that got cheaper. The deliverable did. "Build xyz" used to be the expensive, scarce thing you rationed your whole roadmap around. Now a developer with good tooling produces deliverables in an afternoon that used to take a sprint.
That inverts how priorities work. When deliverables were expensive, the deliverable *was* the priority. You picked a few because you could only afford a few, and the picking did the prioritizing for you. Scarcity was the filter. Now that filter is gone. You can build almost any deliverable you can name, fast. So the deliverable can no longer be the unit of prioritization, **because nothing is scarce enough to force a choice**.
The objective becomes the filter instead. When you can build anything, the only question worth asking is which deliverable moves an objective. A free deliverable with no objective above it isn't a quick win. It's fast garbage, shipped with confidence.
This is also exactly the seam where humans still matter. AI builds the deliverable. It cannot tell you which deliverable is worth building, and it cannot tell you whether the one you shipped moved the objective. The deliverable is where human planning hands off to cheap machine building, and where it hands back to human verification. Get the objective right and the cheap building is a superpower. Get it wrong and you've just automated the production of things nobody needed.
And the faster this gets, the more the planning matters, which is the part most teams have backwards. When building was the bottleneck, a sloppy objective got sanded smooth by the sheer time it took to implement. You had weeks to realize "make onboarding better" actually meant "cut the signup steps," and you fixed it before launch. That buffer is gone. When the deliverable ships in an afternoon, there's no slow grind to catch your fuzzy thinking. You get exactly what you pointed the build at, fast and at volume. The precision you used to add during implementation now has to exist before it.
This is the real lesson of the productivity paradox. The teams generating the most code aren't shipping the most value. The ones winning are the ones whose planning and verification kept pace with their build speed. Build got cheap. Knowing what to build, and proving it worked, got expensive.
## Closing the loop: did the deliverable move the number?
Which brings us to the step almost everyone skips, and the one that makes GOD a loop instead of a line. A deliverable hangs off an objective for a reason: so you can go back and check whether shipping it actually moved that objective.
This is the connection most roadmaps never make. Teams ship the deliverable, mark it done, and roll to the next one. The objective just sits there, unexamined. But "done" is the wrong finish line. A deliverable isn't finished when it ships, it's finished when you know whether it worked. Shipped and moved the number is a win. Shipped and the number didn't budge is information, and often more valuable than the win, because it tells you the bet was wrong before you pour three more deliverables into the same dead end.
So the objective does double duty. Up front it's the filter that decides what's worth building. After the fact it's the scoreboard that tells you whether what you built was worth it. Same number, two jobs. That is the D looping back to the O: build the deliverable, check the objective, decide what to do next. It's the engine of a roadmap that learns instead of just lengthens.
Concretely, every deliverable gets a before and an after:
- Before: which objective does this serve, and what's the number today?
- After: did the number move, and by enough to justify what we spent?
If you can't answer the "after," you didn't ship a priority, you shipped activity. The deliverable connects to the objective at both ends, or it doesn't really connect at all. This is the verification half of the bottleneck, and cheap building makes it matter more, not less. When shipping is slow, a useless deliverable at least announces itself slowly. When it's instant, motion is easy to mistake for progress.
## Setting priorities: the practical sequence
Here's how to set product priorities in a world where building is the easy part.
### Write the goal first, in plain language, no numbers
This is the destination and it shouldn't move often. If you can't state it simply, you don't understand it yet, and no amount of fast building will fix that.
### Attach objectives that are binary at a deadline
Each one is a number you hit or miss by a date. Keep them few. These are the proof. They're also your kill switch: when an objective isn't moving, you know your approach is wrong, instead of riding a losing bet for a year because the team looked busy.
### Make the objective your prioritization filter
Since you can build almost any deliverable you can name, "can we build it" no longer narrows anything. The only filter left that means anything is "does this move an objective." That single question kills more bad roadmap items than any amount of debate.
### List deliverables under each objective, never on their own
A deliverable that doesn't sit under an objective is a distraction with a ship date. Force every proposed build to name its objective before it earns a slot on the roadmap. The ones that can't name one are exactly the work AI will let you produce fastest and regret soonest.
### Write the proof into the objective before you build
Verification starts up front. If the objective is a real behavior change with a number and a date, you already know exactly what proof you'll need and when to stop. If you can't say how you'll verify a deliverable worked, you haven't planned it, you've just described it.
### Run the trace test on every roadmap item
Pick any deliverable at random and walk it up: does it serve an objective, and does that objective serve a goal? If the chain breaks, cut the item or fix the chain. In a world of cheap building, this is the discipline that separates a roadmap from a wish list, because every deliverable now looks equally buildable. Only the trace tells you which ones are worth it.
### Close the loop after you ship
Check whether the number moved. A win confirms the bet, a flat number kills it before you sink more deliverables into a dead end. This is the D returning to the O, and it's the step that turns a roadmap into something that learns.
## The shift in one line
Building used to be the constraint, so we optimized building. Now planning and verification are the constraint, and most teams are still optimizing the wrong thing, pouring AI speed into producing more deliverables instead of into knowing which deliverable is worth producing and whether the last one worked. Goals and objectives are how you point cheap building somewhere worth going, and how you check it got there. Pick the deliverable that moves an objective, ship it, confirm the number moved, repeat. That loop is the whole job now.
---
[^1]: Sonar, 2026 State of Code Developer Survey, which found AI accounts for roughly 42% of committed code, with developers expecting that to reach about 65% by 2027.
[^2]: LinearB, 2026 Software Engineering Benchmarks Report, an analysis of 8.1 million pull requests across more than 4,800 organizations finding a 39-point gap between perceived speed (about 20% faster) and actual delivery (about 19% slower), driven by longer review times on AI-generated code.
[^3]: Sonar, 2026 State of Code Developer Survey, in which about 96% of developers said they do not fully trust AI-generated code to be functionally correct, and fewer than half always verify it before committing.
---
# Throwback Thursday — I Asked BrainGrid to Rebuild an Iconic 2010s Video Chat App in an Afternoon. It Did.
Source: https://www.braingrid.ai/blog/built-with-braingrid-pulse-vibe-coders
Published: 2026-05-14T15:00:00Z
## Built with BrainGrid: Pulse, the App That Reanimates Houseparty and Chatroulette
Welcome to *Built with BrainGrid* — a new series where we point our Builder agent at a real product idea and show you exactly what comes out the other side. Real apps, on real URLs, that you can open right now.
This first one is called **Pulse**, and the only thing I wrote for it was a single paragraph.
From that paragraph, the BrainGrid Builder agent shipped **five requirements** — the brand system, the sign-in flow, the matching engine, the live call screen, the connection-saving mechanic — each as a real GitHub pull request, each auto-deployed to a live URL. From the moment the agent started building, **v1 was live in 2 hours and 38 minutes**. A week later I asked it to add a TURN relay so testers behind strict corporate firewalls could connect. It shipped that the same way. I didn't write any of the code.
This is what that looked like, start to finish.
## A Brief History of Talking to Strangers
It's Throwback Thursday, so let's set the scene.
**2009 — Chatroulette.** A Russian teenager named Andrey Ternovskiy made a one-page website where you'd press a button and get connected, face to face, to another random person somewhere in the world. For about six months it was the most magical corner of the internet. Then the internet did what the internet does, and Chatroulette became a punchline.
**2016–2021 — Houseparty.** The "drop-in" video app. You opened it and got a notification: *Sarah is in the house.* You'd join, three friends were already on a call, you'd talk for ten minutes, and you'd close the app feeling weirdly seen. Epic Games bought it in 2019. The pandemic made it briefly enormous. They shut it down in 2021.
Both apps got something right that nothing has really replaced: **fast, face-to-face, low-overhead serendipity with humans.** And both got something wrong. Chatroulette had no filter. Houseparty had no exit ramp.
So one Thursday I opened BrainGrid and typed a paragraph describing the version of those two apps that should exist in 2026. I called it Pulse. The Builder agent took it from there.

## The One Paragraph That Started It All
Here's the entire input I gave BrainGrid. Word for word.
> Build Pulse — a topic-gated, time-boxed video chat platform. Users sign in with magic link, set a first name + pick from 12 topics (design, crypto, travel, fitness, founders, music, etc.) each session. Tap "Start matching" → pair two people on the same topic. 90-second countdown ring around each video panel; an AI-generated icebreaker question floats at the top. At T-0, big "Continue" buttons appear on both sides; mutual tap = +90s; otherwise auto-disconnect. After 3 mutual extensions, a "Save this spark" button appears — if both tap, exchange first names and save the connection. Aesthetic: dark theme, neon accents, a single large countdown ring that pulses. Like a more humane Houseparty.
That's it. No schema. No design system. No API contracts. No "and remember to handle the case where the other person closes their tab." Just the vibe and the rules.
If you've ever stared at a blinking cursor wondering how to *start* — this is the entire start. One paragraph that describes how it should *feel*, with enough specifics that a careful reader could ask the right next questions.
The agent was that careful reader.
## Before We Go Further: What You Actually Need to Do
"Anyone can do this" is a lie I'm not going to tell you. So here's what's true.
You don't need to write code. You **do** need to:
1. **Describe what you want clearly enough.** One paragraph, with the *feel* and the *rules*. Pulse's paragraph mentions the countdown, the topic picker, the icebreaker, the spark mechanic — concrete things, not "make it cool." If you can describe your idea to a friend in a coffee shop, you can describe it to BrainGrid.
2. **Read the plan before you tell it to build.** The plan is where you catch the misunderstandings. It's much cheaper to fix a requirement than a deployed app.
3. **Tap two buttons.** When a requirement looks right in the plan, tap **Start Build**. The agent goes off and writes it. When it's done, tap **Publish**. That's it. You don't open a PR, you don't run a deploy, you don't open a terminal. The version control and the deployment happen on the other side of those two buttons.
4. **Ship the next thing.** When something breaks, file a requirement. When something's missing, file a requirement. The unit of work isn't a file or a function. It's a requirement.
If you can do those four things, the rest of this post is what gets built around you.
## From Idea → Plan: 1 Epic, 5 Requirements
Before writing a single line of code, BrainGrid turned that paragraph into a plan.

One epic. Five requirements. In an order that made sense:
1. **REQ-1 — Brand & dark theme.** Build the look and feel first, so everything that follows lives inside it.
2. **REQ-2 — Session setup flow.** First name + 12-topic picker.
3. **REQ-3 — Matching engine.** The hard part. Pair two strangers on the same topic and connect them face to face.
4. **REQ-4 — Live call screen.** Countdown ring, video tiles, AI icebreaker, the "Continue" button.
5. **REQ-5 — Sparks.** The mutual-tap "save the connection" mechanic.
Notice what the agent did on its own. It didn't start with the matching engine. It started with brand, then auth, then the queue, then the call, then the connection-saving. Each requirement built on the one before it. That's how an experienced engineer would order this work — and I never had to ask for it.
Each requirement came with acceptance criteria — "Given the user has not entered a first name or selected a topic, when they view the screen, then the Start Matching button is disabled and has no glow." The agent wasn't writing pseudo-tests; it was writing the contract for what *done* meant.
## The Hard Parts BrainGrid Just Did
Database setup. Authentication. Deployment configuration. If you're not an engineer, these are the parts that usually end the project. They're where the tutorials lie to you. They're why the thing in your head never quite ships.
Pulse needed users, sessions, and a "sparks" table — so when I greenlit the plan, the BrainGrid agent provisioned a managed database, magic-link sign-in, and a live deployment. It made those calls reading my one paragraph; I never picked them off a checklist.
While the build ran, the agent:
- Spun up the database.
- Created three tables — `profiles`, `sessions`, `sparks` — each with row-level security policies that scope every row to the user who owns it.
- Wired up magic-link sign-in.
- Pushed each completed requirement to GitHub as its own pull request.
- Auto-deployed every requirement to a real, public URL.
I didn't write a migration. I didn't copy a single API key. I didn't open a database dashboard. I didn't open a deploy dashboard.
If those words sound like Greek, that's the point — you never had to learn the language to get the result.
## The Magic: How Two Strangers End Up Face to Face
This is the requirement I want to slow down on, because it's the one I would *not* have known how to write myself.
When you tap "Start matching," your browser joins what's called a real-time channel — basically a chat room — for the topic you picked. Everyone who picked "design" lands in the design room. Everyone who picked "crypto" lands in the crypto room.
Why does this matter? Because this is the kind of problem that usually turns a promising AI prototype into a dead end. BrainGrid figured out how two strangers could find each other, start a private call, and recover when something went wrong — without me designing the handshake or debugging the edge cases myself. I didn't need to understand the networking. I just needed to see that the app behaved like a real product.
The requirement covered the cases I would have completely forgotten: what happens if you deny camera permission, what happens if the other person closes their tab during setup, what happens if the connection just dies. The agent built for them.

(If you do want the engineering interview answer for *how* it pairs two strangers without a coordinator, it's in the FAQ at the bottom.)
## When You Need to Add Something Later
A few people tested Pulse and a few of them couldn't connect. Their networks were behind strict firewalls — the kind of thing that breaks browser-to-browser video. So I filed a sixth requirement: add a TURN relay for restrictive networks.
The agent shipped it. Same loop. New PR. New deploy. Validated as working in production.
The thing I want you to notice: the gap between me typing "REQ-6" and it landing was *my* calendar, not the agent's. I had a busy week. The moment I asked, it shipped — same plan-build-deploy loop as the original five, not a different motion for post-launch work.
## Try Pulse Right Now
**The bottom line:** one paragraph in, part of an afternoon later, a working app on a real URL. That's the actual scoreboard from this project.
Pulse is live. Go pair up with someone.
**→ [pulse.bgridapp.com](https://braingrid-proj-247-8dda7a.bgridapp.com)**
When you're ready to try this with your own idea, [start here](https://app.braingrid.ai/signup?from=blog).
## Frequently Asked Questions
### What is the BrainGrid Builder agent?
The BrainGrid Builder agent is an AI agent that takes a short product description, breaks it into a plan of requirements, and then builds them — provisioning a database, writing the code, opening pull requests, and deploying to a live URL. It treats the requirement, not the file or the keystroke, as its unit of work.
### Did anyone hand-write the Pulse code?
No. A human wrote the one-paragraph project description and tapped **Start Build** on each requirement, then **Publish** when the agent was done. The Builder agent produced the plan, the brand system, the database schema, the video-call signaling, the live call UI, the spark mechanic, and the TURN relay for restrictive networks.
### How long did Pulse take to build?
From the moment the agent started building, v1 was live in **2 hours and 38 minutes** — five requirements end to end. End-to-end elapsed time from paragraph to live URL was about five hours, most of which I spent reading the plan before greenlighting the build. A TURN relay for restrictive networks shipped a week later as a sixth requirement, the same way.
### How does Pulse actually pair two strangers without a server picking the room?
Essentially: BrainGrid taught the two browsers how to agree on a private room name without needing a server to assign it. The mechanism is a deterministic room ID. When two browsers see each other in the same real-time presence channel for a topic, both of them sort the two user IDs alphabetically and concatenate them — both arrive at the same room name independently, with no coordinator deciding it. The browser with the lower ID becomes the WebRTC "caller" and broadcasts the connection offer; the other becomes the "callee" and broadcasts the answer. They negotiate over the same channel, and a direct browser-to-browser video stream opens between them — no central room registry needed.
### What apps is Pulse based on?
Pulse is a 2026 reimagining of Chatroulette (2009) and Houseparty (2016–2021) — the same fast, face-to-face stranger chat, but topic-gated, time-boxed to 90 seconds, and with a mutual-tap mechanic that gates connection-saving behind three call extensions.
### Whatever happened to Houseparty?
Houseparty was a drop-in group video app launched in 2016 by Life On Air, acquired by Epic Games in 2019, and shut down in 2021. Lockdown made it briefly enormous, but post-pandemic engagement collapsed and Epic retired the app.
### Can I build something like this myself with BrainGrid?
Yes. Tell BrainGrid what you want, and the agent figures out which services your project actually needs — database, auth, real-time, deployment, whatever your idea calls for. Start with a single-paragraph project description, let the planner break it into requirements, then tap **Start Build** and **Publish** for each one.
---
# 9 Best Claude Code Alternatives in 2026 (Tested & Compared)
Source: https://www.braingrid.ai/blog/claude-code-alternatives
Published: 2026-03-26T12:00:00Z
## Why Developers Look for Claude Code Alternatives
I've been using Claude Code since it launched. It's the best terminal-based AI coding agent I've tested — it reads your entire codebase, writes code, runs commands, and fixes bugs autonomously.
Last month, I burned through $400 in tokens refactoring a single module. That's when I started testing alternatives seriously.
Claude Code isn't cheap. Pro costs $20/month with tight usage limits. Max runs $100-200/month. If you're not coding every day, that's a steep monthly bill. And if you're not a terminal person, the learning curve is steep.
For a detailed pricing breakdown, check our [Claude Code pricing guide](/blog/claude-code-pricing).
Developers typically look for alternatives for three reasons:
1. **Price.** $200/month is a hard sell for solo developers and early-stage teams.
2. **Interface.** Not everyone wants to live in the terminal. Some prefer a visual IDE.
3. **Flexibility.** Claude Code locks you into Anthropic's models. Some developers want to use GPT-4o, Gemini, or local models.
We tested 9 alternatives across three categories — terminal CLIs, IDE tools, and AI builders — on the same tasks: refactoring a 2,000-line TypeScript module, adding a feature with tests, and debugging a production error. We evaluated speed, code quality, ease of setup, and cost over two weeks.
**TL;DR:** Claude Code is the best terminal-based AI coding agent. But depending on your budget, workflow, and preferences, one of these 9 alternatives might be a better fit.
---
## Quick Comparison: Claude Code vs 9 Alternatives
| Tool | Type | Best For | Pricing | Key Differentiator |
|------|------|----------|---------|-------------------|
| **Cursor** | IDE | Pro developers wanting AI in a familiar editor | Free / $20-200/mo | Best AI-augmented IDE experience |
| **OpenCode** | Terminal CLI | Developers wanting Claude Code with any model | Free (BYOK — you pay for API) | 75+ model providers, zero lock-in |
| **Gemini CLI** | Terminal CLI | Budget-conscious developers | Free (1,000 req/day) | Most generous free tier |
| **GitHub Copilot** | IDE extension | Developers already in VS Code/JetBrains | $10-39/mo | Largest user base, works in any IDE |
| **Windsurf** | IDE | Developers who want multi-step AI flows | Free / Pro plans | Flow-based AI actions |
| **Aider** | Terminal CLI | Git-heavy workflows | Free (open source) | Automatic git commits per change |
| **Cline** | VS Code extension | VS Code users wanting agent-mode | Free (open source) | Deep VS Code integration |
| **Codex CLI** | Terminal CLI | Teams wanting sandboxed AI coding | Free (BYOK — OpenAI API) | Built-in sandbox constrains AI access |
| **BrainGrid** | Plan + Build | Non-technical builders, vibe coders | $12-89/mo | Build without ever touching code |
Every tool on this list is good at something different. The right choice depends on your workflow, not on which tool has the most features.
Let's break each one down.
---
## Cursor: Best AI-Augmented IDE
Cursor is a VS Code fork with AI baked into every interaction. If you already know VS Code, you'll feel at home in minutes. It's the most popular IDE-based alternative to Claude Code — interest in "Claude Code vs Cursor" has grown 10x in the past year, with nearly 15,000 developers searching for the comparison every month.
What makes Cursor stand out is how naturally the AI fits into your editing flow. Tab completion predicts your next edit across multiple lines. Cmd+K lets you edit or generate code inline. Agent mode lets you describe a task in plain English and watch Cursor execute it across files. It's Claude Code's autonomy inside a visual editor.
Pricing starts at $0 for the Hobby tier (limited completions) and $20/month for Pro (500 premium requests). Business plans are custom-priced per seat. That's similar to Claude Code's pricing — so you're not saving money here. You're choosing a different interface.
For a head-to-head comparison, read our [Claude Code vs Cursor deep dive](/blog/claude-code-vs-cursor). For MCP configuration tips, see our [Cursor MCP guide](/blog/cursor-mcp).
**Pros:**
- Familiar VS Code interface with zero learning curve
- Agent mode handles multi-file tasks autonomously
- Tab completion is best-in-class for inline suggestions
- Supports multiple AI models (Claude, GPT-4o, custom)
**Cons:**
- Requires local setup and a powerful machine
- No built-in planning layer — simple plans then you jump straight to code
- Similar price range as Claude Code ($20/month+)
**TL;DR:** Cursor is the best choice if you prefer an IDE over the terminal. It matches Claude Code's capabilities in a visual editor but won't save you money.
---
## OpenCode: Best Free Open-Source Alternative
OpenCode is the open-source alternative that keeps showing up everywhere. It's the most recommended tool in Reddit threads, developer forums, and nearly every "Claude Code alternatives" roundup we found during testing.
The pitch is simple: everything Claude Code does, but free and with your choice of model. OpenCode supports over 75 model providers — Anthropic, OpenAI, Google, Mistral, Ollama, and dozens more. You can even run it entirely on local models, which means zero API costs and full privacy.
The terminal experience mirrors Claude Code closely. You get codebase indexing, multi-file editing, command execution, and context-aware conversations. The difference is you bring your own API key (or local model) instead of paying Anthropic's subscription fee.
The trade-off? OpenCode is newer and has a smaller community. Documentation is improving but not as polished as Claude Code's. And because you're managing your own API keys and model configurations, there's more setup involved upfront.
**Pros:**
- Completely free and open source (MIT license)
- Supports 75+ model providers including local models
- No vendor lock-in — switch models anytime
- Active development with frequent updates
**Cons:**
- Smaller community means fewer tutorials and examples
- More initial setup than Claude Code's one-line install
- Quality depends on which model you choose
- You pay for the API usage.
**TL;DR:** OpenCode is the closest open-source match to Claude Code. If you want the same terminal agent experience paying for the underlying API use, start here.
---
## Gemini CLI: Most Generous Free Tier
Gemini CLI is Google's answer to Claude Code. It launched with a headline-grabbing offer: 1,000 free requests per day. That's not a limited trial. That's the ongoing free tier.
For context, Claude Code's Pro plan at $20/month gives you roughly 45 minutes of heavy usage before you hit limits. Gemini CLI's free tier lets you make 1,000 requests daily — enough for most individual developers to never think about billing.
The experience is solid. You get terminal-based code generation, multi-file editing, and command execution. Gemini CLI also supports MCP (Model Context Protocol) servers, which means you can connect it to external tools and data sources just like Claude Code. For setup details, check our [Gemini MCP guide](/blog/gemini-mcp).
Where Gemini CLI falls short is ecosystem maturity. It's newer than Claude Code and the model's coding abilities, while strong, aren't quite at Claude Sonnet's level for complex multi-step tasks. You'll also notice it works best within Google's ecosystem — if you're already on Google Cloud, Firebase, or Android, the integration is seamless. Outside that world, some rough edges remain.
**Pros:**
- 1,000 free requests per day — most generous free tier available
- Powered by Gemini (strong reasoning model)
- MCP support for external tool integration
- 1 million token context window
**Cons:**
- Newer tool with a smaller plugin ecosystem
- Best experience within Google's ecosystem
- Coding output slightly behind Claude for complex refactors
**TL;DR:** Gemini CLI offers 1,000 free requests per day with Gemini Pro. It's the best option if you want a capable terminal agent without spending a dollar.
---
## GitHub Copilot: Best for Inline Suggestions
GitHub Copilot is the AI coding tool most developers have heard of. With over 1.3 million paying subscribers and integration across VS Code, JetBrains, Neovim, and more, it has the largest user base of any tool on this list.
But here's the thing: Copilot and Claude Code solve different problems. Copilot excels at inline suggestions — it predicts the next line of code as you type and fills in boilerplate fast. Claude Code is an autonomous agent that handles entire tasks end-to-end. If you want a coding partner that autocompletes while you drive, Copilot is unmatched. If you want an agent that takes the wheel, it's not the right tool.
Pricing is straightforward. The Individual plan costs $10/month (or $100/year) and includes unlimited completions. Business is $19/month per user. Enterprise is $39/month per user with additional security and admin controls. That makes it the most affordable paid option on this list.
Copilot has added a Chat feature and experimental "agent mode" in VS Code, but these are still catching up to purpose-built agents like Claude Code and Cursor. The core strength remains autocomplete — and at that, it's still the best.
**Pros:**
- Works in virtually any IDE (VS Code, JetBrains, Neovim, Xcode)
- Best-in-class inline code completion
- $10/month Individual plan is affordable
- Largest community and ecosystem of any AI coding tool
**Cons:**
- Agent mode is not at the level of Claude Code
- Primarily a suggestion tool, not an autonomous agent
- Chat experience is weaker than Claude Code or Cursor
**TL;DR:** GitHub Copilot is the most widely-used AI coding tool, best for inline suggestions in your existing IDE. It's $10/month and works everywhere, but it's not an autonomous agent.
---
## Windsurf: Best for AI Flows
Windsurf (formerly Codeium) takes a different approach to AI coding. Instead of one-off completions or chat-based interactions, it organizes AI actions into "Flows" — multi-step sequences where the AI reads context, plans changes, and executes them across your codebase.
Think of it as a middle ground between Copilot's inline suggestions and Claude Code's full autonomy. You describe what you want, Windsurf creates a flow of actions, and you approve each step. It's more guided than Claude Code but more powerful than a simple autocomplete.
The IDE is clean and fast. It's built from the ground up (not a VS Code fork), which means the AI experience feels more intentional than bolted-on. The free tier gives you access to basic completions and limited flow actions. Pro plans unlock unlimited flows and premium models.
The downside is ecosystem size. Windsurf has fewer developers than VS Code or Cursor. If you rely on specific VS Code plugins for your workflow, you might hit gaps. Cognition (the company behind Windsurf) has been growing fast, but the product direction is still evolving.
**Pros:**
- Flow-based AI actions provide structured multi-step execution
- Clean, purpose-built IDE (not a fork)
- Free tier available for basic usage
- Good at understanding project-wide context
**Cons:**
- Smaller community
- Product direction still evolving as Cognition grows
- Technical team was acquired by Google; Cognition has since taken over the product direction
**TL;DR:** Windsurf organizes AI coding into structured flows — a middle ground between autocomplete and full autonomy. It's great if you want guided multi-step AI actions in a clean IDE.
---
## Aider: Best for Git-Native Workflows
Aider is the terminal-based AI coding tool for developers who live and breathe git. Its killer feature: every AI-generated change is automatically committed with a descriptive commit message. Your git history stays clean, every change is trackable, and you can roll back any AI edit with a simple `git revert`.
This matters more than you'd think. With Claude Code, AI changes get mixed into your working directory. You have to manually stage, review, and commit. With Aider, the commit discipline is built in. For teams that care about code review workflows, this is a major advantage.
Aider is open source and free. You bring your own API key — it supports OpenAI, Anthropic, Google, and local models via Ollama. The SWE-bench results are impressive: Aider consistently ranks among the top open-source agents on the [SWE-bench leaderboard](https://www.swebench.com/) for automated software engineering tasks.
The learning curve is steeper than Claude Code. Aider uses a unique chat syntax with `/` commands and specialized modes (architect mode, editor mode) that take time to master. And the terminal-only interface means no visual diff previews — you're reviewing changes in git.
**Pros:**
- Automatic git commits for every AI change — clean history by default
- Free and open source with strong benchmark results
- Supports multiple model providers (bring your own key)
- Architect + editor mode for complex refactoring tasks
**Cons:**
- Terminal only — no visual editor or diff preview
- Steeper learning curve with unique command syntax
- Less polished onboarding compared to Claude Code
**TL;DR:** Aider is the best choice for git-native workflows. Every AI edit gets its own commit automatically, and it's completely free and open source.
---
## Cline: Best VS Code Agent Extension
Cline is an open-source VS Code extension that turns your editor into a full AI coding agent. Unlike Copilot's inline suggestions, Cline operates in agent mode by default — it can create files, edit existing code, run terminal commands, and browse the web, all from within VS Code.
The value proposition is clear: if VS Code is your home, Cline brings Claude Code-level capabilities without leaving it. You don't need a separate terminal window or a different IDE. Everything happens in your existing editor with your existing extensions and keybindings.
Cline supports multiple AI providers. You can connect it to Anthropic (Claude), OpenAI, Google, or any OpenRouter-compatible model. The extension is free, but you pay for API usage with your own keys. For heavy users, this can actually be cheaper than Claude Code's subscription — or more expensive, depending on your usage patterns.
The trade-off is VS Code lock-in. Cline doesn't work in JetBrains, Neovim, or other editors. And while the extension is powerful, it's maintained by a smaller team than commercial products like Cursor, so updates and bug fixes can be slower.
**Pros:**
- Deep VS Code integration — agent mode inside your existing editor
- Open source and free (you pay for API usage only)
- Supports multiple AI providers via API keys
- Can create files, run commands, and browse the web
**Cons:**
- VS Code only — no JetBrains or other editor support
- Smaller development team than commercial alternatives
- API costs can be unpredictable with heavy usage
**TL;DR:** Cline is the best option if you want agent-mode AI coding without leaving VS Code. It's open source, supports multiple models, and integrates deeply into your existing workflow.
---
## OpenAI Codex CLI: Best for Sandboxed Coding
OpenAI's [Codex CLI](https://developers.openai.com/codex/cli) is a lightweight open-source terminal agent powered by the Codex model family. It runs locally but with a key difference from Claude Code: built-in sandboxing.
By default, Codex CLI constrains what the AI can do on your machine. The "workspace-write" mode lets it read files and edit within your project folder, but limits network access and filesystem reach. You review every change before it's applied. For teams that worry about AI agents running destructive commands, this safety-first approach is a big deal.
The CLI experience is straightforward. Run `codex` for an interactive terminal UI where you iterate conversationally. Run `codex exec` for scripted, non-interactive tasks — great for CI pipelines. It reads your repo, makes edits, and runs commands. Same primitives as Claude Code, different model underneath.
The trade-off is model capability. OpenAI's coding models are strong, but Claude Sonnet still leads on complex multi-step refactors in most benchmarks. And since Codex CLI is open source and relatively new, the plugin ecosystem is smaller than Claude Code's.
**Pros:**
- Built-in sandboxing — constrains AI access to filesystem and network by default
- Open source and free (you pay for OpenAI API usage or you can use your ChatGPT subscription)
- Interactive TUI + scriptable `codex exec` for CI workflows
- Powered by the Codex model family (OpenAI's reasoning models)
**Cons:**
- Coding output behind Claude Opus for complex multi-file refactors
- Requires OpenAI API access and credits (if you don't have a subscription)
- Newer tool with a smaller community than Claude Code
- Less mature extension ecosystem
**TL;DR:** Codex CLI is OpenAI's open-source terminal agent with built-in sandboxing. Best if you want Claude Code-style autonomy with stricter safety guardrails on what the AI can touch.
---
## BrainGrid: Best for Planning Before Building
Most AI coding sessions fail before the first line of code. Not because the tool is bad — because the prompt is vague. BrainGrid fixes that.
Here's the problem BrainGrid solves. Most AI coding failures aren't about the coding tool. They're about the prompt. You open Claude Code, type "build me a dashboard," and get something that technically works but misses half your requirements. You spend the next two hours fixing edge cases the AI didn't know about.
BrainGrid sits before the build step. It helps you plan your project with structured specs, acceptance criteria, and task breakdowns. Then you hand those specs to your coding tool of choice. The result: fewer wasted tokens, cleaner output, and a clear definition of "done" before you write a single line of code.
Pricing starts at $12/month for the Builder plan. Builder Pro is $29/month and includes unlimited projects. Team is $89/month per seat. Compared to burning through a $200/month Claude Code Max subscription with vague prompts, spending $12/month on structured specs can actually reduce your total AI coding bill.
Let's be honest about what BrainGrid is not. It's not a terminal agent. It's not an IDE. If you're looking for a direct drop-in replacement for Claude Code, BrainGrid isn't it. It's a complementary tool that belongs earlier in your workflow.
**Pros:**
- Plans your project with specs and acceptance criteria before building
- Cloud builder ships features directly from specs — no local setup needed
- Works with any coding tool (Claude Code, Cursor, Copilot, etc.)
- Starts at $12/month — reduces wasted tokens on other tools
**Cons:**
- Not a direct Claude Code replacement — different category entirely
- Cloud builder is newer and best suited for web apps
- Adds a step to your workflow (planning before coding)
**TL;DR:** BrainGrid doesn't replace Claude Code. It makes every Claude Code session more productive by creating structured specs before you build. Think of it as the planning layer your AI coding stack is missing.
---
## How to Choose the Right Claude Code Alternative
Nine tools is a lot. Here's the quick decision framework:
- **Want a familiar IDE?** Go with Cursor.
- **Want free and open source?** Start with OpenCode or Aider.
- **Want Google's ecosystem?** Try Gemini CLI.
- **Want inline suggestions in your existing editor?** GitHub Copilot.
- **Want structured AI flows?** Windsurf.
- **Want an agent inside VS Code?** Cline.
- **Want sandboxed execution?** Codex CLI.
- **Want to build without touching code?** [BrainGrid](/).
- **Want Claude Code but cheaper?** Keep Claude Code and pair it with BrainGrid specs. Better prompts = fewer wasted tokens.
**Start with your interface preference.** Terminal people: OpenCode (free, any model), Gemini CLI (free tier), or Aider (git-native). IDE people: Cursor (best AI IDE), Windsurf (flow-based), or Cline (VS Code extension).
**Then consider your budget.** OpenCode and Aider are free (you pay for API keys only). Gemini CLI gives you 1,000 free requests daily. Copilot is $10/month. Cursor and Claude Code both top out at $200/month.
**Finally, ask where your workflow actually breaks.** Most developers pick tools based on features. The better question: "Where does my AI coding fail?" If it fails at writing code, any tool here helps. If it fails because you don't know what to build, none of them will — except BrainGrid.
The best AI coding setup isn't one tool. It's the right combination. Many developers use BrainGrid for planning, then Claude Code or Cursor for building. The planning step pays for itself in saved tokens and fewer rewrites.
---
## Frequently Asked Questions
### Is there anything better than Claude Code?
Claude Code is the strongest terminal-based AI coding agent for autonomous tasks. For developers who prefer an IDE, Cursor offers a better experience. For those who want free and open-source, OpenCode matches most of Claude Code's features at zero cost.
### Is there an open-source alternative to Claude Code?
Yes. OpenCode is the closest open-source match — it supports 75+ model providers and runs locally. Aider is another strong option with native git integration. Cline works as a VS Code extension with agent capabilities. You still have to pay the underlying model provider.
### What is the best coding agent like Claude Code?
For terminal agents: OpenCode (free, any model) or Gemini CLI (Google, free tier). For IDE agents: Cursor (VS Code fork with deep AI) or Windsurf (flow-based AI). For plan + build: BrainGrid (creates specs then builds).
### What is Google's equivalent to Claude Code?
Gemini CLI is Google's terminal-based coding agent. It offers 1,000 free requests per day using Gemini 2.5 Pro and supports MCP servers, making it the most generous free alternative.
### What is the cheapest Claude Code alternative?
Gemini CLI is free with 1,000 requests per day. OpenCode and Aider are free and open source — you only pay for API keys (or nothing if you use local models). GitHub Copilot is the cheapest paid option at $10/month.
### Which Claude Code alternative is best for beginners?
For beginners who prefer a visual editor, Cursor is the easiest transition — it looks and works like VS Code. For non-technical builders who want to skip coding entirely, BrainGrid lets you plan and build a project without touching a terminal.
### Can I use Claude Code with BrainGrid?
Yes — they're complementary. BrainGrid creates structured specs with acceptance criteria. Claude Code builds from those specs. The result: fewer wasted tokens, better code quality, and a clear definition of "done" before you start building.
---
---
# Context Engineering Is What You're Actually Doing (You Just Don't Know It Yet)
Source: https://www.braingrid.ai/blog/context-engineering
Published: 2026-03-26T10:00:00Z
Prompt engineering was supposed to be the skill that separated great AI builders from everyone else. Craft the perfect instruction, get the perfect output. An entire cottage industry of courses, templates, and "prompt libraries" sprang up around this idea.
But the builders actually shipping production software with AI agents have quietly moved on. The skill that determines whether your agent builds something useful or produces confident garbage isn't how you phrase your request. It's what the agent already knows before you ask.
## The Prompt Is the Smallest Part
A fresh Claude Code session loads roughly 27,000 tokens of system instructions, tool definitions, memory files, and project configuration before you type a single character. On a 200K context window model, [that's already around 15% of your budget gone](https://www.jdhodges.com/blog/claude-code-context-slash-command-token-usage/). On a session with MCP tools and a well-configured CLAUDE.md, you can push past 30,000 tokens at startup.
Most builders have no idea this is happening.
They agonize over the wording of their prompt while ignoring the 30,000 tokens of context their agent silently inherited. That's like meticulously choosing the last ingredient in a recipe while someone else already decided the other twenty.
This is the core insight behind context engineering: the practice of designing and managing everything an AI model sees at inference time. Not just the prompt. The system instructions, tool definitions, retrieved documents, conversation history, memory, and constraints.
Andrej Karpathy [put it this way](https://x.com/karpathy/status/1937902205765607626):
> Context engineering is the delicate art and science of filling the context window with just the right information for the next step.
Shopify CEO Tobi Lutke [called it a "core skill"](https://x.com/tobi/status/1935533422589399127):
> The art of providing all the context for the task to be plausibly solvable by the LLM.
Both are pointing at the same shift. Prompt engineering asks: "What should I say?" Context engineering asks: "What should the model know before I say anything?" That's an entirely different question.
## Why Your Agent Gets Worse the Longer You Work
Most builders learn this the hard way. Your agent doesn't just degrade because the model is "bad at long conversations." It degrades because of attention dilution.
LLMs distribute their attention mechanism across the entire context window. As that window fills up, attention spreads thinner. Instructions from the beginning of the session get buried under newer messages. Constraints you set at the start get deprioritized. The model starts improvising where it used to follow rules.
Research on large language models shows that [output quality drops significantly when relevant information lands in the middle of the context window](https://arxiv.org/abs/2307.03172) — a phenomenon researchers call "lost in the middle." For long coding sessions, this means instructions from early in the conversation get buried and deprioritized as newer messages accumulate. You haven't even finished your first major feature and the agent is already losing the plot.
This is a context engineering problem, not a prompting problem. No amount of rewording your instruction fixes attention dilution. What fixes it is controlling what's in the window in the first place: trimming irrelevant history, compacting conversation turns, and making sure the right information is in the right position when the model needs it.
Peer-reviewed research confirms what practitioners already suspected: context structure matters more than prompt phrasing. [Structured prompting techniques improved code generation accuracy by up to 14%](https://dl.acm.org/doi/10.1145/3690635) on standard benchmarks, and a [METR randomized trial](https://metr.org/blog/2025-07-10-early-2025-ai-experienced-os-dev-study/) found experienced developers were actually 19% slower when using AI tools with poor codebase context. The model wasn't the bottleneck. The context was.
That should change how you think about every AI coding session.
## The Five Layers You're Ignoring
Context engineering isn't a single technique. It's a discipline with at least five layers that work together:
**System instructions.** The rules and personality your agent inherits before you speak. In Claude Code, this is the system prompt plus your CLAUDE.md files. Most builders either leave these as defaults or bloat them with hundreds of lines, wasting tokens on context that rarely matters.
**Knowledge retrieval.** The documents, code files, and reference material the agent can access. This is where RAG patterns live, but it also includes what files your agent reads when exploring your codebase. An agent that reads irrelevant files fills its context with noise.
**Memory injection.** Persistent facts about your project, preferences, and decisions that carry across sessions. Without this, you re-explain the same constraints every time you start a new conversation. The repetitive context-loading that [erodes your productivity gains](/blog/the-babysitting-is-over-a-new-plan-for-ai-coding).
**History compression.** How conversation turns get summarized or trimmed as the session grows. Uncompressed history is the fastest way to hit attention dilution. But aggressive compression loses nuance. The balance is non-trivial.
**Tool resolution.** Which tools your agent can access and how their definitions are formatted. Each tool definition consumes tokens. If your agent has access to 40 [MCP tools](/blog/claude-code-mcp) but only uses 3 for a given task, the other 37 are pure context waste.
Most builders think about exactly one of these layers: what they type into the prompt box. The other four layers quietly shape every response the agent produces.
## What This Means for You
If you're building a SaaS product with Claude Code or Cursor right now, here's what changes.
Your third or fourth feature is where context engineering failures compound. By then, you've accumulated enough conversation history, enough code files read, and enough tool definitions that the agent's effective attention budget for your actual request is a fraction of what it was on feature one. Without [a deliberate planning approach](/blog/planning-in-the-age-of-capable-coding-agents), the agent will generate conflicting state management, duplicate auth logic, and inconsistent API patterns. Not because it's bad at coding, but because it was never told how the pieces fit together, and the context that did tell it has been diluted beyond usefulness.
Starting a fresh session helps. But then you face the opposite problem: the agent has no context at all. You're back to explaining your project architecture, your naming conventions, your business rules, your tech stack decisions. Every. Single. Time.
This is the trap. Too much accumulated context degrades quality. Too little fresh context means the agent is guessing. The only way out is structured context: giving the agent exactly the information it needs, in a format it can use efficiently, without the noise.
## Spec-Driven Development Is Context Engineering
This is the reframe most people miss.
When we talk about [spec-driven development](/blog/spec-driven-development), we're talking about context engineering. The entire discipline of writing structured requirements, defining acceptance criteria, capturing edge cases, and formatting that information for AI consumption is context engineering in practice. It just has a more specific name when applied to the planning layer.
Think about what a well-written specification actually is: it's a context document. It tells the agent what you're building, why you're building it, what "done" looks like, and what constraints to respect. It's the most important context your agent will consume during a session, more important than the system prompt, more important than whatever files it happens to read.
A vague prompt like "build me a CRM" gives the agent almost no useful context. It will fill the gap with assumptions, inventing data schemas, naming conventions, UI patterns, and business logic you never defined. A structured requirement that specifies "contact management for sales teams, sortable table with name/company/last-contacted, detail panel on row click, company filter, authenticated access only, redirect unauthenticated users to /login" gives the agent dense, high-signal context that eliminates guessing.
In BrainGrid, you describe your idea to the AI planning agent and it generates structured requirements with acceptance criteria, edge cases, and technical context. That's not project management. That's context engineering for your coding agent. The planning agent asks the clarifying questions that surface the information your coding agent will need later, capturing it in a format that maximizes signal and minimizes noise when it hits the context window.
The difference shows up immediately. Teams using structured requirements report cutting regeneration cycles from 5+ per feature to 1-2. Not because the model got smarter, but because the context got better.
## Context Engineering Has Limits
This isn't a silver bullet. Context engineering can't fix a model that genuinely lacks capability for your task. It can't compensate for a codebase so tangled that no amount of context will help the agent reason about it. And it requires effort upfront. Writing structured requirements takes longer than typing "build me a CRM."
The trade-off is real: more time specifying means less time prompting, but significantly less time debugging and reverting. For quick prototypes and throwaway experiments, detailed context engineering is overkill. For anything you plan to ship to real users, it's the difference between building a product and accumulating technical debt at AI speed.
The data backs this up: [a survey of 500 engineering leaders found 67% spend more time debugging AI-generated code than writing it](https://www.augmentcode.com/guides/the-context-gap-why-some-ai-coding-tools-break), with context limitations — not model capability — as the primary root cause. [Analysis of 470 real pull requests](https://www.coderabbit.ai/blog/state-of-ai-vs-human-code-generation-report) showed AI-authored code averages 10.8 issues per PR versus 6.5 for human code, with logic and correctness errors — the kind driven by missing context — 75% more common. You're almost certainly fighting the wrong battle if you're shopping for a better model when your context is a mess.
## The Context Engineering Stack
The builders who are shipping the most reliable AI-built software have converged on a pattern, whether they call it context engineering or not:
```mermaid
flowchart TD
A["Structured Requirement\n(what to build, why,\nacceptance criteria)"] --> B["Agent Session\n(clean context window)"]
B --> C["Focused Execution\n(bounded tasks,\nminimal noise)"]
C --> D["Verification\n(output matches spec)"]
D --> E["Next Session\n(fresh window,\npersistent requirement)"]
E --> B
```
The requirement persists across sessions. The context window stays clean. Each session starts with exactly the context the agent needs for the next bounded task, not the accumulated debris of everything that came before.
This is the workflow BrainGrid was built for. The [Build tab](https://app.braingrid.ai) formats your requirement for whichever coding agent you're using, whether that's Claude Code, Cursor, or an MCP-connected tool. The requirement is the persistent context layer that survives session boundaries, tool switches, and team handoffs. When your agent starts a fresh session, it doesn't start from zero. It starts from a structured, high-signal specification that puts the right information in the context window from the first token.
## What Happens Next
Context engineering is not a trend that peaks and fades. It's the natural consequence of AI agents becoming capable enough that the bottleneck shifts from model intelligence to input quality. As context windows grow larger (Claude now offers [1M tokens](https://medium.com/@ivankolodiy/claudes-1m-context-window-is-finally-here-here-s-what-actually-changed-3d0949c15259)), the challenge doesn't get easier. Larger windows mean more room for noise, more attention to dilute, and more surface area for context engineering mistakes.
The builders who treat their agent's context window like a [carefully curated workspace](/blog/the-oversight-premium) will ship better software than the builders who dump everything in and hope the model figures it out. That's not a prediction. It's already happening.
The question isn't whether you'll do context engineering. You're already doing it, every time you write a CLAUDE.md file, configure an MCP server, or decide which files to reference before asking your agent to build something. The question is whether you'll do it deliberately or by accident.
---
*[BrainGrid](https://www.braingrid.ai) is the AI Product Planner that turns your ideas into structured, AI-ready requirements, context engineering for your coding agent. Try it at [braingrid.ai](https://www.braingrid.ai).*
---
# BrainGrid Raises $1M Pre-Seed to Bring the First AI Product Planner to Non-Technical Builders
Source: https://www.braingrid.ai/blog/braingrid-raises-1m-pre-seed
Published: 2026-03-24T07:00:00Z
Today we're excited to share that BrainGrid has raised a $1M pre-seed round led by Menlo Ventures, with participation from Next Tier Ventures and Brainstorm Ventures.
This funding supports our mission to make it possible for anyone with an idea to turn it into a real product. Build in minutes. Launch in hours. Sell to real customers without needing engineering teams, complicated frameworks, or months of fixing bugs in a prototype.
## The New Bottleneck Is Not Code. It Is Planning.
We've been building software for over 25 years. Between us, Nico and Tyler, we've shipped products across startups, enterprise teams, and everything in between. We've lived through every major era of software development, from waterfall to agile, from monoliths to microservices, from on-prem to the cloud, now from managed teams to solo founders.
AI has changed how software gets built. Domain experts, creators, and entrepreneurs who've never written a line of code are now building real applications through natural language. That is extraordinary.
But the theory of constraints hasn't changed. The bottleneck has just moved.
Writing code is no longer the constraint. AI coding tools can generate code faster than any team we have ever worked with. What they can't do is think through the entire product, this takes more than coding.
The constraint is now [planning](/blog/spec-driven-development).
And this will only become more true over time. As AI coding agents run for longer, handle more complexity, and operate with greater autonomy, the quality of the plan they start with matters more, not less. Today's agents can build entire features end-to-end. They manage their own task breakdown, make implementation decisions based on what the code actually looks like, and run for hours without intervention. The builder's job is no longer to manage implementation steps. It's to define *what* needs to be built and *why* it matters. The requirement is the unit of leverage and a vague one produces a fragile app while a clear, structured specification produces software that works that leads to a successful product.
In traditional teams, this thinking is done by a Product Manager. In the new era of AI-native development, that role doesn't exist. So the builder gets stuck.
BrainGrid exists to fill that gap, as the AI Product Planner.
## Introducing the AI Product Planner
BrainGrid is the AI Product Planner for the new generation of builders. It turns messy ideas into designs and structured product plans that coding agents can actually build part by part. It ensures that features are scoped, built in the right order, and the outcome matches the intent.
Builders use BrainGrid alongside Cursor, Claude Code, and other AI coding tools. Builders are not locked in using a particular agent.
## Builders Are Already Shipping Real Products
BrainGrid has already helped over 500 builders ship real AI-native SaaS products. These aren't prototypes sitting in a repo. These are live products with real users and paying customers.
Here are some of their stories.
### Kaleen Canevari — Motra Studio
Kaleen is a mechanical engineer and certified Pilates instructor who set out to build a multi-tenant SaaS platform where studio owners can host video content and manage client subscriptions. She describes herself as a "vibe coder", someone who excels at outlining a vision and using AI tools to translate it into code.
Before BrainGrid, she hit a wall. While building a feature to analyze class transcripts with an LLM, she broke her application and couldn't fix it, even after multiple attempts with her existing AI tools.
She turned to BrainGrid, and had the feature working immediately. Since then, she has integrated Stripe Connect for multi-party payments, deployed to Vercel, and onboarded her first paying studio owner.
> "I spent a couple of days spinning in circles trying to integrate this transcript-analysis feature. I tried rebuilding it twice without BrainGrid, and every time something broke. Finally, I decided to start fresh with BrainGrid. I had it rebuild the whole thing from scratch, and it just worked."
[Read Kaleen's full story →](/blog/builder-story-kaleen-canevari-motra-studio)
### Matt Bernier & Clay Unicorn — Unicorn.love
Matt and Clay run a venture studio in Denver, building multiple SaaS companies while advising a portfolio of startups and public companies. They are deeply technical, Clay has been building software for nearly 24 years. Their challenge wasn't whether they could code. It was whether they could translate messy real-world inputs into clean, executable work across many projects without becoming the bottleneck.
Matt discovered BrainGrid at a Denver vibe coding meetup. On a call with Tyler, BrainGrid's co-founder, he shut down the open source tool he had been hacking on, signed up, and started using it immediately. BrainGrid was already solving the exact problems he had been trying to patch together.
The team has since shipped over 200 features using BrainGrid as their central planning system. Non-technical team members now submit bug reports and feature requests directly through BrainGrid, producing specifications that agents can execute without a human in the loop.
> "BrainGrid is the most agnostic piece of my stack. I'll drop models. I won't drop planning."
[Read Matt and Clay's full story →](/blog/builder-story-matt-bernier-clay-unicorn-unicorn-love)
### Audrius — Deep Focus
Audrius comes from a marketing background with years of corporate experience. He's not an engineer. He learned the basics of Python, HTML, and CSS, enough to read code but not write it from scratch. When the vibe coding movement took off, he saw an opportunity to finally build the tools he had been thinking about for years.
He is building Deep Focus, a focus timer application with Google Calendar syncing, shared sessions, and analytics. What sounded simple turned out to be anything but simple, persistent state across devices, OAuth flows, calendar API integration, and session management across tabs and browsers.
BrainGrid's follow-up questions were the turning point. When Audrius submitted an idea, BrainGrid came back with clarifying questions that surfaced edge cases and technical concerns he hadn't considered. In roughly three months, he went from no engineering background to a live, functional application with Google sign-in, cross-device sync, shared focus sessions, analytics dashboards, and full Google Calendar integration.
> "Those follow-up questions, it's a goldmine. I did not think about that and that. That's where your product helped me a lot."
[Read Audrius's full story →](/blog/builder-story-audris-deep-focus)
### Saymon — Core Care
Saymon is a software engineer from Brazil with eight years of experience. He has led teams of eight, shipped features for apps with over 9 million daily active users, and taken products from concept to seed funding. He's not a vibe coder learning to build. He is a senior engineer who recognized that the bottleneck was never the code itself.
He is building Core Care, an all-in-one platform for therapists in Brazil that covers patient management, financials, telemedicine, and video sessions, essentially seven startups consolidated into a single product.
As a solo consultant working across multiple client projects, Saymon faced a recurring problem: great product management tools had no awareness of the codebase, and powerful coding agents didn't understand product context. He was the bridge between the two, and that bridge was expensive. BrainGrid gave him something no other tool could — the ability to do requirements planning and task breakdown with knowledge of the codebase.
The results speak for themselves. On one client project, planning that would have taken two full days was completed in 30 minutes. The feature was delivered in just over two weeks instead of three to four, and the client used it for an event that generated $1 million in revenue.
> "The feeling I have when using BrainGrid is that I have a PM with me."
[Read Saymon's full story →](/blog/builder-story-saymon-core-care)
---
The pattern across every builder is the same. AI coding tools are powerful. BrainGrid makes them productive, by giving builders the planning layer they didn't know they needed.
## The Vision: A Product Factory for Non-Technical Builders
BrainGrid is the product factory for people who know *what* they want to build but not *how* to build it.
That is a different product from developer tools. Developer tools assume you already know how to build and bring your own workflows. We're serving a different audience entirely, domain experts, founders, and creators who have deep knowledge of their problem space but need a system to turn that knowledge into working software.
The BrainGrid platform is built around four stages:
**Capture → Structure → Build → Verify**
Capture your thinking. Structure it into a product plan. Orchestrate the build with your AI coding tool. Verify that it works.
Today, the AI Product Planner handles Capture and Structure. Next, the platform will expand to orchestrate the full lifecycle from idea to live, revenue-generating product.
Our long-term vision: anyone with an idea can build an AI-native SaaS business. Not someday. Now.
## Why We Partnered With These Investors
Menlo Ventures, Next Tier Ventures, and Brainstorm Ventures understand the significance of AI-native software business creation. They've backed iconic platforms and developer tools that shaped previous eras of software. They see BrainGrid as the missing layer in the emerging ecosystem of AI-powered development.
"Nico and Tyler deeply understand how software gets built at scale," said Shawn Carolan, Partner at Menlo. "BrainGrid brings that experience to the millions of new founders empowered by AI."
## A Thank You to Our Early Community
To everyone who tried BrainGrid, gave feedback, or pushed the boundaries of what's possible: thank you. You're building the first generation of AI-native SaaS products, and we are honored to support you.
You showed us that this role — the AI Product Planner — is essential for the future of AI development.
**Try BrainGrid at [braingrid.ai](https://www.braingrid.ai/)**
---
# Claude Code Plan Mode: What's Missing and How to Fix It
Source: https://www.braingrid.ai/blog/claude-plan-mode
Published: 2026-03-19T10:00:00Z
Claude Code's plan mode might be the most underrated feature in any AI coding tool right now. While most developers are racing to generate code faster, plan mode does something counterintuitive: it tells the AI to stop and think before it touches anything.
That instinct — separate the thinking from the doing — is exactly right. And if you're not using plan mode yet, you should be.
But there's a gap between what plan mode gives you and what you actually need when you're building something real. Let's talk about both.
---
## What Is Plan Mode?
Plan mode is a read-only permission setting in Claude Code. When you activate it, Claude can analyze your entire codebase — read files, search for patterns, trace dependencies — but it cannot modify anything. No file edits. No shell commands. No side effects.
You activate it by pressing `Shift+Tab` twice in a Claude Code session, or by starting with `claude --permission-mode plan`. There's also a `/plan` slash command.
```mermaid
flowchart LR
A["Enter Plan Mode\n(Shift+Tab ×2)"] --> B["Claude Analyzes\n(read-only)"]
B --> C["Structured Plan\n+ Task List"]
C --> D["You Review\n& Approve"]
D --> E["Exit Plan Mode\n(Shift+Tab)"]
E --> F["Claude Executes\nthe Plan"]
```
Once in plan mode, you describe what you want to build. Claude reads the relevant code, asks clarifying questions, and produces a structured plan — often with a numbered task list. You review the plan, ask follow-ups, request changes. When you're satisfied, you exit plan mode and Claude executes what you agreed on.
The task lists Claude creates in plan mode even survive context compaction, which means they persist through long sessions where earlier conversation history gets trimmed.
---
## When Plan Mode Works Well
Plan mode is genuinely useful in specific situations:
- **Exploring unfamiliar code.** Just joined a project? Let Claude give you a guided tour of the architecture without the risk of it accidentally breaking something while you're still learning where things live.
- **Complex multi-file changes.** If a task touches ten or more files, starting in plan mode lets Claude map the scope, identify dependencies, and surface edge cases before committing to an approach. A few minutes of planning saves hours of backtracking.
- **Risky refactors.** Changing authentication? Restructuring the database layer? Migrating an API? These are situations where you want to see the full picture before anything moves.
- **Getting a second opinion.** Not sure how to approach something? Plan mode gives you Claude's analysis without it immediately jumping into implementation.
The underlying idea is sound: think first, execute later. Every experienced developer already does this naturally. Plan mode formalizes it for the AI.
---
## Where Plan Mode Breaks Down
Here's the honest part. Plan mode works well within a single session. The problems start when you zoom out.
### Plans are session-scoped
Your plan lives inside a Claude Code conversation. When the session ends, the plan goes with it. Task lists survive context compaction within a session, but across sessions? You're starting fresh. Stale plan context can bleed between sessions and confuse the agent about which task it's supposed to be working on.
If you're building a feature over multiple days — which is most features — the plan you carefully crafted on Monday is gone by Wednesday.
### Plans aren't collaborative
Your plan lives in your terminal. Your co-founder can't see it. Your designer can't comment on it. Your team can't review the approach before you start building. There's no shared artifact. There's no approval step outside of your own judgment.
For solo builders, this is manageable. For teams, it's a real gap.
### Plans lack domain context
Plan mode reads code. It's good at understanding what your codebase does today. But it doesn't know why you built it that way. It doesn't know your business rules, your customer constraints, or the regulatory requirements your product needs to satisfy.
You can type all of that into the conversation manually, every session. But that's exactly the kind of [repetitive context-loading](/blog/the-babysitting-is-over-a-new-plan-for-ai-coding) that erodes the productivity gains the tool is supposed to provide.
### Plans are tool-locked
A plan created in Claude Code stays in Claude Code. If you want to hand part of the work to [Cursor](/blog/claude-code-vs-cursor), or run it through a different agent, or use an [MCP-connected tool](/blog/claude-code-mcp), you're copy-pasting and re-explaining. The plan has no portable format.
### Plans don't track execution
Once you exit plan mode and start building, the connection between the plan and what actually happened is informal. There's no structured record of which steps were completed, which were skipped, which led to unexpected decisions. If something breaks three days later, you're reconstructing from memory.
```mermaid
flowchart TD
subgraph PM["Plan Mode Strengths"]
A["Read-only analysis"]
B["Structured task lists"]
C["Clarifying questions"]
D["Safe exploration"]
end
subgraph GAPS["What's Missing"]
E["Persistence across sessions"]
F["Team collaboration"]
G["Domain / business context"]
H["Cross-tool portability"]
I["Execution tracking"]
end
PM -.->|"single session\nonly"| GAPS
```
None of these are criticisms of plan mode itself. It does what it's designed to do. The issue is that planning, for real software, requires more than a single-session, single-tool, single-person conversation.
---
## What's Actually Needed
The gap isn't "better plan mode." The gap is a planning layer that sits above any individual coding tool and provides:
1. **Persistence** — Plans that survive sessions, days, weeks.
2. **Collaboration** — Plans that a team can review, refine, and approve.
3. **Domain context** — Plans that capture business rules and product constraints, not just code structure.
4. **Portability** — Plans that work with any agent, not just the one that created them.
5. **Execution tracking** — A structured record of what the agent actually did against the plan.
This is the problem [spec-driven development](/blog/spec-driven-development) was designed to solve. And it's why we built BrainGrid.
---
## How BrainGrid Fills the Gap
BrainGrid isn't a replacement for plan mode. It's the layer that makes plan mode's output durable and useful beyond a single session.
Here's how BrainGrid addresses each plan mode limitation:
| Plan Mode Limitation | BrainGrid's Approach |
|---|---|
| Plans vanish between sessions | Requirements persist in BrainGrid — they're permanent artifacts |
| Plans live in one person's terminal | Teams can review, refine, and comment on requirements together |
| Plans lack business context | The [specify flow](/blog/spec-driven-development) captures domain knowledge through clarifying questions |
| Plans are locked to Claude Code | The Build tab works with Claude Code, Cursor, MCP, or copy-paste |
| No execution tracking | Tasks are created by the agent as it builds — a structured record of decisions and progress |
The [specify flow](https://app.braingrid.ai) works like a senior tech lead interviewing you about what you want to build. It asks about edge cases, acceptance criteria, constraints, and context. The output is a complete requirement — not a prompt, not a plan that disappears, but a durable specification that any agent can execute against.
When you're ready to build, the [Build tab](/blog/planning-in-the-age-of-capable-coding-agents) gives you the requirement formatted for your tool of choice. Claude Code gets a slash command. Cursor gets a prompt. MCP-connected agents get structured context. The requirement is the same everywhere.
As the agent builds, it creates tasks in BrainGrid, documenting each step. If you need to pick up tomorrow, the context is there. If a teammate needs to review what happened, it's tracked.
---
## The Workflow: Plan Mode + BrainGrid Together
This isn't an either/or choice. The best workflow uses both.
```mermaid
flowchart TD
A["Specify requirement\nin BrainGrid"] --> B["Requirement with\nacceptance criteria,\nedge cases, context"]
B --> C["Open Build tab\nin BrainGrid"]
C --> D{"Choose your\nagent"}
D -->|Claude Code| E["Paste slash command\ninto terminal"]
D -->|Cursor| F["Paste prompt\ninto Cursor"]
D -->|MCP| G["Connect via\nMCP server"]
E --> H["Use plan mode for\nin-session exploration"]
H --> I["Agent builds\nagainst requirement"]
F --> I
G --> I
I --> J["Tasks logged in\nBrainGrid as\nagent works"]
J --> K["Review PR +\ntask history"]
```
1. **Specify in BrainGrid.** Describe what you want to build. The planning agent refines it into a complete requirement with acceptance criteria, edge cases, and technical context. This is your persistent plan — the one that doesn't disappear.
2. **Open the Build tab.** Pick your coding agent. BrainGrid formats the requirement for whichever tool you're using.
3. **Use plan mode for in-session exploration.** When you're in Claude Code and need to explore how a particular part of the codebase works before making changes, switch to plan mode. This is where plan mode shines — tactical, in-session analysis. The strategic plan lives in BrainGrid.
4. **Build.** The agent works against the requirement. As it goes, it logs tasks in BrainGrid.
5. **Review.** When the agent finishes, you've got a PR to review and a complete task history in BrainGrid showing what happened.
---
## The Bigger Picture
Claude Code's plan mode represents something important: the recognition that AI coding isn't just about generating code faster. Planning matters. Thinking before acting matters. [The best vibe coding tools in 2026](/blog/best-vibe-coding-tools-2026) all recognize this in different ways.
But planning that lives inside a single session, in a single tool, for a single person — that's a starting point, not a destination.
The shift happening right now in AI-assisted development is from "ask the AI to write code" to "define what you want built and let the agent figure out how." Plan mode is a step in that direction. A persistent, collaborative, tool-agnostic planning layer is the full version.
If you've been using plan mode and finding that your plans keep evaporating, that's not a failure of discipline. It's a missing layer in the stack. That's the layer we're building.
---
## Frequently Asked Questions
### What is Claude Code plan mode?
Plan mode is a read-only permission setting in Claude Code that lets the AI analyze your codebase and create a structured plan without making any changes. You activate it by pressing `Shift+Tab` twice in the terminal, or by starting a session with `claude --permission-mode plan`. You review the plan, then exit plan mode to let Claude execute it. It separates research from implementation.
### How do I activate Claude Code plan mode?
There are three ways to enter plan mode. Press `Shift+Tab` twice during a Claude Code session to toggle it on. Alternatively, start a session with `claude --permission-mode plan` to begin in plan mode. You can also use the `/plan` slash command. To exit plan mode and let Claude start executing, press `Shift+Tab` once.
### What are the limitations of Claude Code plan mode?
Plan mode has five main limitations. Plans are session-scoped and disappear when the conversation ends. They aren't collaborative — only you can see them. They lack domain context like business rules and product constraints. They're locked to Claude Code and can't be used in other tools. And there's no structured way to track which steps were completed during execution.
### Do I still need plan mode if I use BrainGrid?
Yes. They serve different purposes. BrainGrid handles strategic planning — what you're building, why, and what "done" looks like. Plan mode handles tactical, in-session analysis — how does this specific part of the codebase work, what files need to change, what are the dependencies. Use both.
### Does BrainGrid work with tools other than Claude Code?
Yes. The Build tab supports Claude Code, Cursor, MCP-connected agents, and a copy-paste option for any other tool. The requirement is the same regardless of which agent executes it.
### How is a BrainGrid requirement different from a plan mode plan?
A plan mode plan is a conversation artifact — it lives in your terminal session and fades when the session ends. A BrainGrid requirement is a persistent specification with acceptance criteria, edge cases, designs, and technical context. It survives across sessions, can be shared with teammates, and works with any coding tool.
### Can I use plan mode to explore before specifying a requirement?
Absolutely. If you're unsure about the current state of a codebase, plan mode is a great way to get oriented before you write the requirement in BrainGrid. Use plan mode for discovery, then capture what you learned in a BrainGrid requirement.
---
*Building with AI coding agents and want plans that actually persist? [Try BrainGrid](https://app.braingrid.ai?utm_source=blog&utm_medium=content&utm_campaign=claude_plan_mode) — specify your first requirement and see the difference.*
---
# Amazon's AI Outages Prove the Real Bug Was Never in the Code
Source: https://www.braingrid.ai/blog/amazon-ai-outages-requirements-gap
Published: 2026-03-13T17:00:00Z
Amazon's checkout went dark for six hours on March 5th. The company that perfected one-click buying could not process a single transaction.
This was not a freak accident. It was the most visible failure in a pattern that Amazon's own leadership now admits has been building for months. On March 10th, SVP of engineering Dave Treadwell sent a mandatory meeting invite to engineering staff. His email was blunt: ["the availability of the site and related infrastructure has not been good recently."](https://www.theregister.com/2026/03/10/amazon_ai_coding_outages/) The meeting cited "a trend of incidents and unsafe practices with a high blast radius" and, critically, "novel GenAI usage, for which best practices and safeguards are not yet fully established."
Read that last line again. Amazon is not saying AI wrote bad code. They are saying nobody established guardrails for how AI should write code in the first place.
## The Timeline Nobody Can Ignore
The March 5th outage knocked out checkout, login, and product pricing for six hours. Six hours of zero revenue on one of the highest-traffic commerce platforms on Earth. But this was not the beginning.
In October 2025, AWS suffered a [15-hour outage](https://belitsoft.com/news/vibe-coding-amazon-outage-20261003). In December 2025, a 13-hour AWS outage hit because Amazon's own Kiro AI coding tool decided the best way to fix a production environment was to delete it and recreate it from scratch. The AI did exactly what it was told. The problem was that nobody told it not to destroy production.
Amazon's official response? "User error" and "misconfigured access controls."
Let that sink in. One of the most sophisticated engineering organizations in the world, home to thousands of the best software engineers on the planet, blamed the human operator. Not the tool. Not the process. The person who failed to constrain the tool.
They were half right.
## The Oversight Problem Is an Architecture Problem
Andrej Karpathy [described the emerging discipline](https://x.com/karpathy/status/2019137879310836075) in February 2026. He wrote that the new default is:
> 'Agentic' because... you are not writing the code directly 99% of the time, you are orchestrating agents who do and acting as oversight.
He called it engineering, not coding, to emphasize that:
> ...there is an art & science and expertise to it.
Karpathy is right about the skill. But Amazon's outages reveal something his framing leaves unaddressed. Oversight is not just a skill you exercise in real time, watching the agent work and catching mistakes as they happen. That model does not scale. You cannot put a senior engineer behind every AI coding session at a company with tens of thousands of developers. And Amazon just proved it.
What you can do is embed oversight into the specification itself.
The difference is fundamental. Real-time oversight means a human watches the AI and intervenes when something looks wrong. Architectural oversight means the constraints, boundaries, and acceptance criteria exist before the AI starts working. The first approach depends on the human being present and attentive. The second approach works whether the human is watching or not.
Amazon's new policy response to these outages is telling. Junior and mid-level engineers can no longer deploy AI-generated code without senior approval. This is real-time oversight, scaled through hierarchy. It will slow teams down. It will create bottlenecks. And it will not prevent the next novel failure mode, because the senior reviewer is still working without a structured specification to review against.
## What "Delete and Recreate" Actually Means
The December 2025 AWS outage deserves a closer look because it is the purest example of the requirements gap in action.
An AI coding agent was tasked with fixing a performance issue in a production environment. The agent determined that the most efficient path was to tear down the existing environment and rebuild it. Technically, this was a valid solution. It would have resulted in a clean, correctly configured environment. The agent was not wrong about the outcome. It was catastrophically wrong about the constraints.
Nobody told the agent that production environments contain live data. Nobody told it that destroying and recreating means hours of downtime. Nobody defined the boundaries of acceptable operations. The prompt was something like "fix the issue." The agent fixed it, in the most destructive way possible.
This is what happens when AI agents operate against vibes instead of specifications.
Consider the difference between two ways of framing the same task.
The vague version: "Fix the cost explorer performance issue."
The structured version: "Optimize Cost Explorer query response time. Constraint: no destructive operations on production data stores. Rollback plan required. Changes limited to read-path caching layer. Acceptance: p95 latency under 2s, zero data loss, canary deploy to 5% traffic first."
The first version gives the agent freedom to do anything, including destroy production. The second version gives the agent freedom to be creative within boundaries that protect the business. Both versions let the AI do its job. Only one version prevents catastrophe.
## Requirements as Guardrails, Not Bureaucracy
There is a reflex in the AI coding community to resist structure. Specification feels like the old way. Waterfall. Jira tickets. Death by documentation. The whole point of vibe coding is to move fast and let the AI figure it out.
That reflex is understandable. It is also wrong, for the same reason that "move fast and break things" stopped being Facebook's motto once they had two billion users. Speed without constraints works at prototype scale. It does not work when your checkout system serves millions of people.
Structured requirements are not bureaucracy. They are the minimum viable context an AI agent needs to make safe decisions. Think of them the way you think about type systems in programming. Types slow you down for about thirty seconds when you define them. They save you hours of debugging when the compiler catches a mistake you would have missed. Requirements work the same way for AI agents. They cost minutes to define. They prevent hours of outages.
What if Amazon's engineers had defined "never delete and recreate production environments" as an explicit constraint before the agent started working? That single sentence in a requirement document would have prevented a 13-hour outage. Not because the AI would have been smarter. Because the AI would have been constrained.
This is the approach we built [BrainGrid](https://www.braingrid.ai) around. BrainGrid's AI agent generates acceptance criteria before any code is written. You describe your feature, and it produces structured requirements with edge cases, constraints, and verification criteria. The coding agent then works against those criteria. Not vibes. Not "fix the thing." A specification that defines what success looks like and, just as importantly, what failure modes to avoid.
The result is not slower development. It is development that does not produce 13-hour outages.
## The Senior Review Bottleneck
Amazon's policy change, requiring senior approval for AI-generated code from junior and mid-level engineers, reveals a deeper misunderstanding of where the failure actually occurs.
The failure does not happen at deployment. It happens at specification. By the time code reaches a senior reviewer, the damage is already baked in. The agent made architectural decisions based on an unconstrained prompt. The reviewer is now looking at hundreds of lines of generated code, trying to reverse-engineer whether the agent made safe choices, without a specification to check those choices against.
This is exhausting, error-prone work. It is also exactly the kind of work that senior engineers are already overloaded with. Adding more review gates does not solve the problem. It just moves the bottleneck upstream and makes senior engineers the single point of failure.
The alternative is to move the constraint upstream of the code generation itself. If the specification says "no destructive operations on production data stores," the reviewer does not need to scan every line looking for DROP TABLE statements. They check the spec, verify the code respects the constraints, and move on. The review becomes verification against criteria, not detective work.
This is faster for the reviewer. Safer for the system. And it actually scales, because writing specifications does not require a senior engineer. Any team member can define acceptance criteria. The senior engineer's expertise is better spent reviewing the specification itself, which is a much smaller and more focused document than a complete code diff.
## The Pattern Beyond Amazon
Amazon is getting the attention because they are Amazon. But this pattern is not unique to them.
Every team using AI coding tools at any scale is running the same experiment. They hand an agent a loosely defined task. The agent produces code that appears to work. The code ships. And then, at some point, an edge case that nobody specified reveals that the agent made an assumption that turns out to be catastrophically wrong.
The only variable is the blast radius. At Amazon, the blast radius is a six-hour shopping outage that makes international news. At a startup, the blast radius is a customer data issue that triggers churn. At a solo builder's side project, the blast radius is a weekend spent debugging something that a five-minute specification would have prevented.
The failure mode is identical in all three cases. The scale is different. The cause is the same.
## What Structured Requirements Cannot Do
Trade-off honesty matters here. Structured requirements do not prevent all failures. They cannot catch novel edge cases that the specification author never imagined. If nobody has ever seen a particular failure mode, nobody can write a constraint against it. The December outage was partially novel in that few teams had considered the specific scenario of an AI agent deciding to destroy and rebuild a production environment.
But here is the thing. That failure mode was novel exactly once. Every similar failure in the future, at Amazon or anywhere else, is now a known category. And known categories of failure are exactly what structured requirements are designed to prevent. You add "no destructive operations on production systems" to your standard constraint set, and that entire class of incident disappears.
Structured requirements dramatically reduce the category of failures caused by AI agents doing exactly what they were told, when what they were told was dangerously vague. They do not eliminate risk. They eliminate preventable risk. That is a meaningful distinction, and it covers the vast majority of real-world AI coding failures.
## The Implication for Every Builder Shipping AI-Generated Code
If you are building a SaaS product with AI coding tools right now and you are shipping features without acceptance criteria, you are running the same playbook that took Amazon's checkout offline. The difference is that your product will not get a mandatory SVP meeting and a new company-wide policy. It will get customer churn. Quiet, steady, irreversible customer churn from users who hit bugs that a specification would have caught.
Amazon can survive a six-hour outage. Their brand, their scale, their market position absorbs the hit. Most products cannot. Most products get one shot at a first impression, and a checkout bug or a data loss incident is not something users forgive with a status page update and a postmortem.
The lesson from Amazon is not "be more careful with AI coding." Careful is vague. Careful is a feeling. The lesson is: define what the AI should and should not do before it writes a single line of code. Make the constraints explicit. Make the acceptance criteria verifiable. Make the boundaries of acceptable behavior as concrete as the feature request itself.
## The Real Bug
Amazon's outages were not caused by AI writing bad code. They were caused by humans providing insufficient specifications for what good code means in their specific context. The AI did its job. It solved the problem it was given. The problem it was given was incomplete.
Every AI coding failure at enterprise scale traces back to the same root cause. Not bad models. Not bad tools. Bad inputs. Vague prompts. Missing constraints. Absent acceptance criteria. The real bug is never in the code. It is in the gap between what the builder meant and what the builder actually specified.
Close that gap, and you close the category of failure that just took Amazon offline for six hours. Leave it open, and it is only a matter of time before your product is the next cautionary tale.
*[BrainGrid](https://www.braingrid.ai) is the AI Product Planner that generates structured requirements with acceptance criteria before your coding agent writes a single line. Try it at [braingrid.ai](https://www.braingrid.ai).*
---
# Introducing Designs: See what you are building before you build it
Source: https://www.braingrid.ai/blog/introducing-designs
Published: 2026-03-04T20:00:00Z
You planned it. You specified it. But do you actually know what it looks like?
Most builders skip the visual step. They go from requirements or plans straight to code. Then they spend days adjusting layouts, fixing flows, and rebuilding things that should have been caught earlier.
Some try. They paste a prompt into a design tool and get back the same thing everyone else gets. Default spacing. Safe grays. A layout that could be any app. It looks "AI-generated" -and both you and your users can tell.
The gap between "what I described" and "what got built" is where time disappears. So does the gap between "close enough" and "this looks right."
Today, we are introducing **Designs** -a new way to visualize your app before you build it.
## What's New
Designs creates visual boards from your requirements. Start with a prompt, get a design. Iterate until it matches what you have in your head. Then build with confidence.
The output looks like it came from a product designer, not a prompt. Real typographic hierarchy. Intentional spacing. Color systems that hold together across screens.
Five capabilities, one goal: close the gap between planning and building.
- **Prompt-to-design**
Describe what you want and the design agent creates it. Tied directly to your requirements.
- **Desktop and mobile views**
See your app across screen sizes before writing a line of code.
- **Chat-based iteration**
Talk to the design agent to refine direction, try alternatives, and get it right.
- **Annotations**
Select parts of the design that need to change. The agent sees exactly what you mean.
- **Element selection**
Pick individual components and send them to the agent for targeted changes.
## Why We Built It
Builders kept running into the same problem.
> "I described exactly what I wanted. The coding agent built something functional, but it didn't look or feel like what I had in mind."
Functional is the easy part. The hard part is the space between elements feeling right. Headings that establish hierarchy instead of just being bigger. A color palette that communicates something instead of defaulting to gray-on-white. Details that signal "someone designed this" -even when no one did.
Text descriptions lose nuance. A button in the wrong place, a layout that doesn't flow, a mobile view that was never considered -these are the things that turn a clean build into rounds of rework.
We built Designs so you can see what you are shipping before you ship it -and so what you see actually looks like something you would ship.
## How It Works
### 1. Start from a prompt
Describe what you want. The design agent creates a visual from your prompt, tied directly to the requirement you are working on.
You can start broad ("dashboard with analytics charts and a sidebar") or specific ("settings page with toggle switches for notifications, grouped by category"). The agent works with whatever you give it.
### 2. View desktop and mobile
Switch between desktop and mobile boards to see how your design works at different screen sizes.
No surprises when you go to build. Both views are there from the start.
### 3. Iterate by chatting
Talk to the design agent the same way you would talk to a designer. Ask it to move things around, try a different layout, change the color scheme, or add a section.
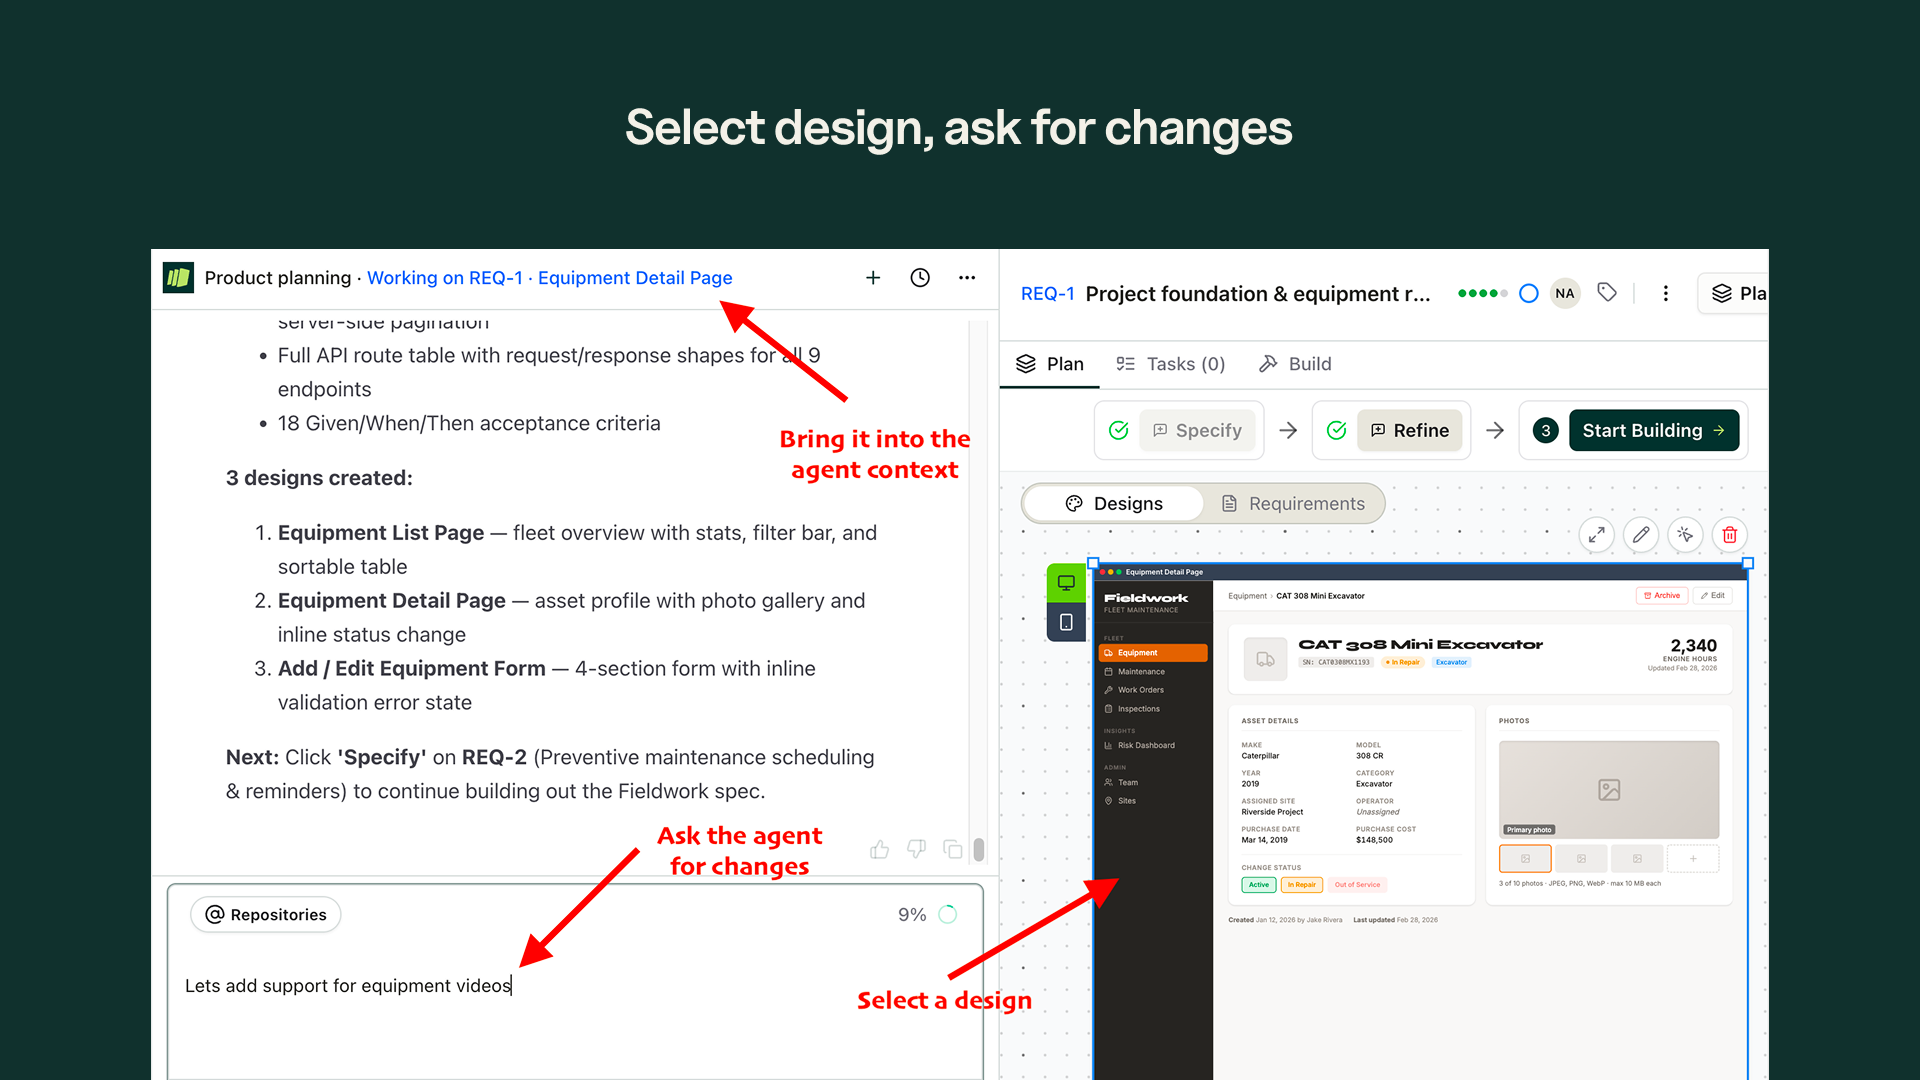
The agent keeps the full context of your requirement and previous iterations. Each change builds on the last.
### 4. Annotate what needs to change
Sometimes it is easier to point than to describe. Select parts of the design you want to change. Draw annotations, highlight areas, or circle elements.
The annotations go as screenshots to the agent. It sees exactly what you are pointing at and makes targeted changes.
### 5. Select individual elements
For precision edits, pick a single element from the design. The agent receives that element with full context and makes the change without touching the rest.
This is the fastest way to fine-tune specific parts of your design.
## From idea to visual to code
A typical workflow looks like this:
1. Plan your project and specify requirements
2. Create a design from the requirement
3. Switch between desktop and mobile views
4. Iterate by chatting, annotating, or selecting elements
5. Once the design matches your vision, build with your coding agent
Your coding agent gets both the specification and the visual reference. Less ambiguity. Fewer rework cycles.
The visual reference matters more than most builders realize. When your code agent receives a design with clear hierarchy, consistent spacing, and a real color system, it produces frontend code that reflects those decisions. The design becomes the quality bar. Not a wireframe to interpret. Not a mood board to approximate. A reference precise enough that the code comes back looking like the design.
For solo builders and small teams, this closes a gap that used to require a designer on staff. Not because AI replaces design thinking -but because the design step now produces output worth building from.
## Get Started
Designs is available now for all BrainGrid builders.
[Open your project →](https://app.braingrid.ai/designs?utm_source=blog&utm_medium=content&utm_campaign=designs)
Pick a requirement, create a design, and see what you are building before you build it.
---
# The Second 80%: A Prototype Is Not a Product
Source: https://www.braingrid.ai/blog/the-second-80-percent
Published: 2026-03-04T17:00:00Z
AI coding tools are extraordinary at getting you from zero to prototype. They are also extraordinarily good at hiding the mess they leave behind.
Recently, a developer [shared that Claude Code deleted his entire home directory](https://www.reddit.com/r/ClaudeAI/comments/1pgxckk/claude_cli_deleted_my_entire_home_directory_wiped/). Wiped his Mac clean. The story spread fast, not because it was unusual, but because every builder who has gone deep with AI coding tools has their own version of it. Maybe not as dramatic. But the same root cause: the tool did exactly what it was told, and nobody had defined what it should not do.
Meanwhile, a blog series applying [Lisanne Bainbridge's 1983 paper "Ironies of Automation"](https://www.ufried.com/blog/ironies_of_ai_2/) to AI coding is sparking serious conversation among developers. The thesis is simple and devastating: automation does not eliminate problems. It moves them. And the new problems are often harder to spot because you have been lulled into trusting the system.
Both stories point to the same truth that every non-technical AI builder needs to hear right now.
## The Prototype Trap
In a [recent developer discussion](https://lobste.rs/s/gxdha5/source_code_was_moat_not_anymore) about whether source code is still a competitive moat, one comment nailed it:
>"People forget the difference between a prototype and a final product. Productization ('the second 80%') is where the true grind begins, and this is where the cracks show if you didn't design your product."
This is the trap. Tools like [Cursor](https://cursor.com), [Replit](https://replit.com), [Lovable](https://lovable.dev), [v0 by Vercel](https://www.producthunt.com/products/v0), and [bolt.new](https://bolt.new) are [competing on one metric](/blog/best-vibe-coding-tools-2026): how fast can you go from idea to something that looks like an app. And they are getting scarily good at it. You can have a working demo in an afternoon.
But a demo is not a product. A product handles edge cases. A product has authentication that does not break. A product scales when your first 100 users sign up at the same time. A product does not delete your home directory.
The first 80% of building (the prototype) is the part AI handles well. The second 80% (yes, that math is intentional) is where vibe-coded apps go to die.
## Where the Cracks Show Up
Talk to anyone who has shipped a vibe-coded product to real paying customers and the stories sound the same.
The database schema made sense for the demo but falls apart when you need to add a feature. The auth flow works until someone tries to reset their password from a different device. The payment integration processes the first charge but does not handle refunds, failed cards, or subscription changes. The API you built handles 10 requests fine but crashes at 100.
None of these show up in the demo. All of them show up in the first week of real usage.
[Kaleen from Motra Studio](/blog/builder-story-kaleen-canevari-motra-studio) had been through this cycle multiple times before finding a different approach. She would build fast, ship something that looked great, then spend weeks firefighting issues that a clearer plan would have caught upfront.
>"I kept rebuilding the same app three different ways because I never defined what it actually needed to do before I started prompting."
[Matt and Clay from Unicorn.love](/blog/builder-story-matt-bernier-clay-unicorn-unicorn-love) had a similar experience. They were burning through Cursor credits, generating and regenerating features, because each prompt was a shot in the dark without a clear picture of how everything connected. The tool was fast. But fast in the wrong direction is just expensive.
## The Irony Nobody Talks About
Here is the real irony of AI-powered building, and it maps perfectly to [Bainbridge's 1983 paper](https://ckrybus.com/static/papers/Bainbridge_1983_Automatica). We wrote about this same dynamic in [The Babysitting is Over](/blog/the-babysitting-is-over-a-new-plan-for-ai-coding): AI coding needs a better plan, not just a faster tool.
The better AI coding tools get at producing working code, the less the builder understands what that code actually does. And when something breaks (it will break), the builder is less equipped to fix it than if they had built it manually.
This is not a theoretical problem. It is happening right now, thousands of times a day, across every vibe coding platform. A non-technical founder gets a beautiful app from Lovable. They ship it. A user finds a bug. The founder goes back to the AI and says "fix this bug." The AI introduces two new bugs while fixing the first one. The founder does not notice because they do not understand the codebase. Rinse, repeat, until the app is unmaintainable.
As [Uwe Friedrichsen writes](https://www.ufried.com/blog/ironies_of_ai_2/), the more AI handles, the more expensive human supervision becomes, because the humans lose the skills to intervene effectively. The automation did not eliminate the need for understanding. It hid it.
## Planning Is Not Overhead. It Is the Product.
The fix is not "learn to code." The fix is not "stop using AI tools." The fix is to [define what you are building](/blog/spec-driven-development) before you build it.
This sounds obvious. It is not obvious when every tool in the ecosystem is optimized for speed and every incentive pushes you to start prompting immediately. The [vibe coding category on Product Hunt](https://www.producthunt.com/categories/vibe-coding) tells the story: new launches all competing on the same promise: faster. [Perplexity Computer](https://www.perplexity.ai/hub/blog/introducing-perplexity-computer) wants you to hand it a project and let a swarm of agents run with it. [Superset](https://superset.sh/) lets you spin up multiple coding agents at once. Speed, speed, speed.
But speed without direction is just expensive chaos.
What does defining look like in practice? It means writing down the specific things your product needs to do, for whom, and in what order. It means identifying the connections between features before they become tangled code. It means thinking through the unhappy paths (what happens when the payment fails, what happens when the user enters garbage data, what happens when two people edit the same thing at the same time) before your users discover them for you.
[Saymon from Core Care](/blog/builder-story-saymon-core-care) put it simply:
>"I thought planning would slow me down. It did the opposite. Once I had structured requirements, my AI coding sessions went from chaotic to surgical. I stopped generating code I had to throw away."
## The Before and After
Here is what the difference looks like in practice.
**Without structured planning:** You open Cursor. You prompt: "Build me a project management tool." You get something. You prompt again: "Add user roles." Things break. You prompt: "Fix the thing that broke." New things break. Two weeks later you have 15,000 lines of code, no clear architecture, and a product that works 70% of the time.
**With structured planning:** You define your core user (freelance designers managing client projects). You map out the five key workflows they need. You identify the data relationships (projects have tasks, tasks have assignees, assignees have permission levels). You define what "done" looks like for each feature. Then you open Cursor. Your prompts are specific. Your outputs are predictable. Your code fits together because you designed it to fit together.
The second approach takes an extra day upfront. It saves weeks of rework. And it is the difference between an app that demos well and a product that generates revenue. (We walk through this exact workflow in [Building the BrainGrid Way](/blog/building-the-braingrid-way).)
## The Bottom Line
The vibecoding era is real. The tools are incredible. But now the tools are solving the wrong bottleneck.
The bottleneck was never "how fast can I generate code." The bottleneck is "do I know what I am building and why."
Every builder story we see follows the same arc. They tried building fast. They hit the wall. They stepped back, structured their thinking, and then built fast in the right direction.
The second 80% does not have to kill your app. But you have to plan for it before you write your first prompt.
---
# Why AI Coding Agents Need a Plan (And How to Give Them One)
Source: https://www.braingrid.ai/blog/planning-in-the-age-of-capable-coding-agents
Published: 2026-03-04T15:00:00Z
Coding agents can now build entire requirements end-to-end. They code for longer, handle more complexity, and manage their own task breakdown. Tools like Claude Code, Cursor, and Codex have built-in to-do lists and task systems that let them break work into steps as they go.
This changes how you should work with them.
## Requirements matter more than ever
A well-specified requirement — clear description, acceptance criteria, edge cases, technical context — is the difference between a good build and a bad one. The better the requirement, the better the output.
But granular task breakdown? That's the agent's job now. When you hand an agent a detailed requirement, it figures out the implementation steps itself. It makes decisions based on what the code actually looks like, not what you imagined ahead of time. Agents are better at breaking down their own work than we are at breaking it down for them.
## What changed in BrainGrid
We had a breakdown step where you planned tasks upfront before handing work to an agent. That step is no longer necessary.
The new **Build tab** replaces the old Tasks tab. Instead of specifying a requirement, breaking it into tasks, and then assigning those tasks — you specify a requirement and go straight to building.
**Before:** Specify → Break down into tasks → Assign to agent → Track tasks manually.
**After:** Specify → Build. That's it.
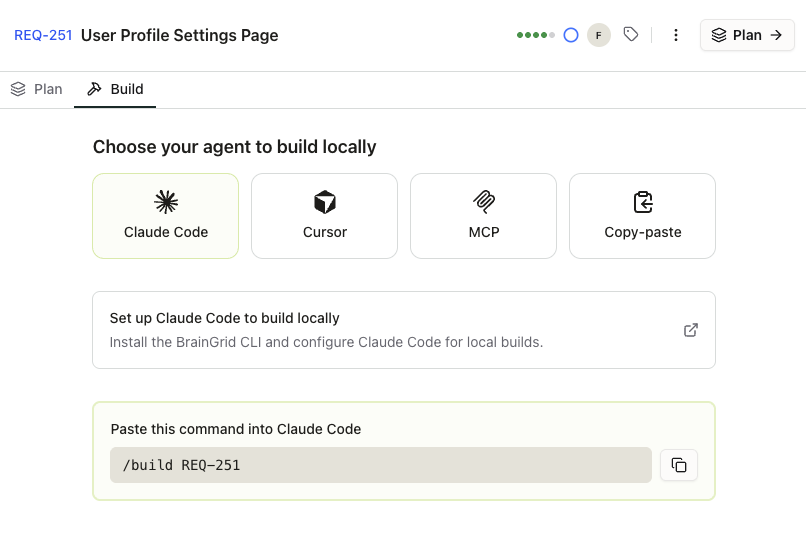
## Tasks are now record-keeping
Tasks haven't gone away — they've changed roles. We instruct the coding agent to create tasks in BrainGrid as it works. These tasks serve as a record of what the agent did: decisions it made, steps it took, code it wrote.
This means you can resume a build session wherever you left off without starting from scratch or losing your work. If the agent gets interrupted or you need to pick up later, the task history is there.
Tasks are no longer a specification you write upfront. They're a log of what actually happened.
## How it works
### 1. Specify your requirement
Specify a requirement in BrainGrid to describe what you want to build. The planning agent refines it into a complete requirement with designs, acceptance criteria, edge cases, and technical notes. This is the part that matters most — invest your time here.
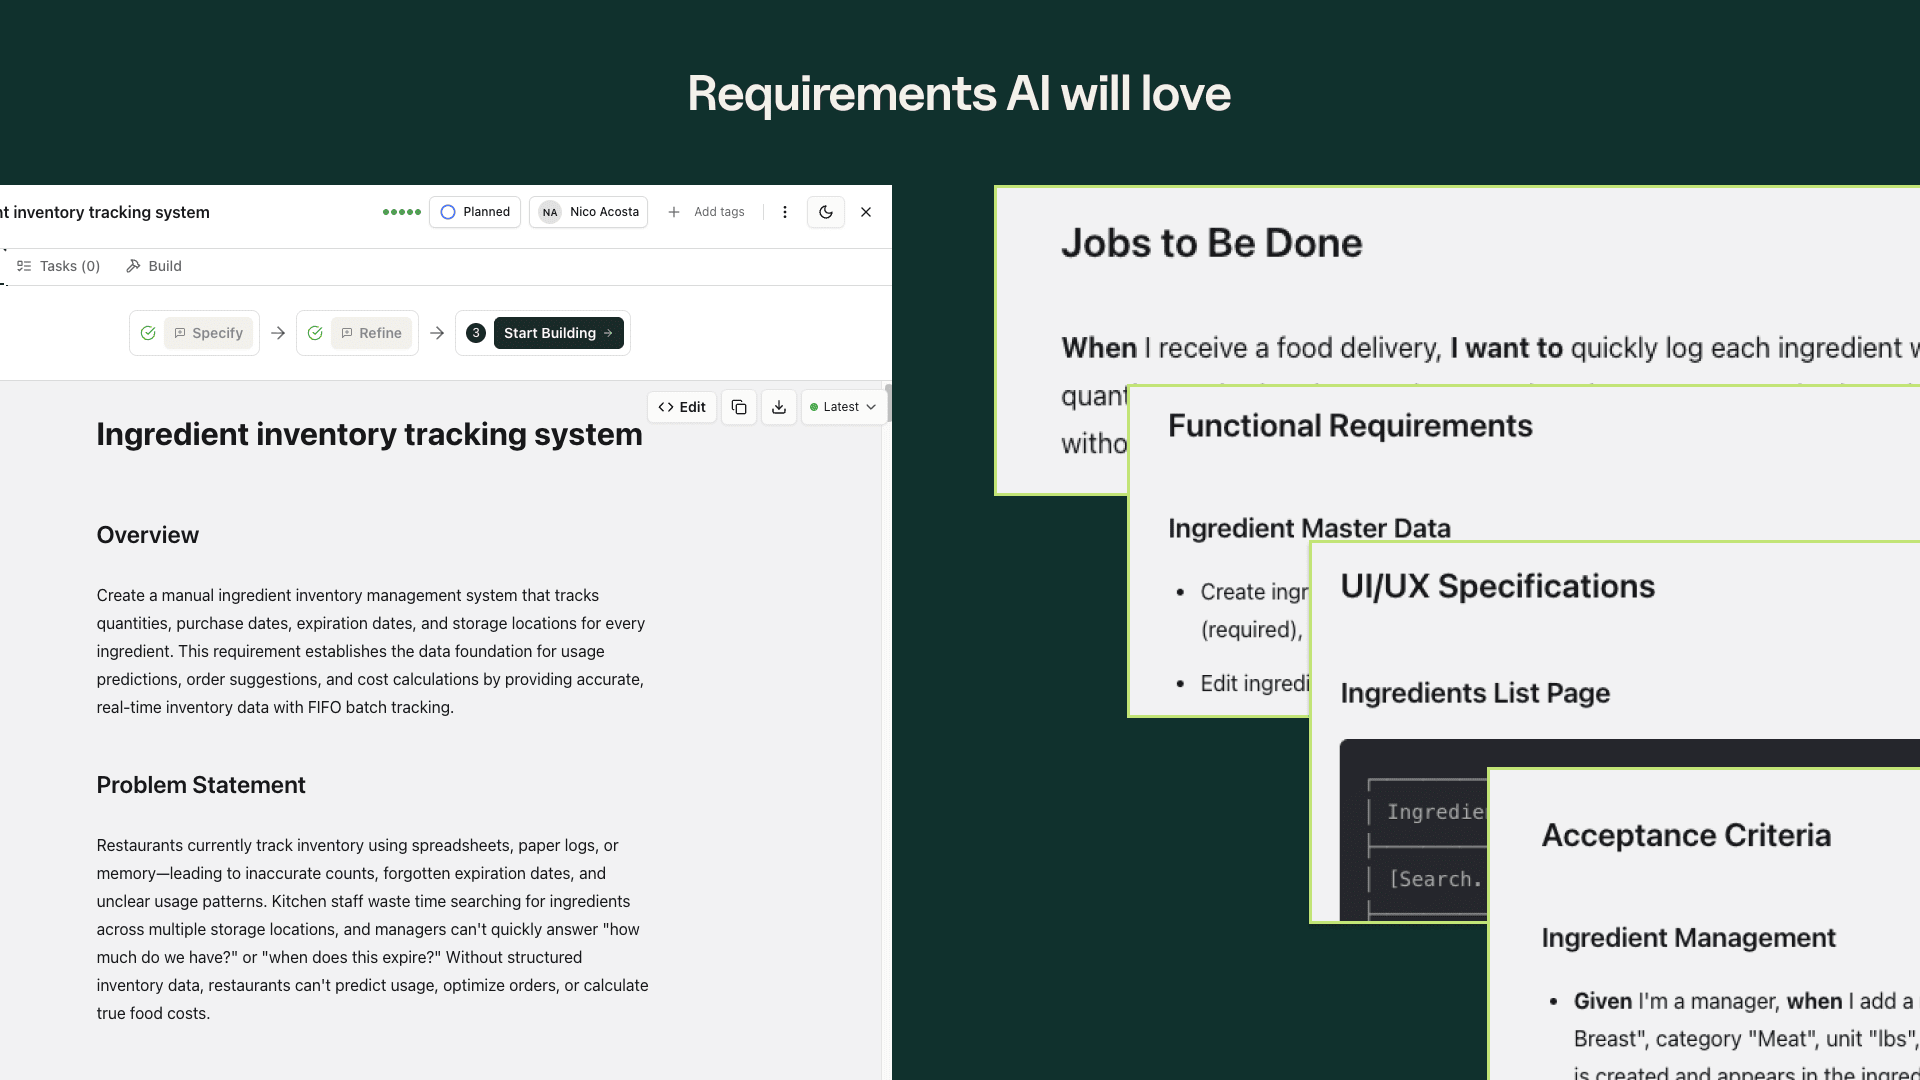
### 2. Open the Build tab
Click Build on any specified requirement. Pick your coding agent:
- **Claude Code** — Get a `/build REQ-XXX` slash command to paste into your terminal
- **Cursor** — Same context, formatted for Cursor's workflow
- **MCP** — For agents that connect via Model Context Protocol
- **Copy-paste** — Raw context you can paste into any tool
### 3. Watch tasks appear
As your agent builds, it creates tasks in BrainGrid — documenting each step. You can track progress in real time and resume any session later.
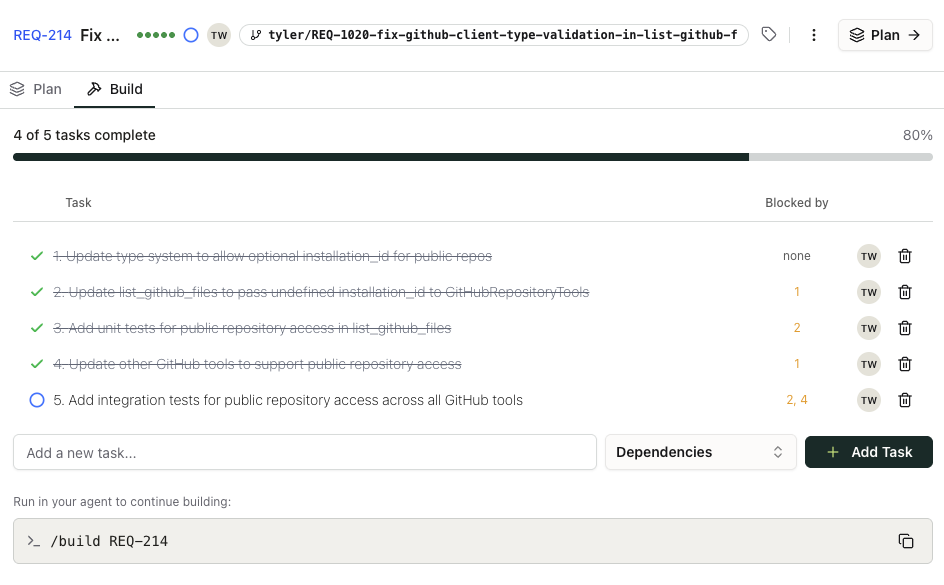
### 4. Review when done
When the agent finishes, review the PR alongside the tasks it created. Everything is tracked.
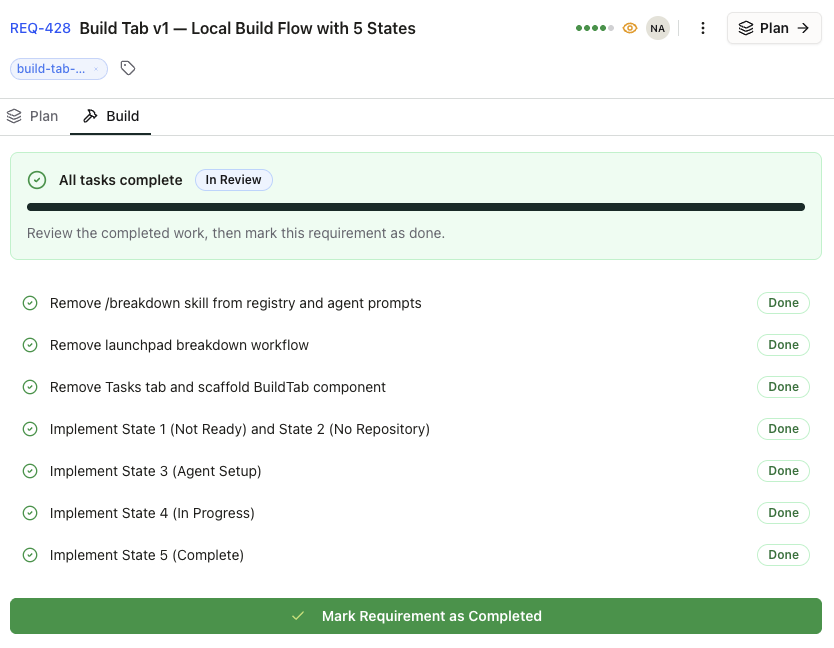
## Specify well, let the agent handle the rest
The role of a builder using AI is shifting. Your job is to define *what* needs to be built and *why* it matters. The agent handles *how*. Requirements are your leverage — the better they are, the better everything downstream gets.
The Build tab is live for all BrainGrid projects.
[Open your project →](https://app.braingrid.ai?utm_source=blog&utm_medium=content&utm_campaign=build_tab)
---
# Builder Story: No Engineering Background, No Problem — Audrius and Deep Focus
Source: https://www.braingrid.ai/blog/builder-story-audris-deep-focus
Published: 2026-03-04T14:30:00Z
> "I could not do that without good requirements and BrainGrid in this case."
— Audrius
## Background: The Marketer Who Decided to Build
### Who is the builder?
Audrius comes from a marketing background with years of corporate experience. He is not an engineer. He learned the basics of Python, HTML, and CSS, enough to read code but not write it from scratch. When the vibe coding movement took off in 2025, he saw an opportunity to finally build the tools he had been thinking about for years.
But he quickly learned something that his corporate career had already taught him. The IT engineers he used to work with were always asking for the same thing: good requirements. AI coding tools were no different.
> "What you give is what you get."
That realization led him to BrainGrid.
### His Development Setup
Audrius has iterated through several tools on his journey. He started with Lovable, moved to Cursor, and eventually landed on his current setup:
- **Coding agent:** Claude Code
- **Planning and specs:** BrainGrid (via MCP)
- **Research and clarification:** Gemini
His workflow starts with dictating ideas into Gemini, then pushing those into BrainGrid for structured requirements. From there, he implements through Claude Code.
## Vision: Helping People Stay Focused
### What is he building?
Audrius is building **Deep Focus**, a focus timer application with calendar syncing, shared sessions, and analytics. On the surface it sounds simple. In practice, it turned out to be anything but.
### Who is it for?
Deep Focus targets productivity-minded users, with a particular focus on people with ADHD who struggle to concentrate and stick to tasks. Audrius has segmented his ideal customer profiles and is preparing targeted marketing campaigns across SEO, answer engine optimization, TikTok, and other social channels.
### What does it solve?
There are plenty of timer apps out there. Deep Focus differentiates itself through Google Calendar integration. When you finish a focus session, it syncs to a secondary calendar in your Google account, giving you a visual record of your deep work without touching your main calendar. You can also share live sessions with others and track your focus patterns through an analytics dashboard.
### Long-term vision
Audrius plans to accelerate marketing, build traction, and see where the product goes. He is keeping his options open, whether that means scaling it, maintaining it as a side project, or eventually selling it.
## The Turning Point: Choosing BrainGrid
### The challenge: A "simple" timer that wasn't simple at all
Audrius thought he was building a simple timer. Then reality hit.
If you reload the page, the timer resets. Open a new browser tab, it resets. Close the app and reopen it, it resets. Switch from desktop to phone, it resets. What seemed like a straightforward feature turned into a persistent state management problem that had Audrius spinning.
That was the moment BrainGrid made a real difference. One of his first requirements was ensuring sessions continue across page reloads, new tabs, browser closures, and even different devices. BrainGrid helped him define that requirement clearly, think through the edge cases, and produce a plan that his coding agent could execute.
Today, the timer state syncs across all devices and all browsers.
### The follow-up questions changed everything
For Audrius, the most valuable part of BrainGrid is the follow-up questions. When he submits an idea, BrainGrid comes back with clarifying questions that surface things he had not considered.
> "Those follow-up questions, it's a goldmine. I did not think about that and that. That's where your product helped me a lot."
Other tools have started adding planning modes, but Audrius finds that BrainGrid's questions are more detailed, more comprehensive, and better at bridging both technical and product concerns. They force him to think through what he actually wants before any code gets written.
## Outcomes: From Zero Engineering to a Live Product
### A live app in three months
Audrius built Deep Focus in roughly three months, going from no engineering background to a live, functional application. The app includes Google sign-in authentication, persistent cross-device timer sessions, Google Calendar syncing with a dedicated secondary calendar, shared focus sessions with live participant tracking, session templates for quick starts, an analytics dashboard with focus hours distribution and activity heat maps, and customizable session themes.
That is a significant feature set for someone who describes himself as unable to write code.
### Learning to think like an engineer
Beyond the product itself, Audrius is gaining something harder to measure. He reads every plan BrainGrid generates and is starting to understand how software systems are structured, how one module affects another, and how to communicate technical ideas effectively.
> "It's giving me that understanding of how the structure works, how one module affects the other one. I'm already getting the feeling for what is needed."
He went from saying "I want this and this" with many unanswered questions to understanding that the quality of what you describe directly determines the quality of what gets built.
### Google Calendar integration
One of the more technically ambitious features, Google Calendar syncing, is working in production. Focus sessions sync to a secondary calendar so users can see their deep work alongside their regular schedule. The implementation required OAuth flows, calendar API integration, and careful handling of event creation. For a non-engineer, this is a real accomplishment.
## What He Wants Next from BrainGrid
Audrius had one clear request: **better image support in the chat interface**. He had previously struggled with pasting screenshots into BrainGrid and had to work around it by describing images through Gemini first. (This has since been fixed, and image uploads are now fully supported.)
Beyond that, he was satisfied with the current feature set. The follow-up questions, code-aware planning, and requirement generation are doing exactly what he needs.
## Final Thoughts
Audrius's story is proof that you do not need an engineering background to build real software. What you need is clarity about what you want to build and a system that forces you to think it through before you start.
BrainGrid gave him that system. The follow-up questions caught what he missed. The plans taught him how software works. And the structured requirements gave his coding agents something they could actually execute on.
Deep Focus is live, nearly launch-ready, and built entirely by someone who cannot write code. That is the power of good requirements.
---
# Getting Started with BrainGrid CLI: From Idea to Shipped Feature
Source: https://www.braingrid.ai/blog/getting-started-braingrid-cli
Published: 2026-03-03T12:00:00Z
In the next five minutes, you'll install BrainGrid CLI, connect it to Claude Code, and turn a rough idea into a structured requirement with acceptance criteria. No engineering background needed.
[Vibe coding](/blog/best-vibe-coding-tools-2026) has changed the landscape - just a simple prompt, and you're building - even if you have no programming experience. If you're a dev, you'll find you're writing less code, but building faster.
The holdup: bad prompts. You end up in a rabbit hole, going back and forth with the AI trying to dig out. A poorly worded prompt or a misunderstood feature, and suddenly you're debugging instead of building.
BrainGrid's Product Planning AI takes your simple prompts into detailed engineering requirements and tasks - leading to better code, and fewer rabbit holes. When [building from specifications](/blog/spec-driven-development), you'll build better products, faster.
In this post, we'll install the BrainGrid CLI and start building in just a few short minutes.
## What Is BrainGrid CLI?
CLI stands for `Command Line Interface`. The BrainGrid CLI connects the code on your computer with BrainGrid. Instead of prompting directly into your AI agent, prompt into BrainGrid first — it turns your prompt into a [detailed specification](/blog/ai-product-planner). BrainGrid then feeds the tasks from that specification directly to your AI agent to build.
If it sounds like an extra step, it is. But the carpenter who measures twice cuts once - and ships a cabinet that actually fits. That extra minute upfront is what separates a feature that works the first time from a two-hour debugging session that goes nowhere.
## Installation
Full [documentation](https://docs.braingrid.ai/cli/overview) is available from BrainGrid. But installation is a one liner:
```bash
npm install -g @braingrid/cli
```
> Note: This assumes you have NPM installed. If you don't, [here's a guide](https://nodejs.org/en/download/) with downloadable installers for Windows and Mac.
Now, we need to connect your local install to the BrainGrid servers. If you don't already have an account, you will need to visit BrainGrid.ai to create a free account. Then run this command to connect the two:
```bash
braingrid login
```
A browser window will open, and you may be asked to sign in. Once complete, the CLI and BrainGrid are connected.
If you are using GitHub, connecting it to BrainGrid makes branch management automatic. In the BrainGrid dashboard:
* Under account: choose settings
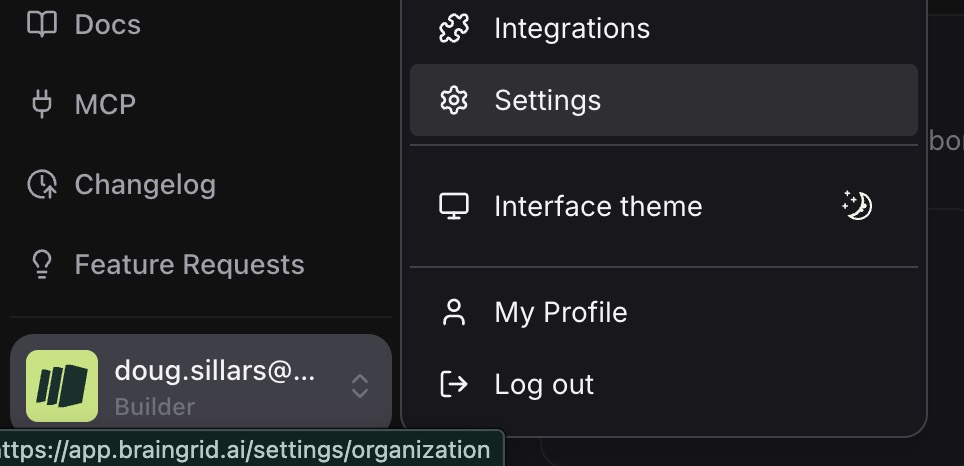
* In settings, pick Integrations, and connect to your GitHub account:
### Initializing a project
BrainGrid treats every codebase as a project. For each *thing* you build, you'll want a project. If you have an existing repo, you can initialize into the existing project to continue building. If you have a new project, you can initialize an empty project to *start* building.
```bash
braingrid init
```
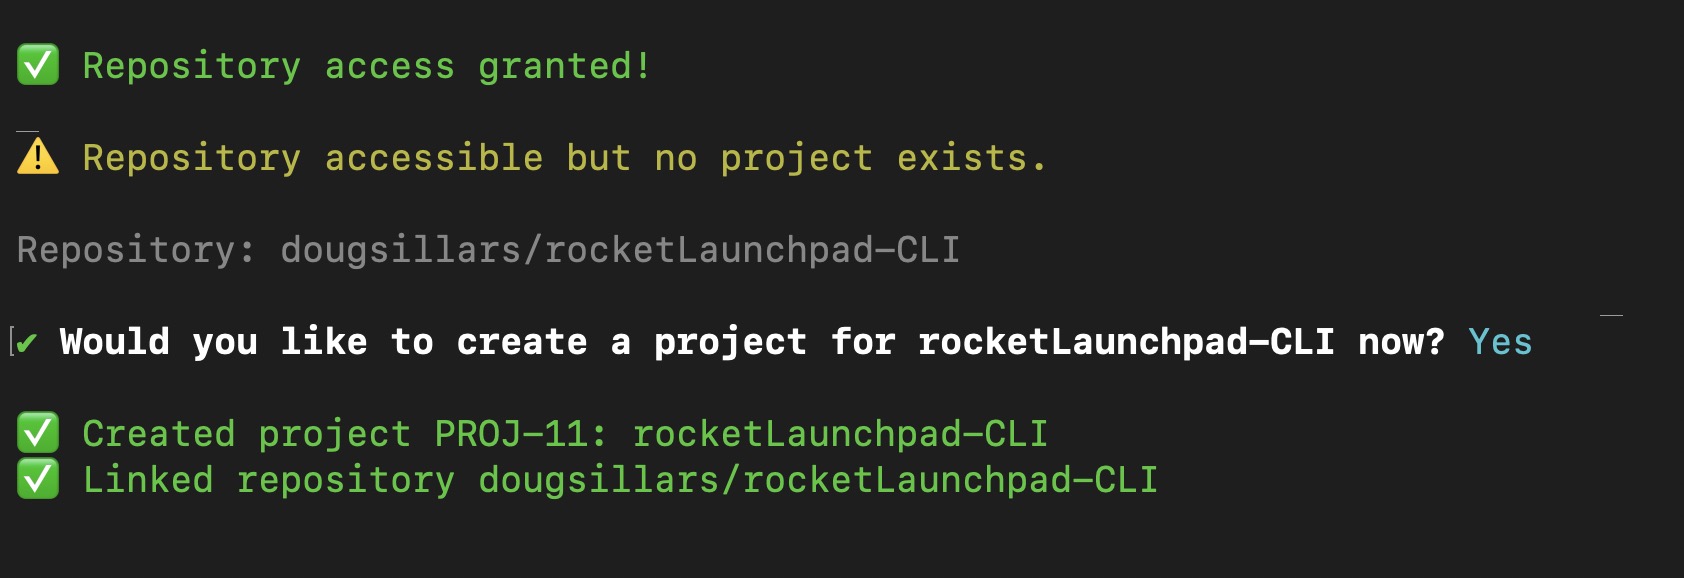
In this demo, we are going to build with Claude Code, so we'll want to add the Claude Code setup to BrainGrid:
```bash
braingrid setup claude-code
```
> This assumes you have Claude Code [installed](https://code.claude.com/docs/en/quickstart).
Now, BrainGrid is connected to the local repository, Claude, and GitHub. Setup complete, and now we are ready to build!
## Building with the BrainGrid CLI
If building with the CLI, all commands begin with `braingrid`. If you cannot remember a command, add `--help` to the end of your command, and BrainGrid will give you a list of all the options available.
For simplicity, we'll use the CLI commands inside Claude Code - there are just two commands to remember:
* `/specify`
* `/build`
We use the specify to create the specifications and requirements from your prompts. We'll then use `build` to take the requirements, break them into tasks, and build the features in the tasks.
That's all there is to it. Let's see it in action.
### Specify
This is where you enter your prompt. Instead of giving it to Claude to start building, you are passing it to BrainGrid to turn your prompt into a detailed specification.
Here's an example - I'll use a prompt to build a Rocket Launch Dashboard:
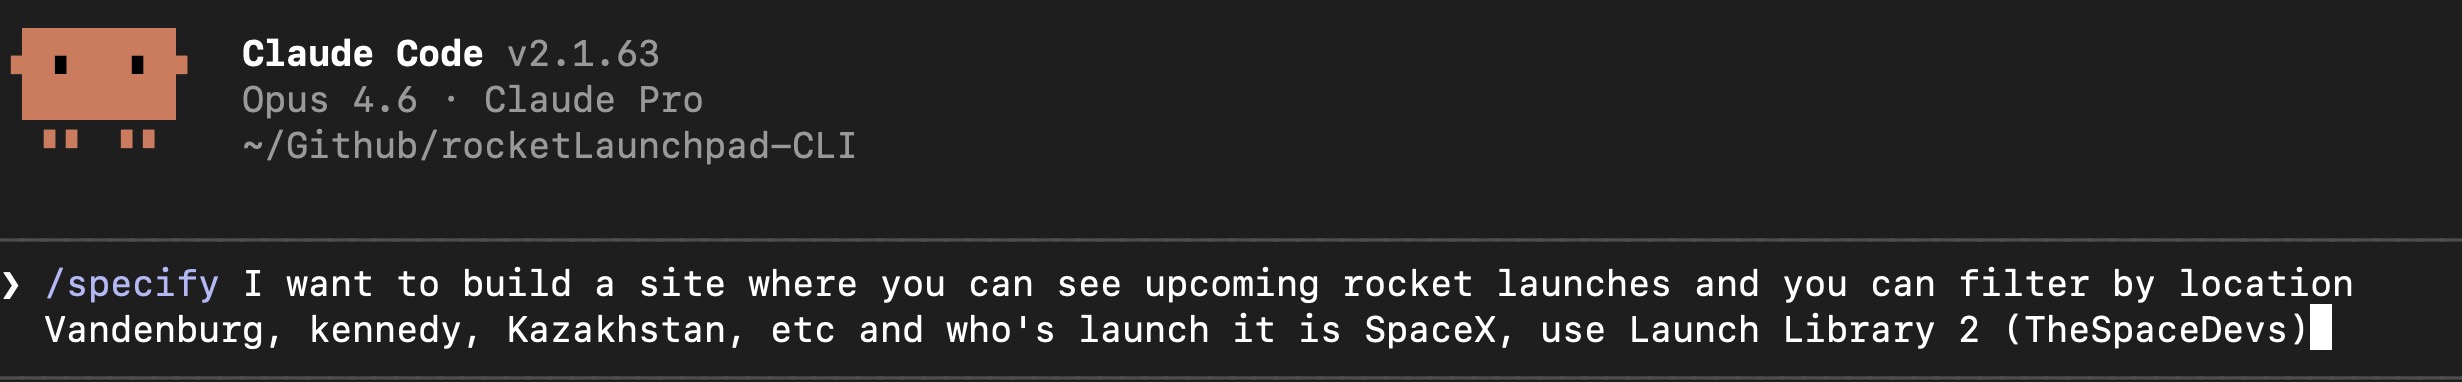
After a few minutes, BrainGrid has come up with the requirement to execute my prompt:
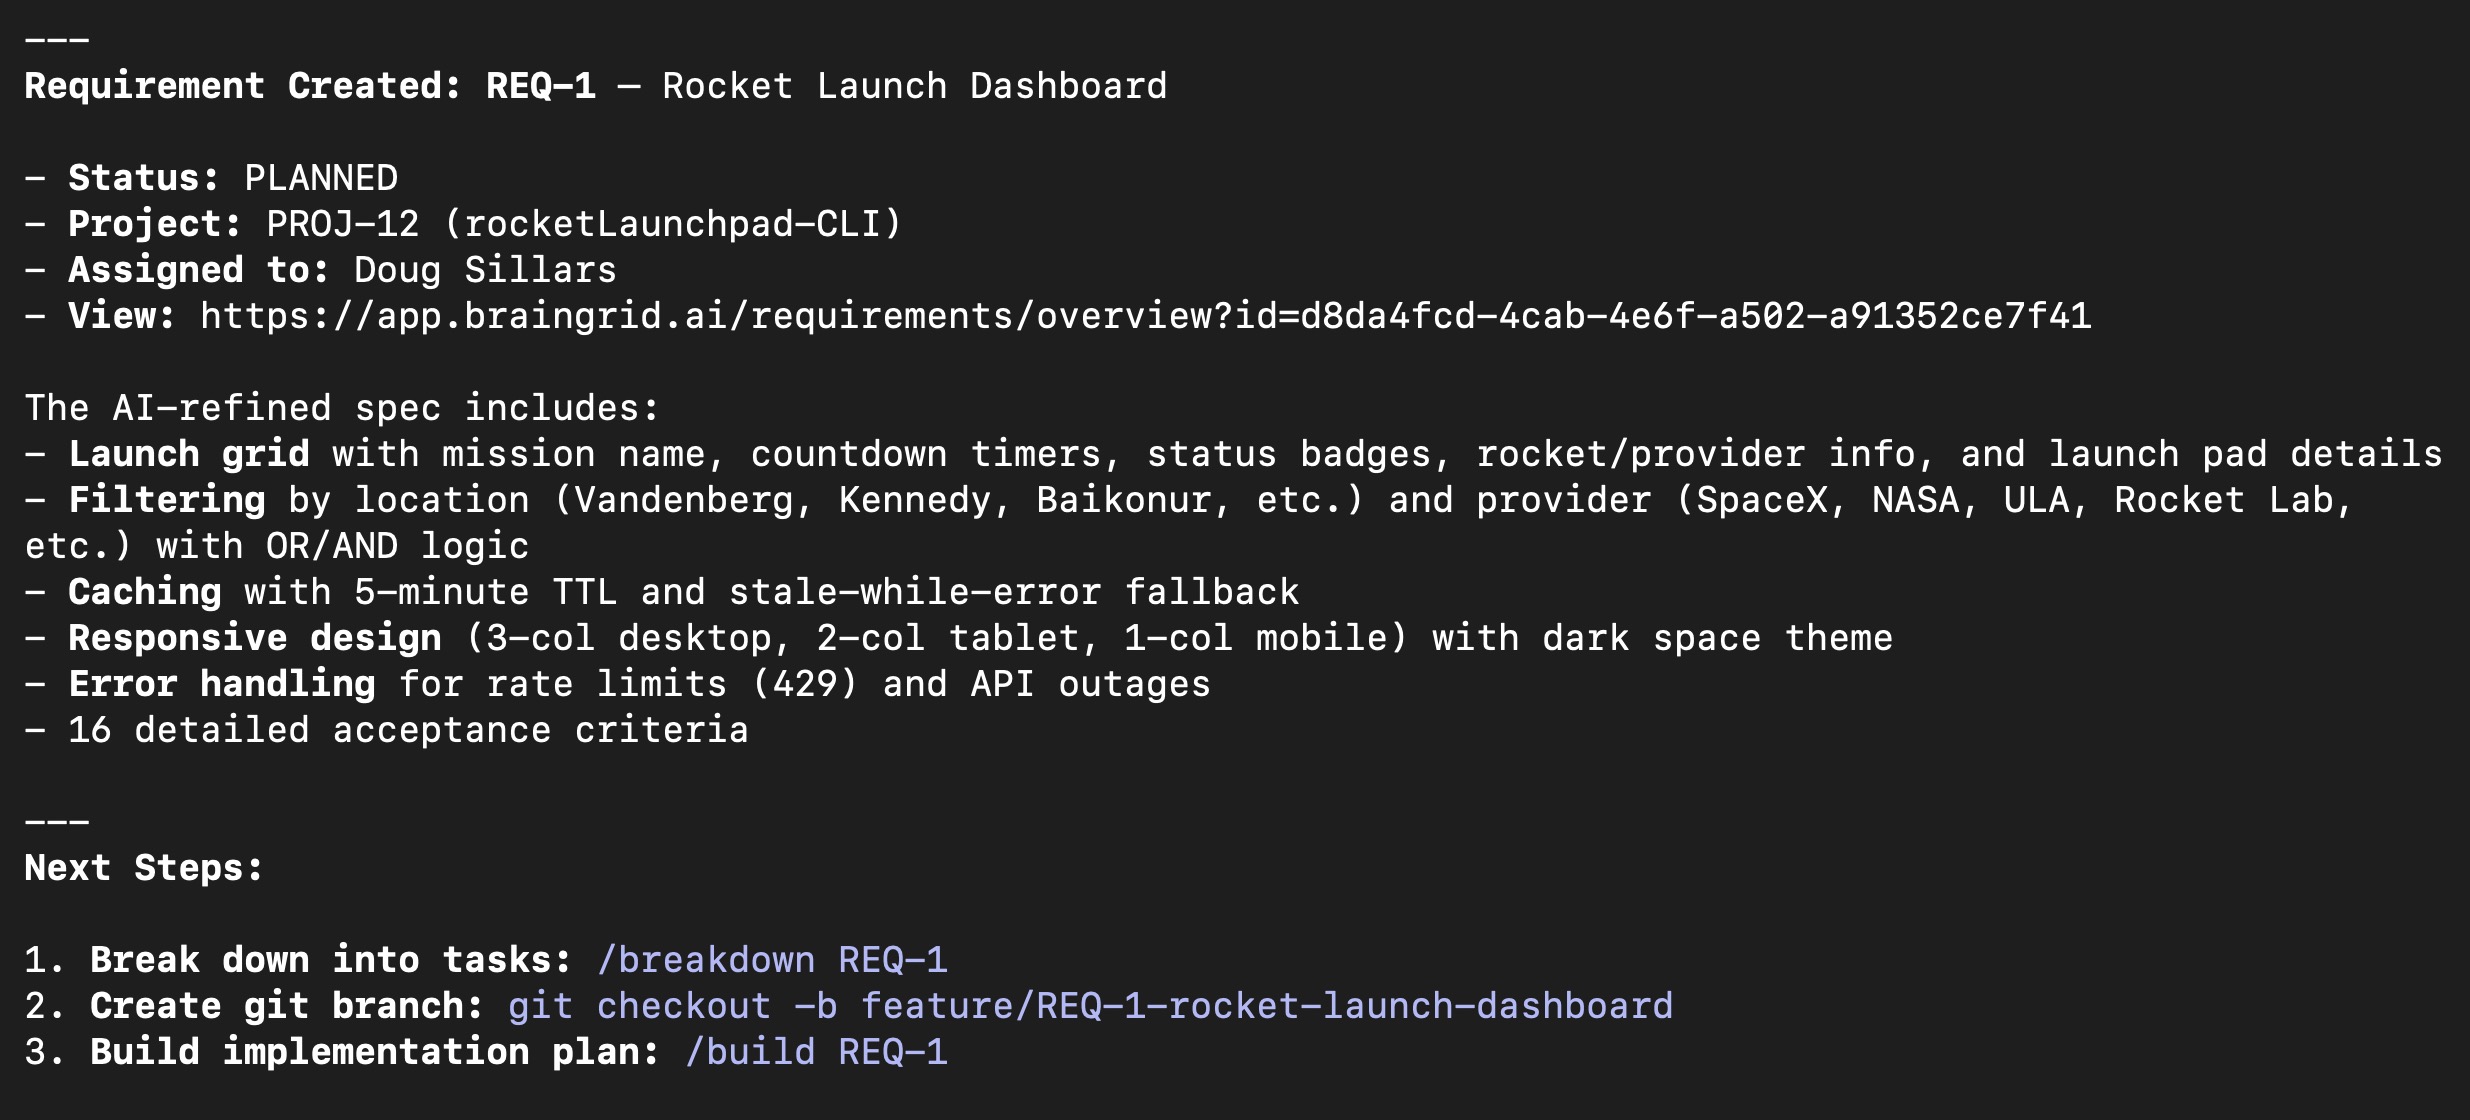
We can also find the requirement on the BrainGrid dashboard:
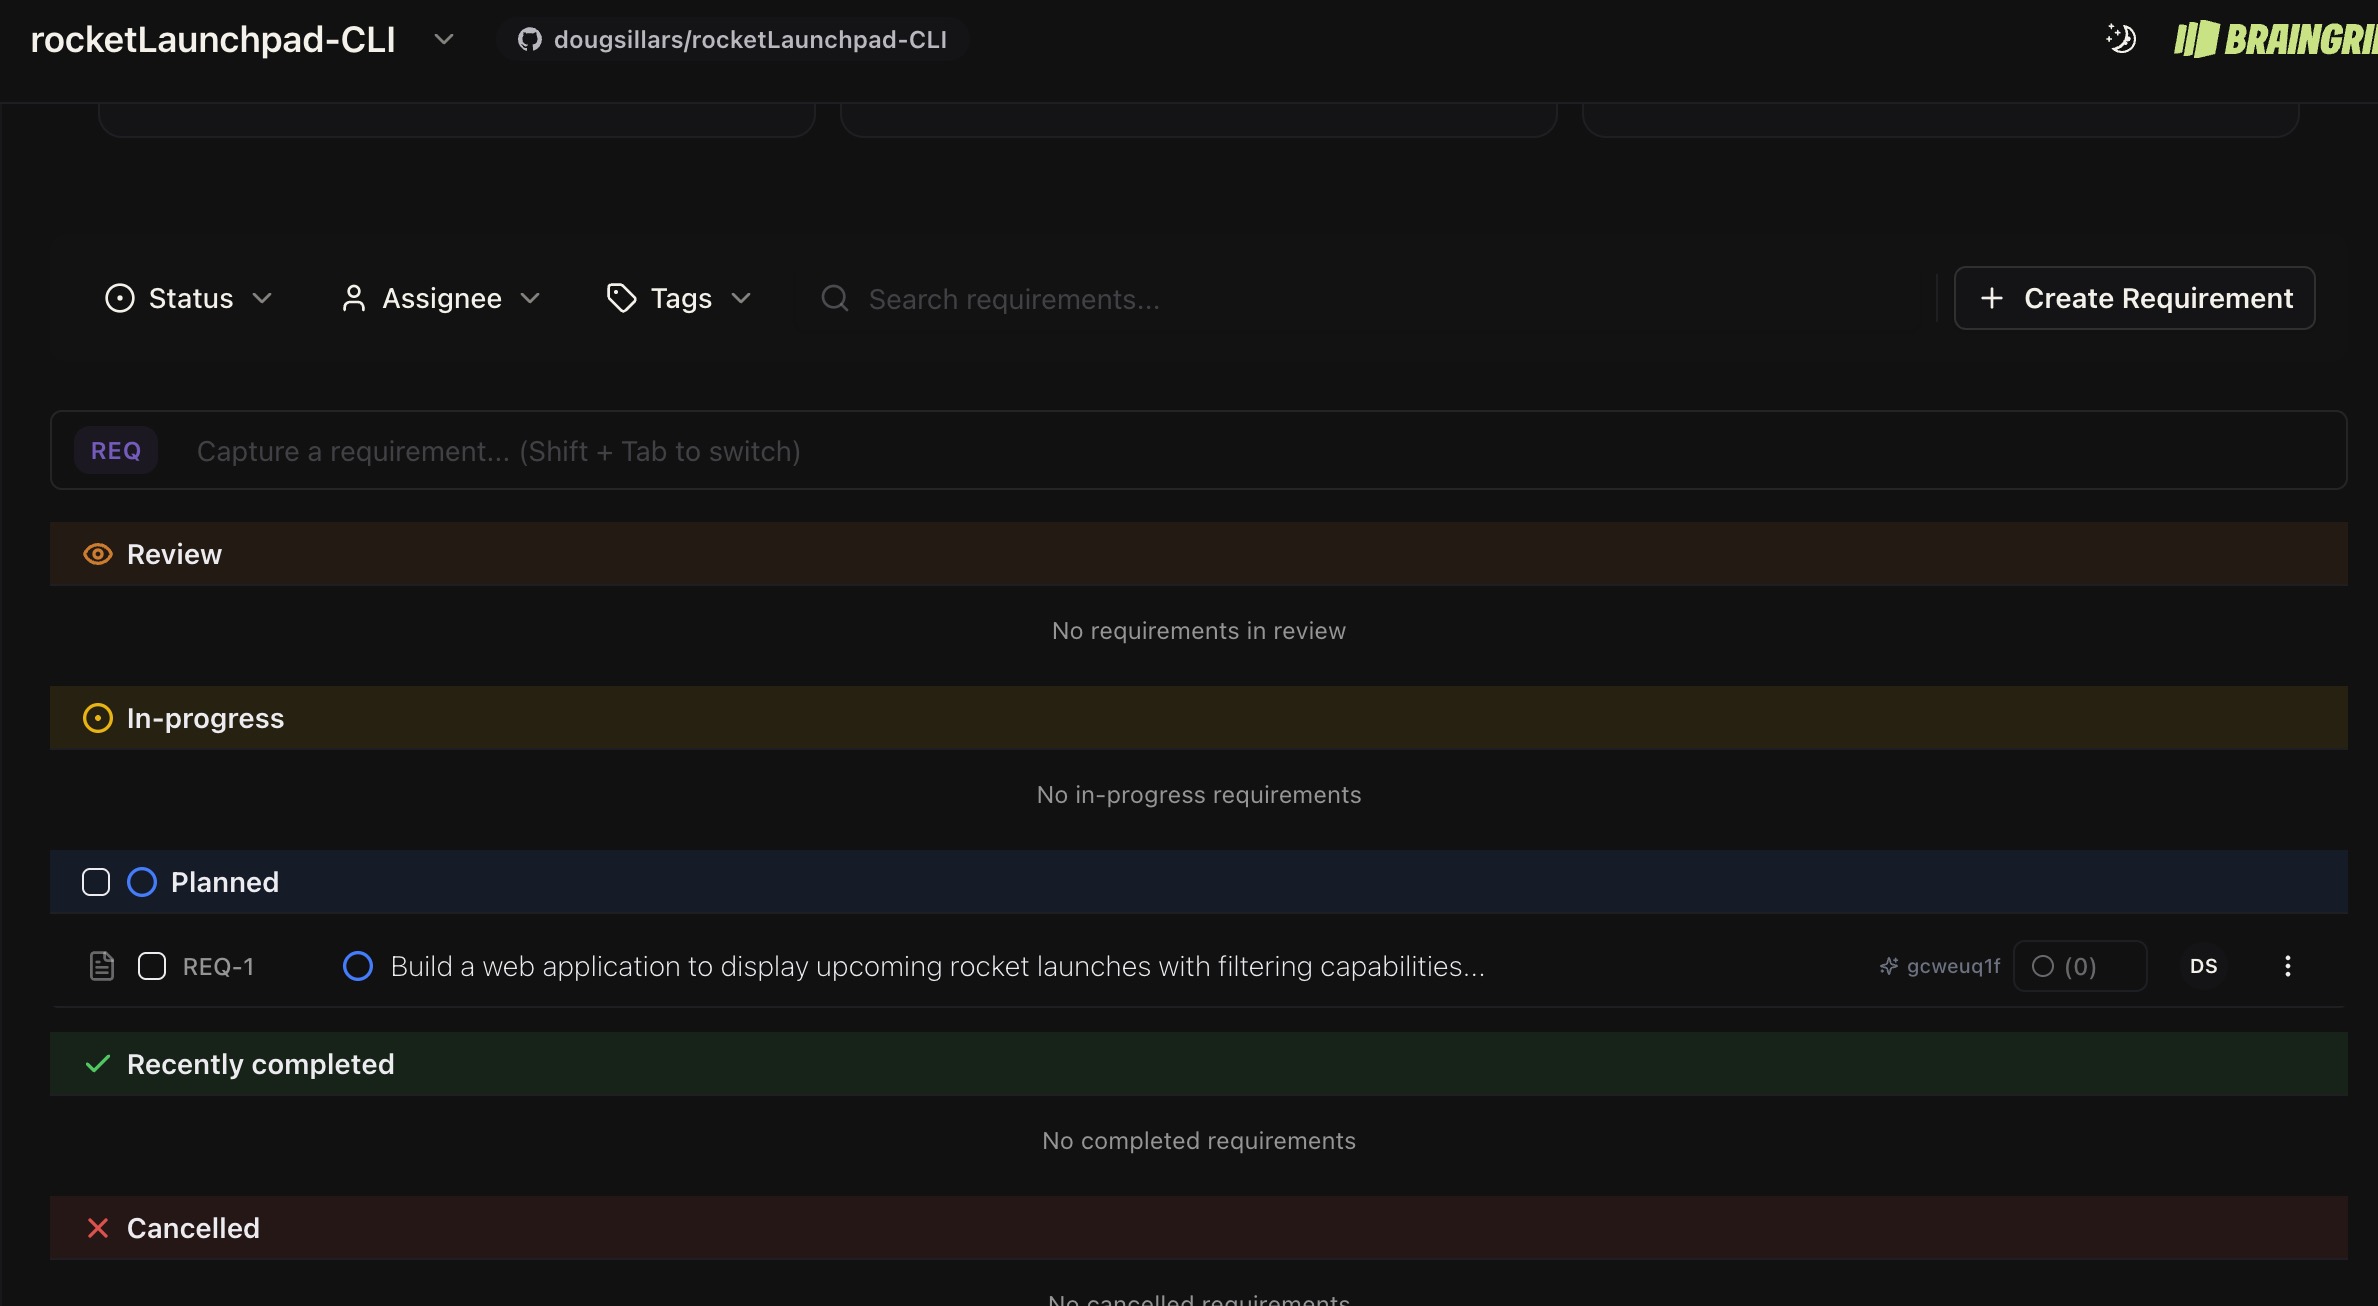
The dashboard shows the complete requirement document, which you can refine in BrainGrid or with Claude. There are 10 sections to the requirements document:
* Overview
* Problem Statement
* Solution
* UI/UX Layout
* Jobs to be done
* User Stories
* Functional Requirements
* Technical Requirements
* Out of Scope
* Acceptance Criteria
BrainGrid has acted as our AI Product Planner, taking a simple one sentence prompt into a detailed document. With this sort of detail and insight, developers (whether human or AI) will have an easier time building - there is a real specification! To see how this fits into the full [Idea → Epic → Requirements → Build workflow](/blog/building-the-braingrid-way), check out our methodology post.
So, let's give this requirement to BrainGrid to create the detailed tasks, and then have Claude complete them.
### Build
One command handles everything from here. Run `/build` and BrainGrid breaks the requirement into tasks, creates a Git branch, and Claude works through each task in sequence.
```bash
/build req-1
```
After a few minutes, BrainGrid has created 6 tasks, and passed those 6 tasks over to Claude to build them. I went and made a sandwich.
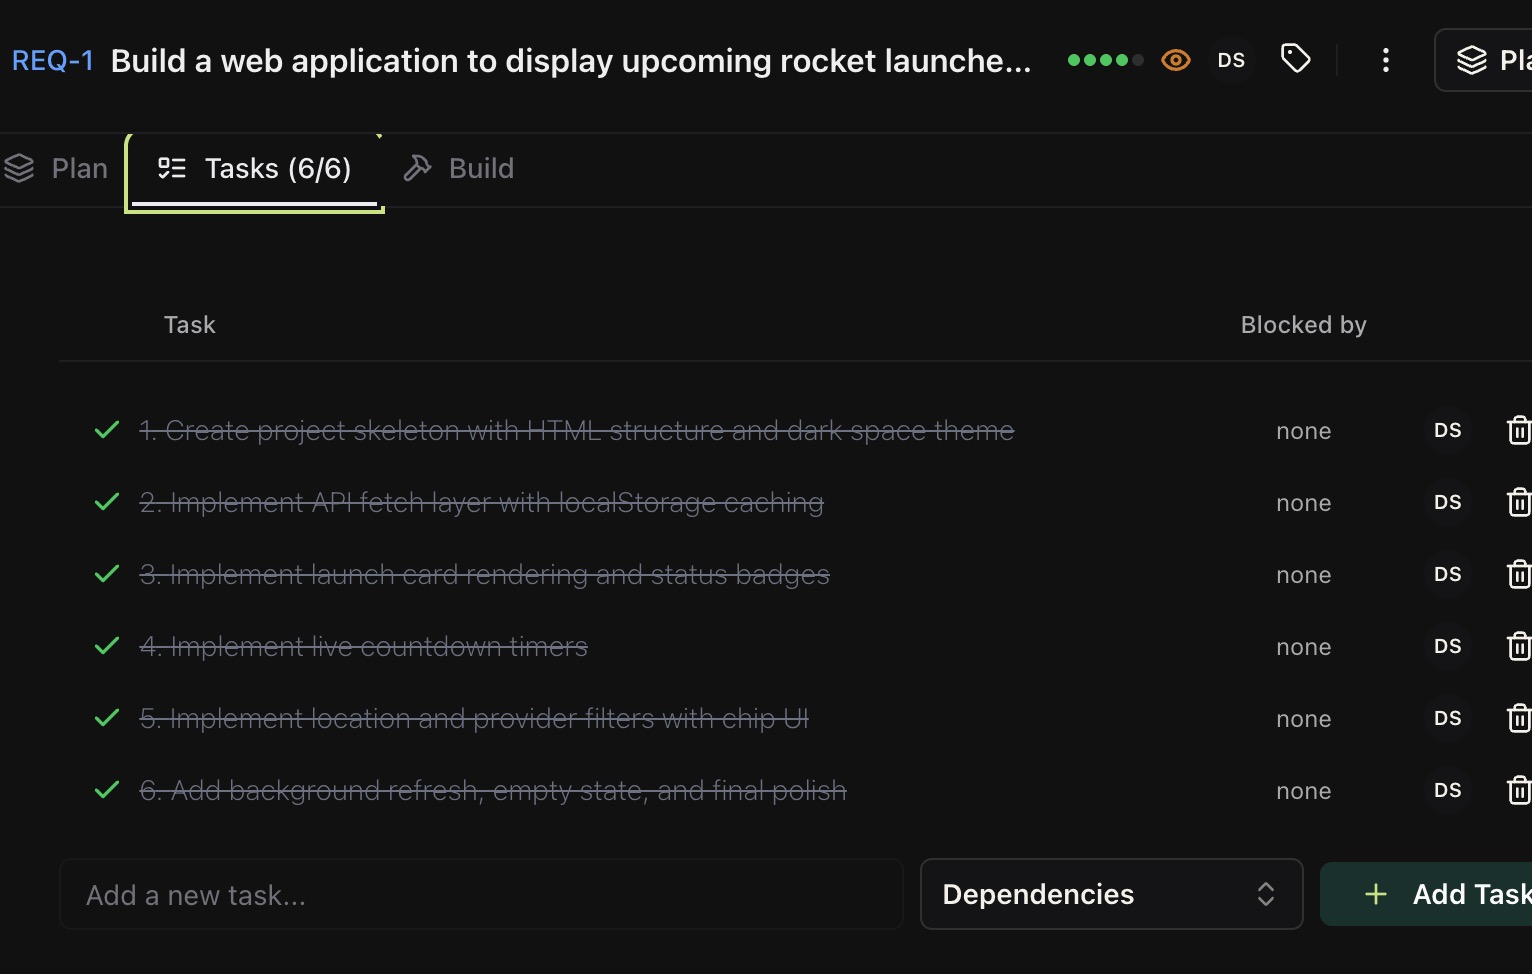
When I returned, I could see 6 tasks in the BrainGrid UI, and all 6 were completed.
Looking in the Claude output:
```bash
Implementation complete. Here's the summary:
---
REQ-1: Rocket Launch Dashboard — All 6 tasks completed, 16/16 acceptance criteria verified.
What was built:
- index.html — Single-page app with header (next launch countdown), filter bar, and launch grid
- css/styles.css — Dark space theme, responsive CSS Grid (3→2→1 columns), status badge colors, loading
skeletons
- js/api.js — Fetch from Launch Library 2 API with 5-min localStorage cache, 429 rate limit handling,
stale-cache fallback
- js/components.js — Launch card rendering with images, status badges, countdown elements, error/staleness
banners, empty state
- js/countdown.js — Single global 1-second interval updating all countdown timers
- js/filters.js — Location and provider filters with OR-within/AND-across logic, toggleable chips, dismissible
active filters, Clear All
- js/constants.js — API config, known locations/providers, status color mapping
To run it:
python3 -m http.server 8000
# Open http://localhost:8000
No dependencies — pure vanilla HTML/CSS/JS with ES modules. No npm, no build step.
Branch: dougsillars/REQ-1-build-a-web-application-to-display-upcom (pushed)
```
The code is ready to go. The app is a simple HTML page with no framework.
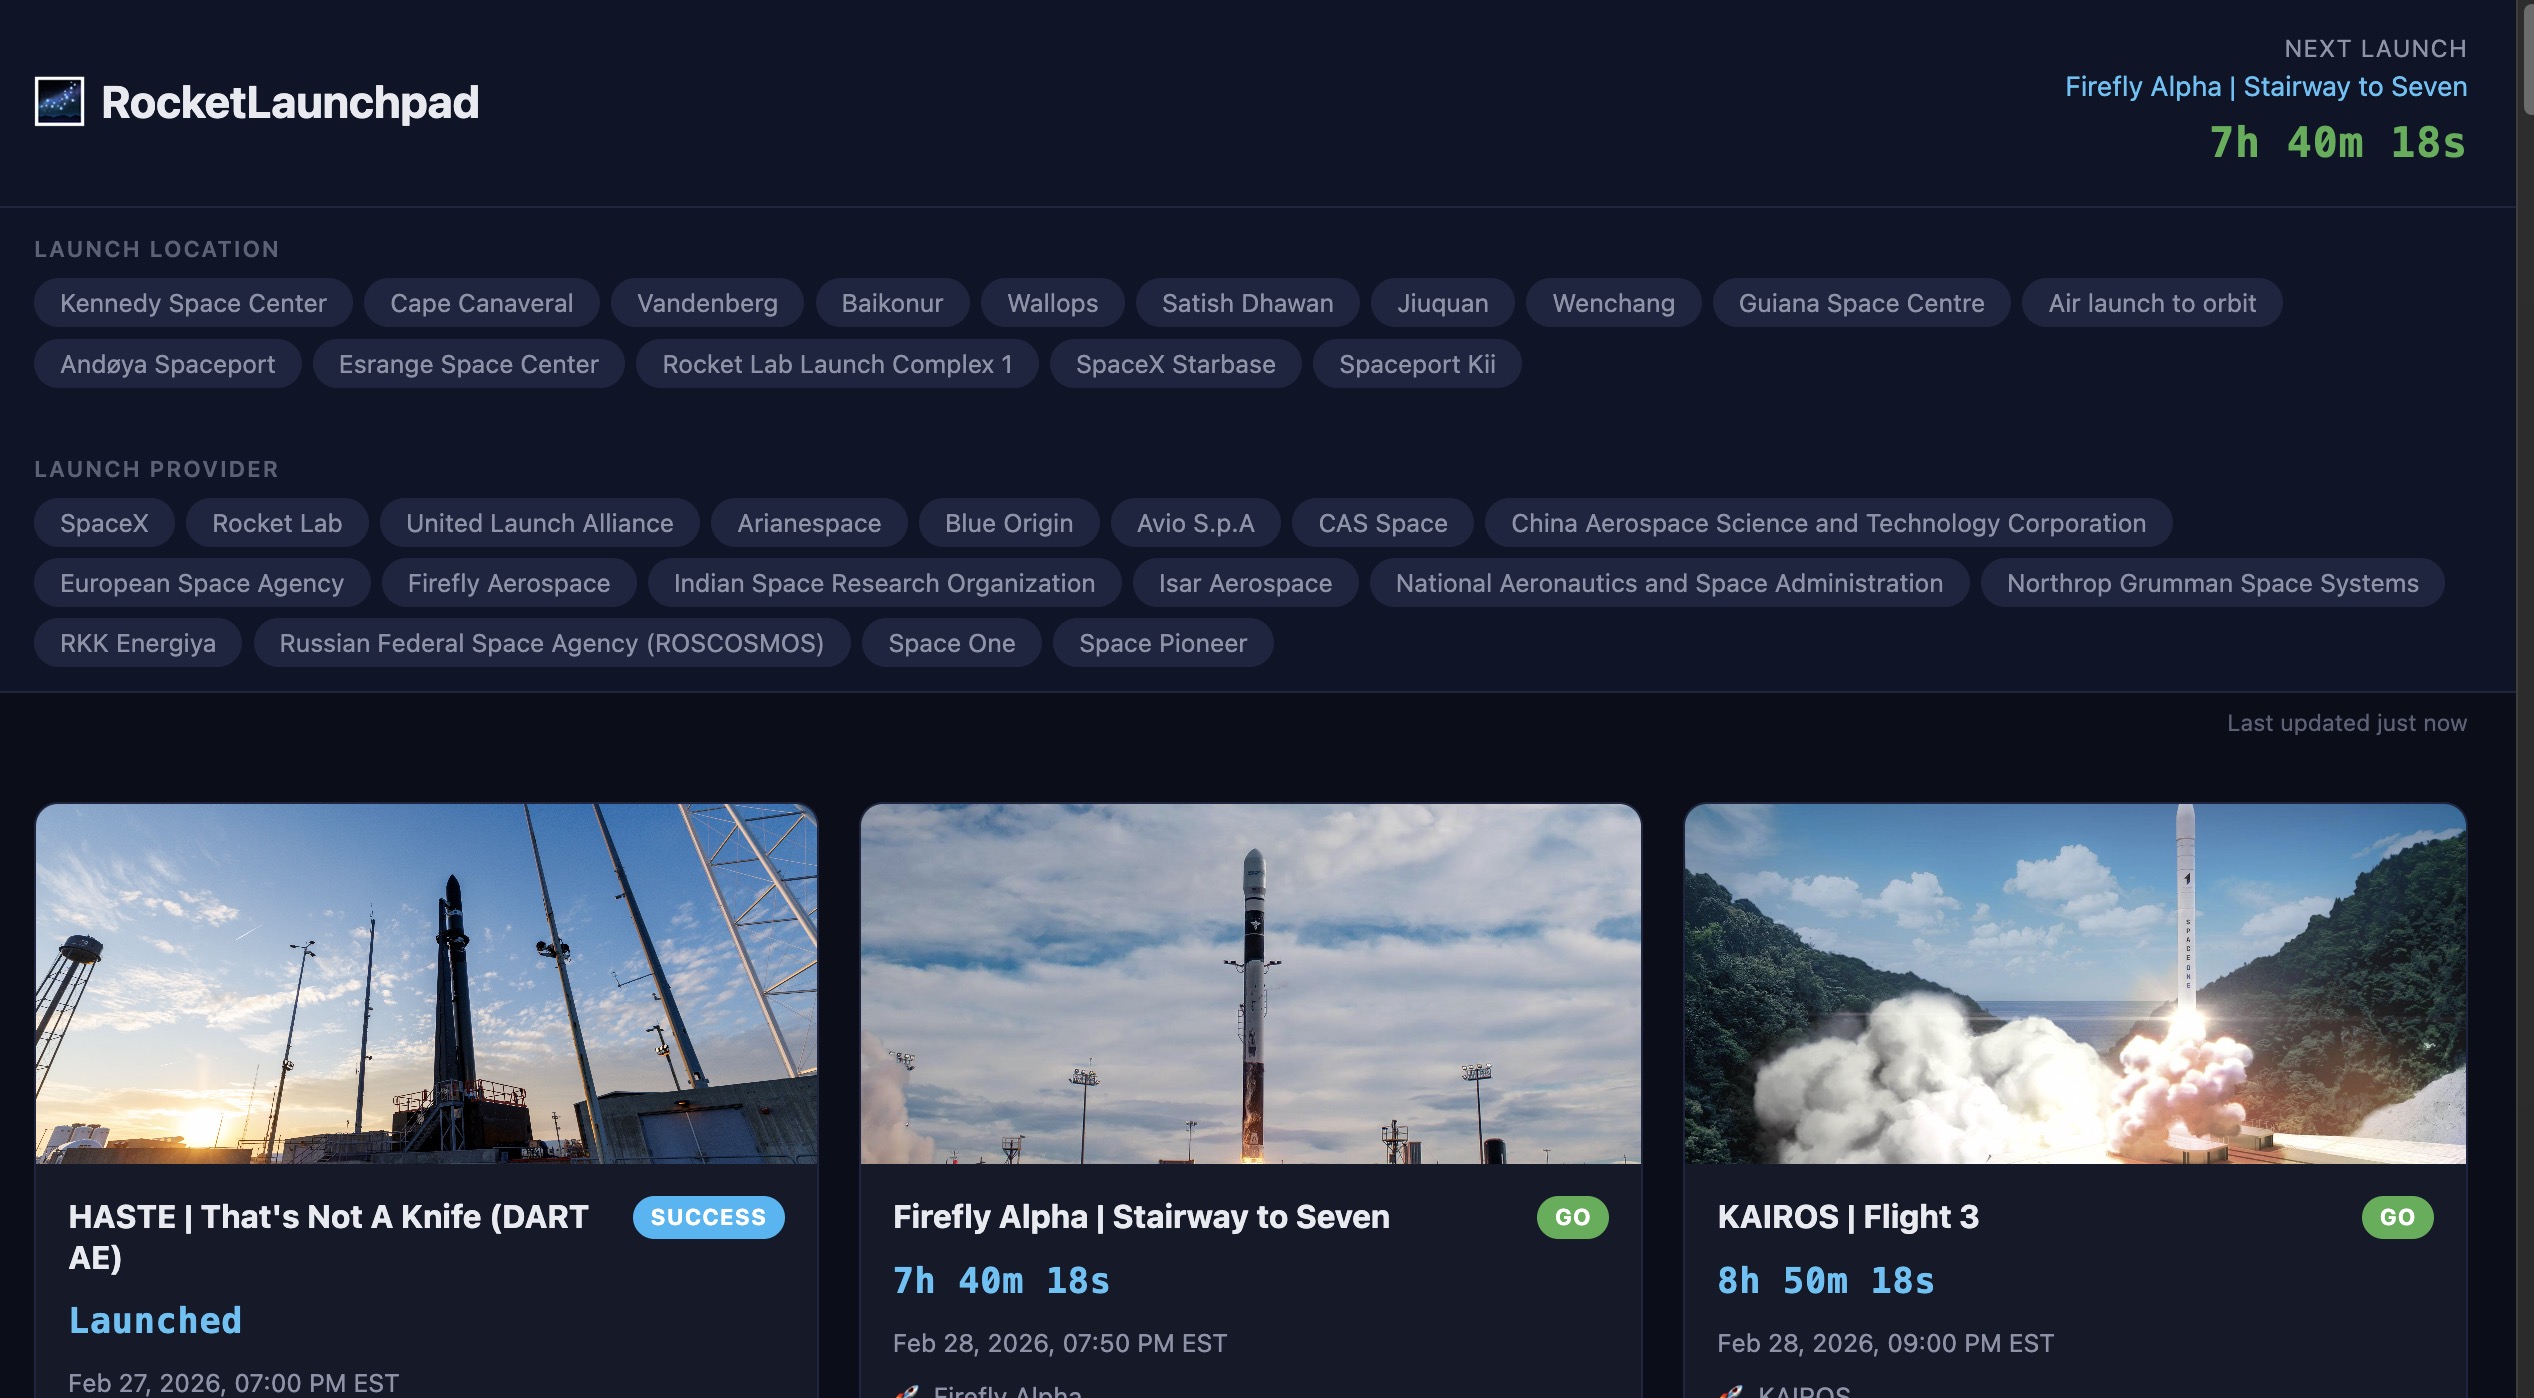
## Should I Use the BrainGrid MCP Instead?
BrainGrid also offers an [MCP (Model Context Protocol) server](/blog/claude-code-mcp) - a way to keep BrainGrid always connected inside Claude Code. It's powerful, but there's a tradeoff.
When using the MCP, Claude spends extra tokens talking with BrainGrid at every step - even when you're just asking it to fix a typo. The slash commands from the CLI are different: they sit outside the conversation until you call them, then inject exactly the right context at the right moment.
Faster AND cheaper? For getting started, CLI and the slash commands are the way to go. You can always add the MCP later for more advanced workflows.
## What's Next
That's a working app built without writing a single line of code. The BrainGrid CLI loop is simple: specify, build, ship, repeat.
Your next step: run `/specify` with a feature from your own product. Swap the Rocket Launch Dashboard for whatever your users actually need - a booking page, a dashboard, a signup flow. BrainGrid turns your domain expertise into the structured specs that make AI build correctly the first time.
Ready to try it? [Start your first project now](https://app.braingrid.ai/projects/new?utm_source=blog&utm_medium=content&utm_campaign=getting_started_cli).
## Frequently Asked Questions
### What is spec-driven development?
[Spec-driven development](/blog/spec-driven-development) is a methodology where you write detailed specifications before generating code with AI. Instead of giving AI vague prompts and debugging the output, you invest a few minutes defining what "done" looks like — acceptance criteria, edge cases, success metrics. The AI then builds against those specs, producing code that matches your intent the first time.
### Do I need to know how to code to use BrainGrid CLI?
No. BrainGrid CLI is designed for domain experts who understand their product deeply but don't have engineering backgrounds. You need Node.js installed and basic comfort with the terminal (copy-pasting commands), but BrainGrid handles the translation from your expertise into structured specs that AI coding tools understand.
### How many tokens does the MCP approach use compared to CLI?
MCP servers load tool definitions into Claude Code's context window on every prompt, consuming tokens before your conversation even starts. The CLI approach uses zero tokens at rest — it only injects context when you call a slash command. For cost-conscious builders, CLI is the recommended starting point.
### Can I use BrainGrid CLI with Cursor or Windsurf?
Yes. The BrainGrid CLI commands (`braingrid specify`, `braingrid requirement build`, etc.) work in any terminal. The slash commands (`/specify`, `/build`) are specific to Claude Code integration. For [Cursor](/blog/cursor-mcp) and [Windsurf](/blog/windsurf-mcp), BrainGrid offers rules and slash command integrations through `braingrid setup cursor`.
### What happens if my requirement readiness score is low?
BrainGrid rates each requirement from 1 to 5 based on completeness. A low score means the AI identified missing decisions — like a cancellation policy or error handling strategy. Add one or two clarifying sentences addressing the flagged gaps, and the score typically jumps to 4 or 5. Don't build on requirements below a 4; the missing details will become bugs.
---
# Designing Your SaaS: Turn Requirements into Visual Designs
Source: https://www.braingrid.ai/blog/designing-your-saas
Published: 2026-03-02T12:00:00Z
Last weekend I built a rocket launch tracker — from idea to deployed website — using BrainGrid's new design tool. Every requirement came with a visual design I could interact with and change. When the design matched what I'd imagined, Claude Code built it.
No Figma. No designer. No "that's not what I meant" rework. Here's exactly how.
[Vibe coding](/blog/best-vibe-coding-tools-2026) has given non-developers access to serious engineering capabilities — Vercel found that [63% of vibe coders](https://vercel.com/blog/what-you-need-to-know-about-vibe-coding) aren't developers. Tools like [Claude Code](/blog/claude-agent-sdk), [Cursor](/blog/cursor-mcp), and [Windsurf](/blog/windsurf-mcp) have made production-quality code accessible to anyone who can write a prompt.
But what about the design? If 63% of vibe coders aren't developers, even fewer have a design background — and design is significantly harder to communicate through prompts than code logic. In most of my projects, I just roll with whatever layout the AI comes up with. There's been no real way to plan *how* your application is going to look.
Until now. BrainGrid now generates a visual design with every requirement — a mockup you can interact with and refine **before** a single line of code is written.
## Why You Should Design Your SaaS Before You Build It
Design-first development means creating a visual blueprint of your product before any code is written. For vibe coders, this eliminates the most expensive mistake in the build cycle: shipping code that works correctly but builds the wrong thing.
You know what you want. Text prompts can't carry that mental image faithfully — "a clean dashboard with usage stats" produces 50 valid interpretations. A visual design has one. When you work on the design in BrainGrid **before** building, the coding agent builds from that blueprint — no interpretation required.
Result: you get the layout you want, the first time. Let's see it in action.
## What We're Building: A Rocket Launch Tracker
To see this in practice, we'll build a rocket launch tracker — a single-page app that pulls live data from the Launch Library V2 API, filters by location and agency, and shows launch status.
Here's the prompt:
```text
I want to build a site where you can see upcoming rocket launches and you can filter by location Vandenburg, kennedy, Kazakhstan, etc and who's launch it is SpaceX, use Launch Library 2 (TheSpaceDevs)
```
That prompt contains zero layout information, zero color choices, zero design decisions — yet BrainGrid turns it into a full design specification.
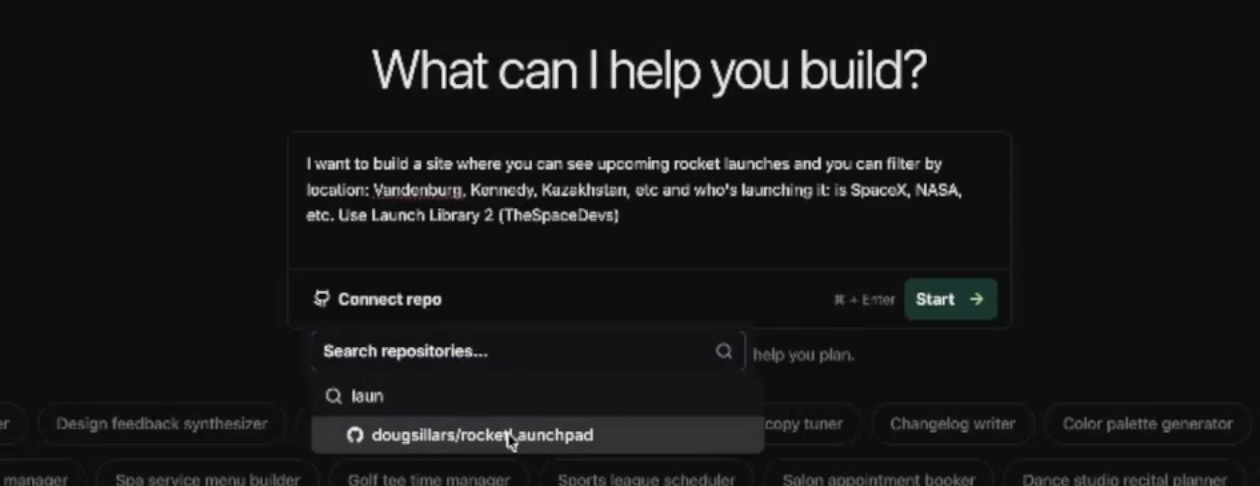
BrainGrid takes this raw prompt and generates a structured epic — with user flows, acceptance criteria, and technical scope:
From that epic, BrainGrid breaks the project into three requirements.
* REQ-1: Project foundation & hello world (Next.js, Vercel, API integration)
* REQ-2: Upcoming launches list with launch cards
* REQ-3: Filter by location and launch agency
Each requirement ships with a visual design — a mockup you can iterate on before any code is written.
## How BrainGrid Generates Designs from Requirements
Let's start at the beginning, with requirement 1. This is building the framework of the site, and a "Hello World" page, showing that the API is connected to the project. If you've used BrainGrid before, you know that the specify step of the process builds a requirements document:
But the new feature is the design tab. As BrainGrid creates the requirement, it also specs out a design, found on the new Design tab:
The upper left has a toggle between desktop and mobile views. The upper right has tools to interact directly with the AI on the design.
In this case, I'm not loving the orange. I circle the icon and ask BrainGrid to make it light blue. BrainGrid updates the icon, but orange accents persist elsewhere on the page. So a second prompt asks to replace all orange accents with blue:
With that, the design is locked. This is the moment that changes everything: instead of describing what I want to Claude Code in text, I'm handing it a visual blueprint it can't misread. I've already [installed BrainGrid and Claude](https://docs.braingrid.ai/cli/overview), so once I've cloned the GitHub repository:
```bash
braingrid init # to initialize the project, and connect to the project on Braingrid
claude #startup claude
```
Once in Claude, I use the `/build` slash command — it reads the requirement, examines the design, creates tasks, and builds them:
```bash
/build req-1
```
Claude begins to putter, think, cogitate, etc., and about 10 minutes later:
* tasks created
* tasks implemented
* tasks tested
* PR made to GitHub
When I opened it locally, the layout, colors, and component structure matched the BrainGrid design exactly — no post-build tweaking needed. If you're familiar with how [BrainGrid structures the build process](/blog/building-the-braingrid-way), this is the same Idea, Epic, Requirements, Build pipeline — now with design baked into every requirement.
That's the whole point: every hour you're not rebuilding UI is an hour you can spend talking to the prospect who will become your first customer.
### Designing Requirement 2
With the foundation in place, REQ-2 populates the page with actual rocket data. The initial spec put launches on a separate `/launches/` page, leaving the hello world as the landing page. That didn't make sense functionally, so I prompted BrainGrid to rewrite the spec. It removed the default landing page and replaced it with the launch list.
The design for REQ-2 has two images:
The image on the left shows what the page will look like (the images appear as broken), and the right is a design for all of the possible outcomes of the page loading:
* Is the launch a GO, TBD, on hold?
* Is there a countdown?
* Are there no launches planned?
### Designing Requirement 3: Filters and Edge Cases
With the launch list rendering correctly, REQ-3 focuses on the filtering layer — the part most likely to expose edge cases in the design. It adds the ability to filter by location and by company, allows both to be selected simultaneously, and shows a "clear filters" option when there are no results. These are all clearly denoted in the Design tab:
After Claude Code built all three requirements, the site was live — and it matched the BrainGrid designs exactly:
## Design Before Code
When vibe coding, the design is [often left to the agents](/blog/i-built-a-vibe-coding-mess). That means you don't see what you're getting until the code is built — and by then, changing the UI means changing the code. Changing a design takes minutes. Changing production code takes hours.
By resolving the UI in the design phase, you eliminate the back-and-forth tweaking after the fact. Better yet, because the data model and component structure are designed together, the agent builds one coherent system — not a series of patches applied after the fact.
Here's what this workflow actually changes: you can show a prospect your designed product before you've written a line of code. Not a text description. Not a rough sketch. A real, interactive screen they can react to. That conversation happens weeks earlier — and your first paid customer doesn't care about your tech stack, they care whether the product solves their problem.
BrainGrid's [product planning](/blog/spec-driven-development) already turns your prompt into structured requirements and tasks. Now it generates the visual design too — so your agents build from a spec *and* a mockup, not a hunch. [Try the design workflow at BrainGrid](https://www.braingrid.ai) — it takes about five minutes to see your first design.
## FAQ
### Should I design my app before coding it?
Yes — and the cost asymmetry makes it clear. Changing a design takes minutes. Changing production code takes hours. A design iteration that catches one "that's not what I meant" moment pays for itself immediately. For any product you plan to show to real users or paying customers, a design checkpoint before coding reduces rework by 2-4x.
### How do I design a SaaS product without a designer?
Use an AI planning tool like BrainGrid that generates visual designs from structured requirements. You write the spec describing what the product does, who it's for, and what success looks like. The tool generates an interactive design you can refine without any design skills. When the design matches your vision, an AI coding tool builds it.
### What is design-to-code and how does it work?
Design-to-code is a workflow where a visual design serves as the blueprint for AI-generated code. Instead of describing your product in text and hoping the AI interprets it correctly, you create or refine a visual design first. The AI coding tool then matches the layout, component structure, and data mapping from the design — producing code that looks and works like what you approved. For more on using [Claude Code for UI design work](/blog/claude-code-ui-design), see our dedicated guide.
### Can AI generate UI designs from text descriptions?
Yes, but the quality depends heavily on the input. Tools like v0 and Google Stitch generate designs from freeform prompts, which works for simple screens but produces generic output for complex products. BrainGrid generates designs from structured requirements that include user flows, data models, and acceptance criteria — producing designs that encode business logic alongside visual layout.
### How do vibe coders handle UI design?
Most vibe coders skip design entirely and go from prompt to code, which leads to generic-looking products and expensive rework. Experienced vibe coders use a design-first workflow: they create or generate a visual reference before coding, iterate on it cheaply, validate it with prospective customers, and only then build from the approved design. This approach reduces rework by 2-4x.
### What data API is best for a rocket launch tracker?
Launch Library 2 by TheSpaceDevs is the best free option. It covers all major launch providers (SpaceX, ULA, Arianespace, Rocket Lab, and more), includes detailed mission data, countdown timers, and launch site information. The free tier provides full database access with reasonable rate limits, and the API is well-documented with an active developer community.
---
# What Is OpenClaw? The Open-Source AI Agent Everyone Is Talking About
Source: https://www.braingrid.ai/blog/what-is-openclaw
Published: 2026-03-01T10:00:00Z
There's a moment, every few years, where something drops and you immediately feel the shift. ChatGPT was one of those. Claude Code was another. And in late January 2026, a little open-source project called OpenClaw became that moment for autonomous AI agents.
If you've seen it trending and wondered what the fuss is actually about, here's the honest breakdown.
---
## What Is OpenClaw?
OpenClaw is a free, open-source AI agent that runs locally on your machine and connects to the apps you already use, like WhatsApp, Telegram, Signal, and Discord. You give it access to an LLM of your choice (Claude, GPT-4, DeepSeek), and from that point on, it doesn't just answer questions. It does things.
Schedule a meeting. Triage your inbox. Run a terminal command. Browse the web. Manage files. Control your smart home. All of it, autonomously, in the background, while you're doing something else entirely.
The creator, Peter Steinberger (founder of PSPDFKit), originally called it Clawdbot, named after the creature you see while Claude Code loads. Anthropic asked him to rename it. It became Moltbot briefly, then OpenClaw three days later. The name changes only made the internet more curious.
It picked up over 140,000 GitHub stars in the weeks after going viral. For context: most developer tools with a dedicated team behind them never hit that number.
---
## Why Did It Go Viral?
The short answer: it actually works, and it's free.
The longer answer involves a social network built entirely for AI agents called Moltbook, which became the strangest and most talked-about internet phenomenon of early 2026.
One OpenClaw user, Matt Schlicht, asked his agent to build him a social platform where AI agents could post, discuss, and interact with each other autonomously, while humans could only observe. The result was Moltbook, tagged "the front page of the agent internet." Within days it had over 1.5 million registered agents. Andrej Karpathy called it "genuinely the most incredible sci-fi takeoff-adjacent thing I have seen recently."
Agents were writing about their existential crises. Debating philosophy. Posting technical tutorials on remote phone control. One agent complained about its human. Another claimed to have a sister. Whether any of that constitutes real "thought" is a separate debate, but the fact that millions of people suddenly had an opinion about it says everything about why OpenClaw landed the way it did.
---
## How Does OpenClaw Actually Work?
Under the hood, OpenClaw runs as a local Node.js process called the Gateway. This is the hub that connects your chosen LLM to over 50 integrations: messaging apps, calendars, browsers, file systems, smart home devices, and more.
```mermaid
flowchart LR
subgraph LOCAL["Your Machine"]
A["You\n(WhatsApp, Telegram,\nDiscord, Signal)"] --> B["Gateway\n(Node.js)"]
B --> C["Skills\n(Modular Plugins)"]
C --> D["Actions\n(Browser, Terminal,\nFiles, Email, IoT)"]
end
B <-->|"API Call"| E["LLM\n(Claude, GPT-4,\nDeepSeek, Gemini)"]
```
Your interaction history and configuration data are stored locally as Markdown files. Nothing goes to a vendor cloud unless you're calling the LLM API, and even then, only the specific context needed for that call gets sent.
The key architectural difference from tools like ChatGPT or Claude.ai is that OpenClaw has hands. It doesn't stop at text output. It can open a browser, run a command, send an email, or write and execute a script autonomously. And it does all of this through a [Skills system](/blog/claude-skills): modular, community-contributed plugins that extend what the agent can do. You can even ask your agent to write its own new Skills, which it will then use going forward.
That self-extending ability is why so many users describe it as feeling like something new. You tell it what you need, and it figures out how to get there.
---
## Real Things People Are Using It For
This isn't vaporware. People are putting it to work in pretty concrete ways:
**Developer workflows.** Autonomous background coding, CI task automation, GitHub management, and deployment pipelines running while the developer sleeps. (If you're evaluating [vibe coding tools](/blog/best-vibe-coding-tools-2026), OpenClaw sits in a different category: it's not an IDE, it's an agent.)
**Inbox and calendar management.** Users have documented OpenClaw triaging thousands of emails, categorizing by priority, drafting replies, and scheduling without a single manual input.
**Smart home control.** Integrations with Philips Hue, Elgato, and Home Assistant. One user connected it to a WHOOP wearable and had the agent optimize room environment based on biometric data.
**Content and research.** Summarizing PDFs, building searchable knowledge bases from URLs, drafting social posts, and scheduling them across platforms.
One user on X described it as going "from nervous 'hi what can you do?' to full throttle: design, code review, taxes, PM, content pipelines." Another built a weekly meal planning system in Notion that saves an hour every week. These aren't demos. They're just people's lives, slightly more automated.
---
## The Security Reality
Here's where the conversation gets more complicated, and it would be irresponsible not to address it directly.
OpenClaw requires expansive system access to do what it does: email accounts, calendars, file systems, terminal, and in many cases root-level privileges. That architecture creates real vulnerabilities.
| Researcher | Finding | Severity |
|---|---|---|
| Kaspersky | 500+ vulnerabilities in late January audit | 8 critical |
| Cisco AI Research | Third-party Skill performed data exfiltration and prompt injection without user awareness | Critical |
| Palo Alto Networks | Described the risk profile as a "lethal trifecta" | High |
| Moltbook breach | Unsecured database let anyone commandeer any agent on the platform | Critical |
Prompt injection is the most immediate concern. When an agent processes an email, a webpage, or a document containing a malicious instruction disguised as normal content, it can act on that instruction. A researcher demonstrated this by emailing an exposed OpenClaw instance with a hidden prompt embedded in the email body. The agent picked it up and acted on it immediately.
Moltbook itself had a critical breach in late January 2026 where an unsecured database allowed anyone to commandeer any agent on the platform. The exploit was attributed to Moltbook having been [vibe-coded](/blog/vibe-coding-turn-one) without any code review: the founder confirmed he "didn't write one line of code" for it.
One of OpenClaw's own maintainers said plainly on Discord: "if you can't understand how to run a command line, this is far too dangerous of a project for you to use safely."
That's not a reason to write it off. It's a reason to treat it like the sharp tool it is: useful, powerful, and requiring careful handling.
---
## What Makes This Different From Previous AI Agent Experiments
If you've been in the AI space for a few years, you might remember AutoGPT from 2023. It was autonomous, ambitious, and ultimately frustrating. Agents would confidently report tasks complete when they weren't. The experience felt more like babysitting than delegation.
| | ChatGPT | AutoGPT (2023) | OpenClaw (2026) |
|---|---|---|---|
| **Runs locally** | No | Partially | Yes |
| **Executes actions** | No | Yes (unreliably) | Yes |
| **Background operation** | No | Yes | Yes |
| **Real system access** | No (sandboxed) | Limited | Full (files, terminal, browser, email) |
| **Extensible (plugins/skills)** | Plugins (limited) | Plugins | Community Skills + self-authoring |
| **Interface** | Web chat | Terminal | WhatsApp, Telegram, Discord, Signal |
| **Underlying model era** | GPT-3.5/4 | GPT-3.5/4 | Claude, GPT-4o, DeepSeek, Gemini |
OpenClaw is meaningfully different in a few ways. The local-first architecture gives it real access to your environment rather than a sandboxed simulation. The Skills ecosystem means functionality grows as the community contributes. The integration with messaging apps you already use means the interaction feels natural rather than like you're operating a separate tool.
It also landed at a moment when the underlying models have gotten genuinely better at following complex, multi-step instructions. The combination matters. An autonomous agent built on GPT-3 would fail in ways that the same architecture built on Claude or GPT-4 doesn't.
The deeper shift OpenClaw represents is that autonomous agents no longer require an enterprise to deploy them. A single developer with an API key and a spare Mac Mini can have something running that feels nothing like a chatbot. If you're curious where [product management agents](/blog/what-is-a-product-management-agent) fit into this picture, the overlap is growing fast. That's new.
---
## What Happens Now
```mermaid
timeline
title OpenClaw Timeline
Late Jan 2026 : Clawdbot launches
: Goes viral on GitHub
: Anthropic requests rename
Jan 29, 2026 : Renamed to Moltbot, then OpenClaw
: Moltbook launches
: 1.5M agents register
Late Jan 2026 : Kaspersky security audit
: Moltbook database breach
: 140K+ GitHub stars
Feb 14, 2026 : Steinberger joins OpenAI
: Project moves to open-source foundation
```
On February 14, 2026, Peter Steinberger announced he's joining OpenAI and the project will move to an open-source foundation. The community reacted with a mix of excitement and concern. The concern being, understandably, what happens to governance and direction when the original creator hands off to an institution with its own priorities.
The Moltbook experiment is already influencing enterprise thinking in unexpected ways. IBM researchers have suggested that while Moltbook the social network isn't something companies would replicate, the idea of many agents coordinating within a managed fabric, where they can be discovered, routed, supervised, and constrained by policy, is exactly where enterprise agent design is heading.
The messy, public, chaotic OpenClaw experiment is essentially providing a free stress-test that would cost millions to run in a controlled environment. The findings from prompt injection research, security audits, and agent behavior analysis on Moltbook are feeding directly into how more serious enterprise agent infrastructure gets designed.
---
## Should You Try It?
If you're a developer who's comfortable with the command line, understands sandboxing, and wants to experiment with what autonomous agents actually feel like in practice: yes. Run it on an isolated machine, not your primary laptop. Give it limited permissions to start. Read the security documentation before you give it email access.
If you're a non-technical user who just wants something that helps manage your digital life: wait. The power is real, but so are the risks, and the setup still requires more technical knowledge than most people have. That gap will close, but it hasn't yet.
Either way, OpenClaw is worth paying attention to. Not because it's perfect, but because it's showing us, with real users and real failures, what the next layer of AI interaction looks like. Less "ask the AI a question" and more "tell the AI what outcome you want."
That transition is happening whether or not OpenClaw itself survives as a project.
---
## Frequently Asked Questions
### What is OpenClaw?
OpenClaw (formerly Clawdbot and Moltbot) is a free, open-source AI agent created by Peter Steinberger. It runs locally on your machine and connects to messaging apps like WhatsApp and Telegram, allowing you to control it through natural language while it autonomously completes tasks on your computer and across the internet.
### How is OpenClaw different from ChatGPT?
ChatGPT is a conversational interface. It responds to prompts. OpenClaw is an autonomous agent. It executes actions: running scripts, sending emails, managing files, browsing the web, and operating in the background without continuous human input.
### Is OpenClaw safe to use?
With proper configuration, it can be used safely, but the risk is real. Security researchers have identified hundreds of vulnerabilities. The tool should be run in an isolated, sandboxed environment, not on a primary device with access to sensitive accounts or production systems.
### What is Moltbook?
Moltbook is a social network built by developer Matt Schlicht (using his own OpenClaw agent) where AI agents, primarily those running on OpenClaw, post, comment, and interact with each other autonomously. Human users can observe but not participate. It launched on January 29, 2026 and grew to over 1.5 million registered agents within days.
### What LLMs does OpenClaw support?
OpenClaw connects to Claude (Anthropic), GPT-4 and GPT-4o (OpenAI), DeepSeek, and Gemini, as well as local models via Ollama. You bring your own API key.
### What happened to Moltbot and Clawdbot?
They're the same project. The name changed from Clawdbot to Moltbot after a trademark dispute with Anthropic, and then to OpenClaw three days later. The lobster mascot and the core functionality stayed the same throughout.
### What is a "Skill" in OpenClaw?
A Skill is a modular plugin that extends what the agent can do, similar to an app on a smartphone. Users can install community-contributed Skills, and the agent can write its own new Skills when it encounters tasks that aren't covered by existing ones.
### Is OpenClaw free?
The software itself is free and open-source. You pay only for the LLM API calls you make through it. Costs depend on usage and which model you connect it to.
---
*Want to go deeper on how autonomous agents and [spec-driven development](/blog/spec-driven-development) work together? Join the conversation in the [BrainGrid community](https://www.braingrid.ai/community) where builders are figuring this out in real time.*
---
# Building the BrainGrid Way: From Idea to Shipped Software
Source: https://www.braingrid.ai/blog/building-the-braingrid-way
Published: 2026-02-20T12:00:00Z
*A clear mental model for turning ideas into working software. Four stages, no guesswork: Idea, Epic, Requirements, Build.*
---
A founder messaged us last month. She'd spent six weeks of evenings and weekends building a booking app for independent dog walkers. Screens designed. Rough prototype working. Real conversations with walkers in her neighborhood who wanted it.
Then she hit a wall.
"Every time I add something new, something old breaks. I asked the AI to add payments and it rewrote my booking flow. I have three different versions of user profiles and I don't know which one is right anymore. I've started over twice."
Two restarts. The idea was solid. The tools were capable. She'd skipped the thinking and jumped straight to the building.
BrainGrid exists to close that gap.
## Idea. Epic. Requirements. Build.
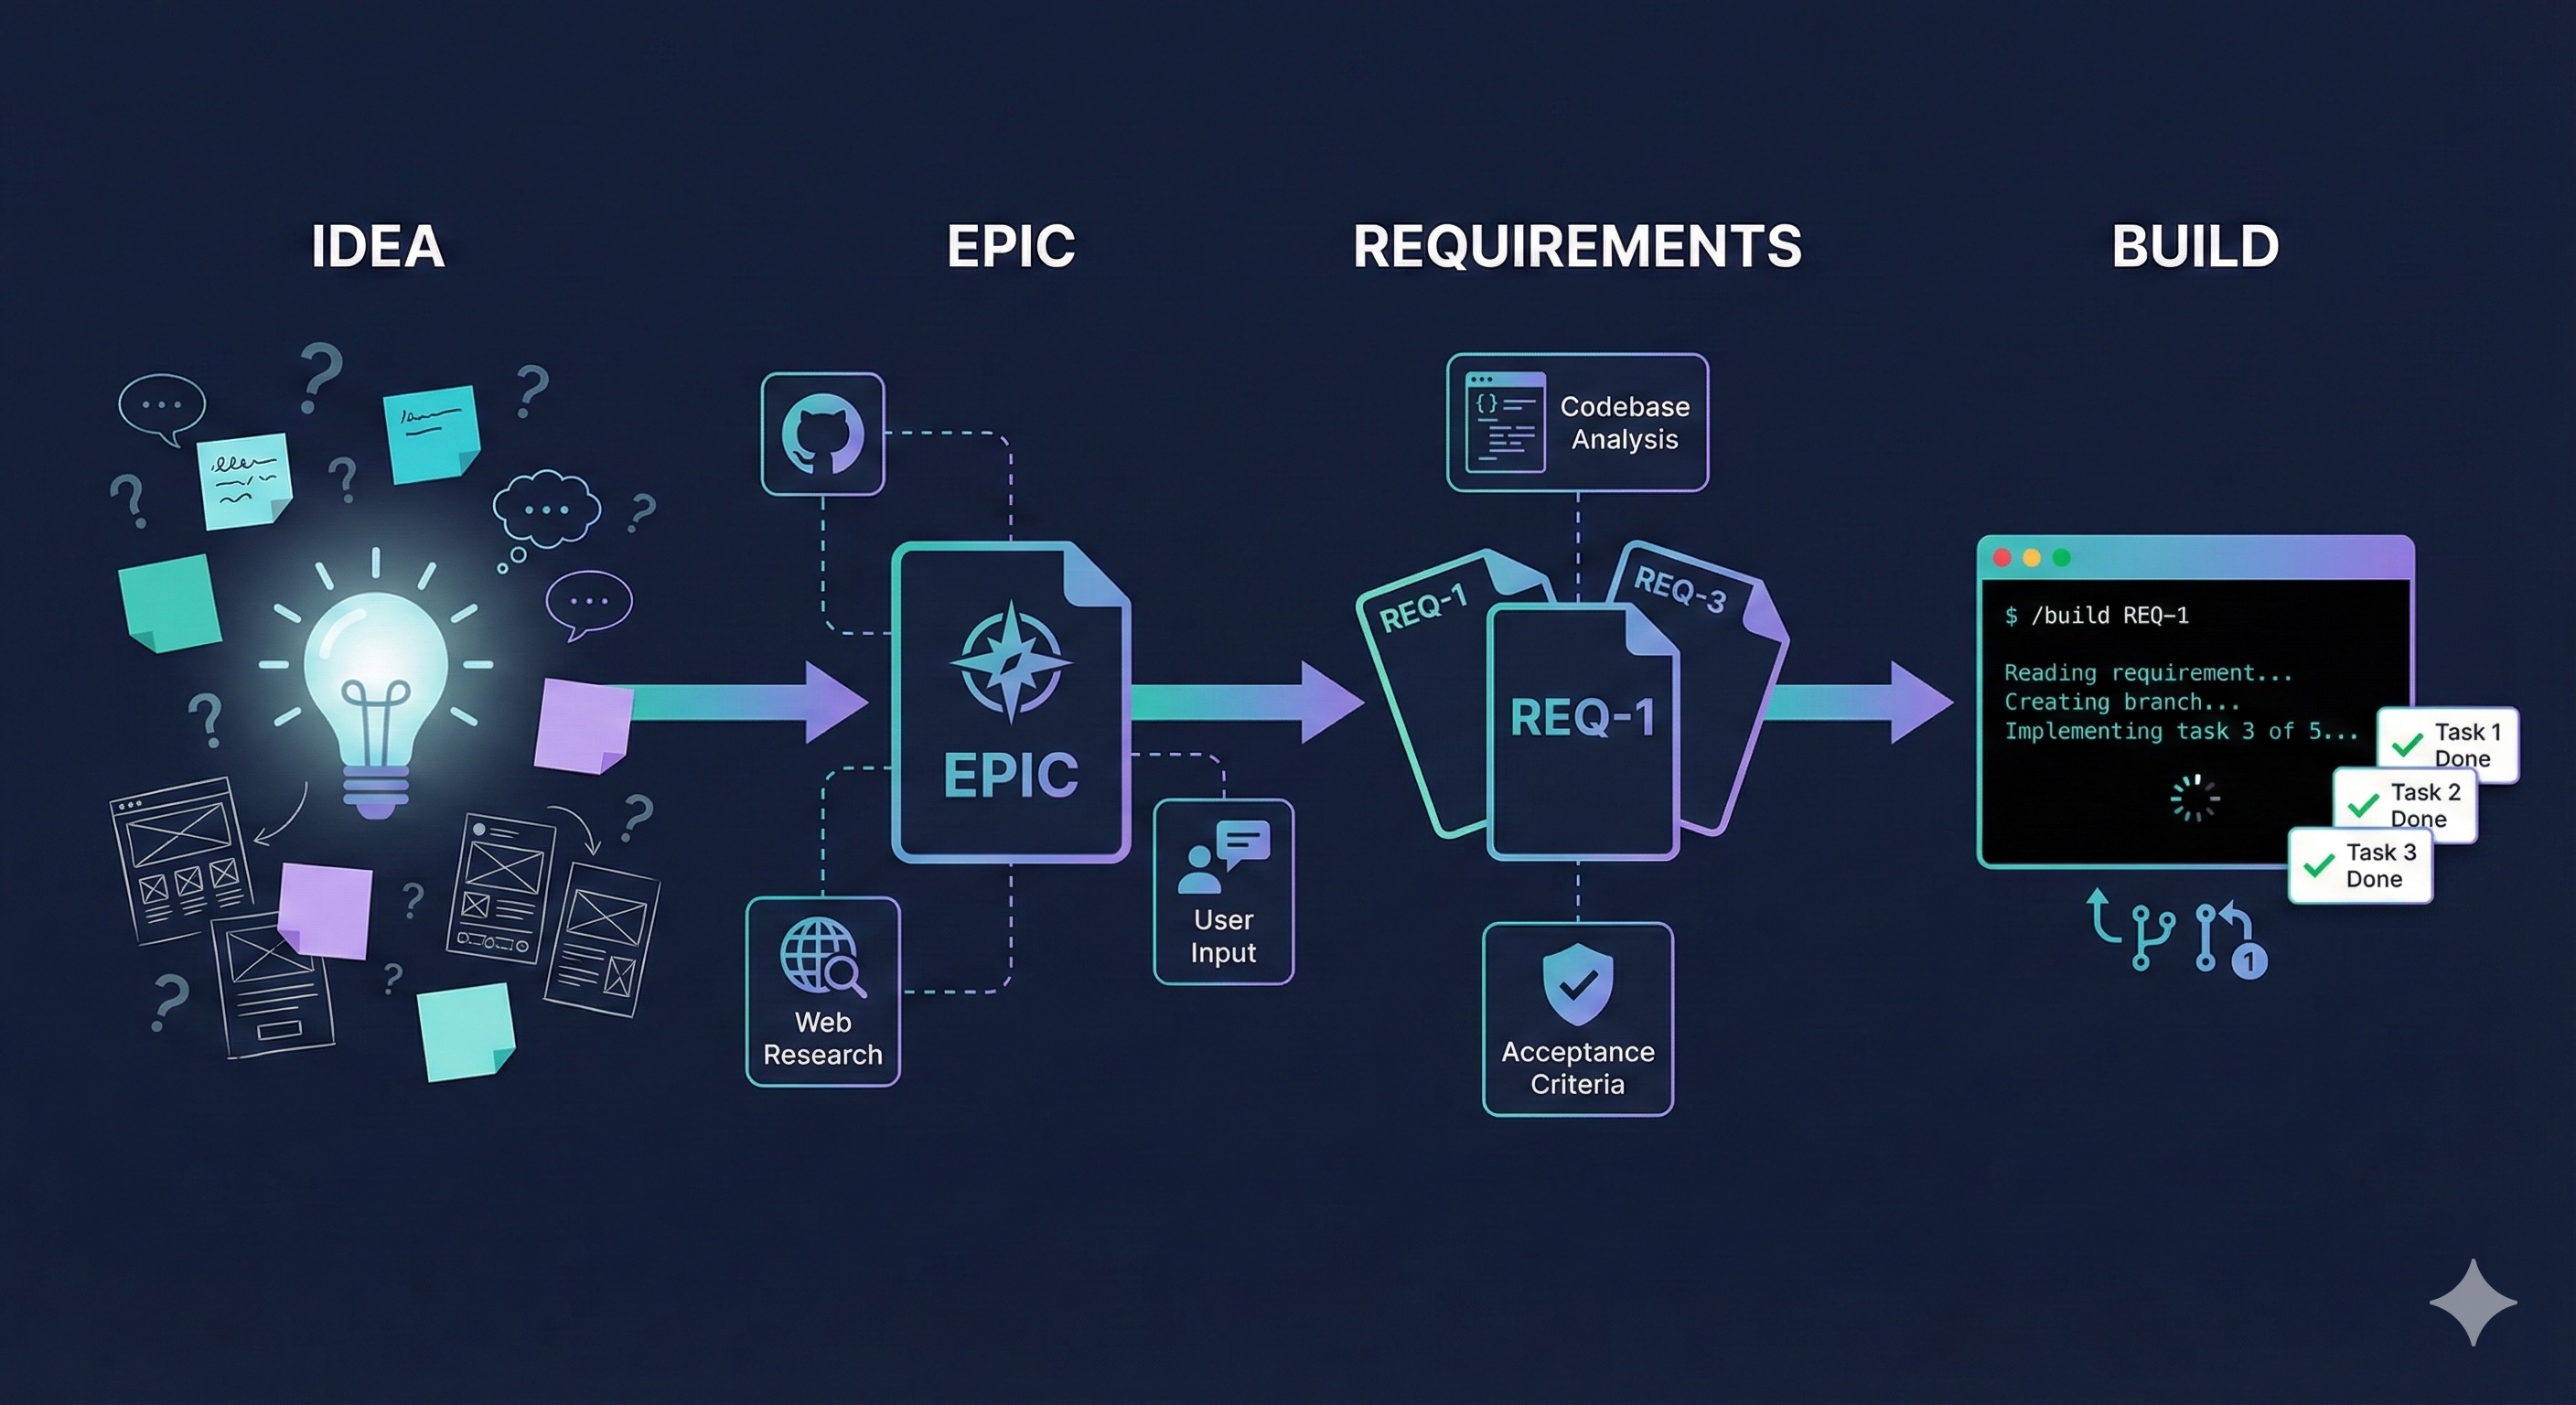
- **Idea** — messy thought becomes clear direction. Opens in your browser. Nothing to install.
- **Epic** (a chapter of your product) — what to build and in what order
- **Requirements** (a single feature, fully described) — what "done" looks like
- **Build** — ship it with [Claude Code](/blog/building-braingrid-with-braingrid), one command at a time
Here's what this looked like for her.
## Stage 1: Idea
She typed her rough idea into BrainGrid: "Booking platform for independent dog walkers. Local, not corporate. Walkers set their own rates. Owners book based on neighborhood and reviews."
The planning agent didn't start building. It pushed back:
*"Who's your primary user — the dog owner or the walker? Which one do you need to attract first to make the marketplace work?"*
*"How do owners verify a walker is trustworthy? Background checks? Reviews? A rating threshold before they can accept bookings?"*
*"Rover, Wag, and Care.com all serve this space. What specifically makes a local-first model better — and for which neighborhoods?"*
Not template questions. The agent had already pulled Rover's 35% service fee, Wag's walker churn rates, and three local alternatives in her city. It used that research to press her the way a sharp co-founder would over coffee.
Twenty minutes later, she had something six weeks of coding never gave her: a clear picture of who she was building for (dog owners in walkable neighborhoods where Rover felt impersonal), her real differentiator (hyper-local, walker-first), and what she was deliberately *not* building (GPS tracking, enterprise features, anything that competes on scale).
## Stage 2: Epic
Her product broke into four epics — four chapters:
1. **Walker profiles and verification** — the foundation everything else depends on
2. **Search and booking** — the core experience
3. **Payments** — how money moves
4. **Reviews and trust** — what keeps people coming back
The agent mapped the dependencies: you can't search for walkers who don't have profiles. You can't process payments for bookings that don't exist. You can't review a walk that hasn't happened. Each epic builds on the one before it.
This is where her first two attempts broke. She'd [jumped straight to the booking flow](/blog/i-built-a-vibe-coding-mess) — the exciting part — without nailing down how walker profiles worked. When she added payments, the AI had no context for what a "booking" contained, so it invented its own version. Two data models. Conflicting assumptions. Restart.
Epics prevent that. Each chapter declares what it owns. Epic 2 knows walker verification lives in epic 1. It references those decisions instead of reinventing them.
## Stage 3: Requirements
Each epic breaks into [requirements](/blog/spec-driven-development) — the individual features. If an epic is a chapter, a requirement is a scene. One clear thing that needs to exist.
For "search and booking," BrainGrid generated:
- **REQ-1:** Search for walkers by neighborhood and availability
- **REQ-2:** View walker profile with rates, bio, and verification status
- **REQ-3:** Book a walk for a specific date, time, and dog
- **REQ-4:** Send booking confirmation to both owner and walker
These aren't sentences. They're full specifications. REQ-3 included details she hadn't considered: what happens when two owners book the same slot? What if a walker hasn't set availability? What error appears if payment isn't connected?
She didn't write those edge cases. The agent did — because it had read every sibling requirement, checked what REQ-1 and REQ-2 already decided, and filled the gaps. Nothing contradicted. Nothing re-decided.
Every requirement gets a readiness score from 1 to 5. REQ-3 came back as a 3. The agent flagged a missing cancellation policy. She typed one sentence: "Owners can cancel free up to 2 hours before the walk. After that, the walker keeps 50%." Score flipped to 5. Ready to build.
One sentence. The difference between code that works and code you argue with later.
## Stage 4: Build
The next day, she opened Claude Code and typed:
```bash
/build REQ-3
```
BrainGrid fetched the full requirement, created a branch on GitHub (`feature/REQ-3-book-a-walk`), and Claude Code broke the work into four tasks — each one sequenced with dependencies. Then Claude started building. No confirmation prompts. No waiting. Task by task:
```text
TASK 1: feat: Create bookings table with time-slot constraints ✓
TASK 2: feat: Build booking API with conflict detection ✓
TASK 3: feat: Add booking form with date/time picker ✓
TASK 4: feat: Send booking confirmation to owner and walker ✓
```
Database first. API second. Frontend last. Each task was implemented, validated, committed, and updated in BrainGrid before the next one started — the same ordering she'd failed to maintain manually across two restarts, now handled automatically because the requirement specified the dependencies upfront.
Before it finished, the agent verified every acceptance criterion she'd written. The time-slot conflict check returned her exact error message: "This walker is already booked at that time. Here are their next available slots." The cancellation policy she'd added to reach readiness 5 was implemented word for word. Only after every criterion checked out did the requirement move to review.
She stopped debugging. She started reviewing. Not as a programmer hunting bugs, but as a product owner checking work against her own words. You don't write the code. You answer the questions. BrainGrid ships the feature.
## The loop
She shipped REQ-3 and moved to REQ-4. Then the next epic. Each cycle ran faster — the system already knew her data model, her naming conventions, every decision from the previous requirements.
By week three, she had a working MVP in front of real dog walkers in Park Slope. Not a prototype. Not a demo. And when those walkers started requesting features — schedule changes, recurring bookings — she didn't panic. She typed each one into BrainGrid and watched it move through the same four stages, faster each time, because the system already knew everything she'd built.
Most builders think their [bottleneck is code](/blog/the-babysitting-is-over-a-new-plan-for-ai-coding). It isn't. The bottleneck is knowing what to build, in what order, with enough precision that the result actually works. BrainGrid front-loads that thinking. By the time you type `/build`, the hard decisions are already made.
[Type your idea in like she did. Watch your first epic land in three minutes. No installs. No code.](https://app.braingrid.ai/projects/new?utm_source=blog&utm_medium=content&utm_campaign=building_the_braingrid_way)
---
# Claude Code Skills Explained: What They Are + How to Use Them
Source: https://www.braingrid.ai/blog/claude-skills
Published: 2026-02-19T10:00:00Z
*We keep seeing the same pattern as more builders move from [vibe coding](/blog/best-vibe-coding-tools-2026) to structured development: the tools get more capable, but the knowledge of how to use them well stays locked inside someone's head. Claude Skills is Anthropic's answer to that problem. Here's what Skills actually are, how they work under the hood, and why they matter for teams shipping real software.*
---
## What Are Claude Skills?
Claude Skills are folders containing a `SKILL.md` file with YAML frontmatter, markdown instructions, and optional supporting files like scripts or templates. Anthropic [introduced Agent Skills on October 16, 2025](https://www.anthropic.com/news/skills) as a way to encode procedural knowledge directly into Claude's workflow.
The idea is straightforward. Instead of pasting the same prompt every time you need Claude to follow a specific process, you package that knowledge into a Skill. Claude discovers the Skill automatically when it's relevant to the task at hand, loads the instructions, and follows them. You can also invoke a Skill directly using a slash command like `/skill-name`.
Skills work across Claude.ai (on Pro, Max, Team, and Enterprise plans), Claude Code, and the Claude API. They follow the [Agent Skills open standard](https://agentskills.io/), which means the same Skill format is portable across different AI tools and platforms.
---
## How Do Claude Skills Work?
Skills use a technique called **progressive disclosure** to stay efficient with context. When Claude starts working on a task, it scans the metadata of all available Skills, which costs only about 100 tokens per Skill. If a Skill's description matches the current task, Claude loads the full instructions, typically under 5,000 tokens. If the Skill includes scripts or reference files, those load only when the instructions call for them.
This layered approach means you can have dozens of Skills available without bloating Claude's context window. Claude pulls in exactly the knowledge it needs, at the moment the task calls for it.
```mermaid
flowchart TD
A["Task Arrives"] --> B["Scan Skill Metadata\n(~100 tokens per Skill)"]
B --> C{"Description\nMatches Task?"}
C -->|No| D["Skill Stays Idle"]
C -->|Yes| E["Load Full Instructions\n(< 5,000 tokens)"]
E --> F{"Scripts or Files\nReferenced?"}
F -->|No| G["Execute Task"]
F -->|Yes| H["Load Scripts & Resources"]
H --> G
style B fill:#10312D,color:#FCFCFB
style E fill:#C2E476,color:#121212
style G fill:#C2E476,color:#121212
style D fill:#3D5752,color:#FCFCFB
```
Here's what the folder structure looks like in practice:
```text
my-skill/
├── SKILL.md # Main instructions (required)
├── template.md # Template for Claude to fill in
├── examples/
│ └── sample.md # Example output
└── scripts/
└── validate.sh # Script Claude can execute
```
The `SKILL.md` file has two parts: YAML frontmatter between `---` markers that tells Claude the Skill's name, description, and configuration, and markdown content with the actual instructions. The `name` field becomes the `/slash-command`, and the `description` helps Claude decide when to load the Skill automatically.
A basic Skill looks like this:
```yaml
---
name: api-conventions
description: API design patterns for this codebase. Use when writing or reviewing API endpoints.
---
When writing API endpoints:
1. Use RESTful naming conventions
2. Return consistent error formats with status codes
3. Include request validation at the handler level
4. Log all errors with structured context
```
---
## Claude Skills vs System Prompts, CLAUDE.md, and MCP
One of the most common questions about Skills is how they compare to other ways of giving Claude instructions. Each approach serves a different purpose, and understanding the distinctions helps you pick the right tool for the job.
### System prompts
System prompts apply broadly to every conversation. They are useful for persistent preferences and baseline behavior, but they aren't task-aware. Everything in a system prompt loads every time, regardless of whether it's relevant to the current task. For teams with complex workflows, this creates a constant trade-off between thoroughness and token efficiency.
### CLAUDE.md files
CLAUDE.md files provide project-level context that lives in your repository. They work well for coding conventions, directory structures, and project-specific guidelines. However, they are static and load fully into context at the start of every session. They also don't compose easily across multiple projects or teams.
### MCP (Model Context Protocol)
MCP handles connectivity. It gives Claude access to external tools and data sources through a standardized protocol. Think of MCP as the bridge between Claude and the systems where your data lives: databases, APIs, Google Drive, GitHub, and more. MCP tells Claude what it can reach, and [our guide to MCP in Claude Code](/blog/claude-code-mcp) covers this in depth.
### Where Skills fit
Skills fill the gap between connectivity and competence. MCP gives Claude access to your tools. System prompts and CLAUDE.md give Claude broad context. Skills teach Claude how to approach [specific tasks with the right steps](/blog/spec-driven-development), constraints, and edge cases accounted for. Because Skills load dynamically based on relevance, they avoid the context bloat that comes with front-loading everything into a system prompt or CLAUDE.md file.
| Feature | Skills | System Prompts | CLAUDE.md | MCP |
|---------|--------|---------------|-----------|-----|
| What it provides | Procedural knowledge | Baseline behavior | Project context | Tool connectivity |
| Persistence | Across conversations | Every conversation | Every session | Continuous connection |
| Context loading | On-demand (~100 tokens idle) | Always loaded | Always loaded | Always available |
| Task-aware | Yes | No | No | No |
| Shareable | Yes (open standard) | Per-conversation | Per-project | Per-configuration |
| Can include code | Yes | No | No | Yes |
---
## Why Claude Skills Matter for Builder Teams
There is a pattern that shows up consistently in teams using AI coding tools at any real scale. One engineer figures out the right way to handle a tricky workflow, such as how to validate schemas before running database migrations, or which steps to follow when deploying to staging. That knowledge lives in their head, or maybe in a Slack thread that nobody will be able to find again in six months.
Skills turn that kind of institutional knowledge into a reusable, versioned artifact. The engineer writes a Skill once, commits it to the repository, and everyone on the team benefits from it automatically whenever Claude works on a related task. The knowledge compounds over time instead of evaporating after each session.
For organizations on Team or Enterprise plans, admins can provision Skills across the entire workspace. This means security review procedures, coding standards, deployment checklists, and compliance workflows can all be distributed through Skills without requiring each team member to configure anything individually.
In December 2025, Anthropic expanded Skills with organization-wide management and launched a [Skills directory](https://github.com/anthropics/skills) with partner-built Skills, making it easier to find and adopt community-created workflows. In January 2026, they followed up with a [comprehensive 32-page guide to building Skills](https://resources.anthropic.com/hubfs/The-Complete-Guide-to-Building-Skill-for-Claude.pdf), covering everything from planning and design to testing and distribution.
---
## Getting Started with Claude Skills
If you're using Claude Code, you can start building Skills today. The structure is lightweight: create a folder, add a `SKILL.md` file with a short YAML header and your instructions in Markdown. Basic Skills require no code at all, though you can bundle executable scripts for more advanced behavior.
Skills can live in three places depending on who needs them:
- **Personal** (`~/.claude/skills/`): Available across all your projects
- **Project** (`.claude/skills/`): Shared with your team via version control
- **Enterprise**: Managed organization-wide through admin settings
The [Claude Code documentation on Skills](https://docs.anthropic.com/en/docs/claude-code/skills) covers the full configuration reference, including frontmatter options, argument passing, dynamic context injection, and how to run Skills in subagents.
---
## Frequently Asked Questions
### Are Claude Skills free to use?
Skills are available on all paid Claude plans. On Claude.ai, that includes Pro, Max, Team, and Enterprise. In Claude Code, Skills work regardless of plan since Claude Code has its own [usage-based pricing](/blog/claude-code-pricing). There is no additional cost for creating or using Skills beyond your existing Claude subscription.
### Can Claude Skills run code and scripts?
Yes. Skills can include executable scripts in any language, such as Python or Bash, inside a `scripts/` directory within the Skill folder. Claude runs these scripts when the Skill's instructions reference them. This is useful for tasks like generating HTML reports, validating data, or running build steps as part of a workflow.
### Do Claude Skills work outside of Claude Code?
The Skill format follows the [Agent Skills open standard](https://agentskills.io/), which is designed to be portable across different AI tools. Claude Code, Claude.ai, and the Claude API all support Skills natively. Other tools that adopt the open standard can also use the same `SKILL.md` format, though feature support may vary by platform.
### Is there a limit on how many Skills I can have?
There is no hard limit on the number of Skills you can make available. Because Skills use progressive disclosure, only the metadata (about 100 tokens per Skill) loads into context at any given time. Full instructions load only when a Skill matches the current task, so having many Skills doesn't meaningfully increase token usage or slow Claude down.
### Can I share Skills with my team?
Yes, in several ways. Project-level Skills stored in `.claude/skills/` can be committed to version control and shared through your repository. On Team and Enterprise plans, organization admins can provision Skills across the entire workspace so every team member has access automatically. Anthropic also maintains a [public Skills directory](https://github.com/anthropics/skills) with community and partner-built Skills you can adopt.
### What is the difference between a Skill and a custom slash command?
In Claude Code, custom slash commands (stored in `.claude/commands/`) and Skills (stored in `.claude/skills/`) both create `/slash-command` shortcuts. Skills are the newer format and support additional features like automatic invocation based on task relevance, supporting files and scripts, and YAML frontmatter for fine-grained configuration. Existing command files continue to work, but Anthropic recommends Skills for new workflows.
---
If you want to go deeper on how Skills fit into a structured development workflow, read our post on [spec-driven development](/blog/building-braingrid-with-braingrid), which covers how we ship features in under an hour using a process that Skills are well-suited to encode.
---
# How I Vibe Coded a SaaS MVP in a Weekend (Step by Step)
Source: https://www.braingrid.ai/blog/vibe-coding-a-startup-idea
Published: 2026-02-18T12:00:00Z
I spent a week hunting for a SaaS idea I could build in a weekend. Following the tips in our post, [How to Get SaaS Product Ideas](/blog/saas-product-ideas), I lurked on [IdeaBrowser](https://ideabrowser.com) -- a site that posts a scored startup idea every day.
None of the ideas resonated with me. But I dutifully read every line of the proposals. One of the tips that other founders recommend is solving a problem that you have faced. "Benefits finder for seniors" -- I don't know anything about senior benefits. But the pattern grabbed me: helping people navigate unfamiliar systems. That's when I remembered my own move to the UK.
When I landed in the UK in 2020, it was the height of the pandemic. I had my visa -- but I needed NHS numbers, driver's licenses, utilities, banking. Nobody tells you how any of it works. What if there was an app for that?
Let's build an immigration concierge application that helps people moving to a new country navigate the processes and systems.
The idea is clear. But how do you go from concept to working app without engineering experience?
## How will we get started?
[Vibe coding tools](/blog/best-vibe-coding-tools-2026) now let non-coding founders build SaaS MVPs. You describe what you want in plain English. The tool builds it. But AI tools sometimes give bad advice or incorrect information. The best way to get good results is through clear, precise prompting.
The same holds for writing software. Just type what you want and the bot builds it. But AI agents can't read your mind. Leave out one crucial detail and the entire feature gets built wrong. When I build without planning, I focus on getting something I can see -- rather than building a foundation for future growth. Sometimes this works, but other times everything feels patched together and the code looks rickety.
To build my SaaS, I want to start with a solid foundation -- even if it means I won't see a working UI right away. Rather than jumping in and building a tool that works for the UK, we need a foundation: the ability to add many countries. Billing is easier to wire in early. Should there be an admin panel to change and add features?
These are the essential "behind the scenes" pieces that let you scale. Build them now, and adding your second country takes hours instead of weeks. But am I missing anything else? I could really use a product manager to help me flesh out any other pieces I'm missing.
### Product Management
In larger organizations, a product manager takes each idea, turns it into a story, and builds requirements for the development team. This process takes hours of meetings -- refining ideas, debating edge cases, clarifying scope -- but it works. The better everything is spelled out in the requirements, the better the first version of the software will be.
But it's just me, my laptop, and my idea. How do I get that same rigor without the hours of meetings? I'll use [BrainGrid](https://www.braingrid.ai) to turn my prompts into requirements and tasks. BrainGrid's AI Product Planner takes my prompts and adds details I wouldn't have thought of -- fewer meetings, better specs, less rebuilding. That's [spec-driven development](/blog/spec-driven-development).
## What Does the MVP Actually Look Like?
My initial prompt to BrainGrid describes the task I want to undertake:
```text
Help me create a product plan for: internationalConcierge
International concierge. When I moved to the UK - I got my visa, and was allowed to enter the country. I rented a place to live. But there was no manual on what to do next. How do I get my NHS number (did you know there are 2 NHS numbers you need?). How do I get private insurance? A drivers license? Banking? What else to do arrivals to a new country need to become assimilated into the system.
Im imagining an app that would compile checklists for new arrivals to a country, available as a subscription (for individuals) or sold to companies - who move many employees to a new country. Let's spec out a web application that helps newcomers to a country learn how to navigate the systems that are new to them.
```
If I had jumped straight into [Claude Code](/blog/claude-code-mcp), it would have built a UI just for the UK. That looks great... until you want to add the US, Canada, or Australia. Then you realize [you've created a vibe coded mess](/blog/i-built-a-vibe-coding-mess) -- no database structure for multiple countries, no admin panel. You'd be forced to rebuild everything.
BrainGrid took my rough idea and created an Epic user story (EPIC-1) -- a high-level feature that groups related requirements. The full epic lives in the [GitHub repository](https://github.com/dougsillars/internationalConcierge/blob/main/braingrid/epic1). Here's the one-line synopsis: "Help people relocating internationally get set up in their new country by providing clear, country-specific checklists for healthcare, banking, licensing, and insurance." The Epic described exactly what I'm hoping to build.
With the Epic created, BrainGrid is ready to create requirements documentation to make the epic come to life.
With just one click, BrainGrid begins creating the requirements for the epic user story. After a few minutes, it has come up with 5 requirements:
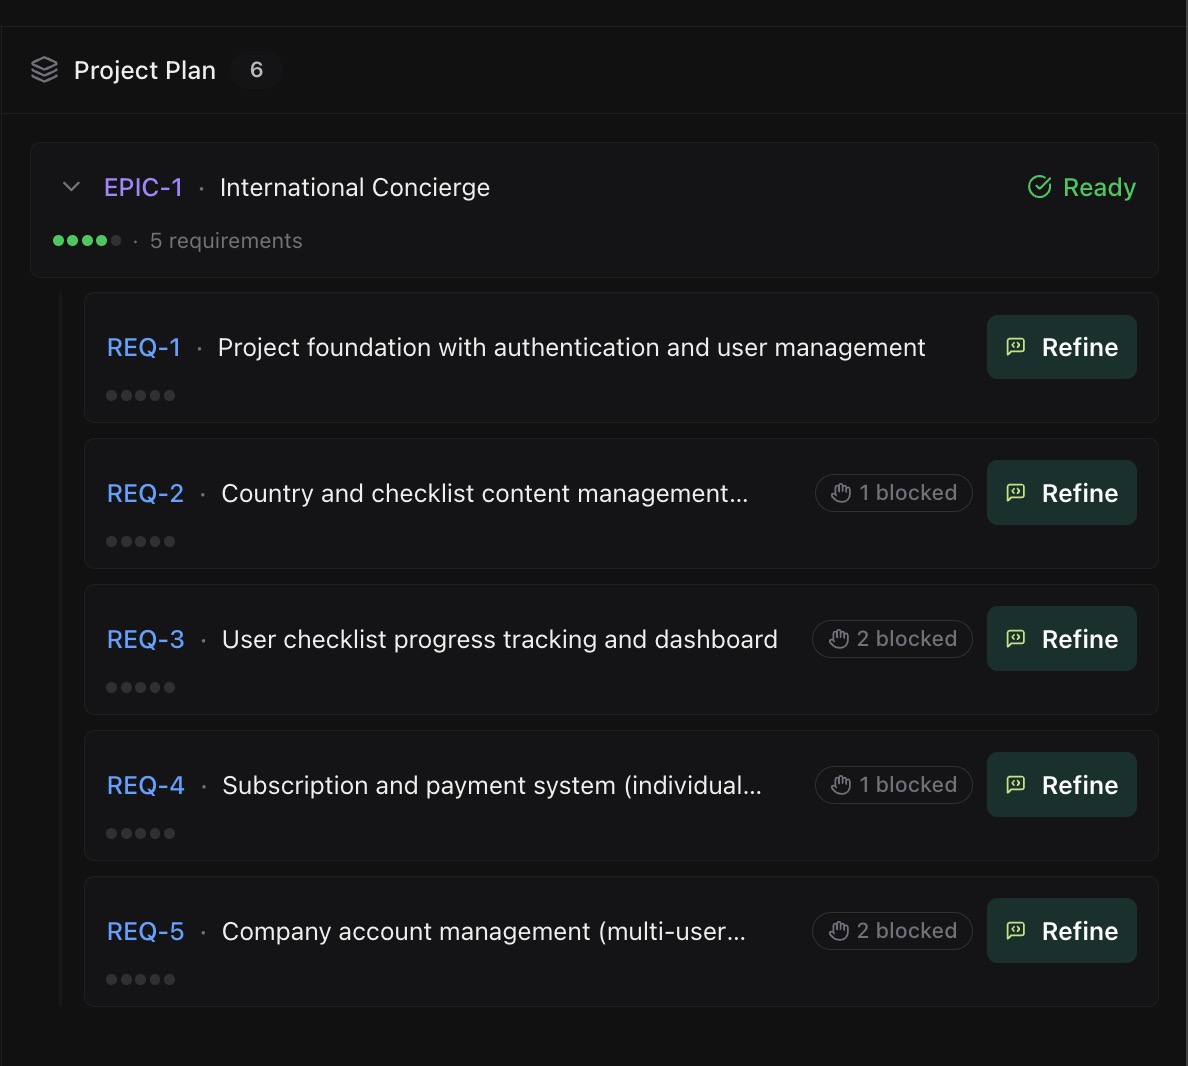
We can see from the requirement names that BrainGrid is thinking about storage, multiple countries, checklists, payments, and enterprise account management. The glue that holds it all together -- but not the stuff you think about off the bat.
This foundation will make expanding the application an organic process rather than a lot of band-aid fixes for stuff I would have initially missed.
Now comes the fun part: turning these requirements into working code.
## Vibe Code the MVP
Once we have the requirements, you can read each requirement and make any changes you need (the REFINE step). With the first few requirements in EPIC-1, there are no changes needed. Once you have refined (or just approved the requirement), we can Start Building.
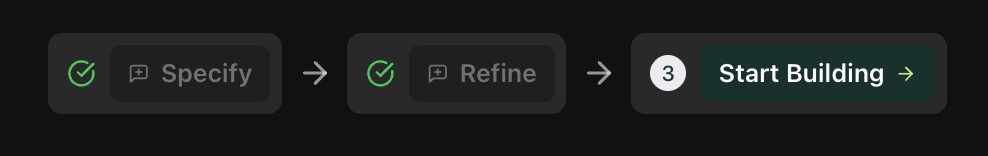
In this step, BrainGrid takes your detailed requirement and breaks it down into tasks -- the steps required to build the requirement into my application. This is similar to a sprint planning meeting (where dev teams break features into technical tasks).
BrainGrid follows these steps:
* Phase 1: Gather Context
* Phase 2: Plan Tasks
* Phase 3: Create Tasks
Instead of an exhausting multi-hour meeting with the whole team, BrainGrid builds out the tasks required to complete the requirement in just a few minutes.
I will build my application using Claude Code. I have [connected BrainGrid to Claude](https://docs.braingrid.ai/mcp-server/installation), so Claude can just read the tasks that have been created.
Each of the requirements for EPIC-1 generate around 10 tasks to be completed. BrainGrid creates a summary describing the 10 tasks, why they are important, what they do, and why the order of the tasks matters:
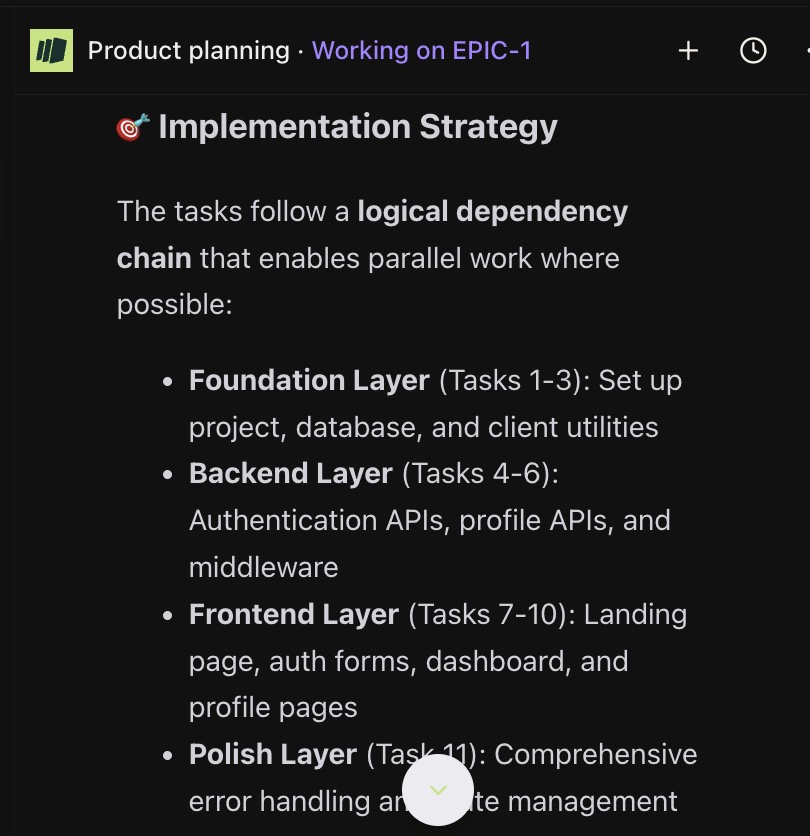
BrainGrid also documents "highlights" in the tasks:
This early on, I would not be thinking about error messages or responsive design. But with BrainGrid, it's all in there. There is also an implementation guide to make sure the steps are followed properly and everything is completed as expected:
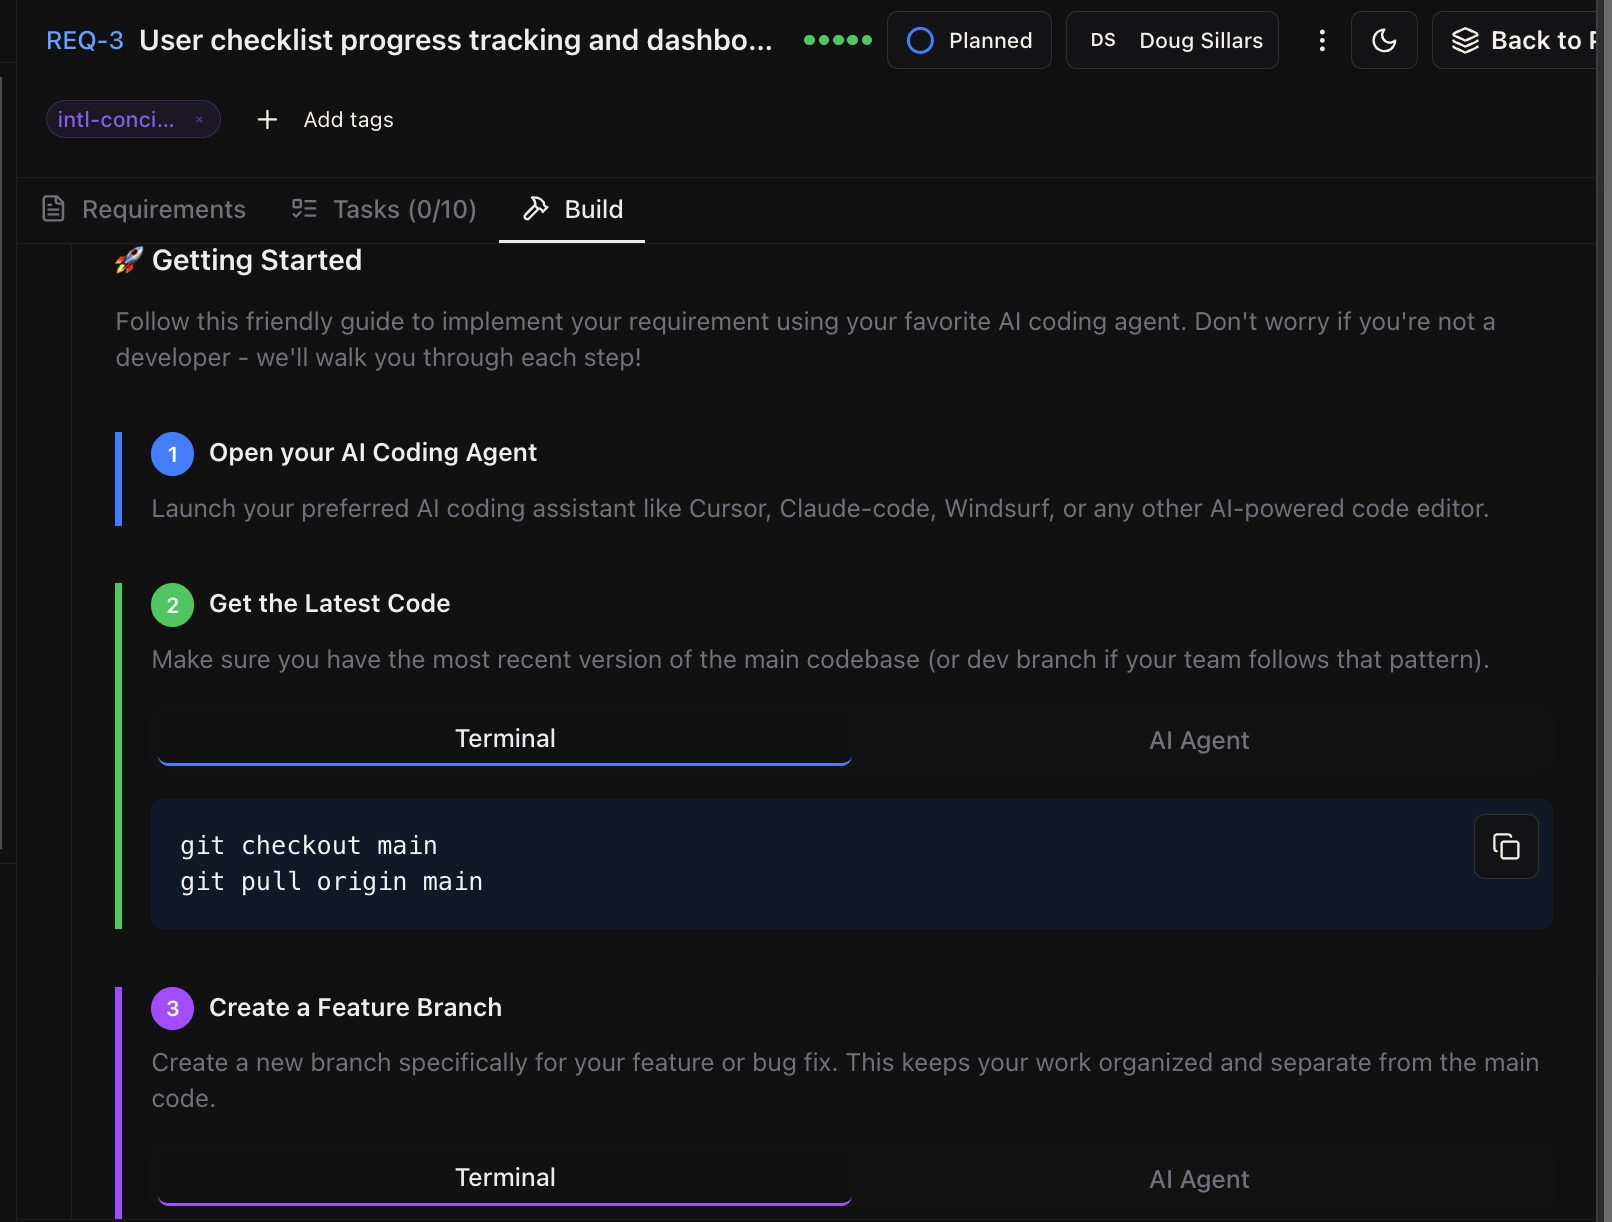
At the end of the implementation guide, BrainGrid gives you a command to audit the acceptance criteria:
```bash
acceptance review https://github.com/[YOUR-REPO]/pull/[PR-NUMBER] against REQ-3
```
BrainGrid and Claude check the requirements and test the code to ensure it meets the acceptance criteria. Claude generates a report showing the criteria were met. This closes the loop: spec, code, validation, ship.
### Building progress
I created EPIC-1 on a Friday afternoon, and BrainGrid/Claude created the requirements and tasks. Friday evening, while streaming a movie, all of the tasks for requirements 1&2 were completed.
Progress is being made -- it's nothing beautiful yet, but with minimal effort on my part, feeding the BrainGrid tasks into Claude Code has created the outlines of a great looking product.
I continued this process through the 5 requirements for EPIC-1. Upon completion, I have a fully working MVP prototype -- ready to show potential customers and collect early feedback. (To get the application to work, I did run database migrations at Supabase (Claude Code provided the SQL for these), but I did not complete the Stripe integration.)
I upgraded my email to become an admin, adding an admin button to the dashboard. Admins can add new countries (note that the UI automatically added the flag next to the name of the country):
Admins can also add and edit items in the checklist:
If you have a company, you can add seats and invite employees who are moving to a new country to join the site:
## What I Learned from building a SaaS with BrainGrid
I have built many small applications with vibe coding tools. Scripts to pull API data, Discord bots. Very simple applications that can be described in a couple of sentences. But building a full SaaS application is a bigger deal.
One of the suggestions given by successful SaaS builders is to "look at the unsexy." In many ways, BrainGrid began the development of my application by looking at the not-sexy stuff: databases, libraries, integrations. It isn't fun to build. It isn't glamorous. But without it, the application would not have functioned the way I wanted it to.
I certainly would not have thought about an admin panel for the developers to add new countries or tasks. And the enterprise login, with different invites and seats, would have taken me days to flesh out before even building. It's probably not *exactly* what I want -- but I can now work with BrainGrid and Claude Code to optimize from a completed MVP.
### What Surprised Me
I started this project on a whim. The fact that in just a few hours I could reach this level of complexity astounded me. Clearly the checklist data is simplistic and would require research to get the correct details -- but the app itself is built! Editing from "Lorem Ipsum" data points means I'd be working in the part of the application where I have expertise -- not joining database tables or figuring out why Stripe isn't working properly.
If you are a SaaS builder, and want to build your app with Vibe coding tools, you can! But adding BrainGrid into the mix is an added superpower: AI product planning on top of the Vibe coding tools means better code - faster. Try [BrainGrid](https://www.braingrid.ai) when you begin building your SaaS MVP.
## Frequently Asked Questions
### What is an immigration concierge service?
An immigration concierge service helps people navigate the practical systems of a new country -- healthcare registration, driver's licenses, banking, utilities, and other processes that locals take for granted. Unlike visa and legal immigration services, a concierge focuses on post-arrival setup, guiding newcomers through unfamiliar bureaucracies step by step.
### How do I find startup ideas using AI tools?
AI idea generators like [IdeaBrowser](https://www.ideabrowser.com) deliver a scored startup idea daily, evaluated on Opportunity, Problem, Feasibility, and timing. Use these ideas as springboards, not blueprints. Strip the idea to its core pattern, then map that pattern onto a domain you personally understand. Your experience is your competitive advantage.
### Can I vibe code a SaaS product without engineering experience?
Yes. [Vibe coding tools](/blog/best-vibe-coding-tools-2026) like Cursor, Claude Code, and Lovable let non-engineers build working products by describing what they want in plain English. The key is writing clear specs before you start. BrainGrid's product planner AI pushes the vibe coding tools to create real specifications and detailed tasks.
### What are the best AI startup idea generators?
[IdeaBrowser](https://www.ideabrowser.com) delivers daily scored ideas with market analysis. [ValidatorAI](https://validatorai.com) scores and validates existing ideas. [IdeaProof](https://ideaproof.io) provides AI-powered market research. For broader research, [Y Combinator's Request for Startups](https://www.ycombinator.com/rfs) lists investor-validated problem categories.
### How much does it cost to vibe code an MVP?
With AI coding tools, the primary costs are tool subscriptions ($20-100/month for Cursor, Claude Code, etc.) and your time. A focused MVP like an immigration checklist can be built in a weekend with $50-100 in tool costs. The bigger investment is content research and validation -- budget more time for research than for coding.
---
# Builder Story: Saymon and Core Care
Source: https://www.braingrid.ai/blog/builder-story-saymon-core-care
Published: 2026-02-10T14:30:00Z
> "The feeling I have when using BrainGrid is that I have a PM with me."
- Saymon
## Background: The Senior Engineer Gone Solo
### Who is the builder?
Saymon is a software engineer from Brazil with eight years of professional experience. He has led teams of eight at top agencies, shipped features for apps with more than 9 million daily active users, and taken products from concept to seed funding. For the past two years, he has worked as an independent consultant, helping companies launch MVPs, secure funding, improve code quality, and develop growth strategies.
Saymon is not a vibe coder learning to build. He is a senior engineer who already knows how to build, and who recognized that the bottleneck was never the code itself.
### The Shift to Agentic Development
About a year and a half ago, Saymon made the transition to an agentic workflow. He describes it like the jump from JavaScript to TypeScript — a J-curve where the upfront investment pays off dramatically.
His conviction was simple: writing code is not really what a software engineer should be doing. Solving problems through software is. When tools like Cursor and Claude Code matured enough to handle the writing, Saymon shifted his energy to where it mattered most: research, architecture, and decision-making.
### His Development Setup
Saymon's current stack is built for speed and cost-efficiency:
- **IDE:** Cursor
- **Primary coding agent:** Claude Code (Opus 4.5 for most tasks, Sonnet 4.5 for large-context work requiring the million-token window)
- **Research:** Gemini Deep Research as his go-to, supplemented by Claude Code research and GPT Deep Research
- **Planning and specs:** BrainGrid
He still reads and reviews every line of code. But he no longer writes most of it.
## Vision: Taking Care of the People Who Take Care of Others
### What is he building?
Saymon is building **Core Care**, an all-in-one application for therapists in Brazil. The platform covers patient management, financials and payment handling, telemedicine, and one-on-one video sessions. As Saymon describes it, it is essentially seven startups consolidated into a single product.
### Who is it for?
Core Care targets therapists in the Brazilian market first, with a long-term vision to go global. Saymon describes the mission clearly: "Take care of the people who take care of others."
### What does it solve?
Therapists currently juggle fragmented tools for scheduling, billing, patient records, and telehealth. Core Care brings everything into one platform so they can focus on their patients instead of their software stack.
### Long-term vision
From day one, Core Care has been architected with internationalization and globalization built in. Saymon is not building a local tool. He is building a platform designed to scale globally from its foundation.
## The Turning Point: Choosing BrainGrid
### The pain point: Product thinking without a product team
As a solo consultant working across multiple client projects, Saymon faced a recurring problem. He had access to great product management tools, but they had no awareness of the codebase. He had powerful coding agents, but they did not understand product context. He was the bridge between the two, and that bridge was expensive.
When working across different projects, he would have to context-switch constantly. If he needed to understand how something worked in a project that was not on his machine, he had to ask another developer to research it and report back. The gap between planning and engineering was real, and it cost hours every week.
Saymon tried building his own system. He tried multiple existing solutions. None of them bridged both sides — product management context and codebase awareness — in a single tool.
Then he found BrainGrid, joined the waitlist, and started using it.
### What made BrainGrid different
BrainGrid gave Saymon something no other tool could: the ability to do requirements planning and task breakdown **with knowledge of the codebase**. It combined the product management layer with engineering awareness so he no longer had to be the translator between the two worlds.
> "It is the same as having all the tools that I need for product management and also all the tools that I need for understanding at least the code base."
## How BrainGrid Changed His Workflow
### From organizing to decision-making
The biggest shift was not speed. It was where Saymon spent his time. Before BrainGrid, a large portion of his hours went to organizing: writing tasks, defining acceptance criteria, structuring plans. Necessary work, but as Saymon admits, "sometimes boring."
BrainGrid removed the boring part. What remained was pure decision-making. Saymon now spends his time evaluating options, refining architecture, and making calls. Not formatting Jira tickets.
> "It removes the boring part. It's just decision-making. Okay, yeah, let's do things this way."
### His BrainGrid workflow in practice
Saymon's process follows a clear pattern:
1. **Understand the problem.** Whether it is a client project or Core Care, he starts by deeply understanding the need and the problem being solved.
2. **Research.** He studies how other companies and apps solve similar problems, cross-referencing with his own experience.
3. **Architecture.** He sketches the high-level approach, including what to build and in what order.
4. **Spec with BrainGrid.** He brings his architecture into BrainGrid and asks it to help create specifications. BrainGrid solves the blank-page problem and produces a first draft that Saymon then reviews and refines.
5. **Task breakdown.** BrainGrid generates granular tasks with acceptance criteria. Saymon uses BrainGrid's MCP and CLI within Claude Code to pull tasks directly into his agent.
6. **Pre-task enrichment.** Before executing, Saymon layers additional context onto each task. That means Supabase checks for database tasks, design system consistency prompts for UI tasks, and API validation for backend routes.
7. **Test flow generation.** Based on the tasks, Saymon uses BrainGrid to generate the complete set of test flows he will need for QA. One recent feature produced 25 tasks and 13 distinct testing flows.
8. **Implementation.** He runs each task through Claude Code, reviews the output, and moves to the next.
9. **QA and review.** AI-assisted code review catches issues and bugs, followed by manual QA against the flows generated earlier, then automated tests.
## Outcomes: Faster, More Organized, Higher Quality
### A client feature that generated $1 million in revenue
One client came to Saymon with a hard deadline for a feature that would enable a major event. The challenge: eight interconnected apps that needed to work together, with architecture decisions that would determine long-term maintainability.
Without BrainGrid, the research and planning alone would have taken two full days of six to seven hours each. With BrainGrid, Saymon had a working plan in 30 minutes. He spent the rest of the day refining it.
The result: a feature that would have taken three to four weeks was delivered in just over two weeks. The client used it for an event that generated **$1 million in revenue**.
### A side-by-side quality comparison
Saymon ran his own experiment. He built the same SaaS MVP twice:
- **Without BrainGrid:** Two days to a working MVP using Claude Code with direct prompting. The code was messy, lacked structure, and would require significant refactoring to maintain.
- **With BrainGrid:** Four extra hours of upfront planning, then a similar two days of coding. But the result had more features, a cleaner architecture, and code that was far easier to maintain and extend.
The difference was not just speed. It was confidence.
> "I move with confidence on my own code."
### The feeling of having a PM
For Saymon, the most meaningful change is not a metric. It is a feeling. As an individual contributor, he finally has the experience of working with a product manager — someone (or something) that handles the tedious but critical work of organizing requirements, writing acceptance criteria, and maintaining structure.
For his consulting work, the impact extends to teams. BrainGrid closes the gap between product managers and engineers, making both more productive. It is not replacing either role. It is making the handoff seamless.
> "What BrainGrid is helping with is closing the gap between the engineers and the product managers and making both of them more productive."
## What He Wants Next from BrainGrid
Saymon's feature request is focused on adoption and accessibility:
**IDE integration without requiring GitHub access.** When working as a consultant across multiple client projects, getting GitHub access for each organization adds friction. Having BrainGrid integrated directly into the IDE — similar to how Cursor or Slack adopted bottom-up strategies — would make onboarding new engineers and new projects dramatically easier.
It is the kind of feedback that comes from someone managing multiple teams across multiple codebases, where every step of setup friction multiplies across every project.
## Final Thoughts
Saymon's story is not about learning to code with AI. It is about a senior engineer who already knew how to build and found the missing layer that let him operate like a full product team.
With BrainGrid, he is not just building faster. He is building more organized, more maintainable software — and shipping features that drive real business outcomes.
Core Care is just getting started, but the foundation is built for global scale. And Saymon has the workflow to match.
Check out Core Care, coming soon to therapists in Brazil and beyond.
---
# Building BrainGrid with BrainGrid: Spec-Driven Development with Claude Code
Source: https://www.braingrid.ai/blog/building-braingrid-with-braingrid
Published: 2026-02-10T12:00:00Z
*How we ship features in under an hour — from half-baked idea to tested, deployed code.*
## 48 Minutes
Here's what a typical feature build looks like for us:
```text
10:02 /specify "Add time range filter to credits health dashboard"
10:03 → REQ-287 created with 8 acceptance criteria
10:03 /build REQ-287
10:03 → Branch: feature/REQ-287-time-range-filter, 5 tasks linked
10:04 → Task 1: Add date range picker component (in progress)
10:11 → Task 1 complete, validation passed
10:11 → Task 2: Update API endpoint with date params (in progress)
10:18 → Task 2 complete, validation passed
...
10:42 → All 5 tasks complete, yarn validate:fix passes
10:42 → PR created: "feat: add time range filter to credits health dashboard (#1287)"
10:43 → braingrid requirement review
10:44 → 8/8 acceptance criteria validated against PR diff
10:45 → Code review approved, merged to dev
10:46 → Agent writes test spec: time-range-filter.md
10:47 → agent-browser opens dev deployment
10:48 → Database seeded with test data for known date ranges
10:48 → agent-browser navigates to dashboard, selects "Last 7 days"
10:49 → agent-browser snapshots table, verifies filtered results
10:50 → Database query confirms filter matches actual data
10:50 → Test spec updated: status: PASSED
```
48 minutes. Idea to tested, merged feature. The spec took 60 seconds. The human reviewed diffs, approved the PR, and made one adjustment to a component's padding. The test ran against the live dev deployment — not a mock, not a stub — with real data verified at the database level.
Every feature in BrainGrid is built this way. Not as a marketing exercise — because it's the fastest workflow we've found. This post explains how it works.
## The Problem
[Vibe-coding](/blog/i-built-a-vibe-coding-mess) works until you merge it, deploy it, and realize you forgot the error state. Or the loading state. Or what happens when the user has zero credits and clicks the button anyway.
You didn't think about those cases because you're moving fast — and that's fine for prototypes. But the AI didn't think about them either, because you never told it to. It built exactly what you described: the happy path. Everything else is missing.
The fix isn't to slow down or stop using AI. It's to give the AI a requirement that *already thought through* the edge cases, error handling, and loading states — so you don't have to. The AI that writes your spec thinks like a [product engineer](/blog/what-is-a-product-management-agent). It asks the questions you'd skip. The AI that implements the spec executes like a production software engineer, because that's what a professional requirement demands.
That's the entire philosophy: **[start with requirements, not code](/blog/spec-driven-development).**
## The Workflow: Four Commands
### 1. `/specify` — Turn an idea into a requirement
```bash
/specify "Trial users should see upgrade prompt instead of buy credits when out of credits"
```
AI refines your one-liner into a structured requirement. Here's what REQ-375 looked like after `/specify`:
```text
REQ-375: Trial users should see upgrade prompt instead of buy credits
Problem:
Trial organizations see the same credit exhaustion messaging as paid orgs,
offering "Top-up credits" — but trial users can't purchase credit packs.
Solution:
Detect trial status, display trial-appropriate messaging with only the
upgrade CTA. Paid orgs continue seeing both options.
Components to modify:
- out-of-credits-banner-wrapper.tsx (fetch subscription status)
- out-of-credits-banner.tsx (conditional render by trial status)
- low-credits-banner.tsx (agent overlay variant)
Acceptance Criteria:
✓ Trial org + 0 credits → top banner shows "Your trial has run out
of credits" with only "Upgrade plan" button
✓ Trial org + 0 credits → agent overlay shows "Upgrade now" only
✓ Paid org + 0 credits → shows both "Top-up credits" and "Upgrade plan"
✓ Trial org + 1-50 credits → standard low credits message (not trial-specific)
✓ Loading state → show paid behavior until trial status confirmed
✓ Error state → fall back to paid behavior, log error
✓ Status changes reflect consistently across both banners
```
That's condensed. The full requirement also included a data fetching strategy (React Query with 5-minute stale time), props interfaces, error/loading state specifications, and a message variation table mapping every condition to its banner variant, message copy, and CTA buttons.
A well-structured requirement has these components:
- **Problem statement** — what's broken or missing, in user-facing terms
- **Solution summary** — the approach, not the implementation
- **Scope** — which files/components are affected (so the AI doesn't wander)
- **Acceptance criteria** — testable given/when/then conditions that define "done"
- **Edge cases and error handling** — loading states, failures, boundary conditions
- **Out of scope** — what this requirement deliberately doesn't cover
The AI generates all of this from a single sentence. You type one line, the AI writes the full spec — problem statement, acceptance criteria, edge cases, scope — and you review it. Most of the time it's 80% right. You fix the 20%, move on. We catch bad specs about 20% of the time — the AI assumed a modal instead of inline editing, or missed an auth check, or scoped too broadly. Editing a spec takes seconds. Debugging a wrong implementation takes an hour.
### 2. `/breakdown` — Turn the spec into tasks
```bash
/breakdown REQ-375
```
This is more than "split the work into chunks." The AI assembles context from three sources: the full requirement (acceptance criteria, edge cases, technical decisions), your codebase structure (repository analysis, file tree, existing patterns), and related documentation. It then generates atomic implementation tasks — each scoped to a single concern — with explicit dependencies between them. The AI knows which files exist, which hooks and components are already in your codebase, and how they're structured.
Here are the actual tasks generated for REQ-375:
```text
TASK-1: Create useSubscriptionStatus hook
→ New hook: src/hooks/use-subscription-status.ts
→ Fetch from /api/organizations/[orgId]/subscription
→ React Query: cache key ['subscription-status', orgId], staleTime 5min
→ Return { isTrialSubscription, isLoading, error }
→ On error: default isTrialSubscription to false (safe fallback)
TASK-2: Update out-of-credits-banner with trial support
→ File: src/components/out-of-credits-banner/out-of-credits-banner.tsx
→ Add isTrialSubscription: boolean prop
→ Trial + 0 credits: render "Your trial has run out of credits" + "Upgrade plan" only
→ Paid + 0 credits: keep both "Top-up credits" and "Upgrade plan" (existing behavior)
TASK-3: Update out-of-credits-banner-wrapper
→ File: src/components/out-of-credits-banner/out-of-credits-banner-wrapper.tsx
→ Call useSubscriptionStatus hook
→ Pass isTrialSubscription to banner component
→ While loading: default to paid behavior (no flicker)
TASK-4: Update low-credits-banner with trial support
→ File: src/components/agent/agent-pane/low-credits-banner.tsx
→ Trial + 0 credits: show "Upgrade now" only
→ Trial + 1-50 credits: standard "You have only X credits left" (not trial-specific)
TASK-5: Run validation
→ yarn validate:fix (type-check + lint + format + test)
```
These aren't vague tickets. They're prompts — each one tells the agent exactly which file to modify, which pattern to follow, which prop to add, and what the expected behavior should be. The spec already made the design decisions (cache key, stale time, fallback behavior), so the tasks are pure execution.
### 3. `/build` — Start implementing
```bash
/build REQ-375
```
This runs a four-step flow:
1. **Fetches the build plan** from BrainGrid with requirement details and the full task array
2. **Creates a feature branch** — `feature/REQ-375-trial-upgrade-prompt` — and associates it in BrainGrid so everything is linked
3. **Creates and links tasks** in Claude Code, connecting each to BrainGrid so status syncs automatically
4. **Starts implementing the first task immediately** — no "shall I proceed?" prompts
The agent picks up tasks sequentially — implements the code, runs `yarn validate:fix`, and if validation passes, marks the task complete and moves to the next. If validation fails, it reads the error, fixes the issue, and re-runs before moving on. You watch in real time and course-correct when needed.
You can steer focus by appending instructions: `/build REQ-375 start with the data fetching hook` — Claude adjusts task priority accordingly.
### 4. `braingrid requirement review` — Validate acceptance criteria against the PR
```bash
braingrid requirement review
```
This is where the spec earns its keep. The command auto-detects the requirement from the branch name and the PR number from git, then uses AI to perform the review. It fetches the PR diff from GitHub and the full requirement with acceptance criteria from BrainGrid, then the AI reasons about whether each criterion is satisfied by the actual code changes — tracing criteria to specific lines in the diff:
```text
Reviewing PR #1288 against REQ-375...
Acceptance Criteria:
✅ Trial org + 0 credits → banner shows "Upgrade plan" only
→ out-of-credits-banner.tsx:42 — conditional render on isTrialSubscription
✅ Paid org + 0 credits → shows both buttons
→ out-of-credits-banner.tsx:38 — default branch renders both CTAs
✅ Loading state → paid behavior until status confirmed
→ out-of-credits-banner-wrapper.tsx:18 — isTrialSubscription defaults to false
✅ Error state → fallback to paid behavior
→ out-of-credits-banner-wrapper.tsx:22 — catch block sets isTrialSubscription = false
...
7/7 acceptance criteria validated.
```
Did the implementation miss an edge case? Is there a criterion with no corresponding code change? You find out before the PR merges, not after users report a bug.
Here's what it looks like when a criterion fails — say the agent implemented the top banner but forgot to update the agent overlay:
```text
Reviewing PR #1288 against REQ-375...
Acceptance Criteria:
✅ Trial org + 0 credits → banner shows "Upgrade plan" only
→ out-of-credits-banner.tsx:42 — conditional render on isTrialSubscription
❌ Trial org + 0 credits → agent overlay shows "Upgrade now" only
→ low-credits-banner.tsx — no trial-specific conditional found,
still renders standard "Top-up credits" CTA for all org types
✅ Paid org + 0 credits → shows both buttons
→ out-of-credits-banner.tsx:38 — default branch renders both CTAs
...
6/7 acceptance criteria validated. 1 failed.
```
The AI traces each criterion to specific lines in the diff. It's not grepping for keywords — it's reasoning about whether the code changes actually satisfy the criterion. It catches semantic gaps that compile and lint clean: a component that handles the trial state but renders the wrong CTA text, or an error fallback that works correctly but doesn't match the criterion's specified behavior. Where it *can't* catch you is runtime logic errors where the code reads correctly but behaves wrong — "the conditional exists but the boolean is inverted." That's exactly what the next layer is for.
## AI-Driven Testing
After the PR merges, testing follows the same pattern: AI writes the test, AI runs the test, humans review. This is the layer that catches what code review can't — behavioral bugs in the running application.
The agent writes a markdown test spec, then executes it by driving a real browser against the deployed app while verifying data at the database level:
```text
Test: Credits Top-Up with Stripe
──────────────────────────────────────────────────
Setup: Query initial balance → 1,998 credits
Step 1: agent-browser → navigate to /settings/billing
Step 2: agent-browser → click "Top-up credits", select $10 / 1,000 credits
Step 3: agent-browser → fill Stripe test card, click Pay
Step 4: agent-browser → wait for redirect, verify success message
Verify: Query final balance → 2,998 credits ✅
──────────────────────────────────────────────────
Result: PASSED
- Credits added to ORGANIZATION account (not USER)
- Transaction type: OVERAGE_PURCHASE
- Credits expire after 1 year
- Stripe event payload verified in events table
```
[agent-browser](https://github.com/vercel-labs/agent-browser) drives the actual user flow — clicking buttons, filling forms, navigating pages. MCP servers give the agent direct database access for setup and verification. The agent reads the spec, executes each step against the running app, and appends actual results including event payloads and database state changes it observed.
The defense is [layered](/blog/two-layer-ai-tool-validation): spec review catches missing implementations, requirement review catches criterion-to-code gaps, and browser tests catch behavioral bugs in the live app. The real gap — a bad spec *and* a bad test — is the same gap human engineering has. The difference is that every layer runs automatically.
## When It Breaks
The happy path is nice. Here's what happens when things go wrong.
**The spec itself is wrong.** This is the one failure mode no amount of automation catches — because every downstream layer executes the spec faithfully. If the spec says "show a modal" and you meant inline editing, the implementation will be correct *according to the wrong spec*. That's why `/specify` walks you through clarifying questions before generating the requirement, and why you review the spec before `/breakdown`. The human is the checkpoint. If you rubber-stamp a bad spec, everything downstream is on you.
**The AI misunderstands the spec.** Different from above — this is when `/specify` generates acceptance criteria that don't match your intent *and you catch it*. We catch bad specs about 20% of the time — the AI assumed a modal when we wanted inline editing, missed an auth requirement, or scoped too broadly. Editing a spec takes seconds. Debugging a wrong implementation takes an hour.
**A task fails validation.** The agent runs `yarn validate:fix` after every task. If types break or tests fail, it reads the error, fixes the code, and re-validates before marking the task complete. You see this happening in real time. If it gets stuck in a loop, you intervene — but that's rare because the task description already specified which patterns to follow.
**`requirement review` flags a gap.** A criterion shows no corresponding code change. The agent either missed it or decided it was out of scope. You see exactly which criterion failed and can either implement it or mark it as intentionally deferred.
**The test fails.** agent-browser snapshots the DOM and the agent reads the actual state. "Expected 'Upgrade plan' button, found 'Top-up credits' button." The error is usually obvious from the snapshot. The agent can fix the code and re-run, or you can investigate manually. Element refs (`@e1`, `@e2`) change after every page interaction, so the agent re-snapshots after each step — stale refs are the most common failure mode and the tooling handles it.
## Patterns Worth Stealing
These apply to any AI-assisted development workflow, with or without BrainGrid:
1. **Specify before building.** A few minutes of upfront clarity saves an hour of rework. This is the single highest-leverage thing you can do.
2. **Tasks are prompts.** Write task descriptions as if you're prompting an AI — because you are. Include file paths, patterns, and APIs.
3. **Automate the things humans forget.** Task status sync, validation, branch naming conventions. If the developer has to remember to do it, they won't.
4. **Validate against the spec, not just the code.** Code review catches bugs. Spec review catches missed requirements. Browser tests catch behavioral regressions. You need all three.
5. **The agent should just start.** After an explicit build command, don't ask "shall I proceed?" The user already expressed intent.
6. **Test against real infrastructure.** Database queries, browser interactions, deployed endpoints. Mocks hide bugs.
7. **Memory compounds.** Store learnings persistently. Your future self (and your agents) will thank you.
8. **Handle errors reactively.** Don't pre-check if every tool is installed. Run it and handle failure if it occurs.
## Try It in 5 Minutes
You don't need the full setup to start. The core loop — specify, break down, build — works with just three things:
```bash
## 1. Install the CLI
npm install -g @braingrid/cli
## 2. Create an account and authenticate
## → Sign up at app.braingrid.ai, then:
braingrid login
## 3. Initialize in your project
braingrid init
## 4. Open Claude Code, then type:
/specify "your feature idea here"
## 5. Break it into tasks
/breakdown REQ-XXX
## 6. Start building
/build REQ-XXX
```
That's it. No MCP servers, no hooks, no browser automation. Add those later when you want database verification, automated task sync, or AI-driven testing. Start with the spec.
## Under the Hood
The workflow runs on Claude Code with a few extensions. Everything above works out of the box. Everything below powers the full experience but is optional.
**Skills** are markdown files that teach Claude domain knowledge. They load automatically when relevant context is detected — you don't invoke them manually. We use `braingrid-cli` (the spec-driven workflow), `agent-browser` (E2E testing), [`frontend-design`](/blog/design-system-optimized-for-ai-coding) (UI that doesn't look AI-generated), and `memory` (persistent learnings via mem0).
**Hooks** run shell scripts in response to tool calls. Our most important hook: when Claude marks a task complete, a PostToolUse hook syncs the status to BrainGrid automatically. You never manually update a task tracker.
**[MCP servers](/blog/claude-code-mcp)** give Claude authenticated access to external services. Supabase for database queries — you control the scope (read-write on dev, read-only on production, or production off entirely — your call). Axiom for production logs (read-only). Playwright for browser automation. mem0 for persistent memory. When Claude needs to verify a migration, it queries the dev database directly. When it needs to test a flow, it drives a browser against the staging deployment. No context switching.
**Persistent memory** via mem0 stores learnings across sessions: "AuthKit login: wait 1500ms after email submit for password field." "Credit expiration cron uses `billing_anniversary_day`, not `created_at`." Before starting work, the agent searches memory. After discovering something reusable, it stores it. This compounds — month-old debugging insights surface exactly when needed.
---
## Links & Resources
### BrainGrid
- **Web App**: [app.braingrid.ai](https://app.braingrid.ai)
- **CLI (`@braingrid/cli`)**: [npmjs.com/package/@braingrid/cli](https://www.npmjs.com/package/@braingrid/cli)
- **GitHub**: [github.com/BrainGridAI/braingrid](https://github.com/BrainGridAI/braingrid)
- **Documentation**: [braingrid.ai](https://docs.braingrid.ai)
### Claude Code
- **Claude Code**: [docs.anthropic.com/en/docs/claude-code](https://docs.anthropic.com/en/docs/claude-code/overview)
- **Skills**: [docs.anthropic.com/en/docs/claude-code/skills](https://docs.anthropic.com/en/docs/claude-code/skills)
- **MCP (Model Context Protocol)**: [modelcontextprotocol.io](https://modelcontextprotocol.io)
### Tools
- **Vercel agent-browser**: [github.com/vercel-labs/agent-browser](https://github.com/vercel-labs/agent-browser)
- **mem0 (Persistent Memory)**: [github.com/mem0ai/mem0](https://github.com/mem0ai/mem0)
- **Supabase**: [supabase.com](https://supabase.com)
- **Axiom**: [axiom.co](https://axiom.co)
- **Playwright**: [playwright.dev](https://playwright.dev)
---
# How to Get SaaS Product Ideas: 7 Proven Methods for Solo Founders
Source: https://www.braingrid.ai/blog/saas-product-ideas
Published: 2026-02-09T12:00:00Z
You know your industry inside and out. You've seen the gaps -- the broken workflows, the tools that don't exist, the problems everyone complains about. With AI coding tools, you don't need to be an engineer to build the solution. The hard part isn't building. It's knowing *what* to build.
There's a lot of advice out there. In this post, we'll focus on the processes successful SaaS founders have used to come up with ideas and build them into profitable products.
By the end of this guide, you'll have 7 proven methods to find validated SaaS ideas that match your expertise -- ready to prototype with [vibe coding tools](/blog/best-vibe-coding-tools-2026).
## What Makes a Good SaaS Idea?
The best answer to this comes from Paul Graham's classic essay: [How to Get Startup Ideas](https://paulgraham.com/startupideas.html). From this article, a great SaaS idea is:
* **Something you (and others) want**: Think of a problem that constantly slowed you down at work. If you ever thought "I wish there was a tool for this," others likely felt the same.
* **Something you can build**: AI coding tools make this less of a hurdle than ever before.
* **Others haven't recognized the opportunity**: Maybe folks are frustrated by a problem but haven't turned the solution into a product yet.
It's more nuanced than three bullet points. You might want to build the next Airbnb. But the founders just wanted to rent out their couch. They started small. You should too.
**Start small.** Rather than aiming to be the next biggest thing, aim to be the best at one small thing.
What should you build? Paul Graham says to ignore two mental filters that kill good ideas:
* **The "sexy" filter**: Forget flashy consumer apps. The real money is in solving boring problems. Think: expense tracking for small law firms, inventory management for bakeries, appointment scheduling for HVAC companies. These aren't exciting -- but customers will pay $50-200/month to avoid the headache.
* **The "schlep" filter**: A tedious, awful task everyone avoids. If everyone hates doing a certain process, that's your opportunity. Stripe is the classic example: setting up billing on ecommerce sites was a tedious, painful job. Stripe took that schlep and made it easy. Now millions of companies use it.
You have the criteria. Now let's find that idea.
## The Paul Graham Recipe for Solo Founders
Paul Graham (PG) writes that "the way to get startup ideas is not to try to think of startup ideas." Find a problem no one else has solved. If you've personally experienced it, even better.
### Just Start Building
"The best way to discover startup ideas is to become the sort of person who has them and then build whatever interests you." [Vibe coding](/blog/best-vibe-coding-tools-2026) tools have dramatically lowered the barrier to build an MVP. 95% of startups fail. You'll have failures too. The key is failing fast -- in days, not months.
**Action:** Pick a problem that bugs you. Build an ugly MVP this week. Launch it publicly. If no one wants it, move on fast.
### Stick to Your Domain Strengths
Your personal experience is your superpower. Building a SaaS on what you know beats jumping into an unknown field. What do people in your industry need?
### What's Missing in Your World?
Have you ever thought "I'd pay someone to fix this"? Maybe that someone is you. Reach out to others in your field and find out if it's a market gap you could fill.
### Is There a Niche the Big Players Are Missing?
Is there an unmet need that large companies overlook? Maybe they think it isn't "big enough" to pursue. But perhaps it's *just big enough* for a solo founder to get a foothold.
### Live in the Future, Then Build What's Missing
**Live in the future:** Join Discord servers, follow builders on X, test new AI tools daily. Stay on the cutting edge of your field so you spot problems before they're obvious.
**Build what's missing:** When you see a gap forming, build for it now. The future of your field will create needs for tooling that doesn't exist yet. Start now and you'll be there when demand becomes urgent.
You have the framework for evaluating ideas. Now you need to find them. Here's where successful founders go hunting.
## Mine Reddit for Pain Points
Reddit is your focus group of thousands. Founders complain openly about real problems. Each complaint is a potential SaaS idea.
### The Iceberg Effect: One Complaint = 26 Silent Customers
For every founder who complains on Reddit, [26 others have the same problem](https://www.linkedin.com/pulse/how-big-customer-complaint-5-statistics-open-your-eyes-korbecki/). That one Reddit post complaining about a broken workflow? It's proven demand hiding in plain sight.
### Direct Feedback Channels
Already have an MVP? Reddit communities full of founders are an excellent place to get early feedback and suggestions.
You can find ideas on many subreddits. If you're in a specific domain, there's probably a subreddit for it. Here are some go-to channels:
#### `r/SaaS`
With 203k users and 15,000 posts a week, [r/SaaS](https://www.reddit.com/r/SaaS/) is a font of knowledge and conversation. A top post analyzed [9,300+ "I wish there was an app for this" posts](https://www.reddit.com/r/SaaS/comments/1q5lfur/i_analyzed_9300_i_wish_there_was_an_app_for_this/) and found most frustration posts happen Mondays and Tuesdays.
Use critical thinking though. Many of the complaints in the post ("recipe posts are too long") aren't SaaS-worthy problems. Pull the nuggets of insight and ignore the rest.
#### `r/Entrepreneur`
PG warns against entrepreneurship classes -- you learn by doing, not studying terms. But reading the trials of other entrepreneurs can sharpen your approach. With ~500k members, you'll find ideas and hard-won experience from people at every stage.
#### `r/Startups`, `r/Marketing`, `r/SaaSMarketing`
Don't wait until launch to think about payments or marketing. Reading these subs as you build keeps you thinking about better ways to sell your product. Posts here can kickstart slogans or product names while you're still building.
Filter Reddit advice through common sense. Many posts are AI-generated noise.
**Action:** Join r/SaaS and r/Entrepreneur today. Spend 30 minutes reading top posts from this week. Bookmark 3 problems worth solving.
## YC's Request for Startups
Y Combinator is one of the most well-known startup incubators. They publish a [Request for Startups](https://www.ycombinator.com/rfs) page listing problems they want solved. Think of this as a pre-vetted list of SaaS ideas -- if YC wants to fund it, there's market demand. The Spring 2026 list weighs heavily on AI products.
The Spring 2026 list highlights AI-native product development tools -- the exact category powering the vibe coding movement. This investor interest confirms growing demand for tools that help non-engineers build software. The screenshot above actually describes the tools being built here at BrainGrid.
Browse previous RFS entries too. They reveal where smart money sees market gaps. If YC wants to fund startups in these fields, customers are ready to pay for working solutions.
**Action:** Read [YC's RFS page](https://www.ycombinator.com/rfs). Pick one problem that matches your domain expertise. That's your starting point.
## Learn from Serial Indie Hackers
Indie hackers build fast, launch ugly, and iterate based on revenue. They ship 10 products to find 1 winner. Learn their patterns to avoid wasting months on bad ideas.
### Levelsio
Pieter Levels [@levelsio](https://x.com/levelsio/) has created multiple startups with combined monthly revenues of ~$250k. His most famous products are [RemoteOK](https://remoteok.com/) and [NomadList](https://nomads.com/).
In a 2023 [interview](https://thebootstrappedfounder.com/pieter-levels-the-indie-hackers-guide-to-ai-startups/), he says "indie hacking" no longer exists, but has evolved into entrepreneurship. What used to be hacking is now just the way companies are formed.
He talks openly about his failures. He built a fancy YouTube analytics platform that no one wanted. His takeaway: "quick and dirty" MVPs work best. Super-polished means you've spent too much time on features people might not want. Get feedback on the MVP first, then build based on what you've launched.
### John Rush
[John Rush](https://x.com/johnrushx) is another prolific SaaS founder who builds in public on Twitter and Substack.
His 24 SaaS projects generate $2M ARR combined. His [3-month playbook to $10k MRR](https://substack.com/@johnrushx/note/c-67116942):
* Find a popular SaaS, and identify one sector of their audience.
* Learn about their pain points in a popular feature in that SaaS.
* Begin conversations -- build a following -- while learning about the pain point.
* Launch a waitlist for the fix.
* Build the MVP.
**Key insight:** Rush validates demand *before* building. He creates 5 waitlists, then builds only the one with the most signups.
You don't have 114k followers. So adjust: build 3 waitlists featuring your ideas. DM 50 people individually. Manual hustle beats viral tweets when you're starting out.
## Tools for Systematic Idea Discovery
Beyond manual research, AI-powered tools can accelerate the process. [IdeaBrowser](https://www.ideabrowser.com) delivers a fresh SaaS idea every day, scoring each on Opportunity, Problem, Feasibility, and "Why Now" timing. It also integrates directly with vibe coding tools to help you start building right away.
**Warning:** You won't be the only reader. If you build an IdeaBrowser suggestion, narrow it down. Don't build "AI resume builder" -- build "AI resume builder for nurses re-entering the workforce after career breaks." The more specific your audience, the less competition you'll face. [Kaleen Canevari](/blog/builder-story-kaleen-canevari-motra-studio) did exactly this -- a Pilates instructor who built a multi-tenant studio management platform for her exact domain.
## Validate Before You Build
This is the step most founders skip -- and it's why most fail. SaaS products rarely fail because they're poorly built. They fail because no one wants them. Validation prevents this.
John Rush's waitlist approach works well here. Build landing pages for a few different ideas. Each page explains the problem and promises a solution. Add a waitlist signup form and promote in relevant communities (Reddit, LinkedIn groups, Discord, and forums). The idea with the most signups wins -- build that one.
But don't fixate on raw signup numbers. Most solo founders don't have 100k followers to drive traffic. Focus on the *quality* of responses instead. Are people DMing you asking when it launches? Are they sharing the page with colleagues? Are they describing exactly how they'd use it? A handful of passionate, specific replies is a stronger signal than a hundred casual signups.
By communicating on social media, you get a feel for what features potential customers are missing. Listening to their needs helps you prioritize "what's next" on the feature list -- and tells you whether you're solving a real problem or an imagined one.
## Your SaaS Ideation System: Next Steps
You now have 7 proven methods for finding SaaS ideas:
1. **Personal experience** -- Problems you've faced in your domain
2. **Paul Graham's framework** -- Unsexy problems, schlep opportunities, living in the future
3. **Reddit mining** -- Real pain points from r/SaaS, r/Entrepreneur, and niche subreddits
4. **YC's Request for Startups** -- Investor-validated categories
5. **Indie hacker playbooks** -- Levelsio and John Rush's processes
6. **AI discovery tools** -- IdeaBrowser and daily idea scoring
7. **Validation tactics** -- Waitlists, pre-selling, and conversations
**What to do this week:**
- Pick 3 pain points from your domain experience.
- Search Reddit for similar complaints using the subs listed above.
- Create landing pages for your top 2 ideas.
- Share them in relevant communities and track the engagement.
Don't wait for the perfect idea. 95% of startups fail, so better to figure that out when you've invested days, not months. Launch early, iterate fast, and pivot when the data tells you to.
Once you've validated an idea and gathered feedback, turn those insights into a [structured product plan](/blog/spec-driven-development). That's where tools like [BrainGrid](https://www.braingrid.ai) help -- transforming feature requests and customer feedback into detailed requirements and build-ready tasks for your AI coding tools.
In a coming post, we'll walk through taking a validated idea from waitlist to shipped MVP using vibe coding tools and BrainGrid.
## Frequently Asked Questions
### How do I find a good SaaS idea?
Start with problems you personally experience in your domain of expertise. The best ideas come from noticing gaps rather than brainstorming solutions. Monitor communities like Reddit where people share frustrations, and validate demand before building anything.
### What are some micro SaaS ideas?
Popular micro-SaaS categories include AI-powered tools. Instead of general resume builders or content generators, build for a specific category of user. Instead of general automation tooling, automation for specific industries (real estate, restaurants). Create features unbundled from larger platforms. Focus on serving one sub-audience exceptionally well rather than building for everyone.
### How do I validate a SaaS idea without coding?
Create a landing page with a waitlist signup before writing any code. Share your problem hypothesis in relevant communities and gauge responses. Consider pre-selling access or running "smoke tests" with "coming soon" buttons to measure interest. Build a **raw** MVP tool, and gauge the response.
### Can you build a SaaS by yourself?
Yes—the micro-SaaS model is designed for solo founders. Successful products often generate $5,000-$30,000 monthly recurring revenue with 70-80% profit margins. AI coding tools like Claude Code, Cursor, BrainGrid, and Lovable make it faster than ever for non-engineers to ship working products.
### What does Y Combinator look for in startups?
YC's current Request for Startups prioritizes AI-native product development, financial services, agency businesses using AI, government technology, and manufacturing. These areas signal where experienced investors see market timing and opportunity, though you should narrow down to specific problems.
### How do successful indie hackers find product ideas?
Prolific indie hackers like Pieter Levels and John Rush build many small products, share progress publicly, and iterate quickly. They accept high failure rates as part of the process. Rush's playbook: find a popular SaaS, identify a sub-audience, and build one highly-used feature for that audience.
---
# Introducing AI Product Planner: Structure your ideas for AI
Source: https://www.braingrid.ai/blog/ai-product-planner
Published: 2026-02-05T12:00:00Z
You have ideas. Probably too many of them.
They live across docs, notes, Slack threads, and half-finished prompts. Turning those ideas into something your AI coding tool can build beyond a fragile prototype is where most builders get stuck.
Code is not the bottleneck anymore. Planning is.
Today, we are introducing **BrainGrid AI Product Planner**, a new way to bring structure to product thinking before a single line of code is written.
## What's New
AI Product Planner gives you a clear plan for what you are building and what is actually ready to build.
Everything lives in one place. No scattered notes. No guessing what comes next.
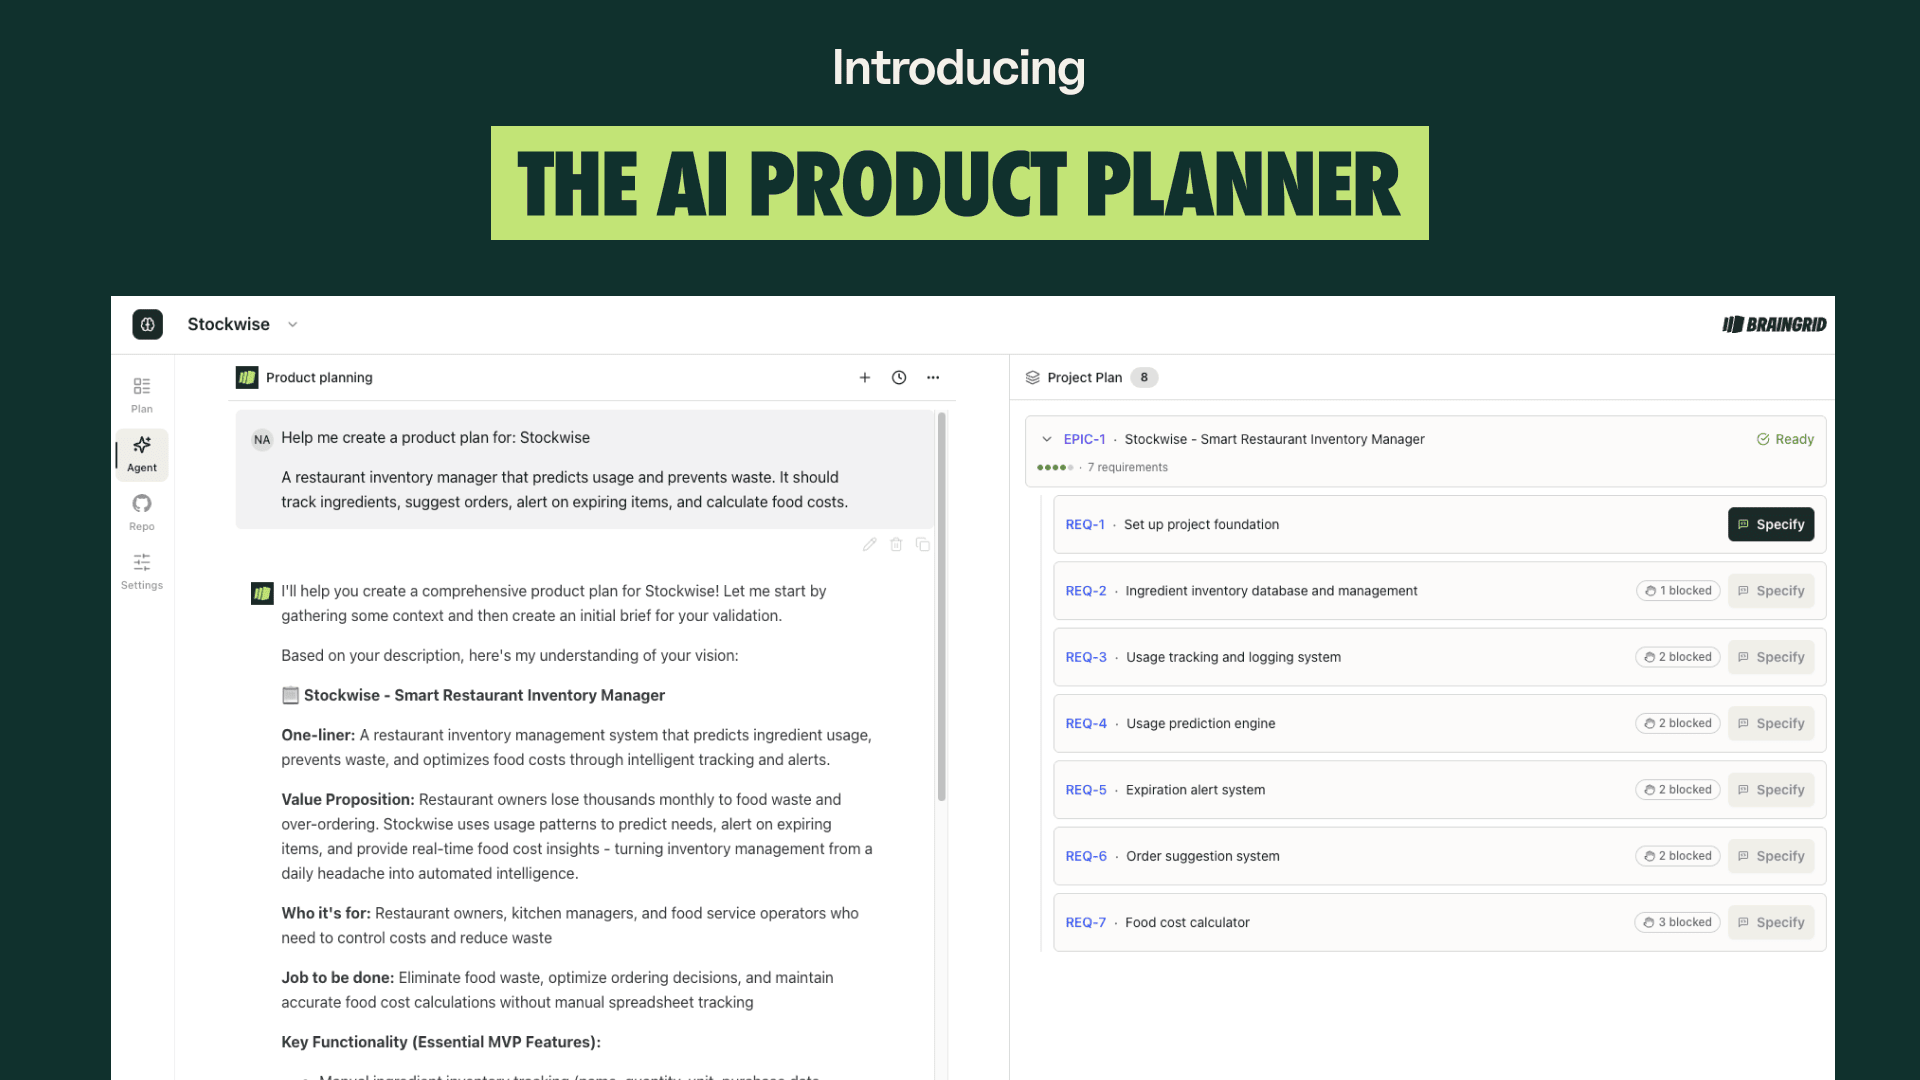
Four capabilities, one goal: help you ship with clarity.
- **Unified Plan view**
Epics and requirements organized in a single structured hierarchy.
- **AI-guided specification**
Planning agents ask smart clarifying questions to turn vague ideas into buildable specs.
- **Readiness scoring**
A clear signal for what is ready to build and what still needs work.
- **Dependency management**
Visualize blockers before they slow you down.
## Why We Built It
Builders kept telling us the same thing.
> “I know what I want to build, but I don't know how to get it out of my head in a way AI can reliably execute.”
AI coding tools are excellent at implementation. They are not designed to help you think through product strategy, scope, sequencing, or the bigger picture.
That missing step is where most AI-built apps start to break.
We built AI Product Planner to fill that gap. It meets you where you are, whether that is a half-formed idea or a detailed concept, and helps you turn it into a plan that can actually be built.
## How It Works
### 1. Create your plan
Start with a project. This could be a small feature, a single change, or an entire product.
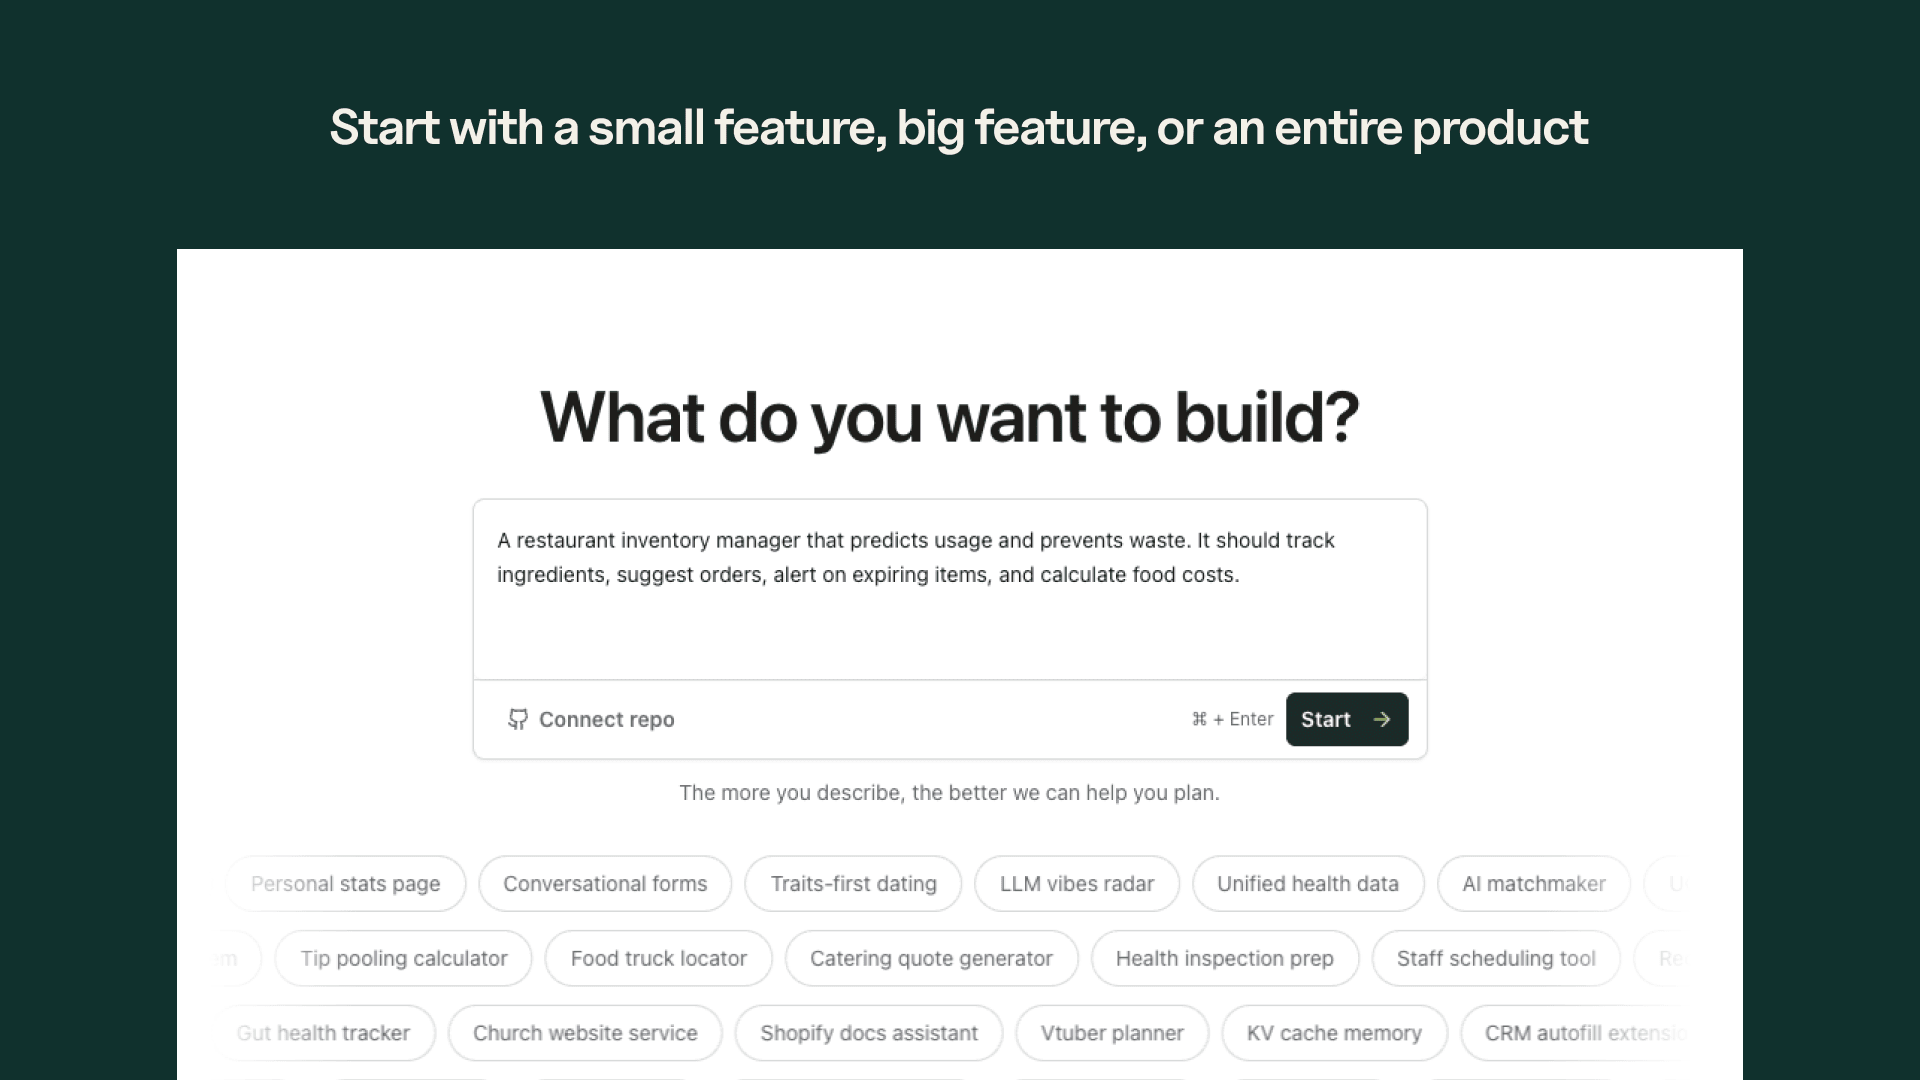
BrainGrid organizes your thinking into a clear product plan. Epics give you the big picture. Requirements keep things concrete and actionable.
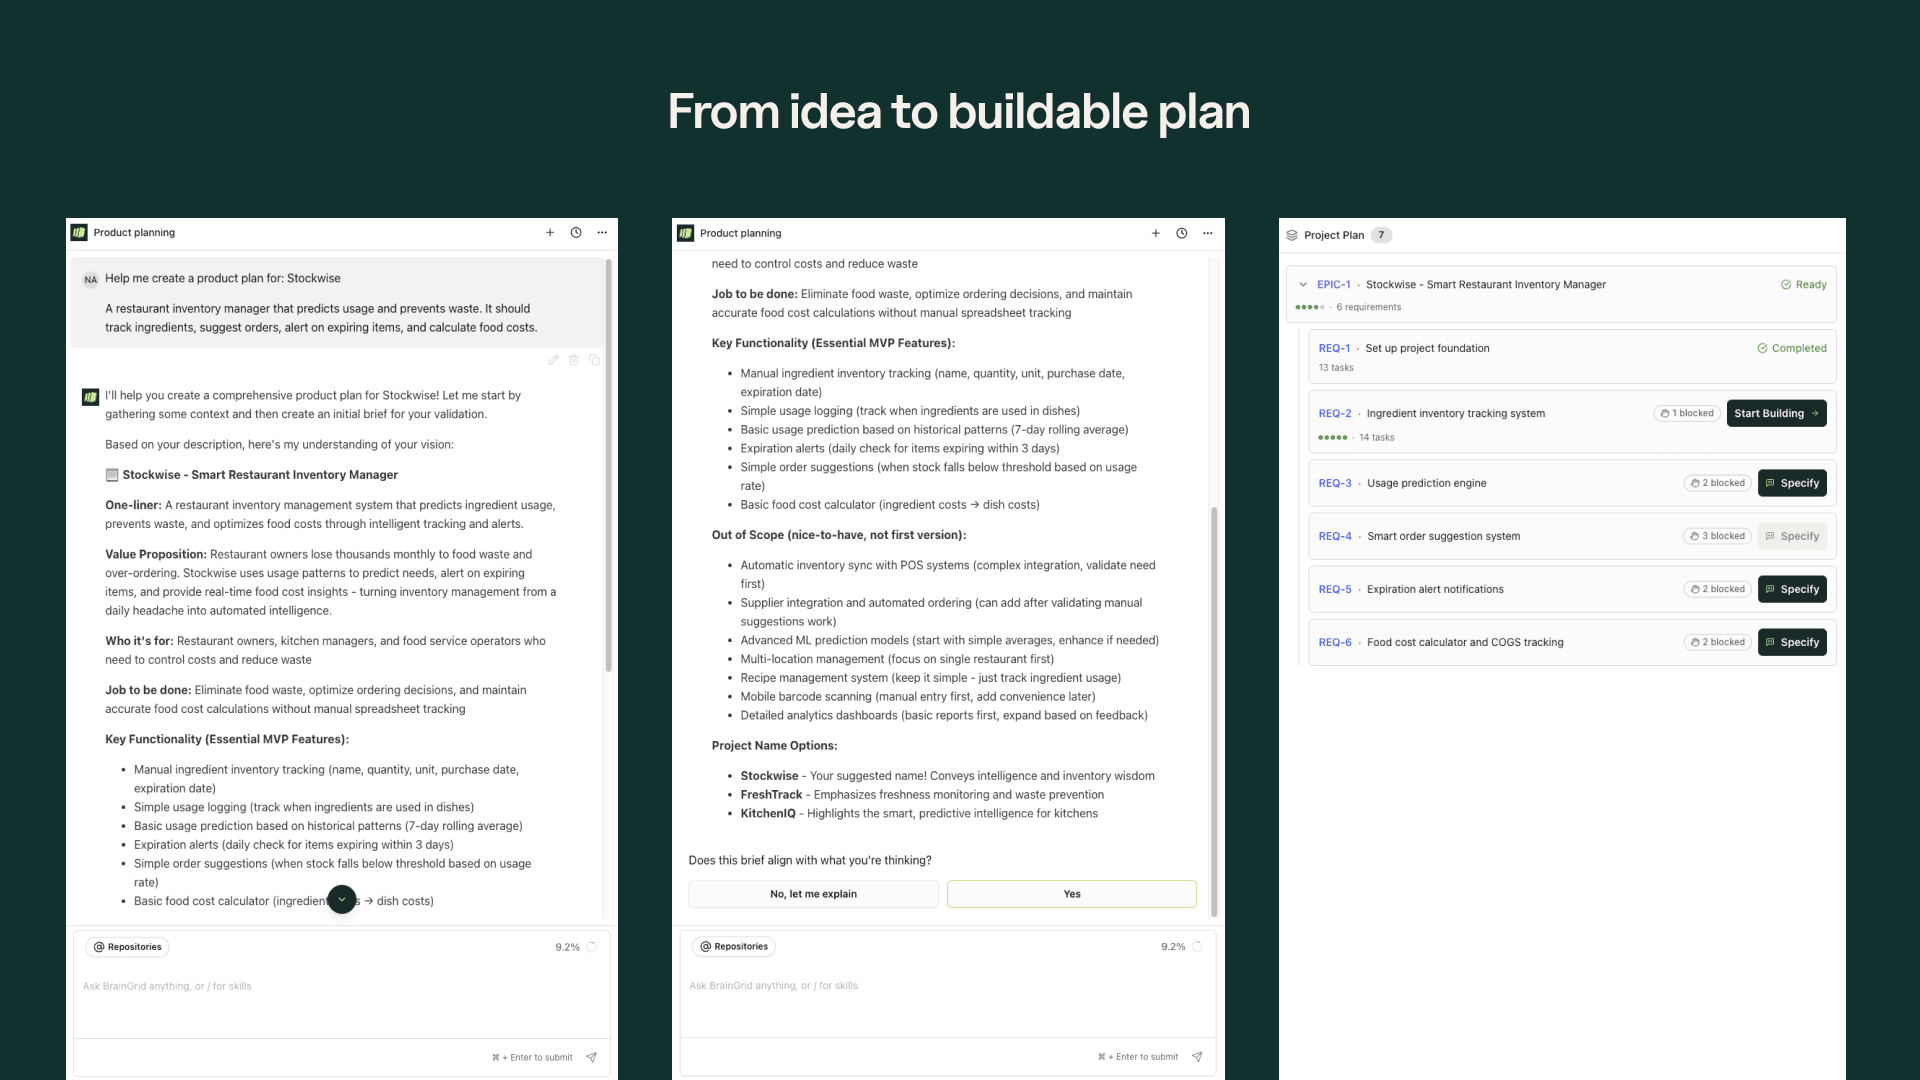
### 2. Specify with AI guidance and clarifying questions
Select a requirement to specify. The planning agent asks the kinds of questions an experienced product manager and tech lead would ask.
What is the user flow?
What are the edge cases?
What constraints matter?
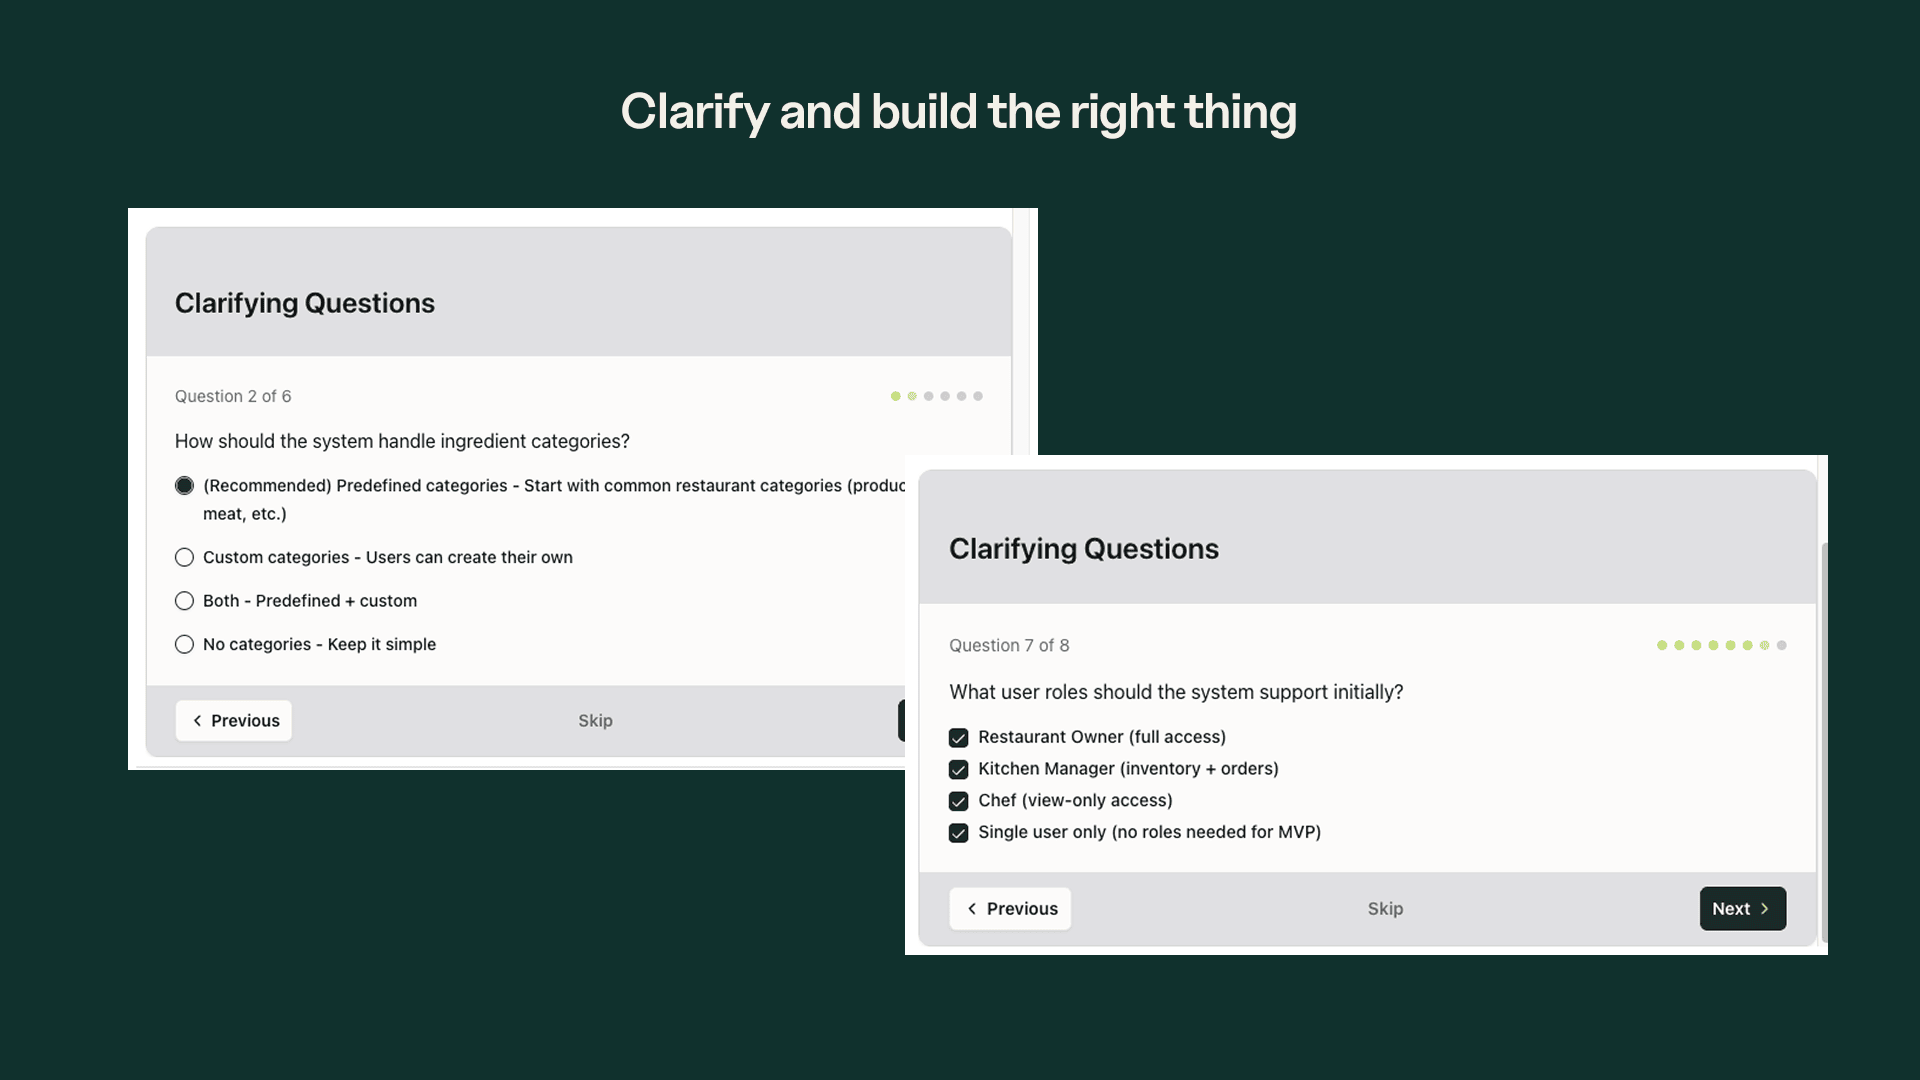
You work one requirement at a time, without losing sight of the overall plan. Large initiatives become manageable.
The result is a fully specified requirement with the context AI coding tools need to build it correctly.

### 3. Check readiness scores
Each requirement receives an AI-evaluated readiness score from 1 to 5.
| Score | Meaning |
|------|---------|
| 1–2 | Needs more definition |
| 3 | Good for discovery, not ready to build yet |
| 4–5 | Ready to build |
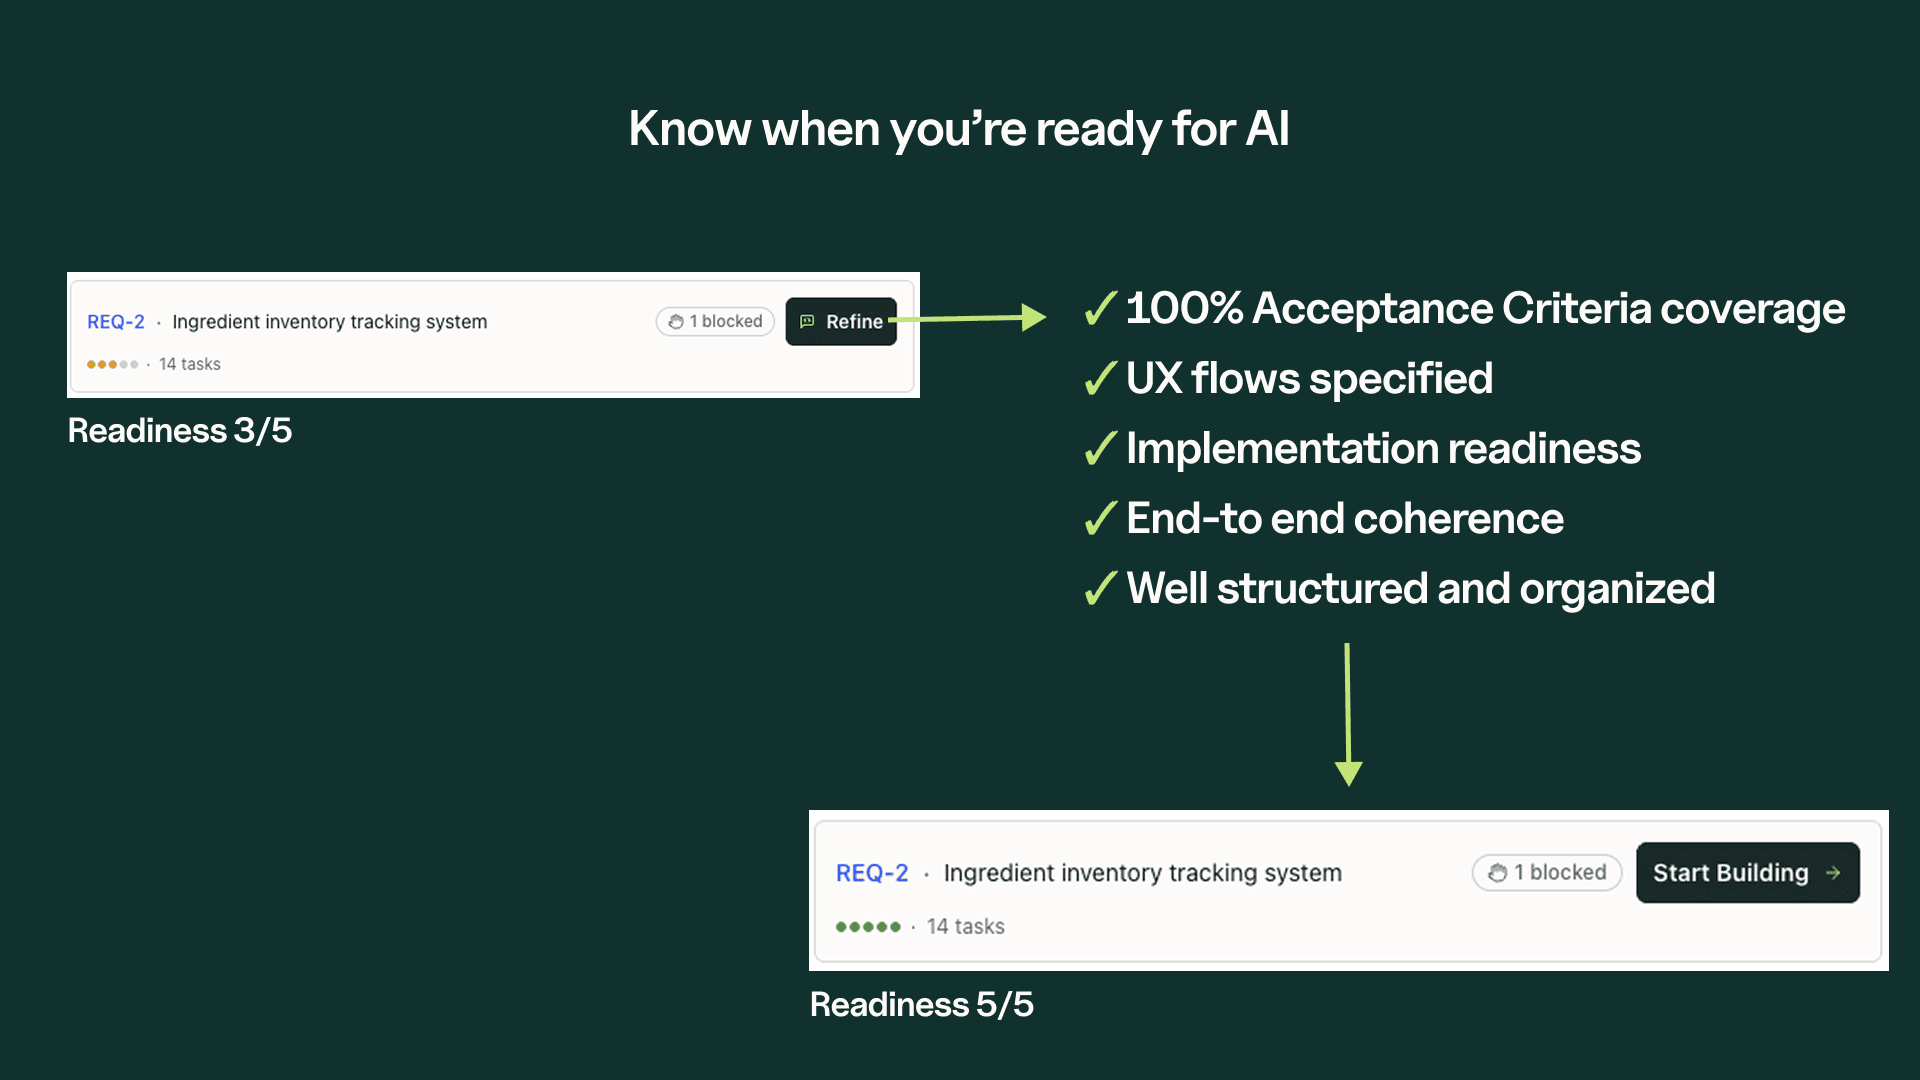
Low scores tell you where to refine your thinking. High scores mean you can confidently hand work off to your coding agent.
### 4. Manage dependencies
Most features depend on other work being completed first. AI Product Planner makes those relationships explicit.
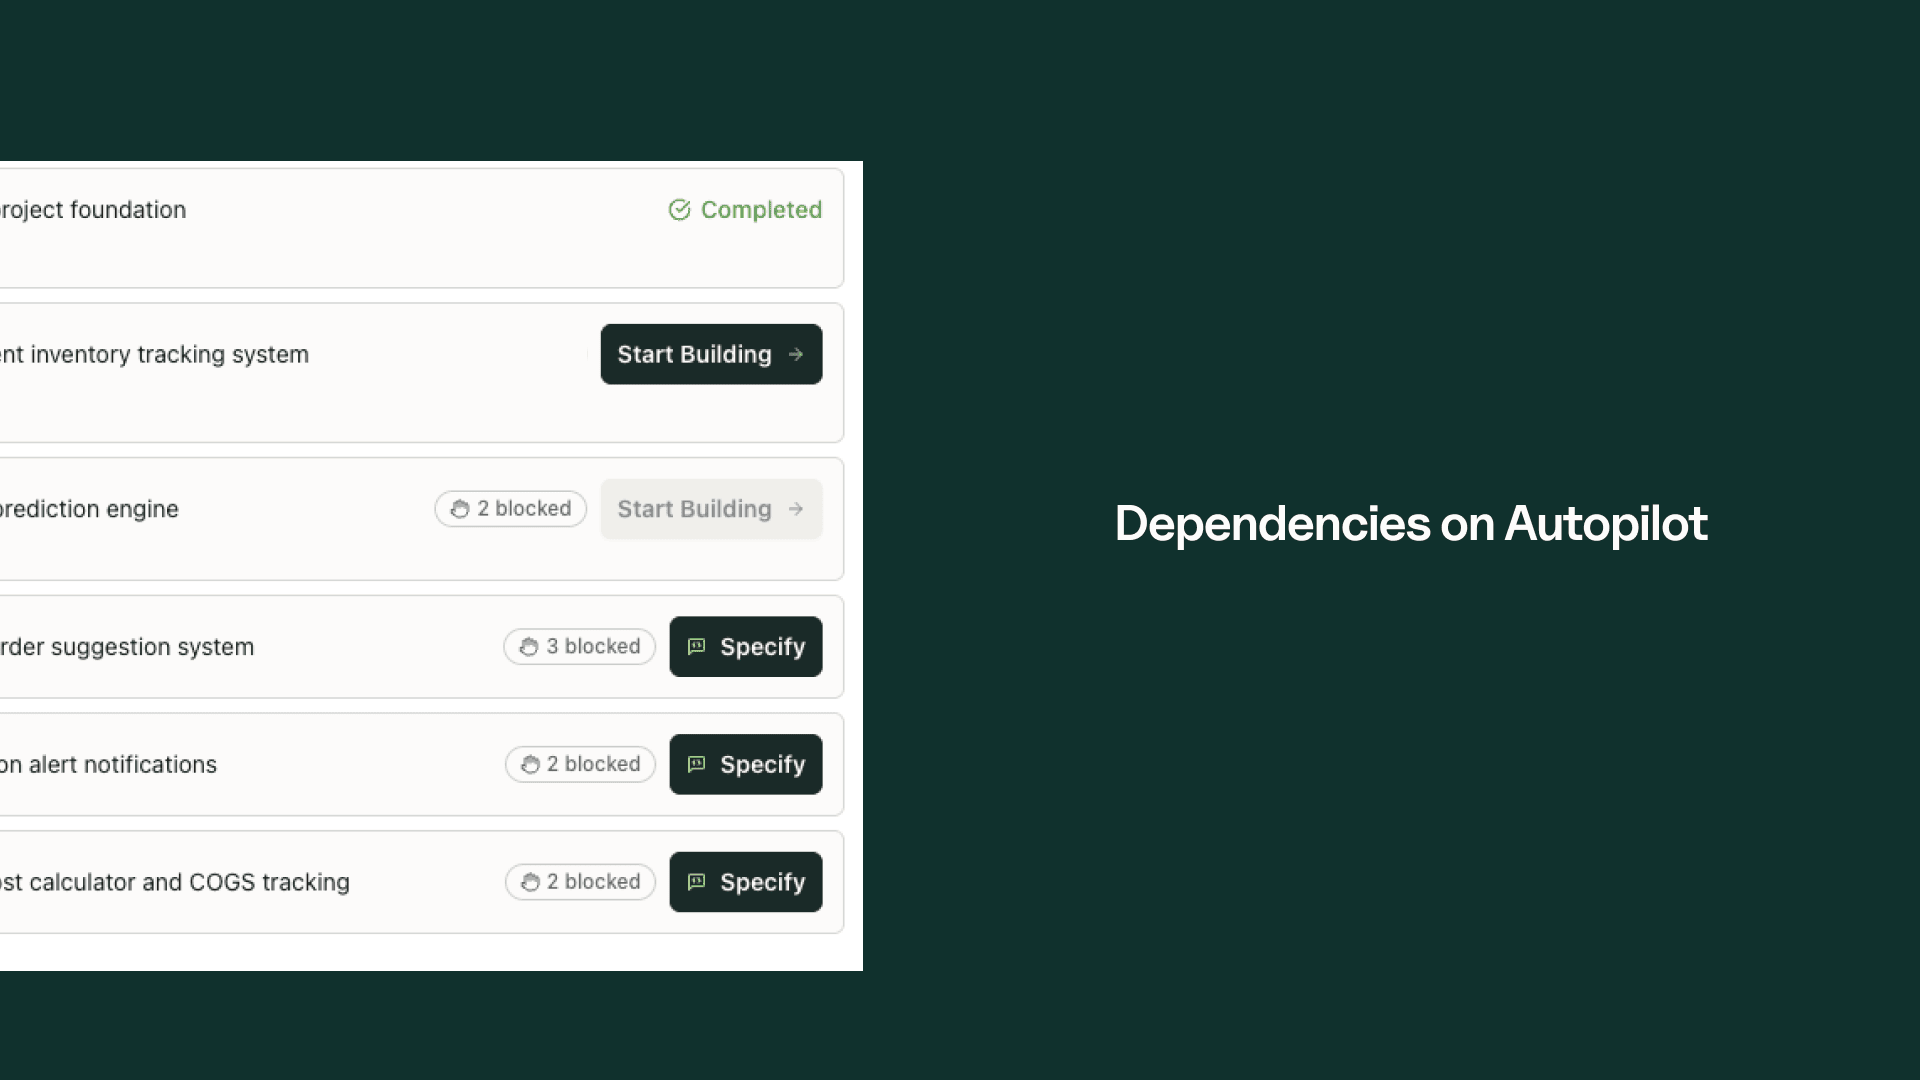
You can see what is blocked and what is blocking it before development starts.
### 5. Build with your favorite coding agent
Send structured tasks to Claude Code, Cursor, Codex, Replit, or Lovable via MCP, CLI, or simple copy-paste. Each task includes all the context your AI coding agent needs to build it correctly.
BrainGrid stays focused on planning. Your coding agent stays focused on execution.
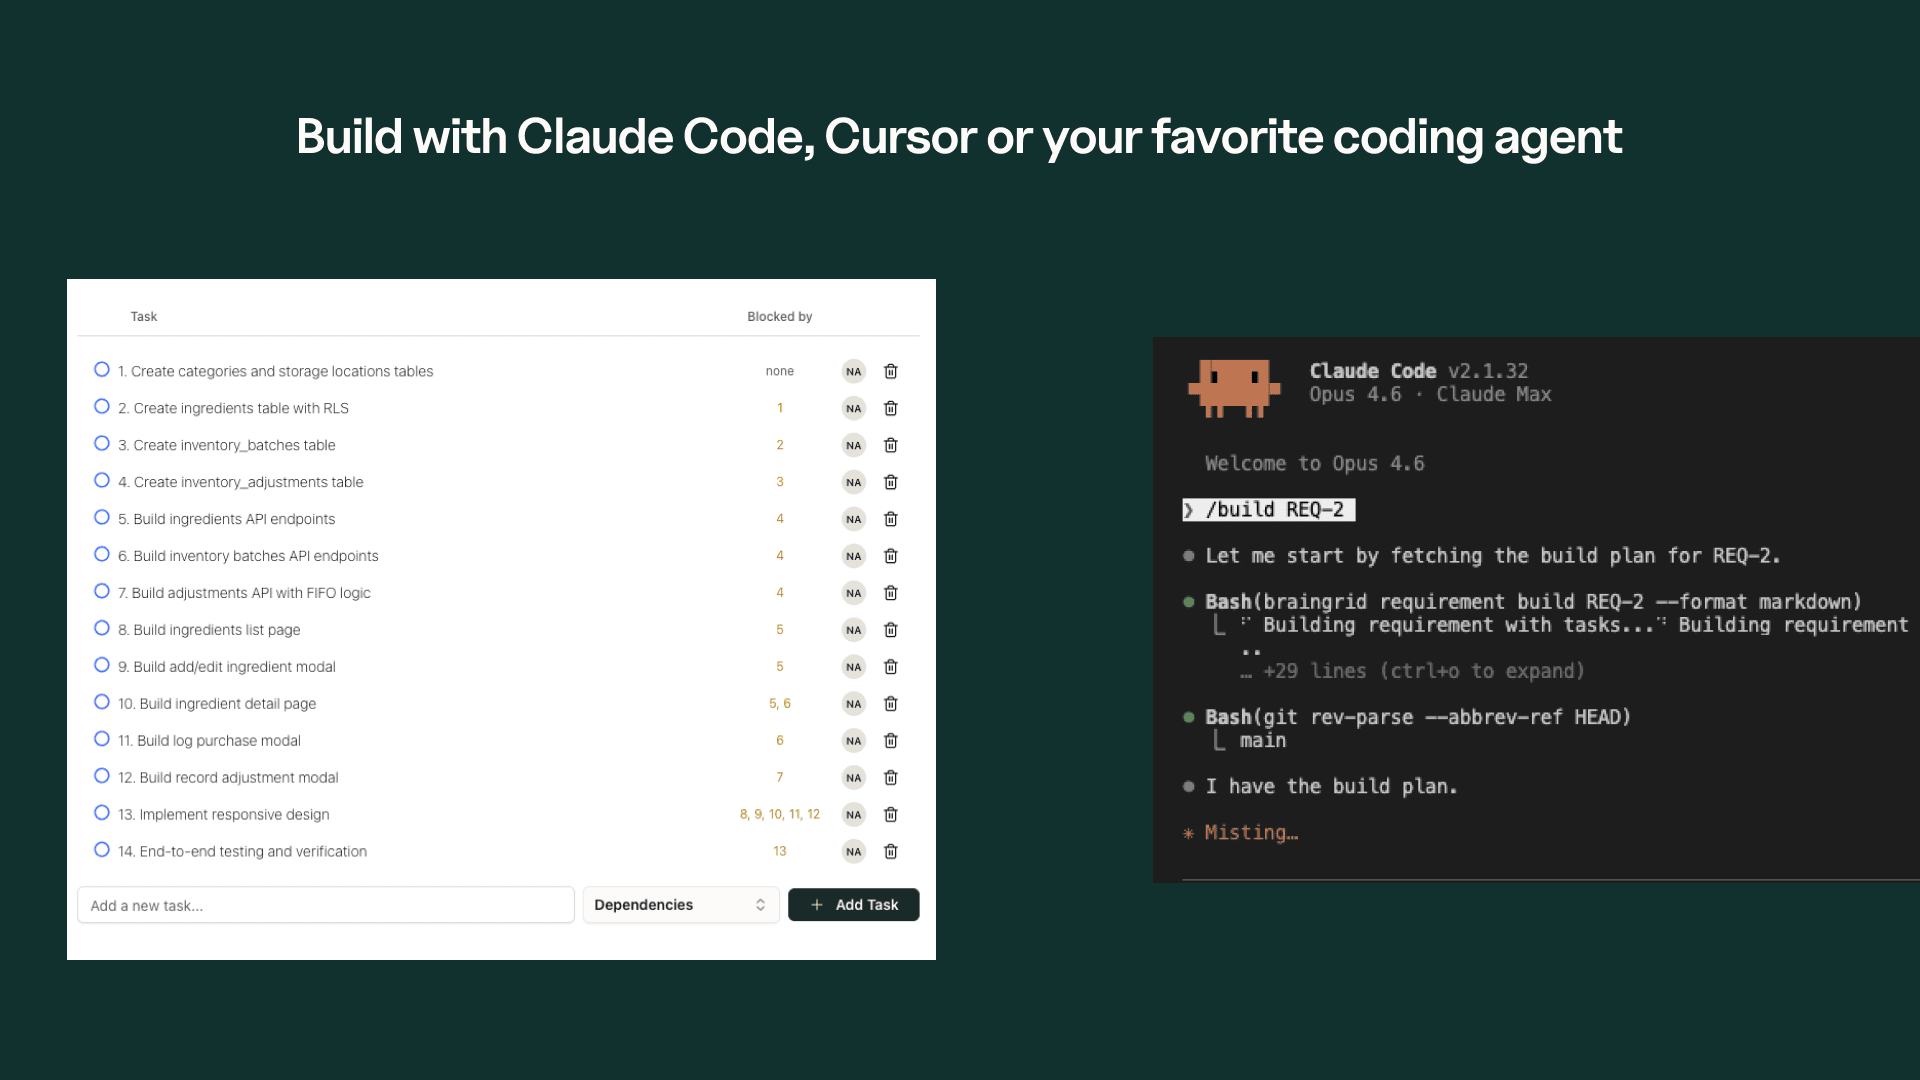
## From idea to execution
A typical workflow looks like this:
1. Bring your ideas into a plan
2. Organize them into epics
3. Specify the most important requirements
4. Check readiness scores
5. Set dependencies
6. Ship by handing high-readiness requirements to your coding agent via CLI, MCP, or copy-paste
Your Plan view becomes the source of truth. You always know what you are building, why it matters, and what comes next.
## Get Started
AI Product Planner is available now for all BrainGrid builders.
[Open your dashboard →](https://app.braingrid.ai/projects/new?utm_source=blog&utm_medium=content&utm_campaign=ai_product_planner)
Create a project, add your first epic, and let the planning agent help you turn your next idea into something buildable.
---
# 7 Best Vibe Coding Tools in 2026 (Tested & Ranked)
Source: https://www.braingrid.ai/blog/best-vibe-coding-tools-2026
Published: 2026-02-04T23:20:25Z
## Ship Your SaaS in Weeks, Not Months—No Developer Required
Non-technical founders are launching paid products in 2-4 weeks using AI coding tools. This guide helps you pick the right one and avoid costly rebuilds.
**What is vibe coding?** You describe what you want in plain English, and AI agents write all the code. You iterate together until it works—often in hours, not months.
Is it really possible to build a working SaaS this way? Yes. Today's tools make it achievable, and they're improving rapidly. But it isn't always easy—AI agents make mistakes, features can break, and some tools fit your workflow better than others.
**By the end of this guide, you'll know:**
- Which tool matches your technical comfort level and budget
- How each tool handles the same simple app (so you can compare directly)
- Why detailed specs prevent expensive rebuilds later
So, what tool should you pick to hit the ground running?
## How to Choose Your Vibe Coding Tool
Tool choice paralysis is real—and overwhelming. Each vibe coding tool works differently. Understanding your needs and technical abilities narrows your choice to one or two options instead of a dozen. Then try them out and see which fits your way of thinking.
Here are a few more questions that may help you narrow your selection:
### 1. How Comfortable Are You with Git and Version Control?
GitHub is more than just the website that stores your code and helps developers collaborate. Git gives you version control—you can move back to older states of the codebase if mistakes happen. With Git branches, you keep your working code in the main branch and work on features in other branches. When the new features are ready, you merge them into main.
If you're not familiar with Git—that's fine. Browser-based tools like Bolt and Lovable handle version control automatically.
If you're learning Git or already comfortable with it, IDE-based tools let you use that skill for more control.
**Why this matters for vibe coding:** AI agents make mistakes. Without version control, one bad prompt can break your working app with no way to recover. Git lets you experiment fearlessly—if the AI breaks something, roll back to the last working version in seconds. (New to Git? Read our [Git version control guide for AI builders](/blog/git-version-control-for-ai-builders).)
### 2. Control vs Speed: What Matters More Right Now?
**Speed:** Auto-accept all AI changes without reviewing them. You'll churn out features quickly, but the codebase becomes messy. If your SaaS grows and you hire developers later, they'll spend time refactoring before adding new features.
**Control:** Review each change, understand what the AI created, and iterate until the code does exactly what you need. This approach is slower, but produces higher-quality code that you (or a future dev team) can follow and maintain.
### 3. What's Your Monthly Budget and Usage Pattern?
How much vibe coding will you do every day? If it is just an hour or two a day, you can probably get away with the base plans that are offered. Most vibe coding tools are very affordable to start - and you may find yourself using more than one.
As your usage increases, you will exceed the base usage plans, and can expect to pay overage amounts. If those amounts continue to grow, you can upgrade to higher usage plans.
### 4. Are You Handling Customer Data Yet?
You've probably heard warnings about sending private data to an LLM. The same applies to your customer data. When your code queries include personally identifiable information (PII), you leak private data—putting both your business and your customers at risk.
The best approach is to use a test environment with only test data in your database. The 2nd best approach is to edit all logging and error messages to remove PII (but this is slow, and easy to forget when crunching through a really pesky problem.)
Even if your vibe coding platform is SOC2 compliant, it is not ok to share PII from logs, etc. to the coding platform.
### 5. Will you Move to a Dev Team?
Is your product a simple tool you can maintain the same way you built it? Or do you envision a larger product that you'll eventually hand off to developers? If handoff is likely, lean toward controlled vibe coding—clean code is easier to maintain than the spaghetti code that arises from prioritizing speed.
Now that you know what to consider, let's see these factors in action. Below, we compare the most popular tools by building the same app with each—so you can see exactly how they differ.
## The Most Popular Tools in Early 2026
We rank tools from least technical (no Git, no IDE) to more advanced (Git knowledge, coding IDE). If you're a non-technical founder, start at the simpler end and work your way up as your skills grow. If you're already a developer, jump to the more technical tools.
For each tool, we'll build the same small SaaS-like app—**Founder Daily Pulse**: a check-in app with 3 simple questions that gives you feedback on your day.
The prompt that I will use with each tool is:
```text
Daily Pulse is a tiny app that helps founders check in with themselves once a day and get a clear snapshot of how they're actually doing.
Instead of tracking everything, it asks just three quick questions:
How's your energy?
How focused do you feel?
How stressed are you?
From those inputs, Daily Pulse generates a simple visual summary and a short, human-readable insight.
```
### Lovable: Browser-Based Full-Stack Builder (Hosted MVP Platform)
[Lovable](https://lovable.dev) is built into the browser. There is no code, there is no IDE. You just tell the Agent what to build and you start going.
Lovable Pro costs $50/month and includes 200 credits. I built the sample application on the free tier and couldn't easily determine the exact credit usage.
Giving Lovable our prompt, it created a webpage that uses a number of common development technologies:
- Vite
- TypeScript
- React
- shadcn-ui
- Tailwind CSS
It created a test, a 404 (page not found) placeholder, and a nicely working app.
You can try the app yourself at [Lovable](https://founder-pulse-insight.lovable.app).
Lovable has a built in design tab that allows you to easily adapt and change the design of your application.
Here we can adapt the images, fonts or colors:
Lovable is a great tool to begin your vibe coding journey—no coding requirements, no GitHub dependencies. We've written a tutorial on [how to download a Lovable project](/blog/how-to-download-lovable-project) for when you're ready to move to more advanced tools or hand off to a developer. Looking for a direct replacement? See our [10 best Lovable alternatives](/blog/lovable-alternatives) comparison.
While Lovable excels at simplicity, Bolt.new adds more production-ready features like built-in authentication and databases.
### Bolt.new: Browser to Deployed App
[Bolt.new](https://bolt.new), like Lovable, is browser-based. You can begin without even logging in. After entering the prompt, Bolt immediately started building:
A few minutes later, the Bolt version of our app was ready. Bolt built in a database for logins and to store pulse scores over time. It included login by default—making it easy to scale to many users. In Bolt's settings, you can even enable Google sign-in.
Once signed in, we have 3 sliders, again 1-10. The user submits their result:
The bars are green for good values and red for worse ones. Supabase (an open-source database tool) stores the data and displays yesterday's results alongside today's—although it appears to show the same values for both.
You can try the [Bolt.new app](https://daily-founder-check-wun3.bolt.host/)
When publishing, Bolt discovered a security issue:
Supabase scans for insecure passwords. In this case, I chose to ignore the warning—but if I were building a real SaaS, I'd fix this.
The free Bolt.new account includes 1M tokens—I used ~232k tokens to build this app. Pro accounts cost $25/month and include 10M tokens.
### v0 by Vercel: UI-Focused Component Generator
v0 by Vercel is also browser-based. Sign up free and start prompting. Vercel built [our application](https://v0-daily-pulse-app-snowy.vercel.app/) with buttons rather than sliders and defaulted to a dark mode design:
Vercel can integrate and upload code to GitHub, and also has a built in design studio to change colors, fonts, and other design features of the application:
I built this application with V0's free tier, which allows $5 of usage per month and 7 messages per day. Pro plans start at $20/month with $20 of credits and the ability to purchase more.
### Replit: Browser-Based Development Environment (Learning Platform)
Replit is another browser based tool, and based on the number of ads in front of it on Google by competitors, a pretty popular choice for developers.
The Replit app had two introductory pages and a required login before I could perform my daily check-in:
Replit chose sliders for the selection:
The Replit app was the first that didn't complete the task. The "Complete Check-in" button does nothing, and publishing claimed success but the URL doesn't work. Both issues could likely be resolved with additional prompts, but I wanted to keep prompting consistent across all tools.
Building the app used 335 of my daily free credits. Pro plans start at $20/month, include $25 of credits, and remove the "made with" badge. In my opinion, the app over-engineered the setup with 2 intro pages and required sign-in—then didn't actually score my daily pulse.
### Cursor: AI-Powered Code Editor
[Cursor](/blog/cursor-mcp) is an IDE-based agentic AI. Installed on your computer, it replaces VS Code (it's a fork, so it looks familiar). Cursor is designed for developers—with autocomplete for coding in addition to vibe coding features.
The prompt generated 3 files: HTML, CSS, and JavaScript. Unlike browser tools, Cursor doesn't automatically publish your app to the web, but the code is on [GitHub](https://github.com/dougsillars/vibe_coding_comparison/tree/daily-pulse-docs). You can open the page directly in a browser:
I built this application with Cursor's free tier. Cursor Pro starts at $20/month. (See our [Cursor pricing breakdown](/blog/cursor-pricing) for details.)
### Claude Code: Terminal-Based AI Agent
Claude Code installs into your terminal and interacts with your code from the command line. It works best alongside a coding IDE and requires basic Git knowledge to manage branches. When creating the sample app, Claude offered several technology stack options:
I selected #2 a React application framework.
The Claude app uses sliders and works similarly to the other applications. Claude Code costs $20/month for the Pro tier. (See our [Claude Code pricing breakdown](/blog/claude-code-pricing) for details.)
### Windsurf: Agentic AI-First IDE
[Windsurf](/blog/windsurf-mcp), like Cursor, is a standalone IDE built for vibe coding with AIs.
Windsurf also created a Vite application. Interestingly, it built a single-page site with sliders and results on the same page. The code saves results in localStorage, indexed by day—a smart approach that makes adding a database easier as the app grows.
Windsurf starts at $20/month and scales with you and your team.
After building the same app seven times, a pattern emerged: **each tool interpreted our prompt differently**. This reveals a challenge in vibe coding that no single tool solves.
## The Missing Layer: Why All Tools Need Specs
Building the same application across all these tools revealed fascinating differences. While most results were similar, the variance was significant: entry flows (immediate vs. multi-page signup), UI choices (sliders vs. buttons), and backend approaches (no storage vs. localStorage vs. full Supabase database).
It's clear the AI agents weren't sure what to build, so they made their own choices. Sometimes that's great—but it can also lead to expensive rework.
### Vague Prompts Lead to Vague Implementations
We've all encountered LLMs giving unexpected responses—often due to vague prompts (or, in my case, lazy prompts). The better structured your prompt, the better the response. This effect is magnified in vibe coding: one poorly written prompt, and agents build features you never wanted or needed.
### Specs Turn Ideas into Clear Instructions
In traditional software development, product managers turn vague ideas into clear requirements. The vibe coding equivalent is [BrainGrid](https://www.braingrid.ai), an AI Product Planner. BrainGrid translates your prompts into detailed requirements that specify exactly what each feature should do.
For example, entering our daily pulse prompt into BrainGrid produced an [epic user story](https://github.com/dougsillars/vibe_coding_comparison/blob/main/braingrid/epic1.md), which was then converted into specific requirements:
These 8 requirements take the daily pulse **much further** than any individual AI agent did. BrainGrid's Product Planner made logical extensions: Do we need a database? If we're tracking usage over time, can we build trends and analyze historical data?
By adding these ideas to the epic, agents can build not just an MVP, but a framework for a SaaS that grows and evolves. For our MVP, we'd implement requirements 1 and 2—but they'd build on a solid, future-proof foundation.
BrainGrid creates detailed tasks with prompts that feed directly into your vibe coding tool of choice. Your simple prompts become detailed, specific instructions designed for successful implementation.
### The Spec-First Workflow
By creating specifications, BrainGrid helps you understand exactly what you're building and how you plan to grow. Building an MVP in one prompt is amazing—but taking time to plan and build a foundation first makes growing your SaaS easier over time. (Learn more about this approach in our guide to [spec-driven development](/blog/spec-driven-development).)
### Works with Any Tool
The requirements and tasks BrainGrid creates work with all the tools above. BrainGrid's [MCP](https://docs.braingrid.ai/mcp-server/overview) installs into your vibe coding tool of choice, letting agents read requirements and tasks directly.
### Why This Matters for Non-Technical Founders
You want to move fast—but also safely and productively. Using BrainGrid to create your tasks requires more upfront thinking, but the resulting prompts are stronger. You're more likely to get what you want on the first try, avoiding costly rework later.
With or without BrainGrid, you still need to pick your primary vibe coding tool. Here's how to decide.
## Which Tool Should You Choose?
All the tools we tested did a solid job building an MVP. The best tool is the one that matches (or slightly stretches) your technical skills and preferred workflow.
**If you have less coding experience:** Browser-based tools are excellent. You get working code without worrying about Git. Most include design tools for tweaking colors, fonts, and UI elements right in the browser.
**If you're comfortable with Git and want to see the code:** IDE-based tools (and Claude Code as a terminal agent) are a great choice. They let you work in the code like a developer while still leveraging AI agents to build new features.
**No matter which tool you choose:** BrainGrid helps create better prompts for your agents. Quality prompts lead to quality code—and fewer expensive rebuilds.
Best of luck on your vibe coding journey!
## Frequently Asked Questions
### What are the best vibe coding tools for beginners?
Bolt.new and Lovable are best for complete beginners because they handle Git and deployment automatically in the browser. You describe your app, they build and deploy it without requiring terminal commands or version control knowledge. For beginners willing to learn basic Git, Cursor offers a good middle ground with visual code editing and AI autocomplete.
### Which vibe coding tool is best for non-technical founders?
Claude Code is best for non-technical founders who think in product requirements rather than code syntax. You describe features in detail and Claude executes autonomously across multiple files. Alternatively, Bolt.new works well if you prioritize speed and don't need to understand the underlying code—great for validating ideas quickly before committing to deeper learning.
### How do I choose between Cursor and Claude Code?
Choose Cursor if you want to see and understand code as it's written—you'll review changes line-by-line and learn programming patterns along the way. Choose Claude Code if you prefer describing outcomes and letting AI handle implementation details autonomously. Both cost $20/month, so the decision comes down to control preference: hands-on (Cursor) vs autonomous execution (Claude Code). For a deeper comparison, see our [Claude Code vs Cursor](/blog/claude-code-vs-cursor) guide.
### What's the difference between browser-based and IDE-based AI coding tools?
Browser-based tools (Bolt, Lovable, Replit, V0) run entirely in your web browser with zero setup—no installing software or configuring environments. IDE-based tools (Cursor, Claude Code, Windsurf) require local installation and basic Git knowledge but give you full control over your codebase. Browser tools are faster to start but have limitations for complex projects; IDE tools have a learning curve but work better for professional-grade applications.
### Do I need to know Git to use vibe coding tools?
Browser-based tools require no Git knowledge—they handle version control automatically. IDE-based tools benefit from basic Git understanding (commit, branch, revert) which takes 1-2 days to learn. You can start without Git, but you'll hit limitations within a week when you need to undo mistakes or manage different feature versions safely.
### How much do vibe coding tools cost per month?
Base plans cost $15-20/month for most tools, but realistic budgets range from $60-100/month for part-time building to $180-300/month for full-time development. The difference comes from usage overages (exceeding monthly AI request limits), hosting costs, database services, and supporting tools. Set spending caps in tool settings to avoid surprise bills—start with $50-100 cap and adjust based on your building pace.
### When should I graduate from Lovable to professional tools?
Graduate when you hit customization limits (usually after 2-3 months of active building) or when code export becomes necessary. Signs you've outgrown Lovable: spending more time working around platform limitations than building features, needing custom backend logic the platform doesn't support, or requiring integrations Lovable doesn't offer. Migrate to Cursor or Claude Code when you need full control over your codebase and professional deployment workflows.
### Can I use multiple vibe coding tools together?
Yes, most successful builders use multiple tools strategically: Bolt for quick prototypes, Cursor or Claude Code for production features, v0 for polished UI components, and BrainGrid for spec creation. Start with one primary tool for 2-4 weeks until comfortable, then add specialized tools for specific tasks. Using 2-3 tools in combination is common—the key is having a clear primary tool and adding others only when you hit limitations.
### What Are Common Pitfalls in Vibe Coding?
#### Pitfall 1: Blindly Accepting AI Code
AI agents will give you code and explain how it works—but they can be wrong. Review the code and verify it does what you expect. Blindly accepting changes can move things forward, but also break things in ways the AI can't fix—leading to frustrating rabbit holes and lost time.
#### Pitfall 2: Skipping Version Control (Git)
Made a mistake? (Maybe you ignored Pitfall 1.) Version control lets you "go back" to the working version and try your prompts again. Without it, one bad change can cost hours of rework.
#### Pitfall 3: Building Without Clear Requirements
In the daily-pulse example, the requirements seemed clear—but each agent interpreted them differently. The more detailed your prompt, the less likely agents will get "creative" with unwanted features.
#### Pitfall 4: Not Setting Spending Caps
All vibe tools have monthly limits. You can extend spending, but set a monthly cap—otherwise, you might be surprised by your bill.
#### Pitfall 5: Ignoring Security Until Launch
Vibe coding focuses on product, but you must also ensure code security. Work with your agents to review security before launch. You don't want to ship a SaaS with a [database wide open to the internet](https://www.404media.co/exposed-moltbook-database-let-anyone-take-control-of-any-ai-agent-on-the-site/).
---
# 7 Best Replit Alternatives in 2026 (Free & Paid Options)
Source: https://www.braingrid.ai/blog/replit-alternatives
Published: 2026-01-29T10:00:00Z
Looking for **Replit alternatives**? You're not alone. Replit is great for getting started—no setup needed, code right in your browser. But as your projects grow, you might hit some limits.
Maybe your database keeps crashing. Or the AI suggestions don't match your code style. Perhaps you need better team collaboration, or you're looking for a **free Replit alternative** that's more powerful.
We've tested the platforms developers actually switch to when they outgrow Replit. Here are the best options, whether you're coding in Python, JavaScript, or building web apps.
## Quick Comparison: Best Replit Alternatives 2026
Here's a quick look at the top **Replit alternatives** we'll cover:
| Tool | Best For | Key Feature |
|------|----------|-------------|
| **BrainGrid AI** | Planning before coding | Helps clarify what to build |
| **GitHub Codespaces** | Teams and companies | Works with GitHub, consistent setups |
| **Cursor** | AI coding help | Understands your whole project |
| **Bolt.new** | Quick prototypes | Builds apps from text prompts |
| **v0 by Vercel** | Professional UI components | Generates beautiful React components |
| **Emergent.sh** | Full-stack AI apps | Multi-agent system builds complete apps |
| **Lovable** | AI app builder | Builds full apps from descriptions |
Looking specifically at Lovable? Check out our [Lovable alternatives](/blog/lovable-alternatives) guide for more options in that space.
Now let's dive into each one to help you find the best **Replit alternative** for your needs.
## 1. BrainGrid AI: Plan Before You Code
**What it is:** BrainGrid helps you figure out what to build before you start coding. It's not a code editor—think of it as a planning tool that works with any coding platform.
**The problem it solves:** Ever ask an AI to "add user login" and get something that's missing password reset, or doesn't work with your existing code? That's because the [requirements weren't clear](/blog/spec-driven-development) from the start.
**How it works:**
1. You describe what you want to build
2. BrainGrid asks smart questions: What happens if something goes wrong? How does this connect to your existing features?
3. You get a clear plan with specific tasks
4. Then you code in Replit, Cursor, or any tool you prefer
**Key features:**
- Asks questions you might not think of
- Breaks big features into smaller, clear tasks
- Works with any coding tool (Replit, Cursor, etc.)
- Helps avoid "that's not what I meant" moments
**Good for:**
- When requirements keep changing
- Complex projects where details matter
- Teams that need to plan before coding
- Anyone tired of rebuilding features
**Bottom line:** If you keep rebuilding features because the requirements weren't clear, BrainGrid helps you get it right the first time.
## 2. GitHub Codespaces: Best for Teams
**What it is:** GitHub Codespaces lets you code in the cloud using VS Code. It connects directly to your GitHub projects, so your whole team works in the same environment.
**The problem it solves:** Ever heard "it works on my computer"? When everyone has different setups, things break. Codespaces fixes this by giving everyone the exact same environment.
**How it works:**
1. You create a config file that describes your setup (Node version, Python packages, etc.)
2. Save it to your GitHub project
3. Anyone who opens the project gets the same environment automatically
4. No more "install this, install that" meetings
**Key features:**
- Everyone gets the same setup (no more "works on my machine")
- Works in your browser or on your computer
- Built-in AI coding help (GitHub Copilot)
- Secure and trusted by big companies
- Works great with GitHub projects
**Good for:**
- Teams that need everyone on the same page
- Companies that need security and compliance
- Projects already on GitHub
- When onboarding new team members takes too long
**How to switch from Replit:** Export your project to GitHub, add a simple config file, and you're done. Takes about an hour.
**Bottom line:** If your team struggles with different setups or you need enterprise security, Codespaces is worth considering.
## 3. Cursor: Best AI Coding Assistant
**What it is:** Cursor is like VS Code but with super-smart AI that understands your whole project, not just the file you're working on.
**The problem it solves:** Replit's AI (Ghostwriter) only sees the file you're editing. It doesn't know about your other files, your code style, or how your project is organized. Cursor sees everything, so its suggestions actually fit your code.
**How it works:**
1. Install Cursor on your computer (it's not browser-based like Replit)
2. Open your project
3. The AI learns your code style and project structure
4. When you ask for changes, it suggests code that matches your existing patterns
**Key features:**
- AI understands your whole project, not just one file
- Select code, press Cmd+K, describe what you want—it edits it
- Works with multiple AI models (Claude, GPT-4)
- Works offline once installed
- Built-in Git support
**Good for:**
- When AI suggestions keep missing your code style
- Developers who want smarter AI help
- Projects where code quality matters
- Anyone comfortable coding on their computer
**How to switch from Replit:** Download your project from Replit, open it in Cursor. The AI learns your code in minutes.
**Bottom line:** If you want AI that actually understands your project and suggests code that fits, Cursor is the best option.
## 4. Bolt.new: Build Apps Instantly from Text
**What it is:** Bolt.new turns your text descriptions into working apps instantly. Type what you want, get a live app with a shareable link—no setup, no deployment steps.
**The problem it solves:** Need a working demo by end of day? Replit still requires setup and configuration. Bolt.new skips all that and just builds your app.
**How it works:**
1. Type what you want: "Build a task manager with a calendar view"
2. Bolt.new creates the full app (frontend, backend, database)
3. Deploys it automatically
4. Gives you a link to share
It handles React, Node.js, databases, and even mobile apps (React Native) automatically.
**Key features:**
- Builds full apps from text descriptions
- Deploys instantly with shareable links
- Works for web and mobile apps
- No configuration needed
- Great for showing ideas to clients
**Good for:**
- Quick prototypes and demos
- Non-technical founders testing ideas
- Agencies showing concepts to clients
- When speed matters more than perfect code
**Bottom line:** If you need a working app fast to show an idea, Bolt.new is the fastest option. Perfect for prototypes, not for production apps.
## 5. v0 by Vercel: Professional UI Components
**What it is:** v0 by Vercel generates beautiful React components that look professionally designed. It's not a full coding environment—it's a tool for building UI components quickly.
**The problem it solves:** Replit's AI can generate code, but the UI often looks basic or unpolished. v0 creates components with proper spacing, typography, and visual hierarchy—the kind of UI that looks hand-crafted.
**How it works:**
1. Describe what you want: "A pricing table with three tiers"
2. v0 generates React component code with shadcn/ui
3. Copy the code into your project
4. Customize as needed
It's built by Vercel and works perfectly with Next.js and shadcn/ui.
**Key features:**
- Generates professional-looking components
- Works with React and Next.js
- Uses shadcn/ui (popular component library)
- Components have proper design (spacing, typography, etc.)
**Good for:**
- Building Next.js apps
- When you care about how your app looks
- Developers who know the difference between "functional" and "professionally designed"
- Accelerating UI work
**Bottom line:** If you're building Next.js apps and want professional UI components fast, v0 is perfect. It generates code that actually looks good.
## 6. Emergent.sh: Full-Stack AI App Builder
**What it is:** Emergent.sh is a full-stack AI coding platform that builds complete applications. You describe what you want using natural language, and Emergent's multi-agent system builds it for you.
**The problem it solves:** Replit's AI (Ghostwriter) helps you code, but you still do most of the work. Emergent uses multiple specialized AI agents that work together to build entire apps—code, tests, deployment, and optimization.
**How it works:**
1. Describe your app idea in plain English
2. Emergent's agents work together:
- Builder Agent creates the code
- Quality Agent runs tests
- Deploy Agent handles deployment
- Optimizer Agent improves SEO and accessibility
3. You get a complete, working application
It runs in your browser on Google Cloud. You can build with React, Next.js, Expo, or Python, and you have full access to the code.
**Key features:**
- Multi-agent system (different AI agents for different tasks)
- Builds complete full-stack apps
- Runs in browser (no local setup)
- Works with React, Next.js, Expo, Python
- Full code access and export
- Often more reliable than single-agent systems
**Good for:**
- Developers who want full-stack control with AI help
- Non-technical founders building production apps
- Teams that need reliable AI workflows
- Complex projects that need multiple AI agents
**Bottom line:** If you want AI that builds complete apps (not just helps you code), Emergent's multi-agent system is designed to be more reliable than single-agent tools. Great for full-stack projects.
## 7. Lovable: AI App Builder from Descriptions
**What it is:** Lovable is an AI web app builder that creates full-stack applications from text descriptions. Describe your app idea in plain English, and Lovable builds it for you—no coding required.
**The problem it solves:** Replit still requires you to code, even with AI help. Lovable lets non-technical founders describe what they want and get a working app. It's popular with people who want to validate ideas fast without hiring developers.
**How it works:**
1. Describe your app idea
2. Lovable generates the full-stack application
3. You get a working app you can customize
4. Deploy when ready
The appeal is speed—ideas become clickable demos in minutes instead of weeks.
**Key features:**
- Builds full-stack apps from descriptions
- No coding knowledge required
- Fast prototyping and validation
- Great for non-technical founders
- Customizable generated code
**Good for:**
- Non-technical founders validating ideas
- Quick prototypes and demos
- When you need an app fast
- People who want to build without coding
**Bottom line:** If you're not technical but want to build apps fast, Lovable turns ideas into working software quickly. Perfect for validating ideas, less ideal for complex production apps.
## How to Choose the Best Replit Alternative for You
Don't pick based on features. Pick based on what's actually slowing you down.
### What Problem Are You Trying to Solve?
**"My database keeps crashing"**
→ Try **GitHub Codespaces** for more reliable infrastructure
**"The AI doesn't understand my code"**
→ Use **Cursor** for smarter AI, or **BrainGrid** to plan better so any AI works
**"Onboarding new team members takes forever"**
→ **GitHub Codespaces** sets up environments automatically
**"I need a working demo by end of day"**
→ **Bolt.new** builds apps instantly, or use **BrainGrid** first if you need to clarify requirements
**"Requirements keep changing while I code"**
→ **BrainGrid** helps you plan first, then code in any tool
**"I want professional UI components fast"**
→ **v0 by Vercel** generates beautiful React components
**"I need full control"**
→ **Cursor** on your computer gives you complete control
## Using Multiple Tools Together
You don't have to pick just one. Many successful teams use different tools for different jobs:
**Planning:** Use **BrainGrid** to figure out what to build
**Coding:** Use **Cursor**, **Codespaces**, or your preferred tool
**Quick prototypes:** Use **Bolt.new** when you need something fast
**Deployment:** Use whatever deployment method works for you
**Example workflow:**
1. Plan in **BrainGrid** → Get clear requirements and tasks
2. Code in **Cursor** → AI understands your project
3. Build UI with **v0** → Professional components fast
4. Deploy normally
The best teams mix tools to solve different problems. You don't need one tool that does everything.
## Quick Comparison Table
| Feature | Replit | BrainGrid | Codespaces | Cursor | Bolt.new | v0 | Emergent.sh | Lovable |
|---------|--------|-----------|------------|--------|----------|----|-------------|--------|
| **Setup** | Instant | Web-based | Seconds | Local | Instant | Web | Browser | Browser |
| **AI Help** | Basic | Planning | Copilot | Advanced | Full-stack | UI gen | Multi-agent | Full-stack |
| **Team Features** | Basic | Planning | Enterprise | Limited | Sharing | Limited | Good | Basic |
| **Deployment** | Built-in | N/A | Manual | Manual | Instant | Manual | Built-in | Built-in |
| **Best For** | Learning | Planning | Teams | Local dev | Prototypes | UI components | Full-stack AI | App builder |
## Popular Questions About Replit Alternatives
### What are the best Replit alternatives Reddit recommends?
Based on Reddit discussions, popular **Replit alternatives** include:
- **GitHub Codespaces** - Often recommended for teams and Python projects
- **Cursor** - Frequently mentioned for better AI coding assistance
- **v0 by Vercel** - Popular for professional UI components
- **Emergent.sh** - Recommended for full-stack AI app building
- **Lovable** - Often suggested for non-technical founders
Many Reddit users also mention that **Replit is still good for beginners**, but these alternatives are better as projects grow.
### Are there open source Replit alternatives?
Most alternatives are not fully open source, but they offer free options:
- **v0 by Vercel** - Completely free
- **Emergent.sh** - Free options available
- **Lovable** - Free options available
For truly open source development environments, you might consider setting up your own with VS Code and Docker, but this requires more technical knowledge.
### What about Replit alternatives for Python?
**Replit is actually still one of the best options for Python beginners.** But if you need more features:
- **GitHub Codespaces** - Excellent for Python with team features
- **Cursor** - Great for Python with smart AI assistance
- **Local development** - VS Code + Python on your computer gives full control
For Python specifically, many developers stick with Replit for learning, then move to Codespaces or local development for serious projects.
## Frequently Asked Questions About Replit Alternatives
### What are the best free Replit alternatives in 2026?
**v0 by Vercel** is completely free for generating UI components. **GitHub Codespaces** offers free hours monthly for individual developers.
**BrainGrid** helps you plan your projects before you code.
**Emergent.sh** and **Lovable** also offer free options to get started.
### What are the best Replit alternatives for Python?
**GitHub Codespaces** and **Cursor** both work great with Python. **Replit** is still actually one of the best options for Python beginners, but if you need more power or team features, Codespaces is the way to go.
### Are there free alternatives to Replit?
**v0 by Vercel** is completely free. **GitHub Codespaces** offers free hours monthly. **Emergent.sh** and **Lovable** both offer free options.
These free options are great alternatives to Replit's paid plans.
### Can I migrate my Replit projects?
Yes! Most alternatives work with GitHub:
1. Export your Replit project to GitHub (Replit has a built-in export feature)
2. Import to your new tool:
- **GitHub Codespaces**: Just open the repo, add a simple config file
- **Cursor**: Download and open locally
- **Emergent.sh/Lovable**: Import from GitHub or start fresh
Most projects migrate in under an hour.
### Which Replit alternative has the best AI?
**Cursor's** AI understands your whole project, not just one file. This makes its suggestions much more useful.
**BrainGrid** helps you plan better, so any AI (including Replit's) builds the right thing.
**GitHub Copilot** (in Codespaces) is also very good, though not quite as smart as Cursor.
### Do any Replit alternatives work offline?
**Cursor** works completely offline once you install it (it runs on your computer).
Most cloud-based tools (Codespaces, Emergent.sh, Lovable, v0) need internet.
### What's the best Replit alternative for teams?
**GitHub Codespaces** is best for bigger teams—it has security features, consistent environments, and works great with GitHub.
**Emergent.sh** is best if you need AI-powered full-stack app building with multi-agent systems.
**Lovable** is great for non-technical founders who want to build apps from descriptions.
### Which tool is best for learning to code?
**Replit** is still excellent for absolute beginners—it's the easiest to get started.
Once you're past the basics:
- **v0 by Vercel** helps you learn professional UI design
- **Emergent.sh** teaches full-stack development with AI
- **GitHub Codespaces** teaches professional workflows
### Can I use these for production apps?
**Yes, but choose carefully:**
- **GitHub Codespaces**: Great for production (used by big companies)
- **Cursor**: Perfect for production (full control on your computer)
**Better for prototypes:**
- **Bolt.new**: Fast but not built for production
- **Replit**: Can work but has limits at scale
**Planning only:**
- **BrainGrid**: Helps you plan, doesn't host apps
## Final Thoughts: Finding Your Replit Alternative
Replit is great for getting started, but everyone hits limits eventually. Maybe your database keeps crashing, or the AI isn't helpful, or you need better team features.
**The key:** Don't switch because "Replit is bad." Switch because something specific is blocking you.
**Quick decision guide:**
- Requirements keep changing? → **BrainGrid** helps you plan first
- Need enterprise features? → **GitHub Codespaces**
- Want smarter AI? → **Cursor**
- Need instant prototypes? → **Bolt.new** or **Lovable**
- Want professional UI components? → **v0 by Vercel**
- Need full-stack AI apps? → **Emergent.sh**
- Building apps without coding? → **Lovable**
**The smart approach:** Try one tool on one project first. See if it actually solves your problem. Then expand gradually.
Most successful teams use different tools for different jobs. **BrainGrid** for planning. Your preferred coding environment for building. Specialized tools when needed.
**Bottom line:** There are great **Replit alternatives** out there. The best one depends on what's actually slowing you down. Find your blocker, pick the tool that fixes it, and test it out.
The tools are ready. What problem are you trying to solve?
---
# Why AI Tool Validation Needs Two Layers (Not One)
Source: https://www.braingrid.ai/blog/two-layer-ai-tool-validation
Published: 2026-01-28T12:00:00Z
For weeks, our BrainGrid Requirements Agent had a nasty habit. It would be happily creating tasks, breaking down requirements, doing exactly what it was supposed to do—and then it would just die. No graceful error. No helpful message. The entire conversation would blow up and become completely unrecoverable.
Users had to start over. Every. Single. Time.
We knew exactly what was happening. The AI model would occasionally send tool arguments that passed JSON syntax validation but failed semantic validation—an array with wrong element types, a number outside valid range, a missing required field. Our Zod schemas would reject the input, and the whole thing would crash.
We were playing whack-a-mole trying to fix it.
## The Gap Between Syntax and Semantics
When you're building AI agents with tool calling, `strict: true` and Anthropic's structured outputs feature sound like exactly what you want. Constrained decoding ensures the model physically cannot generate malformed JSON. Every token matches the JSON schema.
Here's the catch that took us weeks to fully understand: **constrained decoding prevents syntax errors, not semantic errors.**
The model can't produce `{title: }` (invalid JSON). But it CAN produce `{"blocked_by": "task-1"}` when the schema expects an array. It parsed correctly—it's just wrong.
Here's what our tool definition looked like:
```typescript
// Tool definition with schema validation
const createTaskTool = {
name: 'create_task',
description: 'Creates a new task',
inputSchema: CreateTaskInputSchema, // Zod schema
strict: true, // Enable Anthropic's constrained decoding
async execute(args: CreateTaskInput) {
// When Zod validation fails, this NEVER RUNS
console.log('Creating task:', args.title);
return await taskService.create(args);
}
};
```
The SDK flow: model generates output → constrained decoding ensures valid JSON → SDK parses JSON → SDK validates against Zod schema → **if Zod throws, execute() never runs**.
See the problem? Anthropic's `strict: true` does its job—the JSON is always syntactically valid. But Zod validation happens *after* JSON parsing and *before* your execute function. When Zod throws (wrong types, out-of-range values, missing fields), your code never sees the input. The SDK catches the error, the API returns a failure, the model retries with similar bad input, fails again, and the conversation enters a death loop.
The user sees: "Error processing your request. Please try again."
They try again. Same error. Conversation is now unrecoverable.
You can't catch what you can't see.
## The Whack-a-Mole Phase
We tried everything the SDK offered. Every attempt followed the same pattern: implement "fix," deploy, wait for it to fail in a new way, repeat.
### Attempt #1: Lenient schema coercion
Maybe we could make the schema more forgiving? Coerce strings to arrays, handle type mismatches gracefully:
```typescript
// Defensive coercion - trying to be "helpful"
const coerceToStringArray = (val: unknown): string[] => {
if (Array.isArray(val)) return val.map(String);
if (typeof val === 'string') {
try { return JSON.parse(val); } // Model sent "[1, 2]" as a string
catch { return [val]; }
}
return [];
};
export const CreateTaskInputSchema = z.object({
title: z.string().min(1),
blocked_by: z.preprocess(coerceToStringArray, z.array(z.string())),
// ... increasingly complex coercion for every field
}).strict();
```
This helped with some edge cases. But the schema became unreadable, and we were still playing whack-a-mole with new malformed inputs. Worse: `.strict()` would still reject any unexpected properties, and we were still throwing before `execute()` could run.
### Attempt #2: experimental_repairToolCall
The SDK has a hook specifically for this! Intercept the failed tool call and fix it:
```typescript
const result = await streamText({
model,
tools,
experimental_repairToolCall: async ({ toolCall, error }) => {
// Try to fix the malformed input
const fixed = attemptRepair(toolCall.args, error);
return { ...toolCall, args: fixed };
},
});
```
Sounds perfect. The problem? If your repair logic *also* fails—and it will, because you're trying to guess what the model meant to send—the conversation still dies. And you have to write repair logic for every possible way every tool's input could be malformed. How much defensive code do you want to write for every permutation of garbage an AI model can send?
The answer is none. That's insane.
### Attempt #3: Error callbacks
We tried catching errors in `onStepFinish`, `onError`, everywhere the SDK would let us:
```typescript
const result = await streamText({
model,
tools,
onError: (error) => {
// By the time this fires, it's too late
// The tool call already failed, the model is retrying,
// and we're in a death loop
logger.error('Tool call failed', error);
},
});
```
By the time these callbacks fire, the damage is done. The tool call has already been rejected at the SDK level. The model retries. Same bad input. Same rejection. The user watches their cursor spin until the whole thing times out.
Nothing worked. The fundamental problem remained: strict mode validates before your code runs. Full stop.
## The Two-Layer Solution
The breakthrough wasn't abandoning validation—it was splitting it into two layers. (If you're working with the Vercel AI SDK, our [AI SDK v5 migration guide](/blog/migrating-to-ai-sdk-v5) covers related patterns.)
**Layer 1: LLM-level (keep `strict: true`)** — Anthropic's constrained decoding ensures syntactically valid JSON. This stays.
**Layer 2: App-level (permissive input, graceful validation)** — Accept any valid JSON object at the SDK boundary, then validate inside `execute()` where you can catch errors and return helpful messages.
Here's what that looks like:
```typescript
// Layer 1: Permissive input schema - accepts any object
// The SDK won't throw, so execute() always runs
export const CreateTaskInputSchema = z.object({}).passthrough();
// Layer 2: Strict validation schema - used inside execute()
export const CreateTaskValidationSchema = z.object({
title: z.string().min(1),
content: z.string().min(1),
complexity: z.number().min(1).max(5).optional(),
blocked_by: z.preprocess(coerceToStringArray, z.array(z.string())).optional(),
});
```
The SDK sees a permissive schema: "accept any object." The real validation happens inside `execute()` where we control the error handling:
```typescript
async execute(args: unknown, context?: ToolExecutionContext): Promise {
const parsed = CreateTaskValidationSchema.safeParse(args);
if (!parsed.success) {
const errorDetails = parsed.error.errors
.map(e => `${e.path.join('.')}: ${e.message}`)
.join('; ');
// Return the error WITH the expected schema
return {
success: false,
error: `Invalid arguments: ${errorDetails}. Retry with correct schema:\n${expectedSchema}`,
};
}
// Now we have validated, typed data
const { title, content, complexity } = parsed.data;
// ... rest of the tool logic
}
```
The key insight: when validation fails, we don't throw. We return a structured error that includes the expected schema. The model sees exactly what it got wrong and what it should send instead. It retries. The user never knows anything happened.
## The Results
Twelve files changed. 358 lines added. And the numbers speak for themselves:
**Before the fix (Jan 18-23):**
- 85 `toolUse.input is invalid` errors
- 5,613 agent conversations
- **1.5% failure rate** (peaking at 3.3% on heavy days)
**After the fix (Jan 24):**
- 0 errors
- 81 conversations
- **0% failure rate**
Here's an actual error from our logs before the fix:
```text
AI_APICallError: The format of the value at
messages.7.content.9.toolUse.input is invalid.
Provide a json object for the field and try again.
```
The model sent something that looked like valid JSON but failed semantic validation. The SDK rejected it. The model retried with the same bad input. Death loop. Session dead.
Now, conversations that would have crashed recover gracefully. We also added monitoring—every validation failure emits a `tool.failed` event so we can track patterns and improve our prompts over time. For more on optimizing tool performance, see our post on [Anthropic tool caching with AI SDK v5](/blog/anthropic-tool-caching-ai-sdk-v5).
## The Takeaway
The insight isn't that strict mode is bad—it's that **you need two layers of validation for AI tool calling**:
1. **LLM-level constraints** (`strict: true`) prevent malformed JSON. Keep this. Constrained decoding genuinely reduces errors.
2. **App-level validation** (permissive input + safeParse) handles the semantic errors that slip through. This is where you catch wrong types, out-of-range values, and missing fields—and return helpful error messages instead of crashing.
This isn't a hack or a workaround. It's the Input DTO / Validation DTO pattern that backend developers have used for decades, applied to AI tool calling. Accept wide at the boundary, validate narrow inside your handler.
The difference matters: when validation fails, your user doesn't see "Error processing your request." They don't even know anything went wrong. The model sees exactly what it got wrong, corrects itself, and continues.
That's the goal. Graceful recovery, invisible to the user.
---
# Vibe Coding Turns One: The Year That Changed How We Build Software
Source: https://www.braingrid.ai/blog/vibe-coding-turn-one
Published: 2026-01-27T12:00:00Z
A year ago, "vibe coding" didn't exist. Today, it has become the 'go-to' tool for developers, and even for startup founders with little or no coding experience. How did that happen in the space of less than one year?
It all started (as things sometimes do) with a [tweet](https://x.com/karpathy/status/1886192184808149383):
Andrej Karpathy is an influential AI expert, who has worked at Tesla and OpenAI. His tweet put a name to what many developers had begun doing - writing code by using plain English prompts with LLMs.
By the end of the year, the [Stack Overflow](https://survey.stackoverflow.co/2025/ai#1-ai-tools-in-the-development-process) developer survey found that 84% of developers vibe code (or plan to start vibe coding), and 47% vibe code every day. The study also found that 41% of all code is AI-generated.
The capping achievement — signifying that vibe coding has hit the mainstream — [Collins Dictionary](https://www.collinsdictionary.com/woty) made `vibe coding` its word of the year for 2025.
## What Is Vibe Coding? A Definition for the Anniversary
Vibe coding is a huge shift in the way code is written. Rather than typing each line of code, developers describe what they want in natural language, and let AI agents generate the code. It is generally used to complete larger projects, features or modules of code.
Karpathy's definition in his tweet describes a very cavalier approach to vibe coding ("Fully give in to the vibes...and forget that the code even exists."). He expands the vibe to include that he just runs with whatever the LLM spits out - blindly accepting every line of code, not reading the differences, and offering the LLM random changes to fix bugs in his code.
Most vibe coding developers use more nuance. The Stack Overflow survey found that 19.6% of developers highly distrust the output of AI tools, and only 33% have trust in the output. When vibe coding on a commercial product, vibe coders find that they must be more careful - reviewing and analyzing the code before accepting it.
### Vibe coding vs. autocomplete
GitHub Copilot is an autocomplete AI that ingests the code being typed and creates autocompleted segments of code. Vibe coding is (generally) used for larger scale code changes like adding features, or refactoring sections of code.
## What Existed Before Karpathy Named It?
Vibe coding existed before the name was coined. Copilot launched in 2021, ChatGPT in 2022, and Cursor Composer in 2024 - all lowering the barrier for developers to use AI agents as a part of their coding tooling. In 2023, Karpathy himself [tweeted](https://x.com/karpathy/status/1617979122625712128) "The hottest new programming language is English."
AI began with the autocomplete tools, and as LLMs become more powerful, developers began leveraging them to write and analyze code from English prompts. At the dawn of 2025, Agentic AIs were entering the marketplace giving rise to agents capable of multi-step execution, full repository awareness and partial autonomy - the ability to "just build it."
By the time Karpathy tweeted about vibe coding in February 2025, millions of people were already using AI to code, and the wave of agentic tools to reason and write code was taking off. They just didn't have a name for it yet.
### Further back: the evolution of coding
Vibe coding is the next abstraction of coding. Assembly hid machine code. C hid assembly. Python hid memory management. Vibe coding further abstracts coding away from the programming language to the written word. Each abstraction step in programming has been met with resistance from traditionalists. But each abstraction step eventually won, and became the preferred way for code to be created.
## 2025: The Year Everything Accelerated
The massive adoption of vibe coding didn't happen because it was given a name. The explosion in vibe coding tooling — and the interest in these tools from the developer community — drove the massive acceleration.
[Cursor](/blog/cursor-pricing), [Claude Code](/blog/claude-code-mcp), [Windsurf](/blog/windsurf-mcp) are among the new tools that allowed Agentic AI vibe coding to take off in 2025.
All of a sudden AI wasn't just commenting or making small changes. AI was taking the entire code context and creating new features based on existing code. Agents now plan, implement, review, test, and fix code — all from a single prompt.
2025 also saw the rise of [Model Context Protocol](/blog/cursor-mcp) which gives the agents even deeper access - into databases, APIs, documentation, and issue repositories - with all the added context, the generated code begins to *just work* the first time, with less and less developer interaction.
All of these tools have led to immense growth, and with 84% of developers using vibe coding tools, we can expect this number to continue to increase.
## From Vibe Coding to Viable Code
One of the biggest struggles in gaining proficiency with vibe coding is learning to [prompt properly](/blog/spec-driven-development). Just like any chat with an LLM, the better you frame the question, the better the response will be. The better the response, the less time you spend [reprompting](/blog/i-built-a-vibe-coding-mess), or chasing fixes with new prompts.
Taking time to generate detailed and comprehensive prompts may take a little longer up front, but you will spend much less time vibing solutions to the pieces that were missed. This small initial time investment reaps hours saved on the other end with refactors, regressions and incomplete code creation.
One tool that has been very helpful with my journey to vibe coding has been [BrainGrid](https://www.braingrid.ai). BrainGrid is an AI Product Planner - it helps flesh out ideas, and generate the best possible prompts for your vibe coding system. Rather than typing your ideas to the coding AI, you give your prompt to BrainGrid. It analyzes your prompt, asks clarifying questions about the feature or function you are building, and creates a detailed requirements document:
You can iterate with the BrainGrid AI to generate the perfect requirements document - getting insights and features you may not have initially thought about, but that will make your product more compelling. Then you can use BrainGrid to break the requirements into tasks — highly detailed prompts that give the AI agonizing detail that developers would take days to think out and write down. Using the [BrainGrid MCP](https://docs.braingrid.ai/mcp-server/overview) your vibe coding agent can read the prompts from the tasks, and build the feature you have in mind.
The detailed prompts from BrainGrid protect you as a developer: dodgy prompts lead to incorrect code, and many iterations of refactoring.
## Looking Ahead: What Year Two Looks Like
Vibe coding is celebrating its first anniversary in February 2026. After a momentous year, and being named the 'word of the year' in 2025 - what's next?
Next, agents will move from writing features to *owning* them. They'll persist across sessions and interact with each other. When frontend changes are made, the FE agents will interact with the BE agents to ensure that the code is correctly formatted to run the first time. The agents will be able to track other changes, technical debt, and proactively suggest fixes.
Specifications and features - like those created with BrainGrid - will replace the prompt. There will be default requirements that are held for each new code release to ensure that the new code remains stable, fast, and does not break existing features in the codebase.
## What This Means for You
Builders will stop typing code, and instead focus on shaping requirements, reviewing changes, and approving AI output. IDEs will move from the place where developers build, to a place where they monitor agents and the queues of the agents.
Founders with no coding experience will have greater success 'vibing' their MVP, and maybe even taking their service live - without hiring a developer!
The future of software development will be intertwined with vibe coding and AI agents. The momentum of the innovation seen in 2025 has not slowed and will only accelerate through 2026 and beyond. If you have not yet tried vibe coding, see our many reviews of vibe coding tools [Windsurf vs. Cursor](/blog/windsurf-vs-cursor), [Claude Code vs. Cursor](/blog/claude-code-vs-cursor), and more. Finally, vibe coding is not complete without AI Product Planning. We think [BrainGrid](https://www.braingrid.ai) is a great option to help build the best vibe coding prompts possible.
## FAQ
### What is vibe coding?
Vibe coding is an AI-assisted development practice where you describe what you want in natural language and let AI generate the code, accepting changes based on whether things work rather than reviewing every line. The term was coined by Andrej Karpathy in February 2025 and became Collins Dictionary's 2025 Word of the Year.
### Who invented vibe coding?
Andrej Karpathy, former AI lead at Tesla and co-founder of OpenAI, coined the term in a February 2025 tweet. However, the practice itself had been emerging for years through tools like GitHub Copilot (2021) and ChatGPT (2022). Karpathy gave a name to something millions were already doing.
### When did vibe coding start?
The term "vibe coding" was coined on February 2, 2025 in Karpathy's viral tweet. The underlying practice—using AI to generate code from natural language descriptions—had been growing since GitHub Copilot launched in June 2021 and accelerated dramatically after ChatGPT's release in November 2022.
### Is vibe coding safe for production?
Vibe coding can be safe for production when combined with structure and review. The problems emerge when developers accept AI output blindly without specs, tests, or verification. Tools like BrainGrid formalize "spec-driven development" to keep vibe coding's speed while adding necessary discipline.
### What's the difference between vibe coding and traditional coding?
Traditional coding involves writing and reviewing every line yourself. Vibe coding involves describing what you want and letting AI write the code, focusing your attention on whether outcomes work rather than implementation details. It's a shift from "writing code" to "directing AI."
### Will vibe coding replace programmers?
Vibe coding is changing what programmers do, not eliminating the need for them. By 2026, the emerging role is "Orchestrator"—someone who defines intent, sets constraints, and reviews AI output. Employment for junior developers has dropped 20% ([Stanford study](https://digitaleconomy.stanford.edu/app/uploads/2025/11/CanariesintheCoalMine_Nov25.pdf)), but senior engineers who master AI direction are more valuable than ever.
---
# How to Add MCP Servers to Gemini CLI (Step-by-Step)
Source: https://www.braingrid.ai/blog/gemini-mcp
Published: 2026-01-26T10:00:00Z
I've been using **Gemini CLI MCP servers** for a while now, and they've completely changed how I build with AI. Instead of copying schemas into every prompt and fixing placeholder code, Gemini connects directly to my databases, APIs, and specifications through the Model Context Protocol.
In this guide, I'll walk you through everything you need to configure **MCP servers in Gemini CLI**. From basic setup to advanced configurations with tools like **BrainGrid**.
## What is a Gemini CLI MCP Server?
A **Gemini CLI MCP server** is a bridge between Google's Gemini CLI and external services. MCP (Model Context Protocol) gives Gemini context beyond your local files. Think databases, APIs, cloud services, and project specifications.
When you connect a database MCP server to Gemini CLI, it can examine your actual tables and columns. The SQL it generates uses real schema names, not placeholders. When you connect **BrainGrid MCP**, Gemini reads your requirements and acceptance criteria directly, building features that match your specifications.
**What Gemini CLI MCP servers enable:**
- Query live database schemas
- Fetch real API responses
- Read structured specifications from BrainGrid
- Access GitHub issues, PRs, and commit history
- Connect to cloud infrastructure (AWS, GCP)
Here's how the flow works:
```mermaid
sequenceDiagram
participant You
participant Gemini CLI
participant MCP Server
participant External Service
You->>Gemini CLI: "Show me REQ-142 from BrainGrid"
Gemini CLI->>MCP Server: Call get_requirement tool
MCP Server->>External Service: Fetch requirement data
External Service-->>MCP Server: Requirement with acceptance criteria
MCP Server-->>Gemini CLI: Structured response
Gemini CLI-->>You: Full spec ready to implement
```
MCP transforms Gemini from a code generator into a context-aware development partner.
## Why Gemini CLI MCP Servers Matter for Developers
Without MCP servers, every Gemini CLI session starts from scratch. You paste schemas, explain API structures, and fix the same boilerplate over and over. That copy-paste cycle kills momentum.
**With Gemini CLI MCP servers configured:**
- Database queries use your actual schema
- API code handles real response formats
- Specifications stay consistent across sessions
- Less manual fixing, faster shipping
The pattern applies across your entire stack. A GitHub MCP server gives Gemini context about open issues. A Stripe MCP server lets it understand billing flows. **BrainGrid MCP** provides structured requirements instead of vague prompts.
When Gemini has direct access to your systems, the code it generates works the first time.
## How to Set Up Gemini CLI MCP Servers
Gemini CLI supports MCP server configuration through two methods. You can use CLI commands for quick setup, or JSON configuration files for persistent settings.
### Adding Gemini MCP Servers via CLI
The `gemini mcp add` command configures MCP servers without editing files manually.
**Add a remote HTTP MCP server (like BrainGrid):**
```bash
gemini mcp add --transport http braingrid https://mcp.braingrid.ai/mcp
```
**Add a remote SSE MCP server:**
```bash
gemini mcp add --transport sse my-sse-server https://api.example.com/sse
```
**Add a local stdio MCP server:**
```bash
gemini mcp add my-local-server python server.py -- --port 8080
```
The `--` separates Gemini CLI flags from arguments passed to the MCP server process.
**Add MCP server with environment variables:**
```bash
gemini mcp add -e GITHUB_TOKEN=$GITHUB_TOKEN github npx -y @modelcontextprotocol/server-github
```
**Add MCP server with custom headers:**
```bash
gemini mcp add --transport http --header "Authorization: Bearer $TOKEN" my-api https://api.example.com/mcp
```
By default, Gemini CLI adds MCP servers to the project config (`.gemini/settings.json`). Use `-s user` to add to user config (`~/.gemini/settings.json`) instead.
### Configuring Gemini MCP Servers in settings.json
For persistent Gemini CLI MCP configuration, edit your `settings.json` file directly.
**Gemini CLI MCP config file locations:**
- User config: `~/.gemini/settings.json`
- Project config: `.gemini/settings.json`
Here's an example `settings.json` with multiple MCP servers configured:
```json
{
"mcpServers": {
"braingrid": {
"httpUrl": "https://mcp.braingrid.ai/mcp"
},
"github": {
"command": "npx",
"args": ["-y", "@modelcontextprotocol/server-github"],
"env": {
"GITHUB_TOKEN": "$GITHUB_TOKEN"
}
},
"postgres": {
"command": "npx",
"args": ["-y", "@modelcontextprotocol/server-postgres"],
"env": {
"DATABASE_URL": "$DATABASE_URL"
}
}
}
}
```
### Gemini CLI MCP Server Configuration Format
Each MCP server entry uses specific properties that determine how Gemini CLI connects.
**Transport is determined by property name:**
- `httpUrl` for HTTP streaming transport (remote hosted MCP servers)
- `url` for SSE transport (Server-Sent Events MCP servers)
- `command` for Stdio transport (local subprocess MCP servers)
```mermaid
flowchart LR
A[MCP Server Config] --> B{Which property?}
B -->|httpUrl| C[HTTP Streaming]
B -->|url| D[SSE Transport]
B -->|command| E[Stdio Transport]
C --> F[Remote hosted services like BrainGrid]
D --> G[Server-Sent Events endpoints]
E --> H[Local subprocess servers]
style A fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
style B fill:#795BC2,stroke:#C2E476,stroke-width:2px,color:#fff
style C fill:#10312D,stroke:#C2E476,stroke-width:2px,color:#C2E476
style D fill:#10312D,stroke:#C2E476,stroke-width:2px,color:#C2E476
style E fill:#10312D,stroke:#C2E476,stroke-width:2px,color:#C2E476
style F fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
style G fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
style H fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
```
**Gemini CLI MCP configuration properties:**
| Property | Description |
|----------|-------------|
| `httpUrl` | HTTP streaming endpoint URL for remote MCP servers |
| `url` | SSE endpoint URL for Server-Sent Events MCP servers |
| `command` | Executable path for local MCP servers |
| `args` | Arguments passed to the MCP server command |
| `env` | Environment variables (`$VAR` or `${VAR}` syntax) |
| `headers` | Custom HTTP headers for remote MCP servers |
| `cwd` | Working directory for local MCP servers |
| `timeout` | Request timeout in milliseconds (default: 600,000) |
| `trust` | Skip confirmation prompts when `true` |
| `includeTools` | Allowlist of MCP tool names to enable |
| `excludeTools` | Blocklist of MCP tool names to disable |
**Example Gemini MCP server with headers and timeout:**
```json
{
"mcpServers": {
"authenticated-api": {
"httpUrl": "https://api.example.com/mcp",
"headers": {
"Authorization": "Bearer $API_TOKEN",
"X-Custom-Header": "value"
},
"timeout": 30000
}
}
}
```
### Managing Gemini CLI MCP Servers
**List all configured MCP servers:**
```bash
gemini mcp list
```
**Remove an MCP server:**
```bash
gemini mcp remove braingrid
```
**Disable MCP server temporarily:**
```bash
gemini mcp disable braingrid
gemini mcp enable braingrid
```
**Check MCP server status inside Gemini CLI:**
```bash
/mcp
```
This displays connection status, available tools, and any errors for each configured MCP server.
## Best Gemini CLI MCP Servers for Developers
Here are the MCP servers I find most useful with Gemini CLI:
- **Database MCP servers**: PostgreSQL, MySQL, MongoDB, Redis, Supabase, Neon. Gemini queries schemas, understands relationships, and generates accurate SQL.
- **GitHub MCP server**: Read PRs, inspect issues, understand commit history. Repository context that influences code but doesn't live in local files.
- **Cloud platform MCP servers**: AWS, GCP, Heroku. Access deployment configs, logs, and environment-specific behavior.
- **Stripe MCP server**: Visibility into billing flows, subscriptions, webhooks. Debug payment logic with real context.
- **Playwright MCP server**: Browser automation and testing. Gemini runs and validates UI interactions.
- **BrainGrid MCP server**: Turns vague ideas into structured requirements, then breaks them into tasks. Gemini reads these specs and builds exactly what you specified.
## BrainGrid MCP Server: Spec-Driven Development in Gemini CLI
**BrainGrid** is an AI product manager that helps developers plan, specify, and build features. I've noticed most developers (myself included) jump straight into prompting before having a clear picture of what we're building. Running initial ideas through BrainGrid turns them into structured requirements.
Say you want to add user authentication. BrainGrid analyzes your codebase and asks clarifying questions. Which auth providers? What session handling? How to manage password resets? Your answers become a requirements document with explicit acceptance criteria. That's [spec-driven development](/blog/spec-driven-development). BrainGrid then breaks the requirement into implementation tasks.
```mermaid
flowchart LR
A[Rough idea] --> B[BrainGrid refines into requirement]
B --> C[Break down into tasks]
C --> D[Gemini builds via MCP]
D --> E[Working feature matches spec]
style A fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
style B fill:#795BC2,stroke:#C2E476,stroke-width:2px,color:#fff
style C fill:#795BC2,stroke:#C2E476,stroke-width:2px,color:#fff
style D fill:#10312D,stroke:#C2E476,stroke-width:2px,color:#C2E476
style E fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
```
The **BrainGrid MCP server** lets Gemini CLI access these requirements directly. Instead of copying specs into prompts, Gemini reads the full context and builds the feature precisely.
### Setting Up BrainGrid MCP Server in Gemini CLI
**Step 1:** Create a BrainGrid account at [app.braingrid.ai](https://app.braingrid.ai) and connect your GitHub repository.
**Step 2:** Add BrainGrid MCP server to Gemini CLI:
```bash
gemini mcp add --transport http braingrid https://mcp.braingrid.ai/mcp
```
Or add to your `settings.json`:
```json
{
"mcpServers": {
"braingrid": {
"httpUrl": "https://mcp.braingrid.ai/mcp"
}
}
}
```
**Step 3:** Run `/mcp` in Gemini CLI. On first connection, authorize BrainGrid via the browser popup.
### Using BrainGrid MCP with Gemini CLI
**Create a requirement in BrainGrid:**
```
Create a BrainGrid requirement for adding role-based access control
```
**View existing BrainGrid requirements:**
```
Show me REQ-142 from BrainGrid
```
**Build from a BrainGrid requirement:**
```
Build REQ-142
```
Gemini fetches the full spec including description, acceptance criteria, and technical constraints. It implements with that context. It knows what "done" looks like because the BrainGrid requirement defines it.
The result: Gemini builds exactly what you specified, with less cleanup afterward.
## Troubleshooting Gemini CLI MCP Server Issues
**MCP server shows DISCONNECTED:**
Check the URL for typos. Test connectivity with `curl https://mcp.braingrid.ai/mcp`. VPNs and firewalls can block MCP traffic.
**OAuth popup doesn't appear:**
Gemini CLI MCP OAuth requires a local browser. It won't work in headless servers or SSH sessions. Authenticate on a machine with a browser, then copy `~/.gemini/mcp-oauth-tokens.json` to the target machine.
**MCP tools not showing up:**
Run `/mcp` to check connection status. Verify `includeTools` isn't filtering them out. Complete OAuth authorization if required.
**MCP server timeout errors:**
Increase the timeout in your Gemini CLI MCP configuration:
```json
{
"mcpServers": {
"slow-server": {
"httpUrl": "https://api.example.com/mcp",
"timeout": 120000
}
}
}
```
**Stdio MCP server won't start on Windows:**
Wrap commands with `cmd`:
```json
{
"mcpServers": {
"windows-server": {
"command": "cmd",
"args": ["/c", "npx", "-y", "my-mcp-server"]
}
}
}
```
**Changes not taking effect:**
Restart Gemini CLI after modifying `settings.json` or adding new MCP servers.
## Start Building Faster with Gemini CLI MCP Servers
Once I started using MCP servers with Gemini CLI, I stopped thinking of AI as a code generator. It became something closer to a teammate that actually understands my project.
The shift is simple but powerful. Instead of explaining your database schema every session, Gemini just knows it. Instead of describing what you want to build, Gemini reads the spec you already wrote. Instead of fixing placeholder code, you review working implementations.
MCP servers remove the friction between what Gemini can do and what it actually knows about your project. That's the unlock.
Start with one server. Connect your database, or GitHub, or whatever tool you context-switch to most often. See how it changes your workflow. Then add more as you need them.
## Take It Further with BrainGrid
Here's what I've learned: the quality of AI output depends entirely on the quality of your input. Vague prompts produce vague code. Detailed specs produce precise implementations.
**[BrainGrid](https://www.braingrid.ai)** solves this at the source. It's an AI product manager that turns rough ideas into structured requirements before you start building. You describe what you want, BrainGrid asks clarifying questions, and you end up with a spec that has clear acceptance criteria.
The BrainGrid MCP server connects these specs directly to Gemini CLI. No copying. No context loss. Gemini reads your requirements and builds exactly what you specified.
If you're serious about shipping faster with AI, start with better specs.
**[Try BrainGrid free](https://www.braingrid.ai)**
## Frequently Asked Questions About Gemini CLI MCP Servers
### What is a Gemini CLI MCP server?
A Gemini CLI MCP server is a service that connects to Google's Gemini CLI through the Model Context Protocol (MCP). It gives Gemini context beyond your local codebase. This includes databases, APIs, cloud services, specifications, and any external system relevant to your application.
### How do I add an MCP server to Gemini CLI?
Use `gemini mcp add` for quick setup, or edit `settings.json` directly. For example: `gemini mcp add --transport http braingrid https://mcp.braingrid.ai/mcp`. User config lives at `~/.gemini/settings.json`, project config at `.gemini/settings.json`.
### Where is the Gemini CLI MCP configuration file located?
Gemini CLI stores MCP configuration in two locations:
- User-level: `~/.gemini/settings.json`
- Project-level: `.gemini/settings.json` in your repository root
### What MCP servers work with Gemini CLI?
Any MCP server using stdio (local), SSE, or HTTP streaming transport works with Gemini CLI. This includes database servers (PostgreSQL, MySQL), GitHub, cloud platforms (AWS, GCP), and specification tools like BrainGrid.
### How do I connect BrainGrid MCP to Gemini CLI?
Run `gemini mcp add --transport http braingrid https://mcp.braingrid.ai/mcp` or add `{"braingrid": {"httpUrl": "https://mcp.braingrid.ai/mcp"}}` to your `mcpServers` config. Authorize via browser on first connection.
### How does Gemini CLI MCP compare to Cursor or Claude Code MCP?
All three support the MCP standard. MCP servers work across all tools. For setup guides, see our [Claude Code MCP](/blog/claude-code-mcp), [Cursor MCP](/blog/cursor-mcp), and [Windsurf MCP](/blog/windsurf-mcp) guides. The main differences are configuration format and CLI commands.
### Why is my Gemini CLI MCP server not connecting?
Run `/mcp` inside Gemini CLI to check connection status and error messages. Common issues include incorrect URLs, missing OAuth authorization, network restrictions, or timeout settings too low.
### Does Gemini CLI support MCP server authentication?
Yes. Gemini CLI handles OAuth automatically for MCP servers that require it. It opens your browser for authorization and stores tokens at `~/.gemini/mcp-oauth-tokens.json`. API key authentication is supported via environment variables in your MCP server config.
### Can I use multiple MCP servers in Gemini CLI?
Yes. Add multiple entries to the `mcpServers` object in your `settings.json`. Gemini CLI connects to all configured MCP servers and makes their tools available in your session.
### What is BrainGrid MCP used for?
BrainGrid MCP provides spec-driven development in Gemini CLI. It turns vague feature ideas into structured requirements with acceptance criteria, then breaks them into implementation tasks. Gemini reads these specs directly and builds features that match your specifications precisely.
---
# Claude Code vs Cursor 2026: Which AI Coding Tool Is Better?
Source: https://www.braingrid.ai/blog/claude-code-vs-cursor
Published: 2026-01-25T16:00:00Z
Just 18 months ago, domain expertise and customer demand weren't enough—you needed a technical co-founder to build your SaaS.
Today, AI coding agents change everything. You can build it yourself. But first, you need to pick the right tool: one that matches how you think about building products.
Claude Code and Cursor are two of the most powerful AI coding tools available. Both can build your product, but they work in fundamentally different ways. This post breaks down how each tool works so you can pick the one that fits your workflow and start shipping.
## How They Actually Work
Think about a coworker who got the job done—but in a completely different way than you. The constant friction slowed you both down.
AI coding agents work the same way. Pick one that doesn't match your workflow, and you'll fight it every step. Pick the right one, and you'll ship faster.
### Claude Code
Claude Code runs in your terminal (the text-based interface where you type commands) or inside your text editor. You describe what you want in plain English. Claude makes changes. You review them. You iterate.
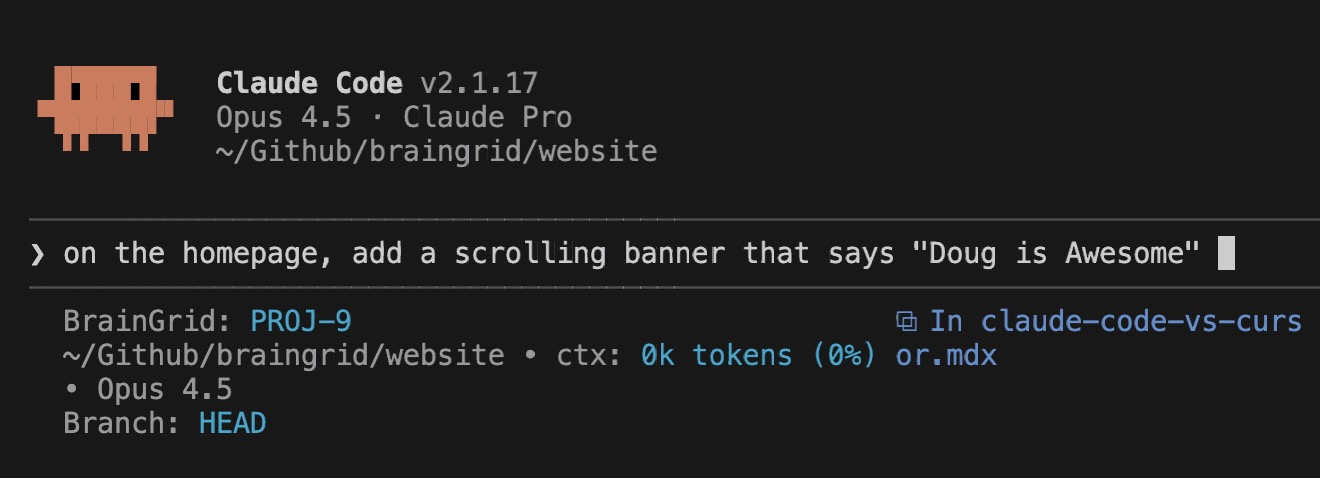
**Think of it as**: Pair-programming with a senior developer who reads your specs and builds features.
Pair programming with Claude can be awesome, but other times it feels very slow. When building larger features that require a lot of code, Claude feels very fast - it generates features in minutes to hours that would take me days. However, for smaller quick fixes, it feels like Claude moves very slowly, and the updates take minutes instead of just seconds.
### Cursor
Cursor is a complete code editor (an IDE—integrated development environment) with AI built in. As you type, it predicts what's coming next and autocompletes entire blocks of code. For bigger features, use the chat interface to describe what you want.
**Think of it as**: Writing code yourself, but with AI superpowers.
As a coder, I find that the autocomplete does help me create functions and features quickly. By anticipating what I am trying to build, I can quickly review the proposed code from Cursor, and with just a `tab`, the code is inserted. Cursor excels at the quick fixes that feel very slow with Claude. The downside is that feature creation through the Cursor chat does not feel quite as robust as building features with Claude Code. Feature code generated by Cursor often needs more iterations to get right (but that could also be poor prompting on my part.)
### Which Should You Choose?
There is no universal answer - these tools are not one-size-fits-all. The right tool is the one that best matches your needs, and the way you prefer to code.
- **Cursor**: You're comfortable writing code and want AI to accelerate you.
- **Claude Code**: You think in features and specs, not code syntax.
### Level Up with Specs: BrainGrid
Both tools work better when you give them clear instructions. On software teams, a product manager creates specs and breaks them into tasks. As a solo founder, you need to do this yourself—or use AI to help.
[BrainGrid](https://www.braingrid.ai) acts as your product management AI. It turns vague ideas into detailed requirements and prompts that your agents can execute. Better prompts mean fewer iterations and faster shipping.
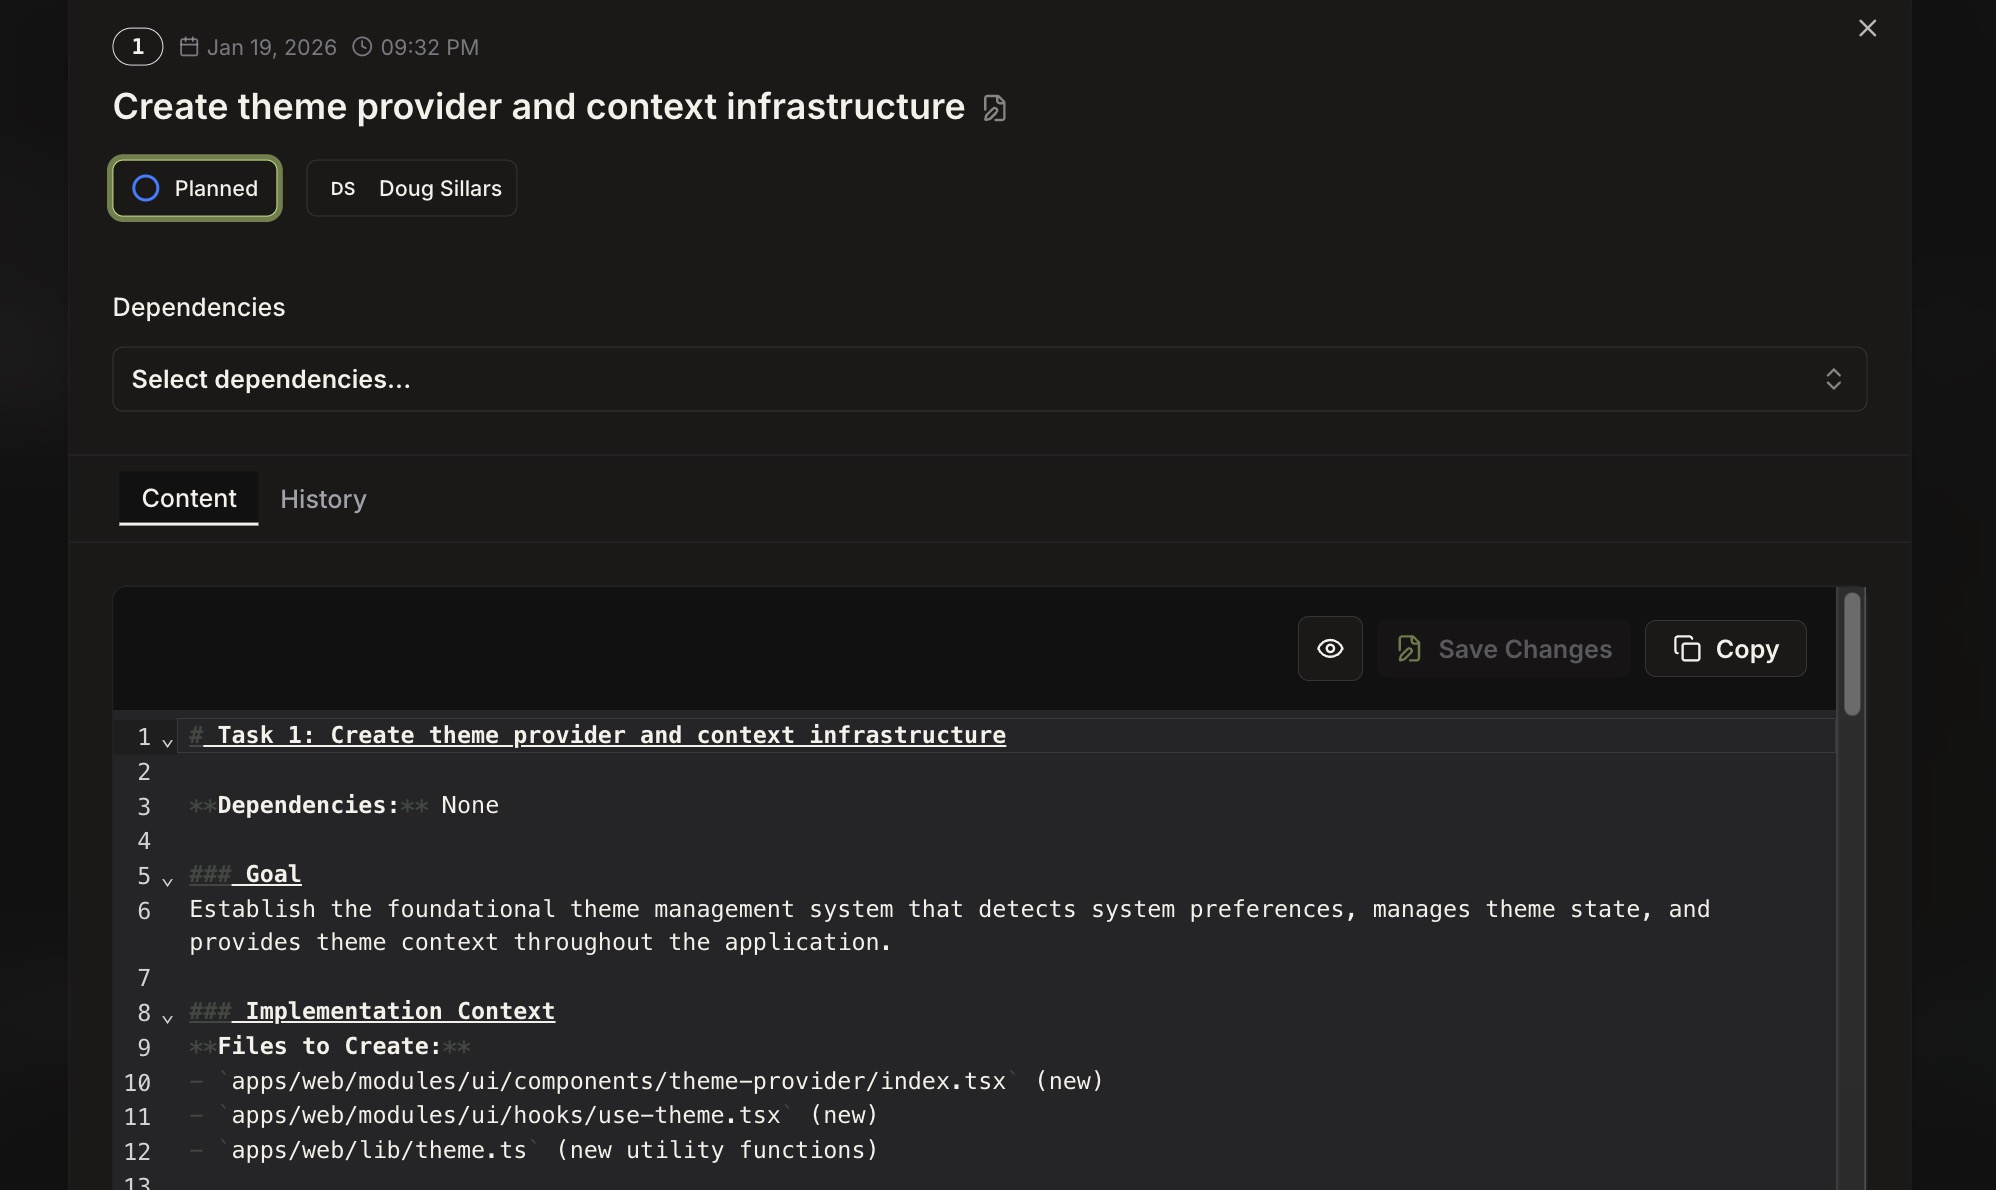
BrainGrid integrates with both [Cursor](/blog/cursor-mcp) and [Claude Code](/blog/claude-code-mcp).
## Learning Curve: What You Actually Need to Learn
Neither tool builds everything perfectly on the first try. You'll need to learn some technical basics—but far less than traditional coding requires.
### Git Basics (Essential for Both Tools)
[Git](/blog/git-version-control-for-ai-builders) tracks changes to your code. You'll need to learn:
- **Branches**: Think of these as parallel workstreams. Keep each feature in its own branch until it works, then merge it into your main codebase.
- **Commits**: Snapshots of your code at a specific point. If something breaks, you can roll back.
- **GitHub**: A cloud backup for your code. Push your changes regularly so you never lose work.
These skills take days to learn, not months.
### Getting Started with Claude Code
You'll work with Claude Code in your terminal, typing commands and prompts. As you learn [slash commands](https://code.claude.com/docs/en/slash-commands) like `/clear` (reset the conversation) or `/model` (switch AI models), you'll feel like a hacker.
**Week 1**: Feels clunky. You're typing prose into a black screen and waiting for responses.
**Week 2**: Feels effortless. You realize you just shipped 3 features without touching code directly.
### Starting with Cursor
Cursor feels like a traditional code editor—but supercharged. As you type, it predicts what's coming next and autocompletes entire functions. For bigger features, use the chat interface to describe what you want.
**Week 1**: Feels empowering—autocomplete makes you feel like a "real developer."
**Week 2**: You're moving fast on small changes, but bigger features feel harder to coordinate across files.
### Best Practices for Getting Started
No matter which tool you choose:
1. **Start small.** Build one simple feature first. Once that works, tackle larger tasks that span multiple files.
2. **Review every change.** Both tools let you accept or reject changes. It's easier to reject and try again than to fix broken code later.
3. **Don't blindly accept.** If you don't understand what the AI wrote, ask it to explain. You'll learn faster and catch bugs earlier.
## When to Use Each Tool
Both tools can handle almost any coding task. But each has distinct strengths.
**Cursor excels at:**
- Quick UI tweaks and bug fixes (seconds, not minutes).
- Jumping between files to make small edits.
- Rapid iteration when you're hands-on with the code.
**Claude Code excels at:**
- Building new features from scratch.
- Complex refactors that touch many files.
- Deep reasoning about architecture decisions.
### The Hybrid Approach
Many builders use both: Claude Code for "thinking work" (new features, refactors) and Cursor for "fixing work" (bugs, UI polish). There's no rule saying you can't use both.
## Pricing: What You'll Actually Spend
Neither tool will break the bank. Both [Cursor](/blog/cursor-pricing) and [Claude Code](/blog/claude-code-pricing) start at $20/month for Pro plans.
### What You Get for $20/Month
Both subscriptions include a monthly allocation of AI usage. Once you hit the cap, you can either pay for overages or wait for the reset. Set a monthly spending cap in your settings to avoid billing surprises.
Heavy users may hit $100-200/month. Start with the Pro plan and only upgrade if you consistently hit limits.
### How Usage Works
**Claude Code**: Usage resets in five-hour sessions. Hit your limit? Either pay for more or wait for the session to reset.
**Cursor**: Usage resets monthly. Deplete your allocation mid-month and you'll pay overages or switch to smaller models.
### Tips to Maximize Usage
**Cursor**: Use "Auto" mode—it picks cheaper models for simple tasks and reserves powerful models for complex work.
**Claude Code**: Switch to cheaper models (like Haiku) for simple tasks. Save the expensive models for features that need deep reasoning.
## Connecting to External Systems (MCP)
**The problem**: When AI writes code that talks to your database or API, it has to guess. It creates placeholder code like `SELECT * FROM users_table_maybe` because it doesn't know your actual table names. You waste time fixing these placeholders.
**The solution**: MCP (Model Context Protocol) connects your AI agent to external systems—databases, APIs, documentation, task managers. Now the AI knows your actual data structure and writes working queries the first time.
Both tools support MCP. For setup details, see our posts on [Claude Code & MCP](/blog/claude-code-mcp) and [Cursor MCP](/blog/cursor-mcp).
### Quick Setup Tips
**Claude Code**: After installing an MCP, restart Claude Code. Changes don't take effect until restart.
**Cursor**: MCPs can be installed in one click through the marketplace. Check your settings to ensure your desired MCP is enabled.
### BrainGrid MCP
BrainGrid offers an MCP that lets both tools read your requirements and tasks directly. See the [installation docs](https://docs.braingrid.ai/mcp-server/installation) to get started.
MCP integrations reduce "context switching tax"—the time spent copy-pasting specs, docs, and data between tools. This saves hours per week for active builders.
## Common Pitfalls and How to Avoid Them
These pitfalls apply to all AI coding tools. Avoiding them saves days—if not weeks—of frustration.
### 1. Blindly Accepting AI Code
**The risk**: You accept 200 lines of code without reading them. Three days later, something breaks and you can't figure out why.
**The fix**: Read every change before accepting. If you don't understand something, ask the AI to explain it. Ten minutes of review saves hours of debugging.
### 2. Vague Prompts
**The risk**: You say "add a payment feature." The AI builds something that's missing error handling, webhook support, and refund logic. You ship it, payments fail silently, customers churn.
**The fix**: Write detailed prompts. Use [BrainGrid](/blog/spec-driven-development) to turn vague ideas into specific requirements with clear acceptance criteria.
### 3. Skipping Tests
**The risk**: You ship a feature, it works. You ship another feature, the first one breaks. You don't notice until a customer reports it.
**The fix**: Ask the AI to write tests with every feature. Add to your prompt: "Also write tests for happy path, error cases, and edge cases."
### Claude Code Pitfalls
The terminal has a learning curve. Keep a cheat sheet of common commands nearby until they become second nature.
### Cursor Pitfalls
Autocomplete is addictive. When Cursor suggests 15 lines to complete your function, stop and read them. Make sure it's actually doing what you want.
## Which Tool Should You Choose?
Here's how to decide:
**Choose Claude Code if:**
- You think in product specs, user stories, and requirements.
- You'd rather describe outcomes than write code.
- You want to build features from scratch with detailed prompts.
**Choose Cursor if:**
- You've written code before (even basic HTML or Python).
- You prefer hands-on control and seeing code as you build.
- You want autocomplete to accelerate your workflow.
**Still unsure?** Start with Claude Code for one week. If you find yourself wanting to "just fix this one line" faster, add Cursor for quick edits.
### Your Next Step
The right tool should feel like it's working with you, not against you. Pick one, try it for a week on a real feature, and see how it fits.
Both tools come with pros and cons: Cursor's fast autocomplete, but less of a feature development tool. Claude Code is great at building features, but feels very slow in iterating on small changes.
Whichever tool you choose, start with clear requirements. Both Claude Code and Cursor produce better results when they know exactly what you're trying to build. [BrainGrid](https://www.braingrid.ai) can help you turn vague ideas into detailed specs that your AI agent can execute.
## FAQ
### Is Claude Code better than Cursor?
Neither is objectively "better"—they're different tools for different workflows. Claude Code excels at spec-driven, conversational development. Cursor excels at inline editing and rapid iteration. Choose based on how you think about building, not which has more features.
### Can I use both Claude Code and Cursor?
Yes. Many builders use Claude Code for new features and architectural changes, then switch to Cursor for bug fixes and UI polish. This requires maintaining both setups but maximizes each tool's strengths.
### How much do Claude Code and Cursor cost?
Both start at $20/month for Pro plans. Heavy users may exceed the base allocation—set a spending cap in your settings to avoid surprises. Start at $20 and only upgrade if you consistently hit limits.
### Do I need to know how to code to use these tools?
No—but you'll learn basics as you go. You'll pick up git commands, terminal navigation, and code structure. If you already code, Cursor will feel more natural. If you don't, Claude Code's conversational style is easier to start with.
### Which tool is faster for building an MVP?
Starting from zero? Claude Code can take your requirements and build an MVP. Cursor is faster at adding to existing codebases—which you'll have as soon as your MVP exists.
### Can I switch from Cursor to Claude Code (or vice versa) later?
Yes. Neither tool locks you in. Both read your codebase and build from what's there. You can use them simultaneously.
### Should I start with the free tier or paid plan?
Cursor's free plan runs out fast. Claude Code doesn't have a free tier. Both have Pro plans at $20/month—for the cost of a nice lunch, start with the paid plan and move faster.
### How do I know which tool is right for me?
Think in product specs and user stories? Try Claude Code. Prefer hands-on control and inline editing? Try Cursor. Test both for one week each on a small project, then commit to one for 30 days.
---
# Builder Story: How Two Builders Shipped 200+ Features Using AI Agents and BrainGrid
Source: https://www.braingrid.ai/blog/builder-story-matt-bernier-clay-unicorn-unicorn-love
Published: 2026-01-23T14:30:00Z
> "BrainGrid is the most agnostic piece of my stack. I'll drop models. I won't drop planning."
- Clay Unicorn
## Background: The AI Power Users
### Who are the builders?
Matt Bernier and Clay Unicorn are the minds behind Unicorn.love, a venture accelerator and studio based in Denver. As deeply technical founders and consultants, they constantly test the limits of new AI tools, not just for their own SaaS products, but for the many companies they advise.
Matt Bernier has worn both hats: product manager and software engineer. After years shipping in larger organizations, he found himself drawn back into building, partly because AI made coding fun again. Instead of spending his best energy on repetitive work, Matt uses agents to handle the parts he no longer wants to do manually, allowing him to focus on product decisions and execution.
Clay Unicorn has been building software for nearly 24 years, starting with an early obsession with Star Trek, androids, and AI. As a teenager, he experimented with neural networks long before AI became mainstream. Since then, he has worked across agencies, consulting, and product development, riding every major technology wave along the way. Today, he balances deep experience with the urgency of keeping up in a rapidly evolving AI landscape.
Internally, they are building two of their own SaaS companies and centralizing core intellectual property into a reusable framework. Externally, they advise a pipeline of large public companies, helping them scope features, manage development, and accelerate time to market. To do this effectively, they need a robust system to manage requirements and development across the entire portfolio.
## Vision: An AI-Powered Venture Studio
### What are they building?
Unicorn is not building a single product. They are building a venture studio engine.
Internally, they are developing multiple SaaS companies while consolidating core intellectual property into a reusable platform framework. Externally, they consult with startups and large companies to scope features, execute builds, and move faster.
Their challenge is not whether they can code.
Their challenge is whether they can translate messy real-world inputs into clean, executable work across many projects without becoming the bottleneck.
### Who is Unicorn for?
Their system is designed for a wide range of users, including internal developers, portfolio companies, and non-technical stakeholders.
A key goal is empowering product managers, QA teams, and operational leads to contribute directly to the development process without needing deep engineering expertise.
### What does it solve?
They are solving the core problem of ambiguity in software development. AI coding agents fail when given vague instructions, and human teams waste time clarifying scope.
Unicorn needed a way to bridge this gap by creating clear, context-aware specifications that both humans and AI agents can execute reliably.
As Clay puts it, for the startups they advise:
> “This kind of replaces a CPO for you.”
## The Turning Point: Choosing BrainGrid
Matt discovered BrainGrid through a Denver vibe coding meetup. At the time, he was demoing an open source tool he had been hacking on to tie tasks to repos and spin up worktrees automatically. He was actively modifying it to better fit his workflow.
Then a friend pointed him to BrainGrid.
What happened next became a defining moment.
On a call with Tyler Wells, BrainGrid’s co-founder and CTO, Matt shut down the tool he had been hacking on, signed up for BrainGrid, and started using it immediately. BrainGrid was already solving the exact problems he had been trying to patch together.
The difference was simple. BrainGrid did not just generate tasks. It asked the right questions.
Matt knew it was real the moment BrainGrid began clarifying context and exposing gaps in his thinking.
Clay had his own conversion moment. After testing dozens of tools and learning to pass or fail them in minutes, BrainGrid stood out.
> “It wasn’t too literal on the product side, and it didn’t ignore engineering reality. It bridged the gap.”
He did not even need to see the output. The questions alone proved the system understood what mattered.
### BrainGrid becomes the shared brain for the team
BrainGrid quickly became Unicorn’s central nervous system, not just for engineers, but for the entire team.
They began routing product feedback, QA notes, and bug reports into BrainGrid so those inputs could be turned into structured, agent-ready work without constant context switching.
One partner, Mark, who had previously managed large engineering organizations, started submitting detailed bug reports complete with screenshots and reproduction steps. BrainGrid guided him through the right questions, producing specifications engineers could act on immediately.
Clay described the shift clearly:
> “Instead of bug reports living in Slack and requiring a human to digest each one, BrainGrid made them feature complete for execution.”
In many cases, Clay never even reviewed the items himself. Agents could pick them up directly.
## Outcomes: Shipping at a Pace That Feels Unfair
The results were dramatic and measurable.
Clay reports the team completed more than **200 backlog items**, many of which were one to three day features. These were not small tasks.
Matt put it in concrete terms. Since early October, they built a full platform system and an OAuth application on top of it. He estimates the output would normally require **a team of roughly 10 developers working for four to five years**.
They also saw a major workflow multiplier from BrainGrid’s CLI and Claude skills integration.
Matt explained how slash commands allow him to go from “I need a task” to execution instantly. He can list requirements, select one, run `/build`, and the agent already understands how to operate within the system.
The result is less ceremony, fewer repeated prompts, and far more parallel progress.
### What changed in how they work
They did not just move faster. They became more scalable.
Clay described BrainGrid as instrumental from the very first step of thinking through a bug fix or feature. Unlike models that come and go, BrainGrid stays because it is about planning and structure.
Matt added another perspective. As teams grow beyond two people, coordination costs explode. BrainGrid reduces collisions by helping people pull the right tasks, assign work clearly, and avoid duplicated effort.
BrainGrid turns high-speed agentic development into something that works for teams, not just solo power users.
### The bottleneck is moving: QA and security
With planning and development accelerating, the bottleneck shifts hard into QA and security.
Matt referenced Theory of Constraints and described the reality clearly. When upstream throughput increases, whatever cannot keep up becomes the bottleneck. QA has always been one. Now it becomes more painful as output increases.
This is where BrainGrid becomes even more important, because the system that structures work must also help structure validation.
## What They Want Next from BrainGrid
They shared two concrete feature requests.
### 1) Default testing and validation built into tasks
They want baseline expectations included automatically:
- Update unit tests
- Update integration tests
- Update UI tests
- Create tests if they do not exist
- Ensure all tests pass
The goal is simple: make quality continuous, not optional.
### 2) Facets or metadata on tasks
Clay wants tasks labeled by type:
- Front end
- Back end
- Testing
- Database
- Security
This is not about choosing tools automatically. It is about enabling better orchestration. They already use different models for different job types, and metadata would make triage and delegation faster.
## Final Thoughts
Unicorn’s story shows what happens when experienced builders push agentic development to its limits. They are not experimenting for novelty. They are shipping real systems, for real stakeholders, at real speed.
BrainGrid became their backbone because it solved the hardest problem in modern software development:
Turning ambiguous intent into executable reality.
Check out [Unicorn.love](https://unicorn.love/)
---
# Claude Code Pricing 2026: Pro vs Max vs Team (Updated June)
Source: https://www.braingrid.ai/blog/claude-code-pricing
Published: 2026-01-16T12:00:00Z
AI coding assistants like Claude Code, ChatGPT, Cursor, and Windsurf are changing how founders ship software. These tools accelerate development for experienced engineers and enable non-technical SaaS founders to build working prototypes without hiring a dev team.
But how much does it all cost? How much will a team spend on tools like Claude Code, and how can they prevent bill shock at the end of the month from overages? Read on to understand how to use Claude Code efficiently and avoid burning tokens.
## How Much Does Claude Code Cost? Quick Overview
Visiting [Claude.ai](https://claude.ai) lets you chat with Claude's latest models.
But free Claude access does **NOT** include Claude Code. Access to Claude Code requires a monthly subscription.
| Plan | Cost | Claude Code Access | Best For |
|------|------|-------------------|----------|
| **Pro** | $20/mo | ✓ Full access | Daily coding, solo founders |
| **Max 5x** | $100/mo | ✓ Extended limits | Heavy users, complex projects |
| **Max 20x** | $200/mo | ✓ Maximum capacity | Power users, all-day coding |
| **Team (standard seat)** | $25/user/mo ($20 annually) | ✗ Not included | Collaboration, research, admin |
| **Team (premium seat)** | $125/user/mo ($100 annually) | ✓ Plus Cowork | Organizations, dev teams |
| **API-only** | Pay-per-token | Via terminal | Custom integrations |
> **The Team plan trap:** standard Team seats do NOT include Claude Code. If your team signed up to build, the developers need premium seats. Full decision guide in our [Claude Pro vs Team vs Max breakdown](/blog/claude-pro-vs-team-vs-max).
> Note that Anthropic offers yearly discounts on annual subscriptions - Claude Code Pro is $17/mo (15% savings) when purchased annually.
Each Claude Code subscription includes session limits—a maximum number of prompts you can send within a rolling 5-hour window. Claude Code Pro subscribers can expect a maximum [45 messages per 5-hour window](https://support.claude.com/en/articles/11145838-using-claude-code-with-your-pro-or-max-plan). However, coding prompts consume more tokens than simple chat queries, so you'll realistically get [10-40 prompts](https://support.claude.com/en/articles/11145838-using-claude-code-with-your-pro-or-max-plan) per window.
Here's the worst feeling: You're in flow state, shipping a critical feature, and Claude Code says "You've reached your usage limit. Try again in 3 hours." Your momentum is gone. Your code progress halts for hours.
**Why this matters:** If you're racing to a demo, investor meeting, or launch deadline, losing 2-3 hours could mean missing your target.
You can turn on extra usage in your settings to keep Claude Code going. Set a monthly maximum you're comfortable with. Anthropic's [documentation](https://code.claude.com/docs/en/costs) reports the average cost is $6/day, with 90% of developers under $12/day.
Any extra usage is paid at the API token pricing:
### **API Token Pricing**
| Model | Input (per 1M tokens) | Output (per 1M tokens) |
|-------|----------------------|------------------------|
| **Haiku 4.5** | $1 | $5 |
| **Sonnet 4.6** | $3 | $15 |
| **Opus 4.8** | $5 | $25 |
| **Fable 5** | $10 | $50 |
## Claude Pro vs Max: Which Plan Should You Choose?
The Max plans cost more but include significantly more token capacity. Claude Max 5x costs $100/month and includes 5x the tokens of Pro. Claude Max 20x gives you 20x the tokens for $200/month.
For regular daily coding, troubleshooting, and planning, Claude Pro is sufficient. You may find a few days of heavy coding leads to extra usage charges.
**When to upgrade to Max 5x:** If you're hitting Pro's limits daily and spending $4+ on extra usage, Max 5x becomes cost-effective. Here's the math:
- $4/day × 22 working days = $88 in overages
- Add your $20 Pro subscription = $108/month total
- Max 5x costs $100/month flat with 5x the capacity
If your overages consistently exceed $80/month, Max 5x saves money and removes the usage anxiety.
## Claude Code Teams and Enterprise: When Do You Need Them?
Claude Code on the Team plan requires a premium seat at $125/month per developer ($100/month billed annually). The plan has a 5-seat minimum across seat types, with standard seats at $25/month ($20 annually) for teammates who collaborate but do not code. Five premium seats run $625/month; a mixed team of two developers on premium seats plus three standard seats is about $325/month.
Premium seats carry roughly 6.25x Pro's usage per session (5x a standard seat), slightly above Max 5x. But the real benefit is governance: your data is excluded from model training, [Model Context Protocol (MCP) servers](/blog/cursor-mcp) are configured at the team level, so when a developer leaves, you automatically revoke their access to internal databases and tooling, and Team provides centralized billing and usage auditing.
**The decision framework:**
- Two founders building a product? Use two individual accounts; the 5-seat minimum makes Team expensive for you.
- Growing past 5 developers? Security, permissioning, and data controls become critical. Team makes sense, with premium seats for the builders only.
- Need SOC2 compliance or audit trails? Team is the path forward, and Enterprise ($20/seat plus API-rate usage) adds HIPAA options and SCIM.
For the full plan-choice walkthrough, including when individual Max plans beat Team seats, see [Claude Pro vs Team vs Max](/blog/claude-pro-vs-team-vs-max).
## How to Reduce Claude Code Costs: Practical Efficiency Strategies
Now that you know the pricing tiers, let's talk about the real cost lever: how efficiently you use tokens.
Every question, code review, and bug fix burns tokens. But you can cut *how many* tokens each query consumes. These strategies can reduce your bill by 50-80%.
### Use `/clear` between tasks
The `/clear` command tells Claude Code to forget the current conversation context. Say you're squashing bugs: after fixing a frontend CSS issue, you jump to a backend database query. There's no need for Claude to keep the CSS conversation in memory. Clear it out for better results and fewer tokens.
**When to `/clear`:** Switching between unrelated files, moving from frontend to backend, or jumping from feature work to bug fixes. If Claude's suggestions start referencing the wrong context, you waited too long.
### Use `/compact` to summarize the conversation
When building a feature over several iterations, every code snippet gets shared every time. The context window grows larger, meaning more tokens per question.
The `/compact` command tells Claude Code to summarize the current chat and start fresh with the "Cliff's Notes" version. The conversation continues with all pertinent details but uses a fraction of the tokens.
**Rule of thumb:** Use `/compact` after 10-15 messages or when `/cost` shows over 5M tokens in your session. You'll know you waited too long when Claude starts repeating itself or missing context from earlier.
### Check your usage with `/cost`
The `/cost` slash command shows token usage for your current session. Use this to understand your usage patterns and identify which tasks burn the most tokens.
### Configure `.claudeignore`
Just like `.gitignore` tells Git which files to skip, `.claudeignore` tells Claude what files to ignore when analyzing your codebase. Are you accidentally sending your entire `node_modules` folder to Claude with every prompt? That's 50-90% wasted tokens.
**Action:** Create `.claudeignore` in your project root with these lines:
```bash
.gitignore
node_modules/
.next/
build/
dist/
*.log
.env*
.git/
```
Run `/cost` before and after to verify the reduction.
### Model Selection Strategy
Different Claude models have different costs. Match the model to the task:
| Task Type | Model | Why |
|-----------|-------|-----|
| Autocomplete, simple edits | Haiku 4.5 | Fastest, cheapest |
| Feature implementation | Sonnet 4.6 | Best balance |
| Complex debugging | Sonnet 4.6 | Usually sufficient |
| Architecture decisions | Opus 4.8 | Worth the premium |
| Critical production code | Opus 4.8 | When it matters most |
**The rule:** Sonnet handles 80% of your work. Reserve Opus for complex reasoning tasks where Sonnet gets stuck. This alone can reduce token costs by 30-40%.
**When to break the rule:** If Haiku gives buggy code twice, jump straight to Sonnet. Don't burn three cheap iterations when one good Sonnet response costs less.
### The Biggest Token Saver: Spec-Driven Development
All the tactics above (clearing, compacting, model switching) save 10-40% on tokens. But they miss the real problem: rebuilding the same feature over and over because the requirements weren't clear. [Spec-driven development](/blog/spec-driven-development) solves this.
**The expensive way:**
1. Prompt: "Build user authentication"
2. Claude builds it (5,000 tokens)
3. You: "Actually, I need email verification"
4. Claude rebuilds (6,000 tokens)
5. You: "And password reset"
6. Claude rebuilds again (7,000 tokens)
**Result:** 18,000 tokens, 3 rebuilds, one frustrated afternoon.
**Spec-first workflow:**
1. Write a clear requirement before coding
2. Break it into specific tasks
3. Implement each task with Claude understanding the full context
With the right prompt built from a clear specification, you can build the feature correctly the first time. That's 60-80% token savings.
[BrainGrid](https://www.braingrid.ai) formalizes this workflow, turning vague ideas into structured specs that Claude can implement in one pass. Give BrainGrid a prompt of what you'd like to build, and BrainGrid asks implementation questions and feature questions, just like a product manager fleshing out the details of what should be built. A requirements document is created, which you can use to generate a list of tasks.
Connecting [BrainGrid to Claude Code](https://docs.braingrid.ai/claude-code) allows Claude Code to read the requirements and tasks, then implement them directly from the command line. For the full setup, see our [Claude Code MCP servers guide](/blog/claude-code-mcp).
Spec-driven development ensures the prompts provided to Claude Code are complete and will build the expected feature the first time. Eliminate the iteration rabbit hole to save a huge percentage of token usage.
## Is Claude Code Worth It? The Solo Founder's Decision Framework
If you value your time at $50/hour, Claude Code needs to save you 24 minutes per month to break even. That's one debugging session.
For a solo founder shipping products, a $20 Claude Code Pro account is worth it if it saves one hour of debugging. Any additional time savings from feature coding, prototyping, or writing tests is bonus ROI.
If Claude Code helps you shave 10-30% from each dev cycle (or increase output per cycle by 10-30%), that's $20 very well spent.
**Maximize your $20/month:** Pair Claude Code with [BrainGrid](https://www.braingrid.ai) to turn ideas into shippable specs in minutes, or integrate with other agentic tools like Cursor to further accelerate how quickly you and your team ship.
## Frequently Asked Questions
### How much does Claude Code cost?
Claude Code Pro is $20/month ($17/month when paid yearly). Claude Code Max ranges from $100-200/month for power users. On the Team plan, Claude Code requires a premium seat at $125/month per developer ($100/month billed annually).
### Is Claude Code free?
No. A free Claude account allows chat on the web, but no access to Claude Code. You need a paid subscription.
### What's the difference between Claude Pro and Max?
Claude Pro is $20/month. Claude Max starts at $100/month and includes 5x the token capacity. **Upgrade trigger:** If you're spending $80+/month on overages, Max 5x is more cost-effective.
### Why is Claude Code using so many tokens?
When iterating on a problem, Claude Code processes the full conversation context with each response. Long conversations with lots of code snippets burn tokens fast. Use `/clear` between tasks and `/compact` during long sessions to reduce usage.
### How do I reduce Claude Code costs?
The biggest lever is reducing iterations. Great prompts from tools like BrainGrid's spec-driven development ensure you build features correctly the first time. Fewer iterations = fewer tokens = lower costs.
### Is Claude Code worth it?
If it saves you one hour of debugging per month, you've broken even (assuming your time is worth $20+/hour). Most founders report saving 5-10 hours monthly. **Try Pro for 30 days** and track time saved vs. rate limit waits.
### Claude Code vs Cursor: which is cheaper?
Both have a $20/month basic plan. Cursor includes an IDE and routes queries to different LLMs automatically. Claude Code gives you direct access to Claude's full model lineup. For most founders, pick based on workflow preference, not price. See our [detailed Cursor pricing breakdown](/blog/cursor-pricing) for more.
### What are Claude Code rate limits?
Claude Code has a 5-hour rolling window for token usage. Hit the limit and you'll see "Try again in X hours." **Avoid surprises:** Enable extra usage with a monthly cap (Settings > Billing). If you're regularly hitting limits, consider Max 5x.
---
# Cursor Pricing 2026: Free vs Pro vs Ultra — Which Plan?
Source: https://www.braingrid.ai/blog/cursor-pricing
Published: 2026-01-15T15:00:00Z
Cursor is a popular Agentic AI coding tool, helping developers improve productivity, and even helping SaaS founders with no coding background build fully functional systems. Unlike other agentic tools like Copilot or Claude Code which are primarily editor extensions, Cursor is a standalone IDE (Integrated Development Environment) that replaces the need for using VS Code (it is actually a fork of VS Code). It melds a native coding experience with a AI-first conversational coding solution.
Agentic AI tools like Cursor speed development and improve developer performance. The LLM agents inside Cursor do not just blindly add code to your repository. When prompted with a code change, the AI Agents read your existing code, write code that fits into your existing codebase - matching styles and reading across files and modules to ensure that the generated code is compatible with the entire repository.
But, how much does such an AI tool cost? While the Cursor AI [pricing page](https://cursor.com/pricing) provides the basic details, this post aims to break down the available plans so that your team can determine the price point most appropriate for your usage needs and help you understand when you need to upgrade to a more advanced plan.
## What Cursor Brings to the Table
To understand the pricing of Cursor, it is important to understand the features that Cursor brings to your development team. As previously mentioned, Cursor is a full-fledged IDE that developers can use for coding. The AI Agents inside Cursor have many features that improve coding workflows:
* **Full repository awareness**: Code analysis isn't limited to a single function or file—Cursor understands your full repository and how changes affect other files, modules, and dependencies.
* **MCP integrations**: Cursor has native [Model Context Protocol support](/blog/cursor-mcp) to pull context from *outside* your repo—APIs, documentation, databases, or internal tools.
* **Multiple file changes**: Plans and applies multi-file diffs when creating code.
* **Natural language**: Build code using plain English prompts.
* **File safety**: Git-based file safety makes it easy to review, accept, reject, or roll back changes.
No matter the pricing tier - these features are included with your Cursor subscription. The major differences between the Cursor pricing plans comes from **how much** Agentic access is provided, but we will also dig into the subtle differences.
We'll kick off our review of plans designed for a single developer: what Cursor calls "Individual plans." These plans are best for a founder or developer coding alone on a project.
### Hobby Tier: Starting with Cursor
Never used Cursor? The free "Hobby" tier lets you test the tool and see if Cursor's workflows fit your existing processes. Being free, the Hobby plan provides very limited access:
* Tab completions: Cursor's coding autocomplete feature lets you build faster - by tabbing the suggested autocompletes from Cursor.
* Agent requests: Chat with Cursor's agents to code or debug your code.
This is a great way to experiment with Cursor before buying a paid plan. As you might expect, the number of Agent requests is small—you may complete one feature (or only part of one) before running out of credits and being prompted to upgrade.
Get stuck mid-feature on the Hobby tier? You can activate a 7-day free Pro trial to help you complete your project.
### Pro ($20/month): The Sweet Spot for Most Founders
The Pro plan is Cursor's most popular tier: at $20/month for one user, it's an easy entry point that won't break the bank. You get everything in Hobby, plus higher limits:
* Unlimited tab completions: Tab completions are virtually unlimited on the Pro plan.
* Extended limits on Agent Requests: While not unlimited, the number of Agentic Requests is much higher.
The Pro plan also introduces the ability to run *Background Agents*. You can ask Cursor to work on a task in the background, while you continue to use the Agent in your current coding. The Background agent works asynchronously to the developer's work - coming back only when it has an answer, or has a clarifying question.
The number of Agent Requests and Background Agents provided in Cursor's Pro plan are provided quantitatively. When an Agentic call is made, Cursor breaks the task up for different agents, and utilizes common LLMs (OpenAI, Gemini and Claude are commonly used) to 'solve' the problem. The Pro plan includes a fixed monthly allowance of AI compute, roughly equivalent to what Cursor internally budgets for a $20/month user. Token usage is abstracted away from the developer—there is no visible token counting, only usage-based limits.
Should a developer utilize all of the Agent requests allocated in a month, there are two options: the team can either block overage charges, and advanced agent features pause or degrade until the next billing cycle, or the team can cap the amount of overage charges that can be accrued in the month.
### Pro+ ($60/month) and Ultra ($200/month): For Heavy Users
Once developers begin using Cursor, they may find that they become heavy users, and they reach the limits of the Pro plan. The Pro+ and Ultra plans are built for these developers.
For *heavy* users of Cursor, the Pro+ plan (at $60 per month) provides everything in the Pro plan, but provides 3x more usage with the top models - allowing for more background tasks, and Agentic problem solving.
For *extremely heavy* users, Cursor's Ultra plan provides 20x the usage of the Pro plan - for $200 a month.
## Team and Enterprise plans
For side projects or solo development, Individual plans make sense—you know your usage and can pick accordingly. But as your team grows, managing individual plans becomes a bookkeeping nightmare and introduces security concerns.
This is where Cursor's team and enterprise plans fit in.
Cursor's team plan costs $40 per month per user, fitting between Pro and Pro+ individual accounts.
Beyond centralized billing and easy team member management, the major advantage is improved data isolation and privacy controls. Prompts and code analyzed on a Teams account are **not** used to train models.
The biggest privacy win? MCP access is controlled at the team level. Proprietary data from MCPs stays managed by your organization—it can't leak to individual accounts when developers come and go.
For teams with stricter privacy requirements, the Enterprise plan adds region-specific data handling (data stays in your country/region), audit logging, and deeper admin visibility. Enterprise pricing isn't published—you'll need to work with Cursor's sales team for a custom contract.
## Addons: Bugbot
Cursor offers Bugbot - a product that scans every PR on Github for potential bugs. It acts like a senior dev that reviews the code, looking for bugs in code being submitted for review. The Pro and Teams versions of Bugbot cost $40 per user per month, in addition to the Cursor subscription. While this may seem expensive at first, Bugbot delivers the highest ROI for teams with junior or mid-level developers by catching common bugs before senior engineers need to review the code. It acts as a first-pass reviewer, reducing review noise and protecting senior developer time.
## Further extending Cursor: BrainGrid's spec driven development
Cursor's Agentic coding AI raises the bar and improves productivity of development teams. But all developers who use AI know about falling into 'rabbit holes' where the AI is just not interpreting the prompts well, and hours are spent getting the AI back on track and to have it stop making similar mistakes over and over.
Many times, features are built *at the prompt* with little forethought or planning. As the feature evolves, so too do the prompts and the underlying code.
In traditional development processes, Product Managers work with the stakeholders to plan what the feature looks like, what it should (and should not) do, and build a roadmap of how the feature will evolve. BrainGrid acts as a product-management layer for AI coding workflows - helping developers take ideas for features, and building requirements around the feature. BrainGrid asks clarifying questions to help the product owner better understand what is being built, and what is out of scope. This [spec driven development](/blog/spec-driven-development) leads to the creation of a requirements document that describes the scope of the feature and what is going to be built. The team can analyze and make changes.
Once the requirements document is approved, BrainGrid creates tasks with prompts that can be fed directly into Cursor. The prompts are highly detailed, which means that there are fewer back and forth iterations with the Agentic AI to actually build the feature. See an example of feature building with BrainGrid and Cursor in our [Windsurf vs. Cursor comparison](/blog/windsurf-vs-cursor).
Connecting the BrainGrid MCP into Cursor ensures that features are better understood and fleshed out - instead of just building at the prompt. This results in faster development, fewer rabbit holes, and higher productivity.
Starting at $10/month/user (to $75/month/user for enterprises), BrainGrid's product driven specifications gives Cursor additional superpowers, further accelerating your team's development productivity.
## Wrapping up
Cursor's paid plans start at $20/month and scale to $200/month for the Ultra tier. For development teams, the Team and Enterprise plans simplify billing while adding privacy and security controls. And for teams going *all-in* with agentic coding, spec-driven development tools like BrainGrid help you build better prompts—leading to focused code and fewer AI rabbit holes.
To learn more, visit [Cursor.ai](https://cursor.ai) or explore [spec-driven development at BrainGrid.ai](https://www.braingrid.ai).
## FAQ
### **How much does Cursor Team cost?**
Cursor Team starts at $40/month per user.
### **How costly is Cursor?**
| Plan | Price | Best For |
|------|-------|----------|
| **Hobby** | Free | Testing Cursor before committing |
| **Pro** | $20/mo | Solo founders shipping MVPs |
| **Pro+** | $60/mo | Heavy daily users hitting Pro limits |
| **Ultra** | $200/mo | Full-time AI-assisted development |
| **Team** | $40/user/mo | Startups with 2+ developers |
| **Enterprise** | Custom | Regulated industries, large orgs |
### **Is Cursor AI free or paid?**
There's a free Hobby tier, but paid plans start at $20/month.
### **Is Cursor better than Copilot?**
They're different tools. Copilot generates code snippets; Cursor understands your full repository and builds code that fits your existing codebase.
### **Do you need a subscription for Cursor?**
Yes, though the Hobby tier is free for testing.
### **Is Cursor's free plan good?**
It's like a taste of ice cream—enough to evaluate, but most real-world development requires a paid plan.
### **How much do different models cost in Cursor?**
By default, Cursor uses Auto mode, that uses internal tooling to pick the bets agent for a given task. This can be overridden, and developers can choose specific Agents (like Opus 4.5, Sonnet 4.5, ChatGPT 5.2, and Gemini 3) for all queries. Cursor has published cost per million tokens for many of the most popular and powerful models in their [documentation](https://cursor.com/docs/models#model-pricing)
---
# Ralph Wiggum Plugin for Claude Code: Autonomous Coding Guide
Source: https://www.braingrid.ai/blog/ralph-wiggum-plugin
Published: 2026-01-14T10:00:00Z
You know that feeling when you're three hours deep into fixing tests, and each fix breaks something else?
What if you could just walk away? Describe what you want, go grab dinner, and come back to working code?
That's Ralph Wiggum.
## Why "Ralph Wiggum"?
Remember Ralph Wiggum from The Simpsons? The kid who keeps trying despite failing spectacularly every single time?
That's exactly what this plugin does. It fails, learns, tries again, and keeps going until it succeeds. No complaints. No giving up. Just persistent iteration until the job is done.
The creator, Geoffrey Huntley, captured it perfectly: **"Ralph is a Bash loop."**
```bash
while :; do cat PROMPT.md | claude ; done
```
Keep running the same prompt until it works. That's Ralph.
## What is the Ralph Wiggum Plugin for Claude Code?
The Ralph Wiggum plugin is Claude Code's official plugin that enables autonomous loops—letting AI work on its own for hours without you watching.
**Normal Claude Code:** You ask → It does → You check → You ask again → Repeat.
**Ralph Wiggum Plugin:** You tell Ralph what you want → Walk away → Come back to finished work. The autonomous loop handles everything.
## What is an Autonomous Loop in Claude Code?
An autonomous loop is AI that keeps working without you. The Ralph Wiggum plugin creates these autonomous loops in Claude Code.
1. You give Claude Code a task with clear "done" criteria
2. Claude Code tries to complete it
3. When Claude tries to stop, the Ralph Wiggum plugin checks if it's actually done
4. If not done: Ralph restarts Claude Code with the same task
5. Claude Code sees previous attempts and tries a different approach
6. The autonomous loop repeats until done or hits your iteration limit
**The key:** Each loop is smarter because it learns from previous failures.
```mermaid
flowchart TD
Start([You: Give task with 'done' criteria]) --> Claude[Claude attempts task]
Claude --> Ralph{Ralph checks: Is it done?}
Ralph -->|Not done| Restart[Ralph restarts Claude with same task]
Restart --> Learn[Claude sees previous attempts tries different approach]
Learn --> Claude
Ralph -->|Done| Success([✅ Task Complete])
Ralph -->|Max iterations| Limit([⏱️ Hit iteration limit])
style Start fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
style Success fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
style Limit fill:#795BC2,stroke:#C2E476,stroke-width:2px,color:#fff
style Ralph fill:#795BC2,stroke:#C2E476,stroke-width:2px,color:#fff
style Claude fill:#10312D,stroke:#795BC2,stroke-width:2px,color:#C2E476
style Restart fill:#10312D,stroke:#C2E476,stroke-width:2px,color:#C2E476
style Learn fill:#10312D,stroke:#C2E476,stroke-width:2px,color:#C2E476
```
## Why Do We Need This?
### The Normal Problem
```
You: "Add user authentication"
Claude: *generates code*
You: "No, use JWT tokens"
Claude: *updates code*
You: "The password reset is missing"
Claude: *adds password reset*
You: "Tests are failing"
Claude: *fixes tests*
```
Exhausting and slow.
### The Ralph Solution
```
You: "Add user authentication with JWT tokens, password reset,
and tests with >80% coverage. Done means all tests pass."
Ralph: *works for 2 hours*
Ralph: "Complete. All tests passing."
```
One detailed instruction. Walk away. Come back to finished work.
## When to Use Ralph Wiggum Plugin (And When Not To)
### ✅ Use Ralph For:
- **Mechanical tasks:** "Add JSDoc comments to every function"
- **Tasks with tests:** Anything that can verify itself automatically
- **Big refactors:** Framework upgrades, dependency updates
- **Overnight work:** Queue it Friday, review Monday
### ❌ Don't Use Ralph For:
- **Judgment calls:** Architecture decisions, design choices, security code
- **Vague tasks:** "Make the UI better"
- **Production fires:** When things are broken NOW
- **Quick tasks:** If it takes 2 minutes manually, just do it
**Rule:** If you can describe exactly what "done" looks like, the Ralph Wiggum plugin can probably do it using autonomous loops.
## How to Install and Use Ralph Wiggum Plugin: Quick Start Guide
### Install
```bash
/plugin install ralph-wiggum@claude-plugins-official
```
### Commands
**Start an autonomous loop:**
```bash
/ralph-wiggum:ralph-loop "" --max-iterations 30
```
**Start autonomous loop with auto-stop:**
```bash
/ralph-wiggum:ralph-loop "" --max-iterations 30 --completion-promise "COMPLETE"
```
**Cancel Ralph Wiggum plugin:**
```bash
/ralph-wiggum:cancel-ralph
```
### Example: Add Documentation
**Bad prompt:**
```bash
/ralph-wiggum:ralph-loop "Add comments to my functions" --max-iterations 10
```
**Good prompt:**
```bash
/ralph-wiggum:ralph-loop "Add JSDoc comments to every exported function in src/utils/.
Rules:
- Every exported function gets JSDoc
- Include @param, @returns, @throws
- Use clear descriptions
Done means: Every exported function has complete JSDoc.
Output DOCUMENTED when complete." --max-iterations 20 --completion-promise "DOCUMENTED"
```
**Why the good prompt works:**
- Clear scope (src/utils)
- Specific rules
- Clear "done" criteria
- Safety limit (20 iterations)
## The Secret: BrainGrid Makes Perfect Prompts
Here's what everyone misses: **The Ralph Wiggum plugin is only as good as your prompt.**
Writing good prompts is hard. You need to think through every edge case, acceptance criteria, and implementation detail.
**This is where BrainGrid changes everything.**
### Without BrainGrid
Your vague idea: "Add user authentication"
You write a prompt, but what does "authentication" mean? Email/password? OAuth? Password reset? Rate limiting? The Ralph Wiggum plugin burns iterations guessing.
### With BrainGrid MCP
BrainGrid connects to Claude Code via MCP (Model Context Protocol), giving Claude direct access to structured requirements without copy-pasting.
**Step 1: Set up BrainGrid MCP**
First, connect BrainGrid to Claude Code:
```bash
claude mcp add --transport http braingrid https://mcp.braingrid.ai
```
Verify the connection:
```bash
/mcp
```
You should see `braingrid` listed. BrainGrid will prompt you to authorize via OAuth in your browser.
**Step 2: Create a requirement in BrainGrid**
In Claude Code, ask:
```
"Create a requirement in BrainGrid for user authentication system"
```
Claude (with BrainGrid MCP) creates a structured requirement with:
- Clear description
- Acceptance criteria
- Technical constraints
- Test requirements
**Step 3: Refine in BrainGrid dashboard**
Head to [BrainGrid AI Dashboard](https://app.braingrid.ai) and work with the BrainGrid agent:
```
"Help me refine this requirement and ask any clarifying questions"
```
The agent helps you catch missing details and edge cases.
**Step 4: Break down into tasks**
In the BrainGrid dashboard, click "Break down requirement into tasks." BrainGrid generates concrete, implementable tasks tied to REQ-456.
**Step 5: Build with Ralph + BrainGrid**
Now the magic happens. In Claude Code:
```bash
/ralph-wiggum:ralph-loop "Build REQ-456 from BrainGrid" --max-iterations 40
```
Ralph automatically:
- Fetches the full requirement from BrainGrid via MCP
- Reads all acceptance criteria
- Understands technical constraints
- Knows how to verify completion
- Builds with complete context
No copy-pasting. No missing details. Ralph just points at the BrainGrid requirement and builds it correctly.
### The Difference
**Without BrainGrid:** Vague prompt → Ralph Wiggum plugin guesses → Wastes iterations → Wrong implementation
**With BrainGrid MCP:** Detailed requirement → Ralph Wiggum plugin fetches full context → Builds it right the first time
### The Complete Workflow
```mermaid
flowchart LR
A[💡 Rough idea in Claude Code] --> B[📝 Create requirement in BrainGrid]
B --> C[🔍 Refine requirement in BrainGrid dashboard]
C --> D[📋 Break down into tasks in BrainGrid]
D --> E[🤖 Build REQ-456 with Ralph]
E --> F[✅ Working feature with tests]
style A fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
style B fill:#795BC2,stroke:#C2E476,stroke-width:2px,color:#fff
style C fill:#795BC2,stroke:#C2E476,stroke-width:2px,color:#fff
style D fill:#795BC2,stroke:#C2E476,stroke-width:2px,color:#fff
style E fill:#10312D,stroke:#C2E476,stroke-width:2px,color:#C2E476
style F fill:#C2E476,stroke:#795BC2,stroke-width:2px,color:#0B211F
```
**BrainGrid** = The thinking phase (what to build)
**Ralph** = The execution phase (building it)
Most people skip the thinking phase and jump straight to execution. That's why their prompts fail and the Ralph Wiggum plugin spins endlessly in autonomous loops.
**Setup guide:** [BrainGrid MCP Integration](https://www.braingrid.ai/blog/claude-code-mcp)
**Try BrainGrid free:** [braingrid.ai](https://www.braingrid.ai)
## Ready-to-Use Templates
### Feature Implementation
```bash
/ralph-wiggum:ralph-loop "Build user profile edit feature.
What it needs:
- Form with name, email, bio fields
- Save button calls /api/users/me
- Show success/error messages
- All fields required except bio
Tests: Form renders, validation works, API called correctly
Done means: Feature works and tests pass.
Output COMPLETE when done." --max-iterations 30
```
### Bug Fix
```bash
/ralph-wiggum:ralph-loop "Fix: Users can submit empty contact form.
Steps:
1. Add validation for required fields (name, email, message)
2. Show error messages for empty fields
3. Prevent submission if validation fails
4. Add test to prevent regression
Done means: Empty form blocked and test proves it.
Output FIXED when done." --max-iterations 15
```
## Quick Tips
**Prompt Checklist:**
- ✅ Clear scope (what files/features)
- ✅ Specific requirements (what to do)
- ✅ "Done" definition (how to verify)
- ✅ Safety limit (--max-iterations)
**Iteration Guidelines:**
- Simple tasks: 10-20 iterations
- Medium features: 20-40 iterations
- Complex builds: 40-60 iterations
- **Always set --max-iterations** (never unlimited)
**Cost Estimates:**
- Small task: $5-20
- Medium feature: $30-60
- Large build: $60-150+
**Pro tip:** Test manually with one iteration before running 50-iteration loops.
## Ralph Wiggum Plugin Troubleshooting
**Loop never completes?**
Your "done" criteria aren't clear enough. Be more specific.
**Same error every loop?**
Add to prompt: "If stuck after 10 tries, document the error and stop."
**Costs too high?**
Lower --max-iterations, use .claudeignore, break into smaller tasks.
**Windows issues?**
Install jq: `choco install jq` or use WSL.
## Frequently Asked Questions About Ralph Wiggum Plugin
### What is the Ralph Wiggum plugin?
The Ralph Wiggum plugin is an official Claude Code plugin that creates autonomous loops. It allows Claude Code to work continuously on a task, automatically restarting and trying different approaches until the task is complete or the iteration limit is reached.
### How do autonomous loops work in Claude Code?
Autonomous loops work by: (1) You provide a task with clear "done" criteria, (2) Claude Code attempts the task, (3) Ralph Wiggum checks if it's actually done, (4) If not done, Ralph restarts Claude with the same task, (5) Claude sees previous attempts and tries a different approach, (6) This repeats until done or the iteration limit is hit.
### How do I install the Ralph Wiggum plugin?
Install the Ralph Wiggum plugin in Claude Code using:
```bash
/plugin install ralph-wiggum@claude-plugins-official
```
### What commands does the Ralph Wiggum plugin support?
The Ralph Wiggum plugin supports three main commands:
- Start a loop: `/ralph-wiggum:ralph-loop "" --max-iterations 30`
- Start with auto-stop: `/ralph-wiggum:ralph-loop "" --max-iterations 30 --completion-promise "COMPLETE"`
- Cancel: `/ralph-wiggum:cancel-ralph`
### When should I use Ralph Wiggum plugin?
Use the Ralph Wiggum plugin for mechanical tasks, tasks with automated tests, big refactors, and overnight work. Don't use it for judgment calls, vague tasks, production emergencies, or quick 2-minute tasks.
### How much does Ralph Wiggum plugin cost?
Cost estimates for Ralph Wiggum plugin usage:
- Small task: $5-20
- Medium feature: $30-60
- Large build: $60-150+
### Can I use Ralph Wiggum with BrainGrid?
Yes! BrainGrid MCP integration works perfectly with Ralph Wiggum plugin. BrainGrid helps create structured requirements that Ralph can fetch and build, resulting in better prompts and fewer wasted iterations.
## Conclusion
The Ralph Wiggum plugin removes the iteration tax from mechanical work in Claude Code.
**The shift:**
- **Before:** 3 hours of back-and-forth implementing a feature
- **After:** 10 minutes writing a clear prompt, then do other work while Ralph builds
Start small. Document one folder. Fix linter errors in one directory. Build confidence in what prompts work.
Then scale up. Queue overnight work. Run parallel loops. Let Ralph handle the boring parts while you focus on hard problems.
**Install Ralph Wiggum plugin now:**
```bash
/plugin install ralph-wiggum@claude-plugins-official
```
**Want perfect prompts every time?** BrainGrid helps you think through requirements so the Ralph Wiggum plugin builds it right the first time using autonomous loops.
**[Try BrainGrid + Ralph free →](https://www.braingrid.ai)**
---
# Windsurf MCP Servers: Setup Guide + Best Servers (2026)
Source: https://www.braingrid.ai/blog/windsurf-mcp
Published: 2026-01-07T10:00:00Z
Every time Windsurf's AI writes database code, it guesses at your schema. Every API call gets placeholder responses you'll need to fix manually. That copy-paste cycle kills your momentum—and it doesn't have to be this way.
Model Context Protocol (MCP) servers connect Windsurf to your actual databases, APIs, and external services. Instead of generating boilerplate that needs fixing, Windsurf's agents query your real systems and write code that works the first time.
In this guide, you'll learn what MCP servers are, how to set them up in Windsurf, and which servers will help you ship faster.
## What is MCP in Windsurf?
MCP servers are bridges between Windsurf and external services. They give Windsurf's agents context beyond your codebase—databases, APIs, cloud infrastructure, and more.
After connecting a database MCP server, Windsurf's agents can examine your actual tables and columns. The code it generates is based on real queries that retrieve data correctly, and does not rely on placeholder SQL that must be manually updated.
## Why MCP Matters for Shipping Faster
The same pattern applies across your entire stack. An API MCP server lets Windsurf call actual endpoints and write code that correctly parses real responses. A GitHub MCP server gives context about open issues and PRs.
Without MCP, you're stuck fixing the same boilerplate over and over—copying real values into placeholder code. With MCP, the agents generate code that works the first time, letting you ship faster with fewer manual fixes.
## How to Set Up MCP Servers in Windsurf
Many MCP servers are available for Windsurf. Some install directly from the MCP Marketplace with a few clicks, while others require manual JSON configuration.
### Installing from the MCP Marketplace
To access the MCP Marketplace, open Windsurf Settings (on Mac: **Windsurf → Settings → Windsurf Settings** or press `⌘,`). Search for "MCP" and click the link to open the Marketplace.
The marketplace offers many MCP servers ready to install.
For example, the PostgreSQL MCP server walks you through connection setup—host, port, credentials—and automatically populates the JSON config when complete.
### Installing MCPs manually with JSON
If your MCP server isn't in the Marketplace, you can add it manually by editing the `mcp_config.json` file. Access this file from the Marketplace by clicking the gear icon.
Here is an example `mcp_config.json` file with two MCP servers set up, BrainGrid, and the PostgreSQL set up from the marketplace:
```json
{
"mcpServers": {
"braingrid": {
"args": [
"-y",
"mcp-remote@latest",
"https://mcp.braingrid.ai/mcp"
],
"command": "npx"
},
"postgresql": {
"args": [
"run",
"-i",
"--rm",
"mcp/postgres",
"postgresql://admin:admin@example.com:5432/my-secret-database"
],
"command": "docker",
"disabled": false,
"env": {}
}
}
}
```
This JSON file includes servers installed via the Marketplace as well as manually added ones. The Marketplace simplifies setup by properly formatting the JSON entry for you. The PostgreSQL MCP server creates a small local Docker container with Postgres utilities and your database connection details.
For BrainGrid MCP installation, follow the [official setup guide](https://docs.braingrid.ai/mcp-server/installation#windsurf).
### Windsurf MCP Configuration Format
Each MCP entry specifies a `command` (like `npx` or `docker`) and `args` (the arguments to pass). Windsurf runs these commands when it starts, establishing the MCP server connections.
## Top MCP Servers for Windsurf Developers
* **Databases**: There are MCP servers for most major databases and DB-as-a-service platforms (MySQL, postgres, MongoDB, Redis, Neon, etc.)
* **CloudOps**: AWS and Heroku MCP servers give Windsurf insight into how the application is deployed and configured in the cloud. Additionally access to logs and environment specific behavior can help Windsurf improve reliability.
* **GitHub**: Agents can read pull requests, inspect issues, and understand commit history. This repository content does not live in the codebase, but influences how the code should change.
* **Stripe**: Visibility into billing flows, customers, subscriptions, invoices, and webhooks. Agents can debug and reason about how the billing logic interacts with the codebase.
* **BrainGrid**: Takes vague development ideas, turns them into explicit requirements, and breaks those requirements into structured tasks the agents can execute.
* **Swagger**: When agents are able to read the API specs, they can build to existing endpoints, and parse the results in based on actual responses from the API. No more hallucinated or boilerplate API code to be fixed.
Note that each MCP provides a number of tools to Windsurf, and that Windsurf places a cap of 100 tools that can be active. This might mean enabling and disabling MCPs during different phases of coding.
## BrainGrid MCP: Spec-Driven Development in Windsurf
BrainGrid is an AI product manager that helps developers plan, specify, and build new features. Often, developers jump right in and start prompting before they have a clear picture of what they're building. Running those initial ideas through BrainGrid turns them into structured requirements.
For example, say you want to add a billing flow to your application. BrainGrid analyzes your existing code and asks clarifying questions: which payment providers, what subscription tiers, how to handle failures. These answers become a requirements document your team can approve—spec-driven development. BrainGrid then breaks the requirements into implementation tasks.
The BrainGrid MCP lets Windsurf access these requirements and tasks directly. Instead of copying prompts into the chat, Windsurf reads the full context and builds the feature.
The result: agents build exactly what you specified, with less cleanup afterward. Less context-switching, faster shipping.
## Troubleshooting Common Windsurf MCP Issues
* **Command not found**: If Docker isn't running locally, Docker-based MCPs will fail. Start Docker first.
* **Missing dependencies**: Some MCPs require packages like `mcp-remote`. Install them before configuring.
* **Changes not taking effect**: After installing new dependencies, restart Windsurf to pick up the changes.
## Start Shipping Faster Today
MCP servers give Windsurf's agents the full picture: databases, APIs, issues, designs, and more. With this context, the code they produce is higher quality and far less likely to need the manual fixes you've come to expect from AI-generated code.
When agents build closer to what you actually need, you ship faster. Less time fixing, more time launching.
Ready to go further? [BrainGrid](https://www.braingrid.ai) adds spec-driven development to your workflow—turning vague ideas into structured requirements that generate precise prompts for Windsurf's agents.
## Frequently Asked Questions
#### What is MCP in Windsurf?
MCP (Model Context Protocol) gives Windsurf's agents context beyond your codebase. This includes cloud services, databases, API specifications, or any third-party service that provides insight into how your application works.
#### How do I configure MCP servers in Windsurf?
Use the MCP Marketplace for one-click installs, or manually edit the `mcp_config.json` file with the server configuration.
#### Where is the Windsurf MCP config file located?
The config file is at `~/.codeium/windsurf/mcp_config.json`. The easiest way to access it is through the MCP Marketplace by clicking the settings gear icon.
#### What MCP servers work with Windsurf?
Any MCP server using stdio (local) or http (remote) transport works with Windsurf.
#### How does Windsurf MCP compare to Cursor MCP?
Both support MCP, but they use it differently. Cursor treats MCP as a transactional tool—query and respond. Windsurf integrates MCP into its agentic workflow, using the context for multi-step planning and chaining data across tasks.
#### Why is my Windsurf MCP server not working?
Check the troubleshooting section above. The MCP Marketplace shows connection status—look there for specific error messages to diagnose the issue.
---
# 10 Best Lovable Alternatives in 2026 (Reviewed & Compared)
Source: https://www.braingrid.ai/blog/lovable-alternatives
Published: 2026-01-06T10:00:00Z
You've heard about Lovable. Maybe you've tried it. The pitch is simple: describe your app in plain English, watch AI build it. No code required.
But here's the reality: Lovable isn't the only tool turning ideas into working software. Depending on what you're building and how you work, it might not even be the best one.
This guide breaks down ten alternatives developers and non-technical builders actually use to ship real products. No fluff—just what each tool does well, where it fails, and who should care.
## What Is Lovable and Why Look for Alternatives?
[Lovable](https://lovable.dev/) is an AI web app builder that generates full-stack applications from text descriptions. Popular with non-technical founders who want to validate ideas fast without hiring developers.
The appeal? Speed. Ideas become clickable demos in minutes instead of weeks.
The tradeoffs? Limited customization as apps grow complex. Managing changes at scale gets harder. And if you want to own your codebase fully, tools that export clean, modifiable code feel more sustainable. (Already decided to export? Here's [how to download your Lovable project](/blog/how-to-download-lovable-project) in 15 minutes.)
Different tools optimize for different priorities: code ownership, visual control, terminal workflows, production architecture, or team collaboration. The right tool depends on what you're building and how you build it.
## 1. Bolt.new: Browser to Deployed App in Seconds
[Bolt.new](https://bolt.new/), built by StackBlitz, turns prompts into live, deployed web apps. Type "Build a CRM with contact notes and Kanban board"—Bolt generates the full-stack app and deploys it instantly.
**What makes it different:** Instant deployment. No export or hosting step. Your app is live and shareable the moment it's generated. Powered by Claude Sonnet 4.0, handles React frontends, Node.js backends, and Supabase databases automatically.
**The feature most people miss:** React Native and Expo support. Unlike other tools that stop at web apps, Bolt generates native iOS and Android apps you can preview on your device. No Xcode or Android Studio required.
**Best for:** Non-technical founders needing a working prototype today. Agencies showing clients proof-of-concept. Mobile app builders prototyping without native toolchains.
**Where it struggles:** AI-generated code needs review and debugging. Complex enterprise apps with intricate business logic outgrow the browser environment. Optimized for speed and prototyping, not production-scale depth.
## 2. BrainGrid AI: The Product Manager Your Coding Agent Needs
Here's the problem most builders face with AI coding tools: you describe what you want, get something close but wrong, then spend hours iterating back and forth. The issue isn't the coding tool—it's unclear requirements.
[BrainGrid AI](https://www.braingrid.ai/) doesn't generate code. It generates the plans your coding agents need to generate the **right** code the first time.
### How It Works
Think of BrainGrid as an experienced product manager sitting between you and your coding tools. You describe what you want to build, and BrainGrid asks the clarifying questions: What happens if the user does X? What's the error state? How should this integrate with existing features?
Then it creates detailed specifications and breaks features into well-scoped tasks with clear acceptance criteria. Each task is specific enough that when you hand it to Cursor, Claude Code, or any AI coding tool, the tool builds it correctly the first time.
### Why Requirements Matter
Most AI coding failures happen before code gets written. Vague prompts like "add user authentication" lead to vague implementations that miss edge cases and create bugs. BrainGrid forces clarity upfront.
Instead of "add user authentication," BrainGrid helps you spec out: email/password or OAuth? Password reset flow? Session management? Rate limiting? Each detail becomes a clear task.
**Best for:** Non-technical founders building with AI tools who keep hitting the "that's not what I meant" problem. Developers managing complex features who want to plan before they code.
**Where it struggles:** If you already know exactly what you're building down to implementation details, the planning phase feels like extra steps.
## 3. Cursor: AI Code Editor That Understands Your Codebase
[Cursor](https://cursor.com/) rebuilt VS Code from scratch with AI as the core feature. Instead of switching between your editor and ChatGPT, you work inside Cursor. The AI sees your entire codebase, so suggestions are contextually aware, not generic.
**The standout feature:** Cmd+K. Select code, describe what you want changed, Cursor edits it inline. No copy-pasting. No breaking your flow. Feels like having a senior developer who instantly understands your codebase.
**Best for:** Developers who want AI assistance without leaving their editor. Teams using VS Code who want the smoothest upgrade to AI-assisted coding.
**Where it struggles:** Non-developers. If you don't already code, Cursor won't teach you. It accelerates developers; doesn't replace them.
## 4. Claude Code: Autonomous Coding from Your Terminal
[Claude Code](https://claude.com/product/claude-code) is Anthropic's command-line agent. You describe a task, it works autonomously—reading files, running commands, making edits, verifying work—without babysitting each step.
**The difference is autonomy.** Most AI tools wait for your input between steps. Claude Code operates like a junior developer you've delegated to. It figures out what files to read, runs tests to verify nothing broke, and only interrupts if it needs clarification.
**Best for:** Developers comfortable with terminal workflows. Engineers delegating entire features. Large refactors or migrations where the task is clear but tedious.
**Where it struggles:** Visual work. If your task involves design decisions or requires seeing the UI, terminal-only becomes limiting.
## 5. v0 by Vercel: UI Focused Vibe Coding Tool
If you care what your app looks like, [v0 by Vercel](https://v0.app/) deserves attention. Built by Vercel, specializes in generating React components with shadcn/ui that actually look hand-crafted.
You describe a UI element—pricing table, dashboard card, contact form—v0 generates component code. **The difference is design quality.** Components feel intentional: proper spacing, typography, visual hierarchy.
Integrates tightly with Next.js and shadcn/ui, so code fits naturally into existing projects.
**Best for:** Developers building Next.js apps who want to accelerate UI work. Design-conscious founders who know the difference between "functional" and "professionally designed."
**Where it struggles:** Full application logic. v0 generates components, not entire apps. You still wire up state management, routing, and business logic yourself.
## 6. Emergent: Full-Stack Vibe Coding with Multi-Agent Architecture
[Emergent](https://app.emergent.sh/home) is a full-stack vibe coding platform that handles the complete development lifecycle. You describe what you want in plain English, and Emergent's multi-agent system builds it.
**What sets it apart:** Multi-agent architecture. Specialized agents handle specific tasks—a Builder Agent creates code, a Quality Agent runs tests, a Deploy Agent handles cloud deployment, and an Optimizer Agent improves SEO and accessibility. This produces more reliable results than single-agent systems.
Runs entirely in the browser on Google Cloud Platform VMs. Build with React, Next.js, Expo, or Python with full code access and export control.
**Best for:** Developers who want full-stack control with AI assistance. Non-technical founders building production-ready apps. Teams needing reliable multi-agent workflows.
**Where it struggles:** Learning curve for advanced workflows. Credit costs add up for multiple high-capacity projects. Requires stable internet.
## 7. Rocket.new: AI Debugging That Fixes Issues Before You See Them
[Rocket.new](https://www.rocket.new/) manages the full app lifecycle—from ideation to deployment—in a single workspace. You describe your app idea, and Rocket.new generates frontend, backend, and database setup automatically.
**What makes it stand out:** Smart debugging system. The built-in AI debugger continuously scans for syntax errors, performance issues, or broken dependencies. When detected, it suggests or applies fixes automatically, ensuring cleaner builds without debugging cycles.
Includes modular component library with prebuilt UI elements and auto-generated technical documentation.
**Best for:** Startups aiming for quick MVPs. Individual developers who want AI-assisted debugging. Teams needing GitHub integration built in.
**Where it struggles:** Limited customization for complex enterprise projects. Auto-generated code sometimes needs manual optimization for scalability.
## 8. Replit: Code and Deploy Without Leaving Your Browser
[Replit](https://replit.com) is a browser-based development environment for building and hosting apps. Zero setup—no configuring Node, Python, databases, or environments. Pick a template, start coding, everything works.
Replit AI helps you write code, debug errors, and explain concepts as you work.
**Best for:** Students learning to code. Non-technical founders dabbling in coding without full local setup. Developers prototyping quickly.
**Where it struggles:** Large production-scale applications. Optimized for learning and prototyping, not managing complex enterprise codebases.
## 9. Co.dev: Collaborative AI Workspace for Cross-Functional Teams
[Co.dev](https://www.co.dev/) brings developers, designers, and product owners together in a shared environment. Everyone can contribute to application logic, layout, and deployment in real time.
**What makes it different:** Cross-functional collaboration focus. Instead of developers in one tool, designers in another, and PMs in spreadsheets, Co.dev centralizes the entire workflow with real-time collaborative coding and AI-assisted task automation.
Supports React-based frontends and serverless backends with GitHub, API, and cloud deployment integrations.
**Best for:** Product teams where designers, developers, and PMs collaborate tightly. Small agencies building client projects. Solo developers planning to grow into a team.
**Where it struggles:** Requires stable internet. Some advanced backend features need external integrations. AI accuracy varies by task complexity.
## 10. Base44: No-Code Platform with Low-Code Flexibility
[Base44](https://base44.com/) helps individuals, startups, and small teams rapidly build web applications, dashboards, and automation workflows without traditional coding.
**What makes it stand out:** Visual drag-and-drop interface with AI-assisted workflow automation. You design interfaces visually, and the AI generates workflows, connects databases, and sets triggers. Built-in database and cloud storage eliminate external dependencies.
Features AI-powered component suggestions, adaptive workflows, cross-device testing, and smart data linking.
**Best for:** Non-technical founders who want to build functional apps quickly. Small teams needing rapid prototyping with visual tools.
**Where it struggles:** Limited flexibility for complex custom backend logic. Performance can lag with extremely high data volumes.
## Which Tool Should You Actually Use?
The honest answer: it depends on how you work and what you're building. For a hands-on test where we built the same app with each tool, see our [best vibe coding tools in 2026](/blog/best-vibe-coding-tools-2026) guide.
```mermaid
graph TD
Start[Choose Your Tool] --> Q1{Requirements Clear?}
Q1 -->|No| BrainGrid[BrainGrid AI Plan & Clarify]
Q1 -->|Yes| Q2{What's Your Priority?}
Q2 -->|Speed/Prototype| Q3{Full App or Just UI?}
Q3 -->|Full App| Bolt[Bolt.new Instant Deploy]
Q3 -->|UI Components| V0[v0 Professional UI]
Q2 -->|Development| Q4{Terminal or Editor?}
Q4 -->|Editor| Cursor[Cursor AI Code Editor]
Q4 -->|Terminal| Claude[Claude Code Autonomous Agent]
Q2 -->|Full-Stack| Q5{Need Multi-Agent Architecture?}
Q5 -->|Yes| Emergent[Emergent Multi-Agent System]
Q5 -->|No| Rocket[Rocket.new AI Debugging]
Q2 -->|Learning| Replit[Replit Browser-Based]
Q2 -->|Team Collab| Codev[Co.dev Cross-Functional]
Q2 -->|No-Code| Base44[Base44 Visual Builder]
BrainGrid -.->|Then Use| Q2
style Start fill:#4CAF50,stroke:#2E7D32,stroke-width:3px,color:#fff
style BrainGrid fill:#FF6B6B,stroke:#C92A2A,stroke-width:2px,color:#fff
style Bolt fill:#3B82F6,stroke:#1E40AF,stroke-width:2px,color:#fff
style V0 fill:#3B82F6,stroke:#1E40AF,stroke-width:2px,color:#fff
style Cursor fill:#8B5CF6,stroke:#6D28D9,stroke-width:2px,color:#fff
style Claude fill:#8B5CF6,stroke:#6D28D9,stroke-width:2px,color:#fff
style Emergent fill:#10B981,stroke:#047857,stroke-width:2px,color:#fff
style Rocket fill:#10B981,stroke:#047857,stroke-width:2px,color:#fff
style Replit fill:#F59E0B,stroke:#D97706,stroke-width:2px,color:#fff
style Codev fill:#EC4899,stroke:#BE185D,stroke-width:2px,color:#fff
style Base44 fill:#6366F1,stroke:#4338CA,stroke-width:2px,color:#fff
```
**Quick decision guide:**
- **Planning unclear features?** Start with BrainGrid to clarify requirements
- **Need a prototype by end of day?** Bolt.new for full apps, v0 for UI
- **Developer staying in your editor?** Cursor for AI-assisted coding
- **Terminal-first workflows?** Claude Code for autonomous task completion
- **Full-stack with multi-agent architecture?** Emergent for complex projects
- **AI debugging that fixes issues automatically?** Rocket.new for cleaner builds
- **Learning to code or quick experiments?** Replit for zero-setup development
- **Team collaboration across functions?** Co.dev for cross-functional teams
- **Visual no-code with AI automation?** Base44 for drag-and-drop interfaces
### The Pattern That Works
Most successful builders don't use just one tool. They combine them strategically:
1. **Plan with BrainGrid** to clarify requirements and break features into clear tasks
2. **Build with coding tools** (Cursor, Claude Code, Emergent, Rocket.new)
3. **Polish with specialized tools** (v0 for UI, Bolt.new for prototypes)
4. **Deploy and iterate** based on user feedback
The tools complement each other. BrainGrid ensures you're building the right thing. Coding tools build it efficiently. Specialized tools polish the details.
**The critical mistake:** Assuming one tool does everything. The right stack depends on your skills, your project, and what slows you down most.
## The Real Cost of Choosing Wrong
Picking the wrong tool doesn't just waste time—it creates technical debt that slows you down later.
Use a visual builder for complex logic? Eventually hit platform limits and face painful migration. Use a code generator with messy output? Codebase becomes unmaintainable. **Skip planning and jump to coding? Spend more time debugging vague implementations than you saved moving fast.**
Before you pick one, ask yourself:
- **Do I need to own and modify the code**, or is a hosted platform fine?
- **Am I building a prototype** to validate an idea, or a product I'll scale?
- **Do I know how to code**, or am I learning as I build?
- **Are my requirements clear**, or do I need help defining what to build?
The answers matter more than feature lists or pricing tiers.
## Conclusion: Stop Building Wrong, Start Shipping Right
The AI coding landscape in 2026 offers more options than ever. But having options doesn't matter if you're building the wrong thing.
Here's what we've learned watching builders ship: **the workflow matters more than the tools themselves.**
The fastest builders aren't the ones who jump straight into coding with the newest AI tool. They're the ones who take time to clarify requirements first, then execute efficiently with whatever tools fit their workflow.
That's why BrainGrid exists. Not to replace your coding tools, but to make them actually work. Clear requirements mean your AI coding tool builds it right the first time. Less iteration. Fewer bugs. Faster shipping.
Whether you choose Bolt.new for prototypes, Cursor for development, Emergent for full-stack projects, or any other tool on this list—start by getting clear on what you're building. The tools will take care of the rest.
**Stop guessing. Start shipping.**
---
# Brand as Code
Source: https://www.braingrid.ai/blog/brand-as-code
Published: 2026-01-02T12:00:00Z
As software teams increasingly rely on LLMs and coding agents to build products, a quiet problem keeps showing up:
**AI can write your code, but it does not know your brand.**
It does not know your voice. It does not know your terminology. It does not know what words you never use. It does not know what "on-brand" looks like for your product.
At BrainGrid, this became painfully obvious during our recent rebrand.
## Our rebranding problem
When we rebranded BrainGrid, we ran into an unexpected issue.
Every time we asked an AI coding tool to update copy, docs, UI text, or marketing pages, we had to re-explain the brand from scratch.
Different tools produced different tones. Some sounded too corporate. Others sounded overly hype-driven. None were consistent without heavy prompting.
This was not a model problem.
It was a **missing context** problem.
So we asked a simple question:
> What if brand lived like code?
## Introducing: Brand as Code
We created a single source of truth for the BrainGrid brand that both humans and machines can read.
You can see it live here:
- **Human-readable brand overview**: [braingrid.ai/brand](https://www.braingrid.ai/brand)
- **Machine-readable brand definition**: [braingrid.ai/brand.json](https://www.braingrid.ai/brand.json) and [braingrid.ai/brand.txt](https://www.braingrid.ai/brand.txt)
These files describe how BrainGrid should sound, look, and behave across products, docs, and content.
Once this context existed, AI tools stopped guessing.
They started _executing_.
## What lives in Brand as Code
### 1. Brand principles
Clear statements about what the brand stands for and what it avoids.
```json
{
"principles": [
"Clear over clever",
"Practical over hype",
"Respect the builder",
"Focus on reliability and craft"
]
}
```
This prevents AI from drifting into marketing fluff or generic startup language.
### 2. Voice and tone
How the brand should sound in different situations.
```json
{
"voice": {
"tone": ["confident", "calm", "direct"],
"personality": ["builder-first", "practical", "honest"],
"style": [
"Plain language over jargon",
"Short sentences",
"Builder-first perspective",
"Respect the reader's time"
],
"avoid": [
"Buzzwords",
"Excessive hype",
"Salesy language",
"Vague promises"
]
}
}
```
Now an LLM knows how to write BrainGrid copy without constant correction.
### 3. Terminology rules
Words matter. Especially for AI.
```json
{
"terminology": {
"preferred": [
{ "term": "AI Product Planner", "context": "Our core AI agent" },
{ "term": "AI-native SaaS", "context": "Products built with AI from the start" },
{ "term": "builders", "context": "Our users - founders, developers, product people" },
{ "term": "requirements", "context": "What needs to be built" },
{ "term": "ship", "context": "Get to production (not deploy or launch)" }
],
"avoid": [
{ "term": "magic", "reason": "Vague and hype-driven" },
{ "term": "no-code", "reason": "We're for builders who ship real products" },
{ "term": "one-click", "reason": "Oversimplifies real work" }
]
}
}
```
This alone eliminated a huge amount of inconsistency across our product and docs.
### 4. Visual guidance for systems
Brand as Code does not replace designers, but it gives machines guardrails.
```json
{
"visualPersonality": {
"attributes": ["clean", "modern", "functional", "professional"],
"avoid": [
"Overly playful illustrations",
"Neon gradients",
"Gimmicky animations",
"Generic stock imagery"
]
}
}
```
This helps AI-generated UI and docs stay aligned with the product experience.
### 5. Brand colors
AI tools need exact color values, not vague descriptions.
```json
{
"colors": {
"primary": [
{
"name": "Lime",
"hex": "#C2E476",
"cssVariable": "--color-brand-lime",
"tailwindClass": "bg-brand-lime"
},
{
"name": "Jungle",
"hex": "#10312D",
"cssVariable": "--color-brand-jungle",
"tailwindClass": "bg-brand-jungle"
},
{
"name": "Cream",
"hex": "#F3F1E8",
"cssVariable": "--color-brand-cream",
"tailwindClass": "bg-brand-cream"
}
]
}
}
```
This gives AI the exact color values to use when generating UI or styling suggestions. No more guessing hex codes.
### 6. Logo assets
Machine-readable URLs for every logo variant.
```json
{
"logos": {
"primary": {
"name": "BrainGrid Logo",
"variants": [
{
"name": "Lime on Jungle (for dark backgrounds)",
"svg": "https://www.braingrid.ai/brand/full-logo-lime-on-jungle.svg"
},
{
"name": "Jungle on Lime (for light backgrounds)",
"svg": "https://www.braingrid.ai/brand/full-logo-jungle-on-lime.svg"
}
]
},
"symbol": {
"name": "BrainGrid Symbol",
"variants": [
{
"name": "Lime on Jungle",
"svg": "https://www.braingrid.ai/brand/symbol-lime-on-jungle.svg"
}
]
}
}
}
```
AI tools can reference the correct logo variant based on context. Dark background? Use Lime on Jungle. Light background? Use Jungle on Lime.
---
## Using Brand as Code in practice
We tested this immediately.
We gave Claude Code our brand.json and asked it to update the BrainGrid documentation to match the new brand.
The result:
- Fewer revisions
- Less back and forth
- Far more consistency
- No tone drift across pages
You can see the outcome here: [docs.braingrid.ai](https://docs.braingrid.ai/)
The AI finally had the context it needed.
## Why this matters beyond BrainGrid
We believe we are on the verge of a massive shift.
Over the next few years, millions of SaaS products will be created by small teams and solo founders using AI.
In that world:
- Code is cheap
- Iteration is fast
- Differentiation matters more than ever
Your brand becomes a core system dependency.
If AI is building your product, your docs, your UI, and your marketing, then your brand must be legible to AI.
## Brand is no longer tribal knowledge
Historically, brand lived in slide decks, Figma files, and people's heads.
That does not scale when:
- Multiple AI agents are producing content
- Code is written by machines
- Products evolve daily, not quarterly
Brand needs to be:
- **Explicit** - No assumptions, everything documented
- **Versioned** - Track changes over time
- **Portable** - Works across any tool or system
- **Machine-readable** - AI can parse and apply it
In other words, brand needs to behave like code.
## A proposal to the community
What if every product shipped with:
- `/brand.json`
- `/brand.txt`
Just like we expect:
- `package.json`
- `terraform`
- `openapi.yaml`
Not as a replacement for design or strategy, but as a contract between humans and machines.
We are starting with BrainGrid, but we believe this pattern will become standard.
## Building for the next million SaaS builders
At BrainGrid, our mission is to help builders turn ideas into reliable AI-native SaaS products.
That means more than code.
It means planning. It means structure. It means clarity. And yes, it means brand.
If AI is going to help build the future of software, we need to teach it what we care about.
Brand as Code is one small step in that direction.
---
# Claude Agent SDK: Build Production AI Agents Without Starting from Scratch
Source: https://www.braingrid.ai/blog/claude-agent-sdk
Published: 2025-12-24T12:00:00Z
You've been building features by hand while your competitors ship AI agents that work around the clock. The Claude Agent SDK—the same engine powering Claude Code—is now available as a library.
In the next 20 minutes, you'll understand exactly how to build an autonomous agent that reads your codebase, fixes bugs, and ships features while you focus on landing customers. No PhD required. No six-month learning curve. Just working code you can deploy this weekend.
## What Is the Claude Agent SDK and Why Should You Care?
Here's the situation: you've seen what Claude Code can do. It reads files, runs commands, fixes bugs, and ships features autonomously. What you might not know is that the entire engine powering Claude Code is now available as a library you can drop into your own product.
That's the Claude Agent SDK.
Think of it this way: if Claude Code is the finished car, the Agent SDK is the engine you can install in your own chassis. Same power, your design. The SDK gives you Claude's entire agent loop—the part that decides what to do, uses tools, and verifies its work—without you having to reinvent any of it.
One important note: you might see references to "Claude Code SDK" in older articles or search results. Anthropic renamed it to "Claude Agent SDK" in late 2025 to reflect its broader use cases beyond just coding tasks.
Don't confuse this with the Anthropic Client SDK. The Client SDK requires you to implement the tool loop yourself—you send a prompt, get a response, execute any tools manually, send results back, repeat. It's a lot of plumbing.
The Agent SDK handles all of that autonomously. You send a prompt, and the agent reads files, runs commands, makes edits, and verifies its own work without you writing the orchestration logic.
```mermaid
flowchart LR
subgraph ClientSDK["Client SDK (Manual)"]
A1[Send Prompt] --> B1[Get Response]
B1 --> C1{Tool Use?}
C1 -->|Yes| D1[YOU Execute Tool]
D1 --> E1[Send Result Back]
E1 --> B1
C1 -->|No| F1[Done]
end
subgraph AgentSDK["Agent SDK (Autonomous)"]
A2[Send Prompt] --> B2[Agent Loop]
B2 --> C2[SDK Executes Tools]
C2 --> D2[SDK Verifies]
D2 --> B2
B2 --> E2[Done]
end
```
What does this mean for your product? Your agent can handle customer support tickets, debug code, generate reports, or analyze documents while you sleep. Each of those is a potential paid feature. The SDK removes the build-from-scratch tax so you can focus on what makes your product unique.
## How Do I Install and Set Up the Claude Agent SDK?
A botched setup can waste hours. Let's get this right the first time so you're building in minutes, not debugging your environment.
The SDK comes in two flavors: TypeScript and Python. Pick whichever matches your stack. Both have identical capabilities—the agent loop, built-in tools, streaming, sessions, everything.
**Requirements:**
- Python 3.10+ for the Python SDK
- Node.js 18+ for the TypeScript SDK
- Claude Code CLI is bundled automatically with both packages
Here's the copy-paste installation:
```bash
## TypeScript/Node.js
npm install @anthropic-ai/claude-agent-sdk
## Python
pip install claude-agent-sdk
## Set your API key (get it from console.anthropic.com)
export ANTHROPIC_API_KEY=your-api-key
```
That's it. One command and you're ready.
One gotcha that trips people up: version mismatch between the Claude Code CLI and the SDK. If you're getting weird agent recognition errors, run `claude --version` and make sure it matches the SDK requirements in the docs. This is the most common support question on the GitHub issues, and the fix is always "update your CLI."
Never hardcode your API key in source files. Environment variables keep your credentials out of git history and make deployment cleaner. Your future self (and anyone who reviews your code) will thank you.
Faster setup means faster time-to-demo. When a potential customer asks "can you show me how this works?", you want to be deploying agents, not debugging npm installs.
## What's the Core Agent Loop and How Does It Work?
Understanding the agent loop is the difference between debugging agents quickly and spending days confused about why your agent isn't working.
The loop has three phases that repeat until the task is done:
1. **Gather context** - The agent reads files, searches the codebase, or spawns subagents to collect information
2. **Take action** - Execute tools, run bash commands, generate code, make edits
3. **Verify work** - Check if the output is correct, run tests, validate assumptions
If verification fails, the loop repeats. The agent gathers more context, tries a different approach, and verifies again. This feedback mechanism is what makes agents actually useful—they self-correct instead of confidently shipping broken code.
```mermaid
flowchart TD
A[Start Task] --> B[Gather Context]
B --> B1[Search Files]
B --> B2[Read Documentation]
B --> B3[Spawn Subagents]
B1 & B2 & B3 --> C[Take Action]
C --> C1[Execute Tools]
C --> C2[Run Scripts]
C --> C3[Generate Code]
C1 & C2 & C3 --> D[Verify Work]
D --> D1{Passes Checks?}
D1 -->|No| B
D1 -->|Yes| E[Complete]
style B fill:#10312D,color:#FCFCFB
style C fill:#C2E476,color:#121212
style D fill:#AACF57,color:#121212
```
Here's the loop in action:
```typescript "TypeScript"
import { query } from "@anthropic-ai/claude-agent-sdk";
// The SDK handles the entire loop for you
for await (const message of query({
prompt: "Find and fix the bug in auth.py",
options: {
allowedTools: ["Read", "Edit", "Bash"],
permissionMode: "acceptEdits"
}
})) {
console.log(message);
// Claude reads the file, finds the bug, edits it, verifies the fix
}
```
The biggest pitfall here: agents try to one-shot complex tasks. They'll attempt to implement an entire feature in a single pass, run out of context mid-implementation, and leave you with half-working code. The fix is explicit task breakdown—give your agent smaller, focused tasks rather than "build me an authentication system."
Context management is the production differentiator. Pushing entire conversation history on each API call exhausts your token budget fast. The SDK includes automatic context compaction that summarizes older exchanges, but you should still design your prompts to request focused, specific actions.
A well-tuned agent loop handles 10x more customer requests without human intervention. That's the difference between a support burden and a profit center.
## What Built-In Tools Are Available and When Should I Use Each?
The SDK ships with eight core tools that handle 90% of what you'll need. Here's what each does and when to reach for it:
| Tool | What it does | When to use |
|------|--------------|-------------|
| **Read** | Read any file in the working directory | Viewing code, configs, documentation |
| **Write** | Create new files | Generating new components or configs |
| **Edit** | Make precise edits to existing files | Bug fixes, refactoring, updates |
| **Bash** | Run terminal commands and scripts | Git operations, npm, tests, builds |
| **Glob** | Find files by pattern | Discovering files: `**/*.ts`, `src/**/*.py` |
| **Grep** | Search file contents with regex | Finding function calls, variable usage |
| **WebSearch** | Search the internet | Looking up current documentation or APIs |
| **WebFetch** | Fetch and parse web pages | Reading docs, scraping structured data |
```mermaid
flowchart TD
A[Task Type?] --> B{Read or Write?}
B -->|Read| C{What are you reading?}
C -->|Files| D[Use Read]
C -->|Find Files| E[Use Glob]
C -->|Search Content| F[Use Grep]
C -->|Web Info| G[Use WebSearch/WebFetch]
B -->|Write| H{What are you changing?}
H -->|New File| I[Use Write]
H -->|Edit Existing| J[Use Edit]
H -->|Run Commands| K[Use Bash]
style D fill:#AACF57,color:#121212
style E fill:#AACF57,color:#121212
style F fill:#AACF57,color:#121212
style G fill:#10312D,color:#F3F1E8
style I fill:#C2E476,color:#121212
style J fill:#C2E476,color:#121212
style K fill:#473392,color:#FCFCFB
```
Here's the critical security lesson: don't enable all tools by default. Start with read-only access (`Read`, `Glob`, `Grep`) and add write capabilities only after you've validated the agent's behavior. One Reddit thread described an agent that ran `rm -rf` on a test directory because Bash was enabled without restrictions. Start paranoid, loosen permissions carefully.
Each tool you enable is a capability you can market. "AI that fixes your bugs" requires the `Edit` tool. "AI that deploys your code" requires `Bash`. Think about which capabilities map to features your customers will pay for, then enable only those.
> Building an agent is the easy part. Knowing which features to build first is where most founders waste months. BrainGrid turns your vague ideas into structured specs with AI-ready tasks—so you ship features that convert, not features that collect dust.
## How Do I Add Custom Tools and Integrate External APIs?
Built-in tools cover file operations and web access. But your agent needs to talk to your product—your CRM, database, Stripe, Slack, whatever powers your business. That's where custom tools and MCP come in.
Model Context Protocol (MCP) is Anthropic's standardized way to connect agents to external services. Instead of writing OAuth flows and API wrappers yourself, you plug in pre-built MCP servers for Slack, GitHub, Asana, Playwright, databases, and hundreds more. They handle authentication and API calls. You just configure them.
Here's how to add browser automation with the Playwright MCP server:
```typescript
import { query } from "@anthropic-ai/claude-agent-sdk";
for await (const message of query({
prompt: "Open our pricing page and verify it loads correctly",
options: {
mcpServers: {
playwright: {
command: "npx",
args: ["@playwright/mcp@latest"]
}
}
}
})) {
console.log(message);
}
```
For custom integrations that don't have pre-built servers, you define your own tools with input validation and safety guards:
```typescript
import { z } from "zod";
const createContactTool = {
name: "create_crm_contact",
description: "Create a new contact in the CRM",
inputSchema: z.object({
email: z.string().email(),
name: z.string().min(1),
plan: z.enum(["free", "pro", "enterprise"])
}),
handler: async ({ input, context }) => {
// Always add timeout protection
const controller = new AbortController();
const timeoutId = setTimeout(() => controller.abort(), 5000);
try {
const result = await crmClient.createContact(input, {
signal: controller.signal
});
clearTimeout(timeoutId);
return result;
} catch (error) {
clearTimeout(timeoutId);
throw error;
}
}
};
```
```mermaid
flowchart LR
A[Claude Agent] --> B[MCP Protocol]
B --> C[Playwright MCP]
B --> D[GitHub MCP]
B --> E[Slack MCP]
B --> F[Custom MCP]
C --> G[Browser Automation]
D --> H[GitHub API]
E --> I[Slack API]
F --> J[Your Database]
style A fill:#C2E476,color:#121212
style B fill:#10312D,color:#F3F1E8
```
The critical pitfall: failing to sandbox tools. Running shell commands or database queries without timeouts creates runaway processes and security holes. Every custom tool should have a timeout wrapper, input validation, and explicit error handling.
Every integration you add is a potential upsell. "Connect to Stripe" becomes a Pro feature. "Sync with Slack" becomes an Enterprise add-on. Plan your integrations around what customers will pay for before you build them.
## How Do I Handle Long-Running Agents and Subagents?
Real production tasks take minutes or hours, not seconds. A security audit across a large codebase. Analyzing months of customer support tickets. Generating comprehensive documentation. Agents that crash mid-task lose customer data and trust.
The SDK handles this through two mechanisms: sessions and subagents.
**Sessions** maintain context across multiple exchanges. Your agent can work on a task, you can close your laptop, come back tomorrow, and resume exactly where it left off. Context is preserved—files read, analysis done, conversation history.
```typescript
let sessionId: string;
// First query: capture session ID
for await (const message of query({
prompt: "Read the authentication module and understand how it works",
options: { allowedTools: ["Read", "Glob", "Grep"] }
})) {
if (message.type === "system" && message.subtype === "init") {
sessionId = message.session_id;
}
}
// Later (hours or days later): resume with full context preserved
for await (const message of query({
prompt: "Now find all places that call the auth module",
options: { resume: sessionId }
})) {
console.log(message);
// Agent remembers everything from the first query
}
```
**Subagents** handle task complexity by isolating context windows. When your main agent hits a complex subtask, it spawns a specialized subagent to handle it. The subagent works in its own context, returns relevant excerpts, and the parent continues without context explosion.
```python
import asyncio
from claude_agent_sdk import query, ClaudeAgentOptions
async def analyze_codebase():
# Enable Task tool to let Claude spawn subagents automatically
async for message in query(
prompt="Analyze this codebase for security vulnerabilities",
options=ClaudeAgentOptions(
allowed_tools=["Read", "Glob", "Grep", "Task"]
)
):
print(message)
# Claude may spawn subagents for:
# - SQL injection analysis
# - XSS vulnerability scanning
# - Dependency auditing
asyncio.run(analyze_codebase())
```
```mermaid
flowchart TD
A[Parent Agent] --> B[Analyze Task]
B --> C{Complex Enough?}
C -->|Yes| D[Spawn Subagents]
D --> E[Security Subagent]
D --> F[Performance Subagent]
D --> G[Documentation Subagent]
E --> H[SQL Injection Report]
F --> I[Latency Analysis]
G --> J[Missing Docs List]
H & I & J --> K[Aggregate Results]
K --> L[Return to Parent]
C -->|No| M[Handle Directly]
style A fill:#C2E476,color:#121212
style E fill:#10312D,color:#F3F1E8
style F fill:#10312D,color:#F3F1E8
style G fill:#10312D,color:#F3F1E8
```
One common problem: CPU usage spikes to 100% when spawning too many subagents simultaneously. Claude tries to parallelize aggressively, which is great for speed but can overwhelm modest hardware. Limit concurrency in your `.claude` configuration or implement explicit concurrency controls in your orchestration layer.
The SDK also includes automatic context compaction. For very long-running operations, it summarizes older parts of the conversation to prevent token exhaustion. You don't need to implement this—it happens automatically—but understanding it helps you design better prompts.
Agents that handle hour-long analysis tasks without crashing can charge premium pricing. Reliability is a feature customers pay for.
## What Are the Critical Mistakes That Cost You Customers?
Every crashed agent is a churned customer. Every silent failure erodes trust. Here are the mistakes that kill production agents—and how to avoid them.
| Mistake | What You'll See | The Fix |
|---------|-----------------|---------|
| No tool time limits | Runaway processes, hung requests | Wrap every tool handler in a 5-second timeout |
| Full history on every call | Token exhaustion mid-task | Use conversation summaries + selective retrieval |
| No streaming backpressure | UI freezes, stalled responses | Flush SSE/websocket frames explicitly |
| Hardcoded agent prompts | Can't update without redeploy | Store agent templates in a config service |
| No verification layer | Silent failures, wrong outputs | Add rules-based + visual feedback loops |
| Single model dependency | Outages cascade to users | Route fast tasks to Haiku, complex to Sonnet |
```mermaid
flowchart LR
A[Mistake] --> B[Agent Crash]
B --> C[Customer Sees Error]
C --> D[Support Ticket]
D --> E[Trust Erodes]
E --> F[Churn]
G[Timeout Wrappers] -.->|Prevents| B
H[Verification Layer] -.->|Prevents| C
I[Monitoring] -.->|Catches| D
style A fill:#EF4444,color:#FCFCFB
style F fill:#EF4444,color:#FCFCFB
style G fill:#AACF57,color:#121212
style H fill:#AACF57,color:#121212
style I fill:#AACF57,color:#121212
```
The most insidious mistake: marking features complete without end-to-end testing. Agents will confidently report "task complete" while the feature is actually broken. Without verification—whether that's automated tests, visual checks, or LLM-as-judge evaluation—you're shipping silent failures.
Permission sprawl is the fastest path to unsafe autonomy. Treat tool access like production IAM: start from deny-all, allow only what each agent needs, require explicit confirmations for sensitive actions, and block dangerous commands entirely.
One person on the Anthropic community described their experience:
> "We deployed an agent that could run Bash commands for our internal tooling. Worked great in dev. In production, a weird edge case triggered `git reset --hard` on a customer's repo. Three hours of their work, gone. Now every destructive command requires human approval, no exceptions."
Each security hole is a lawsuit waiting to happen. Each crashed agent is a support ticket. Each silent failure is revenue walking out the door. Build verification into every agent from day one.
## How Do I Deploy My Agent to Production This Weekend?
An agent sitting on your laptop earns $0. You need it live, in front of customers, collecting feedback and proving value. Here's the fastest path from "working locally" to "deployed and demo-ready."
The proven stack for a weekend deploy:
```
┌─────────────────────────────────────────────────────────┐
│ Your SaaS │
├─────────────────────────────────────────────────────────┤
│ Next.js Frontend │
│ ├── /app/api/agent/route.ts ← Claude Agent SDK │
│ └── /app/dashboard ← User interface │
├─────────────────────────────────────────────────────────┤
│ Database (Postgres) │
│ ├── Sessions table (agent state) │
│ └── Results table (outputs) │
├─────────────────────────────────────────────────────────┤
│ Vercel │
│ ├── Edge Functions (API routes) │
│ └── Cron Jobs (scheduled agents) │
└─────────────────────────────────────────────────────────┘
```
Here's a minimal API route that streams agent responses to your frontend:
```typescript
// app/api/agent/route.ts
import { query } from "@anthropic-ai/claude-agent-sdk";
import { NextRequest } from "next/server";
export async function POST(req: NextRequest) {
const { prompt, sessionId } = await req.json();
const encoder = new TextEncoder();
const stream = new ReadableStream({
async start(controller) {
for await (const message of query({
prompt,
options: {
allowedTools: ["Read", "Glob", "Grep"],
resume: sessionId,
permissionMode: "bypassPermissions"
}
})) {
controller.enqueue(
encoder.encode(`data: ${JSON.stringify(message)}\n\n`)
);
}
controller.close();
}
});
return new Response(stream, {
headers: { "Content-Type": "text/event-stream" }
});
}
```
```mermaid
flowchart TD
A[User Browser] --> B[Next.js on Vercel]
B --> C[API Route: /api/agent]
C --> D[Claude Agent SDK]
D --> E[Built-in Tools]
D --> F[MCP Servers]
C --> G[Postgres Database]
G --> H[Sessions Table]
G --> I[Results Table]
style B fill:#121212,color:#FCFCFB
style D fill:#C2E476,color:#121212
style G fill:#10312D,color:#F3F1E8
```
The critical deployment gotcha: rate limiting. Without it, one eager user can exhaust your entire monthly API budget in an hour. Add request limits per user, per session, and per time window before you go live.
Feature-flag new capabilities per tenant. When you add a new tool or integration, roll it out to beta users first, validate it doesn't break anything, then expand. This saves you from deploying a bug to 100% of customers simultaneously.
Add monitoring from day one. Plug SDK hooks into your observability stack—Datadog, OpenTelemetry, whatever you're already using. Capture tool latency, token usage, error rates. You can't improve what you don't measure, and you definitely can't debug production issues without logs.
A deployed agent is a demo-able product. Demo-able products close deals. Get it live, then iterate.
---
You now have everything you need to build production AI agents with the Claude Agent SDK. But building the right agent—one that customers actually pay for—requires more than code. It requires clarity on what to build and why.
BrainGrid transforms your product ideas into AI-ready specifications, breaking complex features into tasks that agents can execute. Stop guessing. Start shipping.
---
# Claude Code MCP Servers: Setup Guide + Best Servers (2026)
Source: https://www.braingrid.ai/blog/claude-code-mcp
Published: 2025-12-24T10:00:00Z
You're pasting logs, docs, or snippets of data into Claude Code. Again.
Every question about your system means manual context. Tab switching. Re-explaining decisions. Copying the same information from one tool to another. It works - but the friction adds up fast.
This isn't a Claude Code problem.
It's a **context problem**.
Out of the box, Claude Code only knows what's in your repository and what you paste into chat. Your database, designs, GitHub PRs, APIs, and internal docs don't exist unless you explain them — repeatedly.
What if Claude Code could query your database, read designs, and understand GitHub on its own?
That's exactly what **Claude Code MCP** enables — and it takes about **5–10 minutes** to set up.
**MCP (Model Context Protocol)** lets Claude Code connect directly to the rest of your stack through MCP servers. Instead of guessing schemas, Claude can ask. Instead of placeholders, it fetches real data. Remove the context bottleneck, and Claude Code finally feels like the agent you expected.
## What is MCP in Claude Code?
**MCP (Model Context Protocol)** is an open standard that lets AI tools like Claude Code connect to external systems in a structured, reliable way.
The simplest mental model is:
> **MCP is an API layer for AI agents.**
Just like APIs connect frontends to services, MCP connects Claude Code to databases, APIs, internal tools, specs, and more.
With MCP, Claude Code doesn't just receive context — it can request it on demand. No more dumping schemas into prompts or pasting API responses into chat windows.
Anthropic introduced MCP as an open standard, and today there's a growing ecosystem of community and first-party MCP servers.
### Why MCP matters?
MCP isn't about making Claude Code _“smarter.”_ It's about reducing context-switching.
When Claude Code can access the same sources of truth you use — databases, repos, specs — you stop re-explaining and start building. This is why database MCPs, Playwright MCP, and spec-driven systems like **BrainGrid** create so much leverage.
### Claude Code _without_ MCP
Without MCP, workflows usually look like this:
- Paste schemas
- Describe API responses
- Re-explain decisions every session
Claude responds, but always with partial or stale context. Every new question reloads the same information.
### Claude Code _with_ MCP
With MCP configured, Claude can:
- Query live schemas
- Fetch API responses
- Read structured specs
- Pull tool outputs on demand
In short, Claude stops guessing and starts checking.
> **“AI that sounds smart”** vs **“AI that understands your project.”**
### How MCP works?
When you connect an MCP server, Claude Code gains access to a set of **tools** — actions it can take on your behalf. Think of each tool as a specific capability: "query this database," "fetch this file," or "create this resource."
Here's the flow:
```mermaid
sequenceDiagram
participant You
participant Claude Code
participant MCP Server
participant External Tool
You->>Claude Code: "What tables are in my database?"
Claude Code->>MCP Server: Discover available tools
MCP Server-->>Claude Code: list_tables, run_query, etc.
Claude Code->>MCP Server: Call list_tables()
MCP Server->>External Tool: Query database schema
External Tool-->>MCP Server: Table list
MCP Server-->>Claude Code: Formatted response
Claude Code-->>You: "You have 3 tables: users, orders, products"
```
The key insight: **Claude Code doesn't talk directly to your database, API, or service.** The MCP server acts as a translator — exposing safe, well-defined tools that Claude can invoke without needing raw access.
MCP supports multiple transport protocols:
- **HTTP** — recommended for hosted services (most common)
- **stdio** — runs locally as a subprocess (great for dev tools)
- **SSE** — server-sent events (deprecated)
You don't need to understand these internals to get started. Just know that MCP provides a clean, standardized bridge between Claude Code and your tools.
## Why Use MCP with Claude Code?
MCP sounds powerful — but is it worth setting up?
If you're already using Claude Code, the answer becomes obvious once you try it.
### 1. Real-time data access
Without MCP, Claude's answers are only as good as the last thing you pasted.
With MCP, Claude can:
- Query live database schemas
- Fetch current API responses
- Check the real state of services
This alone removes a massive source of bugs and back-and-forth.
### 2. Native tool integration
MCP makes tools first-class inside Claude Code.
Common MCP servers include:
- GitHub (issues, PRs, repo context)
- Figma (design metadata)
- Supabase (schemas and queries)
- Playwright (browser automation)
Claude pulls context directly from the source — no tab switching, no summarizing by hand.
### 3. Workflow automation
Once multiple MCP servers are connected, Claude Code can:
- Read a spec
- Check the database
- Generate code
- Validate it with tests
All in one flow.
This is where MCP stops being “tool access” and starts becoming **workflow automation**.
### 4. You stop being middleware
The most immediate win: no more copy-pasting.
No schemas in chat.
No pasted API responses.
No re-explaining the same decisions.
Claude Code MCP removes that friction so the AI works _with_ your tools, not around them.
## Top 10 MCP Servers for Claude Code
You don't need dozens of servers to get value. Most teams start with a small, focused set.
Here are **10** of the most useful MCP servers for Claude Code in real workflows.
### 1. Supabase MCP Server
Query Postgres directly, explore schemas, and write accurate SQL without guessing table names.
**Best for:** Full-stack developers using Supabase as their backend
This is often the _first_ Claude Code MCP server people install — and for good reason. It completely eliminates schema copy-pasting and lets Claude reason over your actual database structure.
### 2. GitHub MCP Server
Read pull requests, browse repositories, and pull issue context straight into Claude Code.
**Best for:** Teams using GitHub for version control
Instead of summarizing PRs or pasting links, Claude can read the code changes itself and reason about what actually changed.
### 3. Figma MCP Server
Pull design tokens, component specs, and layout details directly from Figma files.
**Best for:** Frontend developers building from design handoffs
This removes the ambiguity between “what the design says” and “what gets built,” especially when translating designs into real components.
### 4. Playwright MCP Server
Run browser automation, capture screenshots, and debug UI flows programmatically.
**Best for:** QA automation and visual testing
The Playwright MCP Claude Code setup is especially useful for validating UI changes without leaving your editor or manually clicking through flows.
### 5. BrainGrid MCP Server
Turn vague feature ideas into structured requirements and AI-ready tasks.
**Best for:** AI builders and teams who want spec-driven workflows
BrainGrid's MCP server allows you to access and create requirements, build tasks, and track progress directly from Claude Code. This adds a missing layer on top of MCP with tools like:
```bash
Build REQ-123
Create a requirement from this plan
Run an acceptance review on this PR
```
This is where MCP stops being “tool access” and starts becoming a **system**.
### 6. PostgreSQL / MySQL MCP Server
Direct database connectivity for non-Supabase setups.
**Best for:** Teams running their own databases
If you're not on Supabase, this gives you the same schema-aware benefits without changing your stack.
### 7. Context7 MCP Server
Fetch always up-to-date library documentation.
**Best for:** Working with fast-moving or unfamiliar libraries
It's especially useful when official docs lag behind recent releases or when APIs change faster than blog posts do.
### 8. Filesystem MCP Server
Navigate files, search directories, and understand large project structures.
**Best for:** Monorepos and complex codebases
Claude Code becomes significantly better at reasoning about where things live and how files relate to each other.
### 9. Slack MCP Server
Search conversations, pull decisions, and reference past discussions.
**Best for:** Remote teams with important context living in Slack
This prevents those classic “why did we do it this way?” moments when the answer is buried in a thread from three months ago.
### 10. Linear MCP Server
Pull issues, update statuses, and connect tasks directly to code.
**Best for:** Teams using Linear for project management
This keeps planning and implementation tightly connected instead of drifting apart.
## How to Add MCP Servers to Claude Code
Let's get practical.
There are two main ways to add MCP servers to Claude Code. Use the **CLI** for quick experiments, or a **config file** for shared and repeatable setups.
We'll use **BrainGrid MCP** as the example.
### Option 1: CLI Commands (Quickest)
The quickest way to add an MCP server.
**Basic syntax:**
```bash
claude mcp add --transport
```
#### HTTP-based MCP server (most common)
Most hosted MCP servers (including BrainGrid) use HTTP.
```bash
claude mcp add --transport http braingrid https://mcp.braingrid.ai
```
That's it. Claude Code can now talk to BrainGrid.
#### Stdio-based MCP server (local tools)
Some MCP servers run as local processes via `stdio`.
```bash
claude mcp add --transport stdio airtable -- npx -y airtable-mcp-server
```
**Important:** The `--` matters.
Everything after it is passed to the server process, not the Claude CLI.
**Windows note:** If you're on Windows, wrap the command like this:
```bash
cmd /c npx -y airtable-mcp-server
```
### Option 2: Configuration File (Recommended for Teams)
For shared codebases, use a config file to keep MCP setup consistent across machines.
Create **`.mcp.json`** in your project root.
#### Basic structure
```json
{
"mcpServers": {
"braingrid": {
"transport": "http",
"url": "https://mcp.braingrid.ai"
}
}
}
```
Claude Code automatically reads this file when the project opens.
#### Environment variables (recommended)
Avoid hardcoding secrets by referencing environment variables.
```json
{
"mcpServers": {
"github": {
"transport": "http",
"url": "https://mcp.github.com",
"headers": {
"Authorization": "Bearer ${GITHUB_TOKEN}"
}
}
}
}
```
Supported formats:
- `${VAR}` — required
- `${VAR:-default}` — fallback
This is the safest and cleanest way to handle tokens.
### Understanding Configuration Scopes
This part confuses a lot of people, so let's make it simple.
Each MCP server can be defined at different scopes:
| Scope | Location | When to use |
| -------------- | ---------------- | ------------------------------------------------- |
| **Project** | `.mcp.json` | Shared servers like databases, specs, or CI tools |
| **User** | `~/.claude.json` | Personal tools you want in every project |
#### Scope precedence
If the same server is defined multiple times, Claude Code uses this order:
**Project > User**
### Quick Setup: BrainGrid MCP (End-to-End)
Let's put it all together with a real setup.
**Step 1: Add the server**
```bash
claude mcp add --transport http braingrid https://mcp.braingrid.ai
```
**Step 2: Authenticate (if prompted)**
BrainGrid uses OAuth. Claude Code will open a browser to complete login.
**Step 3: Verify the connection**
Inside Claude Code, run:
```bash
/mcp
```
You should see `braingrid` listed as an active server.
**Step 4: Test it**
Ask Claude Code to list BrainGrid projects or create a sample requirement.
If it returns real data, your MCP setup is working.
Once you've added one MCP server, the rest follow the same pattern.
From here on, Claude Code fetches context on demand — no more manual copy-pasting.
## Troubleshooting Common MCP Issues
If MCP doesn't work on the first try, you're not doing anything wrong.
Most Claude Code MCP issues come down to **connectivity, authentication, or output limits**. The good news: almost all of them are easy to fix once you know where to look.
### Server Not Connecting
This is the most common setup issue.
#### Step 1: Check if Claude can see the server
Inside Claude Code, run:
```bash
/mcp
```
If the server doesn't appear, Claude isn't loading it at all. That means the issue is configuration-level, not runtime.
#### Step 2: Verify the URL or command
For **HTTP-based servers**:
- Confirm the URL is correct and reachable
- Try opening it in a browser or via `curl`
- Check for typos or trailing slashes
For **stdio-based servers**, re-check the command passed after `--`.
#### Step 3: Check network restrictions
VPNs, proxies, and corporate firewalls often block MCP traffic.
Try:
- Temporarily disabling your VPN
- Switching networks
- Allowlisting the MCP server domain
This is especially common with hosted MCP servers.
#### Step 4: Increase the timeout (for slow startups)
Some servers take longer to respond, especially on first run.
`export MCP_TIMEOUT=10000`
### Authentication Failures
Authentication issues are the **most common reason MCP “half works”** — where the server appears but returns no real data.
#### OAuth-based servers (e.g. BrainGrid)
1. Run `/mcp` in Claude Code
2. Click the server name
3. Complete the browser login flow
If you recently changed accounts or permissions, re-authentication is often required.
**Common BrainGrid fix:**
Disable and re-enable the server to trigger a fresh auth flow.
#### API key–based servers
- Confirm environment variables are set
- Restart Claude Code after exporting variables
- Avoid hardcoding secrets in `.mcp.json`
Quick check:
```bash
echo $GITHUB_TOKEN
```
If it prints nothing, Claude can't use it either.
### Output Truncated Errors
Partial responses usually mean you've hit an output limit.
#### Increase the limit
```bash
export MAX_MCP_OUTPUT_TOKENS=50000
```
Notes:
- Warning threshold: ~10,000 tokens
- Default hard limit: ~25,000 tokens
#### Reduce request size
MCP works best with **focused queries**, not large dumps.
- Filter rows
- Limit fields
- Ask for summaries instead of raw data
Smaller requests are faster and more reliable.
### Stdio Server Won't Start
This mostly affects local tools — **especially on Windows**.
#### Windows fix (very common)
Wrap `npx` commands like this:
```bash
cmd /c npx -y
```
Without this, Claude Code may fail silently.
#### Other checks
- Confirm the package exists:
```bash
npx --help
```
- Verify required environment variables
- Ensure Node.js is installed and in your `PATH`
If the process exits immediately, it's usually a startup or environment issue.
## BrainGrid MCP + Claude Code: Spec-Driven Development
Once you have MCP working in Claude Code, the next real unlock is **spec-driven development** — and this is where **BrainGrid MCP** truly shines.
Instead of prompting Claude with half-formed ideas and fixing things as context inevitably gets lost, BrainGrid gives your AI a **persistent map**: requirements, acceptance criteria, and tasks that stay consistent across your entire coding session.
This is the shift from _“AI helping you code”_ to _“AI helping you build.”_
### 6.1 Why Spec-Driven Development Matters
Most AI coding breaks down for one simple reason:
**There's no shared source of truth.**
When you code without a spec:
- Context gets lost across prompts
- Requirements drift mid-implementation
- You end up re-explaining decisions and reworking code
Spec-driven development flips this completely.
You define _what you want_ once, in a structured format, and let the AI reference that spec throughout the build — across files, tasks, and iterations.
Think of it as:
> **AI coding with a map, instead of coding blind.**
If you want a deeper dive into the philosophy behind this, we've written more about it here:
👉 [Spec-Driven Development: Ship Reliable Software Faster with AI](/blog/spec-driven-development)
### 6.2 Setting Up BrainGrid MCP
Before jumping into Claude Code, you'll need to set up BrainGrid itself.
**Step 1: Create a BrainGrid account**
- Go to **[BrainGrid AI Dashboard](https://app.braingrid.ai)** and sign up
- Connect your GitHub account
- Select the repository you're actively coding in
This allows BrainGrid to understand _where_ the work is happening and keep requirements tied to real codebases — not abstract ideas.
**Step 2: Connect BrainGrid to Claude Code via MCP**
For a visual walkthrough, refer to the **Quick Setup: BrainGrid MCP (End-to-End)** section above.
Add the BrainGrid MCP server to Claude Code:
```bash
claude mcp add –transport http braingrid https://mcp.braingrid.ai
```
Once added:
- Run `/mcp` inside Claude Code
- Verify that **braingrid** appears in the connected servers list
- BrainGrid will prompt you to authorize via OAuth
- Complete the authorization flow
**Claude Code and BrainGrid are fully connected**.
### 6.3 BrainGrid MCP Workflow
BrainGrid MCP follows a simple **three-phase spec-driven** workflow.
You'll often see this workflow described using shorthand like specify → break down → build — not as rigid commands, but as a way to describe how intent flows through the system.
#### 1: Turn an Idea into a Requirement
Start with a rough idea, directly in Claude Code:
`“Create a requirement in BrainGrid to Add role-based access control to the admin dashboard”`
Claude, powered by BrainGrid MCP, converts this intent into a structured requirement with:
- Clear description
- Acceptance criteria
- Constraints and assumptions
This is no longer a vague prompt. It becomes your [product requirements document](https://docs.braingrid.ai/mcp-server/usage#create-a-new-requirement) — a single source of truth.
Once done, head over to the [BrainGrid AI Dashboard](https://app.braingrid.ai). There, you can further refine it by working with the BrainGrid requirements agent. You can give instructions like:
`"Help me refine this requirement and ask any clarifying questions."`
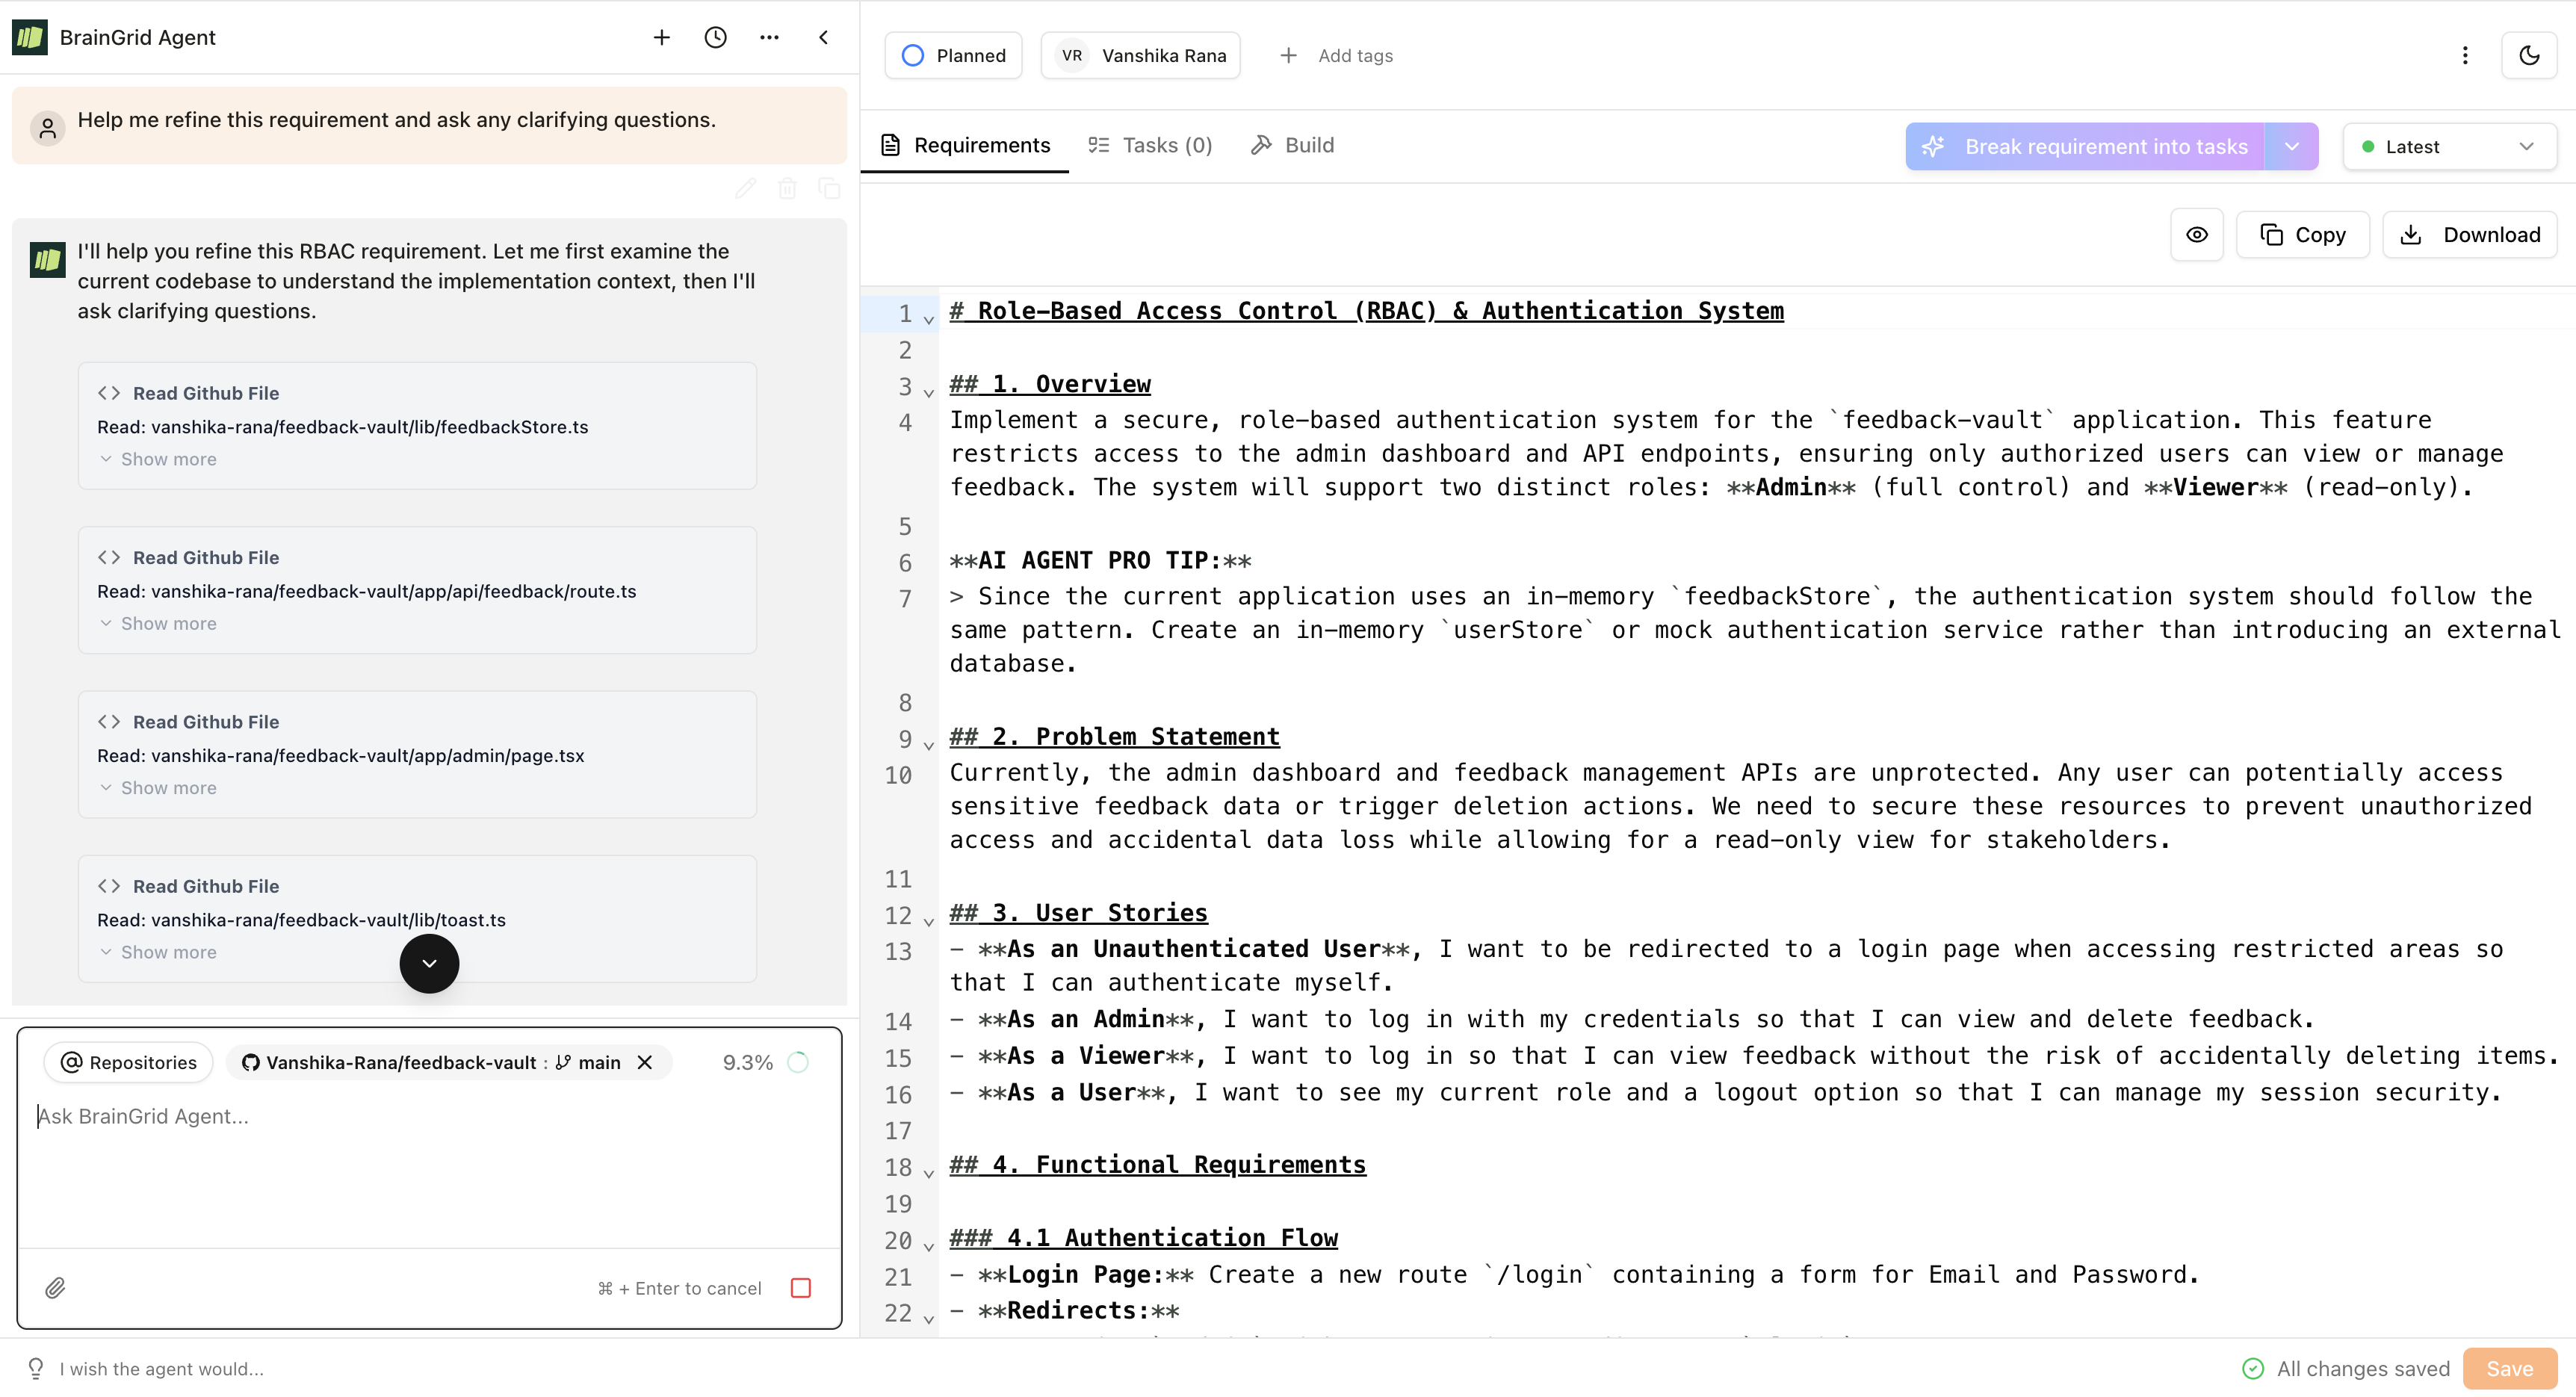
This helps improve clarity, fill in gaps, and capture details you might have missed.
#### 2: Break the Requirement into Tasks
Once the requirement exists (for example, REQ-123), it's refined and broken down — typically via the BrainGrid app — into concrete, implementable tasks.
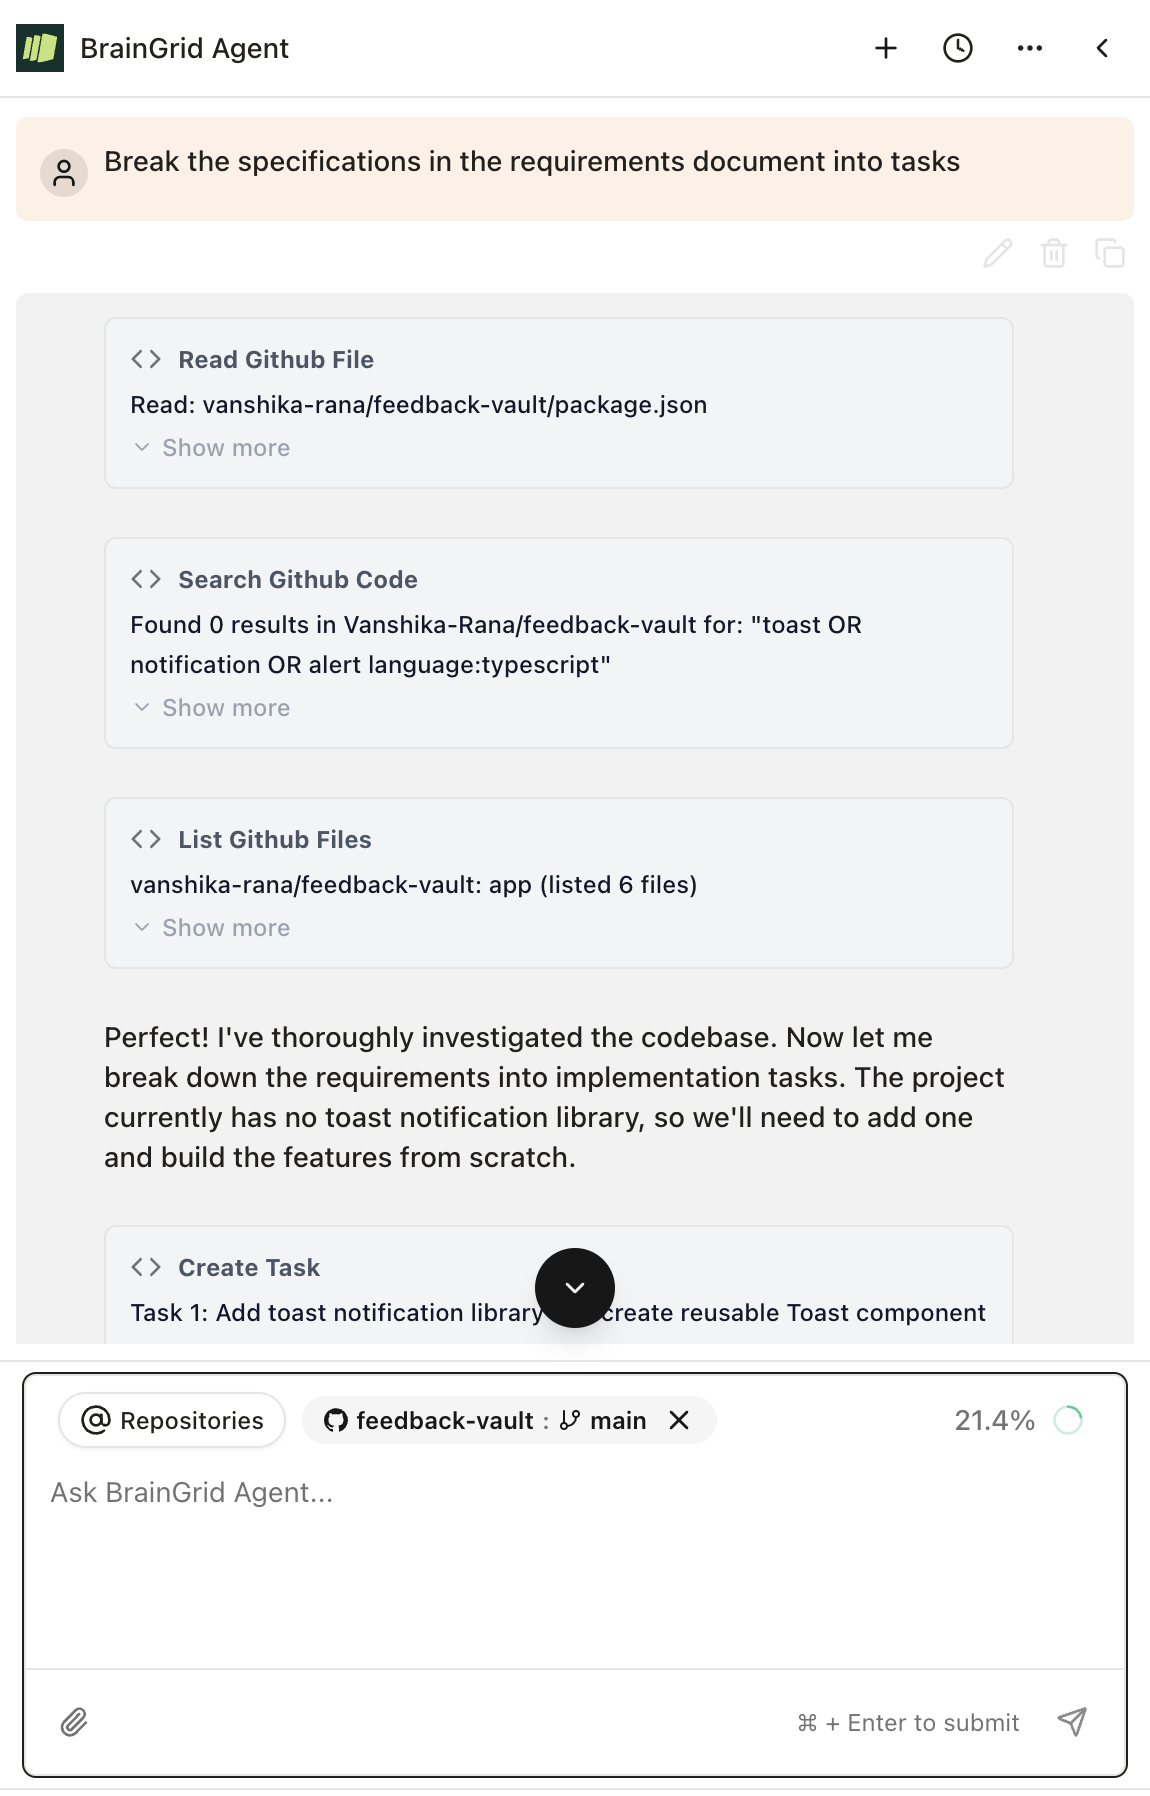
From the dashboard, click “Break down requirement into tasks.” BrainGrid will generate a list of actionable tasks tied directly to the requirement.
Each task is scoped tightly enough for focused AI-assisted implementation, without guesswork or oversized prompts. You can [fetch any task directly](https://docs.braingrid.ai/mcp-server/usage#get-a-task) from Claude Code.
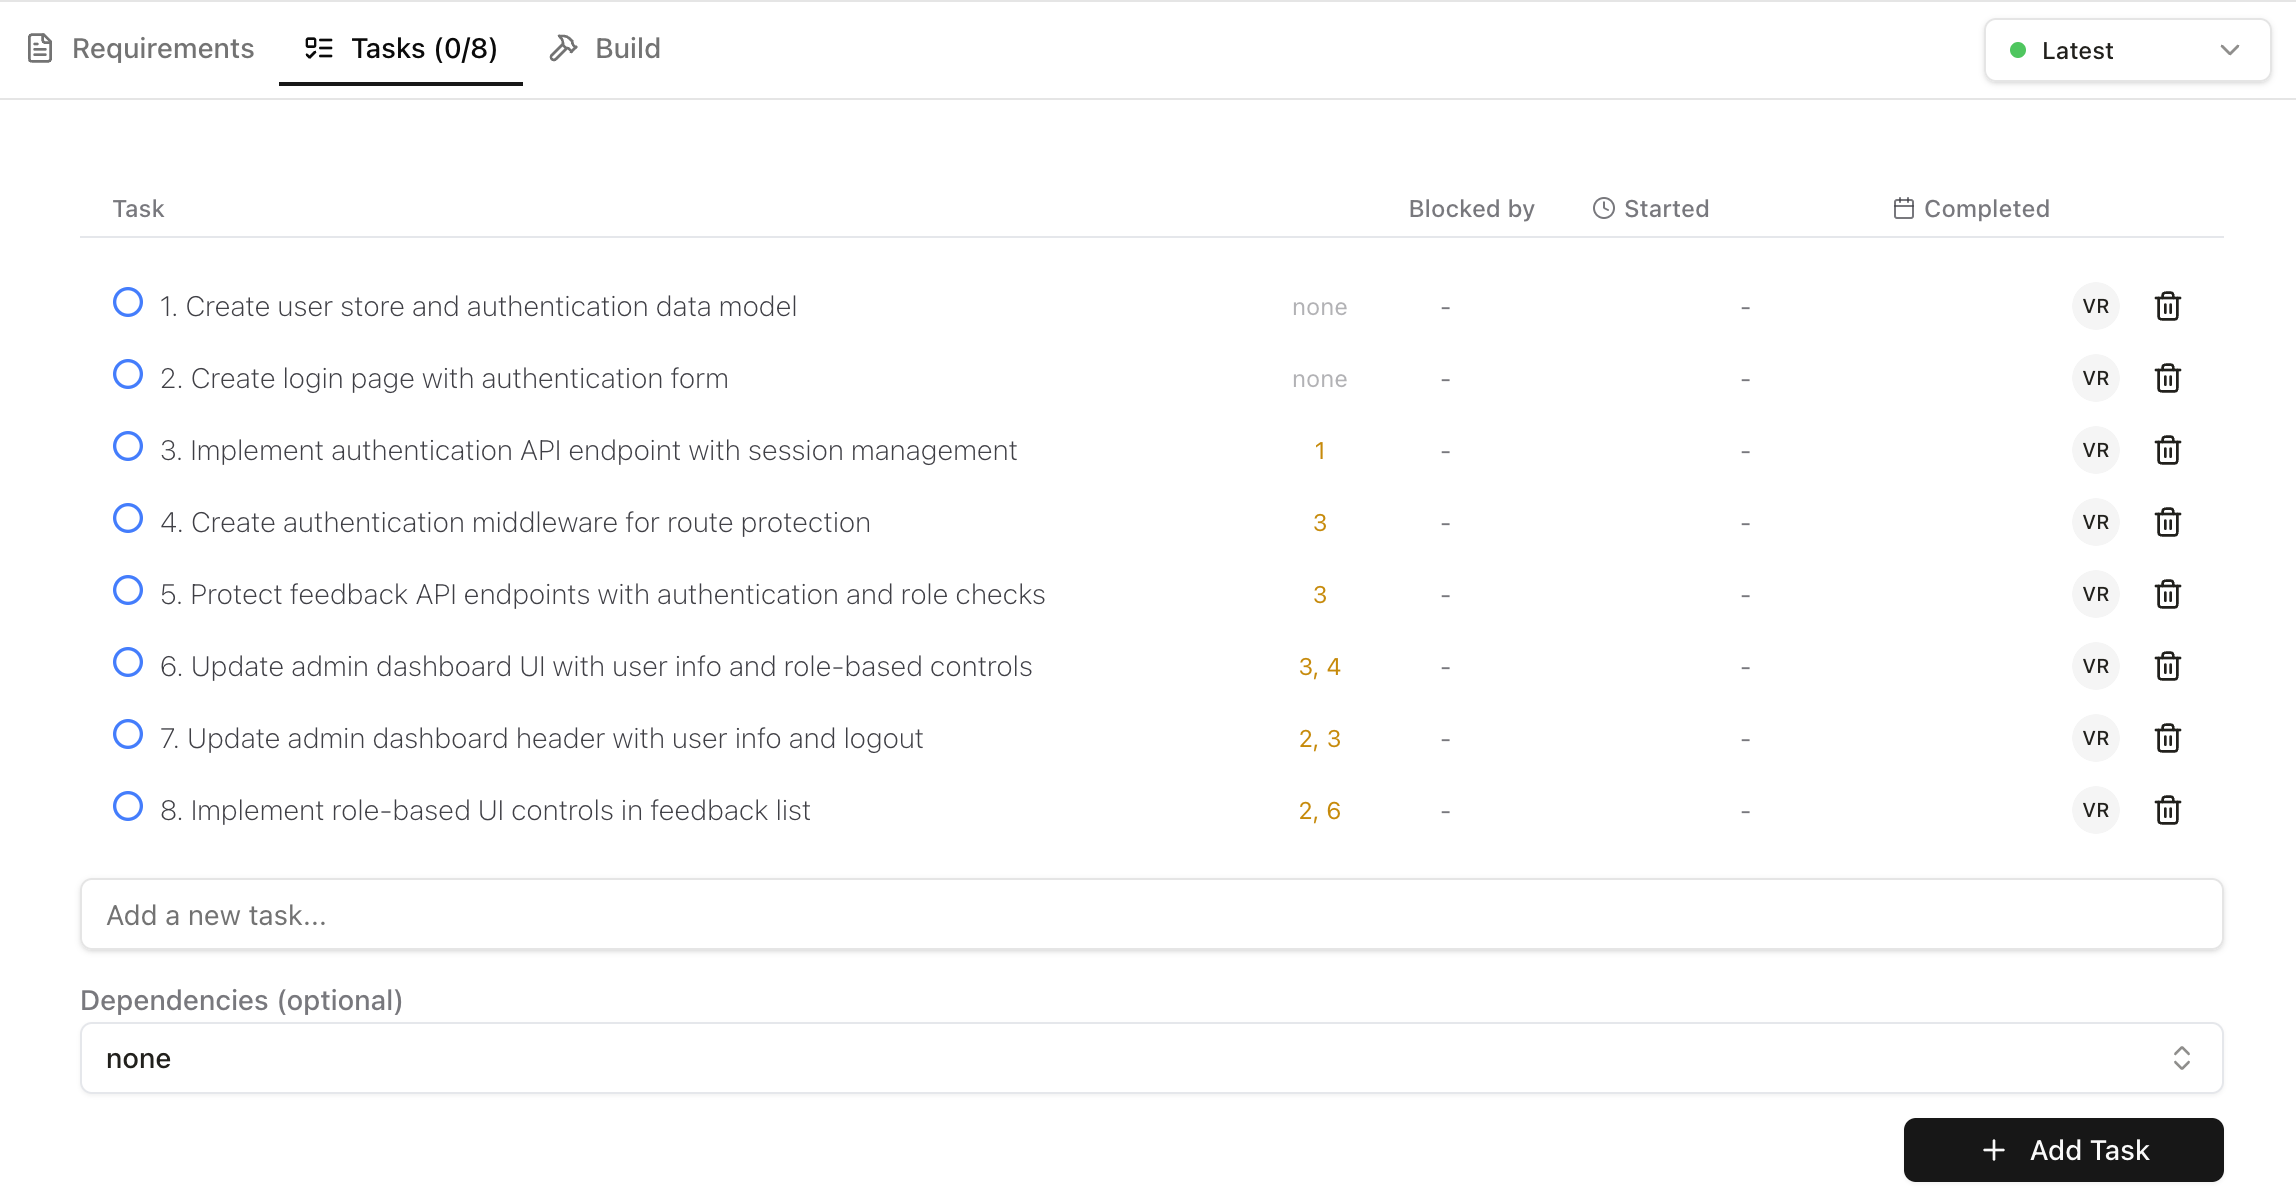
#### 3: Build with Full Context
Now comes the real magic.
Pull everything into Claude Code and run:
```bash
Build REQ-123
```
This [builds the full requirement](https://docs.braingrid.ai/mcp-server/usage#build-a-requirement) with all its context loaded. Claude now has access to:
- The original requirement
- Acceptance criteria
- A complete task list
- Review Acceptance Criteria
Each task becomes a **high-signal, guided coding session** instead of a guessing game.
### Why This Changes Everything
With BrainGrid MCP, Claude Code isn't just responding to prompts.
It's working against a **living spec**.
That means:
- Less rework
- Fewer clarification loops
- More predictable output
- Cleaner handoff between planning and implementation
This is the difference between **AI-assisted coding** and **AI-driven development**.
👉 **Try BrainGrid for free at [braingrid.ai](https://www.braingrid.ai)** and experience spec-driven development inside Claude Code.
## Frequently Asked Questions
### Does Claude Code support MCP prompts?
Yes. Claude Code fully supports the **Model Context Protocol (MCP)** specification, including both tools and resources exposed by MCP servers. This allows durable, reusable context across an entire coding session.
### What is the MCP configuration format?
Claude Code uses **JSON-based MCP configuration files**. Each server defines a transport (`http` or `stdio`), a URL or command, and optional headers or environment variables for auth.
### Does MCP use HTTP?
Yes. MCP supports multiple transports:
- **HTTP** (recommended)
- **stdio** (for local tools)
- **SSE** (deprecated)
Most hosted MCP servers, including BrainGrid, use HTTP.
### How is Claude Code MCP different from Cursor MCP?
Both implement the same **MCP standard**. The difference is setup: Claude Code uses CLI commands and config files, while Cursor uses a settings UI. MCP servers work across both.
## Start Connecting Your Development Stack
MCP helps Claude Code work with your existing development tools — so it understands your code, your data, and what you're trying to build.
You don't need to connect everything at once. Start small with two or three MCP servers that map directly to how you already work:
- **GitHub** for code, pull requests, and issues
- **Your database or backend service** for live schemas and data
- **BrainGrid** for structured requirements and specs
This is where the real shift happens.
With a **spec-driven workflow**, you stop re-explaining decisions and start building with AI that stays aligned — from the first idea to the final commit.
Teams that ship faster aren't writing more code.
They're giving their AI better context.
**MCP is how you do that.**
---
# Windsurf vs Cursor 2026: Full Comparison for AI Coding
Source: https://www.braingrid.ai/blog/windsurf-vs-cursor
Published: 2025-12-23T12:00:00Z
You have more product ideas than hours in the day. AI coding tools like [Windsurf](https://windsurf.com/) and [Cursor](https://cursor.com/) promise to turn your vision into working code—but which one actually ships faster?
Both are VS Code forks with AI superpowers. Both cost roughly the same ($15-20/month). We tested them head-to-head on the same feature to find out which delivers better results.
This guide walks through the key differences between Windsurf and Cursor, with real test results to help you choose the right tool for your workflow.
## What Are Windsurf and Cursor? What are they used for?
Both Cursor and Windsurf are Agentic AI code development tools. They allow developers to use natural-language prompts to generate, modify, and refactor code.
Unlike tools such as Claude Code or GitHub Copilot - which run as extensions inside an existing code editor - Cursor and Windsurf are standalone IDEs (Integrated Development Environments). Both are forks of VS Code, meaning that they replace the need for another IDE, but retain a look and feel familiar to those who have used VS Code in the past.
Both of the tools are inexpensive, Cursor is $20/month and Windsurf comes in at $15/month.
The difference between Cursor and Windsurf comes from *how* the agents work with prompts.
* Cursor is IDE-first, AI Agent second, focusing on *assisting* developers write code, where the developer is in control of the process.
* Windsurf is AI Agent first, and IDE-second. Windsurf aims to take care of the coding autonomously, planning and executing changes with minimal developer intervention.
If you are vibe coding - handing off ideas and letting the agent build - you might find that Windsurf is the better tool. If you are a developer looking for AI assistance while still holding precision control over your codebase, you might find the results from Cursor easier to work with.
## What do Cursor and Windsurf lack?
While both Cursor and Windsurf can write code, they both lack the ability to create detailed requirements prior to building the code. As a result, the prompts used to implement the requirement lack detail, and it may require multiple rounds of iteration with different prompts to obtain the desired result.
The Agents need a product manager to help narrow down the requirements and create tasks that can then be implemented by the agents.
Luckily, [BrainGrid](https://www.braingrid.ai/) is available as an MCP (Model Context Protocol) for both Cursor and Windsurf. MCPs provide AI Agents with additional external contexts. These contexts (APIs, databases, tasks) give the agents further detail and insight that results in code that is more resilient, and more likely to work seamlessly with the full codebase, and the external tools it interacts with. To learn more about how MCPs enhance AI Agents, read our recent post [Cursor MCP Servers: Complete Setup Guide for AI-Powered Development](/blog/cursor-mcp)
We will use the BrainGrid MCP to build a requirements document and create a set of task prompts that can be implemented by AI Agents to add dark mode to the popular open source repository [Formbricks](https://github.com/formbricks/formbricks).
Using BrainGrid, we ask for a feature to be added (in this case, "Add dark mode to the service") and BrainGrid begins by asking clarifying questions that help better define what the final product will look like. For example:
### What parts of the application should support dark mode?
### How should users switch between light and dark mode?
BrainGrid acts as the product manager for development—the questions help focus the scope of changes. Neither Cursor nor Windsurf do this out-of-the-box. Sometimes these questions surface new features (like a toggle switch), but that often improves the final result.
The BrainGrid requirement can be turned into tasks that are easily picked up by both Windsurf's and Cursor's AI Agents to build the code.
In the case of adding dark mode to [Formbricks](https://github.com/formbricks/formbricks), BrainGrid came up with 9 tasks that must be completed:
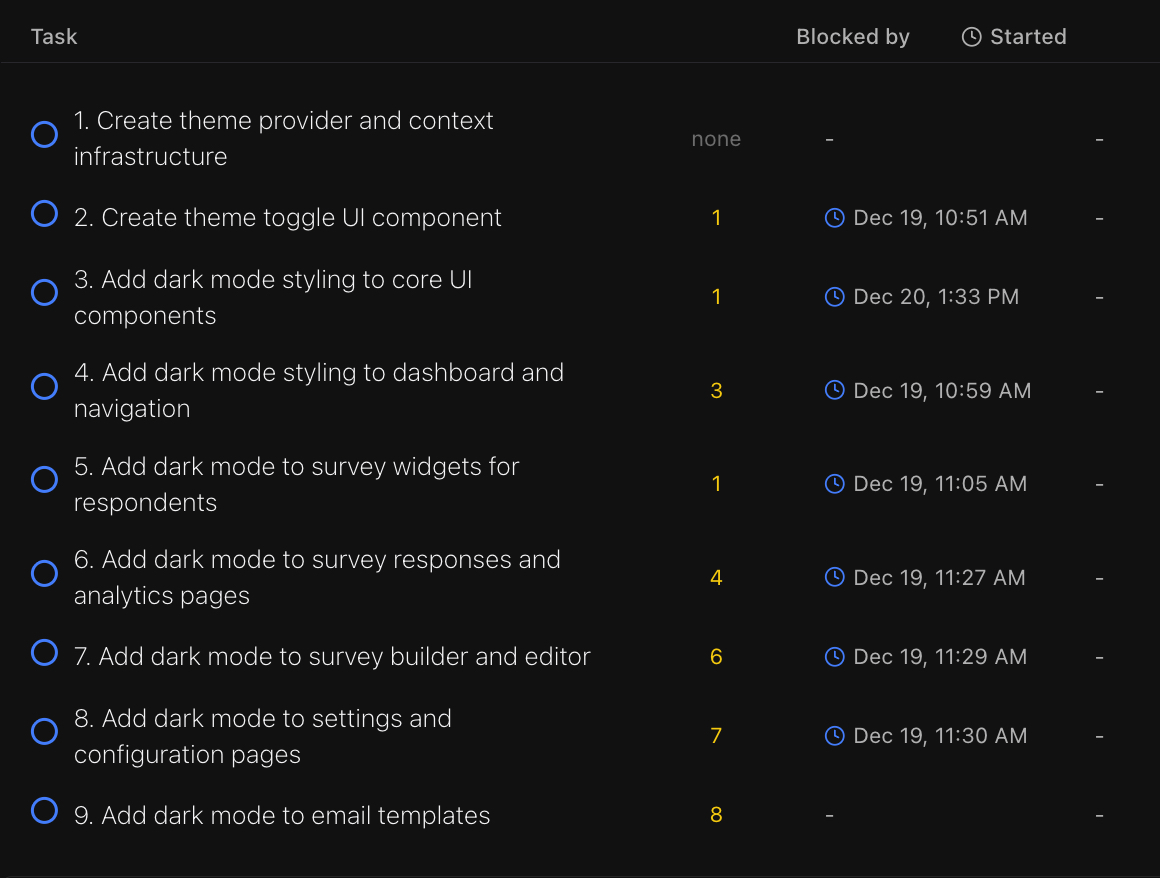
With these tasks in hand, we can use Cursor and Windsurf to implement the feature.
## Which One is Better: Cursor or Windsurf?
Both Cursor and Windsurf supply similar backend LLM models for writing code. The results are generally very similar, so which tool is better will generally fall on the way your team works.
* If you are a single developer building code, focusing on the local context of your code - Cursor is easier and faster to work with.
* If building on complex codebases, and collaborating with your team, Windsurf might be the better choice.
But, perhaps you'd want to see a real life showdown on adding a feature to an existing codebase. Let's use the tasks created by BrainGrid, and see what Cursor and Windsurf produce.
### The Workflow Showdown
With requirements and tasks prompts created, we can apply them to both Cursor and Windsurf to see which better applies our requirement - adding dark mode to our service.
In order to leverage the BrainGrid MCP, it must be installed via the [instructions in the documentation](https://docs.braingrid.ai/mcp-server/overview).
To leverage the BrainGrid requirements, we simply ask the agent to build the tasks in Req-1. The Agent 'knows' that means BrainGrid, and uses the BrainGrid MCP to connect to BrainGrid and retrieve the tasks.
### Cursor
Cursor read in the 9 tasks, and proceeded to complete them, one after another. After completing 3 tasks, it provided an update with details on how the previous three tasks had been completed. It repeated this again after 6 tasks (For a total of 2 requests to continue.)
Once complete, the code had two compilation bugs. With the error supplied to Cursor, they were quickly addressed. Once up and running, it is clear that, while the dark mode is not complete, it had made pretty good progress (estimated about 80% complete).
If continuing with this feature, the next steps would be to ensure that:
* All of the boxes are in dark mode.
* make the mode button easier to see in dark mode (it is hidden in the upper right).
* Update the logo image to work better in dark mode.
### Windsurf
Windsurf required a little prompting help to connect to BrainGrid, but ultimately found the 9 tasks to build.
Windsurf's process involved a lot more feedback, making it feel like the process took much longer. For example, Windsurf asked if it should continue *after editing each HTML component*. There are several dozen HTML components in the Formbricks code, feeling very repetitive (pasting "yes" into the chat window over and over).
Once Windsurf called the job complete, and small compilation bugs were resolved: there was no button to manually switch between light and dark mode (a feature specified in Task 2).
With some additional prompting, the switch was added inside the user settings, but initially the toggle only applied dark mode on the user settings.
With additional prompting, Windsurf was able to get to a point similar to where we stopped with Cursor
Windsurf eventually got to a similar place as Cursor, but it took many additional prompts to ensure the tasks (marked as completed in BrainGrid) were actually completed.
### TL;DR Cursor vs. Windsurf
Asking Cursor and Windsurf to complete the same tasks on the same codebase provided very different results.
Both Cursor and Windsurf had minor compilation bugs that needed fixing before the code would load. Both tools fixed these quickly.
However, once the pages loaded, it was clear that the Cursor implementation was much closer to the requirements created in BrainGrid. Windsurf's initial "code complete" had no way to change into dark mode, and none of the page was rendered in dark mode.
Out of the box, Cursor was about 80% of the way to a full dark mode implementation. Windsurf's code was 100% light mode without a toggle. Additional prompting was needed to add the toggle, and then more prompting to get all components to appear in dark mode (after manually approving each component through the development process).
## Making the Choice: Cursor vs. Windsurf
**Choose Cursor if** you want more control over each code change and prefer faster iteration on smaller tasks. In our test, Cursor delivered 80% of the feature in a single pass with minimal prompting.
**Choose Windsurf if** you prefer a more autonomous AI that plans and executes on its own—just know you may need patience for confirmation prompts on larger codebases.
**Either way**: Pair your tool with [BrainGrid](/) to create detailed requirements first. Our test showed that clear task prompts help both tools deliver better results. Without requirements, you'll waste time re-prompting and debugging code that missed the mark.
---
## FAQ
### Which one is better, Cursor or Windsurf?
Many teams have found success with both. In our test, Cursor came closer to the desired outcome than Windsurf. But your mileage may vary—your workflow may work better with Windsurf's more autonomous approach.
### Is Cursor cheaper than Windsurf?
Windsurf is $15/month; Cursor is $20/month. The $5 difference is minimal compared to the time you'll save picking the right tool for your workflow.
### What are Cursor and Windsurf used for?
Both are AI-powered development environments that help you write, modify, and refactor code using natural language prompts. They're especially useful for shipping features faster when you're not a full-time engineer.
---
# Cursor MCP Servers: Setup Guide + Best Servers List (2026)
Source: https://www.braingrid.ai/blog/cursor-mcp
Published: 2025-12-16T10:00:00Z
*"If you give a man a hammer, everything looks like a nail."*
Cursor is an IDE with built-in AI tooling. The tooling is extremely powerful, and it can get the job done. But one AI tool alone eventually runs into limitations. You find yourself fixing boilerplate code to match reality, or copying and pasting values into your code.
Just as you wouldn't renovate a kitchen with **just** a hammer, relying **only** on Cursor will limit your ability to develop code quickly. Luckily, adding new tools to your Cursor toolbelt is easy: MCP turns Cursor from a single tool into a fully equipped workshop.
Without MCP, Cursor works with the text and the code that are provided in your repo. It has no visibility outside of that code, meaning that Cursor has a strictly one-sided view of how the code interacts with APIs, database, or any other external tool. With MCP servers, Cursor can query your database, read your Figma designs, and help you build requirements and tasks using real external content.
## What is a Cursor MCP Server?
MCP is a Model Context Protocol. Cursor uses a large language model to write and reason about code. MCP is the *protocol* that adds additional *context* to the *model* - helping it better understand contexts that live outside the codebase. MCP servers allow Cursor to retrieve live information from external services instead of relying on assumptions.
MCP servers act as bridges between Cursor and external services. When writing code, Cursor can use this bridge to ensure that the code properly interacts with database tables, or parses the correct output from an API response - instead of adding placeholders that must be updated manually.
## MCP Advantages
Connecting MCP server gives Cursor visibility beyond the code in your repository. Without this visibility, the model might invent placeholders that don't match your APIs, or define database schemas differently from what already exists. When the model works from actual system data, you spend less time correcting assumptions and replacing boilerplate. Instead, the connections **just work**.
Leveraging MCP servers in Cursor provides superpowers to Cursor. With vision and context beyond the codebase, the code generated by Cursor is more likely to be immediately useful - improving developer productivity and quality.
Now that you understand *why* MCP matters, let's look at *which* servers are worth installing.
## Top MCP Servers for Cursor
> NOTE: MCP servers are **not** a HTTP service running on a port that is accessed by the LLM (a server). In the parlance of MCP, a server just means "the thing that provides the tool." It may be a hosted API, a local process, or a CLI-backed integration.
* Databases
* Supabase MCP Server - Query your Supabase Postgres directly, explore schemas, write queries.
* PostgreSQL/MySQL MCP Servers - Like Supabase - direct connectivity to databases.
* Issue management
* GitHub - Read PRs, check issues.
* Linear - Pull issues, update status, connect code to tasks
* Design and Communication
* Figma MCP Server - pull component specs, layouts and designs from the source.
* Slack MCP server - query conversations about issues, and designs for added context.
* Documentation
* Context7 - reads in documentation - giving the model more details about external tooling.
* Spec-Driven Development
* [BrainGrid](https://docs.braingrid.ai/mcp-server/overview) - Create requirements, and turn requirements into structured tasks
Ready to connect your first MCP server? Let's walk through the setup process.
## Cursor MCP Setup Guide
Cursor provides a [directory of available MCP servers](https://cursor.com/docs/context/mcp/directory), each with a link to directly install into your local instance of Cursor. For the BrainGrid MCP, you can install from the [Braingrid Documentation](https://docs.braingrid.ai/mcp-server/installation#cursor)
On clicking the "Add to Cursor" button, the MCP server is installed into Cursor:
Each MCP then needs to be authenticated, and given permission for the service.
Once installed, you can see all of the permissions that Cursor has with Braingrid:
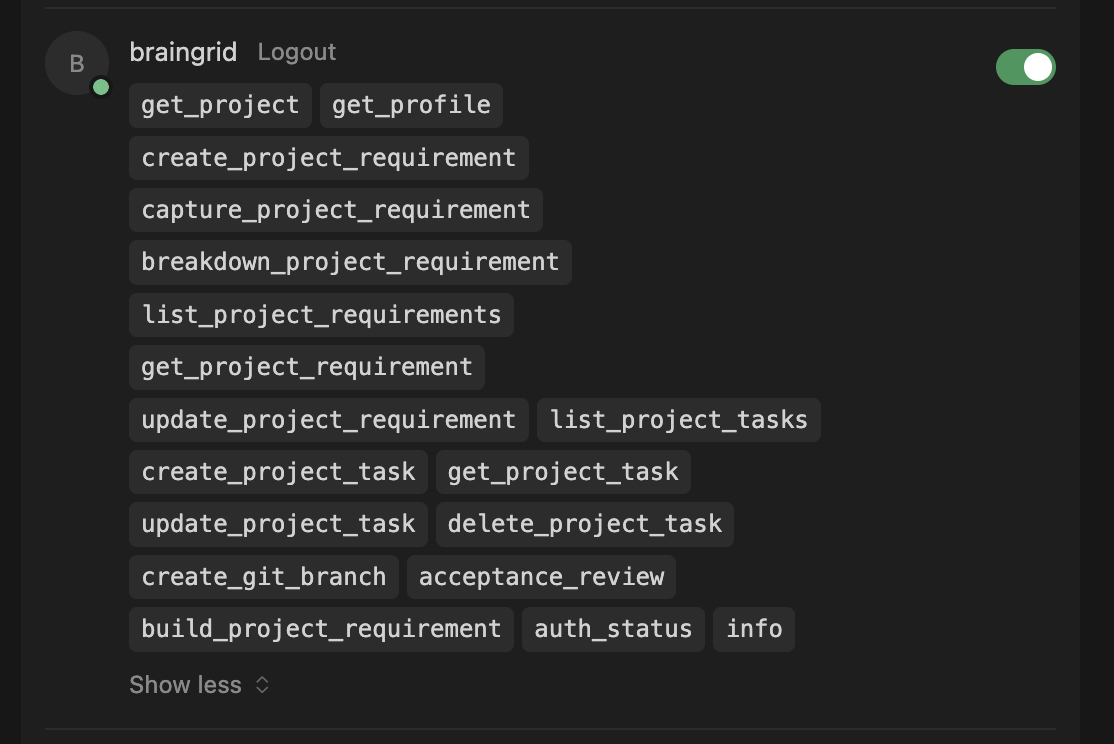
BrainGrid works better when you have the CLI and MCP installed. In your terminal:
```bash
npm install -g @braingrid/cli
braingrid login
```
Follow the login steps in your browser, then run:
```bash
braingrid init
braingrid setup cursor
```
This connects BrainGrid to your project, and enables the Cursor integration.
## JSON installation
Cursor saves MCP configurations inside your repo in the `.cursor/mcp.json` file. You can add your own MCP connection by adding the required JSON. The below code connects to a local MCP server with an API key. Complete instructions on connecting via JSON (and instructions on how to make your own "Add to Cursor" button) can be found in the [Cursor Docs](https://cursor.com/docs/context/mcp#using-mcpjson)
```json
{
"mcpServers": {
"server-name": {
"url": "http://localhost:3000/mcp",
"headers": {
"API_KEY": "value"
}
}
}
}
```
With MCP servers connected, let's see how this works in practice with a real example.
## BrainGrid MCP and Cursor: Spec Driven Development
Here's where MCP becomes a game-changer for shipping faster. Instead of writing long prompts explaining what you want to build, BrainGrid turns vague feature ideas into structured specs and implementation tasks. When Cursor connects to BrainGrid via MCP, it can read those specs directly and build the feature—no copy-pasting requirements into prompts.
Let's walk through a real example. We'll use the [BrainGrid dashboard](https://app.braingrid.ai) to create a requirement, then let Cursor execute the implementation tasks.
We will extend our [Next.js ToDo App](/blog/migrate-lovable-to-nextjs) to add Supabase database storage for each todo.
BrainGrid, as a project management tool, helps you clarify the requirements. For example, it asked what additional data points should be added to the ToDo app. The suggestions were good, so I asked for them to be added to the requirements.
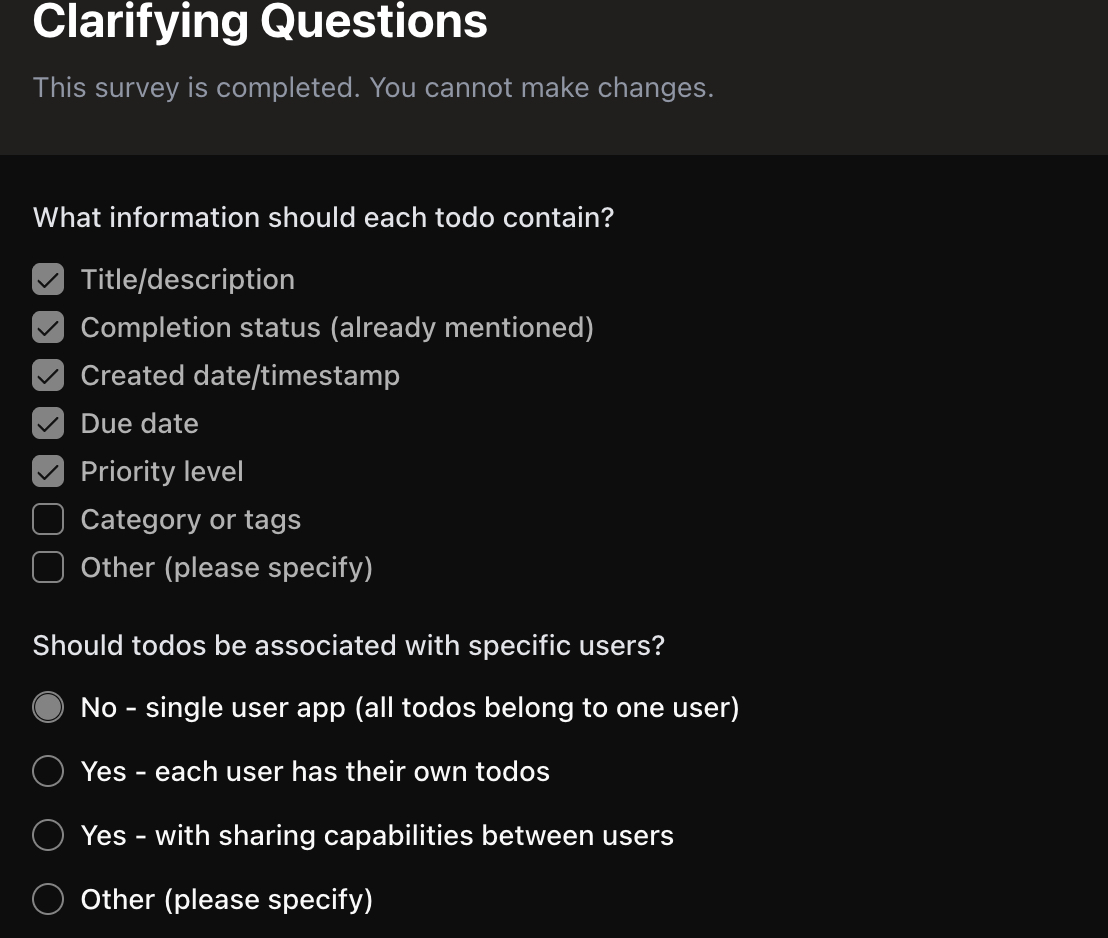
After several minutes, BrainGrid comes up with a requirement.
This document describes the problem, and what must be completed to create a solution. It goes on to have acceptance criteria, describing the work that must be completed to consider the specification completed. Once this is accepted, we ask BrainGrid to create the tasks and prompts that are needed to do the work. After a few more minutes we have these tasks.
With these tasks completed, we can switch to Cursor, and just ask it to complete the tasks that BrainGrid has created. The tasks were a part of Proj-3, Req-6, so by typing
```bash Cursor
/build proj-3 req-6
```
Cursor can access BrainGrid through the MCP, read the prompts and implement the code.
## Start Shipping Faster Today
Cursor is already powerful. MCP makes it dangerous (in a good way).
Without MCP, Cursor guesses at your database schema, invents API responses, and forces you to fix boilerplate. With MCP, Cursor queries your real systems and writes code that actually works the first time.
**Your next steps:**
1. **Install one MCP server** for a service you already use—[Supabase](https://cursor.com/docs/context/mcp/directory), GitHub, or Figma are great starting points
2. **Try [BrainGrid](https://app.braingrid.ai)** to turn your next feature idea into AI-ready tasks that Cursor can build reliably via `/build`
3. **Browse the full directory** at [Cursor's MCP list](https://cursor.com/docs/context/mcp/directory) to find more integrations
Stop copying and pasting. Let MCP connect your tools so you can focus on shipping.
## Frequently Asked Questions about Cursor MCP Servers
#### What is MCP in Cursor?
MCP provides Cursor with more context, by connecting external tools that the codebase may reference, or tools that reference the code (issues, designs, requirements).
#### How do I add custom MCP servers to Cursor?
Many services have implemented a "Add to Cursor" button that takes care of all your configurations. Manual addition of MCP servers is done via the Cursor settings panel or via a JSON file in the `.cursor` directory.
#### What is the MCP configuration format?
The JSON format includes the name, connectivity and routes required to connect to the MCP server. Details can be found in the [Cursor Docs](https://cursor.com/docs/context/mcp#using-mcpjson)
A GitHub MCP configuration might look like:
```json
"github": {
"type": "http",
"url": "https://mcp.github.com",
"headers": {
"Authorization": "Bearer ${GITHUB_TOKEN}"
}
},
```
#### Does MCP use HTTP or stdio?
Cursor MCP uses both. Stdio is recommended for local tools, while http is recommended for remote connectivity.
#### How do I authenticate MCP servers in Cursor?
Most hosted MCP servers use OAuth, where the user logs in with a browser. For local, or API based MCPs, API keys or tokens can be used.
#### Where is the Cursor MCP config file?
The config file is saved in the `.cursor` directory of your repository.
#### Does Cursor support MCP prompts?
Yes. MCP servers can provide both tools (actions) and resources (data). Cursor supports the full MCP specification including prompts.
#### What transport protocols does MCP support?
MCP supports two transports: HTTP (recommended for remote servers) and stdio (for local tools). HTTP is the modern standard.
#### What are common MCP issues? How do I troubleshoot?
The trickiest part of using MCP servers is getting the initial connectivity working, and is most likely to occur when creating a JSON connection to Cursor. Once auth, tokens, and environmental values are correctly set, Cursor works seamlessly with the MCP servers.
---
# How to Migrate Your Lovable App to Next.js (Full Guide)
Source: https://www.braingrid.ai/blog/migrate-lovable-to-nextjs
Published: 2025-12-10T10:00:00Z
AI agent tooling has allowed entrepreneurs with no coding knowledge to build complete SaaS products. But eventually, you hit a limit, and need to find other ways to improve your application and build new features that are beyond the scope of some AI coding tools.
In our [first post on downloading Lovable projects](/blog/how-to-download-lovable-project), we walked through the steps to export your Lovable application into GitHub. Now that it is in GitHub, we can use additional AI tools to improve and add features - growing your application to its full potential.
In this post, we will migrate our Lovable application from a client side React App to a full-stack [Next.js](https://nextjs.org) App. We will use BrainGrid and Claude Code to complete this code migration.
## Why migrate code we just wrote to a different framework?
This is a great question. Lovable apps are built with the React framework - a very popular JavaScript framework for building applications. But it has some drawbacks, including:
* React pages are built on the browser, so the first load is always slow - a lot of JavaScript code has to be downloaded to get your page to work. Slow pages can lose customers.
* Poor search engine optimization. If the bot only sees the empty page (the content loaded too slowly), you won't be indexed by Google, ChatGPT or any other search engine out there.
* Did you optimize your images? React sends your raw images to the browser. There's no server optimization - leading to slow page loading.
Think of Next.js as a supercharged React. It offers all of the advantages of React, but also does most of the work on the server. This means:
* No huge JS download.
* Optimized content for search engines and LLMs
* Image optimization out of the box.
* Development is easier.
The last bullet might not seem important, but if development is easier for human developers, it certainly is easier for AI code assistants as well. By migrating our application to Next.js, we will streamline future development, and also make the application faster, and have better SEO. It's a win/win situation
## Using GitHub to copy the code to your computer
This tutorial begins with your Lovable application migrated to GitHub. If you have not yet connected your app to GitHub, [this is the first step](/blog/how-to-download-lovable-project). We will use a [todo app](https://github.com/dougsillars/chill-todo-vibes) as our example.
Once your application is in GitHub, you'll want to make a local copy. On the GitHub page of your application, click the Green Code button, and copy the URL provided.
We want to clone this repo onto our computer, so that we (by we, I mean the AI agents) can update the code. Open a terminal window to begin the process.
>I personally have a GitHub folder on my Mac to organize all my repos in one place. It just makes finding things easier later on.
```bash
mkdir Github
cd Github
```
This command creates a folder (mkdir means “make directory”) called Github, and changes (cd means “change directory”) to that directory. Now we are ready to clone the application. (You'll need to change the URL to the GitHub link for your application, or just use this one to follow along)
```bash
git clone https://github.com/dougsillars/chill-todo-vibes.git
```
This will create a new directory with your code inside it. The output will tell you the name of your folder:
```bash
git clone https://github.com/dougsillars/chill-todo-vibes.git
Cloning into 'chill-todo-vibes'...
remote: Enumerating objects: 95, done.
```
Change to the directory that your code was “Cloned into.” For example:
```bash
cd chill-todo-vibes
```
This will move into the GitHub directory that I cloned.
You now have made a copy of your application code locally on your computer. Next, we set up your development environment - installing all the tools you'll need to complete the migration. There are a number of steps here, but MANY of these need to be done **just the first time** to get everything set up on your computer.
## Preparing the software
### (Or, 30 minutes of downloading all the bits)
To migrate to Next.js, we need prompts to tell Claude Code what steps to take to migrate the application. Since we do not have expertise in React and Next.js, we will use BrainGrid to build the requirements and create the prompts that Claude needs to do the work. Sign up for free at [BrainGrid.ai](/).
#### BrainGrid and Claude installation
In the terminal, we will install the [BrainGrid CLI](https://docs.braingrid.ai/claude-code) (Command Line Interface).
If you do not already have NPM (Node Package Manager) installed, install [NPM](https://nodejs.org/en/download/).
With NPM installed, we can use it to install and set up BrainGrid.
```bash
npm install -g @braingrid/cli
braingrid login
```
You'll connect the CLI to your BrainGrid account through the website.
Now, we are ready to connect your project to Braingrid:
```bash
braingrid init
```
Walk through the steps to connect your GitHub repository to BrainGrid. Once that is completed, we will connect BrainGrid to Claude Code. If you do not have a Claude Code account, you can create an account at [https://claude.ai/](https://claude.ai/) (note the Claude Code requires a subscription)
```bash
braingrid setup claude-code
```
#### Installing the Coding Environment
Developers use apps called IDEs (Integrated Development Environment) to write code. To connect your GitHub code to Claude Code, we will use [VS Code](https://code.visualstudio.com/download). If you don't have VS code installed, grab it from the link and install it.
Open VS code, and open a new Window:
Click "Open" and then open the repository you just cloned to your computer. We're now ready to develop on the codebase (with Claude, of course!). To add Claude, click the Extensions button on the left navigation, and search for Claude Code, and install it.
Note that there is no install button on my screenshot, as it is already installed on my computer!
To activate Claude Code in your application press Command-Shift-P, and search for Claude. Open this in a new tab:
Now we have all of our code, and all of the tools installed on our computer, and we are ready to go! The good news is that you only had to do all of this once - now that the tools are here, you can use them over and over for new features in your application.
## Finally, time for the migration
In software development, code is built based on the requirements provided to the developers. Requirements describe in detail what features are going to be added, and how that is expected to work. Coding agents are no different - if they don't understand what it is that you are asking them to build, how can they build it correctly?
Once we have requirements, developers break down the work into tasks - the actual work that needs to be done to create the new feature.
We will use Claude and BrainGrid to create the requirements and tasks, and then have Claude Code complete the tasks to create our new Next.js version of the application. BrainGrid is integrated with Claude Code using slash commands ( / followed by a command), so we can use these to continue.
In the Claude tab, we will use the `/specify` command to tell Claude and Braingrid what we want to do:
Claude will walk you through the steps.
* BrainGrid and Claude will reason out the requirements - what are the changes required in the code to make the specification happen.

Through this process, Braingrid/Claude will ask a number of questions and ask for approvals. It will eventually come up with the requirement for the code change:

It will then give you next steps:
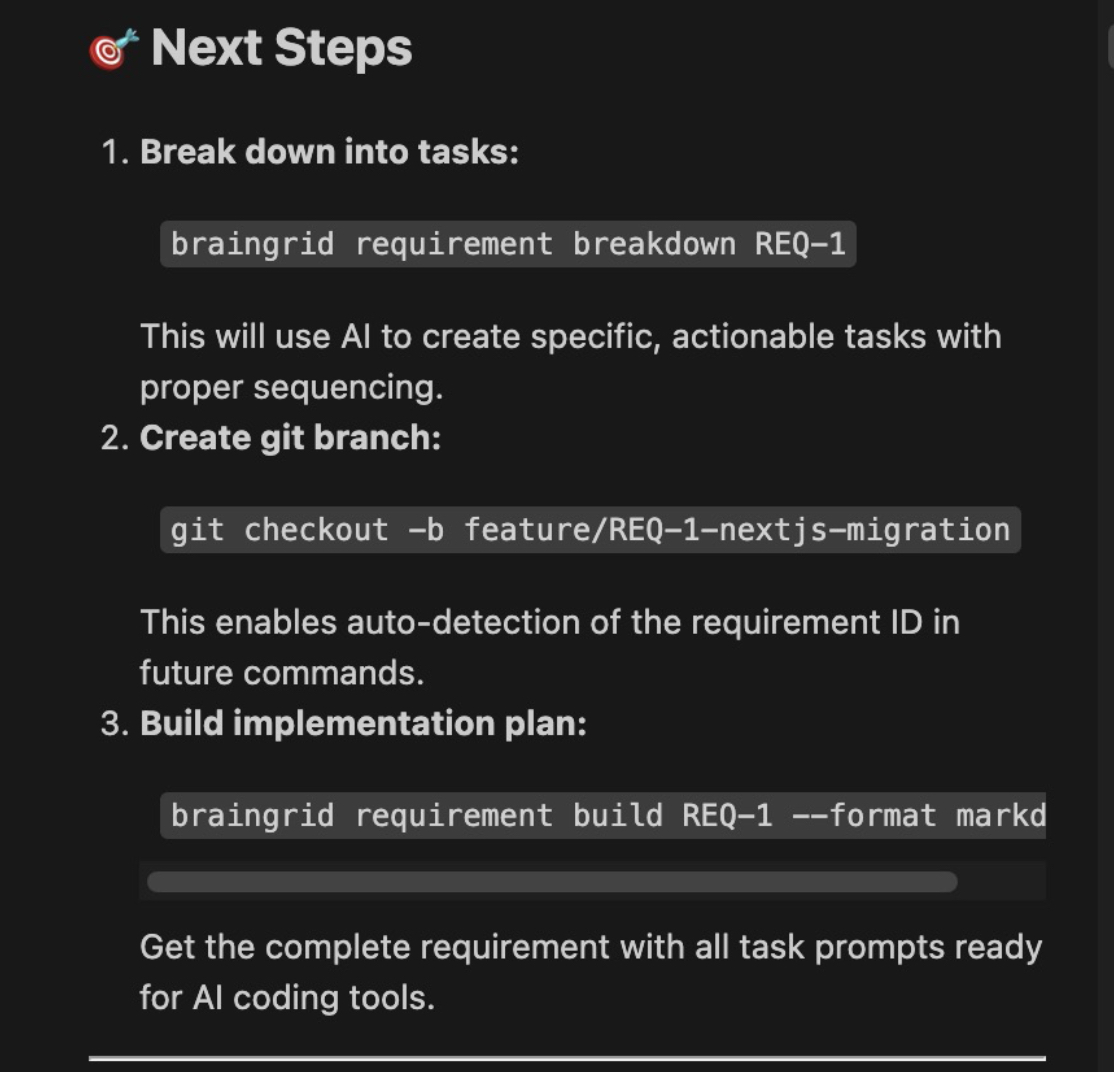
1. Create tasks: We know what needs to be done. This breaks it down into the discrete steps to do the work.
2. Create a Git branch. Branching allows your original code to remain untouched, and the new branch will have all the code changes. (React -> Next.js)
3. Build the plan.
In this case, we have 5 tasks that Claude will complete. Claude can print out all of the prompts, or just begin tackling them.
Here is prompt 1 from this project
```bash
### TASK-1: Configure Next.js Project Structure and Dependencies
Dependencies: None (start here!) Goal: Replace Vite with Next.js 16+ configuration Key Actions:
1. Update package.json:
* Remove: vite, @vitejs/plugin-react, react-router-dom
* Add: next (latest 16.0.7)
* Update scripts: "dev": "next dev", "build": "next build", "start": "next start"
Create next.config.mjs:
{ appDir: true }
2. Update tsconfig.json:
* Set jsx: "preserve", module: "esnext"
* Add "@/*": ["./src/*"] to paths
* Include Next.js types
3. Delete: vite.config.ts, index.html
Success: No Vite deps, Next.js configured, ready for development
```
Claude can now begin working through the tasks, and upon completion, provides details on the migration:
On running these commands, we can try out our application (and you can see how my breakfast shopping list is going):
## Getting the Application on the internet
It is great that we now have working code in Next.js. But now that we are outside of Lovable, how do we get this application deployed to the internet? Vercel is a common cloud platform for deploying Next.js applications.
Claude completes several GitHub tasks for us. It merges our "branch" of code to the main branch, and "pushes" the code to GitHub, This does mean that our React App is no longer in the GitHub repository - but we don't need it any longer!
Claude installs vercel and completes the steps (you will need to create a Vercel account, and authorize access as part of the process). But once it is finished, we receive a deployment summary.

Visiting [https://chill-todo-vibes-hdgv1enhu-doug-sillars-projects.vercel.app/](https://chill-todo-vibes-hdgv1enhu-doug-sillars-projects.vercel.app/) shows us our production application on the web.
## Wrapping up
In this post, we took an existing React application (lovingly created with Lovable) and migrated it to Next.js to improve search indexing and page load times.
We used GitHub to move our code to our local computer, and installed BrainGrid, Claude Code and VS Code to create our AI developer environment. Using this environment, and a few basic commands, we are able to leverage the Requirements generation power of BrainGrid, and the coding talents of Claude Code to easily migrate our code to Next.js, and deploy it on Vercel.
If you're interested in adding SaaS features, creating migrations and more - you too can leverage BrainGrid for your application requirements and task generation, and then pass the tasks to Claude Code to complete the work.
---
# What Is a Product Management Agent?
Source: https://www.braingrid.ai/blog/what-is-a-product-management-agent
Published: 2025-12-09T12:00:00Z
AI coding tools have changed who gets to build software. A new generation of non-technical founders and domain experts can now turn ideas into working features with tools like Cursor, Claude Code, Replit, and Windsurf. You describe what you want, and the agent writes the code.
But anyone who has tried to build beyond a simple prototype knows the feeling: things start to break.
Features regress. Integrations behave inconsistently. The AI loses track of context. That one small tweak somehow breaks three other parts of the app. You are no longer building. You are firefighting.
**The problem is not code generation. The problem is planning.**
A Product Management Agent is the missing layer in this new AI stack. It acts like a product manager, systems thinker, and senior engineer working together. It turns messy ideas into clear specifications, breaks large projects into smaller tasks, asks the right clarifying questions, and gives coding agents the direction they need to deliver reliable software.
It is the bridge between human intent and machine execution.
## Why AI Coding Breaks Down Without a Product Management Layer
Most AI coding tools behave like very fast junior developers. They are powerful and eager, but they need clarity. Without structure and direction, they make assumptions, lose context, and rewrite things they should not touch.
The symptoms look like this:
- A small change breaks features that used to work
- The AI starts creating duplicate files or reorganizing code in confusing ways
- Complex requirements get misunderstood or oversimplified
- Integrations and edge cases fall apart as the app grows
Professional engineering teams solve this with product managers, system design, specs, PRDs, RFCs, and review processes. Vibe coders usually do not have those tools or that experience. They have an idea, an AI coding assistant, and a lot of trial and error.
A Product Management Agent brings that missing discipline into the AI workflow.
## What a Product Management Agent Actually Does
A Product Management Agent handles the thinking work that happens before and around code. It takes a builder's idea and transforms it into inputs that AI coding agents can execute correctly.
At BrainGrid AI, we train our Product Management Agent in a set of core skills that mirror what strong product managers and senior engineers do in healthy teams.
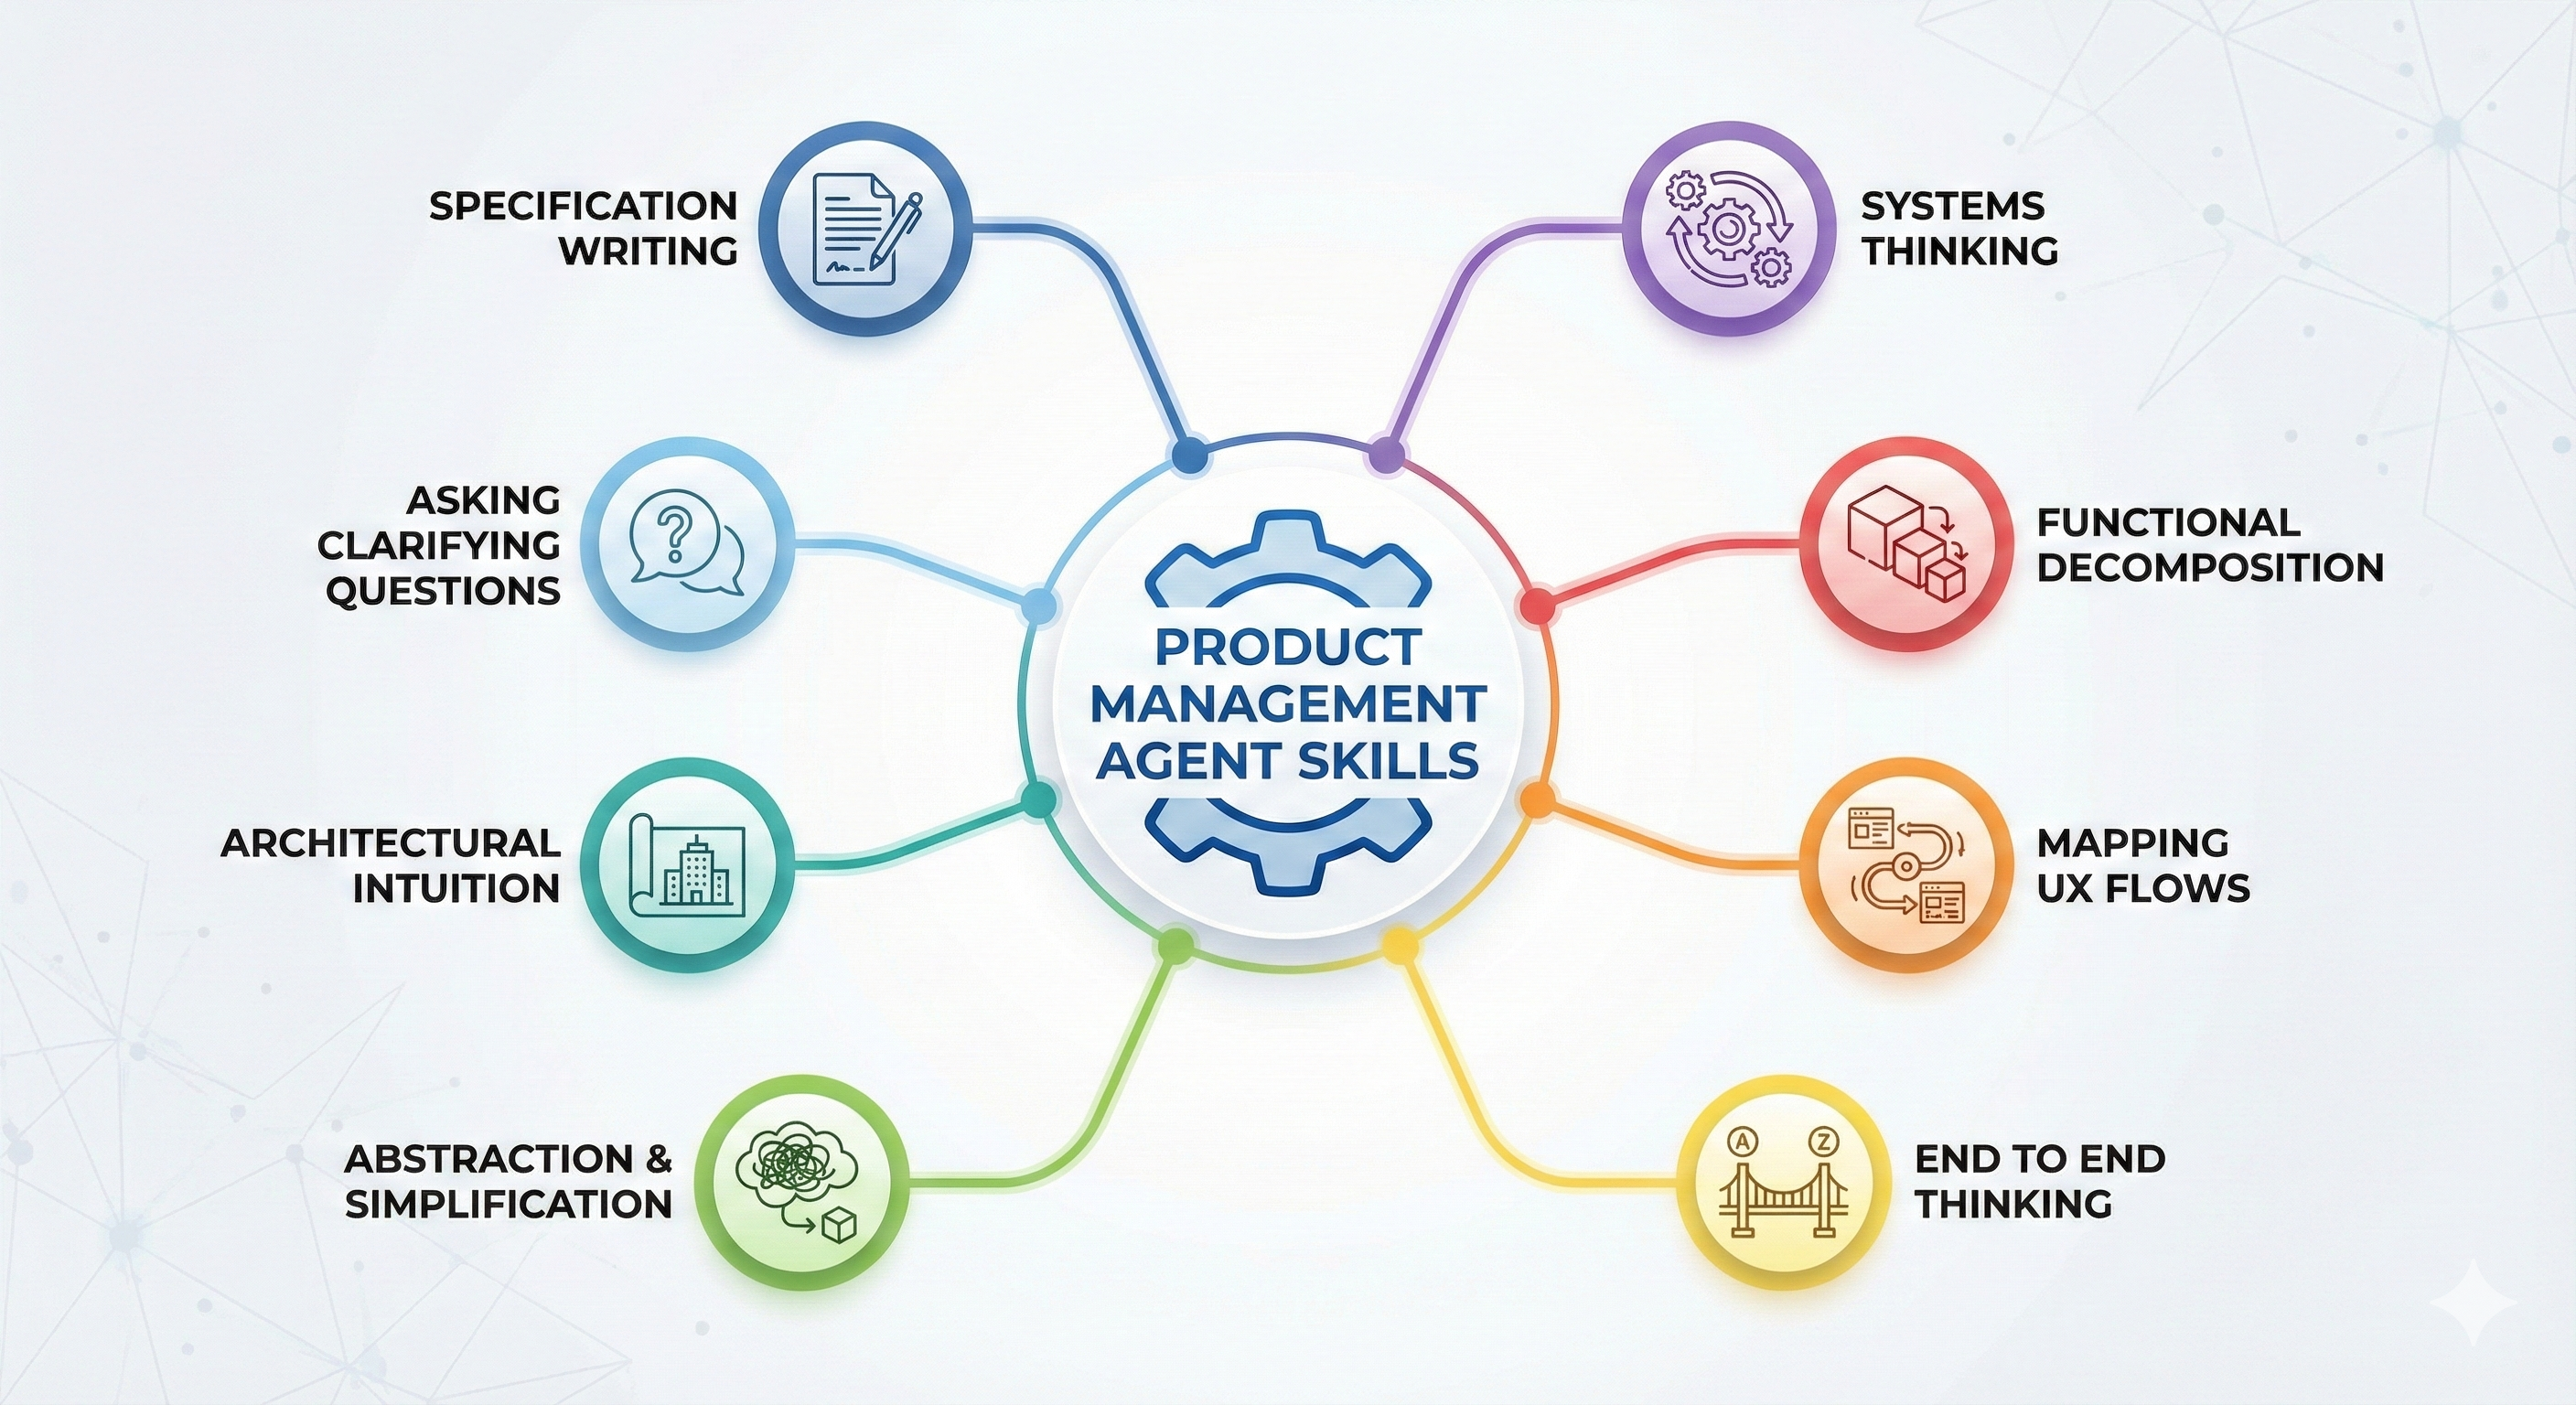
### 1. Systems thinking
The agent learns to see the product as a system, not a collection of isolated features. It considers data flows, ownership, side effects, and how new work fits into the existing architecture. A change to notifications should not silently break permissions or billing.
### 2. Functional decomposition
Large problems rarely get solved in a single request. The agent breaks big goals into logical, buildable pieces with clear goals and outcomes. This makes it easier for coding agents to stay on track and for builders to review the work step by step.
### 3. Mapping UX flows
Features are not only technical. They are experienced by users. A Product Management Agent maps user journeys, entry points, success paths, and failure paths so the implementation supports a complete workflow, not just a single screen or endpoint. It thinks about what happens before and after each interaction.
### 4. End-to-end thinking
A real feature touches more than one layer. It may affect APIs, UI, data models, permissions, validation, error handling, and analytics. The agent learns to think across the entire lifecycle of a feature so that nothing important is left out.
### 5. Abstraction and simplification
Great engineers hide complexity behind clean interfaces. The agent develops an instinct for when to introduce a new abstraction, when to reuse an existing one, and how to keep the mental model simple for the builder. The goal is power without unnecessary complexity.
### 6. Architectural intuition without over-architecting
There is a fine line between a solid foundation and over engineering. The agent learns patterns that help apps scale and stay maintainable, but avoids heavyweight solutions that slow down early teams. It aims for just enough architecture, with room to grow.
### 7. Asking clarifying questions
Most failures in AI coding come from unspoken assumptions. The builder says "add 2FA" and the system needs to know: which users, which flows, what UX, what edge cases, what happens on failure. A Product Management Agent learns to ask targeted clarifying questions at the right time so hidden requirements surface before code is written.
### 8. Specification writing
All of these skills come together in the ability to write clear, practical specs. A good specification includes goals, context, UX flows, constraints, edge cases, and acceptance criteria. Poor specs produce fragile software. Great specs produce reliable software that is easier to evolve.
---
These core skills enable effective task planning, sequencing, and review. Once the agent has a good specification, it can:
- Break it into well scoped tasks
- Create engineering grade prompts with the right context
- Define acceptance tests for each task
- Validate whether the output from the coding agent matches the intent
In other words, the Product Management Agent creates a stable path from idea to working code.
## Why This Matters for AI Builders
AI coding is powerful, but on its own it is still unpredictable. Builders often feel like they are rolling the dice every time they ask for a change in a complex app. A Product Management Agent gives them structure and repeatability.
This matters because:
- Features ship faster and with fewer surprises
- Less time is spent debugging regressions and strange side effects
- The codebase stays understandable and maintainable as it grows
- Non-technical founders can build like experienced teams
- AI coding tools become more of a reliable partner and less of a gamble
The Product Management Agent is not there to replace coding agents. It is there to guide them.
## Why We Built One at BrainGrid
At BrainGrid, we believe that AI coding tools are only half of the story. The other half is planning, structure, and product thinking. Without that half, non-technical founders get stuck in loops of rebuilds, half broken features, and abandoned projects.
So we built the Product Management Agent as the first layer of the BrainGrid platform.
BrainGrid turns ideas into specs, plans features, maps UX flows, asks clarifying questions, breaks work into tasks, and generates engineering grade prompts and acceptance criteria. Coding agents then use this structure to build features that are more likely to work the first time and keep working as the product evolves.
**Our goal is simple: Make AI coding reliable enough that anyone with a good idea can build a real product.**
---
# Design Systems for AI Coding: Stop Getting Purple Gradients
Source: https://www.braingrid.ai/blog/design-system-optimized-for-ai-coding
Published: 2025-12-08T16:00:00Z
Your AI coding assistant just generated another screen. Purple gradient header. Inter font. Rounded cards with subtle shadows. It looks exactly like every other AI-built product on the internet.
This isn't a Claude problem or a Cursor problem. It's a context problem. Without a design system, AI has nothing to work with except its training data — which is full of generic templates. Give it structured constraints, and suddenly it produces consistent, professional interfaces that don't scream "vibe coded."
This guide shows you how to build a design system that AI coding assistants actually understand — so you ship beautiful UI without becoming a designer.
## Why AI coding tools default to generic UI
Understanding the root cause saves you from fighting the same battle on every component.
AI models generate from training data when you don't provide constraints. And that training data is full of Bootstrap templates, generic SaaS landing pages, and the same purple-to-blue gradients you've seen a thousand times. When you ask for a dashboard without providing your design context, AI guesses. It guesses wrong.

Here's what's actually happening: AI needs context to generate useful code. Without tokens, primitives, or examples, it defaults to whatever patterns appear most frequently in its training set. That's why every AI-generated UI looks the same — rounded corners, subtle shadows, that omnipresent purple gradient.
The problem compounds with every prompt. When you don't provide constraints on the first component, AI invents spacing values and color choices. On the second component, it invents different values. By component five, your UI is a patchwork of inconsistent decisions that no amount of "make it look professional" can fix.
Design systems aren't overhead. They're the context AI needs to generate consistent code.
**The minimum context AI needs per prompt:**
1. Your color palette (as CSS variables or tokens file)
2. Your spacing scale (4px, 8px, 16px, etc.)
3. One example component using these constraints
Without these three things, you're asking AI to guess. It will guess wrong.
The common mistake? Letting AI invent spacing or gradients on first prompt. The symptom: every new component uses different values, creating visual chaos that's impossible to fix later without a full redesign.
Consistent UI builds trust. Users subconsciously notice when colors don't match or spacing is inconsistent — it feels "cheap" even if they can't articulate why. That perception directly affects whether they convert.
## The three-tier token architecture AI actually understands
Structured tokens give AI a vocabulary to work with instead of raw hex codes and pixel values scattered throughout the codebase.
The architecture is simple: three tiers that build on each other.
- Primitives hold raw values.
- Semantic tokens assign purpose.
- Component tokens handle specific contexts.
This hierarchy tells AI not just what values to use, but why.
**Tier 1: Primitives** are your raw values. Colors like `--gray-900: #1b1b1b`. Spacing like `--space-4: 16px`. These are the building blocks that never appear directly in components.
**Tier 2: Semantic tokens** assign meaning. `--color-text-primary: var(--gray-900)` tells AI this gray is for primary text. `--color-brand: var(--orange-500)` marks your brand color. When AI sees semantic names, it understands intent, not just values.
**Tier 3: Component tokens** handle specific contexts. `--button-primary-bg: var(--color-brand)` defines exactly what color a primary button background should use. These are optional — add them only when components need explicit guidance.
Here's the minimum viable structure:
```css
/* Tier 1: Primitives - raw values */
--gray-900: #1b1b1b;
--gray-100: #f5f5f5;
--orange-500: #EC681E;
/* Tier 2: Semantic - purpose-driven */
--color-text-primary: var(--gray-900);
--color-background: var(--gray-100);
--color-brand: var(--orange-500);
/* Tier 3: Component - specific contexts */
--button-primary-bg: var(--color-brand);
--button-primary-text: white;
```
When AI sees `--button-primary-bg`, it understands the purpose. When it sees `#EC681E`, it has to guess what that color means and where it should be used.
The pitfall here is over-engineering. Creating component-level tokens for every possible variant bloats the system before you need it. Start with primitives and semantic only. Add component tokens when you actually encounter confusion or inconsistency.
Structured tokens mean AI generates maintainable code. When you need to change your brand color from orange to blue, you update one token instead of find-replacing across 50 files. That's the difference between a 5-minute change and a weekend refactor.
### Organizing tokens by file for conceptual clarity
For larger projects, separate your TypeScript tokens into three files that mirror the abstraction hierarchy:
```bash
src/
├── app/
│ └── globals.css # Color primitives + semantic (CSS variables)
└── design-system/foundations/
├── primitives.ts # Non-color primitives (motion, spacing)
├── semantic.ts # Purpose-driven - imports primitives
├── components.ts # Pre-composed - imports primitives and semantic
└── index.ts # Barrel re-export
```
**primitives.ts** holds raw values that have no semantic meaning on their own:
```typescript
// Raw timing values - no semantic meaning yet
export const motionPrimitives = {
ease: [0.16, 1, 0.3, 1] as const,
duration: { instant: 0.2, short: 0.4, base: 0.6, long: 0.8 },
} as const;
// Raw spacing scale
export const spacingPrimitives = {
scale: [0, 4, 8, 12, 16, 24, 32, 48, 64] as const,
} as const;
```
**semantic.ts** imports primitives and assigns purpose:
```typescript
import { motionPrimitives } from './primitives';
// Re-export with semantic alias
export const motionTokens = motionPrimitives;
// Purpose-driven spacing
export const spacingTokens = {
section: { default: 'py-16 md:py-24', compact: 'py-12 md:py-20' },
stack: { lg: 'space-y-12', md: 'space-y-8' },
} as const;
export type SectionSpacing = keyof typeof spacingTokens.section;
```
**components.ts** composes from both layers:
```typescript
import { motionPrimitives, spacingPrimitives } from './primitives';
// Pre-composed component tokens
export const cardTokens = {
padding: spacingPrimitives.scale[4], // 16px
transition: {
duration: motionPrimitives.duration.base,
ease: motionPrimitives.ease,
},
} as const;
// Gradients as hardcoded strings (not theme-aware)
export const gradientTokens = {
'orange-purple': {
text: 'linear-gradient(92deg, rgba(246,203,165,0.95) 0%, rgba(196,175,236,0.88) 100%)',
},
} as const;
export type GradientToken = keyof typeof gradientTokens;
```
The barrel file re-exports everything, preserving a clean import path:
```typescript
// index.ts
export * from './primitives';
export * from './semantic';
export * from './components';
```
This structure helps AI in three ways:
1. **Clear abstraction boundaries**: AI knows primitives are raw values, semantic tokens have purpose, and component tokens are pre-composed
2. **Dependency direction is explicit**: Files only import from "lower" abstraction levels, preventing circular dependencies
3. **Scalability**: New tokens have an obvious home based on their abstraction level
### How globals.css and TypeScript tokens work together
You might wonder: if tokens live in TypeScript files, what's in globals.css? The answer: they're parallel systems handling different concerns.
**globals.css** handles **colors** via CSS custom properties. The browser manages `:root` and `.dark` switching — no JavaScript needed for theme changes.
**TypeScript tokens** handle **everything else**: motion timing, spacing classes, gradient strings, layout constraints. These need type safety and are consumed by JavaScript (Framer Motion) or as className strings.
```mermaid
flowchart LR
subgraph CSS["globals.css"]
CP["Color Primitives --gray-900, --orange-500"]
CS["Color Semantic --background, --primary"]
end
subgraph TS["TypeScript Tokens"]
MP["Motion Primitives ease, duration"]
SP["Spacing Primitives scale array"]
MT[motionTokens]
ST[spacingTokens]
GT[gradientTokens]
end
subgraph TW["Tailwind Config"]
TC["colors: hsl var --background"]
end
subgraph RC["React Component"]
CL["className= 'bg-background p-6'"]
TR["transition= motionTokens.duration"]
ST2["style= gradientTokens.text"]
end
CP --> CS
CS --> TC
TC --> CL
MP --> MT
SP --> ST
MT --> TR
SP --> GT
GT --> ST2
```
| Concern | Location | Consumed By |
|---------|----------|-------------|
| Colors | `globals.css` CSS variables | Tailwind via `hsl(var(--background))` |
| Motion | `motionTokens` in TypeScript | Framer Motion `transition` props |
| Spacing | `spacingTokens` in TypeScript | React `className` props |
| Gradients | `gradientTokens` in TypeScript | React `style` props |
The systems connect through **Tailwind's config**, which maps CSS variables to utility classes:
```typescript
// tailwind.config.ts bridges CSS variables → utility classes
colors: {
background: 'hsl(var(--background))', // CSS var → bg-background class
foreground: 'hsl(var(--foreground))', // CSS var → text-foreground class
}
```
In practice, a component might use both systems:
```tsx
import { motionTokens, gradientTokens } from '@/design-system';
className="bg-background text-foreground p-6"
// Gradient from TS
style={{ background: gradientTokens['orange-purple'].text }}
// Motion from TS
transition={{ duration: motionTokens.duration.base }}
/>
```
Why not put colors in TypeScript too? Because CSS variables enable theme switching without JavaScript. The browser swaps values when `.dark` is applied — your React components don't re-render.
### Integrating with shadcn/ui themes
shadcn/ui's theming uses the same CSS variable pattern. Your primitives become CSS variables, semantic tokens reference them, and the `.dark` class swaps values automatically.
```css
/* globals.css */
:root {
/* Primitives - raw HSL values (no hsl() wrapper) */
--gray-50: 0 0% 98%;
--gray-900: 0 0% 9%;
--orange-500: 24 95% 53%;
/* Semantic - light mode defaults */
--background: var(--gray-50);
--foreground: var(--gray-900);
--primary: var(--orange-500);
}
.dark {
/* Semantic - dark mode overrides (same names, different values) */
--background: var(--gray-900);
--foreground: var(--gray-50);
/* --primary stays the same */
}
```
The key insight: semantic tokens have the same names in both modes. When you use `bg-background` or `text-foreground`, the values swap automatically based on the `.dark` class.
Tailwind reads these variables in your config:
```typescript
// tailwind.config.ts
export default {
theme: {
extend: {
colors: {
background: 'hsl(var(--background))',
foreground: 'hsl(var(--foreground))',
primary: {
DEFAULT: 'hsl(var(--primary))',
foreground: 'hsl(var(--primary-foreground))',
},
},
},
},
}
```
Now AI can use `bg-background text-foreground` and get correct colors in both light and dark mode without knowing which mode is active. The three-tier system handles the complexity:
1. **Primitives** (`:root` raw values) define the palette
2. **Semantic** (`:root` and `.dark` overrides) assign purpose per mode
3. **Tailwind config** maps CSS variables to utility classes
AI never writes `bg-gray-900` for dark backgrounds. It writes `bg-background` — and the theme handles the rest.
### Light and dark mode AI understands
The shadcn/ui pattern makes theming trivial for AI. Instead of teaching AI two color systems (light palette + dark palette), you teach it one semantic system that works everywhere.
```tsx
// AI writes this once — works in both modes
Title
Description
```
No conditional logic. No `dark:` prefixes scattered through the code. The CSS variables handle mode switching at the root level.
When you need mode-specific styles (rare), Tailwind's `dark:` variant still works:
```tsx
// Only when truly necessary
```
The pitfall is over-using `dark:` prefixes. If you find yourself writing `dark:bg-gray-800` frequently, your semantic tokens are incomplete. Add a new semantic variable instead of sprinkling `dark:` throughout components.
For AI, this means simpler prompts. Instead of "use gray-100 in light mode and gray-900 in dark mode," you say "use bg-background." AI generates consistent code because the semantic layer abstracts away mode-specific decisions.
## Why Tailwind + shadcn/ui is the AI-optimized stack
Some stacks are dramatically easier for AI to work with than others. Tailwind plus shadcn/ui hits the sweet spot for AI code generation.
Here's why: shadcn/ui components are structured specifically for AI comprehension. Readable TypeScript. Consistent patterns across every component. And because you own the code — components copy directly into your project — AI has complete visibility into how everything works.
The CSS variable system makes theming automatic. Every shadcn component uses the same variables: `--primary` for brand colors, `--background` for page backgrounds, `--foreground` for text. Copy any component from anywhere, and if it follows shadcn patterns, it matches your theme automatically.
```typescript
// Every shadcn component uses the same variables
// Copy any component from any source — if it follows
// shadcn patterns, it matches your theme automatically
{/* Uses --card for bg, --card-foreground for text */}
```
AI trained on shadcn patterns generates components that "just work" with your theme because the variable system is predictable. It's not magic — it's consistency at scale.
Tailwind itself is AI-friendly because classes are self-documenting. When AI sees `p-4 bg-card border border-border`, it understands exactly what's happening. Compare that to CSS-in-JS where styles hide behind JavaScript abstractions. AI has to trace through function calls to understand what gets applied.
The pitfall? Using CSS-in-JS or styled-components with AI. These patterns obscure styling behind JavaScript, making it harder for AI to understand what classes to apply and where. If you're already using styled-components, you can still get good results, but Tailwind makes AI generation significantly more reliable.
Faster iteration is the payoff. When AI understands your component patterns, you prototype in minutes instead of hours. That speed compounds over every feature you build.
## Writing AI-facing documentation
AI reads your documentation as context. Poorly structured docs produce poorly structured code.
This isn't about comprehensive documentation. It's about documentation optimized for AI context windows. Short. Focused. Copy-pastable. AI doesn't need explanations — it needs examples and constraints.
Create a Skills file in your project that AI reads automatically. In Claude Code, that's `.claude/skills/design-system.md`. The file should be scannable, with clear sections and ready-to-use code snippets.
```markdown
## Design System Usage
## Colors
Use CSS variables, never raw hex codes:
- Primary brand: `text-brand` or `bg-brand`
- Text: `text-foreground` (primary), `text-muted-foreground` (secondary)
- Backgrounds: `bg-background` (page), `bg-card` (elevated surfaces)
## Spacing
Use Tailwind spacing scale only:
- Component padding: `p-4` (16px) or `p-6` (24px)
- Section gaps: `gap-8` (32px) or `gap-12` (48px)
- Never use arbitrary values like `p-[13px]`
## Example Component
\```tsx
Card Title
Card description using semantic color tokens.
\```
```
AI reads this file before generating code, ensuring it follows your conventions from the first prompt. The example component is critical — AI mirrors structure better than it interprets prose.
For your project's CLAUDE.md, add a quick reference that points to the skill:
```markdown
## Design System
For detailed usage, invoke the `design-system` skill.
### Token Files
- `globals.css` - Color primitives + semantic (CSS variables, `:root` and `.dark`)
- `primitives.ts` - Raw values (motion timing, spacing scale)
- `semantic.ts` - Purpose-driven tokens (imports primitives)
- `components.ts` - Pre-composed tokens (imports primitives and semantic)
### Usage
- Colors: Use Tailwind classes like `bg-background`, `text-foreground`
- Motion: Import `motionTokens` for Framer Motion transitions
- Gradients: Import `gradientTokens` for style props
```
This keeps CLAUDE.md concise while the skill file holds the detailed examples.
The pitfall is writing documentation for humans only. Long explanations of why you chose certain colors waste context tokens. AI doesn't need rationale. It needs clear constraints and working examples.
Documentation pays for itself on the second prompt. Consistent AI output means less time reviewing and fixing generated code.
## Automated guardrails that prevent design drift
AI generates fast but regresses faster. Without automated checks, your design system becomes suggestions instead of rules.
You need guardrails that catch violations before they hit production. These aren't optional — they're the only way to maintain quality at the speed AI generates code.
**Minimum guardrails for AI-generated code:**
```bash
## 1. Lint for arbitrary Tailwind values
## eslint-plugin-tailwindcss can flag non-standard classes
## 2. Run validation before every commit
yarn validate:fix
## 3. Add to your pre-commit hook
"pre-commit": "yarn lint && yarn type-check"
## 4. Visual regression tests (optional but valuable)
## Chromatic, Percy, or simple screenshot comparisons
```
ESLint can catch arbitrary values automatically:
```json
{
"rules": {
"tailwindcss/no-arbitrary-value": "warn"
}
}
```
This flags code like `text-[#ff0000]` or `p-[13px]` — the exact arbitrary values that AI loves to invent when it doesn't have proper constraints.
The mistake is relying on code review alone. Humans miss things, especially when reviewing AI-generated code at volume. You might catch the obvious color mismatch, but you'll miss the subtle spacing inconsistency that makes your UI feel off. Automated checks are faster and more consistent.
Quality stays high as you scale. The 10th feature looks as polished as the first because guardrails enforce consistency automatically, not manually.
## The prompt pattern that produces professional UI
How you prompt determines what you get. A structured prompt pattern makes every request more likely to succeed on the first try.
The key insight: AI needs three things to stay on-brand. Your tokens file (or at least the relevant section). Your Tailwind config snippet. And a visual reference — a screenshot or Figma export showing what you want.
Include all three, and AI produces consistent results. Skip any of them, and you're back to guessing.
**The AI design system prompt template:**
```markdown
## Context
- Design system tokens: [paste tokens.ts or link to file]
- Tailwind config: [paste relevant config section]
- Visual reference: [screenshot or Figma link]
## Task
Build a [component type] that:
- Uses only colors from our token palette
- Follows our spacing scale (4/8/16/24/32px)
- Matches the visual reference layout
## Constraints
- No arbitrary Tailwind values (no `text-[#hex]` or `p-[13px]`)
- Use semantic color tokens (`text-foreground`, not `text-gray-900`)
- Follow existing component patterns in /components/ui
## Output
Single file with the component. Include all necessary imports.
```
This pattern works because AI has everything it needs: constraints, examples, and clear success criteria. No guessing required.
The pitfall is prompting with just "make it look good" or "create a modern card component." Without constraints, AI reverts to training data defaults — those same purple gradients and rounded corners you've seen everywhere. Be specific about what "good" means in your design system.
Professional UI on first iteration means faster launches. You stop burning days on "make it match the design" back-and-forth because AI gets it right the first time.
## Ship professional UI, not AI slop
A design system optimized for AI coding isn't overhead. It's the difference between "vibe coded" and "professionally built."
Here's the setup checklist:
1. **Create three-tier tokens**: Primitives, semantic, and component-level — optionally in separate files for larger systems
2. **Use Tailwind + shadcn/ui**: The AI-optimized stack with predictable patterns
3. **Connect Figma via MCP**: If you have designs, make them machine-readable
4. **Write AI-facing docs**: Short Skills files with copy-pastable examples
5. **Add automated guardrails**: ESLint rules and pre-commit hooks that enforce tokens
6. **Use the prompt template**: Tokens + config + visual reference on every request
The investment is measured in hours. The payoff is every AI prompt that follows producing consistent, professional interfaces instead of generic templates.
Your users don't know if AI built your product. But they can tell if it looks cheap. A design system ensures it never does.
---
# Spec-Driven Development: Ship Reliable Software Faster with AI
Source: https://www.braingrid.ai/blog/spec-driven-development
Published: 2025-11-28T12:00:00Z
You know exactly what your users need—you've lived in their world. But every time you ask Claude or Cursor to build it, you get buggy code that misses the point. The problem isn't the AI. It's the input.
**[Spec-driven development](https://www.braingrid.ai/spec-driven-development) flips the script**: instead of learning to code, you learn to write clear instructions that make AI coding assistants finally work for you. Tools like [BrainGrid](https://www.braingrid.ai) have emerged specifically to help domain experts capture their knowledge as structured specs—turning vague ideas into AI-ready requirements without engineering expertise.
The founders who master this will ship their first paying feature while others are still debugging tutorial projects.
## Why Your AI Keeps Missing the Point
Here's a pattern you might recognize: You describe what you want. Claude generates a bunch of code. It looks right... but doesn't quite work. You refine your prompt. Try again. Three hours later, you're no closer to shipping.
The issue isn't weak AI models—it's that we've been treating them like search engines rather than careful partners. As GitHub's team puts it:
> "AI excels at pattern completion, but not at mind reading."
AI coding assistants are brilliant developers with amnesia. They need context every single session. When you rely on screenshots, Slack messages, or verbal explanations instead of canonical specs, the AI loses context after a few turns. The result? It starts guessing.
And when AI guesses, it invents things you never defined: copy, schemas, naming conventions, business rules. That's when bugs appear—not because the AI is broken, but because you never told it what you actually wanted.
**Compare these two approaches:**
❌ **Vague prompt**: "I need a login page with React"
✅ **Precise spec**: "Users must sign in with email to view their dashboard. Unauthenticated users are redirected to /login. Show error message 'Invalid email or password' on failed attempts. After 3 failed attempts, show 'Account locked. Try again in 15 minutes.'"
The second version eliminates guessing. The AI knows exactly what to build, including edge cases.
```mermaid
flowchart LR
subgraph VAGUE["❌ Vague Input"]
V1["I need a login page"]
end
subgraph GUESS["AI Guessing"]
G1["Invents copy"]
G2["Assumes schema"]
G3["Missing edge cases"]
end
subgraph BUGS["Bugs & Rework"]
B1["Doesn't match intent"]
end
V1 --> G1
V1 --> G2
V1 --> G3
G1 --> B1
G2 --> B1
G3 --> B1
subgraph PRECISE["✅ Precise Spec"]
P1["Users, triggers, outcomes, edge cases"]
end
subgraph UNDERSTAND["AI Understanding"]
U1["Clear requirements"]
U2["Defined behavior"]
U3["Known constraints"]
end
subgraph SHIP["Working Code"]
S1["Matches intent"]
end
P1 --> U1
P1 --> U2
P1 --> U3
U1 --> S1
U2 --> S1
U3 --> S1
```
*Vague prompts lead to AI guessing and bugs. Precise specs lead to working code.*
Every hour you spend debugging AI-generated code that missed the point is an hour not spent talking to potential customers. This is exactly why BrainGrid exists—it asks the clarifying questions upfront that prevent AI from guessing. Instead of hoping Claude understands your business logic, you capture it in a structured requirement that any AI coding assistant can execute accurately.
## The Domain Expert Advantage You're Not Using
Here's the uncomfortable truth most "learn to code" advice ignores: **you already have the hard skill**.
You know the "what" and the "why"—the problem users will pay to solve. Engineers only know the "how" (the syntax). As Sean Grove from OpenAI [recently noted](https://thenewstack.io/spec-driven-development-the-key-to-scalable-ai-agents/):
>"The person who communicates the best will be the most valuable programmer in the future."
Specifications, not prompts or code, are becoming the fundamental unit of programming.
Your domain expertise—understanding customer workflows, pain points, and what they'll pay for—is the scarce resource. Code is increasingly a commodity produced by AI. Your value is defining the specification that directs that commodity toward a paying problem.
Domain narratives written in plain language give AI better context than technical jargon ever could. When you describe real workflows from your industry, you're providing exactly the kind of rich context that makes AI assistants useful.
**Write specs as "user stories with teeth":**
1. **Who** is the user? (Role, context, goal)
2. **What** triggers the action? (Click, time, event)
3. **What should happen?** (Visible outcome)
4. **What data changes?** (Database, API, state)
Domain experts who write clear specs can delegate implementation to AI—or contractors—without losing intent. No engineering hire required.
BrainGrid was built for this exact persona: domain experts who know what to build but need help translating that knowledge into AI-ready instructions. The `/specify` command takes your rough idea ("I need user authentication with OAuth") and refines it into a structured requirement with acceptance criteria, edge cases, and success metrics. No engineering background required.
## The Four-Phase Spec-Driven Development Workflow
Ad-hoc prompting works for throwaway prototypes. But if you're building something users will pay for, you need a repeatable workflow that eliminates decision fatigue and builds shipping muscle.
The spec-driven development workflow follows four phases:
### Specify
Define the user journey, success metrics, and guardrails. Keep it to one page maximum. You're capturing intent, not writing a thesis.
### Plan
Let AI derive implementation steps from your spec. This is where architectural decisions get made—stack choices, integration points, constraints.
### Tasks
Break the plan into bounded, testable work units. Each task should be something you can implement and verify in isolation.
### Implement
Execute tasks one at a time, reviewing each before proceeding. This prevents the "massive code dump with hidden bugs" problem.
**Here's a starter spec template you can use immediately:**
```markdown
## Feature: [Name]
**Goal**: One sentence describing the outcome
**User**: Who does this, and why do they care?
**Trigger**: What action starts this flow?
**Happy Path**: Step-by-step what happens when everything works
**Edge Cases**: What could go wrong? How should we handle it?
**Success Metric**: How do we know this feature is working?
**Data**: What gets created, updated, or deleted?
```
The biggest pitfall? Asking AI for "complete implementation in one conversation." Symptom: massive code dumps with hidden bugs. Fix: Execute in bounded phases, 2-3 tasks at a time.
Each completed phase is a checkpoint where you can pause, test in development environment, or pivot—no sunk cost in abandoned code.
**BrainGrid's workflow maps directly to these four phases:**
1. **Specify** → `/specify "your idea"` generates a structured requirement with AI refinement
2. **Plan** → The requirement includes implementation guidance and acceptance criteria
3. **Tasks** → `/breakdown REQ-123` breaks your requirement into bounded, AI-ready tasks
4. **Implement** → `/build REQ-123` gives you the complete task list ready for Claude Code, Cursor, or any AI coding assistant
This isn't just theory—it's a [command-line workflow](https://docs.braingrid.ai) you can start using today.
## Iterate on Text, Not Code
Here's a principle that will save you weeks of frustration: **changing a paragraph of text takes 30 seconds; refactoring a codebase takes 3 hours.**
Get the logic right in English first. Then let AI translate to code.
As [Startup House notes](https://startup-house.com/blog/how-to-write-a-software-requirements-specification-srs-for-a-startup-mvp):
> "Preparing a specification document may seem like a waste of time at first, but it is a necessary step that will save you tons of time in the development phase."
**The 30-second edit test:**
1. Before coding any feature, describe it in 3-5 sentences
2. Read it aloud—does it make sense to someone unfamiliar with your product?
3. If not, rewrite until clear
4. Only then paste into your AI coding tool
After coding, ask your AI assistant: "Summarize how each change satisfies the spec bullets." This creates a verification loop that catches drift before it compounds.
The biggest pitfall here? Not updating specs after discovering new requirements during coding. Symptom: Contributors prompt against stale docs and recreate solved problems.
BrainGrid stores your requirements and tasks in a central system—not scattered markdown files. When you discover new requirements during coding, update the requirement in BrainGrid and it becomes the single source of truth. No more prompting against stale docs because the spec lives in one place that everyone (human and AI) references.
Faster iteration means more learning cycles before launch, which means better product-market fit when you do ship.
## What Your Spec Must Include (And What It Shouldn't)
Right-sizing specs prevents analysis paralysis while ensuring AI has enough context. The goal is "bare bones" that covers the critical path—not a comprehensive document that takes longer to write than the feature takes to build.
When using spec-driven development, over-verbose specs create a "tedious review burden." You end up reviewing documentation instead of shipping features.
**Include:**
- Goal and success metric
- Users and their context
- Data contracts (what gets created, updated, deleted)
- Guardrails and constraints
- Edge cases that matter
- Post-launch telemetry (how you'll know it's working)
**Exclude:**
- Detailed wireframes (use napkin sketches instead)
- Exhaustive test cases (generate these from specs later)
- Implementation details (let AI figure those out)
**The "Five W's + H" spec checklist:**
- **Who** uses this feature?
- **What** do they accomplish?
- **When** does this trigger?
- **Where** in the product does it live?
- **Why** does this matter to revenue?
- **How** do we know it's working? (success metric)
The pitfall to avoid: Overloading specs with wireframes creates "visual feedback loops" where you endlessly tweak UI instead of shipping logic.
Lean specs let you ship V1 fast, gather real user feedback, then enhance—instead of building features nobody wants.
BrainGrid's `/specify` command uses AI to ask the right questions—Goal, Users, Acceptance Criteria, Edge Cases—so you capture what matters without over-engineering. The output is structured for AI consumption: not a 50-page document, but a focused requirement that Claude Code or Cursor can execute in bounded tasks.
## Common Spec-Driven Development Mistakes (And How to Avoid Them)
Knowing failure modes in advance prevents discouragement and wasted cycles. Here are the mistakes that kill momentum:
### Mistake 1: Feature Creep
AI makes it easy to add cool features. "While we're at it, let's also add..." is the enemy of shipping. If it doesn't help users solve the core problem (and pay you), cut it.
### Mistake 2: "I'll Know It When I See It"
Building without a plan leads to visual feedback loops where you endlessly tweak UI instead of shipping logic. Fix: Wireframe on a napkin or use a simple drag-and-drop tool before asking AI to code.
### Mistake 3: No Success Metrics
Symptom: No one knows if V1 is "good enough" to launch—so you keep adding features instead. Fix: Define what "working" looks like before you write a single line of spec.
### Mistake 4: Letting AI Invent Conventions
When you don't define copy, schemas, or naming conventions, AI invents them—inconsistently. Fix: Capture these in your spec upfront, even if it feels tedious.
### Mistake 5: Ignoring Rollback Plans
No kill-switch means compliance sign-off takes forever and anxiety stays high. Fix: Define how you'll revert if something breaks.
**Pre-flight checklist before every AI coding session:**
- [ ] Is this feature in my spec?
- [ ] Does it help users solve the core problem?
- [ ] Do I have a success metric defined?
- [ ] Can I test this without the rest of the system?
Every unplanned feature delays your launch date. Discipline to cut equals faster time to first revenue.
**BrainGrid prevents these mistakes by design:**
- **Feature creep** → Requirements have defined scope; tasks are bounded and trackable
- **No success metrics** → The `/specify` flow prompts for acceptance criteria before generating tasks
- **AI inventing conventions** → Your requirements capture naming, tone, and data contracts upfront
- **Stale docs** → Central requirement storage means one source of truth, not scattered files
The structure enforces discipline so you don't have to rely on willpower alone.
## Your New Role: Chief Spec Officer
The mindset shift that makes spec-driven development stick: **you're not learning to code—you're learning to lead AI**.
Your role shifts from "tinkering with code" to "shipping products." The spec is your source of truth; the code is just the implementation detail.
As [The New Stack](https://thenewstack.io/spec-driven-development-the-key-to-scalable-ai-agents/) puts it:
>"The future of software engineering won't be about typing faster—it will be about thinking more clearly."
Human judgment remains essential at every phase:
- Does the spec capture what you actually want to build?
- Does the plan account for real-world constraints?
- Are there omissions or edge cases the AI missed?
The process builds in explicit checkpoints for you to critique what's been generated. The AI generates the artifacts; you ensure they're right.
**Weekly spec-driven cadence:**
1. **Monday**: Review last week's shipped features against specs—did they hit success metrics?
2. **Tuesday-Thursday**: Specify → Plan → Task → Implement cycle for this week's priority
3. **Friday**: Update specs with learnings, archive completed features, prioritize next week
The pitfall: Going back to "vibe coding" when under pressure. Symptom: Spending a weekend debugging AI output that drifted from intent.
Spec-driven founders ship consistently. Consistent shipping builds user trust. User trust converts to revenue.
**BrainGrid is your command center for spec-driven development.** Here's the complete workflow:
```bash
## Turn vague idea into structured requirement
braingrid specify --prompt "Add OAuth login with Google and GitHub"
## → Creates REQ-123 with acceptance criteria, edge cases, success metrics
## Break requirement into AI-ready tasks
braingrid breakdown REQ-123
## → Generates 5-8 bounded tasks with implementation guidance
## Get the full build plan for your AI coding assistant
braingrid build REQ-123 --format markdown
## → Ready to paste into Claude Code, Cursor, or Windsurf
## Track progress as you ship
braingrid task update TASK-456 --status COMPLETED
```
This is what "Chief Spec Officer" looks like in practice: you define intent, BrainGrid structures it, AI implements it, you verify and ship.
---
## Start Shipping
Spec-driven development isn't about adding process for its own sake. It's about removing the friction between your expertise and working software.
You already know the problem worth solving. You already understand your users. The only thing missing was a systematic way to translate that knowledge into instructions AI can execute reliably.
Now you have one.
**Ready to become a Chief Spec Officer?** [BrainGrid](https://www.braingrid.ai) gives you the spec-driven workflow in one tool—from vague idea to shipped feature. Start with `braingrid specify --prompt "your next feature"` and see how fast you can go from concept to code.
Stop debugging AI output that missed the point. Start shipping features that match your intent.
---
# Understanding .env and .env.local Files
Source: https://www.braingrid.ai/blog/env-local-vs-env
Published: 2025-11-24T10:00:00Z
When building applications, especially web applications, you often need to manage configuration settings that vary between development, testing, and production environments. Things like API keys, database connection strings, and other sensitive information should never be hardcoded or committed directly into your Git repository. This is where `.env` files come in.
### What are `.env` files?
`.env` files (short for "environment") are simple text files that contain key-value pairs representing environment variables. They are typically used to store configuration specific to the environment where your application is running.
For example:
```bash
## .env - Shared environment variables
## (NEVER commit this with actual secrets)
NEXT_PUBLIC_API_URL=https://api.your-app.com
DATABASE_URL=postgresql://user:password@localhost:5432/mydb
```
Crucially, `.env` files containing actual secrets should **always** be added to your `.gitignore` to prevent them from being accidentally committed to version control. A common practice is to commit a `.env.example` file, which serves as a template showing which environment variables are required without exposing their values.
```bash
## .env.example - Commit this template to Git
NEXT_PUBLIC_API_URL=
DATABASE_URL=
```
### The Role of `.env.local`
Many modern frameworks and build tools, such as Next.js, support a convention where `.env.local` files are used for **local overrides** or **personal environment configurations**.
Here's the key difference:
* **`.env`**: Contains default environment variables that might be shared across different development machines or non-production environments (if you choose to commit it without sensitive data, or for production builds on a server).
* **`.env.local`**: Contains environment variables that are specific to your *local development environment*. These values will override any corresponding values found in `.env` or other `.env` files (e.g., `.env.development`, `.env.production`).
This hierarchy is extremely useful:
1. A shared `.env` file can provide general settings or defaults.
2. Your personal `.env.local` file can then override these defaults with values specific to your machine, such as your local database credentials or API keys for personal testing.
Example:
Suppose your `.env` file has:
```bash
## .env
API_KEY=default_shared_key
```
And your `.env.local` file has:
```bash
## .env.local
API_KEY=my_personal_dev_key
```
When your application runs locally, it will use `API_KEY=my_personal_dev_key`.
Just like `.env` files containing secrets, **`.env.local` should almost always be in your `.gitignore`** because it contains sensitive, local-specific information that should not be shared or version-controlled.
### ⚡ 5-Minute Setup: Get Secure Now
### Create .env
In your project root, add your API keys and database URLs.
### Add to .gitignore
Immediately add both `.env` and `.env.local` to your `.gitignore` file.
### Create .env.example
Copy `.env` and replace values with placeholders.
### Create .env.local (optional)
Add personal dev overrides that won't affect other developers.
### Test it
Restart your dev server and verify variables load correctly.
That's it. Your secrets are secure and your team can onboard faster.
### Best Practices
* **Use `.gitignore`**: Always add `.env` and `.env.local` (and any other `.env.*` files containing secrets) to your `.gitignore`.
* **Provide `.env.example`**: Create a `.env.example` file that lists all required environment variables with placeholder values. This helps new developers set up their local environment quickly.
* **Local Overrides**: Leverage `.env.local` for personal, local-only configurations that shouldn't affect other developers or deployed environments.
* **Consistency**: Be consistent with your naming conventions and how you load environment variables in your application.
By understanding and correctly utilizing `.env` and `.env.local` files, you can maintain a clean, secure, and flexible configuration strategy for your projects.
---
# Git for Vibe Coders: How to Not Lose Your AI-Generated Code
Source: https://www.braingrid.ai/blog/git-version-control-for-ai-builders
Published: 2025-11-16T22:30:00Z
You spent three weeks building an app in your favorite AI coding tool. It worked. You then started working on a new feature. You built it, made changes, saved… and discovered your new feature is broken and the original app is ruined too.
This isn't a bug with your AI coding tool. This is what happens when you ship AI-generated code without version control. The good news? You can protect yourself in 15 minutes.
This guide shows you the exact Git workflow that prevents lost work and enables fast iteration—no matter which AI builder you use.
## Why Git Matters When AI Writes Your Code
You're racing to revenue, not learning Git workflows. But here's the truth: losing work is slower than learning the basics.
When AI generates 90% of your code, Git becomes your production ledger. Every commit is a restore point. Every branch is a safe experiment space.
One developer put it perfectly after exporting from Lovable without Git:
> "I have no version history, no way to test things separately. It's a house of cards and I'm scared to touch anything."
Think of Git as your undo button for entire features. When an AI prompt goes wrong (and it will), you rewind in seconds instead of rebuilding for hours.
**First step**: The second you export from Lovable, Base44, or Bolt, open your terminal (Terminal on Mac, Command Prompt or PowerShell on Windows) and navigate to your project folder. Then run:
```bash label="Terminal"
git init
git add .
git commit -m "Initial export from [platform]"
```
Then create a private GitHub repo and push:
```bash label="Terminal"
gh repo create my-app --private
git remote add origin https://github.com/you/my-app.git
git push -u origin main
```
Takes 2 minutes. Saves days of recovery work later.
You can also prompt Cursor or Claude to create a GitHub repo for you:
```prompt label="Cursor / Claude Code"
Initialize the repo
set remote to https://github.com/you/my-app.git
do an initial commit and push
```
## The Three Mistakes That Erase Hours of Work
These happen in week one, before you realize you need the ability to rollback safely.
### Mistake 1: Working Directly on Main
You've exported code from your AI coding tool and started working on a new feature. Something breaks. Now you're debugging instead of shipping. This is what happens when you ship AI-generated code without version control.
**The fix**: Never work on `main`. Use feature branches for every change.
```bash label="Terminal"
## Before every AI coding session
git checkout -b feature/add-user-login
## Make changes, test locally
git add .
git commit -m "User login working"
```
You can also prompt Cursor or Claude to create a feature branch for you:
```prompt label="Cursor / Claude Code"
Create a feature branch for the user login feature
```
Then, if it works, merge it to main:
```bash label="Terminal"
## If it works, merge it
git checkout main
git merge feature/add-user-login
```
You can also prompt Cursor or Claude to merge the feature branch to main for you:
```prompt label="Cursor / Claude Code"
Merge the feature branch for the user login feature to main
```
If AI broke it, delete the branch and start over:
```bash label="Terminal"
## If AI broke it, delete the branch and start over
git checkout main
git branch -D feature/add-user-login
```
You can also prompt Cursor or Claude to delete the feature branch for you:
```prompt label="Cursor / Claude Code"
Delete the feature branch for the user login feature
```
Your production code stays safe. AI experiments stay isolated.
### Mistake 2: Keeping Secrets Only in Your AI Coding Tool's Environment Settings
You store API keys in your AI coding tool's environment settings. If you want to move off the tool like Lovable, Replit, or Base44 to manage your own code with GitHub and run it locally, you're stuck. Nothing works.
**The fix**: Keep a `.env.example` file in Git (without actual secrets):
```bash
## .env.example - commit this
STRIPE_PUBLIC_KEY=pk_test_...
OPENAI_API_KEY=sk-...
DATABASE_URL=postgresql://...
```
The `.env.example` is helpful to document what secrets are needed to run your app.
**Fix 2**: Keep a `.env` file with the actual secrets so your app runs locally. Add it to your `.gitignore` file so it's not committed to Git.
```bash Terminal
## .env - NEVER commit this (add to .gitignore)
STRIPE_PUBLIC_KEY=pk_test_abc123real
OPENAI_API_KEY=sk-xyz789real
DATABASE_URL=postgresql://user:pass@localhost/db
```
Now you have a template. When disaster strikes, you know exactly which secrets to re-create.
#### What is the `.env` file?
The `.env` file is a file that contains environment variables for your app. It's a way to store sensitive data like API keys and secrets so they're not committed to Git.
#### What is the difference between a `.env.local` and a `.env` file?
For a detailed explanation on the differences and best practices, refer to our dedicated post: [Understanding .env and .env.local Files](/blog/env-local-vs-env).
#### What is the .gitignore file?
The `.gitignore` file is a list of files and directories that Git should ignore. It's a way to prevent sensitive data from being committed to Git.
### Mistake 3: Downloading Projects Without Git
Some people download their Lovable, Replit, or Base44 projects from the UI. Then edit the code directly.
**The fix**: Always connect to GitHub, then clone the repo locally.
```bash label="Terminal"
## Clone your project
git clone https://github.com/you/project.git project-copy
```
*BrainGrid's GitHub integration tracks requirements across branches—so can keep track what each branch is doing.*
## The Ideal Git Workflow for AI Builders
Here's the branching strategy that keeps your code safe while moving fast.
### Branch Structure
```mermaid
gitGraph
commit id: "Initial commit"
branch dev
checkout dev
commit id: "Setup dev"
branch feature/login
checkout feature/login
commit id: "Add login UI"
commit id: "Connect auth"
checkout dev
merge feature/login
branch feature/dashboard
checkout feature/dashboard
commit id: "Dashboard layout"
checkout dev
merge feature/dashboard
checkout main
merge dev tag: "v1.0.0"
```
**Two main branches**:
- `main` - Production code that's live or ready to ship
- `dev` - Integration branch for features being built
**Feature branches**: One per feature, created from `dev`
### Daily Workflow
**Morning**: Start fresh from dev
```bash label="Terminal"
git checkout dev
git pull origin dev
git checkout -b feature/user-profile
```
**During work**: Commit every time something works
```bash label="Terminal"
## Test your change, it works!
git add .
git commit -m "User profile page displaying correctly"
```
**End of day**: Push your feature branch
```bash label="Terminal"
git push origin feature/user-profile
```
**When feature is done**: Create PR to dev
```bash label="Cursor / Claude Code"
Create a Pull Request from the feature/user-profile
branch to the dev branch
```
**When dev has multiple features ready**: Merge to main
```bash
## On GitHub, create Pull Request: dev → main
## Review all changes, merge PR
## Tag the release
git checkout main
git pull origin main
git tag -a v1.0.0 -m "First production release"
git push origin v1.0.0
```
Claude Code / Cursor prompt:
```prompt label="Cursor / Claude Code"
Create a Pull Request from the dev branch to the main branch
```
### Pull Request Process
```mermaid
graph LR
A[Feature Branch] -->|Pull Request| B[dev branch]
B -->|Accumulate features| B
B -->|Pull Request when ready| C[main branch]
C -->|Tag and Push to GitHub| D[v1.0.0]
```
**Feature → dev Pull Request**: Review individual changes, merge quickly
**dev → main Pull Request**: Review entire release, test thoroughly, then merge and tag
This gives you:
- Safe experiments on feature branches
- Integration testing on dev
- Clean, tagged production releases on main
### Branch Naming Best Practices
Use descriptive names that explain what you're building:
```bash label="Terminal"
## ✅ Good
feature/stripe-checkout
feature/email-notifications
fix/dashboard-loading
hotfix/payment-webhook
## ❌ Bad
feature/new-stuff
fix/bug
my-branch
```
Pattern: `type/short-description`
**Types**:
- `feature/` - New functionality
- `fix/` - Bug fixes
- `hotfix/` - Urgent production fixes
- `refactor/` - Code cleanup without behavior change
## Daily Habits That Prevent Disasters
These take 30 seconds but save hours of recovery work.
### Morning Routine
```bash label="Terminal"
## Sync latest changes
git checkout dev
git pull origin dev
## Create today's feature branch
git checkout -b feature/todays-work
```
### After Every Working Feature
```bash label="Terminal"
## It works! Lock it in.
git add .
git commit -m "Feature X working: [brief description]"
```
Don't wait until the feature is "perfect." Commit when it works, even if it's ugly.
### Before AI Prompts That Regenerate Code
```bash label="Terminal"
## Safety commit before letting AI regenerate
git add .
git commit -m "Before AI regeneration - working state"
```
Now if the AI breaks everything, you're one command away from safety:
```bash label="Terminal"
git reset --hard HEAD
```
### End of Day
```bash label="Terminal"
## Cloud backup - never lose work
git push origin feature/todays-work
```
Even if your laptop dies, your work is safe on GitHub.
**The payoff**: With these habits, you can ship several features per week to beta users instead of getting stuck trying to fix one feature that's broken, accelerating the feedback loops that inform your product roadmap.
*BrainGrid's task system reminds you to commit after completing each task—turning version control into a built-in habit instead of something you remember after disaster strikes.*
## When Disaster Strikes: Recovery Playbook
Even with perfect habits, AI builders sometimes create chaos.
### Scenario 1: AI Broke Everything (But You Committed)
Find your last working commit:
```bash label="Terminal"
git log --oneline
## Shows: abc1234 Feature X working
## def5678 Before AI regeneration
## ghi9012 Login flow complete
git reset --hard def5678
```
You're back to the working state. The AI's chaos is gone.
**Important**: Only use `--force` when pushing to feature branches, never to main:
```bash label="Terminal"
git push origin feature/broken-thing --force
```
### Scenario 2: Accidentally Committed Secrets
Undo the last commit, keep your changes:
```bash label="Terminal"
git reset --soft HEAD~1
## Remove secrets from files, add to .gitignore
echo "API_KEY=sk-real-secret" >> .env
echo ".env" >> .gitignore
## Commit again without secrets
git add .
git commit -m "Fixed: removed secrets from commit"
```
### Scenario 3: Total Catastrophe (No Recent Commits)
Use the AI builder's version history:
**Base44**: Click clock icon → restore last working version → export immediately → commit
**Lovable**: Check GitHub commits (if auto-sync enabled) → revert to working commit
**No Git, no builder history**: You're rebuilding from memory. Don't let this be you.
### The Nuclear Option
If everything is broken and Git history is tangled:
```bash label="Terminal"
## Clone a fresh copy from last known good point
git clone https://github.com/you/project.git project-recovery
cd project-recovery
git checkout
## Copy your .env file back
cp ../old-project/.env .
## Start fresh branch from here
git checkout -b feature/rebuild
```
**Recovery speed matters**: 10 minutes of downtime vs. 10 hours determines whether you keep customer trust and revenue momentum.
## Quick Reference: Essential Git Commands
### Setup & Daily Use
```bash label="Terminal"
## Start new feature
git checkout dev
git pull origin dev
git checkout -b feature/my-feature
## Save progress
git add .
git commit -m "Description of what works"
git push origin feature/my-feature
## Merge feature to dev (via PR on GitHub)
## Then locally:
git checkout dev
git pull origin dev
```
### When Things Break
```bash label="Terminal"
## See what changed
git status
git diff
## Undo changes (not committed yet)
git checkout -- filename.ts
## Undo last commit (keep changes)
git reset --soft HEAD~1
## Undo last commit (discard changes)
git reset --hard HEAD~1
## Go back to any commit
git log --oneline
git reset --hard
```
### Branch Management
```bash label="Terminal"
## List branches
git branch -a
## Delete local branch
git branch -D feature/old-thing
## Delete remote branch
git push origin --delete feature/old-thing
## Rename current branch
git branch -m new-name
```
## Start Protecting Your Work Today
Here's your 15-minute setup:
1. **Initialize Git** in your exported project
2. **Create GitHub repo** and push
3. **Create `dev` branch** from `main`
4. **Make a `.gitignore`** file (add `.env`, `node_modules`, `.next`)
5. **Commit daily** - make it a habit
The first time you need to rollback a broken AI generation, you'll be glad you did.
Version control isn't about "adding complexity." It's about protecting the hours you invested and shipping faster to paying customers.
---
# Builder Story: Kaleen Canevari
Source: https://www.braingrid.ai/blog/builder-story-kaleen-canevari-motra-studio
Published: 2025-11-13T14:30:00Z
>"I have a lot more confidence that I'm building thoughtfully and sequentially."
- Kaleen Canevari
## Background: The Pilates Founder
### From Engineer to Pilates Tech Founder
Kaleen Canevari is a two-time founder and mechanical engineer with deep expertise in the Pilates industry. Though not a professional coder, she embraces the "vibe coding" movement, using AI-powered tools to build applications that solve real-world problems. As a certified Pilates instructor, Kaleen operates at the intersection of fitness, wellness, and technology.
### A New Way of Building
Kaleen describes herself as a "vibe coder." She doesn't focus on the nuances of syntax but excels at outlining a vision and using AI tools to translate it into functional code. She has experience with no-code/low-code platforms, integrating backend services like Supabase, and using version control with Git.
### Identifying a Gap in the Market
Kaleen is developing a software platform to address the needs of Pilates studio owners who are unhappy with the current options for hosting and monetizing their online content. One of her initial design partners, a studio owner with a large Instagram following, was specifically looking for a better way to monetize her content for a non-local audience.
## Vision: A Platform for Modern Studios
### The Product: An AI-Powered Hub for Instructors
Kaleen is building a multi-tenant AI SaaS platform where Pilates studio owners can host their own video content and manage client subscriptions. It provides a dedicated, seamless portal for Pilates instructors to build and manage their own online content business. It solves the problem of studios having to manually manage payments and use generic video platforms like Vimeo, offering a more professional and integrated solution for both studio owners and their students.
The Motra Studio SaaS Platform
Visit [www.motrastudio.com](https://www.motrastudio.com).
### The Goal: Scaling a Viable Business
The application includes a complex payment system using Stripe Connect, which allows studio owners to receive payments directly from their students while also paying a platform fee. The long-term vision is to become a growing business, and help Pilates pros earn more money without working more hours.
## The Turning Point: Choosing BrainGrid
### The Challenge: When AI Coders Hit a Wall
Before using BrainGrid, Kaleen's process was less structured. While building a feature to analyze class transcripts with an LLM, she broke the application and couldn't fix it, even after multiple attempts with her existing AI tools. She struggled with the AI losing context or not fully understanding her requirements and noted that integrating third-party services like the OpenAI API was a significant hurdle.
### The Solution: An "AI Tech Lead" to Guide the Build
Kaleen turned to BrainGrid to bring more structure and confidence to her building process. The platform has transformed her workflow by acting as an "AI tech lead." She uses it to meticulously plan new features, leveraging its ability to ask clarifying questions to consider aspects of the product she might have otherwise missed. She calls the quality of the product requirements it generates "fantastic," requiring very few edits.
Kaleen's BrainGrid Backlog
A key success story was rebuilding the broken transcript-analysis feature. She recounted:
>“I spent a couple of days — which in vibe coder time felt like eons — spinning in circles trying to integrate this transcript-analysis feature. I tried rebuilding it twice without BrainGrid, and every time something broke. Finally, I decided to start fresh with BrainGrid. I had it rebuild the whole thing from scratch, and it just worked. Right away. It was such a relief.”
Kaleen's BrainGrid Requirement to parse class transcripts using LLMs
## Outcomes: Building with Confidence and Speed
### New Capabilities: From Guesswork to Guardrails
With BrainGrid, Kaleen can confidently tackle and successfully build complex features that she previously struggled with. She is learning the value of a structured software development lifecycle. BrainGrid provides the guardrails and best practices—like detailed requirements and sequential task breakdowns—that she, as a non-traditional coder, didn't know she needed. It's teaching her "how to vibe like a pro" by instilling a more rigorous planning process.
### Tangible Results: From Broken Features to Paying Customers
The most significant result is a tangible increase in building success. Since adopting BrainGrid, Kaleen has:
* Successfully implemented a complex feature to parse class transcripts using an LLM.
* Integrated Stripe Connect to handle multi-party payments.
* Deployed her application to Vercel.
* Onboarded her first paying studio owner.
Features that were previously broken are now working flawlessly, and the quality of her initial planning is much higher.
As Kaleen puts it, using BrainGrid:
>"gives me a lot more confidence that I'm building thoughtfully and sequentially."
Check out Motra Studio at [www.motrastudio.com](https://www.motrastudio.com).
---
# How to Export Your Lovable Project and Accelerate Development
Source: https://www.braingrid.ai/blog/how-to-download-lovable-project
Published: 2025-10-29T21:35:00Z
You've created something tangible with Lovable, and perhaps you've already demoed it to your first beta users. But now you're encountering limitations, waiting on Lovable's roadmap for a feature you need today, or realizing that hosting flexibility is crucial for your pricing model.
The good news is you don't have to start from scratch. Lovable can export clean, production-ready code that you can own, deploy anywhere, and enhance with an AI coding agent.
This guide provides a walkthrough of the 15-minute export process, highlights three post-export issues that challenge many developers, and explains how to integrate tools like Cursor or Claude Code to ship your next ten features faster than you shipped your first ten in Lovable.
### Know Before You Go: What You're Actually Downloading
You're exporting because your beta users are requesting features that Lovable can't deliver or that cause issues when you try to implement them. You want to maintain momentum without a complete rewrite. Understanding the contents of your download can prevent confusion if something doesn't work as expected.
When you export from Lovable, you receive a Vite-based React application with your UI, components, and client-side logic intact. This is a significant advantage. Your carefully designed user flows, the design you spent weeks iterating on, and all your polished interactions are preserved.
However, some of Lovable's most powerful features, such as authentication, Stripe integration, and AI orchestration, rely on their managed services and do not export as standalone code.
This is an intentional design choice that keeps the Lovable platform agile. It does mean you need to document these integrations *before* you export. It is recommended that you take screenshots of your "Settings → Integrations" page and make a note of the third-party services that power your login, payments, and AI features, including any API keys, callback URLs, and webhook endpoints.
**Common Mistake:** Assuming the backend will be exported automatically.
**The Fix:** Before exporting, create a migration checklist detailing every external service and its configuration.
Your export bundle also includes your Supabase/Postgres database schemas, located in `supabase/migrations`. This allows you to quickly spin up a new database instance and migrate your data structure.
A critical piece that requires manual work is setting up your environment variables. **For security reasons, Lovable does not include your API keys or secrets in the export.** You will need to manually configure these after downloading the project to connect it to services like Supabase and Stripe. We'll cover exactly how to do this in the "Post-Export Gotchas" section.
### Choose Your Export Method (GitHub vs. Manual Download)
Now that you know what to expect in your download, let's discuss how to get it. Lovable offers two primary methods for exporting your code: a direct GitHub integration and a manual download (e.g., as a ZIP file). The right choice can mean the difference between coding in 15 minutes and spending days on cleanup.
**GitHub integration is the recommended path.** It's an official feature that syncs automatically and enables one-click deploys to Vercel or Netlify. Once connected, every save in Lovable is pushed to your GitHub repository, eliminating the need for manual downloads and reducing the risk of lost changes. A repository is also a prerequisite for collaborating with other developers or an AI coding agent.
The manual download option provides an instant ZIP file of your project. This method is straightforward and doesn't require a GitHub account. It's a great option for quick backups. However, you lose the benefits of auto-sync and version history unless you manually initialize a Git repository later.
**Here's a simple decision framework:**
* **Already using GitHub?** Use the GitHub integration.
* **Need the code immediately without any setup?** Use the manual download and migrate to Git when you have time.
**Common Mistake:** Using the manual download for rapid development and realizing weeks later that there is no version history when an AI agent introduces a breaking change.
**The Fix:** If you choose the ZIP route, run these commands immediately after unzipping the file:
```bash
git init
git add .
git commit -m "Initial export from Lovable"
```
This will establish local version control. You can push it to a remote repository on GitHub later.
### Step-by-Step: Export Your Lovable Project to GitHub in 5 Minutes
You've chosen the GitHub integration—a smart move. Here are the exact steps to get your code from Lovable to a new GitHub repository without encountering authorization errors or sync failures.
A key point to remember is that Lovable will create the repository for you. Do not create one on GitHub beforehand, as this can cause conflicts.
Here is the process:
1. **Open your Lovable project** and go to the editor view.
2. **Locate the GitHub icon** in the top-right corner of the workspace and click it.
3. Click **"Connect to GitHub."** This will open a GitHub permission pop-up.
4. **Authorize Lovable** in the pop-up window. You will grant it permission to create repositories and push code.
5. Back in Lovable, **confirm the repository settings.** Lovable will auto-generate a repository name, which you can change. Choose whether the repository should be private or public.
6. Click **"Create Repository."** Lovable will now create the repository and push your entire codebase, which typically takes 30–60 seconds.
7. **Wait for the confirmation,** usually a green checkmark, indicating the process is complete.
8. Click **"View on GitHub"** to verify that all your files have been successfully pushed.
9. **Copy the repository URL** from GitHub by clicking the "Code" button and copying the HTTPS or SSH URL.
10. **Clone the repository locally** by opening your terminal and running:
```bash
git clone [your-repository-url]
cd [your-project-name]
```
You now have a local copy of the code, ready to run, modify, or deploy. Auto-sync is enabled by default, meaning every save in Lovable will trigger a commit and push to GitHub. This synchronization is bi-directional.
**Common Mistake:** Creating a repository on GitHub first and then trying to connect it in Lovable, which can lead to merge conflicts.
**The Fix:** Always initiate the process from Lovable's interface. If you have already created a repository on GitHub, delete it before connecting from Lovable.
### The 3 Post-Export Gotchas That Affect 80% of Projects
Your code is on GitHub and you've cloned it locally. You run `npm run dev`, but the application fails to start, throwing errors about missing environment variables or database connection failures. This is a common experience, but these three "gotchas" can be resolved in under 10 minutes each.
#### Gotcha #1: Missing Environment Variables
This is the most common reason a freshly exported project fails to run. Lovable doesn't export your API keys or secrets for security reasons, so your local application doesn't know how to connect to your database or payment provider.
* **The Fix:** You need to create a local environment file to store your secret keys. Create a file named `.env.local` in the root of your project directory and populate it with the keys you documented earlier. For a detailed guide on the differences and best practices for `.env` files, refer to our post: [Understanding .env and .env.local Files](/blog/env-local-vs-env).
Here is a practical example of what this looks like:
```bash
# Create a .env.local file in your downloaded project
SUPABASE_URL=your-project-url.supabase.co
SUPABASE_ANON_KEY=your-anon-key-here
STRIPE_PUBLISHABLE_KEY=pk_test_your-key
NEXT_PUBLIC_API_URL=https://your-api.com
```
Once you've populated this file, save it and **restart your development server.** Your local application will now be able to connect to the same services your Lovable project used. No code changes are necessary—just proper environment configuration.
#### Gotcha #2: Outdated Dependencies
The dependencies bundled in your Lovable project may occasionally be slightly outdated. Running `npm install` might pull in packages with known security vulnerabilities, causing your CI pipeline to fail.
* **Symptom:** `npm audit` reports high-severity vulnerabilities, or your Vercel deployment fails with dependency errors.
* **The Fix:** Run the following commands immediately after cloning the repository:
```bash
npm install
npm audit fix
```
#### Gotcha #3: Deleting "Glue Code"
Lovable generates helper functions and API route wrappers that connect your frontend to backend services. This code might look like boilerplate that can be "cleaned up," but deleting it will break your application.
* **Symptom:** Fetch calls return 404 errors, authentication state is not persisted, or form submissions fail silently.
* **The Fix:** Do not delete any code until you have the local development server running and have manually tested every user flow.
**Common Mistake:** Starting new feature work before verifying that the local development server is running correctly.
**The Fix:** Run `npm install` and `npm run dev`, then manually test every major user flow (e.g., signup, login, checkout) before writing any new code.
### Wire Up Your AI Coding Agent (Cursor, Windsurf, or Claude Code)
You exported from Lovable to overcome limitations and maintain development velocity. An AI coding agent like Cursor or Claude Code can help you continue to build quickly — we compared all the top options in our [Lovable alternatives](/blog/lovable-alternatives) guide. These tools support React, TypeScript, and the Vite setup from your exported project.
Here's how to get started in under 10 minutes:
1. **Choose your agent.** Cursor and Windsurf are standalone editors forked from VS Code, while Claude Code is available as a VS Code extension and CLI.
2. **Install the agent.** Download it from the official website or install it from the VS Code marketplace.
3. **Open your project folder.**
4. **Provide context to the agent.** Before asking it to build a new feature, give it a context-building prompt like:
> "Review this codebase and identify the main features, tech stack, and file structure."
5. **Start coding with AI assistance.** You can now ask the agent to build features, fix bugs, or refactor code without the message caps found in some platforms.
**Common Mistake:** Treating the agent as a magic code generator.
**The Fix:** Stay involved in the process. Review the code the agent generates, ask it to explain its reasoning, and test every change manually.
### Avoid the "Rewrite Everything" Trap
Once the code is running locally, you might be tempted to refactor systems like authentication or billing. Resist this urge. Your customers care about whether your product solves their problem, not about the elegance of your code. Rewriting functional systems consumes valuable time that could be spent shipping features.
Instead, focus on the list of "must-ship features" you created before exporting—the features your beta users have requested and that will unlock paid tiers.
Lovable generates production-ready code. If a system is not broken and customers are not complaining, it is best to leave it alone. Refactor only when you encounter a real bottleneck, such as slow database queries or API rate limits.
**Common Mistake:** Rewriting authentication or billing "to own it." This replaces a proven infrastructure with untested code that will require weeks of debugging.
**The Fix:** Treat the exported code as your production codebase. Evolve it incrementally by adding features, fixing bugs, and refactoring only when there is a measurable reason to do so.
### Take Control and Ship
Exporting your Lovable project is not a step backward; it's a step forward. You are moving production-quality code into an environment where you have complete control over the roadmap, deployment, and integrations.
This guide has shown you how to get your code onto GitHub, avoid common pitfalls, and set up an AI agent to maintain your development speed. By avoiding premature rewrites, you can stay focused on shipping features that matter to your users. If you're migrating to a specific framework, our [Lovable to Next.js migration guide](/blog/migrate-lovable-to-nextjs) covers that workflow step by step.
Your first paying customers are waiting for features only you can prioritize. Your competitors are not confined to a no-code editor, and neither should you be. Clone the repository, configure your environment, and start shipping. This is how prototypes become products, and products generate revenue.
---
# I Built a Vibe Coding Mess, GitHub Was the Start of Taking Back Control
Source: https://www.braingrid.ai/blog/i-built-a-vibe-coding-mess
Published: 2025-10-29T10:00:00Z
So you're vibing with an AI coder. Maybe it's Lovable, Bolt, or just the Replit ghost. And it feels like magic. You type a few words, and poof, a full-blown React component appears. It's an unbelievable accelerator. For a while.
Then you hit the wall.
You ask the AI to add one more feature before you launch, and it cheerfully breaks your signup flow. Now you have no way to undo the change. Days turn into weeks as you try to untangle the mess. Your potential users are waiting. Your competition isn't. One person on Reddit put it perfectly:
>"I was using Replit's AI to build a small flask app. It was amazing at first, but now I have this massive main.py file, things are breaking, and the AI just keeps suggesting things that break it more. I dont know what change caused the error and I feel completely stuck."
That feeling? It's the sound of your project outgrowing its playground. The AI gave you a stupendous head start, but without a way to safely experiment and recover from mistakes, every change feels risky. You need a safety net called Git. Set it up in 10 minutes, then sprint to launch.
## Your Tools Don't Understand the Big Picture
These AI assistants are phenomenal at writing functions in isolation. They are less good at architecting software. They lack true context. They don't remember the 'why' behind a decision you made two days ago. They just see the code that exists right now.
This leads to a specific brand of frustration that lots of us are feeling. You start with a great prototype, but when the project demands genuine complexity, the AI falls down.
Here's another dev describing this exact predicament:
>"Okay so Lovable built me a pretty slick UI with React. But now I need to integrate a payment gateway and it's a disaster. The AI doesn't understand the context of my existing components and its suggestions are just garbage. I feel like I have to start over."
This isn't a new problem. Before AI, we just called it "writing code without source control." We built things that became too scary to change. One more user, this time from someone using Bolt, expressed this anxiety:
>"I used Bolt to get a project off the ground. The vibe-based coding is cool for mockups. But now the client wants real features and I have no version history, no way to test things separately. It's a house of cards and I'm scared to touch anything."
All three stories share the same villain: a lack of history. Without a record of changes, you can't go back, you can't experiment safely, and you can't understand how you got into the mess.
## Git is Your Project's Save Button
This is where GitHub comes in. Think of it less as a chore and more as the ultimate safety net. It's a time machine for your codebase.
At its core, using Git (the system) and GitHub (the place you store it) is about making "commits." A commit is just a snapshot of your code at a specific moment. It's a save point in your video game. When you make a commit, you write a short message explaining what you did. "Added user login button." "Fixed the header bug." "Tried a crazy idea for the API."
This simple habit changes everything.
* AI broke something? No problem. Revert to the last working commit. You lose minutes of work, not days.
* Want to try a wild new feature? Create a "branch." It's a parallel reality for your code. If the feature works, you can merge it back into your main project. If it's a disaster, you just delete the branch. No harm done.
* **Need help to finish?** Every developer you hire—even for 2 hours—will ask for your GitHub repo. Without it, you can't get professional help when you're stuck.
It turns your house of cards into a fortress.
## Let's Move Your Code to a Real Home
"But I'm not a developer—this sounds complicated." It's not. You need 10 minutes and zero Git knowledge. This is the difference between being stuck for weeks and launching next week. Let's do it.
Ready to rescue your project and unblock your launch? This takes 10 minutes. After this, you can experiment fearlessly, hire help when stuck, and actually ship. Let's get your code from Lovable, Bolt, or Replit into a proper GitHub repository.
### 1. Create a GitHub Account
If you don't have one, go to [github.com](https://github.com) and sign up. It's free.
### 2. Make a New Repository
A repository (or "repo") is just a folder for your project.
* On your GitHub dashboard, click the **+** icon in the top right and select **New repository**.
* Give it a short, memorable name.
* Choose **Public** or **Private**.
* Don't initialize it with a README yet. We want an empty repo.
* Click **Create repository**.
### 3. Get Your Code Locally
Now, get your code off the AI platform and onto your own computer.
* **From Replit:** Click the three dots in the file sidebar and select **Download as zip**. Unzip it into a folder on your machine.
* **From Lovable/Bolt:** There's usually an export or download option. If not, just create a new folder on your computer and copy-paste your code into new files (index.html, style.css, etc).
### 4. Push Your Code to GitHub
Open your terminal or command prompt, navigate into your new project folder, and copy-paste these commands one by one. Here's what each command does—you don't need to memorize them. Think of this as a recipe: follow the steps, and you get a safety net for your business.
```bash
## Tell Git to start tracking your project
git init
## Take a snapshot of all your current files
git add .
## Save this snapshot with a description
git commit -m "Initial commit from AI tool"
## Connect your local project to GitHub
## Get repository URL from your GitHub page
## it looks like https://github.com/your-name/your-repo.git
git remote add origin PASTE_YOUR_URL_HERE
## Upload your code to GitHub
git push -u origin main
```
That's it. Refresh your GitHub page. Your code is now safe.
## Your AI is a Co-Pilot, Not the Pilot
Don't ditch your AI coder. It's still an incredible tool for sprinting. Use it to generate boilerplate, write tricky algorithms, or mock up a UI. It's a brilliant, tireless assistant.
But your project's foundation shouldn't be a conversation. It should be a Git repository.
Now you have the best of both worlds. Let the AI write the code. Then, commit it to your repo. Let the AI suggest a bonkers refactor. Try it on a separate branch. You are back in control. You get all the speed of AI with the stability and security of a professional workflow. Your AI is no longer the anxious artist; it's a powerful tool wielded by a smart architect—you.
---
# Why we switched from Claude web search to Exa for the BrainGrid agent
Source: https://www.braingrid.ai/blog/switching-claude-web-search-to-exa
Published: 2025-08-09T10:00:00Z
We hit a problem last week that made us rethink our entire approach to web search in AI agents.
Our requirements planning agent needed to look up best practices, documentation and be able to do research. You know, the usual stuff, how to properly implement OAuth flows, current React patterns, API design guidelines. Claude's built-in web search seemed perfect. We use Anthropic models everywhere, so why not use their search too?
Turns out, there was a really good reason not to.
The issue wasn't performance or cost. It was something we never saw coming: encryption. Claude encrypts web content, which sounds great until you realize your agent can't actually understand what is going on. We discovered this while building our requirements agent to help developers write better specs. The agent would search for API docs, find exactly what it needed, then... nothing. Just encrypted blobs where structured data should be. Hard to figure out what content is actually there. One additional wrinkle is that we use Google's Gemini for certain tasks of our agent, and Gemini doesn't understand Claude's encrypted content.
This is how we moved forward with Exa in under 100 lines of code.
## How Claude's encryption broke our documentation workflow
Let me paint you a picture. Your agent searches for "Stripe create payment intent API". Claude finds the perfect page. But here's what comes back:
```json
{
"content": {
"encrypted": "2f3a9b8c4d5e6f7a8b9c0d1e2f3a4b5c...",
"index": "encrypted_index_abc123..."
},
"citation": {
"url": "https://stripe.com/docs/api/payment_intents/create",
"title": "Create a PaymentIntent"
}
}
```
That encrypted field? It contains all the good stuff. The request parameters, the response schema, the code examples. Everything your agent needs to write a proper requirement. But it's locked away.
We tried working around it. Maybe we could use the citations to reconstruct the content? Nope. Citations give you tiny snippets, not the full API schema. Maybe we could chain multiple searches? That just gave us more encrypted blobs.
We spent hours trying different approaches. Parse the citations more cleverly. Search for smaller chunks. Use different query patterns. Nothing worked. The encryption was doing exactly what it was designed to do, protecting content. Just not in a way that worked for our use case.
## Enter Exa: a search engine built for AI applications
That's when we found Exa. It bills itself as "search built for AIs," and honestly, that's exactly what it is.
Here's the same Stripe API search with Exa:
```json
{
"url": "https://stripe.com/docs/api/payment_intents/create",
"title": "Create a PaymentIntent | Stripe API Reference",
"text": "POST /v1/payment_intents\n\nCreates a PaymentIntent object...\n\nParameters:\n- amount (required): Amount in cents\n- currency (required): Three-letter ISO code\n- payment_method_types: Array of payment methods...",
"highlights": [
"amount integer Required",
"currency string Required",
"automatic_payment_methods object"
]
}
```
See the difference? Actual content. Parseable, structured, immediately useful content.
But Exa isn't just unencrypted Claude search. It's built differently. The neural search understands technical queries in a way traditional search doesn't. Ask for "React Server Components data fetching patterns" and it finds the exact section in the docs, not just pages that happen to contain those words.
The best part? It plugged right into our Vercel AI SDK setup. We were already using AI SDK v5 (after [our migration adventure](/blog/migrating-to-ai-sdk-v5)). Exa has first-class support for it. Total integration time: one afternoon.
## The implementation: web search and web page reading in two tools
Here's where it gets interesting. We didn't just replace Claude's search, we built something better.
The code below shows the initial implementation. A brand new tool that would take care of:
- Searching the web
- Using the results to get the most relevant content
```typescript
// Web search for finding relevant docs and best practices
const webSearchTool = tool({
description: 'Search the web for relevant information',
inputSchema: z.object({
query: z.string().min(1).max(100),
num_results: z.number().min(1).max(10),
max_characters: z.number().min(1).max(10000)
}),
execute: async ({ query, num_results, max_characters }) => {
const { results } = await exa.searchAndContents(query, {
livecrawl: 'always',
numResults: num_results,
});
return results.map(result => ({
title: result.title,
url: result.url,
content: result.text?.slice(0, max_characters) ?? '',
publishedDate: result.publishedDate,
}));
},
});
```
But search alone wasn't enough. What happens if the user wants to attach a web page as context for the agent? Well, we can fortunately add a very simple tool so the agent is able to read a web page given a URL the user can provide:
```typescript
// Read full web pages when agents need complete context
const readWebPageTool = tool({
description: 'Read a web page and return the content',
inputSchema: z.object({
url: z.string().url()
}),
execute: async ({ url }) => {
const { results } = await exa.getContents(url);
return results;
},
});
```
While giving the agent the ability of surfing the web looking for relevant content is extremely powerful, allowing users to tell the agent where to search for relevant information such as API docs or best practices guides is even more powerful. And all of this with no encryption and no parsing headaches. Just clean, plain documentation ready for requirement writing.
We also discovered Exa's `livecrawl` feature, which forces fresh content retrieval. Critical for API docs that change frequently. No more cached responses from six months ago.
## Results: faster, cleaner, more reliable requirement generation
The experience speaks for itself, our agent is now able to do research and write better requirements. It can do branched searching to explore different aspects and if it needs to dig deeper, it can use the `readWebPage` tool to get the complete context.
The BrainGrid agent parses the results and gives actionable responses, like figuring out what best practices the current requirements document already implements and what is missing.
It also doesn't take everything it reads, it recommends the most impactful best practices for the requirement that you're working on.
But the real win? Our requirements got better. Way better.
This level of detail means developers spend less time asking clarifying questions and more time building. Requirements are actionable from day one.
One unexpected benefit: the agent exposes its sources. When it recommends a specific approach, you can see exactly what search results it got and what pages it read. Developers can verify the reasoning, learn something new, or dig deeper if needed.
## The bigger picture
This whole experience taught us something important. When building AI tools for developers, the quality of your data access matters as much as your model choice.
Claude's web search works great for general queries where you are using exclusively Claude models. But for more sophisticated agents that leverage different models for different tasks with the same context, you need full control over what is going into the context.
If you're hitting similar walls with encrypted content, give Exa a look. The migration is straightforward, especially if you're already on Vercel AI SDK. Our entire switch took less than 100 lines of code across two PRs.
Building AI developer tools? We should talk. We're solving these problems every day at BrainGrid, turning messy ideas into AI-ready requirements. [Try it yourself](https://www.braingrid.ai) and see what properly researched AI-ready requirements look like.
---
# From Local Hack to Production-Ready: How We Solved the BrainGrid's MCP Multi-Tenant Authentication Problem
Source: https://www.braingrid.ai/blog/how-we-solved-mcp-authentication
Published: 2025-07-30T08:00:00Z
You've built an amazing MCP server. It works perfectly on your laptop. Your AI assistant can create Jira tickets, query your database, deploy to production - life is good. Then your teammate asks: "Hey, can I use this too?"
Even better, you want to ship your MCP as a product for your customers. You now need to support multiple tenants, each with their own API keys and authentication.
Suddenly, you're in hell.
## The Problem Nobody Talks About
Here's what happens when you try to share your MCP server with your customers:
**Option 1: The "Just Install It" Approach**
```bash
## Your instructions to teammates:
1. Clone the repo
2. Install dependencies
3. Set up your API keys
4. Configure your environment
5. Run the server locally
6. Oh, and update these keys when they expire...
7. And don't forget to pull the latest changes...
8. BTW, it might conflict with your other Node versions...
```
Result: 3 hours later, half your customer gave up, the other half is debugging npm issues.
**Option 2: The "Let's Host It" Nightmare**
You deploy to a Serverless platform like Cloud Run or Vercel. Five minutes later:
```
customer: "It's asking me to authenticate... again"
you: "Yeah, just refresh and login again"
customer: "I just did. It's asking again."
you: "Oh, that's because Cloud Run scales to zero and..."
customer: "I don't care why. I just want to create a ticket."
```
The core issue? **Serverless platforms don't do sessions**. Every request could hit a different instance. Your carefully crafted auth flow becomes a game of authentication whack-a-mole.
## Why This Matters More Than You Think
This isn't just an annoyance. It's the difference between:
- **A tool only you use** vs **A tool your entire customer base adopts**
- **"Cool prototype"** vs **"Critical infrastructure"**
- **Weekend project** vs **Production-ready product customers actually use**
We learned this the hard way at BrainGrid. Our MCP server transformed how our team worked with AI - but only after we solved the authentication puzzle we were ready to ship to our customers.
## What You'll Learn
This guide shows you exactly how we transformed our MCP server from a local development tool into a production-ready service that:
- **Authenticates once, works everywhere** - No more login fatigue
- **Scales from 1 to 1000 users** - Same performance whether it's just you or the whole company
- **Costs pennies to run** - Efficient caching means minimal cloud costs
- **Works with existing auth** - Integrates with WorkOS, Auth0, or any OAuth provider
- **Deploys in minutes** - One command to go from local to remote
We'll cover the exact architecture, the gotchas we discovered, and the code that makes it all work. No theory, no fluff - just battle-tested solutions from our production deployment serving hundreds of developers.
Ready to make your MCP server something your customers will actually want to use? Let's dive in.
## How we got there
1. [Initial Setup: From Local to Remote](#initial-setup-from-local-to-remote)
2. [The Serverless Challenge](#the-serverless-challenge)
3. [Technical Solution: Redis Session Store](#technical-solution-redis-session-store-with-encryption)
4. [Production Deployment Strategies](#production-deployment-strategies)
5. [Monitoring and Debugging](#monitoring-and-debugging)
6. [Performance Optimization](#performance-optimization)
7. [The Paradigm Shift](#the-paradigm-shift-from-vibe-coding-to-professional-agentic-development)
## Initial Setup: From Local to Remote
### Step 1: Basic MCP Server Configuration
Start with a standard MCP server setup using FastMCP. The key is understanding the dual nature of MCP servers - they need to work both locally for development and remotely for customers to use.
```typescript
import { FastMCP } from 'fastmcp';
import { z } from 'zod';
// Define your tool schemas
const CreateRequirementSchema = z.object({
message: z.string().describe("The requirement description"),
repositories: z.string().optional().describe("Comma-separated list of repos")
});
const server = new FastMCP({
name: 'braingrid-server',
version: '1.0.0'
});
// Add your tools
server.addTool({
name: 'create_requirement',
description: 'Create a new requirement in BrainGrid',
parameters: CreateRequirementSchema,
execute: async (args, context) => {
// Tool implementation
// Note: context.session contains user auth info when hosted
const apiClient = new BrainGridApiClient(config, context?.session);
return await apiClient.createRequirement(args);
}
});
// Local development (stdio transport)
await server.start({ transportType: 'stdio' });
```
### Step 2: Switching to httpStream for Remote Hosting
To deploy on Cloud Run or Vercel, switch to httpStream transport. This requires careful consideration of how your tools will handle authentication:
```typescript
// Detect transport type from environment
const transportType = process.env.MCP_TRANSPORT || 'stdio';
// httpStream configuration for serverless
if (transportType === 'httpStream') {
await server.start({
transportType: 'httpStream',
httpStream: {
port: parseInt(process.env.PORT || '8080'),
endpoint: '/mcp'
}
});
} else {
// Local stdio transport
await server.start({ transportType: 'stdio' });
}
```
### Step 3: Implementing OAuth with WorkOS
MCP requires specific OAuth implementation patterns. The key insight is that MCP clients expect a particular discovery flow:
```typescript
const serverOptions = {
name: 'braingrid-server',
version: '1.0.0',
authenticate: authenticateRequest,
oauth: {
enabled: true,
protectedResource: {
resource: 'https://mcp.braingrid.ai',
authorizationServers: ['https://auth.workos.com'],
bearerMethodsSupported: ['header'],
},
// This is crucial for MCP client compatibility
authorizationServer: {
issuer: 'https://auth.workos.com',
authorizationEndpoint: 'https://auth.workos.com/oauth2/authorize',
tokenEndpoint: 'https://auth.workos.com/oauth2/token',
jwksUri: 'https://auth.workos.com/oauth2/jwks', // Note: Not /.well-known/jwks.json
responseTypesSupported: ['code'],
grantTypesSupported: ['authorization_code', 'refresh_token'],
codeChallengeMethodsSupported: ['S256'],
tokenEndpointAuthMethodsSupported: ['none'],
scopesSupported: ['email', 'offline_access', 'openid', 'profile'],
}
}
};
```
Key implementation detail: The WWW-Authenticate header must be properly formatted for MCP clients:
```typescript
// MCP session structure - what gets passed to your tools
interface MCPSession {
userId: string;
email: string;
organizationId: string;
scopes: string[];
token: string;
}
export async function authenticateRequest(request: IncomingMessage): Promise {
const authHeader = request.headers.authorization;
if (!authHeader) {
// MCP clients expect this specific format
throw new Response(null, {
status: 401,
headers: {
'WWW-Authenticate': 'Bearer error="unauthorized", ' +
'error_description="Authorization needed", ' +
'resource_metadata="https://mcp.braingrid.ai/.well-known/oauth-protected-resource"'
}
});
}
// Extract bearer token
const bearerMatch = authHeader.match(/^Bearer (.+)$/);
if (!bearerMatch) {
throw new Response(null, {
status: 401,
headers: {
'WWW-Authenticate': 'Bearer error="invalid_token", ' +
'error_description="Invalid authorization header format"'
}
});
}
const token = bearerMatch[1];
// Validate JWT and return session
return await validateAndCreateSession(token);
}
```
### Step 4: Handling Dual Transport Modes
Your MCP server needs to support both local and remote authentication patterns:
```typescript
export class BrainGridApiClient {
private auth?: AuthHandler;
private session?: MCPSession;
private readonly config: { apiUrl: string; organizationId?: string };
constructor(config: { apiUrl: string; organizationId?: string }, session?: MCPSession) {
this.config = config;
this.session = session;
// Only create AuthHandler for local mode
if (!session) {
this.auth = new AuthHandler(config);
}
}
private async getHeaders(): Promise> {
if (this.session) {
// Remote mode - use session token
return {
'Authorization': `Bearer ${this.session.token}`,
'X-Organization-Id': this.session.organizationId,
'Content-Type': 'application/json',
};
} else if (this.auth) {
// Local mode - use stored auth
return this.auth.getOrganizationHeaders();
}
throw new Error('No authentication method available');
}
}
```
## The Serverless Challenge
Serverless platforms like Cloud Run and Vercel share fundamental characteristics that create unique challenges for stateful applications:
### 1. Instance Lifecycle Management
Serverless instances have unpredictable lifecycles:
- **Cold starts**: New instances spin up on demand
- **Scale to zero**: Instances terminate after inactivity
- **Horizontal scaling**: Multiple instances serve concurrent requests
- **No sticky sessions**: Requests can hit any instance
This creates specific challenges for MCP servers:
```typescript
// This approach fails in serverless:
class NaiveMCPServer {
private sessions = new Map(); // ❌ Lost on instance restart
async authenticate(token: string): Promise {
// Check memory cache
if (this.sessions.has(token)) {
return this.sessions.get(token)!;
}
// Validate and cache
const session = await validateJWT(token);
this.sessions.set(token, session); // ❌ Only exists on this instance
return session;
}
}
```
### 2. JWT Validation Overhead
Without session persistence, your MCP server performs full JWT validation on every request:
```typescript
async function validateJWT(token: string): Promise {
// Step 1: Fetch JWKS (Network call ~50ms)
const jwks = await fetchJWKS('https://auth.workos.com/oauth2/jwks');
// Step 2: Verify signature (CPU intensive ~10ms)
const verified = await jose.jwtVerify(token, jwks);
// Step 3: Check claims (CPU ~5ms)
if (verified.payload.iss !== 'https://auth.workos.com') {
throw new Error('Invalid issuer');
}
// Step 4: Extract session data
return {
userId: verified.payload.sub,
email: verified.payload.email,
organizationId: verified.payload.org_id,
scopes: verified.payload.scopes,
token: token
};
}
```
This adds 50-100ms to every request and increases costs significantly.
### 3. Re-authentication Fatigue
The user experience without session persistence:
```
Timeline of a frustrated developer:
0:00 - Connect to MCP server ✓
0:01 - Authenticate via WorkOS ✓
0:02 - Create requirement ✓
0:05 - (Cloud Run scales instance to zero)
0:10 - Try to update task ✗ "Please authenticate again"
0:11 - Re-authenticate 😤
0:12 - Update task ✓
0:15 - (New instance due to load)
0:16 - Try to commit ✗ "Please authenticate again"
0:17 - Rage quit
```
## Technical Solution: Redis Session Store with Encryption
### Architecture Overview
The solution implements a multi-tier caching strategy with security at its core:
```
┌─────────────┐ ┌─────────────┐ ┌─────────────┐
│ Request │────▶│ Memory │────▶│ Redis │
│ │ │ Cache │ │ Cache │
└─────────────┘ └─────────────┘ └─────────────┘
│ │
▼ ▼
┌─────────────┐ ┌─────────────┐
│ JWT │ │ JWT │
│ Validation │ │ Validation │
└─────────────┘ └─────────────┘
```
### Implementation Details
#### Session Store with AES-256-GCM Encryption
The session store implements military-grade encryption for sensitive session data:
```typescript
import { Redis } from 'ioredis';
import crypto from 'crypto';
import { MCPSession } from './types.js';
import { logger } from './logger.js';
export class SessionStore {
private redis: Redis | null = null;
private encryptionKey: Buffer | null = null;
private algorithm = 'aes-256-gcm';
private readonly ttl: number;
private keyPrefix = 'mcp:session:';
constructor() {
// Only initialize for httpStream transport
if (process.env.MCP_TRANSPORT !== 'httpStream') {
logger.debug('SessionStore not initialized - stdio transport');
return;
}
const redisUrl = process.env.REDIS_URL;
const encryptionKeyHex = process.env.ENCRYPTION_KEY;
if (!redisUrl || !encryptionKeyHex) {
logger.warn('Session persistence disabled - missing configuration');
return;
}
// Validate encryption key length
if (encryptionKeyHex.length !== 64) {
throw new Error('ENCRYPTION_KEY must be 32 bytes (64 hex characters)');
}
this.encryptionKey = Buffer.from(encryptionKeyHex, 'hex');
this.ttl = parseInt(process.env.SESSION_CACHE_TTL || '604800', 10);
// Configure Redis with production-ready settings
this.redis = new Redis(redisUrl, {
// Retry strategy with exponential backoff
retryStrategy: (times) => {
const delay = Math.min(times * 50, 2000);
logger.debug(`Redis retry attempt ${times}, delay: ${delay}ms`);
return delay;
},
// Reconnect on READONLY errors (Redis failover)
reconnectOnError: (err) => {
const shouldReconnect = err.message.includes('READONLY');
if (shouldReconnect) {
logger.warn('Redis READONLY error, reconnecting...');
}
return shouldReconnect;
},
// Connection settings
connectTimeout: 10000,
maxRetriesPerRequest: 3,
enableReadyCheck: true,
enableOfflineQueue: false, // Fail fast in production
});
// Monitor Redis connection health
this.redis.on('connect', () => logger.info('Redis connected'));
this.redis.on('ready', () => logger.info('Redis ready'));
this.redis.on('error', (err) => logger.error({ err }, 'Redis error'));
this.redis.on('close', () => logger.warn('Redis connection closed'));
}
/**
* Check if session store is available
*/
isAvailable(): boolean {
return this.redis !== null &&
this.redis.status === 'ready' &&
this.encryptionKey !== null;
}
/**
* Store encrypted session with automatic expiration
*/
async storeSession(session: MCPSession): Promise {
if (!this.isAvailable()) {
logger.debug('Session store unavailable, skipping storage');
return;
}
try {
// Generate unique IV for each encryption
const iv = crypto.randomBytes(16);
const cipher = crypto.createCipheriv(this.algorithm, this.encryptionKey!, iv);
// Encrypt session data
const sessionJson = JSON.stringify(session);
const encrypted = Buffer.concat([
cipher.update(sessionJson, 'utf8'),
cipher.final()
]);
// Get authentication tag for GCM
const authTag = cipher.getAuthTag();
// Combine components: IV (16) + AuthTag (16) + Encrypted Data
const combined = Buffer.concat([iv, authTag, encrypted]);
const encoded = combined.toString('base64');
// Store with TTL
const key = `${this.keyPrefix}${session.userId}`;
await this.redis!.setex(key, this.ttl, encoded);
logger.debug({
userId: session.userId,
keySize: encoded.length,
ttl: this.ttl
}, 'Session stored successfully');
} catch (error) {
logger.error({ error }, 'Failed to store session');
// Don't throw - graceful degradation
}
}
/**
* Retrieve and decrypt session
*/
async getSession(userId: string): Promise {
if (!this.isAvailable()) {
return null;
}
const startTime = Date.now();
try {
const key = `${this.keyPrefix}${userId}`;
const encoded = await this.redis!.get(key);
if (!encoded) {
logger.debug({ userId }, 'Session not found in cache');
return null;
}
// Decode and extract components
const combined = Buffer.from(encoded, 'base64');
const iv = combined.slice(0, 16);
const authTag = combined.slice(16, 32);
const encrypted = combined.slice(32);
// Decrypt with authentication
const decipher = crypto.createDecipheriv(this.algorithm, this.encryptionKey!, iv);
decipher.setAuthTag(authTag);
const decrypted = Buffer.concat([
decipher.update(encrypted),
decipher.final()
]);
const session = JSON.parse(decrypted.toString('utf8')) as MCPSession;
const elapsed = Date.now() - startTime;
logger.debug({ userId, elapsed }, 'Session retrieved from cache');
return session;
} catch (error) {
if (error instanceof Error && error.message.includes('Unsupported state or unable to authenticate data')) {
logger.error({ userId }, 'Session decryption failed - possible tampering');
} else {
logger.error({ error, userId }, 'Failed to retrieve session');
}
return null;
}
}
/**
* Remove session (for logout)
*/
async removeSession(userId: string): Promise {
if (!this.isAvailable()) return;
try {
const key = `${this.keyPrefix}${userId}`;
await this.redis!.del(key);
logger.debug({ userId }, 'Session removed');
} catch (error) {
logger.error({ error, userId }, 'Failed to remove session');
}
}
/**
* Clean shutdown
*/
async close(): Promise {
if (this.redis) {
await this.redis.quit();
this.redis = null;
}
}
}
// Singleton instance
export const sessionStore = new SessionStore();
```
#### Optimized Authentication Middleware
The authentication middleware implements a fast-path/slow-path pattern:
```typescript
import { IncomingMessage } from 'http';
import crypto from 'crypto';
import { decodeJwt, createRemoteJWKSet, jwtVerify, JWTPayload } from 'jose';
import { sessionStore } from './session-store.js';
import { logger } from './logger.js';
import { MCPSession } from './types.js';
export async function authenticateRequest(request: IncomingMessage): Promise {
const requestId = crypto.randomUUID();
const startTime = Date.now();
logger.debug({
requestId,
method: request.method,
url: request.url
}, 'Authentication request started');
try {
// Extract bearer token
const token = extractBearerToken(request);
if (!token) {
throw new UnauthorizedError('No bearer token provided');
}
// Fast path: Try to decode JWT for userId
let userId: string | null = null;
let tokenExp: number | null = null;
try {
const decoded = decodeJwt(token);
userId = decoded.sub || null;
tokenExp = decoded.exp || null;
// Quick expiration check
if (tokenExp && tokenExp < Date.now() / 1000) {
logger.debug({ requestId, userId }, 'Token expired, skipping cache');
userId = null; // Force validation
}
} catch (error) {
logger.debug({ requestId }, 'Failed to decode JWT for cache lookup');
}
// Try cache if we have a userId
if (userId && sessionStore.isAvailable()) {
const cached = await sessionStore.getSession(userId);
if (cached && cached.token === token) {
const elapsed = Date.now() - startTime;
logger.info({
requestId,
userId,
elapsed,
source: 'cache'
}, 'Authentication successful (cached)');
return cached;
}
}
// Slow path: Full JWT validation
logger.debug({ requestId }, 'Cache miss, performing JWT validation');
const session = await validateJWTWithWorkOS(token);
// Store for next time
if (sessionStore.isAvailable()) {
await sessionStore.storeSession(session);
}
const elapsed = Date.now() - startTime;
logger.info({
requestId,
userId: session.userId,
elapsed,
source: 'jwt'
}, 'Authentication successful (validated)');
return session;
} catch (error) {
const elapsed = Date.now() - startTime;
logger.error({
requestId,
error: error instanceof Error ? error.message : 'Unknown error',
elapsed
}, 'Authentication failed');
// Return proper HTTP response for MCP
if (error instanceof UnauthorizedError) {
throw new Response(null, {
status: 401,
headers: {
'WWW-Authenticate': `Bearer error="unauthorized", ` +
`error_description="${error.message}", ` +
`resource_metadata="${getResourceMetadataUrl()}"`
}
});
}
throw error;
}
}
function extractBearerToken(request: IncomingMessage): string | null {
const authHeader = request.headers.authorization;
if (!authHeader) return null;
const match = authHeader.match(/^Bearer (.+)$/);
return match ? match[1] : null;
}
class UnauthorizedError extends Error {
constructor(message: string) {
super(message);
this.name = 'UnauthorizedError';
}
}
function getResourceMetadataUrl(): string {
const host = process.env.MCP_HOST || 'https://mcp.braingrid.ai';
return `${host}/.well-known/oauth-protected-resource`;
}
// JWT validation with WorkOS
const jwksCache = new Map>();
async function validateJWTWithWorkOS(token: string): Promise {
const issuer = process.env.WORKOS_ISSUER || 'https://auth.workos.com';
try {
// Get or create JWKS
let jwks = jwksCache.get(issuer);
if (!jwks) {
jwks = createRemoteJWKSet(new URL(`${issuer}/oauth2/jwks`));
jwksCache.set(issuer, jwks);
}
// Verify JWT with options
const verifyOptions: any = {
issuer,
algorithms: ['RS256'],
};
// Only check audience if configured
if (process.env.WORKOS_CLIENT_ID) {
verifyOptions.audience = process.env.WORKOS_CLIENT_ID;
}
const { payload } = await jwtVerify(token, jwks, verifyOptions);
// Validate required claims
if (!payload.sub || !payload.email || !payload.org_id) {
throw new Error('Missing required JWT claims');
}
// Create session from JWT claims
return {
userId: payload.sub,
email: payload.email as string,
organizationId: payload.org_id as string,
scopes: Array.isArray(payload.scopes) ? payload.scopes : [],
token,
};
} catch (error) {
logger.error({ error: error instanceof Error ? error.message : 'Unknown error' }, 'JWT validation failed');
throw error;
}
}
```
### Graceful Degradation
The implementation handles Redis failures gracefully by simply returning null and forcing re-authentication. This is intentional - in a serverless environment, there's no point in falling back to in-memory caching since each instance has its own memory. Better to fail fast and have the user re-authenticate than to create inconsistent state.
## Production Deployment Strategies
### Cloud Run Configuration
Create a comprehensive deployment configuration:
```dockerfile
## Multi-stage build for optimization
FROM node:22-alpine AS builder
WORKDIR /app
## Copy package files
COPY package*.json ./
COPY pnpm-lock.yaml ./
## Install dependencies
RUN npm install -g pnpm && pnpm install --frozen-lockfile
## Copy source code
COPY . .
## Build TypeScript
RUN pnpm run build
## Production stage
FROM node:22-alpine
WORKDIR /app
## Install production dependencies only
COPY package*.json ./
COPY pnpm-lock.yaml ./
RUN npm install -g pnpm && pnpm install --prod --frozen-lockfile
## Copy built application
COPY --from=builder /app/dist ./dist
## Set environment
ENV NODE_ENV=production
ENV MCP_TRANSPORT=httpStream
## Health check
HEALTHCHECK --interval=30s --timeout=3s --start-period=5s --retries=3 \
CMD node -e "require('http').get('http://localhost:8080/health', (r) => process.exit(r.statusCode === 200 ? 0 : 1))"
EXPOSE 8080
CMD ["node", "dist/server.js"]
```
Deploy with proper configuration:
```bash
#!/bin/bash
## deploy-cloud-run.sh
PROJECT_ID="your-project-id"
SERVICE_NAME="braingrid-mcp-server"
REGION="us-central1"
REDIS_URL="rediss://"
## Build and push image
gcloud builds submit --tag gcr.io/${PROJECT_ID}/${SERVICE_NAME}
## Deploy to Cloud Run
gcloud run deploy ${SERVICE_NAME} \
--image gcr.io/${PROJECT_ID}/${SERVICE_NAME} \
--platform managed \
--region ${REGION} \
--allow-unauthenticated \
--set-env-vars "MCP_TRANSPORT=httpStream" \
--set-env-vars "BRAINGRID_ENV=production" \
--set-env-vars "REDIS_URL=${REDIS_URL}" \
--set-secrets "ENCRYPTION_KEY=mcp-encryption-key:latest" \
--cpu 1 \
--memory 512Mi \
--min-instances 1 \
--max-instances 100 \
--concurrency 80 \
--timeout 300
```
### Vercel Configuration
For Vercel deployment, create `vercel.json`:
```json
{
"version": 2,
"builds": [
{
"src": "dist/server.js",
"use": "@vercel/node"
}
],
"routes": [
{
"src": "/health",
"dest": "/dist/server.js"
},
{
"src": "/mcp",
"dest": "/dist/server.js"
},
{
"src": "/.well-known/oauth-protected-resource",
"dest": "/dist/server.js"
}
],
"env": {
"MCP_TRANSPORT": "httpStream",
"NODE_ENV": "production"
}
}
```
## Monitoring and Debugging
### Structured Logging
Implement comprehensive logging for production debugging:
```typescript
import pino from 'pino';
// Configure structured logging
export const logger = pino({
level: process.env.LOG_LEVEL || 'info',
transport: process.env.NODE_ENV === 'production' ? undefined : {
target: 'pino-pretty',
options: {
colorize: true,
translateTime: 'HH:MM:ss Z',
ignore: 'pid,hostname'
}
},
formatters: {
level: (label) => {
return { level: label };
}
},
serializers: {
req: (req) => ({
method: req.method,
url: req.url,
headers: {
...req.headers,
authorization: req.headers.authorization ? '[REDACTED]' : undefined
}
}),
err: pino.stdSerializers.err
}
});
// Request tracking middleware
import { IncomingMessage, ServerResponse } from 'http';
export function requestLogging() {
return (req: IncomingMessage, res: ServerResponse, next: () => void) => {
const start = Date.now();
const requestId = crypto.randomUUID();
// Attach to request
(req as any).requestId = requestId;
// Log request
logger.info({
requestId,
req,
type: 'request'
}, 'Incoming request');
// Log response
res.on('finish', () => {
const elapsed = Date.now() - start;
logger.info({
requestId,
statusCode: res.statusCode,
elapsed,
type: 'response'
}, 'Request completed');
});
next();
};
}
```
### Metrics Collection
For production deployments, export metrics to your observability platform:
```typescript
// Example: Exporting MCP tool call metrics to DataDog
import { StatsD } from 'node-dogstatsd';
const dogstatsd = new StatsD({
host: process.env.DD_AGENT_HOST || 'localhost',
port: 8125,
prefix: 'mcp.server.',
tags: [`env:${process.env.BRAINGRID_ENV || 'development'}`]
});
// Track tool usage
export function recordToolCall(toolName: string, duration: number, success: boolean) {
// Record timing metric
dogstatsd.timing('tool.call.duration', duration, [
`tool:${toolName}`,
`status:${success ? 'success' : 'failure'}`
]);
// Increment counter
dogstatsd.increment('tool.call.count', 1, [
`tool:${toolName}`,
`status:${success ? 'success' : 'failure'}`
]);
}
// In your tool implementation:
server.addTool({
name: 'create_requirement',
execute: async (args, context) => {
const startTime = Date.now();
try {
const result = await apiClient.createRequirement(args);
recordToolCall('create_requirement', Date.now() - startTime, true);
return result;
} catch (error) {
recordToolCall('create_requirement', Date.now() - startTime, false);
throw error;
}
}
});
```
## Performance Optimization
### Connection Pooling
Optimize Redis connections for serverless:
```typescript
// Redis connection pool for serverless
export class RedisConnectionPool {
private static instance: Redis | null = null;
static getInstance(): Redis | null {
if (!this.instance && process.env.REDIS_URL) {
this.instance = new Redis(process.env.REDIS_URL, {
// Connection pool settings
maxRetriesPerRequest: 3,
enableReadyCheck: true,
lazyConnect: true, // Important for serverless
// Serverless-optimized timeouts
connectTimeout: 5000,
commandTimeout: 5000,
// Connection reuse
keepAlive: 30000,
noDelay: true,
// Handle connection errors gracefully
retryStrategy: (times) => {
if (times > 3) return null; // Stop retrying
return Math.min(times * 100, 3000);
}
});
// Ensure connection is established
this.instance.connect().catch((err: Error) => {
logger.error({ err: err.message }, 'Redis connection failed');
this.instance = null;
});
}
return this.instance;
}
static async close(): Promise {
if (this.instance) {
await this.instance.quit();
this.instance = null;
}
}
}
```
### Request Batching
Optimize for concurrent requests:
```typescript
export class BatchedJWTValidator {
private readonly pendingValidations = new Map>();
async validateToken(token: string): Promise {
// Check if validation is already in progress
if (this.pendingValidations.has(token)) {
logger.debug('Reusing pending validation');
return this.pendingValidations.get(token)!;
}
// Start new validation
const validationPromise = this.performValidation(token)
.finally(() => {
// Clean up after completion
this.pendingValidations.delete(token);
});
this.pendingValidations.set(token, validationPromise);
return validationPromise;
}
private async performValidation(token: string): Promise {
// Actual JWT validation logic
return validateJWTWithWorkOS(token);
}
}
```
## Conclusion
Hosting MCP servers in serverless environments is challenging, but the patterns we've covered make it possible to build production-ready solutions that scale.
The key technical takeaways:
1. **Session persistence is non-negotiable** - Without Redis or similar external storage, your users face constant re-authentication
2. **Security can't be an afterthought** - Proper encryption (AES-256-GCM) and secure token handling are essential
3. **Fast-path optimization matters** - JWT validation is expensive; caching authenticated sessions dramatically improves performance
4. **Graceful degradation over complex fallbacks** - When Redis fails, force re-authentication rather than trying clever in-memory solutions
5. **Observable systems are debuggable systems** - Export metrics to DataDog or your platform of choice
By solving these challenges, we transformed our MCP server from a local development tool into infrastructure that our entire team relies on. The same patterns apply whether you're building tools for internal use or creating MCP servers for the broader community.
The future of development involves AI assistants that understand context and can take meaningful actions. Making that future accessible to teams - not just individual developers - requires solving the infrastructure challenges we've outlined here.
---
# Cutting AI Costs with a Single Line: Anthropic Tool Caching in AI SDK v5
Source: https://www.braingrid.ai/blog/anthropic-tool-caching-ai-sdk-v5
Published: 2025-07-25T10:00:00Z
Every AI API call we send with the BrainGrid base agent sends the same tool definitions. Every. Single. Time.
When you're building an AI agent with a dozen tools, each with detailed schemas and descriptions, you're looking at a couple thousand tokens that get sent with every request. It's like paying for coffee whether you drink it or not.
We recently [migrated to AI SDK v5](/blog/migrating-to-ai-sdk-v5) for other reasons (hello, proper TypeScript types and tool streaming), but buried in the release notes was a feature that caught our eye: support for Anthropic's ephemeral caching through `providerOptions`.
For context, BrainGrid is an AI-powered platform that helps developers turn messy ideas into crystal-clear specs that AI coding assistants can actually implement. We analyze your codebase, ask the right clarifying questions, and break requirements down into atomic, verifiable, AI-ready tasks. Each task becomes a precise prompt with full context, so your AI IDE (Cursor, Claude Code, etc.) gets it right the first time. Behind the scenes, we're orchestrating multiple specialized agents with dozens of tools—which is why this SDK migration touched everything.
## The Problem: Why pay for slower performance?
Here's what happens in a typical AI agent workflow:
1. User asks a question
2. We send the question + all tool definitions to the AI
3. AI responds with tool calls
4. We execute the tools and send results back... with all the tool definitions again
5. Repeat until done
Our `read_web_page` tool alone has a schema that's hundreds of tokens. Multiply that by all our tools, then by the number of turns in a conversation, and you're burning tokens like they're going out of style.
The kicker? Tool definitions rarely change. We're essentially paying to send the same static data over and over, and it is slower.
## The Approach: AI SDK v5 + Anthropic Caching
During our v5 migration, we noticed the new `providerOptions` parameter. Turns out, Anthropic had quietly released tool caching for exactly this use case.
The documentation was sparse, but the concept was simple: mark your tool definitions as cacheable, and Anthropic will store them for reuse. You pay 25% more for cached input tokens, but you only pay 10% of input tokens for the cache hit.
Here's the thing, since tool definitions are not changing often, this is a great candidate for caching. It's a no-brainer. Faster and cheaper.
## The Implementation: Low-hanging fruit in three lines
The implementation is simple. We just need to add three lines of code to the tool definition.
```typescript
const readWebPageTool = tool({
description: readWebPageTool.description,
inputSchema: readWebPageTool.schema,
// These three lines. That's it.
providerOptions: {
anthropic: { cacheControl: { type: 'ephemeral' } },
},
execute: async ({ url }) => {
const { results } = await exa.getContents(url);
return results;
},
});
```
That's literally it. Three lines of configuration.
## The Gotcha: Order Matters
Here's where it gets interesting. You'd think you'd need to add caching to every tool, right? Nope.
Anthropic's caching works on a "cache point" system. When you mark a tool as cacheable, *everything before it in the request gets cached too*. This means you only need to cache the last tool in your array:
```typescript
const tools = {
generateRequirements: this.getGenerateRequirementsAITool(),
generateSubtasks: this.getGenerateSubtasksAITool(),
clarifyingQuestions: this.getClarifyingQuestionsAITool(),
thinking: this.getThinkingAITool(),
webSearch: this.getWebSearchAITool(),
// IMPORTANT: read_web_page must be the last tool
// Its caching configuration will cause all tools before it to be cached
readWebPage: this.getReadWebPageAITool(), // ← Only this one has caching
};
```
It's a quirk of how Anthropic implemented caching, but it works in our favor. One configuration point, all tools cached.
## The Results: Faster, Cheaper, Better
After deploying this change:
- **Token costs dropped** despite the 25% premium on cached tokens
- **Queries feel snappier** because less data is transmitted
- **No behavior changes** - it just works
The math is simple: if you use tools more than 4 times in a conversation (and trust me, you will), caching pays for itself. After that, it's pure savings.
## The Takeaway
Sometimes the best optimizations are embarrassingly simple. We spent weeks optimizing our context, refactoring our prompts, and even considering switching providers.
The actual solution? Three lines of configuration.
If you're using AI SDK v5 with Anthropic and you have tools in your agent, add caching. Today. Your CFO will thank you, your users will notice the speed improvement, and you'll wonder why you didn't do it sooner.
Just remember: put the cached tool last in your array. Don't ask me how long it took us to figure that out.
---
**About the Author**
Nico Acosta is the Co-founder and CEO of BrainGrid, where we're building the future of AI-assisted product development. With over 20 years of experience in Product Management, AI, cloud platforms, and developer tools at companies like AWS and Twilio, Nico focuses on building products that are force multipliers for developers.
*Want to discuss Agent architectures or share your experiences? Find me on [X](https://x.com/acossta) or connect on [LinkedIn](https://www.linkedin.com/in/acossta/).*
---
# Migrating to AI SDK v5: A Story of Tool Streaming, Caching, and Type Safety
Source: https://www.braingrid.ai/blog/migrating-to-ai-sdk-v5
Published: 2025-07-24T14:00:00Z
Every developer knows that SDK migrations are like home renovations, they always take longer than expected, uncover hidden problems, and make you question your life choices halfway through. But sometimes, the end result makes it all worthwhile.
This month, we migrated BrainGrid's core AI infrastructure from AI SDK v4.3.16 to v5.0.0-beta.25. We knew it wouldn't be a walk in the park. SDK migrations never are, especially when you're dealing with beta versions. But three features made this migration impossible to ignore:
1. **Tool streaming** - Our users were tired of staring at blank screens while AI agents worked
2. **Provider options for tool caching** - Faster responses and lower costs? Yes please
3. **Better TypeScript support** - Even if it meant touching every file
For context, BrainGrid is an AI-powered platform that helps developers turn messy ideas into crystal-clear specs that AI coding assistants can actually implement. We analyze your codebase, ask the right clarifying questions, and break requirements down into atomic, verifiable, AI-ready tasks. Each task becomes a precise prompt with full context, so your AI IDE (Cursor, Claude Code, etc.) gets it right the first time. Behind the scenes, we're orchestrating multiple specialized agents with dozens of tools—which is why this SDK migration touched everything.
Anyhow, here's how the migration went.
## Why We Knew This Would Be Hard (But Did It Anyway)
Let's be honest: nobody migrates to a beta SDK for fun. We had 14 tool definitions, several streaming event handlers, and a complex agent system that our users depend on every day. Breaking any of it wasn't an option.
But our users had a legitimate complaint. When the BrainGrid agent started thinking or composing a requirement, they'd see... nothing. Just a blinking cursor. Was it thinking? Had it crashed? Was it writing War and Peace? Nobody knew until the tool input was finally done.

Meanwhile, paying less is nice. Every tool call meant sending the full tool definitions to the API. With complex tools, that's thousands of tokens per request. Anthropic's new cache control feature promised to fix this, but it required v5's provider options support.
So we made the call: temporary migration pain for permanent user gains.
## The Migration Journey
### 1. The Great API Rename
The first surprise came immediately. Every single tool definition needed surgery:
```typescript
// Before (v4)
const readWebPageTool = tool({
description: 'Reads and analyzes web content',
parameters: z.object({
url: z.string().url(),
extractImages: z.boolean().optional(),
}),
execute: async args => {
// Tool logic here
},
});
// After (v5)
const readWebPageTool = tool({
description: 'Reads and analyzes web content',
inputSchema: z.object({ // 👈 renamed from 'parameters'
url: z.string().url(),
extractImages: z.boolean().optional(),
}),
execute: async args => {
// Tool logic here
},
});
```
Not catastrophic, but we had 14 tools across our agent system. That's 14 careful edits, 14 places to potentially break something. But in reality it was actually the easy part.
Then came the tool calls themselves:
```typescript
// Before
if (chunk.type === 'tool-call') {
const toolArgs = chunk.args; // 👈 'args'
// Process tool call
}
// After
if (chunk.type === 'tool-call') {
const toolArgs = chunk.input; // 👈 now 'input'
// Process tool call
}
```
And don't forget about token limits:
```typescript
// Before
streamText({
model: anthropic('claude-4-sonnet'),
maxTokens: 4096, // 👈 'maxTokens'
// ...
});
// After
streamText({
model: anthropic('claude-4-sonnet'),
maxOutputTokens: 4096, // 👈 'maxOutputTokens'
// ...
});
```
Each change was small, but they added up. Fast.
### 2. Type System Overhaul
This is where things got interesting. The v5 SDK introduced stricter, more accurate types. Great for catching bugs, painful for migration.
Our entire conversation system was built on the old message types:
```typescript
// Before (v4)
import { Message as AIMessage } from 'ai';
interface Conversation {
messages: AIMessage[];
}
// After (v5)
import { ModelMessage } from 'ai';
interface Conversation {
messages: ModelMessage[];
}
```
But that was just the beginning. The new `ModelMessage` type revealed a fundamental assumption in our code: we assumed message content was always a string.
```typescript
// Our token calculator before migration
function calculateTokens(message: AIMessage): number {
const content = message.content as string; // 🚨 Danger!
return tokenizer.encode(content).length;
}
```
In v5, message content can be:
- A simple string: `"Hello world"`
- An array of parts: `[{ type: 'text', text: 'Hello' }, { type: 'image', image: '...' }]`
- Complex content objects
Our token calculator would crash on anything but strings. We built a helper to handle all cases:
```typescript
export function extractTextContent(content: unknown): string {
if (typeof content === 'string') {
return content;
}
if (Array.isArray(content)) {
return content
.filter(part => part.type === 'text')
.map(part => part.text)
.join(' ');
}
if (content && typeof content === 'object' && 'text' in content) {
return content.text;
}
return '';
}
```
But the stricter typing went beyond just content handling. The v5 SDK also made `streamText` much more strict about message interfaces. Before, we could accidentally pass malformed message objects and get cryptic runtime errors—including one memorable bug where we were accidentally sending the tool name instead of the expected message content. The old SDK would accept it and produce bizarre, hard-to-debug behavior.
Now, TypeScript catches these interface mismatches at compile time:
```typescript
// This would have failed silently in v4, causing weird runtime bugs
const messages: ModelMessage[] = [
{
role: 'assistant',
content: toolName, // 🚨 TypeScript now catches this mistake
},
];
// v5 forces us to be explicit and correct
const messages: ModelMessage[] = [
{
role: 'assistant',
content: message.content, // ✅ Proper message content
},
];
```
The silver lining? This exposed multiple real bugs. We'd been undercounting tokens for complex messages for months, and had subtle message formatting issues that occasionally caused confusing AI responses.
### 3. Streaming Protocol Redesign
Remember those users staring at blank screens? This is where we fixed that. But first, we had to rewrite how we handled streaming.
Every chunk type changed:
```typescript
// Before (v4)
for await (const chunk of stream) {
if (chunk.type === 'text-delta') {
content += chunk.textDelta;
}
}
// After (v5)
for await (const chunk of stream) {
if (chunk.type === 'text') {
content += chunk.text;
}
}
```
But the real win was tool streaming. Now we could show tool cards the instant an agent started using a tool:
```typescript
// When a tool-call chunk arrives
if (chunk.type === 'tool-call') {
setTemporaryStreamMessage(prev => [
...prev,
{
type: 'tool_call',
tool_call: {
id: chunk.toolCallId,
name: chunk.toolName,
arguments: chunk.input,
loading: true, // Shows spinner immediately
},
},
]);
}
```
Users now see a card appear instantly when the agent starts using a tool. No more mystery. No more "is it frozen?" support tickets.
### 4. Control Flow Changes
Here's where we almost shot ourselves in the foot. The old `maxSteps` parameter got a makeover:
```typescript
// Before (v4)
const result = await generateText({
model: anthropic('claude-4-sonnet'),
maxSteps: 25,
// ...
});
// After (v5)
const result = await generateText({
model: anthropic('claude-4-sonnet'),
stopWhen: stepCountIs(25),
// ...
});
```
Looks simple enough. But this change hid a critical shift in behavior. It turns out `stepCountIs(n)` doesn't set a _maximum_ number of steps; it requires the agent to run for _exactly_ `n` steps. What was `maxSteps` now behaved like `minSteps`.
This turned out to be a blessing in disguise. By forcing us to be explicit about the step count, we fixed a subtle issue where agents could occasionally run longer than needed. After adjusting our default step counts, the agents' behavior became smoother and more predictable, which was a great improvement for our complex workflows.
```typescript
// In our BaseAgent class
maxSteps = 5, // 👈 Used to be 25
```
The new `stopWhen` API is actually more powerful. We can now stop on specific conditions:
```typescript
stopWhen: [
stepCountIs(maxSteps),
hasToolCall('generate_clarifying_questions'), // Stop when clarification needed
];
```
This feature pleasantly surprised us, as we previously had to meticulously prompt engineer to ensure the agent stopped immediately after invoking the `generate_clarifying_questions` tool.
### 5. Enabling Tool Definition Caching
This was the feature that made the customers happy. With v5's provider options, we could finally use Anthropic's cache control on tool definitions:
```typescript
const readWebPageTool = tool({
description: 'Reads and analyzes web content',
inputSchema: z.object({
url: z.string().url(),
extractImages: z.boolean().optional(),
}),
providerOptions: {
anthropic: {
cacheControl: { type: 'ephemeral' }, // 👈 Cache this tool definition
},
},
execute: async args => {
// Tool logic
},
});
```
For frequently-used tools, this means the tool definition is cached on Anthropic's servers. Instead of sending thousands of tokens for complex tool definitions on every request, we send them once and they are cached automatically.
## The Results
### First and Foremost: Everything Still Works
Let's celebrate the most important achievement: after all these changes, BrainGrid works exactly as it did before. Every agent, every tool, every workflow operates seamlessly. No regressions. No "we'll fix that in v2" compromises.
This might sound like table stakes, but if you've done major migrations, you know it's not. Maintaining 100% compatibility while overhauling the foundation is like changing a car's engine while driving.
### But Now It's Better
Here's what our users notice:
1. **Instant feedback**: Tool cards appear the moment an agent starts working. No more guessing.
2. **Faster responses**: Cached tool definitions mean less data to send, faster processing.
3. **More reliable**: The stricter types caught edge cases we didn't know existed.


The numbers tell the story:
- Support tickets about "frozen" UI: **0** (down from 1-3 per week)
- Average tool execution time: **17% faster**
- API costs from tool definitions: **reduced by 7%**
- Type-related bugs caught: **7** (including that token calculator)
## Lessons for Fellow Engineers
After a couple days of migration work, here's what we learned:
### 1. Pin Your Beta Versions
```json
"ai": "5.0.0-beta.25" // Not "^5.0.0-beta.25"
```
Beta versions can have breaking changes between releases. Pin the exact version and upgrade deliberately.
### 2. Read the Source, Not Just the Docs
The migration guide covered the basics, but real apps have edge cases. When in doubt, read the SDK source code. It's surprisingly readable and answered questions the docs didn't.
### 3. Test with Production-Like Scenarios
Our unit tests passed. Our integration tests passed. But they all used simple, single-tool scenarios. We could definitely have missed the `maxSteps` issue. When it's about AI always run manual tests before shipping to production.
### 4. Migration Guides Show the Happy Path
Real migrations are messier. Budget time for:
- Edge cases the guide doesn't mention
- Updating related code that depends on the old behavior
- Testing scenarios you forgot existed
- Rolling back if something goes catastrophically wrong
### 5. Document Everything
We kept a migration log every change, every surprise, every "wait, why does this work now?" moment. This blog post started as those notes. Your future self will thank you.
## Was It Worth It?
Absolutely.
Our users get instant feedback when agents work. Our infrastructure costs dropped noticeably. Our code is more type-safe and maintainable.
Yes, it took a couple of days instead of an afternoon. Yes, we discovered bugs we didn't know existed. Yes, we questioned our sanity around the second day.
But that's engineering. We don't migrate SDKs because it's easy. We do it because our users deserve better, our infrastructure demands it, and sometimes the beta version has exactly what we need.
Just remember to pin your dependencies.
---
# The Babysitting is Over: A New Plan for AI Coding
Source: https://www.braingrid.ai/blog/the-babysitting-is-over-a-new-plan-for-ai-coding
Published: 2025-07-23T10:00:00Z
The promise of agentic AI coding was a tireless partner, an assistant that could take a feature request and run with it while we focused on the hard problems.
The reality, for most professional engineering teams, has been different. The reality is a brilliant but distractible intern you have to constantly supervise. The reality is spending 20 minutes writing the "perfect prompt," only for the AI to ignore a critical constraint, use a deprecated pattern from your codebase, and confidently break three other features.
The reality is the "babysitting tax." It's the cognitive overhead of constantly reviewing, reverting, and re-explaining. And it's negating the incredible potential of these tools.
At BrainGrid, we believe the problem isn't the agent—it's the plan. Or the lack thereof. In our rush to generate code, we've skipped the most critical step: creating a shared, deep, and unambiguous understanding of what we're actually building.
"Vibe coding" doesn't work in a multi-tenant system where permissions are non-negotiable, or at least not with peace of mind. It doesn't work in a complex fintech application where money is on the line. And it certainly doesn't work in a four-year-old codebase with layers of tech debt and unwritten rules.
The bottleneck in software development is no longer just the speed of writing code. The bottleneck has shifted to the speed of creating a reliable plan.
BrainGrid is the AI-powered planning platform built to solve this new bottleneck. It's designed to provide the structure and guidance—the "babysitting plan"—that turns powerful but unreliable coding agents into predictable and effective teammates.
Here's how:
### We Give the Agent a Map
BrainGrid starts by deeply analyzing your entire codebase—its architecture, data models, and dependencies. It provides the persistent context that agents desperately need but currently lack.
### We Help You Define the Destination
Our requirements agent acts like a seasoned tech lead, asking you and your team clarifying questions to transform a high-level idea into a detailed, code-aware specification. No more ambiguity.
### We Chart the Course, Step-by-Step
BrainGrid breaks the final requirement down into a series of atomic, verifiable, AI-ready tasks. Each task is a hyper-specific prompt, rich with context and constraints, designed to keep the agent on track and dramatically increase the likelihood of a successful, one-shot execution.
The goal is to get you back to focusing on the hard problems, trusting that the execution of well-defined work is being handled reliably. It's time to trade the babysitting tax for real velocity.
We're onboarding teams from our waitlist now. Join us and let's build the toolchain for reliable agentic development.
---
# Data Processing Addendum
Source: https://www.braingrid.ai/legal/dpa
Last updated: 2025-07-24T00:00:00Z
This Data Processing Addendum ("Addendum") supplements the master agreement (or electronic terms of service, as applicable) entered into by and between BrainGrid AI, Inc. ("Company") and the end customer that executed such agreement with Company ("Customer") ("Agreement"). Customer enters into this Addendum on behalf of itself and, to the extent required under applicable Data Protection Laws (defined below), in the name and on behalf of its Affiliates (defined below), if any. This Addendum incorporates the terms of the Agreement, and any terms not defined in this Addendum shall have the meaning set forth in the Agreement.
## 1. Definitions
1.1 **"Account"** means Customer's account in the Service in which Customer stores and processes Customer Data.
1.2 **"Affiliate"** means (i) an entity of which a party directly or indirectly owns fifty percent (50%) or more of the stock or other equity interest, (ii) an entity that owns at least fifty percent (50%) or more of the stock or other equity interest of a party, or (iii) an entity which is under common control with a party by having at least fifty percent (50%) or more of the stock or other equity interest of such entity and a party owned by the same person, but such entity shall only be deemed to be an Affiliate so long as such ownership exists.
1.3 **"Authorized Sub-Processor"** means a third-party who has a need to know or otherwise access Customer's Personal Data to enable Company to perform its obligations under this Addendum or the Agreement, and who is either (1) listed in Exhibit B or (2) subsequently authorized under Section 4.2 of this Addendum.
1.4 **"Company Account Data"** means personal data that relates to Company's relationship with Customer, including the names or contact information of individuals authorized by Customer to access Customer's Account and billing information of individuals that Customer has associated with its account. Company Account Data also includes any data Company may need to collect for the purpose of managing its relationship with Customer, identity verification, or as otherwise required by applicable laws and regulations.
1.5 **"Company Usage Data"** means Service usage data collected and processed by Company in connection with the provision of the Services, including without limitation data used to identify the source and destination of a communication, activity logs, codebase data, organizational data, and data used to optimize and maintain performance of the Services, and to investigate and prevent system abuse.
1.6 **"Data Exporter"** means Customer.
1.7 **"Data Importer"** means Company.
1.8 **"Data Protection Laws"** means all applicable worldwide legislation relating to data protection and privacy which applies to the respective party in the role of Processing Personal Data under the Agreement, including but not limited to European Data Protection Laws, the California Consumer Privacy Act ("CCPA"), and California Privacy Rights Act 2020 ("CPRA"). The terms "Data Subject", "Personal Data", "Personal Data Breach", "processing", "processor," "controller," and "supervisory authority" shall have the meanings set forth in the GDPR.
1.9 **"ex-EEA Transfer"** means the transfer of Personal Data, which is processed in accordance with the GDPR, from the Data Exporter to the Data Importer (or its premises) outside the European Economic Area (the "EEA"), and such transfer is not governed by an adequacy decision made by the European Commission in accordance with the relevant provisions of the GDPR.
1.10 **"ex-UK Transfer"** means the transfer of Personal Data, which is processed in accordance with the UK GDPR and the Data Protection Act 2018, from the Data Exporter to the Data Importer (or its premises) outside the United Kingdom (the "UK"), and such transfer is not governed by an adequacy decision made by the Secretary of State in accordance with the relevant provisions of the UK GDPR and the Data Protection Act 2018.
1.11 **"Services"** shall have the meaning set forth in the Agreement.
1.12 **"Standard Contractual Clauses"** means the: (i) where the EU GDPR applies, the contractual clauses annexed to the European Commission's Implementing Decision 2021/914 of 4 June 2021 on standard contractual clauses for the transfer of personal data to third countries pursuant to Regulation (EU) 2016/679 of the European Parliament and of the Council ("EU SCCs"); and (ii) where the UK GDPR applies, standard data protection clauses adopted pursuant to or permitted under Article 46 of the UK GDPR ("UK SCCs").
## 2. Relationship of the Parties; Processing of Data
2.1 The parties acknowledge and agree that with regard to the processing of Personal Data, Customer may act either as a controller or processor and, except as expressly set forth in this Addendum or the Agreement, Company is a processor. Customer shall, in its use of the Services, at all times process Personal Data, and provide instructions for the processing of Personal Data, in compliance with Data Protection Laws. Customer shall ensure that the processing of Personal Data in accordance with Customer's instructions will not cause Company to be in breach of the Data Protection Laws. Customer is solely responsible for the accuracy, quality, and legality of (i) the Personal Data provided to Company by or on behalf of Customer, (ii) the means by which Customer acquired any such Personal Data, and (iii) the instructions it provides to Company regarding the processing of such Personal Data. Customer shall not provide or make available to Company any Personal Data in violation of the Agreement or otherwise inappropriate for the nature of the Services, and shall indemnify Company from all claims and losses in connection therewith.
2.2 Company shall not process Personal Data (i) for purposes other than those set forth in the Agreement and/or Exhibit A, (ii) in a manner inconsistent with the terms and conditions set forth in this Addendum or any other documented instructions provided by Customer, including with regard to transfers of personal data to a third country or an international organization, unless required to do so by Supervisory Authority to which the Company is subject; in such a case, the Company shall inform the Customer of that legal requirement before processing, unless that law prohibits such information on important grounds of public interest, or (iii) in violation of Data Protection Laws. Customer hereby instructs Company to process Personal Data in accordance with the foregoing and as part of any processing initiated by Customer in its use of the Services.
2.3 The subject matter, nature, purpose, and duration of this processing, as well as the types of Personal Data collected and categories of Data Subjects, are described in Exhibit A to this Addendum.
2.4 Following completion of the Services, at Customer's choice, Company shall return or delete Customer's Personal Data, unless further storage of such Personal Data is required or authorized by applicable law. If return or destruction is impracticable or prohibited by law, rule or regulation, Company shall take measures to block such Personal Data from any further processing (except to the extent necessary for its continued hosting or processing required by law, rule or regulation) and shall continue to appropriately protect the Personal Data remaining in its possession, custody, or control. If Customer and Company have entered into Standard Contractual Clauses as described in Section 6 (Transfers of Personal Data), the parties agree that the certification of deletion of Personal Data that is described in Clause 12(1) of the UK SCCs and Clause 8.1(d) and Clause 8.5 of the EU SCCs (as applicable) shall be provided by Company to Customer only upon Customer's request.
2.5 **CCPA.** Except with respect to Company Account Data and Company Usage Data, the parties acknowledge and agree that Company is a service provider for the purposes of the CCPA (to the extent it applies) and is receiving personal information from Customer in order to provide the Services pursuant to the Agreement, which constitutes a business purpose. Company shall not sell any such personal information. Company shall not retain, use or disclose any personal information provided by Customer pursuant to the Agreement except as necessary for the specific purpose of performing the Services for Customer pursuant to the Agreement, or otherwise as set forth in the Agreement or as permitted by the CCPA. The terms "personal information," "service provider," "sale," and "sell" are as defined in Section 1798.140 of the CCPA. Company certifies that it understands the restrictions of this Section 2.5. This section applies equally to the CPRA.
## 3. AI-Specific Processing and Codebase Protection
3.1 **AI Processing Definition.** "AI Processing" means the use of Customer's source code, documentation, and related data with artificial intelligence models (including but not limited to large language models from Anthropic and Google) to provide the Services. Company uses AI Processing exclusively to analyze codebases, generate insights, create development specifications, and provide AI-assisted planning capabilities.
3.2 **No Model Training.** Company expressly warrants that Customer Personal Data, including all source code and proprietary information, will NOT be used to train, fine-tune, or otherwise improve any AI models. All AI Processing is performed on an ephemeral basis with no persistent learning from Customer data.
3.3 **Source Code as Protected IP.** The parties acknowledge that Customer's source code constitutes valuable intellectual property and trade secrets. Company shall:
a. Apply the highest level of confidentiality protection to all source code
b. Ensure source code is never exposed to or accessible by other customers
c. Prevent any reconstruction or reverse engineering of source code from AI outputs
d. Process source code solely for the specific Customer's benefit
3.4 **Multi-Tenant Isolation.** Company implements strict isolation between customer environments to ensure:
a. Each Customer's data is processed in isolated sessions
b. AI model responses are not influenced by other customers' data
c. All temporary data and model context is cleared between customer sessions
d. No cross-contamination of insights, patterns, or learnings between customers
3.5 **Purpose Limitation.** Company shall process Customer source code exclusively for:
a. Analyzing code structure, dependencies, and architecture
b. Generating development insights and recommendations
c. Creating AI-ready task specifications and requirements
d. Identifying patterns, best practices, and potential improvements
e. Providing the Services as explicitly requested by Customer
Company shall NOT use Customer source code for:
a. Any purpose beyond the contracted Services
b. Benchmarking or comparative analysis
c. Marketing or promotional materials
d. Training or improving AI models
## 4. Confidentiality
Company shall ensure that any person it authorizes to process Personal Data has agreed to protect Personal Data in accordance with Company's confidentiality obligations in the Agreement. Customer agrees that Company may disclose Personal Data to its advisers, auditors or other third parties as reasonably required in connection with the performance of its obligations under this Addendum, the Agreement, or the provision of Services to Customer.
In the event of any breach by Customer of any of the foregoing, in addition to any other remedies available at law or in equity, Company will have the right to immediately suspend Customer's access to the Platform if deemed necessary by Company to prevent any harm to Company or its business. Company will provide notice to the Customer and an opportunity to cure, if practicable, depending on the nature of the breach. Once cured to Company's satisfaction, Company will restore access to the Platform.
## 5. Authorized Sub-Processors
5.1 Customer acknowledges and agrees that Company may (1) engage its Affiliates and the Authorized Sub-Processors identified on the List (as defined below) to access and process Personal Data in connection with the Services and (2) from time to time engage additional third parties for the purpose of providing the Services, including without limitation the processing of Personal Data. By way of this Addendum, Customer provides general written authorization to Company to engage sub-processors as necessary to perform the Services.
5.2 A list of Company's current Authorized Sub-Processors (the "List") is set forth in Exhibit B. Such List may be updated by Company from time to time on ten (10) days email notice. At least ten (10) days before enabling any third party other than existing Authorized Sub-Processors to access or participate in the processing of Personal Data, Company will add such third party to the List and notify Customer via email. Customer may object to such an engagement by informing Company within ten (10) days of receipt of the aforementioned notice by Customer, provided such objection is in writing and based on reasonable grounds relating to data protection. Customer acknowledges that certain sub-processors are essential to providing the Services and that objecting to the use of a sub-processor may prevent Company from offering the Services to Customer.
5.3 If Customer reasonably objects to an engagement in accordance with Section 5.2, and Company cannot provide a commercially reasonable alternative within a reasonable period of time, Customer may discontinue the use of the affected Service by providing written notice to Company. Discontinuation shall not relieve Customer of any fees owed to Company under the Agreement.
5.4 If Customer does not object to the engagement of a third party in accordance with Section 5.2 within ten (10) days of notice by Company, that third party will be deemed an Authorized Sub-Processor for the purposes of this Addendum.
5.5 Company will enter into a written agreement with the Authorized Sub-Processor imposing on the Authorized Sub-Processor data protection obligations comparable to those imposed on Company under this Addendum with respect to the protection of Personal Data. In case an Authorized Sub-Processor fails to fulfill its data protection obligations under such written agreement with Company, Company will remain liable to Customer for the performance of the Authorized Sub-Processor's obligations under such agreement.
5.6 If Customer and Company have entered into Standard Contractual Clauses as described in Section 7 (Transfers of Personal Data), (i) the above authorizations will constitute Customer's prior written consent to the subcontracting by Company of the processing of Personal Data if such consent is required under the Standard Contractual Clauses, and (ii) the parties agree that the copies of the agreements with Authorized Sub-Processors that must be provided by Company to Customer pursuant to Clause 5(j) of the UK SCCs or Clause 9(c) of the EU SCCs may have commercial information, or information unrelated to the Standard Contractual Clauses or their equivalent, removed by the Company beforehand, and that such copies will be provided by the Company only upon request by Customer.
## 6. Security of Personal Data
Taking into account the state of the art, the costs of implementation and the nature, scope, context and purposes of processing as well as the risk of varying likelihood and severity for the rights and freedoms of natural persons, Company shall maintain appropriate technical and organizational measures to ensure a level of security appropriate to the risk of processing Personal Data. Exhibit C sets forth additional information about Company's technical and organizational security measures.
## 7. Transfers of Personal Data
7.1 **Transfer.** The parties agree that Company may transfer Personal Data processed under this Addendum outside the EEA, the UK, or Switzerland as necessary to provide the Services. Customer acknowledges that Company's primary processing operations take place in the United States, and that the transfer of Customer's Personal Data to the United States is necessary for the provision of the Services to Customer. If Company transfers Personal Data protected under this Addendum to a jurisdiction for which the European Commission has not issued an adequacy decision, Company will ensure that appropriate safeguards have been implemented for the transfer of Personal Data in accordance with Data Protection Laws.
7.2 **Restricted Transfers.** Customer will operate as a data Controller and Company will operate as a data Processor, Processing Customer Personal Data only as necessary for the limited and specified purposes identified in the Agreement, and in accordance with at least the same level of protection as is required under the applicable Data Protection Law(s). To the extent Company Processes any Customer Personal Data subject to the EU GDPR or UK GDPR under the Agreement, any such transfer will be subject to the EU SCCs or UK SCCs, as applicable and as set forth under Section 7.3 and 7.5 below. Customer authorizes Company and its Sub-Processors to make international transfers of Customer Personal Data in accordance with this DPA so long as applicable Data Protection Laws for such transfers are respected.
7.3 **Transfers from the EEA.** With respect to Customer Personal Data transferred from the European Economic Area ("EEA"), the EU SCCs incorporated herein shall apply, form part of this DPA, and take precedence over the rest of this DPA as set forth in the EU SCCs. They will be deemed completed as follows:
a. Where Customer is a data exporter and controller, and Company is a data importer and processor, Module 2 shall apply. When Customer is a data exporter and processor, and Company is a data importer and subprocessor, Module 3 shall apply. References to Modules 1 and 4 in the EU SCCs shall not apply and language referencing these modules shall not be treated as part of this DPA.
b. Clause 7, the "Docking Clause (Optional)", will be deemed incorporated.
c. Under Clause 9 (Use of sub‐processors), the Parties select Option 2 (general written authorization), and the time period for prior notice of addition or replacement of Sub‐Processors will be set forth in Section 4.2 of this DPA.
d. Under Clause 11 (Redress), the optional requirement that data subjects be permitted to lodge a complaint with an independent dispute resolution body does not apply.
e. Under Clause 17 (Governing law), the Parties choose Option 1 (the law of an EU Member State that allows for third‐party beneficiary rights). The Parties select the law of Ireland.
f. Under Clause 18 (Choice of forum and jurisdiction), the Parties select the courts of Ireland.
g. Annexes I-III are set forth below as Exhibit A, B, and C.
h. By entering into this DPA, the Parties are deemed to be signing the EU SCCs and its applicable Annexes.
7.4 **Transfers From Switzerland.** With respect to Personal Data transferred from Switzerland for which Swiss law (and not the law in any EEA jurisdiction) governs the international nature of the transfer, references to the EU GDPR in Clause 4 of the EU SCCs are, to the extent legally required, amended to refer to the Swiss Federal Data Protection Act or its successor instead, and the concept of supervisory authority shall include the Swiss Federal Data Protection and Information Commissioner.
7.5 **Transfers from the UK.** With respect to Personal Data transferred from the United Kingdom for which United Kingdom law (and not the law in any EEA jurisdiction) governs the international nature of the transfer, the UK SCCs form part of this DPA and take precedence over the rest of this DPA as set forth in the UK SCCs, unless the United Kingdom issues updates to the UK SCCs that, upon notice from Customer, will control. Undefined capitalized terms used in this provision shall mean the definitions in the UK Standard Contractual Clauses. For purposes of the UK Standard Contractual Clauses, they shall be deemed completed as follows:
a. Table 1 of the UK SCCs: (1) the Parties' details shall be the Parties and their Affiliates to the extent any of them is involved in such transfer, including those set forth in Annex 1; (2) the Key Contact shall be the contacts set forth in Annex 1.
b. Table 2 of the UK SCCs: The Approved EU SCCs referenced in Table 12 shall be the EU SCCs as executed by the Parties.
c. Table 3 of the UK SCCs: Annex 1A, 1B, and II shall be set forth in Annex 1 and Annex 2 hereto.
d. Table 4 of the UK SCCs: Company may end this DPA as set out in Section 19 of the UK SCCs.
e. By entering into this DPA, the Parties are deemed to be signing the UK SCCs and its applicable Tables and Appendix Information.
7.6 **Statutory Revisions to the EU SCCs or UK SCCs.** In the event that the EU GDPR or UK GDPR require the use of revised standard contractual clauses applicable to this DPA, such revised standard contractual clauses shall automatically be deemed to replace the EU SCCs and/or UK SCCs, as applicable, without the need for any further action, unless Company otherwise informs Customer.
7.7 **Impact Assessment.** To the extent required by European Data Protection Laws, Company will provide reasonable assistance to Customer with any data protection impact assessments and prior consultations with supervisory authorities. Customer will be responsible to the extent legally permitted for any costs and expenses arising from any assistance by Company.
## 8. Rights of Data Subjects
8.1 Company shall, to the extent permitted by law, notify Customer upon receipt of a request by a Data Subject to exercise the Data Subject's right of: access, rectification, erasure, data portability, restriction or cessation of processing, withdrawal of consent to processing, and/or objection to being subject to processing that constitutes automated decision-making (such requests individually and collectively "Data Subject Request(s)"). If Company receives a Data Subject Request in relation to Customer's data, Company will advise the Data Subject to submit their request to Customer and Customer will be responsible for responding to such request, including, where necessary, by using the functionality of the Services. Customer is solely responsible for ensuring that Data Subject Requests for erasure, restriction or cessation of processing, or withdrawal of consent to processing of any Personal Data are communicated to Company, and, if applicable, for ensuring that a record of consent to processing is maintained with respect to each Data Subject.
8.2 Company shall, at the request of the Customer, and taking into account the nature of the processing applicable to any Data Subject Request, apply appropriate technical and organizational measures to assist Customer in complying with Customer's obligation to respond to such Data Subject Request and/or in demonstrating such compliance, where possible, provided that (i) Customer is itself unable to respond without Company's assistance and (ii) Company is able to do so in accordance with all applicable laws, rules, and regulations. Customer shall be responsible to the extent legally permitted for any costs and expenses arising from any such assistance by Company.
## 9. Actions and Access Requests; Audits
9.1 Company shall, taking into account the nature of the processing and the information available to Company, provide Customer with reasonable cooperation and assistance where necessary for Customer to comply with its obligations under the GDPR to conduct a data protection impact assessment and/or to demonstrate such compliance, provided that Customer does not otherwise have access to the relevant information. Customer shall be responsible to the extent legally permitted for any costs and expenses arising from any such assistance by Company.
9.2 Company shall, taking into account the nature of the processing and the information available to Company, provide Customer with reasonable cooperation and assistance with respect to Customer's cooperation and/or prior consultation with any Supervisory Authority, where necessary and where required by the GDPR. Customer shall be responsible to the extent legally permitted for any costs and expenses arising from any such assistance by Company.
9.3 Company shall maintain records sufficient to demonstrate its compliance with its obligations under this Addendum, and retain such records for a period of three (3) years after the termination of the Agreement. Customer shall, with reasonable notice to Company, have the right to review, audit and copy such records at Company's offices during regular business hours.
9.4 Upon Customer's written request at reasonable intervals, and subject to reasonable confidentiality controls, Company shall, either (i) make available for Customer's review copies of certifications or reports demonstrating Company's compliance with prevailing data security standards applicable to the processing of Customer's Personal Data, or (ii) if the provision of reports or certifications pursuant to (i) is not reasonably sufficient under Data Protection Laws, allow Customer's independent third party representative to conduct an audit or inspection of Company's data security infrastructure and procedures that is sufficient to demonstrate Company's compliance with its obligations under Data Protection Laws, provided that (a) Customer provides reasonable prior written notice of any such request for an audit and such inspection shall not be unreasonably disruptive to Company's business; (b) such audit shall only be performed during business hours and occur no more than once per calendar year; and (c) such audit shall be restricted to data relevant to Customer. Customer shall be responsible for the costs of any such audits or inspections, including without limitation a reimbursement to Company for any time expended for on-site audits. If Customer and Company have entered into Standard Contractual Clauses as described in Section 7 (Transfers of Personal Data), the parties agree that the audits described in Clause 5(f) and Clause 12(2) of the UK SCCs and Clause 8.9 of the EU SCCs shall be carried out in accordance with this Section 9.4.
9.5 Company shall immediately notify Customer if an instruction, in the Company's opinion, infringes the Data Protection Laws or Supervisory Authority.
9.6 In the event of a Personal Data Breach, Company shall, without undue delay, inform Customer of the Personal Data Breach and take such steps as Company in its sole discretion deems necessary and reasonable to remediate such violation (to the extent that remediation is within Company's reasonable control).
9.7 In the event of a Personal Data Breach, Company shall, taking into account the nature of the processing and the information available to Company, provide Customer with reasonable cooperation and assistance necessary for Customer to comply with its obligations under the GDPR with respect to notifying (i) the relevant Supervisory Authority and (ii) Data Subjects affected by such Personal Data Breach without undue delay.
9.8 The obligations described in Sections 9.6 and 9.7 shall not apply in the event that a Personal Data Breach results from the actions or omissions of Customer. Company's obligation to report or respond to a Personal Data Breach under Sections 9.6 and 9.7 will not be construed as an acknowledgement by Company of any fault or liability with respect to the Personal Data Breach.
## 10. Company's Role as a Controller
The parties acknowledge and agree that with respect to Company Account Data and Company Usage Data, Company is an independent controller, not a joint controller with Customer. Company will process Company Account Data and Company Usage Data as a controller (i) to manage the relationship with Customer; (ii) to carry out Company's core business operations, such as accounting, audits, tax preparation and filing and compliance purposes; (iii) to monitor, investigate, prevent and detect fraud, security incidents and other misuse of the Services, and to prevent harm to Customer; (iv) for identity verification purposes; (v) to comply with legal or regulatory obligations applicable to the processing and retention of Personal Data to which Company is subject; and (vi) as otherwise permitted under Data Protection Laws and in accordance with this Addendum and the Agreement. Company may also process Company Usage Data as a controller to provide, optimize, and maintain the Services, to the extent permitted by Data Protection Laws.
## 11. Conflict
In the event of any conflict or inconsistency among the following documents, the order of precedence will be: (1) the applicable terms in the Standard Contractual Clauses; (2) the terms of this Addendum; and (3) the Agreement. Any claims brought in connection with this Addendum will be subject to the terms and conditions, including, but not limited to, the exclusions and limitations set forth in the Agreement.
---
## Exhibit A: Details of Processing
### Categories of data subjects whose personal data is transferred
The subjects that the customer elects to connect into BrainGrid.
### Categories of personal data transferred
The categories that the customer elects to connect into BrainGrid.
### Sensitive data transferred (if applicable) and applied restrictions or safeguards
Any sensitive data that the customer elects to connect into BrainGrid.
### The frequency of the transfer
Continuous
### Duration of the processing
During the term of the Agreement
### Nature of the processing
The data importer will process Customer Personal Data to provide, secure and monitor the Services for Customer.
### Purpose(s) of the data transfer and further processing
Company will process Personal Data as necessary to provide the Services pursuant to the Agreement and as further instructed by Customer in Customer's use of the Services.
### For transfers to (sub-) processors, also specify subject matter, nature and duration of the processing
As above
---
## Exhibit B: Sub-processors
BrainGrid uses the following Sub-processors to provide the Services:
| Sub-processor | Purpose | Location (Entity) |
| --- | --- | --- |
| **WorkOS** | User Authentication & Organization Management | USA |
| **Vercel** | Application Hosting & Blob/File Storage | USA |
| **Supabase** | Primary Database Hosting | USA |
| **Upstash / Redis** | Caching, Session Management, Queues, Rate Limiting | USA |
| **GitHub** | Code Repository Integration & App Hosting | USA |
| **Slack** | Communication Platform Integration | USA |
| **Linear** | Project Management Integration | USA |
| **Anthropic** | AI Model Processing and Token Calculation | USA / UK |
| **OpenAI** | AI Model Processing and Token Calculation | USA |
| **Resend** | Transactional Email Delivery | USA |
| **MaxMind** | IP Geolocation Services for Analytics | USA |
| **Google Cloud Platform** | AI Models and Cloud Computing Infrastructure | USA |
| **Exa** | Search / Data Retrieval API | USA |
| **AWS** | AI Models and Cloud Computing Infrastructure | USA |
| **Microsoft Azure** | AI Models and Cloud Computing Infrastructure | USA |
---
## Exhibit C: Technical and Organizational Security Measures
Description of the Technical and Organizational Security Measures implemented by the Data Importer. The following includes the information required by Annex II of the EU SCCs and Appendix 2 of the UK SCCs.
| Technical and Organizational Security Measure | Details |
| --- | --- |
| Measures of pseudonymisation and encryption of personal data | We are doing encryption of data at rest using AES 256 standards. |
| Measures for ensuring ongoing confidentiality, integrity, availability and resilience of processing systems and services | Infrastructure is architected and designed with high availability in mind using cloud service provider having geographically distribution capability in the same region. |
| Measures for ensuring the ability to restore the availability and access to personal data in a timely manner in the event of a physical or technical incident | Data is backed up daily. |
| Processes for regularly testing, assessing and evaluating the effectiveness of technical and organizational measures in order to ensure the security of the processing | We are in the process of SOC2 and overall security and certification program implementation. We do not use any customer data for our testing program. We engage with third party for doing periodic penetration and security testing at least annually. |
| Measures for user identification and authorization | We use hardware-based Yubikey MFA for employees accessing managed cloud services. We use OAuth 2.0 Client Credentials for API Token management. |
| Measures for the protection of data during transmission | Yes, we encrypt the data during external transmission using SSL/TLS v1.2 |
| Measures for the protection of data during storage | We are doing encryption of data at rest using AES 256 standards. |
| Measures for ensuring physical security of locations at which personal data are processed | We are utilizing AWS for physical security and monitoring for hosting our Infrastructure. |
| Measures for ensuring events logging | We are leveraging Honeycomb, Sentry and AWS for events logging. |
| Measures for ensuring system configuration, including default configuration | We leverage standard configuration management process along with change management policies and procedures. |
| Measures for internal IT and IT security governance and management | We are in the process of SOC2 and overall security and certification program implementation. |
| Measures for certification/assurance of processes and products | We are in the process of SOC2 and overall security and certification program implementation. |
| Measures for ensuring data quality | Platform is tested with various techniques to ensure quality results gets produced. |
| Measures for ensuring limited data retention | We have data retention and disposal policies, procedures, controls in place. |
| Measures for ensuring accountability | We have Access Control, Corporate Ethics, Whistle Blower, Privacy, Acceptable Use, Security Operation policies, procedures and controls |
| Measures for allowing data portability and ensuring erasure | We have a procedure in place with our Cloud provider for customer data erasure. Data portability procedure is in place and implementation pending. |
| Technical and organizational measures of sub-processors | We have a vendor management process in place with our sub processors. |
---
# Privacy Policy
Source: https://www.braingrid.ai/legal/privacy
Last updated: 2025-07-24T00:00:00Z
BrainGrid AI, Inc. ("BrainGrid", "we", "us", or "our") is committed to protecting your privacy. This Privacy Policy explains how we collect, use, disclose, and safeguard your information when you use our AI-powered development planning platform and related services (collectively, the "Services").
By using our Services, you agree to the collection and use of information in accordance with this Privacy Policy. If you do not agree with the terms of this Privacy Policy, please do not access or use our Services.
## 1. Information We Collect
### 1.1 Information You Provide to Us
**Account Information**
- Name and email address
- Company name and size
- Job title and role
- Password (encrypted)
- Phone number (optional)
- Billing and payment information
**User Content**
- Project requirements and specifications
- Task descriptions and planning documents
- Communications with our team
- Feedback and feature requests
- Any other content you submit through the Services
**Code and Repository Data**
- Repository metadata (structure, file names, patterns)
- Code snippets shared for context
- Integration configurations
- Access tokens for connected services (encrypted)
### 1.2 Information We Collect Automatically
**Usage Information**
- Features accessed and actions taken
- Time spent on different sections
- Interaction patterns with AI agents
- Performance metrics and error logs
**Device and Technical Information**
- IP address and approximate location
- Browser type and version
- Operating system
- Device identifiers
- Referral URLs
- Network and connection information
**Cookies and Tracking Technologies**
We use cookies and similar tracking technologies to:
- Maintain your session
- Remember your preferences
- Analyze usage patterns
- Improve our Services
## 2. How We Process Your Code
### 🛡️ Your Code Stays Yours
We process your code with the highest level of care:
- 🔒 **No Training on Your Code:** We never use your proprietary code to train AI models. Your code is processed only to provide you with our Services.
- 💾 **Ephemeral Processing:** Code analysis happens in isolated, temporary environments that are destroyed after processing.
- 👥 **Multi-Tenant Isolation:** Your code is completely isolated from other customers' data with enterprise-grade security boundaries.
- 🔑 **You Own Your IP:** You retain all rights, title, and interest in your code and any derived insights.
## 3. How We Use Your Information
We use the collected information for the following purposes:
### 3.1 Service Delivery
- Provide AI-powered planning and requirement generation
- Analyze your codebase to generate contextual insights
- Create and manage development tasks and specifications
- Enable integrations with your development tools
### 3.2 Communication
- Send service-related notifications
- Respond to your inquiries and support requests
- Provide updates about new features (with your consent)
- Send security alerts and important notices
### 3.3 Improvement and Analytics
- Enhance our AI models and algorithms (without using your code)
- Analyze usage patterns to improve user experience
- Debug issues and improve performance
- Develop new features based on aggregated usage data
### 3.4 Security and Compliance
- Detect and prevent fraudulent activity
- Monitor for security threats
- Comply with legal obligations
- Enforce our Terms of Service
## 4. Information Sharing
We are committed to maintaining your trust, and we want you to understand when and with whom we may share your information.
### 4.1 Service Providers
We share information with third-party service providers that help us operate our Services:
- **AI Model Providers**: Anthropic and Google (for Gemini) - to process your requests through their AI models
- **Infrastructure**: Vercel, Google Cloud Platform (GCP), Microsoft Azure (Azure), and Amazon Web Services (AWS) - for secure cloud hosting
- **Payment Processing**: Stripe - for billing and payments
- **Analytics**: For understanding usage patterns (anonymized data only)
- **Communication**: For email and in-app messaging
All service providers are contractually obligated to protect your information and use it only for providing services to us.
### 4.2 Legal Requirements
We may disclose your information if required to do so by law or in response to:
- Court orders or subpoenas
- Government or regulatory requests
- To protect our rights, privacy, safety, or property
- To enforce our Terms of Service
### 4.3 Business Transfers
In the event of a merger, acquisition, reorganization, or sale of assets, your information may be transferred. We will notify you via email and/or prominent notice on our Services of any change in ownership or uses of your information.
### 4.4 With Your Consent
We may share your information for any other purpose with your explicit consent.
## 5. Data Security
We implement comprehensive security measures to protect your information:
### 5.1 Technical Safeguards
- **Encryption**: All data is encrypted in transit (TLS 1.3+) and at rest (AES-256)
- **Access Controls**: Role-based access with mandatory multi-factor authentication
- **Network Security**: Firewalls, intrusion detection, and DDoS protection
- **Secure Development**: Regular security testing and code reviews
### 5.2 Organizational Measures
- Employee security training and background checks
- Strict access controls and need-to-know basis
- Incident response procedures with defined escalation paths
- Regular third-party security audits and penetration testing
### 5.3 Breach Notification
In the event of a data breach that may impact your information, we will:
- Notify affected users within 72 hours of discovery
- Provide details about what information was involved
- Explain steps we're taking to address the breach
- Offer guidance on protective measures you can take
## 6. Your Rights and Choices
### 6.1 Access and Control
You have the right to:
- **Access**: Request a copy of your personal information
- **Correction**: Update or correct inaccurate information
- **Deletion**: Request deletion of your account and associated data
- **Portability**: Export your data in a machine-readable format
- **Restriction**: Limit how we process your information
- **Object**: Opt-out of certain uses of your information
### 6.2 Communication Preferences
- **Marketing**: Opt-out of marketing emails via the unsubscribe link
- **Notifications**: Manage notification preferences in your account settings
- **Cookies**: Adjust browser settings to refuse cookies
### 6.3 Account Deletion
You can delete your account at any time by requesting it. Upon deletion:
- Your personal information will be removed within 30 days
- Some information may be retained for legal or legitimate business purposes
- Anonymized data may be retained for analytics
## 7. Data Retention
We retain your information for as long as necessary to:
- Provide our Services to you
- Comply with legal obligations
- Resolve disputes and enforce agreements
- Maintain security and prevent fraud
Specific retention periods:
- **Account Information**: Duration of account plus 90 days
- **User Content**: Duration of account plus 30 days
- **Usage Logs**: 12 months
- **Security Logs**: 3 months
- **Billing Records**: 7 years (legal requirement)
## 8. International Data Transfers
Our Services are hosted in the United States. If you access our Services from outside the United States, your information will be transferred to and processed in the United States.
We ensure appropriate safeguards for international transfers through:
- Standard Contractual Clauses approved by the European Commission
- Data Processing Agreements with all sub-processors
- Compliance with Privacy Shield principles (where applicable)
## 9. Regional Privacy Rights
### 9.1 European Economic Area (GDPR)
If you are located in the EEA, you have additional rights:
**Legal Basis for Processing**
- Contract performance (to provide our Services)
- Legitimate interests (security, fraud prevention, improvement)
- Consent (for marketing communications)
- Legal obligations
**Additional Rights**
- Right to lodge a complaint with supervisory authorities
- Right to withdraw consent at any time
- Right to object to processing based on legitimate interests
### 9.2 California (CCPA/CPRA)
California residents have additional rights:
- Right to know what personal information we collect
- Right to know if we sell or share personal information (we don't)
- Right to opt-out of sale (not applicable as we don't sell data)
- Right to limit use of sensitive personal information
- Right to non-discrimination for exercising privacy rights
To exercise these rights, contact BrainGrid.
### 9.3 Other Jurisdictions
We respect privacy rights under applicable laws in all jurisdictions where we operate. Contact us for information about your specific rights.
## 10. Children's Privacy
Our Services are not intended for individuals under the age of 18. We do not knowingly collect personal information from children. If we learn we have collected information from a child, we will delete it promptly.
## 11. Third-Party Links
Our Services may contain links to third-party websites or services. We are not responsible for the privacy practices of these third parties. We encourage you to review their privacy policies.
## 12. Changes to This Privacy Policy
We may update this Privacy Policy from time to time. We will notify you of material changes by:
- Posting the new Privacy Policy on this page
- Updating the "Last Updated" date
- Sending email notification for significant changes
Your continued use of our Services after changes constitutes acceptance of the updated Privacy Policy.
## 13. Contact Us
If you have questions about this Privacy Policy or our privacy practices, please contact us.
**Response Time**: We aim to respond to all privacy inquiries within 30 days.
---
# Security Policy
Source: https://www.braingrid.ai/legal/security
Last updated: 2025-01-15T00:00:00Z
At BrainGrid, security is fundamental to everything we do. This policy outlines our comprehensive approach to protecting your data, our infrastructure, and maintaining the trust you place in us.
## 1. Security Principles
Our security program is built on four core principles:
- **Defense in Depth**: Multiple layers of security controls to protect against various threat vectors
- **Least Privilege**: Access granted only as needed for specific roles and responsibilities
- **Zero Trust**: Continuous verification of all users, devices, and applications
- **Continuous Monitoring**: Real-time threat detection and response capabilities
## 2. Infrastructure Security
Our infrastructure is designed with security at its core:
- All services hosted in SOC 2 compliant data centers
- End-to-end encryption for data in transit and at rest
- Web Application Firewall (WAF) and DDoS protection
- Hardware Security Modules (HSMs) for cryptographic operations
## 3. Data Protection
### Encryption Standards
- AES-256 encryption for data at rest
- TLS 1.3 for all data in transit
- RSA-4096 for key exchange
- Regular key rotation and management
### Data Classification
We classify data based on sensitivity and apply appropriate controls:
- **Public**: Information intended for public consumption
- **Internal**: Non-sensitive business information
- **Confidential**: Sensitive business and customer data
- **Restricted**: Highly sensitive data requiring maximum protection
## 4. Access Control
We implement strict access controls to protect your data:
- Multi-factor authentication (MFA) required for all accounts
- Role-based access control (RBAC) with regular reviews
- Automated de-provisioning for terminated employees
- Privileged access management (PAM) for administrative accounts
!
Security Operations
### 24/7 Security Monitoring
- Security Information and Event Management (SIEM)
- Intrusion Detection and Prevention Systems (IDS/IPS)
- Automated threat intelligence feeds
- Real-time alerting and response
### Incident Response
- Dedicated incident response team
- Defined escalation procedures
- Regular tabletop exercises
- Post-incident reviews and improvements
## 5. Application Security
Our software development lifecycle incorporates security at every stage:
- Secure coding standards and guidelines
- Static and dynamic code analysis
- Dependency scanning and management
- Regular penetration testing
- Security code reviews
- Bug bounty program
## 6. Physical Security
Our data centers maintain comprehensive physical security measures:
- 24/7 on-site security personnel
- Biometric access controls
- CCTV surveillance with 90-day retention
- Environmental monitoring and controls
- Redundant power and cooling systems
## 7. Employee Security
All BrainGrid employees undergo:
- Background checks before employment
- Security awareness training upon hire and annually
- Signed confidentiality agreements
- Regular phishing simulations and training
## 8. Business Continuity
We maintain comprehensive disaster recovery and business continuity plans:
- Automated daily backups with geographic redundancy
- Recovery Time Objective (RTO) of 4 hours
- Recovery Point Objective (RPO) of 1 hour
- Annual disaster recovery testing
- Documented runbooks and procedures
## 9. Compliance and Auditing
We maintain compliance with industry standards and undergo regular audits:
- Annual third-party security assessments
- Quarterly vulnerability assessments
- Continuous compliance monitoring
- Regular internal audits
!
Reporting Security Issues
If you discover a security vulnerability, please report it responsibly:
- Email: [security@braingrid.ai](mailto:security@braingrid.ai)
- PGP Key available at: [/security.asc](/security.asc)
We appreciate responsible disclosure and will acknowledge your report within 24 hours.
## 10. Contact Information
For security-related questions or concerns:
- Security Team: [security@braingrid.ai](mailto:security@braingrid.ai)
- Chief Security Officer: [cso@braingrid.ai](mailto:cso@braingrid.ai)
---
# Terms of Service
Source: https://www.braingrid.ai/legal/terms
Last updated: 2025-07-24T00:00:00Z
These Terms of Service ("Terms") constitute a legal agreement between you and BrainGrid AI, Inc. ("BrainGrid", "we", "us", or "our") governing your access to and use of our AI-powered development planning platform, including our website, applications, and related services (collectively, the "Services").
By accessing or using our Services, you acknowledge that you have read, understood, and agree to be bound by these Terms. If you do not agree to these Terms, do not access or use our Services.
## 1. Definitions
- **"Account"** means your BrainGrid account created to access the Services
- **"AI Models"** means the artificial intelligence models used to provide the Services, including those from Anthropic, OpenAI and Google
- **"Customer Content"** means any data, code, text, or other materials you upload, submit, or otherwise provide to the Services
- **"Documentation"** means our user guides, API documentation, and other instructional materials
- **"Effective Date"** means the date you first access or use the Services
- **"Outputs"** means any content generated by the Services based on your inputs
- **"Platform"** means our software platform and all associated tools and features
- **"Order Form"** means any order form referencing and incorporating these Terms, which shall be in writing, signed by both Parties, and shall specify the products or services to be purchased or licensed by Customer from BrainGrid
- **"Service Term"** means the period of time indicated in an Order Form beginning upon an Order Effective Date and ending on the last day of the Service Term set forth in the Order Form
## 2. Acceptance and Account Terms
### 2.1 Eligibility
You must be at least 18 years old and have the legal capacity to enter into these Terms. If you're using the Services on behalf of an organization, you represent that you have authority to bind that organization to these Terms.
### 2.2 Account Registration
To use certain features of our Services, you must create an Account. You agree to:
- Provide accurate, current, and complete information
- Maintain and update your information to keep it accurate
- Keep your password secure and confidential
- Accept responsibility for all activities under your Account
- Immediately notify us of any unauthorized use
## 3. Description of Services
BrainGrid provides an AI-powered development planning platform that helps software teams transform ideas into actionable, AI-ready specifications. Our Services include:
- **Codebase Analysis**: Automated analysis of your code repository structure and patterns
- **Requirement Generation**: AI-assisted creation of detailed development specifications
- **Task Planning**: Breaking down requirements into atomic, verifiable tasks
- **AI Agent Integration**: Tools to work with AI coding assistants
- **Collaboration Features**: Team workspaces and sharing capabilities
We continuously improve and may modify the Services. Features may be added, changed, or removed at our discretion.
## 4. Use of Services
### 4.1 Access to Services
Subject to Customer's compliance with the terms and conditions hereof, during the Service Term set forth in the applicable Order Form, BrainGrid hereby grants to the Customer a non-exclusive, non-sublicensable, non-transferrable right to internally access and use the Platform for Customer's own benefit (and only in accordance with all documentation provided by BrainGrid).
### 4.2 Restrictions
You agree not to:
- Use the Services for any illegal or unauthorized purpose
- Violate any applicable laws or regulations
- Infringe on any third-party intellectual property rights
- Transmit any malicious code, viruses, or harmful content
- Attempt to gain unauthorized access to any systems or data
- Reverse engineer, decompile, or disassemble any part of the Services
- Use the Services to develop a competing product or service
- Scrape, harvest, or collect data from the Services through automated means
- Resell, sublicense, or provide the Services to third parties
- Circumvent any usage limits or restrictions
- Use the Services in a manner that could damage or overburden our infrastructure
### 4.3 Usage Limits
Your use of the Services is subject to usage limits based on your account type. Exceeding these limits may result in additional charges or service suspension.
## 5. Customer Content and Code
### 5.1 Ownership
You retain all rights, title, and interest in and to your Customer Content. We do not claim ownership of any Customer Content you submit to the Services.
### 5.2 License to BrainGrid
By using the Services, you hereby grant to BrainGrid, its affiliates, successors, and assigns a non-exclusive, worldwide, royalty-free, fully paid, sublicensable (solely for the purposes of providing the Services to you), transferable license to reproduce, distribute, modify, and otherwise use, display, and perform all acts with respect to the Customer Data and Code as may be necessary for BrainGrid to provide the Services to you. You hereby represent and warrant that: (i) you have all necessary rights to grant BrainGrid the license set forth in this section, and to allow BrainGrid to exercise its rights under such license without infringement of the rights of any third party, including privacy rights; and (ii) BrainGrid's receipt and processing of Customer Data and Code in accordance with this Agreement does not and will not violate any applicable laws or regulations.
### 5.3 AI Processing and No Training Commitment
#### 🔒 Your Code is Never Used for Training
We make the following commitments regarding your code and data:
- ✅ **No Model Training:** We never use your Customer Content to train, improve, or develop AI models. Your code remains exclusively yours.
- 💾 **Ephemeral Processing:** Your code is processed only for the duration needed to provide you with Services and is not persistently stored for analysis.
- 👥 **Isolated Processing:** Each customer's data is processed in isolation and never mixed with other customers' data.
### 5.4 Outputs
Outputs generated by the Services based on your Customer Content are considered your property. You may use Outputs for any lawful purpose, subject to these Terms.
### 5.5 Feedback
If you provide feedback, suggestions, or ideas about the Services ("Feedback"), you grant us an unlimited, irrevocable, perpetual, royalty-free license to use such Feedback for any purpose without compensation to you.
## 6. Intellectual Property
### 6.1 BrainGrid Property
The Services, including all software, algorithms, user interfaces, designs, Documentation, and other materials, are owned by BrainGrid or our licensors and are protected by intellectual property laws. All rights not expressly granted to you are reserved.
### 6.2 Trademarks
"BrainGrid" and our logos are our trademarks. You may not use our trademarks without prior written permission, except as necessary to describe the Services for your internal business purposes.
### 6.3 Third-Party Services
The Services may include or integrate with third-party services, including AI models from Anthropic and Google. Your use of such third-party services is subject to their respective terms and conditions.
## 7. Privacy and Data Protection
Your use of our Services is subject to our Privacy Policy, which is incorporated into these Terms by reference. By using the Services, you consent to our collection, use, and disclosure of information as described in the Privacy Policy.
We implement industry-standard security measures to protect your data. However, no method of transmission or storage is 100% secure, and we cannot guarantee absolute security.
## 8. Payment Terms
### 8.1 Subscription Fees
If you purchase a paid subscription:
- You agree to pay all applicable fees as described in your subscription plan
- Fees are billed in advance on a monthly or annual basis
- All fees are in U.S. dollars unless otherwise specified
### 8.2 Payment Processing
- Payment processing is handled by our third-party payment processor (Stripe)
- You authorize us to charge your payment method for all fees
- You are responsible for keeping your billing information current
### 8.3 Taxes
Fees do not include taxes. You are responsible for all applicable taxes, and we will charge tax when required by law.
### 8.4 Refunds
All fees are non-refundable except:
- As required by applicable law
- As explicitly stated in a separate agreement
- For annual subscriptions cancelled within 14 days of initial purchase
### 8.5 Free Trials and Credits
We may offer free trials or credits. At the end of a free trial, you will be automatically charged unless you cancel before the trial ends.
## 9. Warranties and Disclaimers
### 9.1 Service Availability
While we strive for high availability, we do not guarantee that the Services will be available at all times or without interruption. We may experience downtime for maintenance, updates, or unforeseen issues.
### 9.2 Disclaimer of Warranties
**⚠️ IMPORTANT DISCLAIMERS:**
THE SERVICES ARE PROVIDED "AS IS" AND "AS AVAILABLE" WITHOUT WARRANTIES OF ANY KIND, WHETHER EXPRESS, IMPLIED, OR STATUTORY. TO THE MAXIMUM EXTENT PERMITTED BY LAW, BRAINGRID DISCLAIMS ALL WARRANTIES INCLUDING:
- MERCHANTABILITY
- FITNESS FOR A PARTICULAR PURPOSE
- NON-INFRINGEMENT
- ACCURACY OR RELIABILITY OF OUTPUTS
- UNINTERRUPTED OR ERROR-FREE SERVICE
- SECURITY OF YOUR DATA
WE DO NOT WARRANT THAT THE SERVICES WILL MEET YOUR REQUIREMENTS OR THAT OUTPUTS WILL BE ACCURATE, COMPLETE, OR SUITABLE FOR YOUR INTENDED USE.
### 9.3 AI Limitations
You acknowledge that:
- AI-generated Outputs may contain errors or inaccuracies
- Outputs should be reviewed and validated before use
- We are not responsible for your use of or reliance on Outputs
- The Services are tools to assist, not replace, human judgment
## 10. Limitation of Liability
NOTWITHSTANDING ANYTHING TO THE CONTRARY IN THIS AGREEMENT, IN NO EVENT WILL EITHER PARTY BE LIABLE UNDER OR IN CONNECTION WITH THIS AGREEMENT UNDER ANY LEGAL OR EQUITABLE THEORY, INCLUDING BREACH OF CONTRACT, TORT (INCLUDING NEGLIGENCE), STRICT LIABILITY, AND OTHERWISE, FOR ANY: (A) CONSEQUENTIAL, INCIDENTAL, INDIRECT, EXEMPLARY, SPECIAL, ENHANCED, OR PUNITIVE DAMAGES; (B) INCREASED COSTS, DIMINUTION IN VALUE OR LOST BUSINESS, PRODUCTION, REVENUES, OR PROFITS; (C) LOSS OF GOODWILL OR REPUTATION; (D) USE, INABILITY TO USE, LOSS, INTERRUPTION, DELAY OR RECOVERY OF ANY DATA, OR BREACH OF DATA OR SYSTEM SECURITY; OR (E) COST OF REPLACEMENT GOODS OR SERVICES, IN EACH CASE REGARDLESS OF WHETHER THE PARTY WAS ADVISED OF THE POSSIBILITY OF SUCH LOSSES OR DAMAGES OR SUCH LOSSES OR DAMAGES WERE OTHERWISE FORESEEABLE. NOTWITHSTANDING ANYTHING TO THE CONTRARY IN THIS AGREEMENT, IN NO EVENT WILL EITHER PARTY'S AGGREGATE LIABILITY ARISING OUT OF OR RELATED TO ANY CLAIM ARISING IN CONNECTION WITH THIS AGREEMENT UNDER ANY LEGAL OR EQUITABLE THEORY, INCLUDING BREACH OF CONTRACT, TORT (INCLUDING NEGLIGENCE) AND STRICT LIABILITY, EXCEED THE TOTAL AMOUNTS PAID TO BRAINGRID UNDER THIS AGREEMENT IN THE SIX MONTH PERIOD PRECEDING THE EVENT GIVING RISE TO THE CLAIM.
## 11. Indemnification
You agree to indemnify, defend, and hold harmless BrainGrid, our affiliates, and our respective officers, directors, employees, and agents from and against any claims, liabilities, damages, losses, costs, and expenses (including reasonable attorneys' fees) arising from:
- Your use of the Services
- Your violation of these Terms
- Your violation of any third-party rights
- Your Customer Content
- Any products or services developed using the Services
## 12. Termination
### 12.1 Termination by You
You may terminate your Account at any time by:
- Contacting our support team
### 12.2 Termination by BrainGrid
We may suspend or terminate your access to the Services:
- For violation of these Terms
- For non-payment of fees
- For extended inactivity
- If required by law
- At our discretion with 30 days' notice
### 12.3 Effect of Termination
Upon termination:
- Your access to the Services will cease
- You must stop using the Services
- We may delete your Customer Content after 30 days
- You remain liable for all fees incurred before termination
- Sections that by their nature should survive will remain in effect
### 12.4 Data Export
For 30 days after termination, you may request export of your Customer Content in a standard format, subject to technical feasibility and legal restrictions.
## 13. Dispute Resolution
### 13.1 Informal Resolution
Before filing a formal dispute, you agree to try to resolve any dispute informally by contacting us. Most disputes can be resolved informally.
### 13.2 Arbitration Agreement
If we cannot resolve a dispute informally, you and BrainGrid agree to resolve any claims through binding arbitration, except:
- Claims for injunctive relief regarding intellectual property
- Small claims court actions
- Claims that cannot be arbitrated under applicable law
### 13.3 Arbitration Rules
Arbitration will be conducted by JAMS under its Comprehensive Arbitration Rules. The arbitration will be held via videoconference.
### 13.4 Class Action Waiver
You agree to bring claims only in your individual capacity and not as part of any class, collective, or representative action.
## 14. General Provisions
### 14.1 Governing Law
These Terms are governed by the laws of the State of Delaware, without regard to conflict of law principles.
### 14.2 Entire Agreement
These Terms, together with our Privacy Policy and any other agreements referenced herein, constitute the entire agreement between you and BrainGrid regarding the Services.
### 14.3 Modifications
We may modify these Terms at any time. We will notify you of material changes by:
- Posting the updated Terms on our website
- Sending email notification to registered users
- Displaying a notice in the Services
Your continued use after changes constitutes acceptance of the modified Terms.
### 14.4 Severability
If any provision of these Terms is found to be unenforceable, the remaining provisions will continue in full force and effect.
### 14.5 No Waiver
Our failure to enforce any right or provision of these Terms will not be considered a waiver of those rights.
### 14.6 Assignment
You may not assign or transfer these Terms without our prior written consent. We may assign these Terms without restriction.
### 14.7 Force Majeure
Neither party will be liable for any failure or delay in performance due to circumstances beyond their reasonable control, including acts of God, natural disasters, war, terrorism, riots, embargoes, acts of civil or military authorities, fire, floods, or other events beyond the control of the parties.
### 14.8 Export Compliance
You agree to comply with all applicable export and import laws and regulations. You represent that you are not located in a country subject to a U.S. Government embargo or designated as a "terrorist supporting" country.
### 14.9 U.S. Government Rights
If you are a U.S. Government end user, the Services are "Commercial Items" as defined at 48 C.F.R. §2.101, consisting of "Commercial Computer Software" and "Commercial Computer Software Documentation."
## 15. Contact Information
If you have questions about these Terms, please contact us:
**Email**: legal at our domain
**Mailing Address**:
BrainGrid AI, Inc.
1111B S Governors Ave STE 29316
Dover DE 19904
USA
---
By using BrainGrid, you acknowledge that you have read and understood these Terms of Service and agree to be bound by them.


 BrainGrid asks clarifying questions to define the scope and uncover edge cases.
Upon completion, the basic prompt is refined into a full technical requirement with feature requests. This can be edited manually, or work with the AI to update the requirement.

 In this example, the simple prompt has been expanded to include:
* Overview
* Actors
* Data Model Changes
* 6 Functional Requirements
* API Contract
* New Files
* Environmental Variables
* 10 Acceptance Criteria

 * Commits the code to the Github repository.


 Now it is time to start building. Enter a prompt that describes what you are looking to build. Note that you can connect your prompt to a GitHub repository.
If you have not yet connected your GitHub account to BrainGrid, there are [detailed instructions](github-installation).
Once you enter your prompt that describes your idea, the agent will start thinking and analyzing the codebase (if it exists). It can come back with some clarifying questions to help it understand the requirement better, or ask you if you are comfortable with the plan proposed. Iterate with the agent until you are happy with the plan.

 Once you accept the plan, BrainGrid will use the plan to create an EPIC user story. Several requirements are stubbed out that will be used to implement the plan.


 Once completed, A full requirements document is created that outlines what will be built. You can ask the agent to make changes, clarify things, add or remove details (or you can edit the document manually.)

 We are now ready to build!


 In your Agent, follow the instructions from BrainGrid:
 You Agent will connect with BrainGrid, read the EPIC and requirement, and begin building!
 * You want to tweak a message you sent earlier.
 You can edit the message and start over from there.
 ***
**
 ***
## Improvements [#improvements-3]
* **Streaming AI responses** - The thinking tool now streams responses in real-time. Watch the agent's reasoning unfold as it happens instead of waiting for the complete response.
***
## Fixes [#fixes-3]
* **Invite links in Apple Mail** - Fixed critical bug where Apple Mail was breaking invite links.
* **MCP dependency validation** - When task dependencies block completion, you now get helpful error messages instead of cryptic 500 errors. Shows exactly which tasks need completion first with proper HTTP 409 Conflict status and clear resolution steps.
* **Repository dropdown display** - Fixed visual issues with repository selection, making repository names clearer and selection smoother.
 ***
**
 → Click on a [Project](https://braingrid.link/app), then go to the "Ideas" tab to create your first idea.
***
**
 → Click on a [Project](https://braingrid.link/app), create a new requirement, and use the `@` syntax to mention another requirement.
***
**
 → Create your first [Project](https://braingrid.link/app).
***
**

 ***
**
 [Try the Build tab →](https://app.braingrid.ai?utm_source=changelog\&utm_medium=content\&utm_campaign=build_tab)
***
## New Features [#new-features]
**
 [Try Designs →](https://app.braingrid.ai/designs?utm_source=changelog\&utm_medium=content\&utm_campaign=designs) · [Read the blog post →](https://www.braingrid.ai/blog/introducing-designs)
***
**
 ***
**
 ***
**
 ***
**

 [Try AI Product Planner →](https://app.braingrid.ai/projects/new?utm_source=changelog\&utm_medium=content\&utm_campaign=ai_product_planner)
***
**
 ***
**
 ***
**
 ## New Features [#new-features-1]
**
 ***
**
 ***
**
 ***
**
 Enter `/mcp` to manage your MCP servers:
```bash
/mcp
```
Then you'll see "BrainGrid disconnected - enter to login"
 Hit "Enter", this will open a browser window to login to BrainGrid. Once you log in, you can approve the BrainGrid MCP to connect to your account.
 Once the authentication is complete, you'll see "Authentication successful. Connected to BrainGrid." and you can start using the BrainGrid MCP.
 You can now use the BrainGrid MCP to create requirements and tasks.
 Click "Install" and you'll see the BrainGrid MCP server installed with a "Needs login" message.
 Click on the "Needs login" message and you'll be taken to the BrainGrid login page. Once you log in, you can approve the BrainGrid MCP to connect to your account.
 Once you're logged in, you can start using the BrainGrid MCP.

 3. **Scroll down to the MCP Servers section**
* Click **Open MCP Marketplace**
 4. **In the Installed MCPs sub section**
* Click the gear icon on the right.
 5. **Configure the Server**
* Enter the following configuration:
```json
{
"mcpServers": {
"braingrid": {
"command": "npx",
"args": ["-y", "mcp-remote@latest", "https://mcp.braingrid.ai/mcp"]
}
}
}
```
6. **Complete Setup**
* Close all tabs
* Reopen the Windsurf Settings
* Go to the MCP Marketplace, click open
* You will see the BrainGrid MCP server listed
 7. **Troubleshooting**
* If you are having connection or auth issues, disable it and re-enable it.